Credits
Every photograph and diagram on Robot Wiki is listed here with its creator, source page and licence. Article images are CC0, CC BY, CC BY-SA, public domain or used under a documented reuse permission. No image is AI-generated.
Market-map logos include official company marks, recorded as unlicensed or unknown where no reuse grant is named. The site's own text and original diagrams are licensed CC BY 4.0.
Written and maintained by Josef Chen (@josefchen).
Who is behind Robot Wiki
I spent three years building and deploying robots at KAIKAKU (acquired by REEF). What I needed over those years was scattered across papers that skip the deployment context and demos that never quote a failure rate. Robot Wiki collects it for engineers who come from machine learning and cites the source of every claim.
Corrections follow the editorial policy; report a factual issue on GitHub.
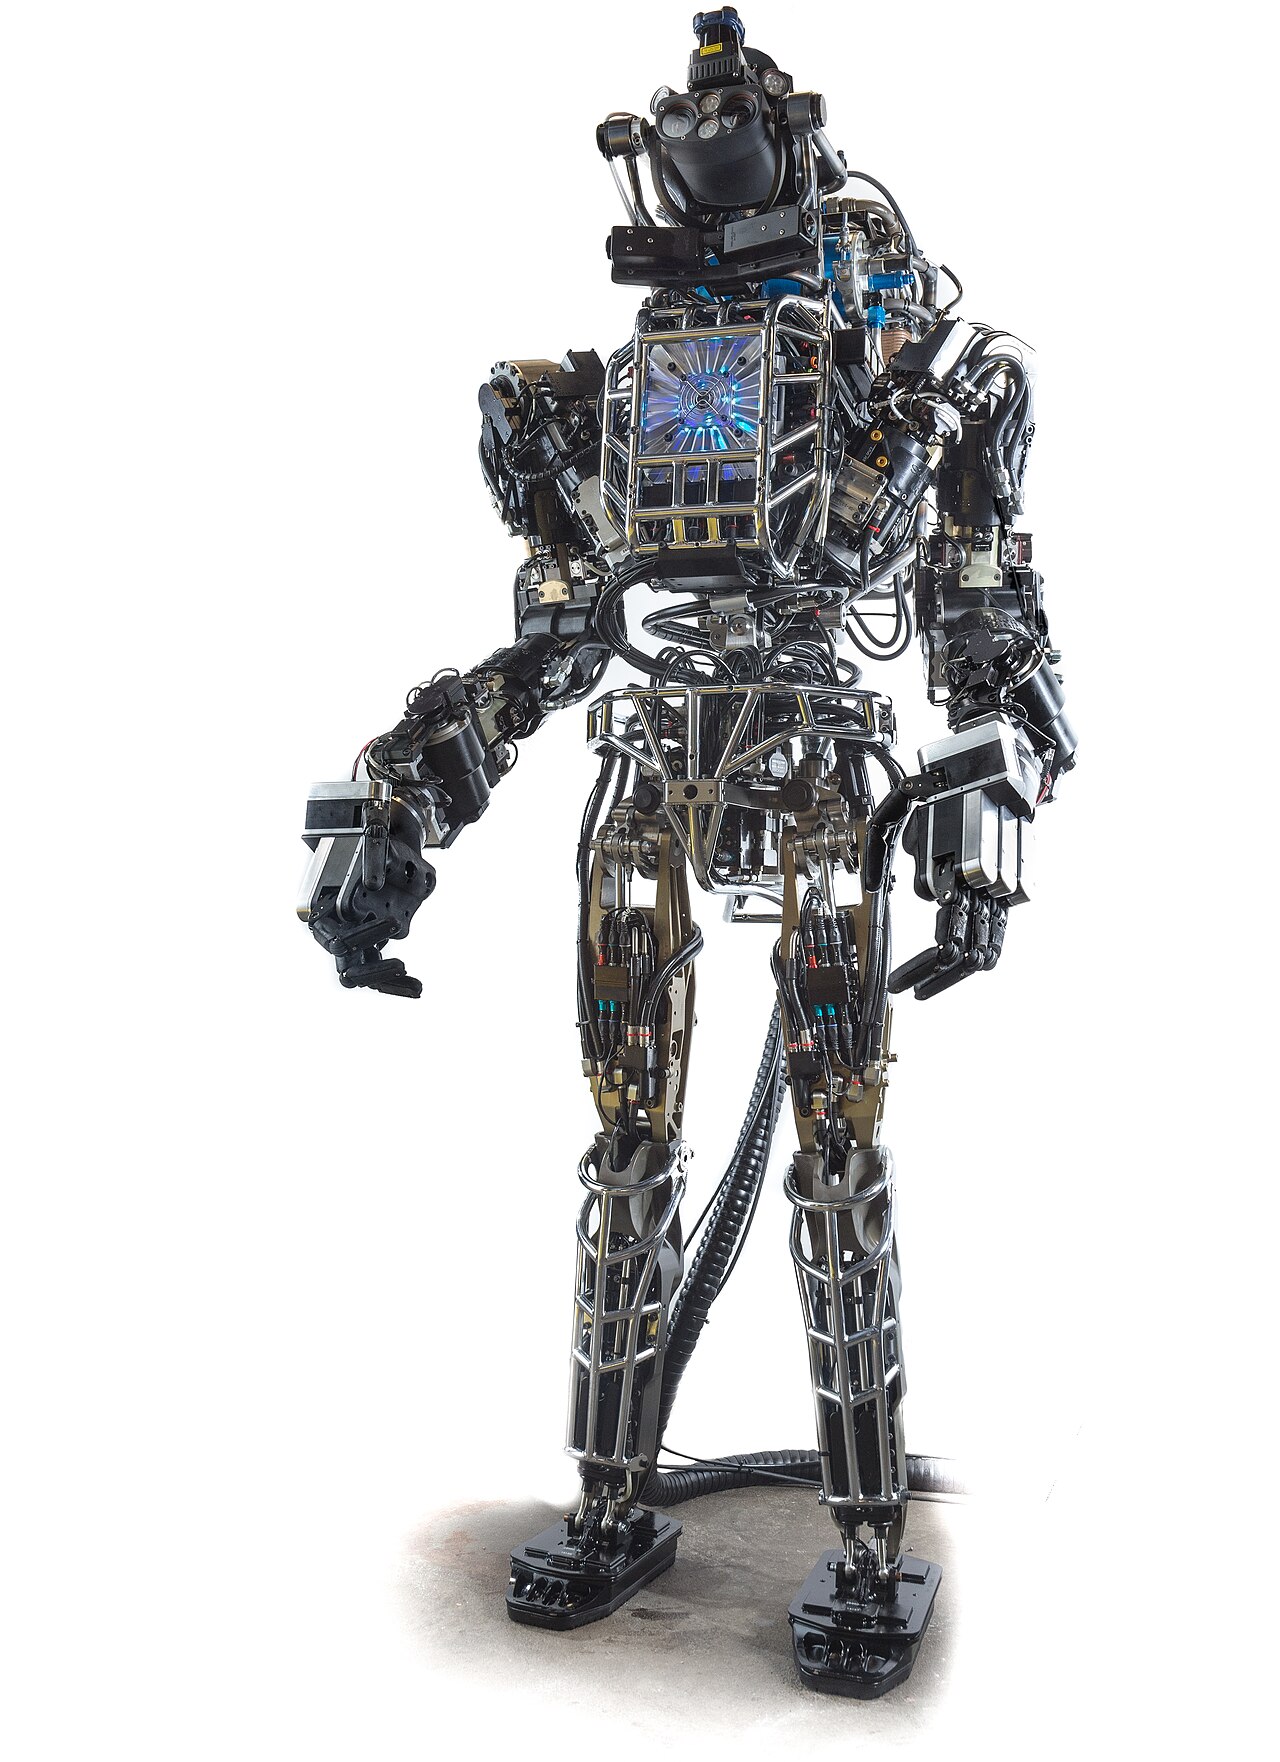
The original Atlas humanoid, built for the 2013 DARPA Robotics Challenge: hydraulically actuated, tethered, with its frame and sensor head exposed. The electric Atlas discussed above is its clean-sheet successor. Photo: DARPA / Wikimedia Commons. Licence: Public domain.Appears on: Hardware Taxonomy
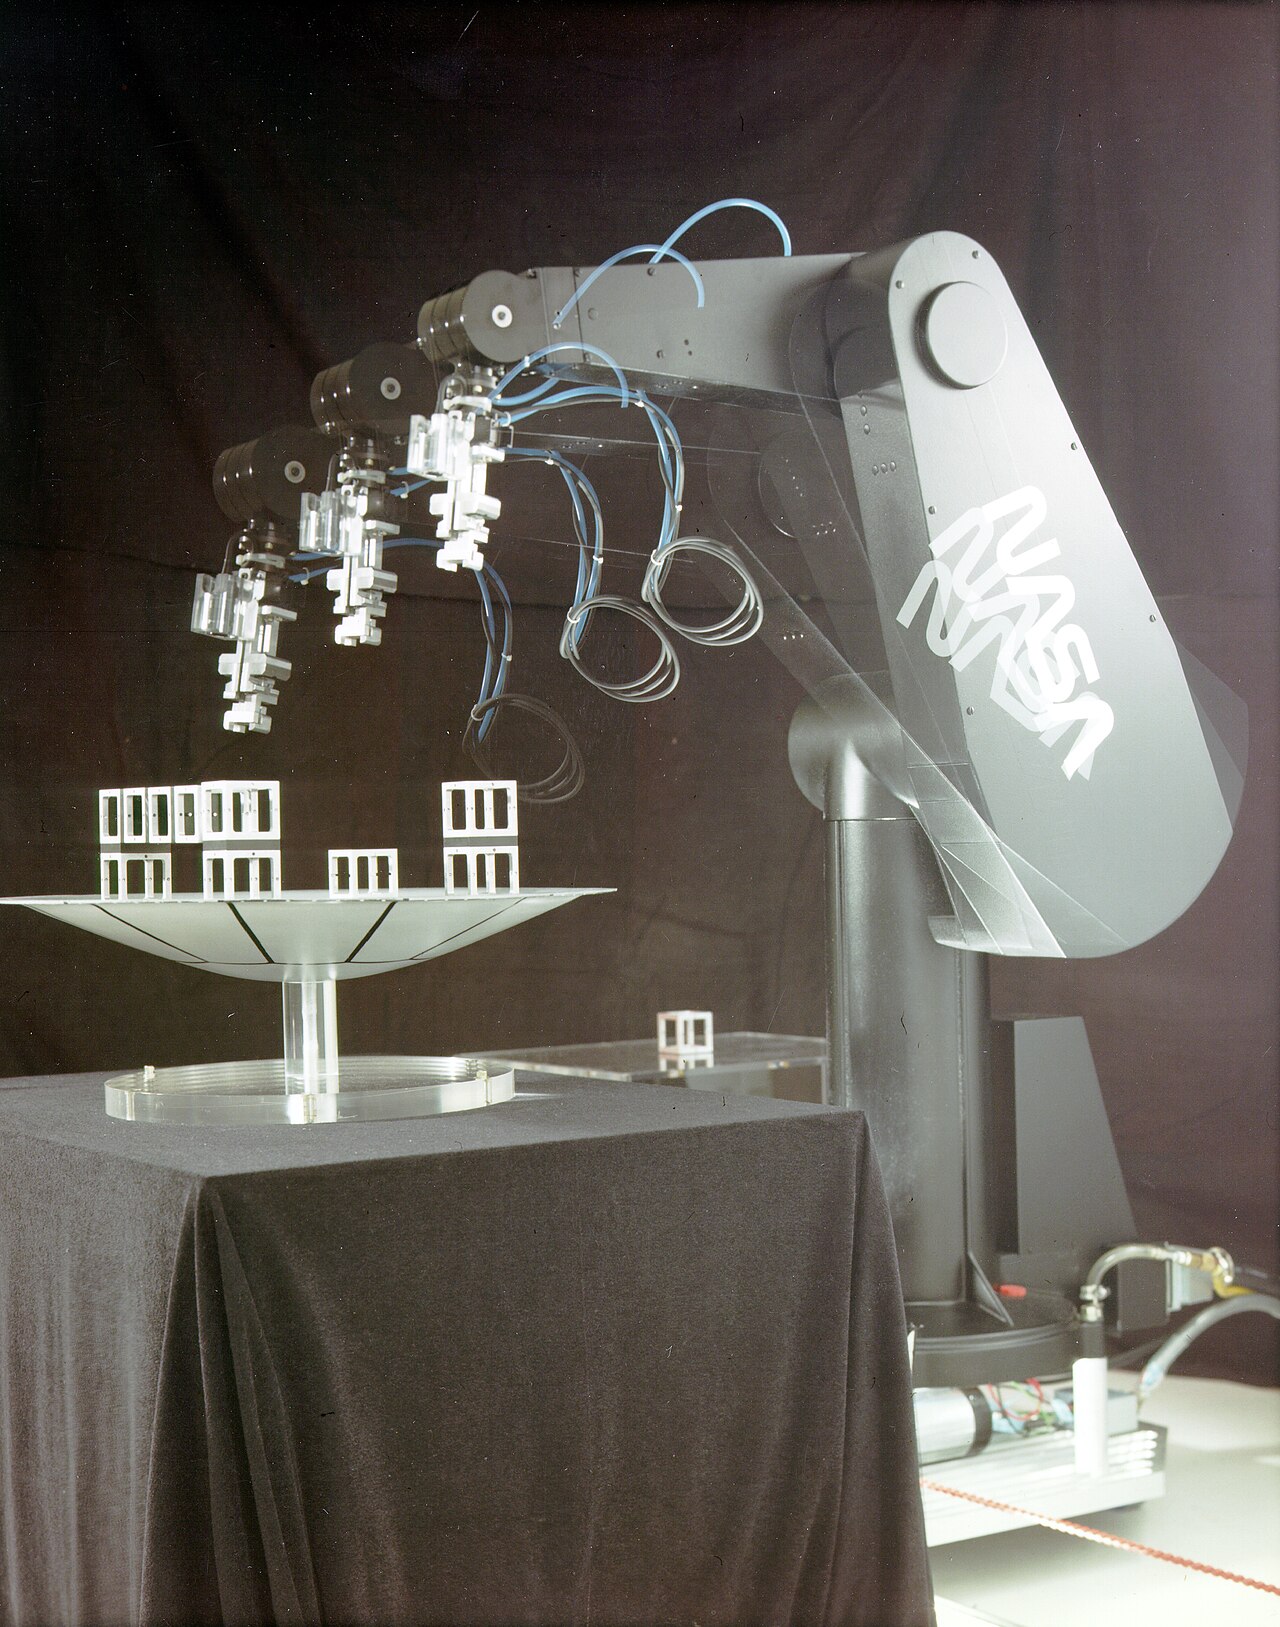
A PUMA 560 at NASA Ames, photographed in a stroboscopic exposure as it cycles through its workspace. The six-revolute PUMA layout is the canonical teaching example for the Denavit-Hartenberg convention. Photo: NASA / Dominic Hart / Wikimedia Commons. Licence: Public domain.Appears on: Kinematics
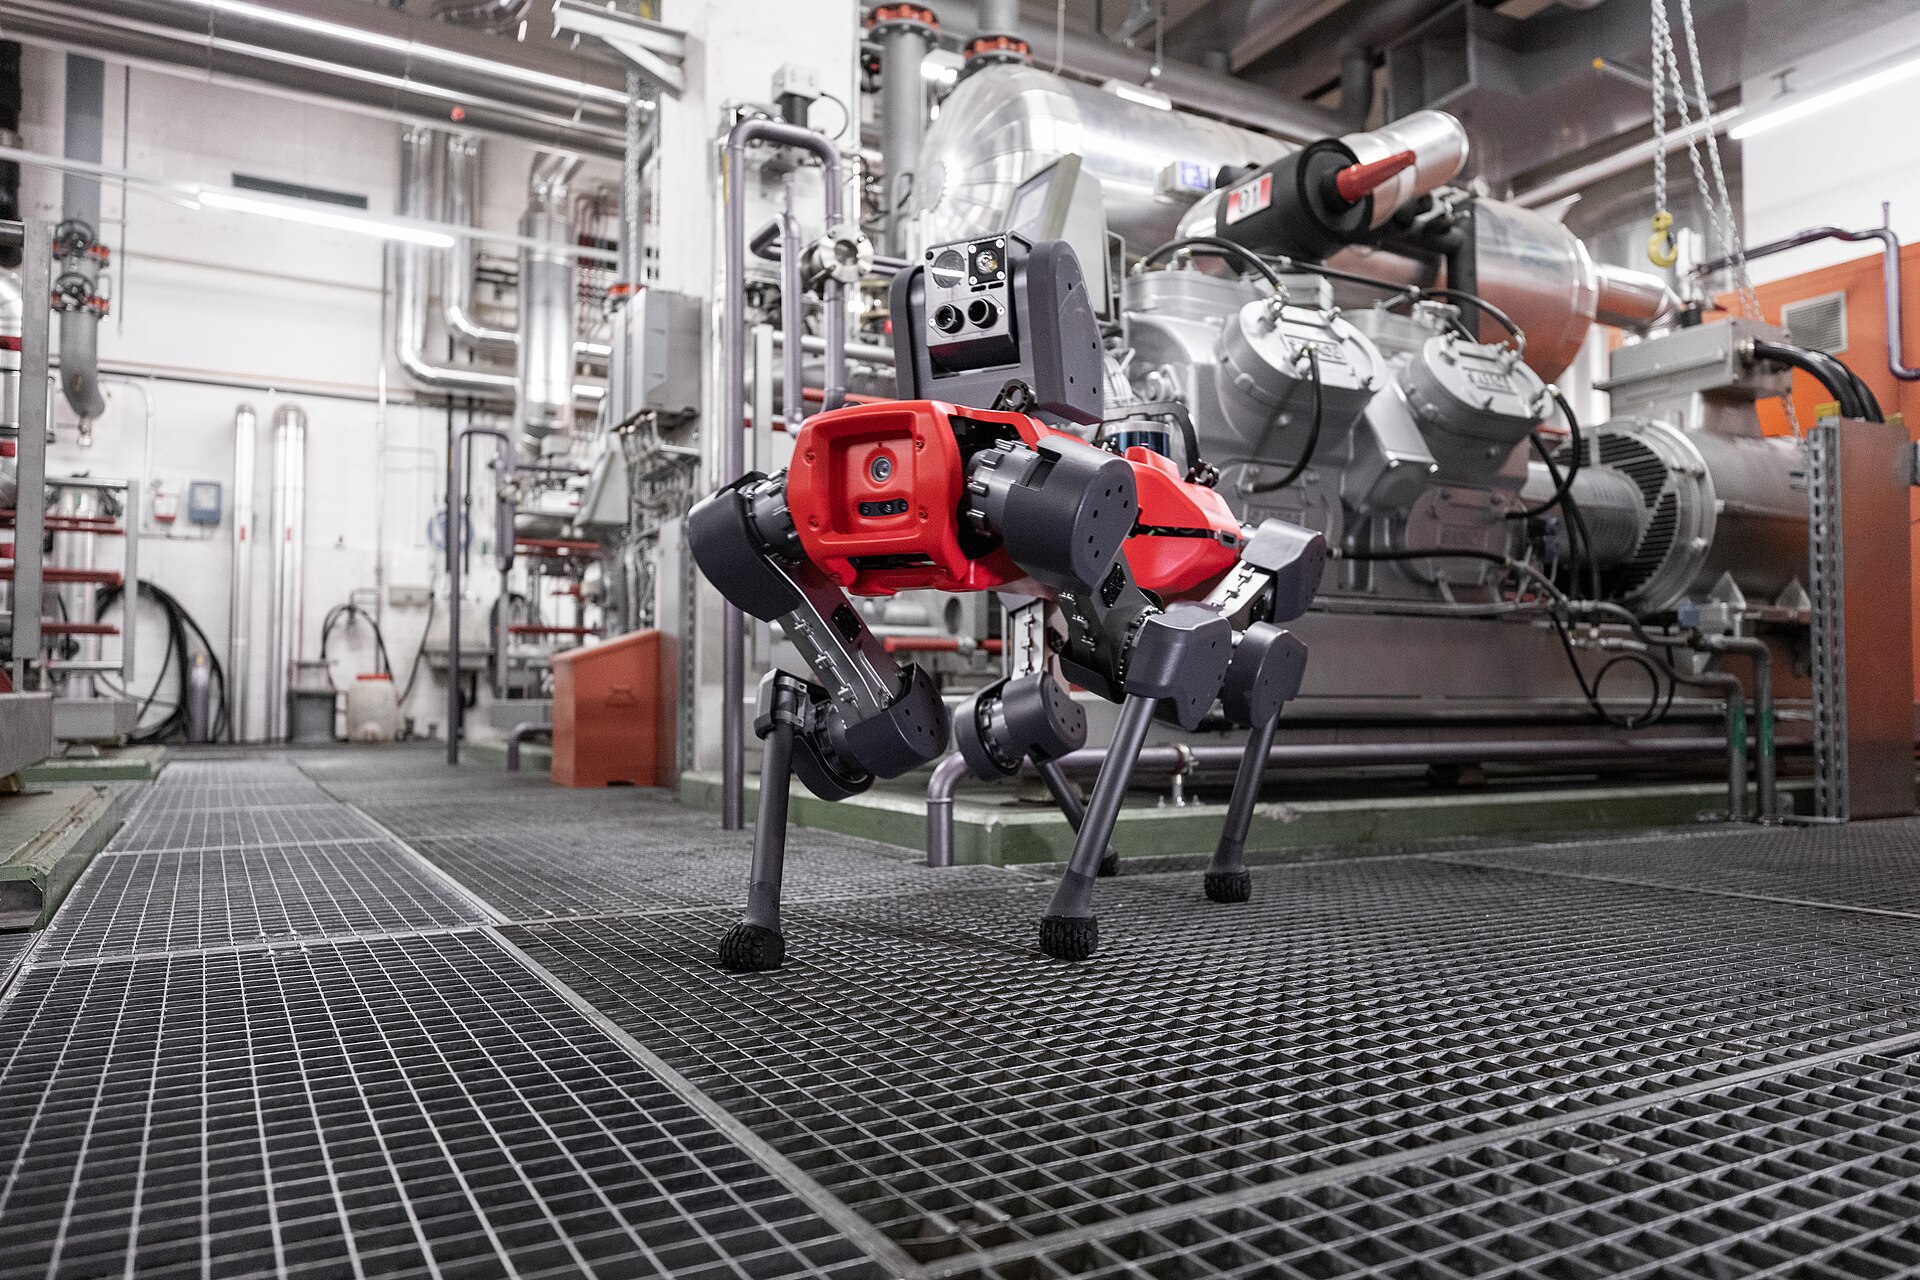
ANYmal, the ANYbotics quadruped behind the ETH Zurich locomotion lineage, on an industrial inspection floor. The actuator-network and terrain-curriculum results above all ran on this platform. Photo: ANYbotics / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Legged Locomotion Lineage
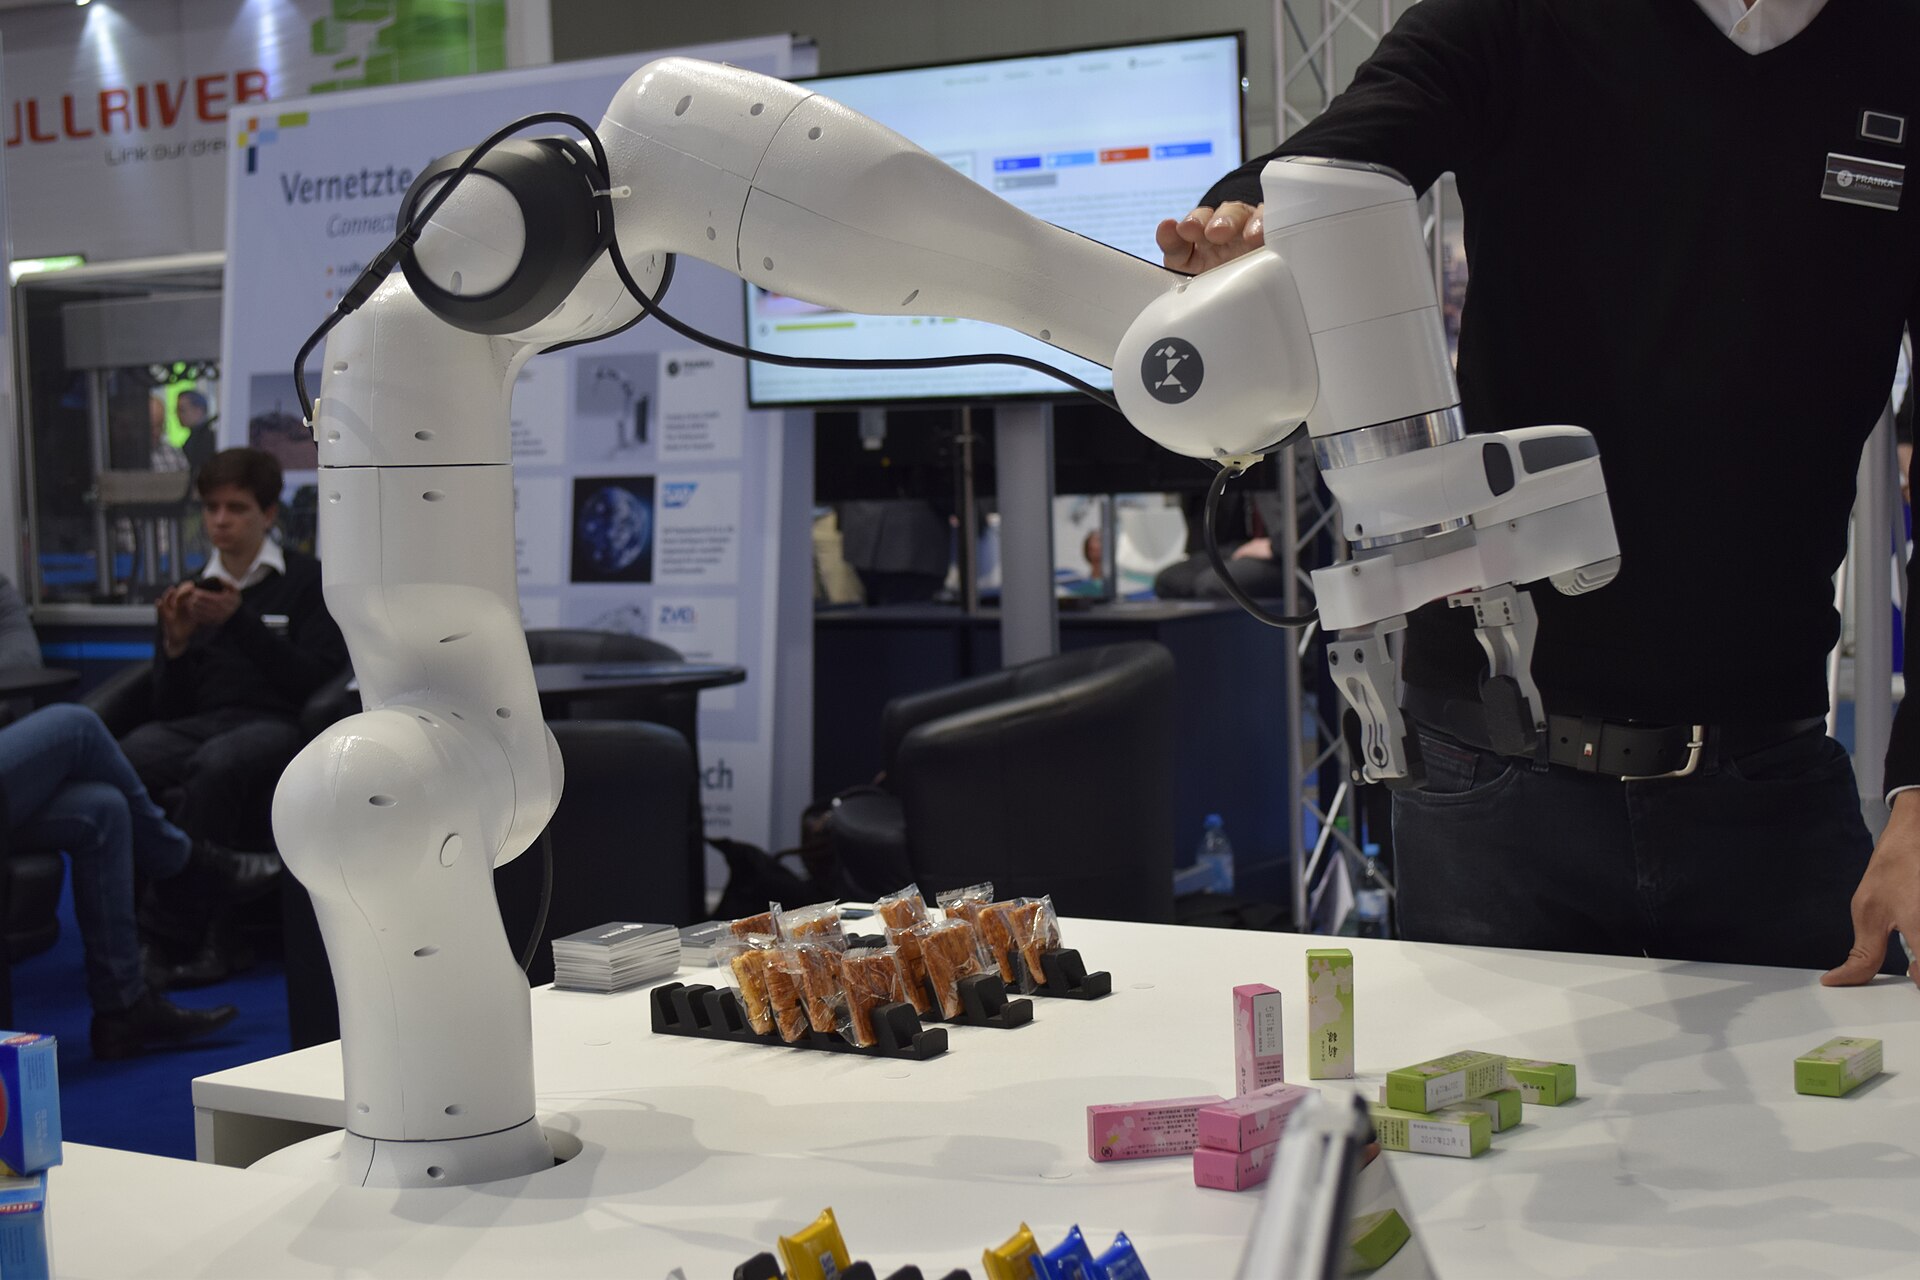
The Franka Emika Panda, the seven-DoF research arm, demonstrated at CeBIT 2017 with a human guiding it by hand. Photo: Ims / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Hardware Taxonomy
- Covariate shiftOne small slip, and the robot leaves familiar groundOriginal schematic
Robots trained by copying only learn the situations they were shown; one slip lands them somewhere new, where slips grow. How this was made
A schematic, not data. A robot trained by behavior cloning learns from the states an expert visited (the shaded corridor of demonstrations). Running on its own, it visits its own states, and the two drift apart after its first mistake: from there it is outside anything it was trained on, so its next mistake is likely to be larger.
The mismatch between the training states and the states the robot reaches is called covariate shift, or distribution shift. Ross, Gordon and Bagnell (2011) showed that the resulting cost can grow with the square of the task length, and proposed DAgger, which has an expert label the states the robot actually visits.
Diagram: Robot Wiki contributors / Robot Wiki (original diagram). Licence: CC BY 4.0.Appears on: Behavior Cloning Foundations
- Temporal ensemblingThree overlapping plans vote; the oldest gets the loudest voiceOriginal schematic
Blending several overlapping plans smooths the robot’s motion, so one odd prediction jerks the arm less. How this was made
A schematic, not data. In ACT the robot asks its policy for a fresh chunk of future moves at every control step, so the chunks issued at earlier steps each still hold a prediction for the current move. Temporal ensembling averages those predictions, and the oldest gets the largest weight.
Counting from the oldest (i = 0), prediction i gets the raw weight w_i = exp(−m·i); the weights are then divided by their sum. The drawing uses m = 0.5 so the three weights differ visibly: raw 1.00, 0.61, 0.37, which is 51%, 31%, 19% of the vote. The ACT reference code uses m = 0.01, which makes the weights almost equal.
Diagram: Robot Wiki contributors / Robot Wiki (original diagram). Licence: CC BY 4.0.Appears on: Action Chunking (ACT and ALOHA)
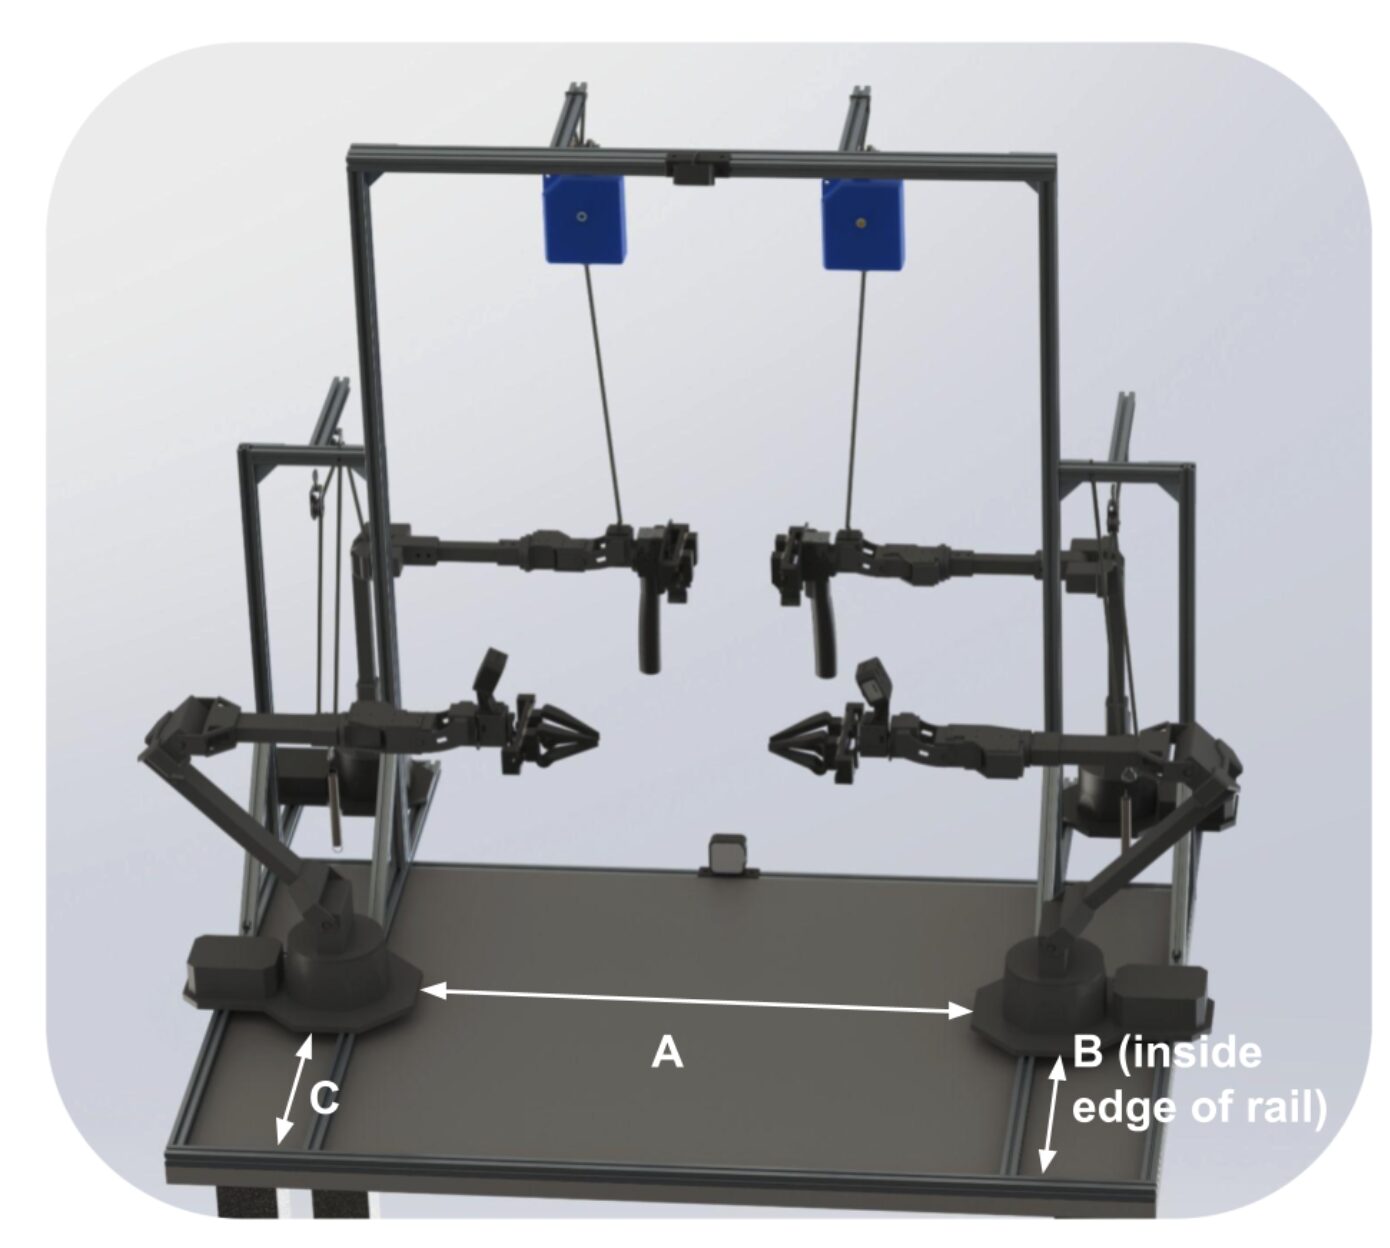
ACT was introduced with ALOHA, a low-cost bimanual rig on which a person demonstrates by moving leader arms. A render of the ALOHA 2 workcell, with its frame segments labelled A, B and C. Paper figure: Tony Z. Zhao et al. / arXiv. Licence: CC BY 4.0.Appears on: Action Chunking (ACT and ALOHA)
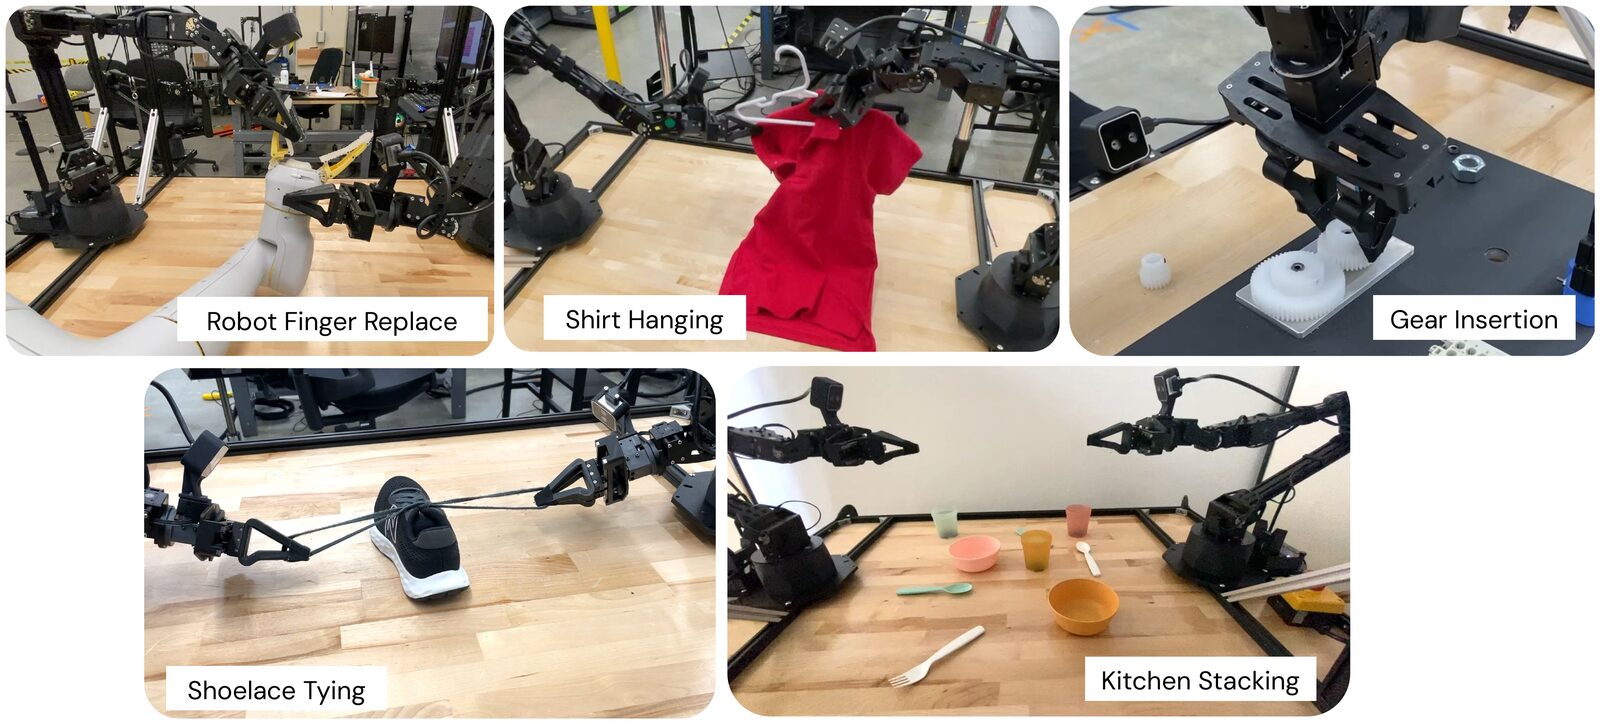
Chunked policies now do dexterous bimanual work such as tying shoelaces and hanging shirts. ALOHA Unleashed collected over 26,000 demonstrations for these five tasks on ALOHA 2 and ran each predicted chunk open loop. Paper figure: Tony Z. Zhao et al. / arXiv. Licence: CC BY 4.0.Appears on: Action Chunking (ACT and ALOHA)
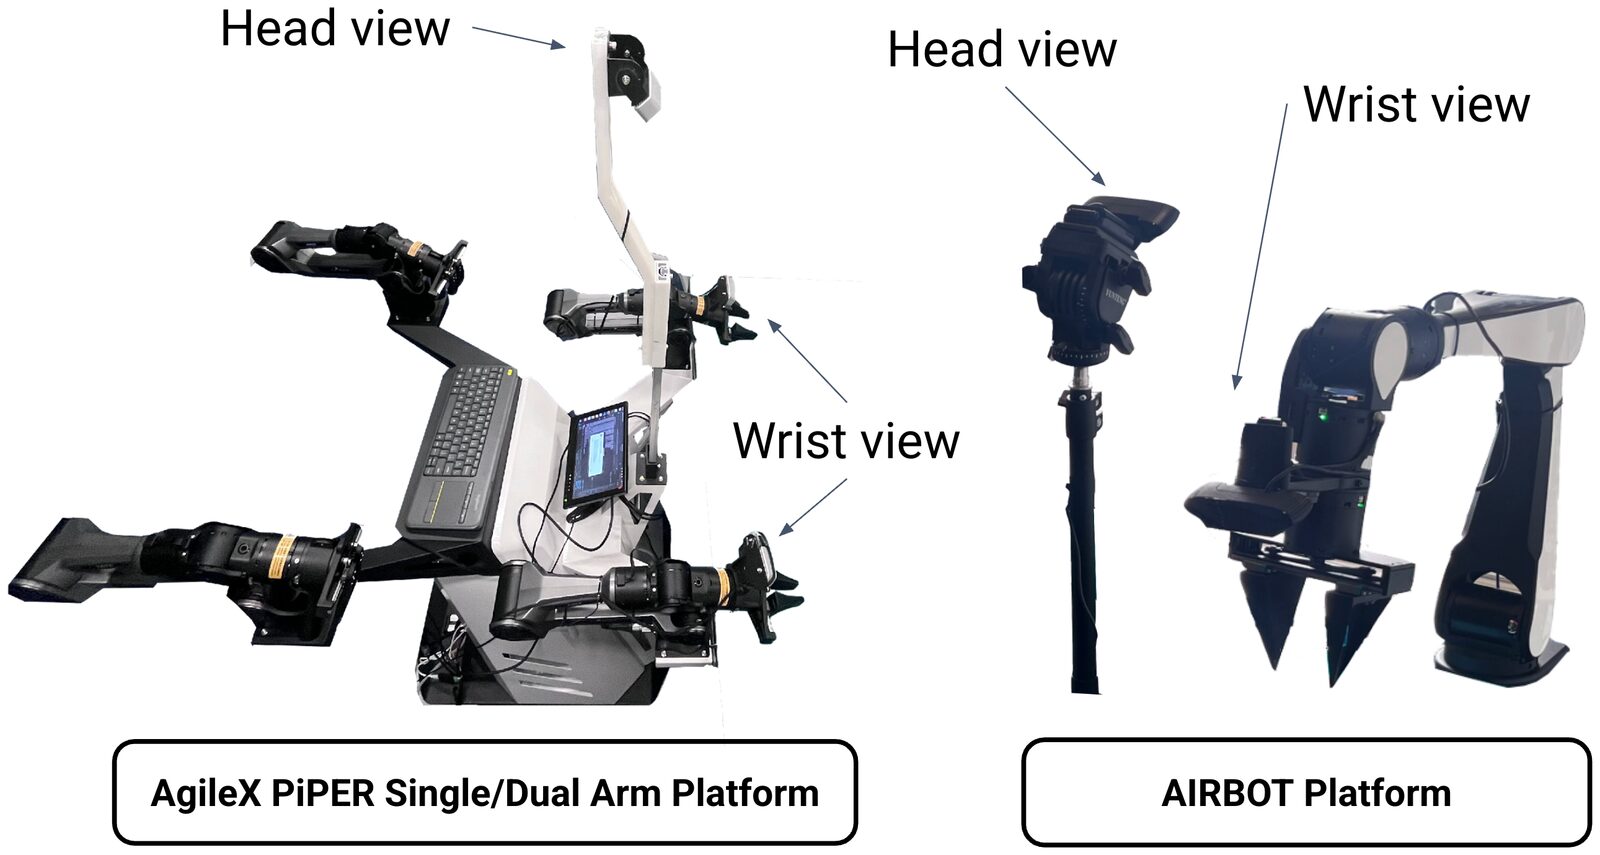
The two arm platforms of an action-space study with more than 13,000 real rollouts and 500+ models. Predicting delta actions consistently helped; joint space favoured control stability and task space favoured generalisation. Paper figure: Yuchun Feng et al. / arXiv. Licence: CC BY 4.0.Appears on: Action Spaces for Robot Learning
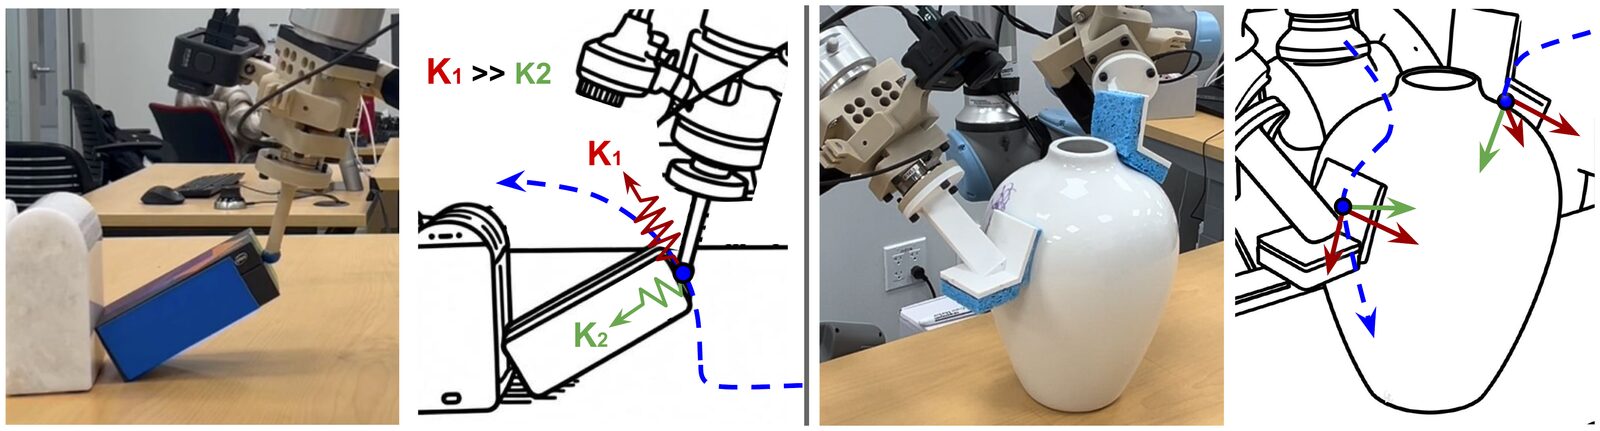
An impedance action sets the robot's stiffness in each direction as well as its goal. Adaptive Compliance Policy flips an item, soft (K2) along the push and stiff (K1) elsewhere, and wipes a vase with both arms compliant. Paper figure: Yifan Hou et al. / arXiv. Licence: CC BY 4.0.Appears on: Action Spaces for Robot Learning
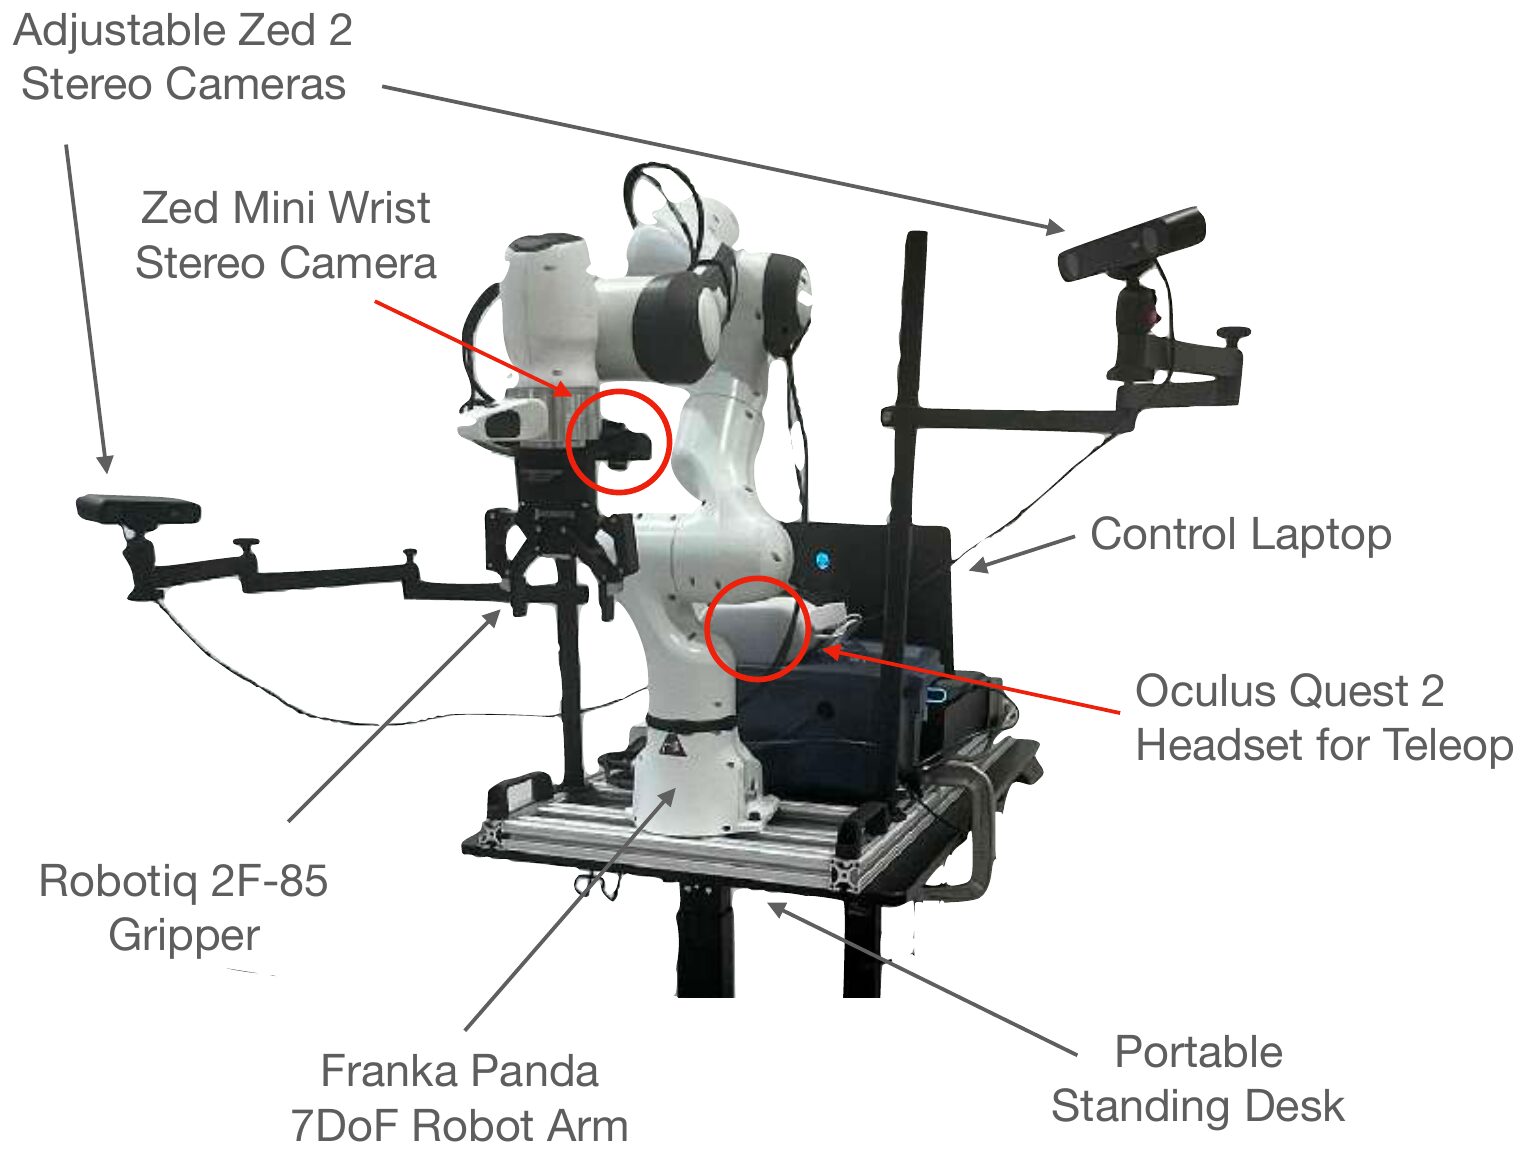
Behavior cloning starts from demonstrations recorded on rigs like this one, where a person teleoperates the arm through a VR headset. DROID used this Franka Panda setup at every institution. Paper figure: Alexander Khazatsky et al. / arXiv. Licence: CC BY 4.0.Appears on: Behavior Cloning Foundations
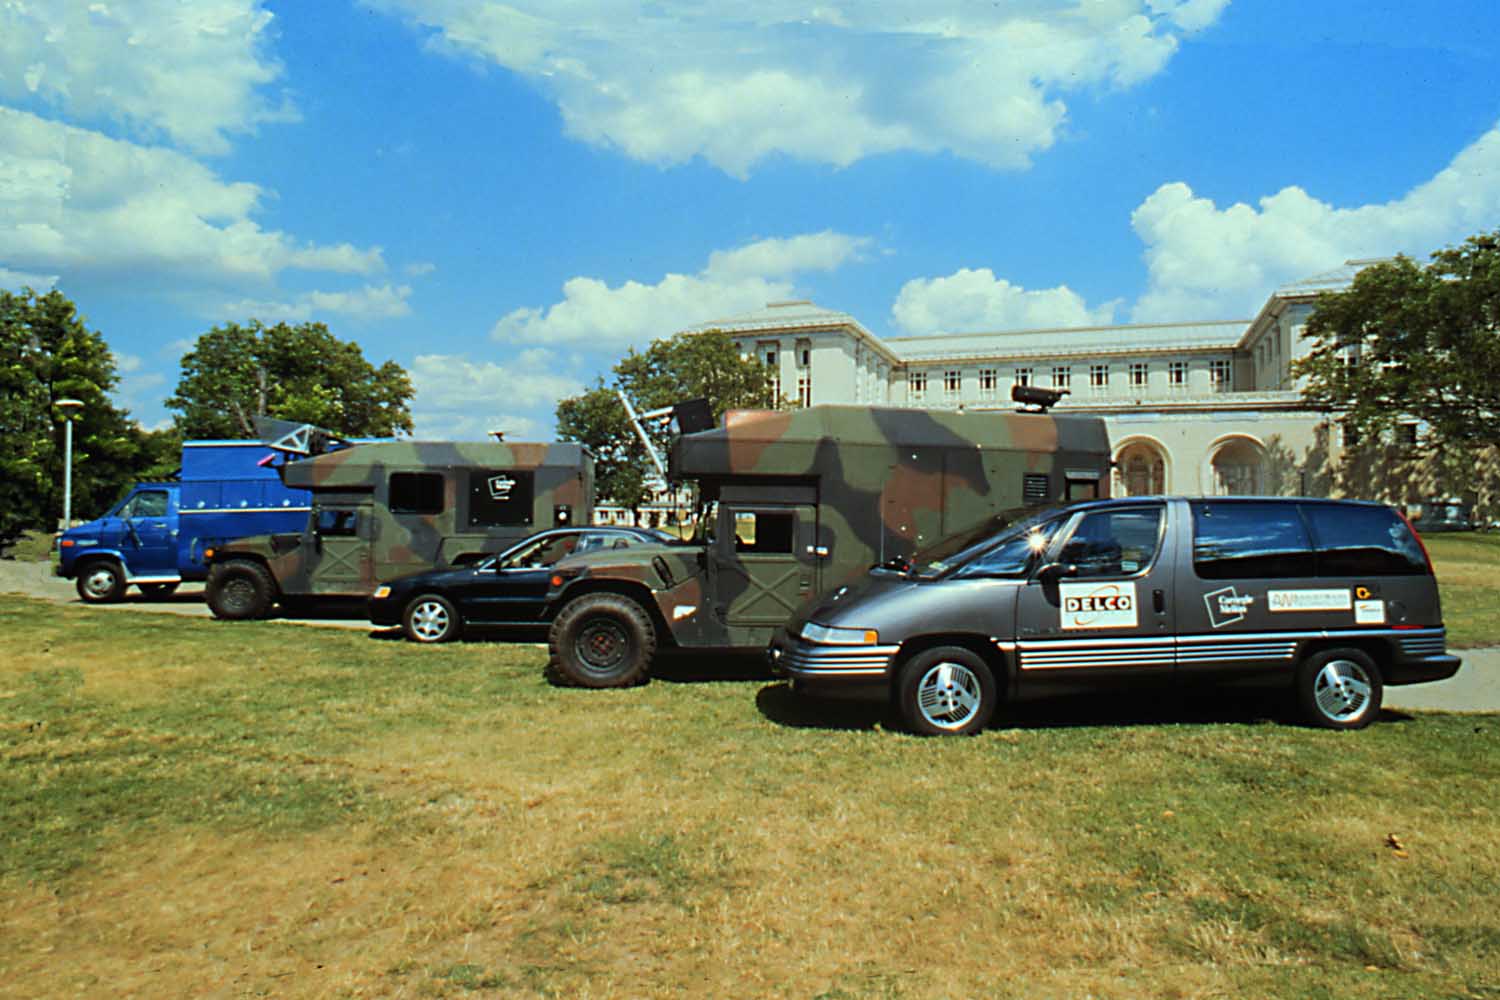
Behavior cloning began on the road: ALVINN learned to steer the Navlab van by watching a human driver. Navlab 1 (back) through Navlab 5 (front), built at Carnegie Mellon University from 1984 to 1995. Photo: Firefly4342 / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Behavior Cloning Foundations
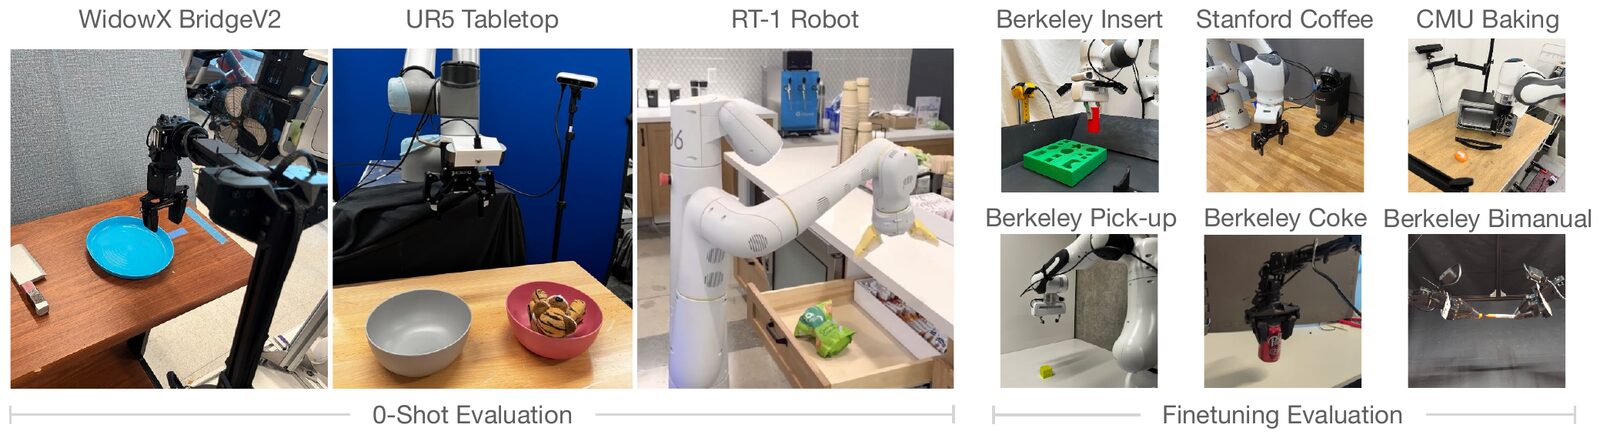
Octo, an open-weights policy, was evaluated out of the box on three robot setups and fine-tuned on six more, some with new observations, action spaces or embodiments. Paper figure: Octo Model Team / arXiv. Licence: CC BY 4.0.Appears on: Comparison Matrix, Vision-Language-Action Models
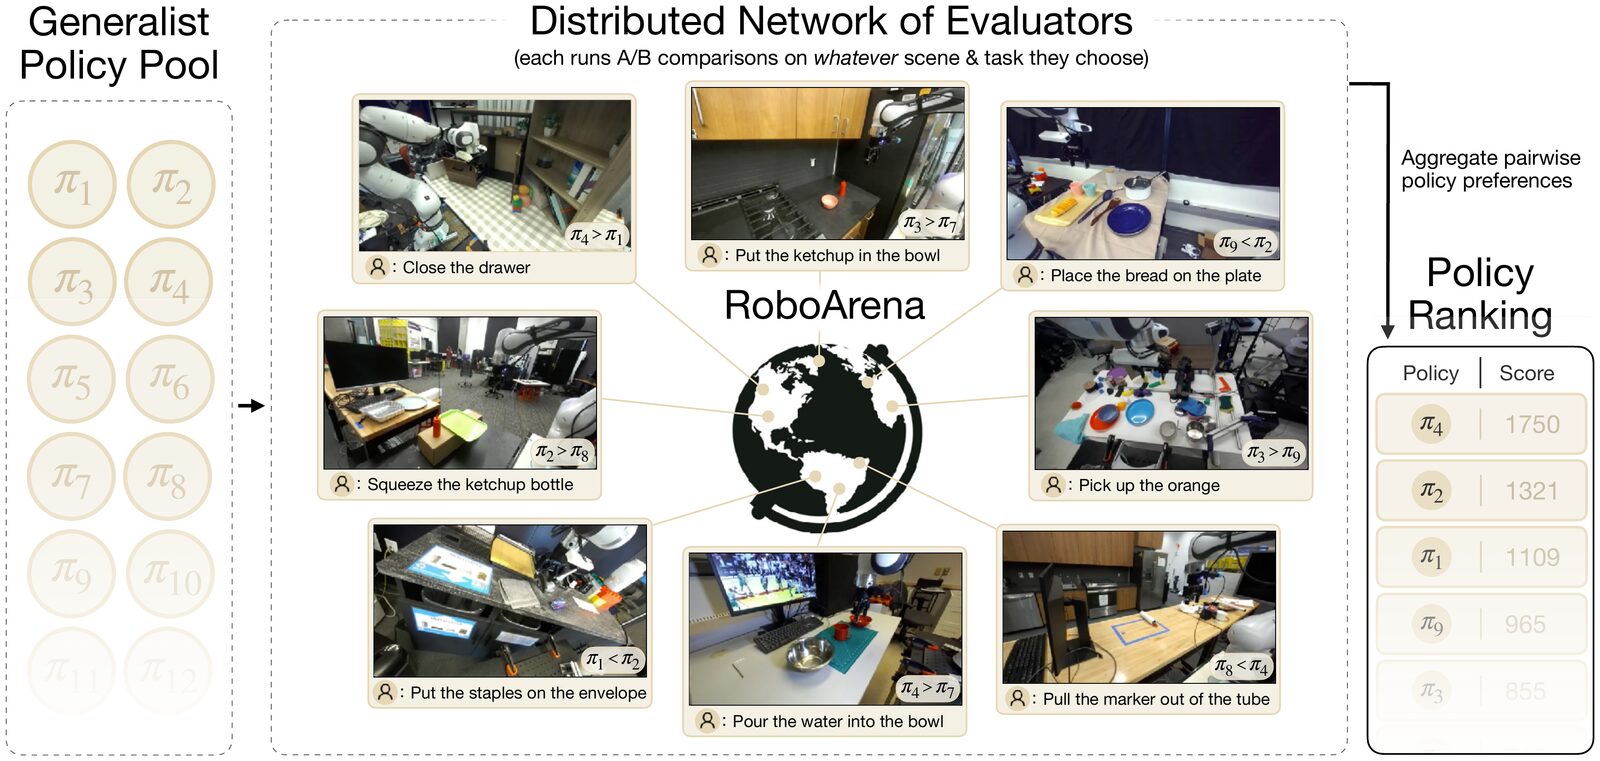
RoboArena ranks policies from double-blind pairwise trials that many evaluators run on their own scenes and tasks. More than 600 real-robot episodes on the DROID platform ranked seven generalist policies. Paper figure: Pranav Atreya et al. / arXiv. Licence: CC BY 4.0.Appears on: The Evaluation Crisis, Comparison Matrix, Other Generalist Policies, World Model Evaluation for Robotics
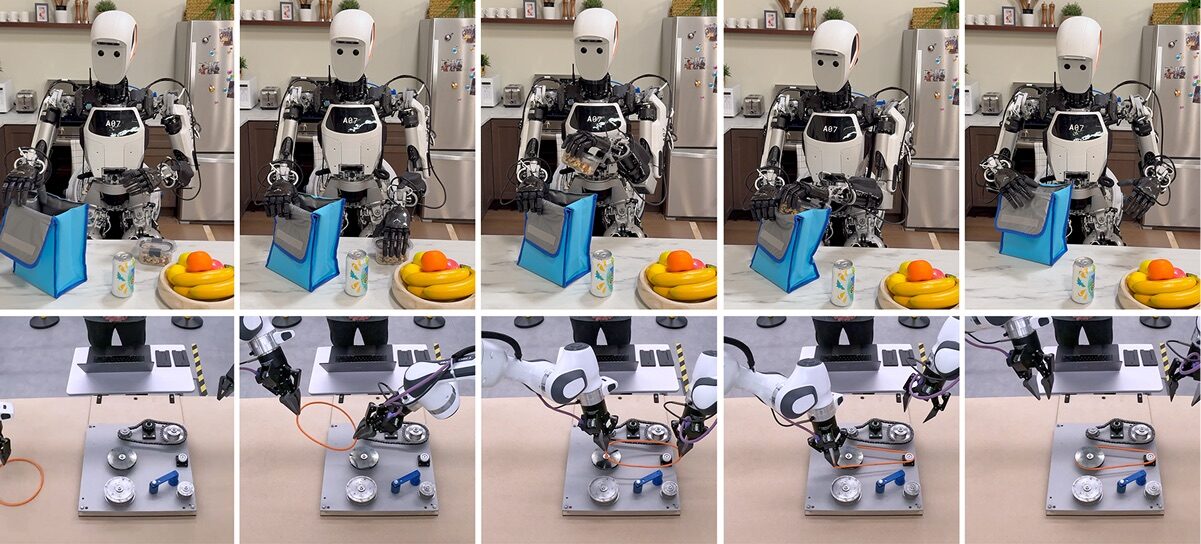
One Gemini Robotics model was fine-tuned to drive very different bodies, from the Apollo humanoid packing a lunch bag (top) to a bi-arm Franka fitting a rubber band around pulleys (bottom). Paper figure: Gemini Robotics Team / arXiv. Licence: CC BY 4.0.Appears on: Comparison Matrix, Other Generalist Policies
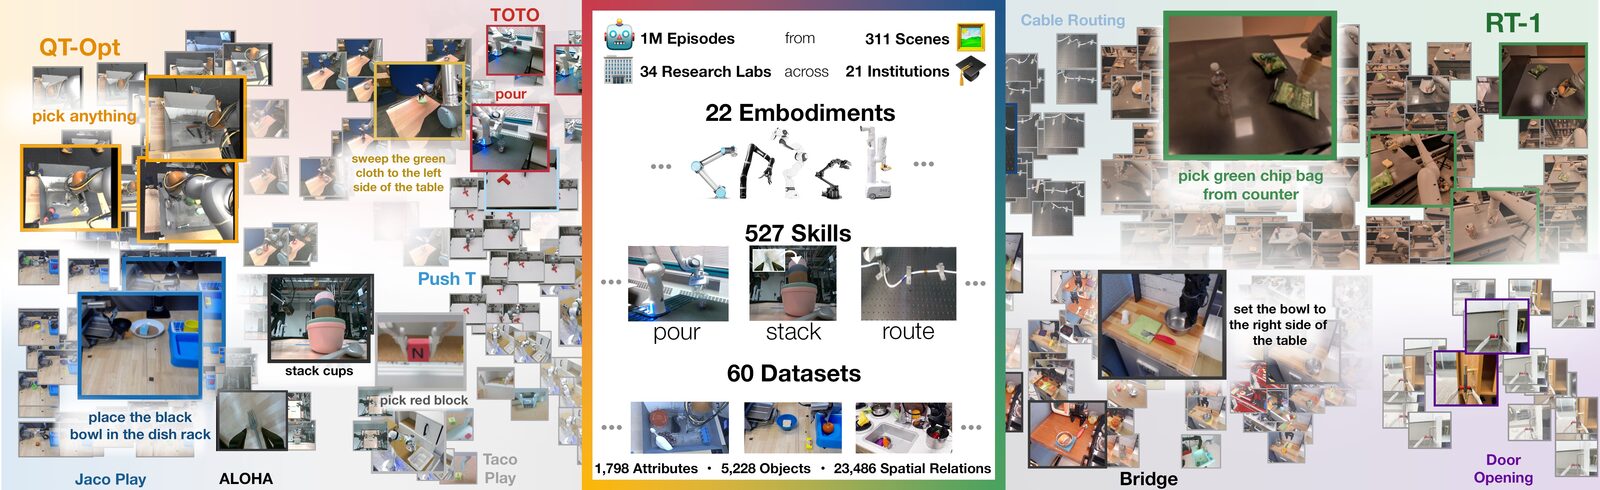
Open X-Embodiment pooled robot data into one training set: 1M episodes from 60 datasets, 22 embodiments and 527 skills, contributed by 34 labs at 21 institutions. Paper figure: Open X-Embodiment Collaboration / arXiv. Licence: CC BY 4.0.Appears on: Major Datasets, Cross-Embodiment Transfer, Vision-Language-Action Models
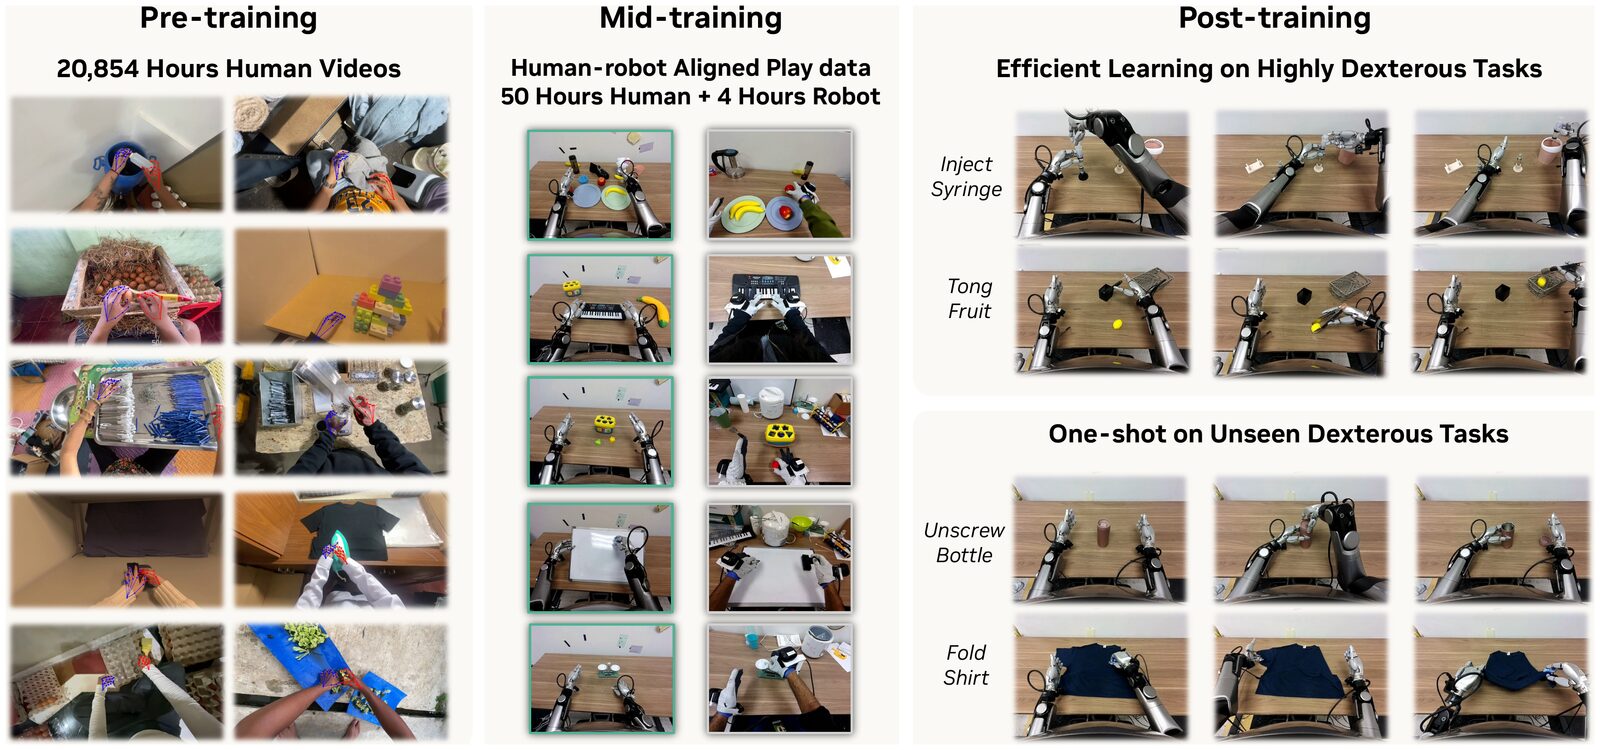
EgoScale pretrains on human video, mid-trains on aligned human and robot play, then post-trains on robot tasks. The pretraining stage uses 20,854 hours of egocentric video with wrist motion and retargeted hand actions. Paper figure: Ruijie Zheng et al. / arXiv. Licence: CC BY 4.0.Appears on: Cross-Embodiment Transfer
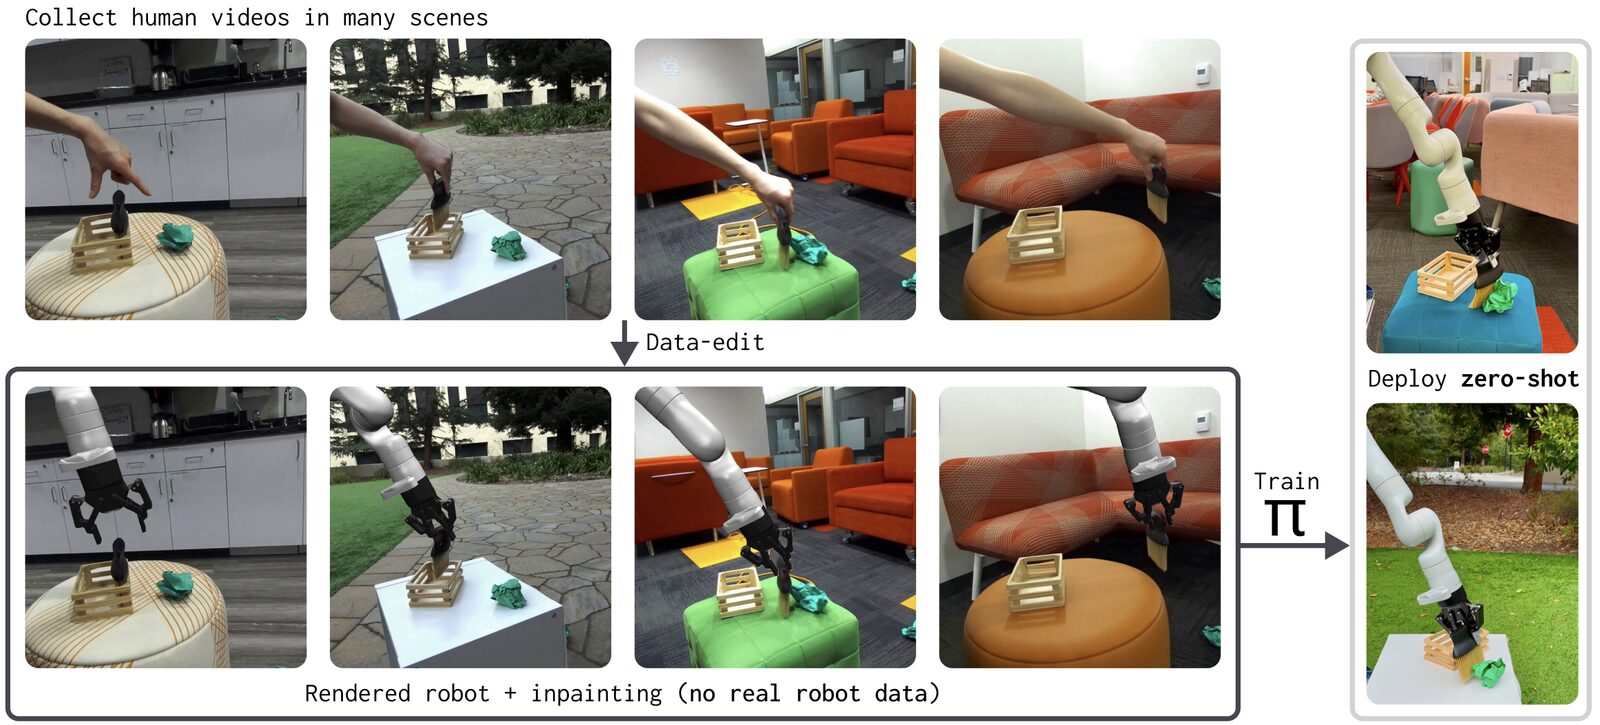
Phantom trains a robot policy without robot data by erasing the human hand from demonstration videos and rendering a robot arm in its pose. The policy then deploys zero-shot on a real robot, with success up to 92%. Paper figure: Marion Lepert et al. / arXiv. Licence: CC BY 4.0.Appears on: Cross-Embodiment Transfer
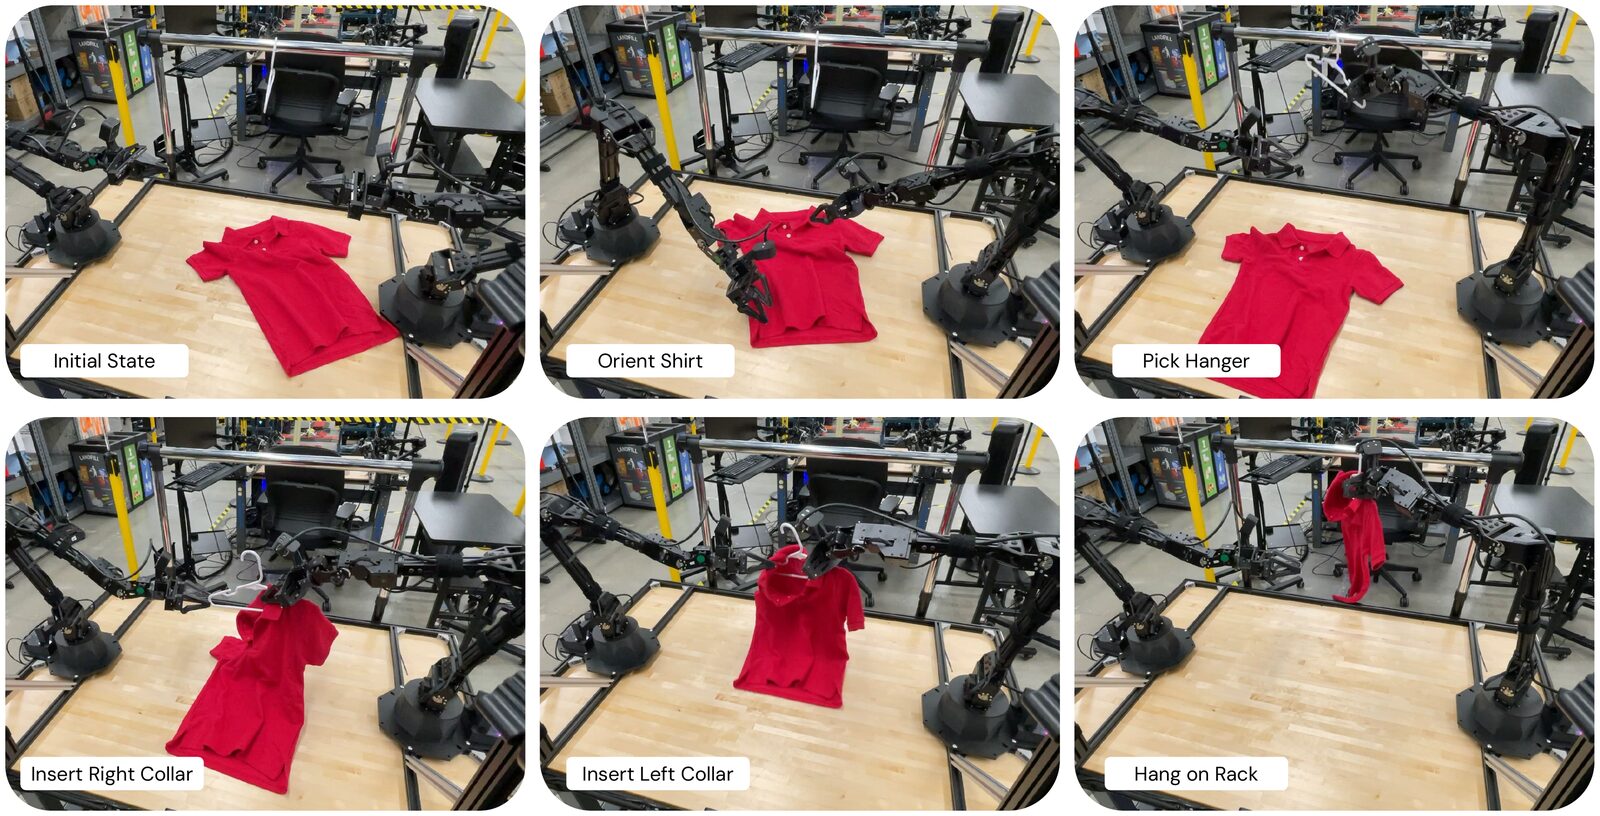
A diffusion policy hangs a shirt on its own, a long-horizon task with a deformable object and several bimanual stages. Six frames of an autonomous ALOHA Unleashed rollout, from the initial state to the shirt on the rack. Paper figure: Tony Z. Zhao et al. / arXiv. Licence: CC BY 4.0.Appears on: Diffusion Policy
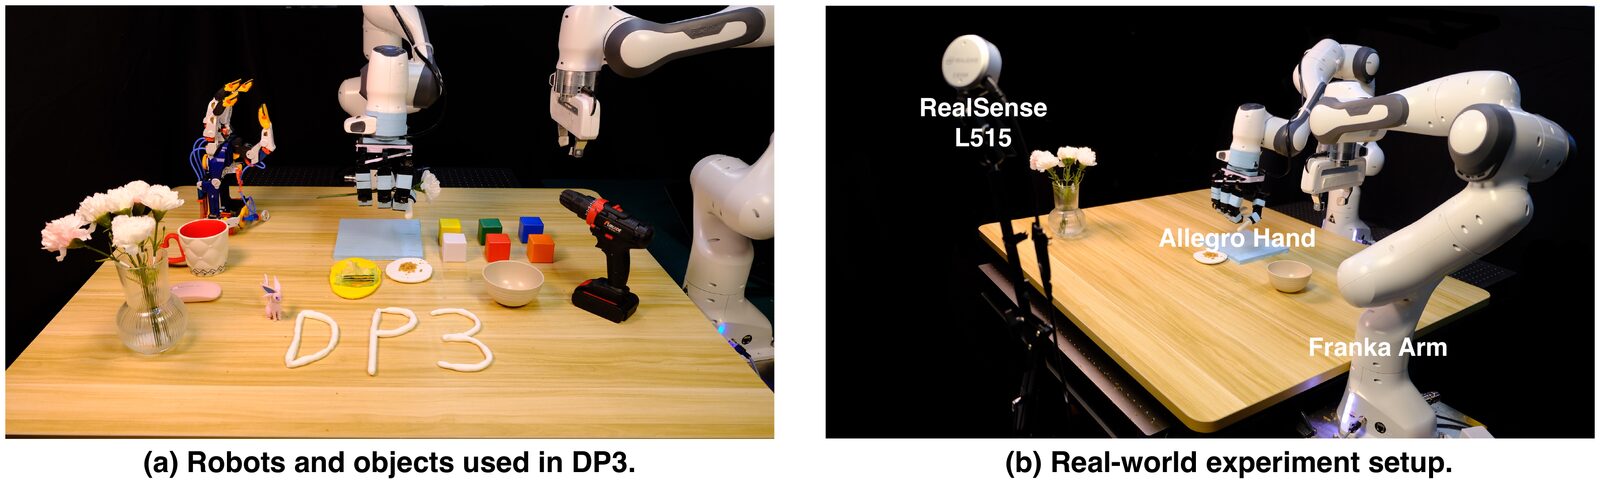
3D Diffusion Policy swaps images for sparse point clouds from a single depth camera. Left, the everyday objects in its real tasks; right, a Franka arm with an Allegro hand under a RealSense L515. Paper figure: Yanjie Ze et al. / arXiv. Licence: CC BY 4.0.Appears on: Diffusion Policy
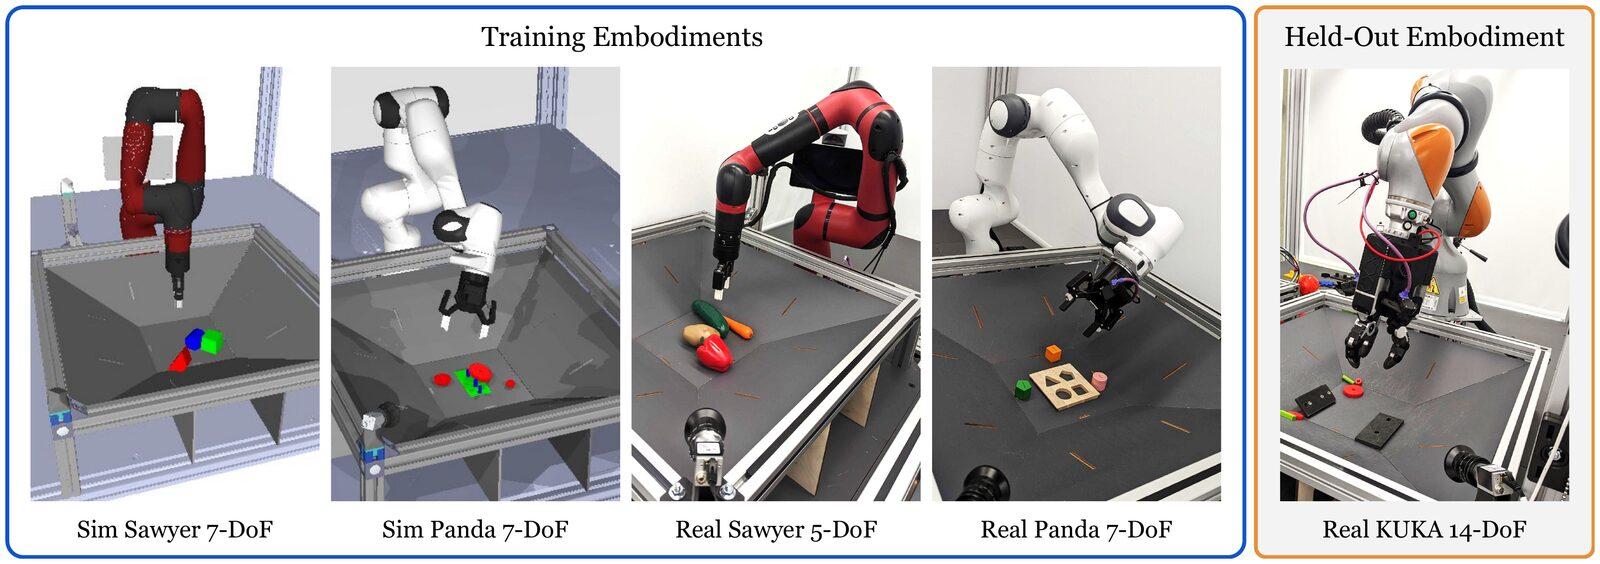
An adaptation budget is part of a foundation claim: RoboCat learned Sawyer and Panda arms in training and met the KUKA arm with a three-finger hand only at fine-tuning, from 100 to 1,000 examples. Paper figure: Konstantinos Bousmalis et al. / arXiv. Licence: CC BY 4.0.Appears on: Foundation Models for Robotics
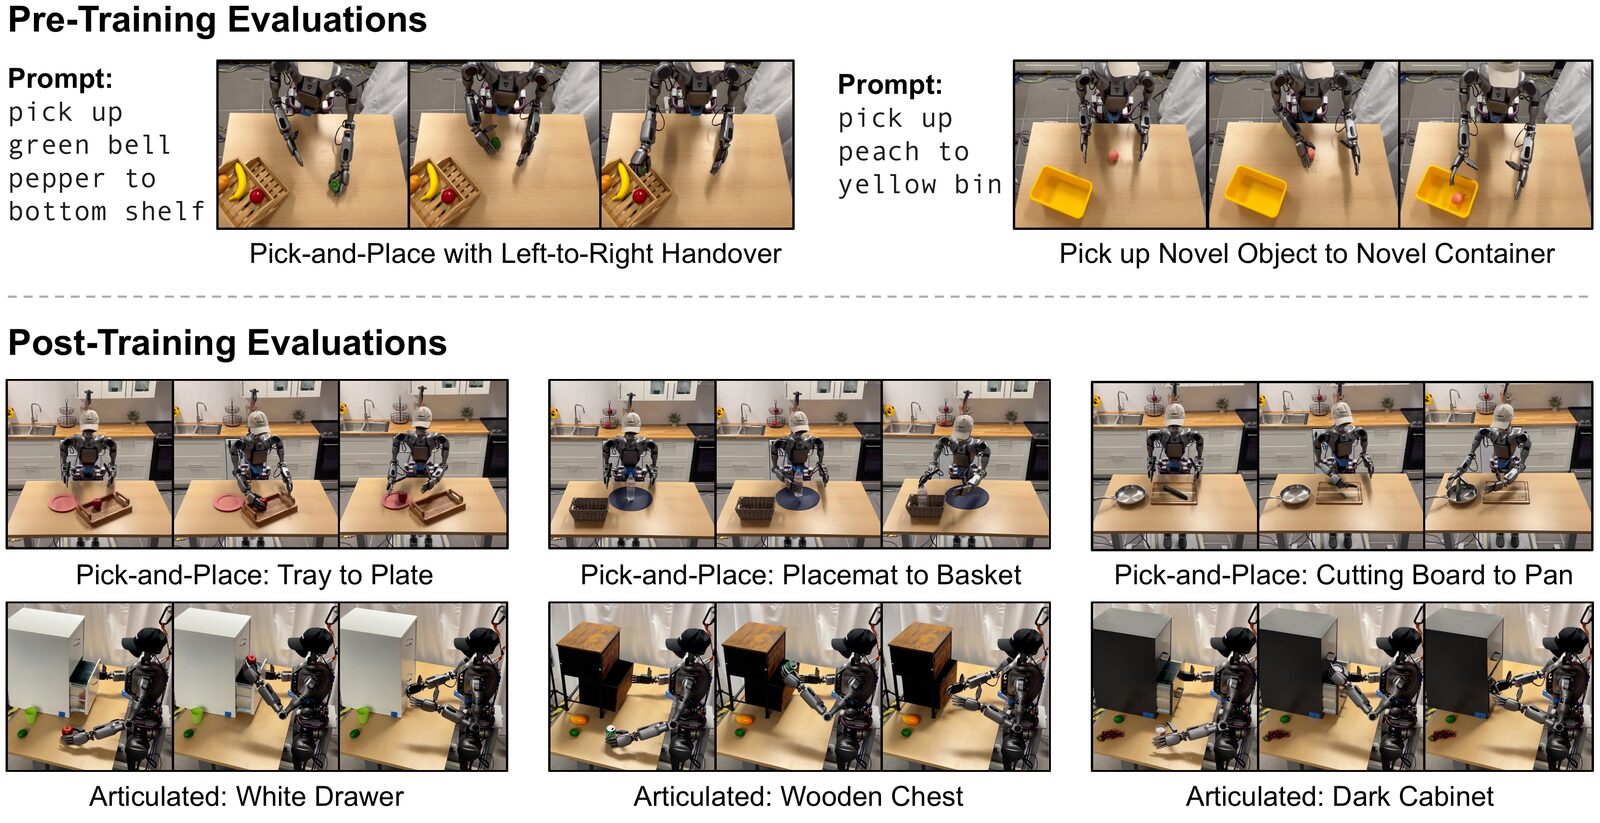
GR00T N1 runs a vision-language model at 10 Hz over a 120 Hz action module on the GR-1 humanoid. Frames from real rollouts: pretraining evaluations (top) and post-trained pick-and-place and articulated-object tasks (bottom). Paper figure: NVIDIA et al. / arXiv. Licence: CC BY 4.0.Appears on: Foundation Models for Robotics, Hierarchical Approaches
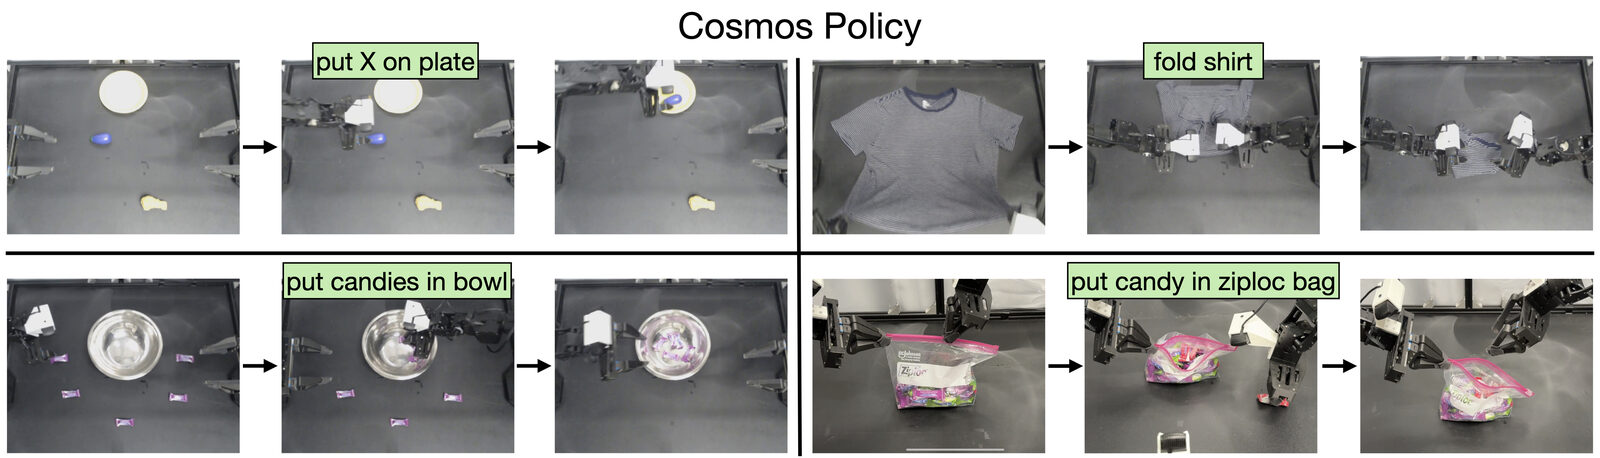
Cosmos Policy fine-tunes a pretrained video model into a robot policy, so a predictive model becomes the controller. Rollouts on four ALOHA tasks, from folding a shirt to putting candy in a zip bag. Paper figure: Moo Jin Kim et al. / arXiv. Licence: CC BY 4.0.Appears on: Foundation Models for Robotics, What Is a World Model?
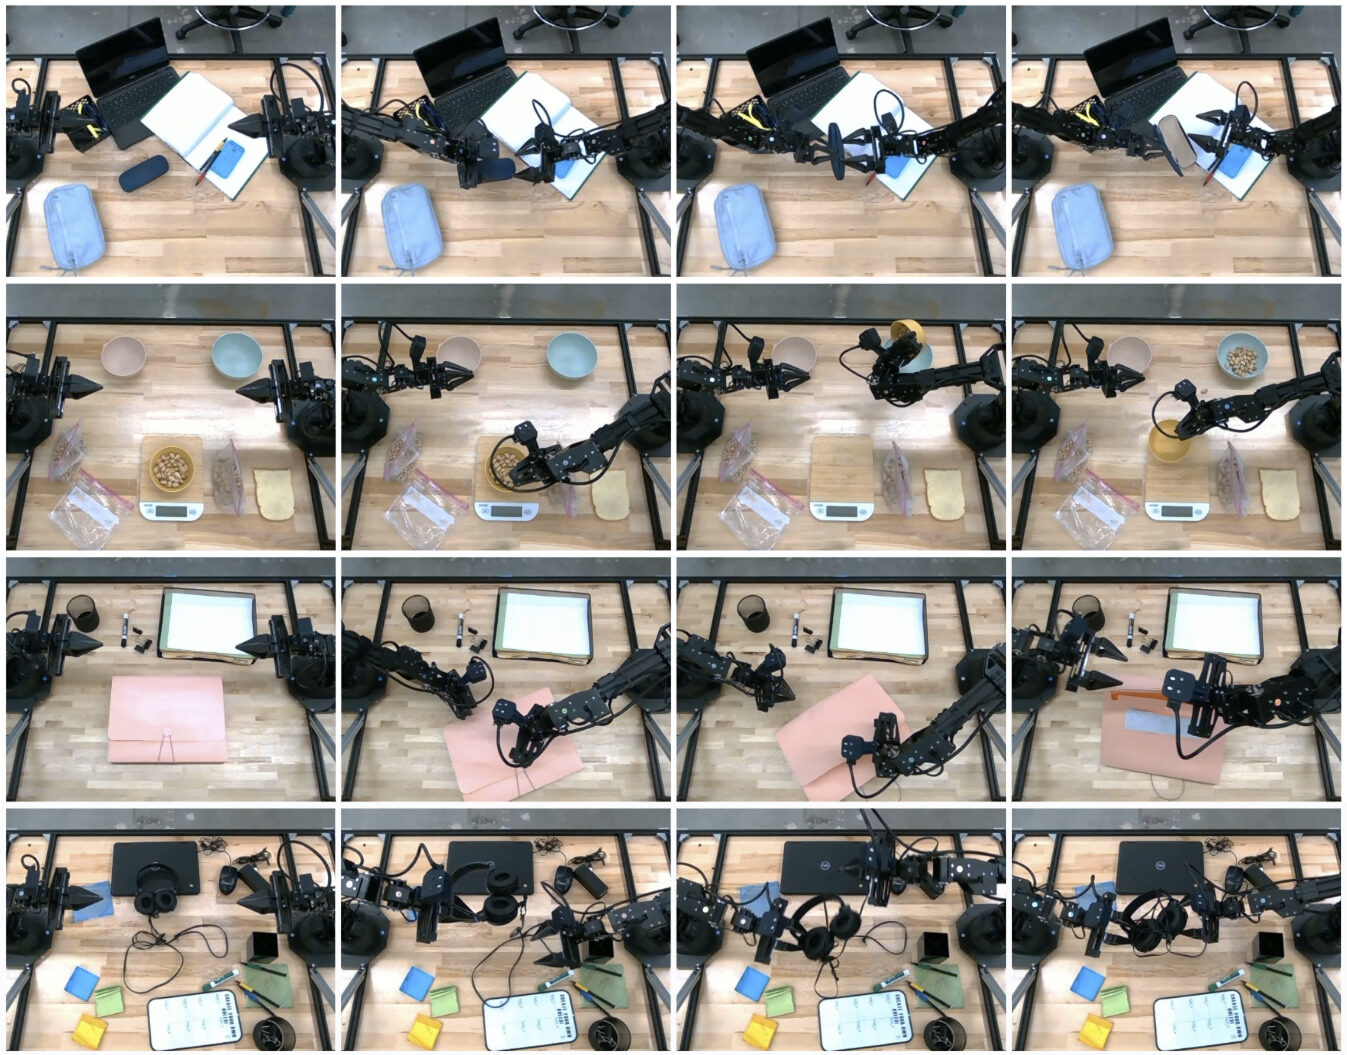
A vision-language-action model performs dexterous bimanual work in clutter. Gemini Robotics on ALOHA, top to bottom: open the eyeglasses case, pour pulses, unfasten a file folder and wrap a headphone wire. Paper figure: Gemini Robotics Team / arXiv. Licence: CC BY 4.0.Appears on: Other Generalist Policies, Vision-Language-Action Models
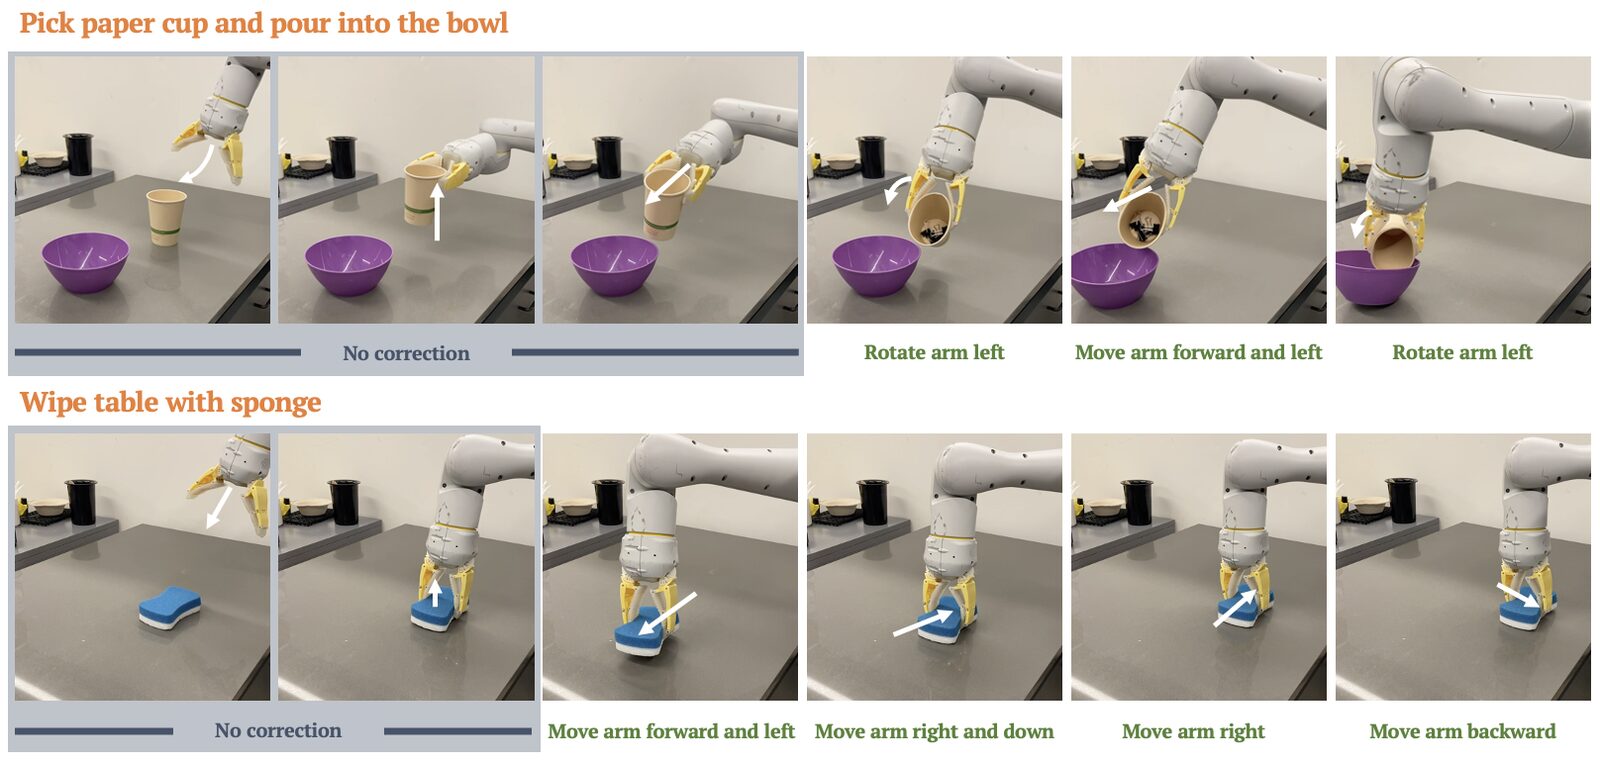
RT-H first predicts a language motion such as "rotate arm left", then the action, so a person can correct the motion in words. Frames from two unseen tasks, with and without such corrections. Paper figure: Suneel Belkhale et al. / arXiv. Licence: CC BY 4.0.Appears on: Hierarchical Approaches
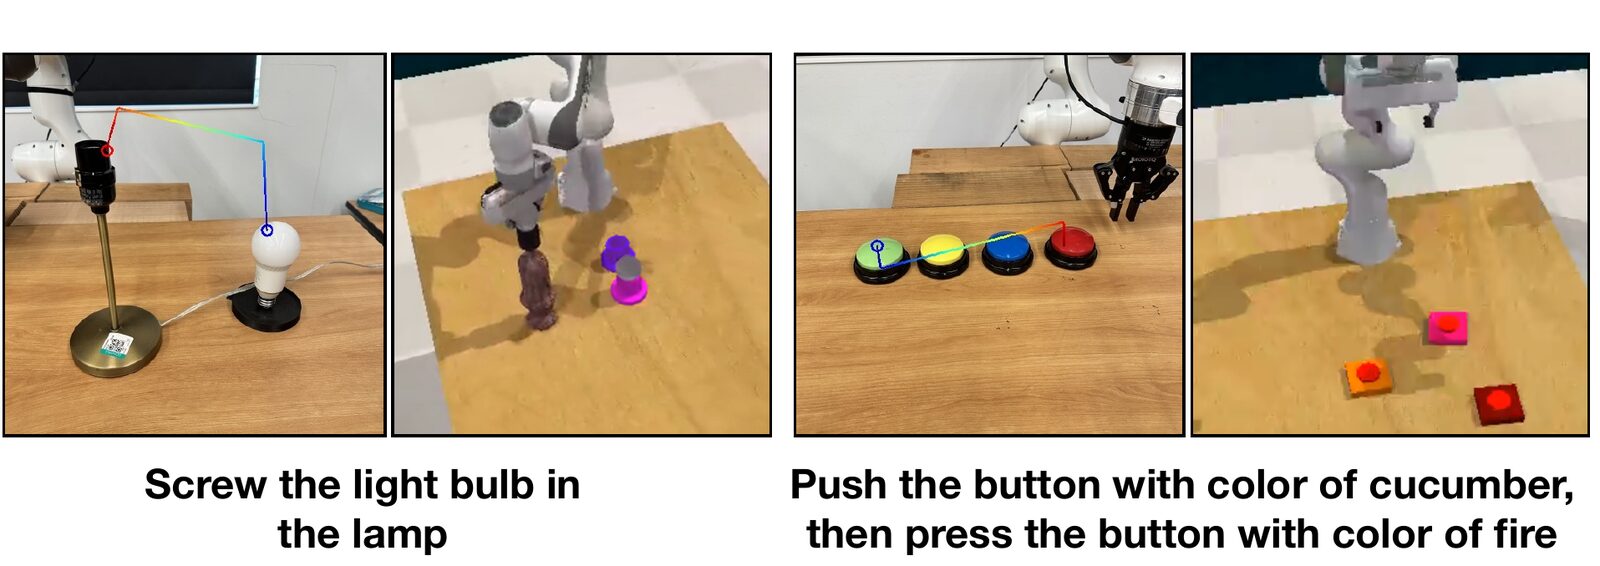
HAMSTER's high level draws a coarse 2D path for the gripper, and a low-level policy turns the path into motion. Paths predicted on real scenes run from blue to red; blue and red circles mark grasp and release. Paper figure: Yi Li et al. / arXiv. Licence: CC BY 4.0.Appears on: Hierarchical Approaches
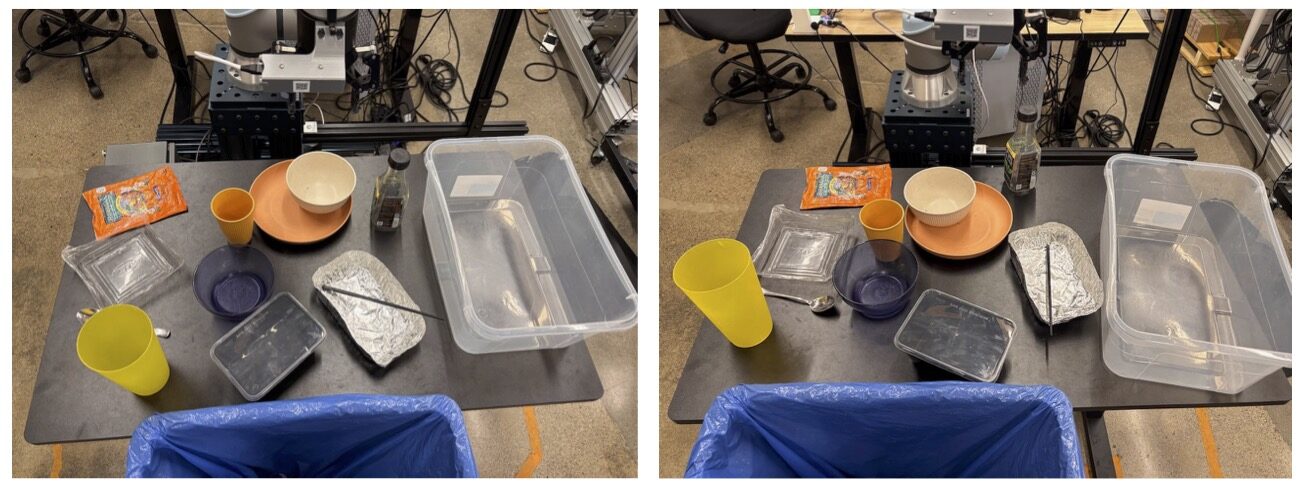
Table bussing is the task behind KI's training-cost result: a many-embodiment π0 generalist needed 7.5 times the training steps of π0.5 with KI to reach similar performance. Frames of the task from the FAST paper. Paper figure: Karl Pertsch et al. / arXiv. Licence: CC BY 4.0.Appears on: Knowledge Insulation
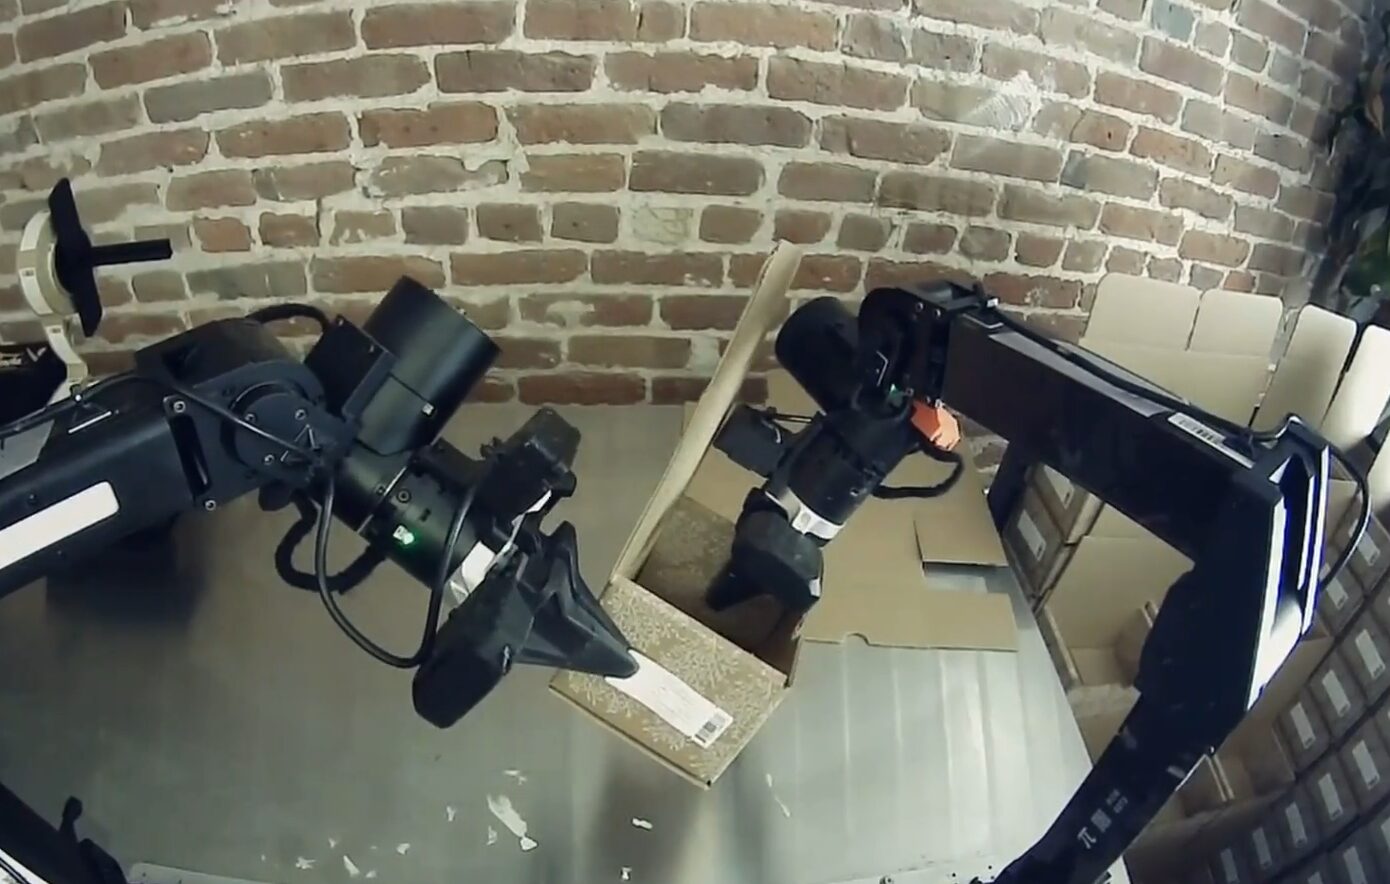
π0.6, whose card lists a Gemma3 4B backbone with an insulated expert of about 860M parameters, building a box. Physical Intelligence used this task to test training-time real-time chunking. Photo: Kevin Black et al. / arXiv. Licence: CC BY 4.0.Appears on: Knowledge Insulation
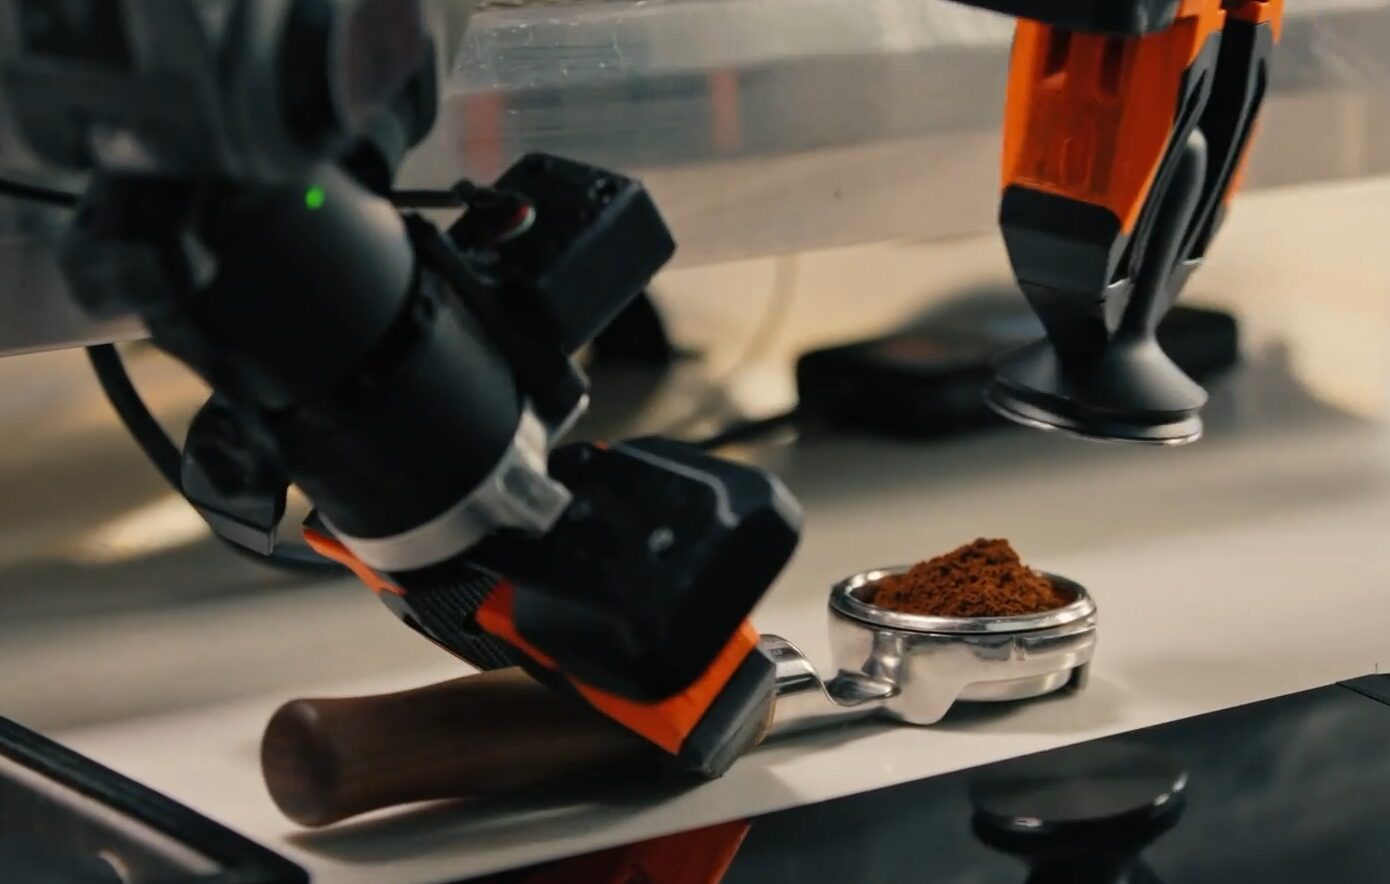
A π0.6 policy making espresso on Physical Intelligence's bimanual rig. The pi line runs one vision-language backbone with a flow-matching action expert across tasks like this one. Photo: Kevin Black et al. / arXiv. Licence: CC BY 4.0.Appears on: The Pi Line
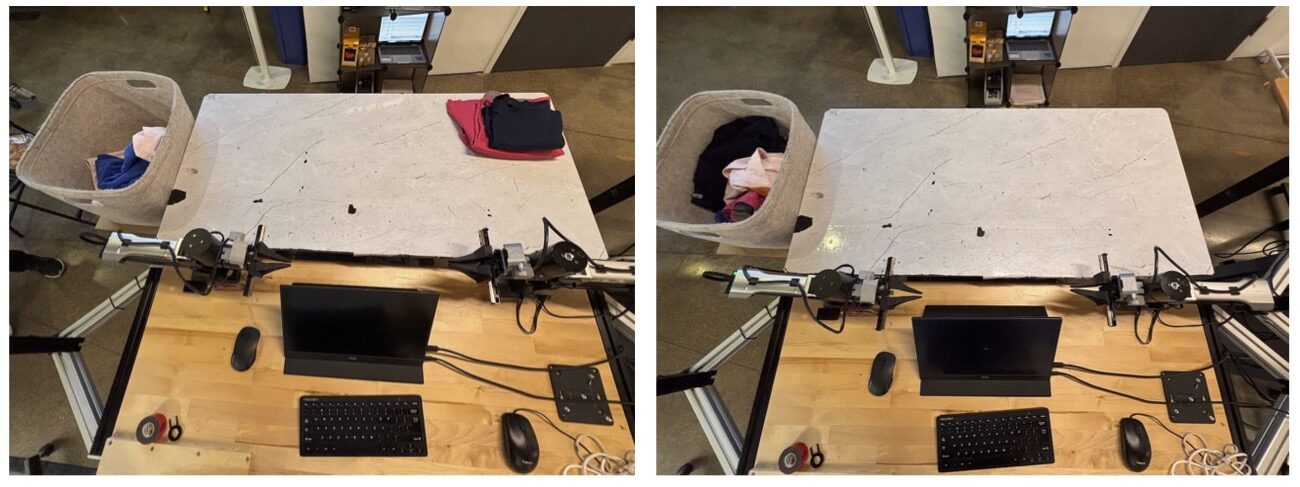
Laundry folding is the kind of high-frequency task FAST was built for: with naive per-step tokens, policies made no progress on T-shirt folding at 50 Hz. Frames of the task from the FAST paper. Paper figure: Karl Pertsch et al. / arXiv. Licence: CC BY 4.0.Appears on: The Pi Line
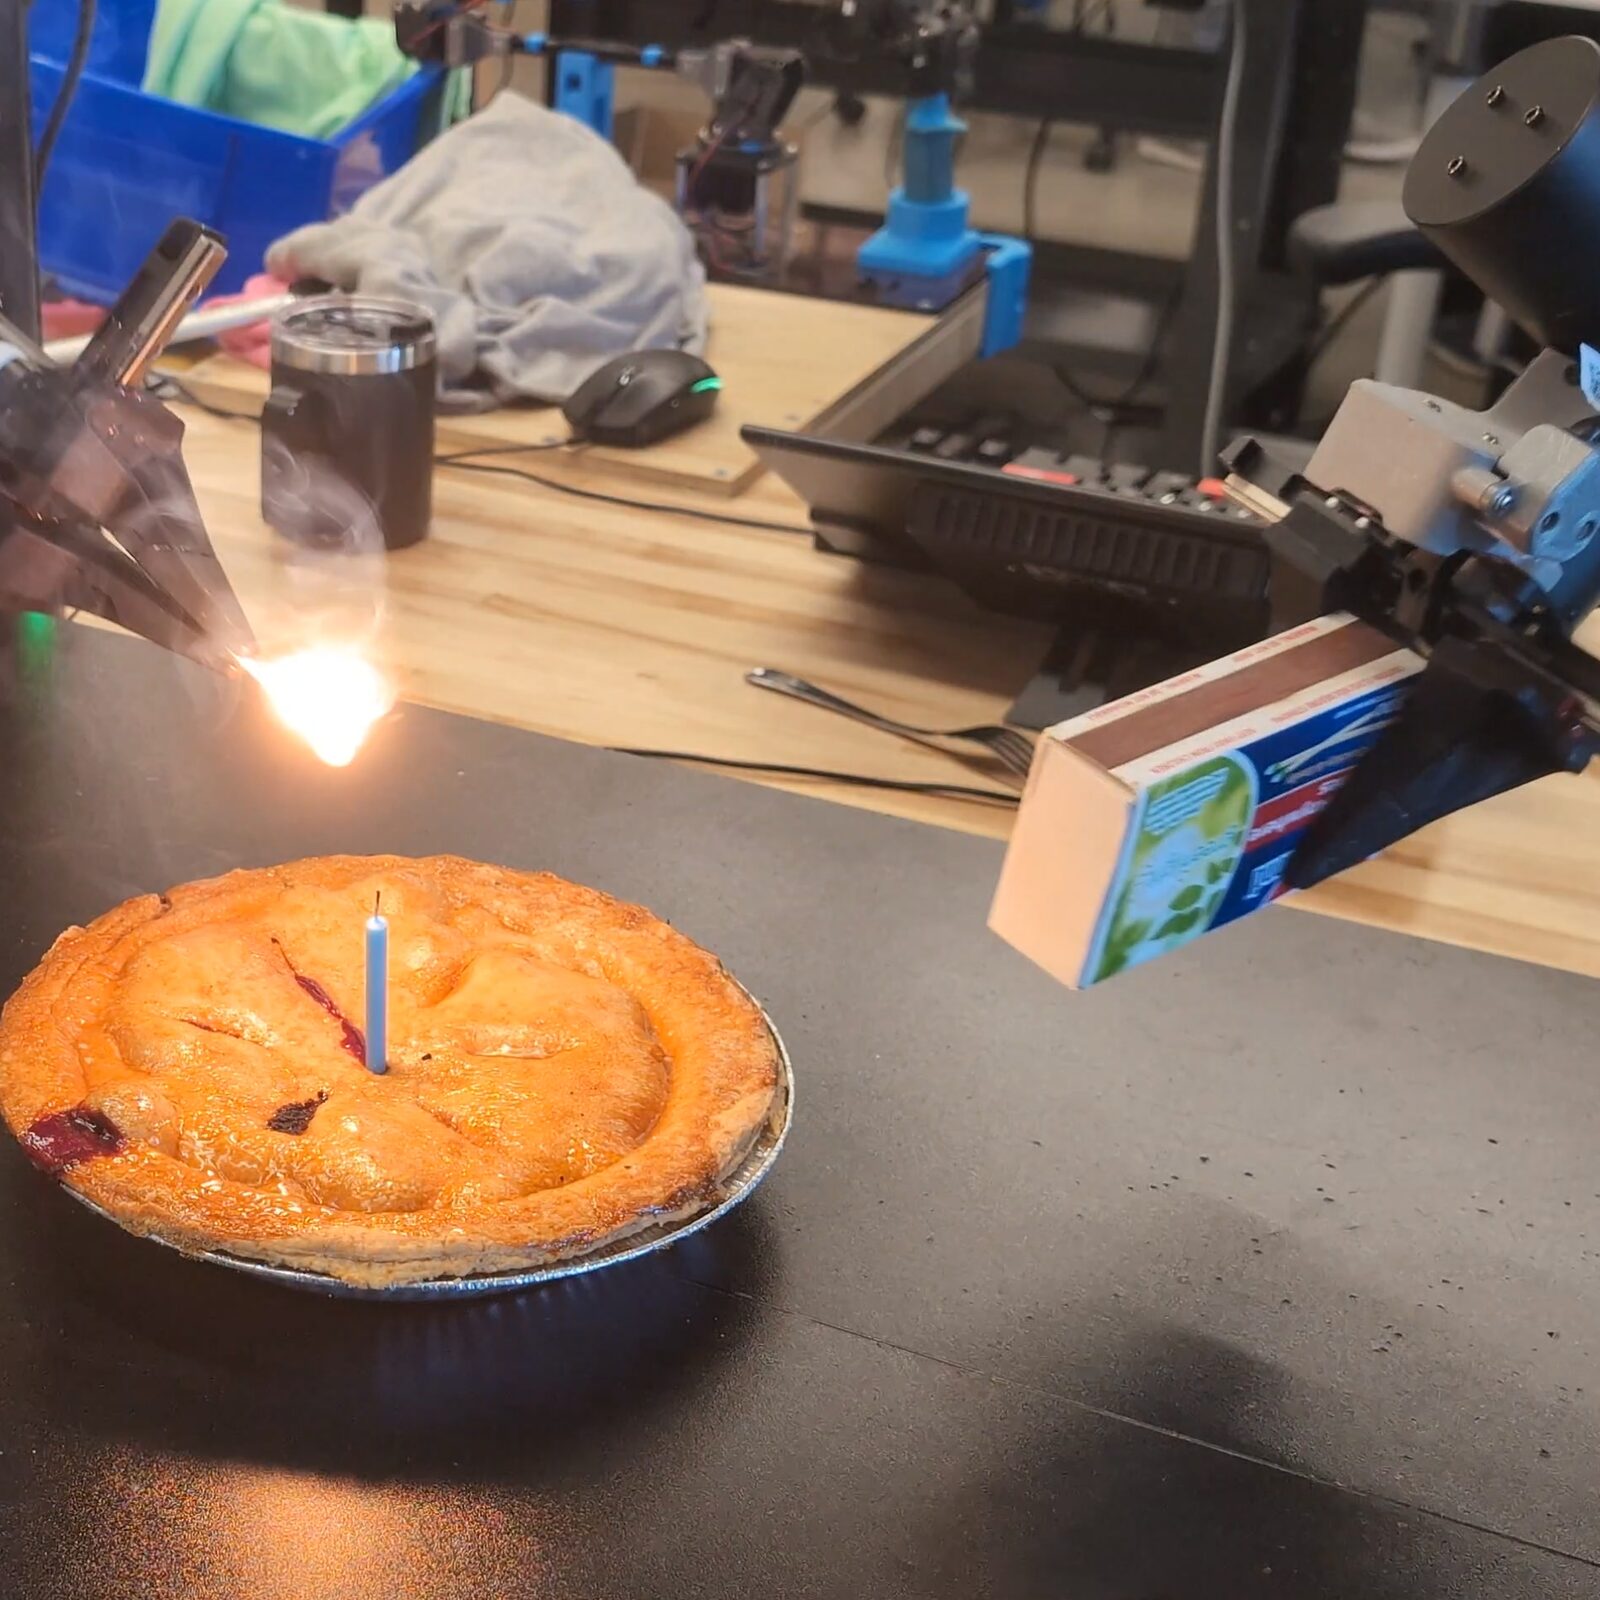
Real-time chunking lets a robot strike a match and light a candle despite inference delays above 300 ms, more than 30% of the model's prediction horizon. A frame from the RTC paper's candle task. Photo: Kevin Black et al. / arXiv. Licence: CC BY 4.0.Appears on: Real-Time Execution
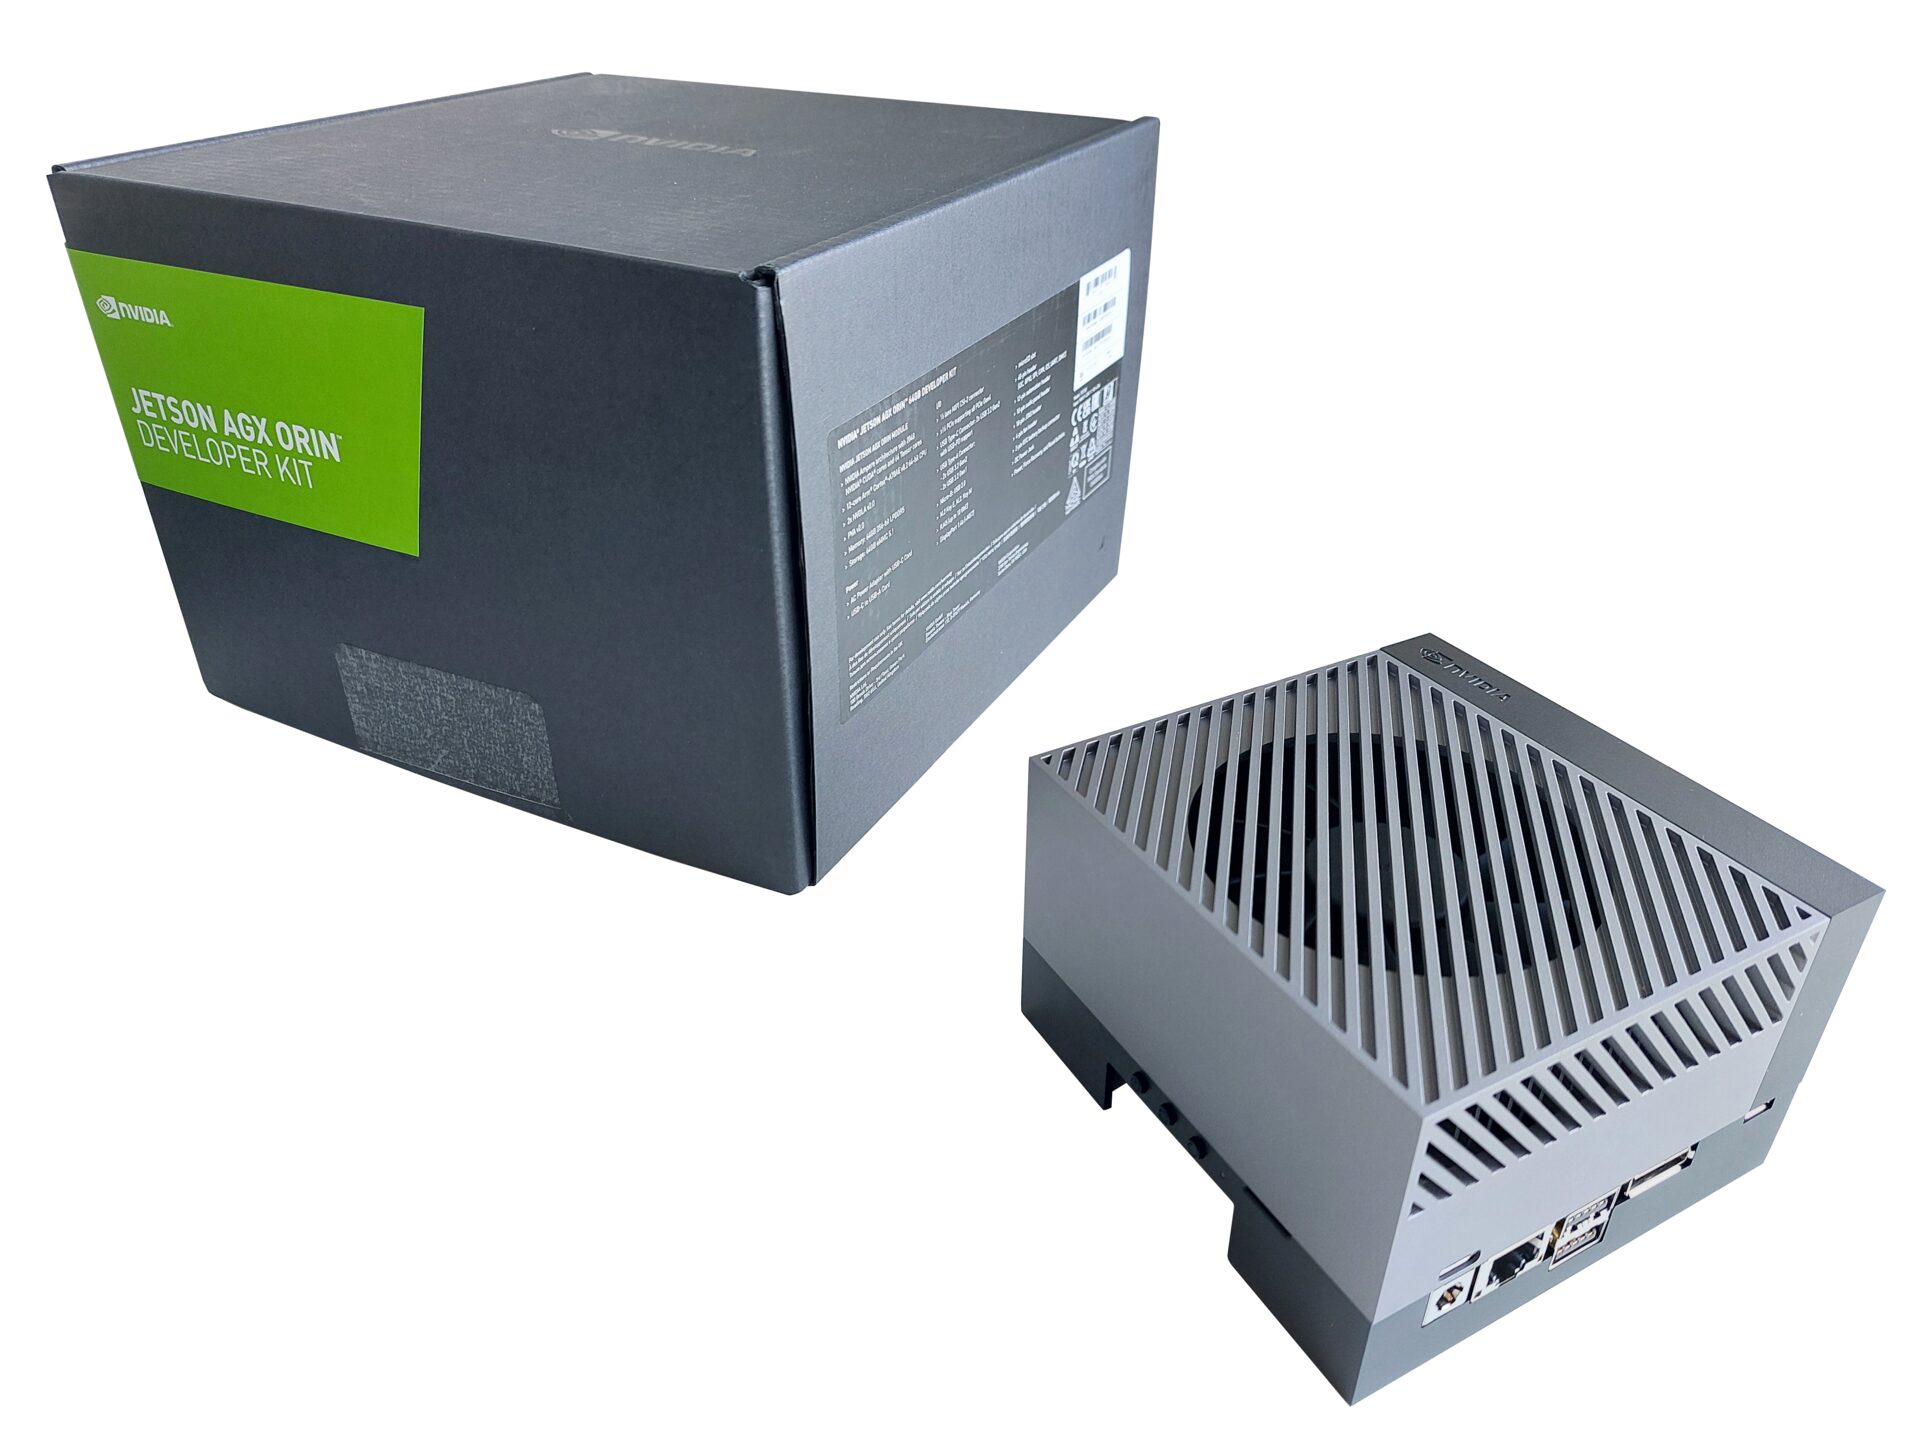
On-robot compute such as the NVIDIA Jetson AGX Orin developer kit sets the hardware wall: a policy that fits a desktop GPU's budget can miss the control tick here. Photo: Auledas / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Hardware Taxonomy, Real-Time Execution
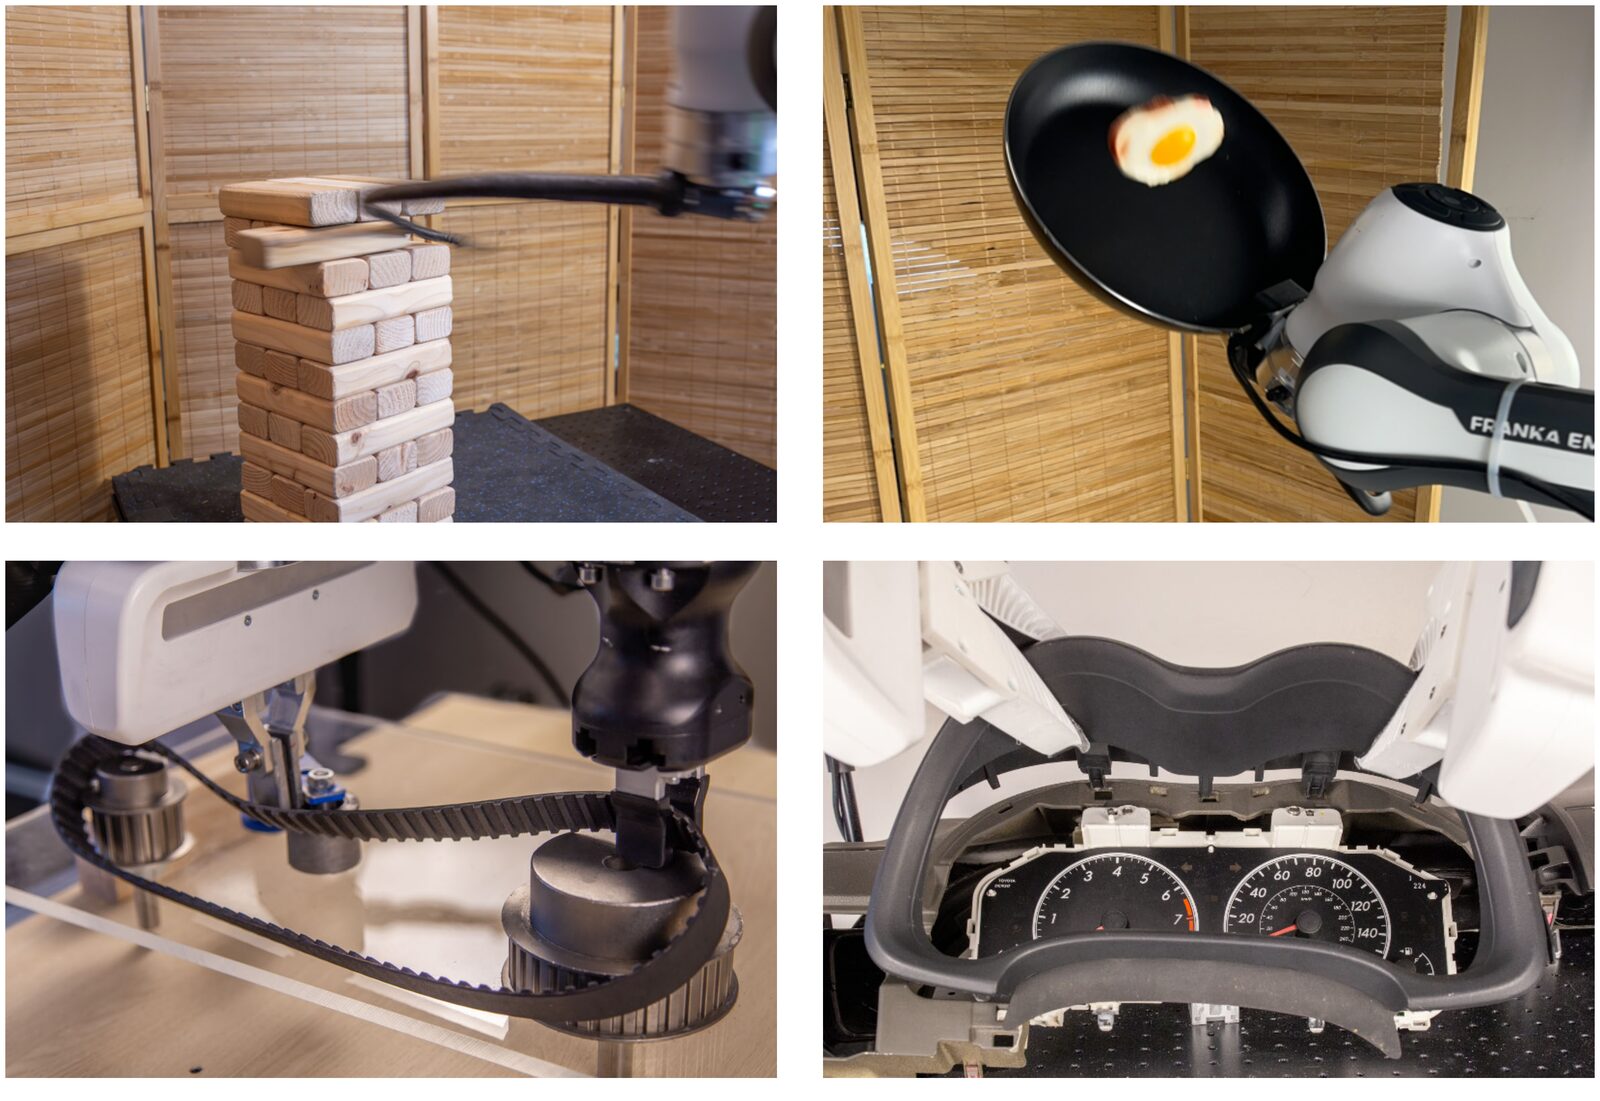
Reinforcement learning on the real robot reaches precise, dynamic skills that demonstrations alone struggle with. Four of the HIL-SERL tasks: Jenga whipping, object flipping in a pan, timing-belt assembly and dashboard assembly. Paper figure: Jianlan Luo et al. / arXiv. Licence: CC BY 4.0.Appears on: RL Fine-Tuning of Policies
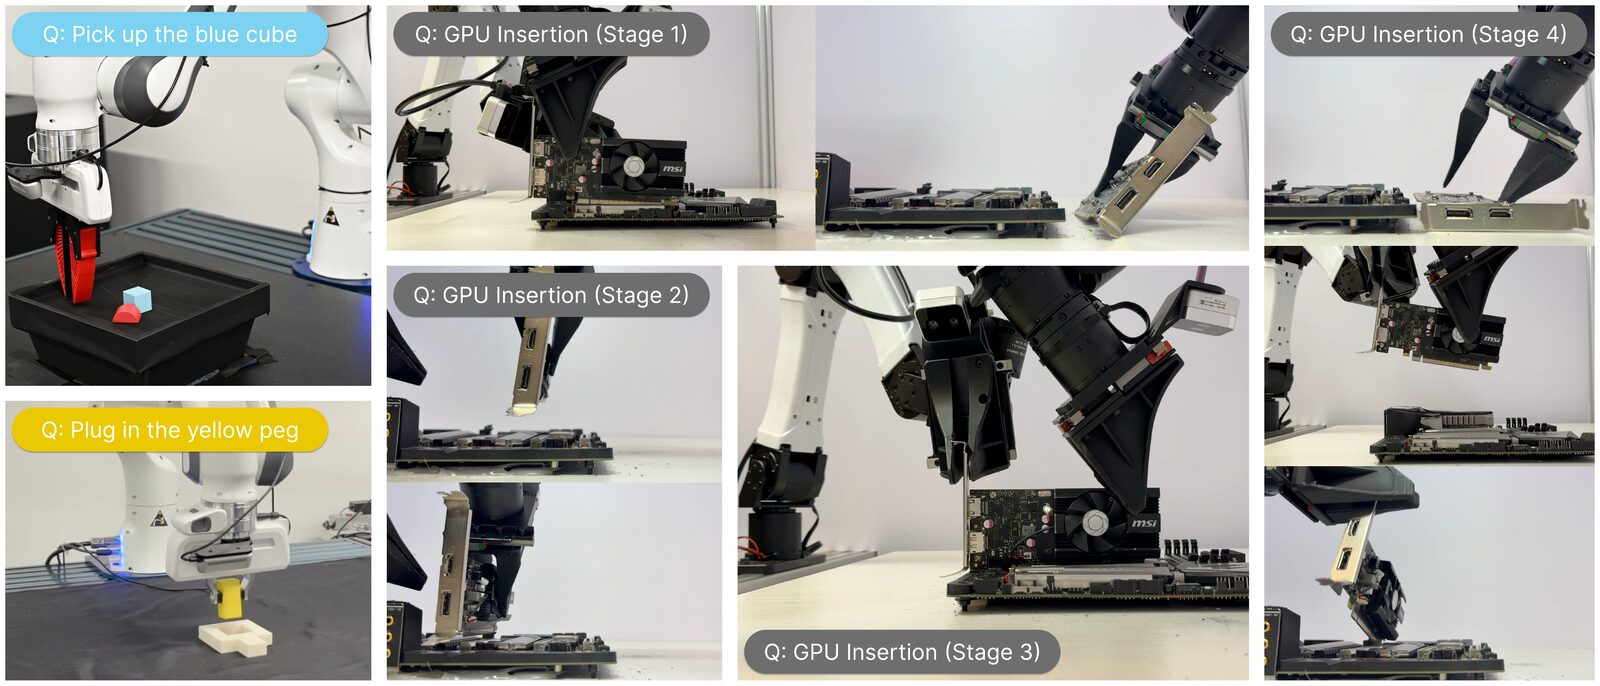
PLD trains a residual RL policy on top of a frozen VLA and distills the improved behavior back into it. On bimanual YAM arms the result ran GPU insertion and unplugging for a continuous hour without human resets. Paper figure: Wenli Xiao et al. / arXiv. Licence: CC BY 4.0.Appears on: RL Fine-Tuning of Policies
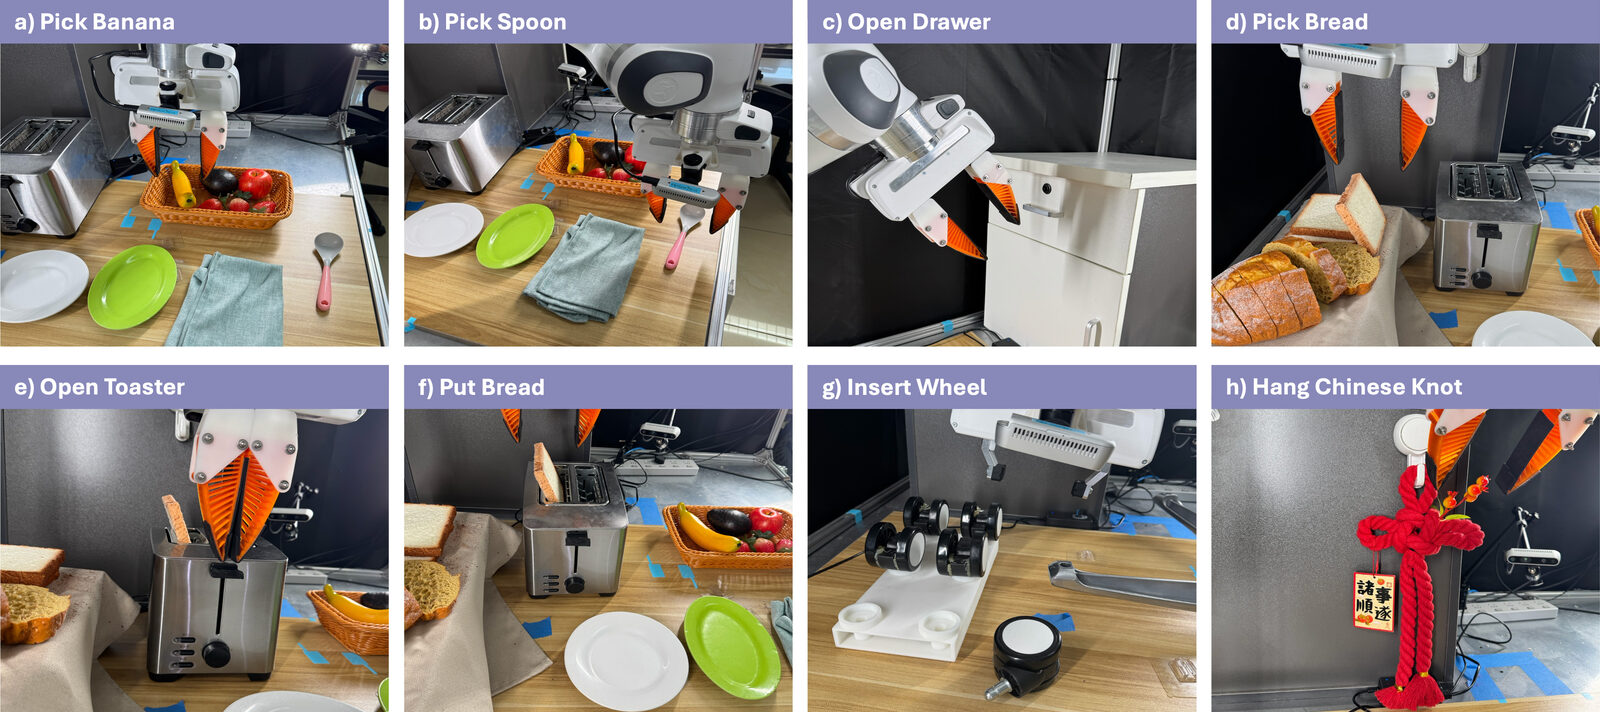
ConRFT fine-tunes a VLA with real-world reinforcement learning across eight contact-rich tasks, from picking a banana to inserting a chair wheel and hanging a Chinese knot. Paper figure: Yuhui Chen et al. / arXiv. Licence: CC BY 4.0.Appears on: RL Fine-Tuning of Policies
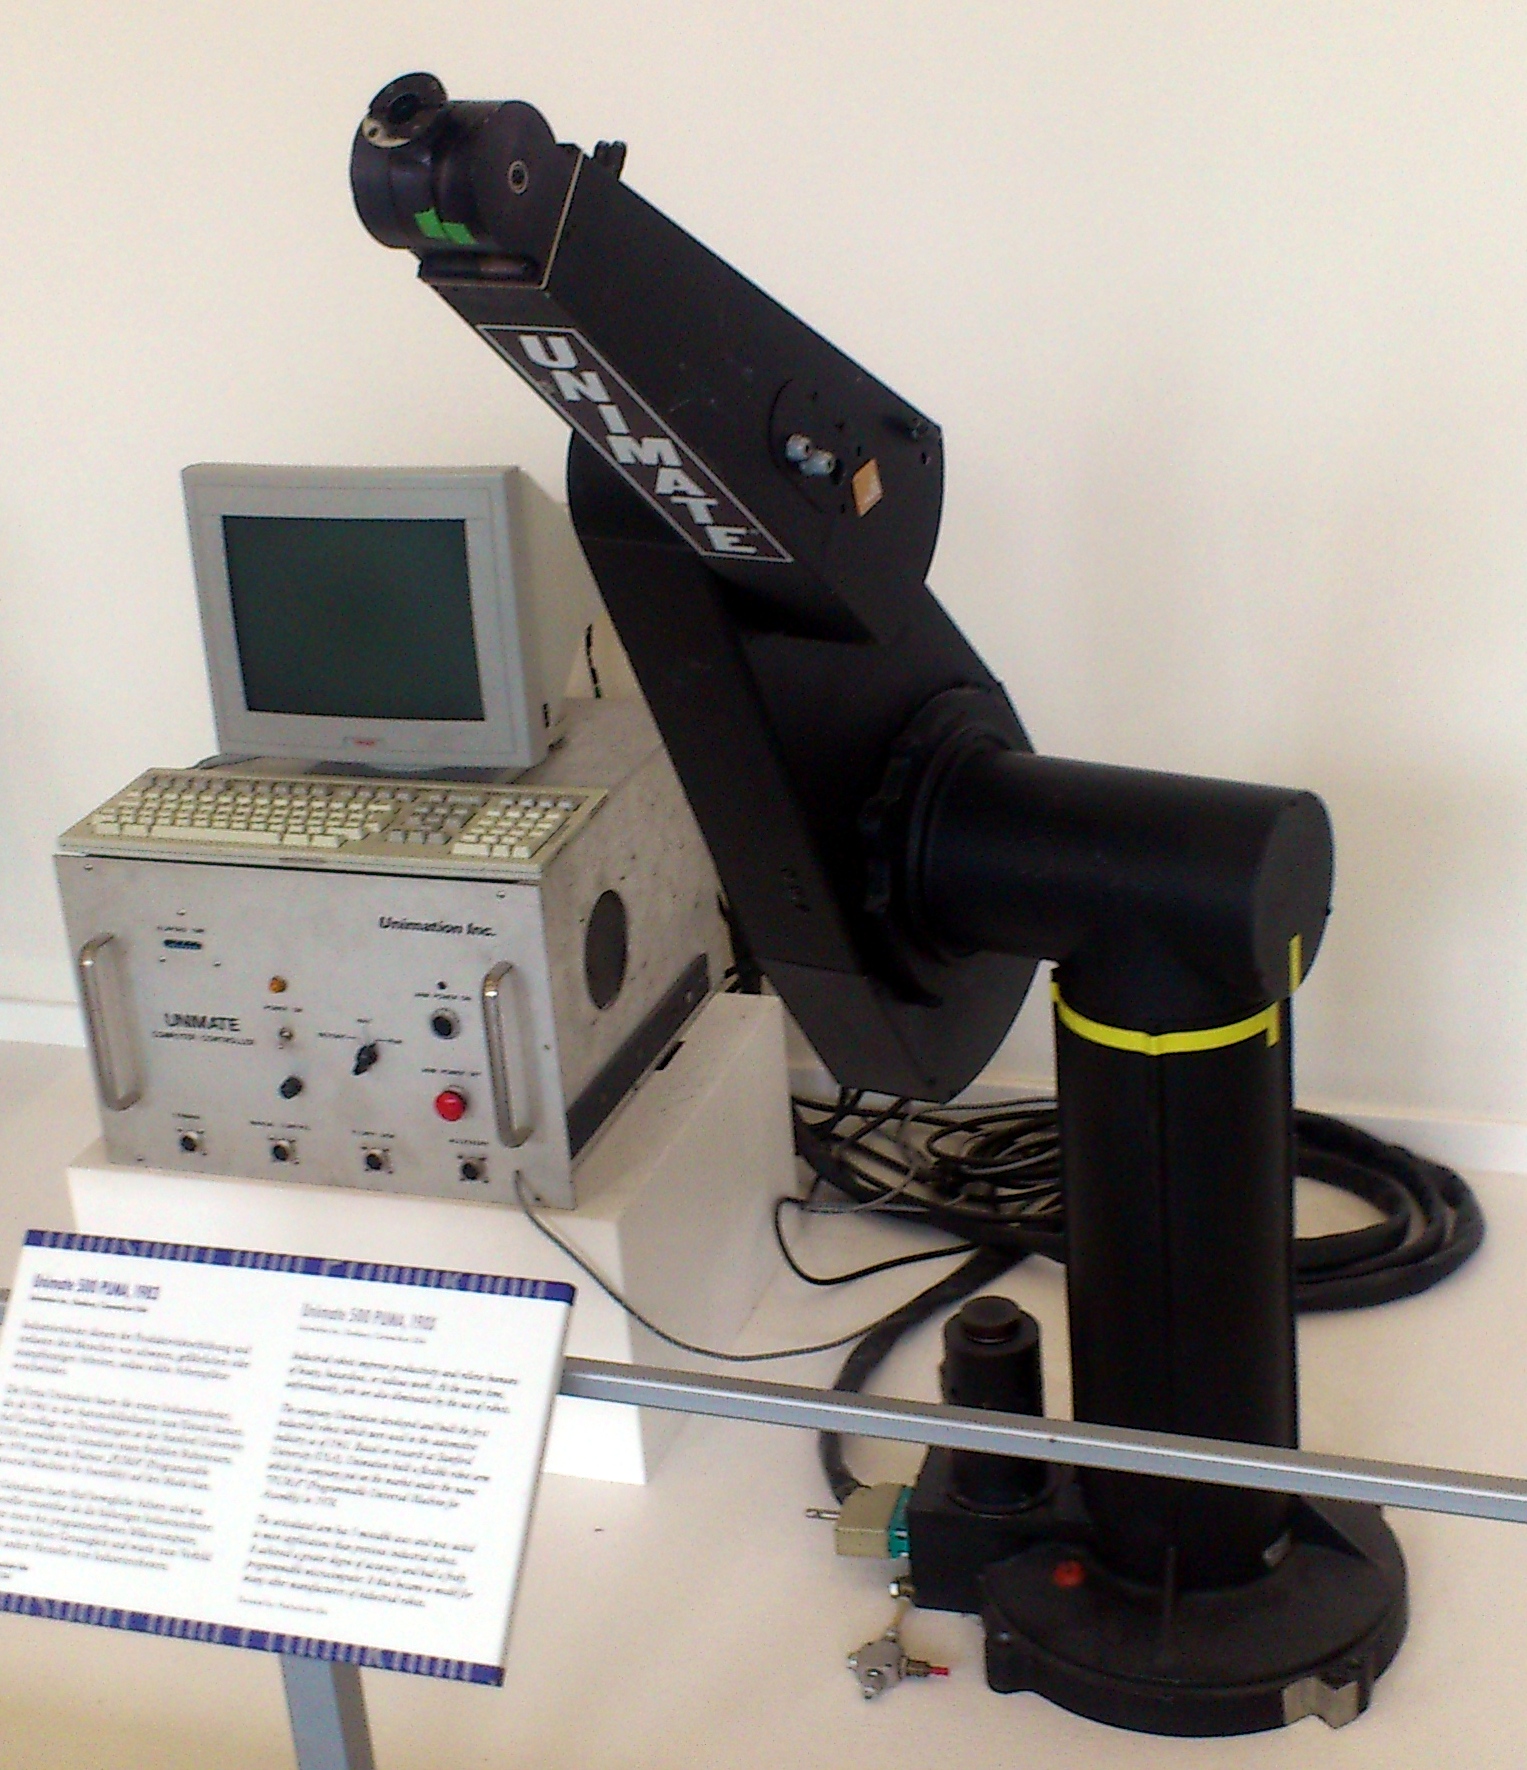
Every learned policy still runs through coordinate frames like those of this Unimate PUMA 500 (1983), an industrial arm whose kinematics became the textbook example. Exhibit at the Deutsches Museum, Munich. Photo: Theoprakt / Wikimedia Commons. Licence: CC BY-SA 3.0.Appears on: Robot Learning Curriculum for ML Engineers
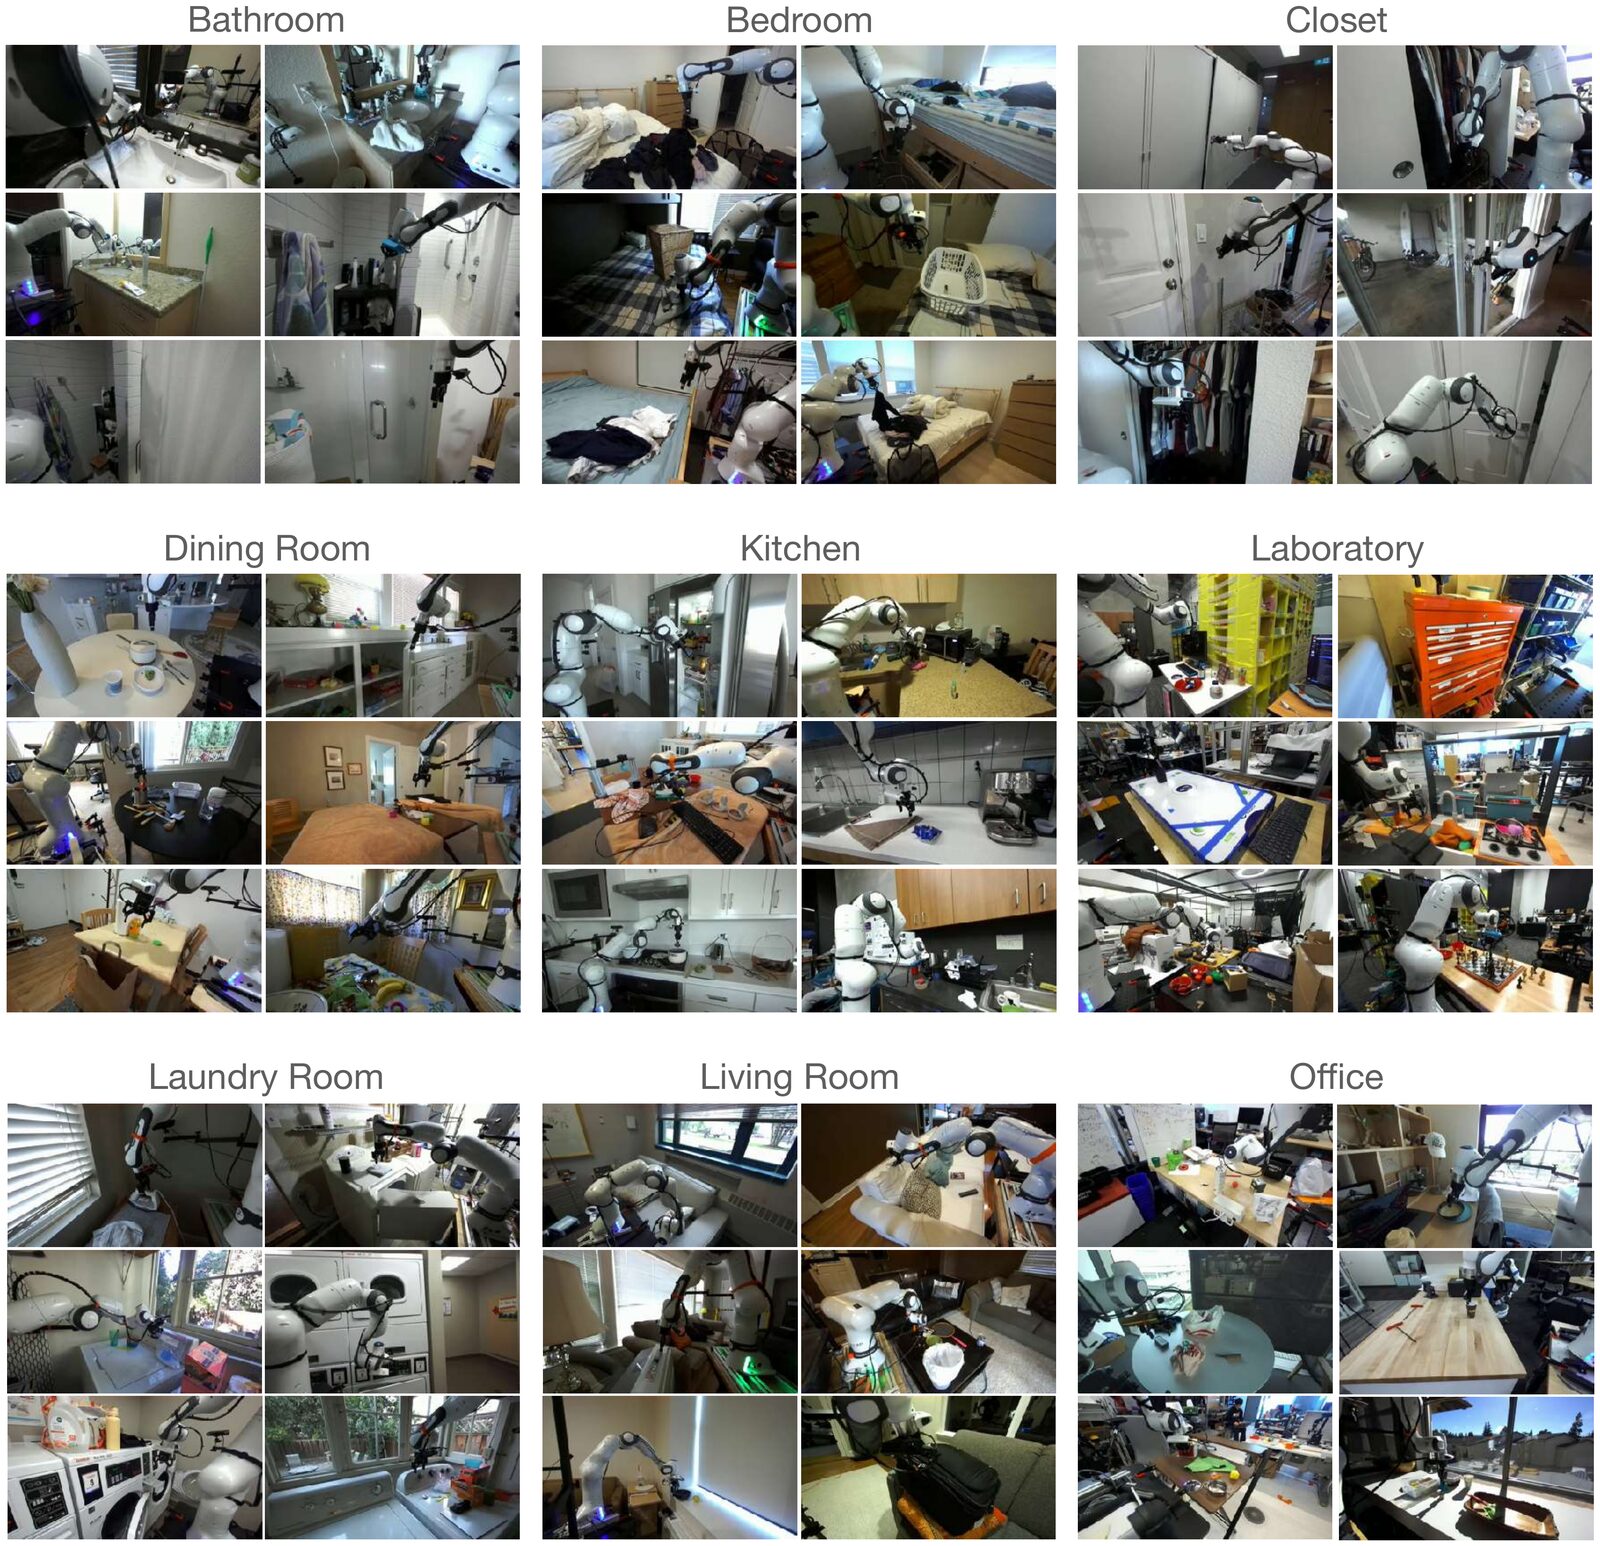
Frames from DROID grouped into its 9 scene types. The same Franka setup recorded every trajectory, in kitchens, bedrooms, offices and other real buildings. Paper figure: Alexander Khazatsky et al. / arXiv. Licence: CC BY 4.0.Appears on: The Data Bottleneck, Robot Learning Curriculum for ML Engineers
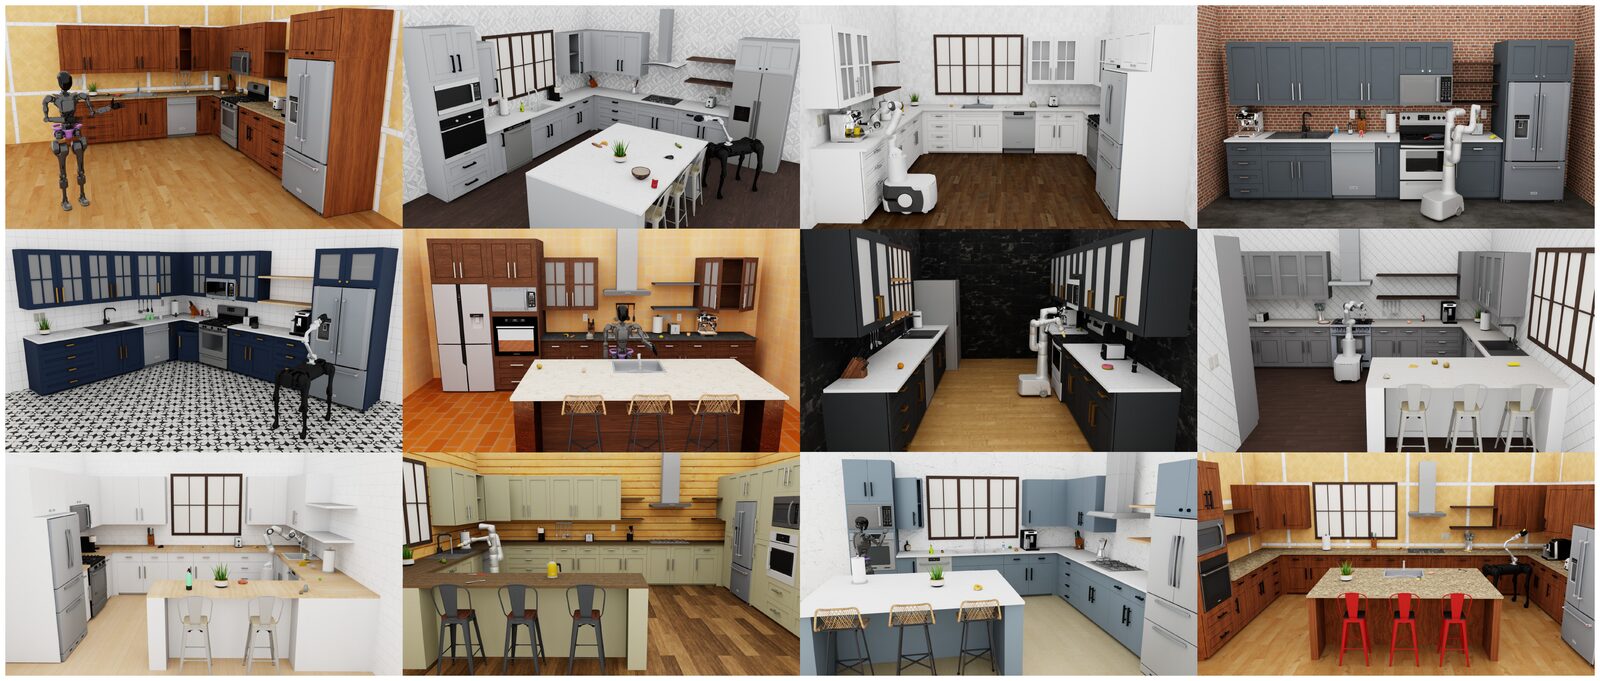
Simulation lets a team test policies across many environments before touching hardware. Rendered RoboCasa kitchens, each holding a simulated robot among varied layouts and styles. Paper figure: Soroush Nasiriany et al. / arXiv. Licence: CC BY 4.0.Appears on: Robot Learning Curriculum for ML Engineers, Generative Simulation
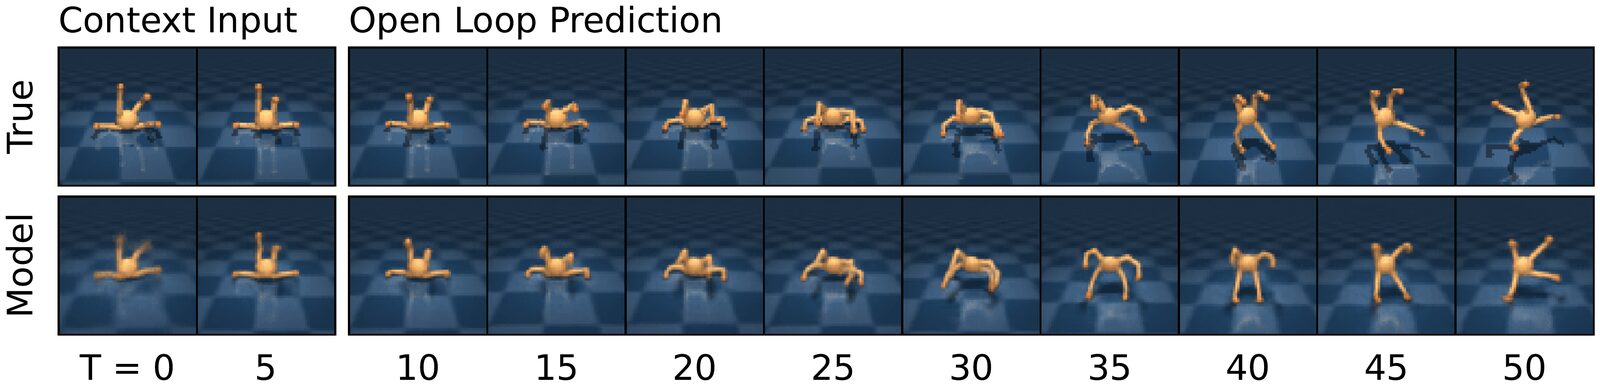
A world model predicts how an environment evolves under actions. From 5 context frames and the actions alone, DreamerV3 predicts 45 frames of a simulated quadruped; the model row tracks the true row. Paper figure: Danijar Hafner et al. / arXiv. Licence: CC BY 4.0.Appears on: What Is a World Model?
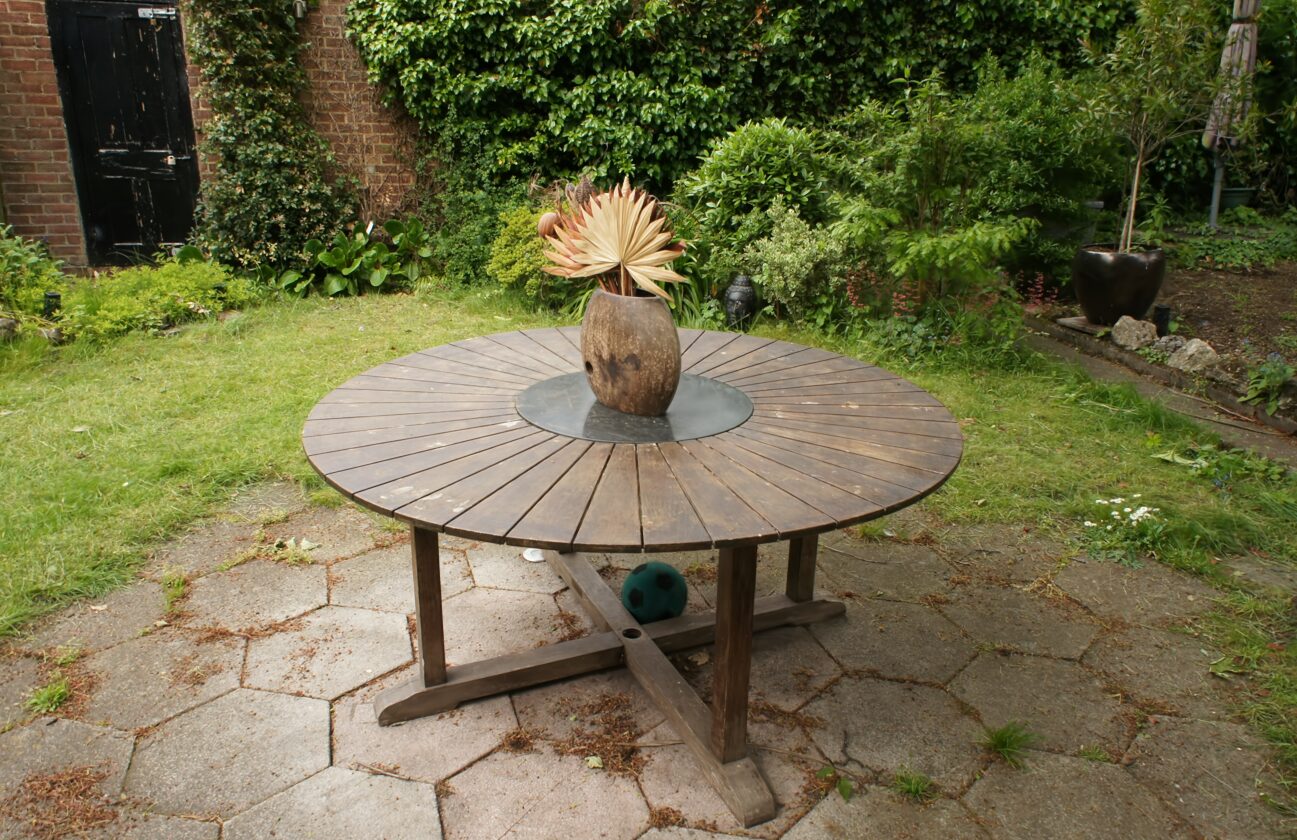
A 3D Gaussian Splatting reconstruction is a learned renderer: it predicts a real scene from a new camera pose by rasterising the fitted Gaussians. A garden scene rendered by the original method. Paper figure: Bernhard Kerbl et al. / arXiv. Licence: CC BY 4.0.Appears on: What Is a World Model?, World Models vs Physics Simulators
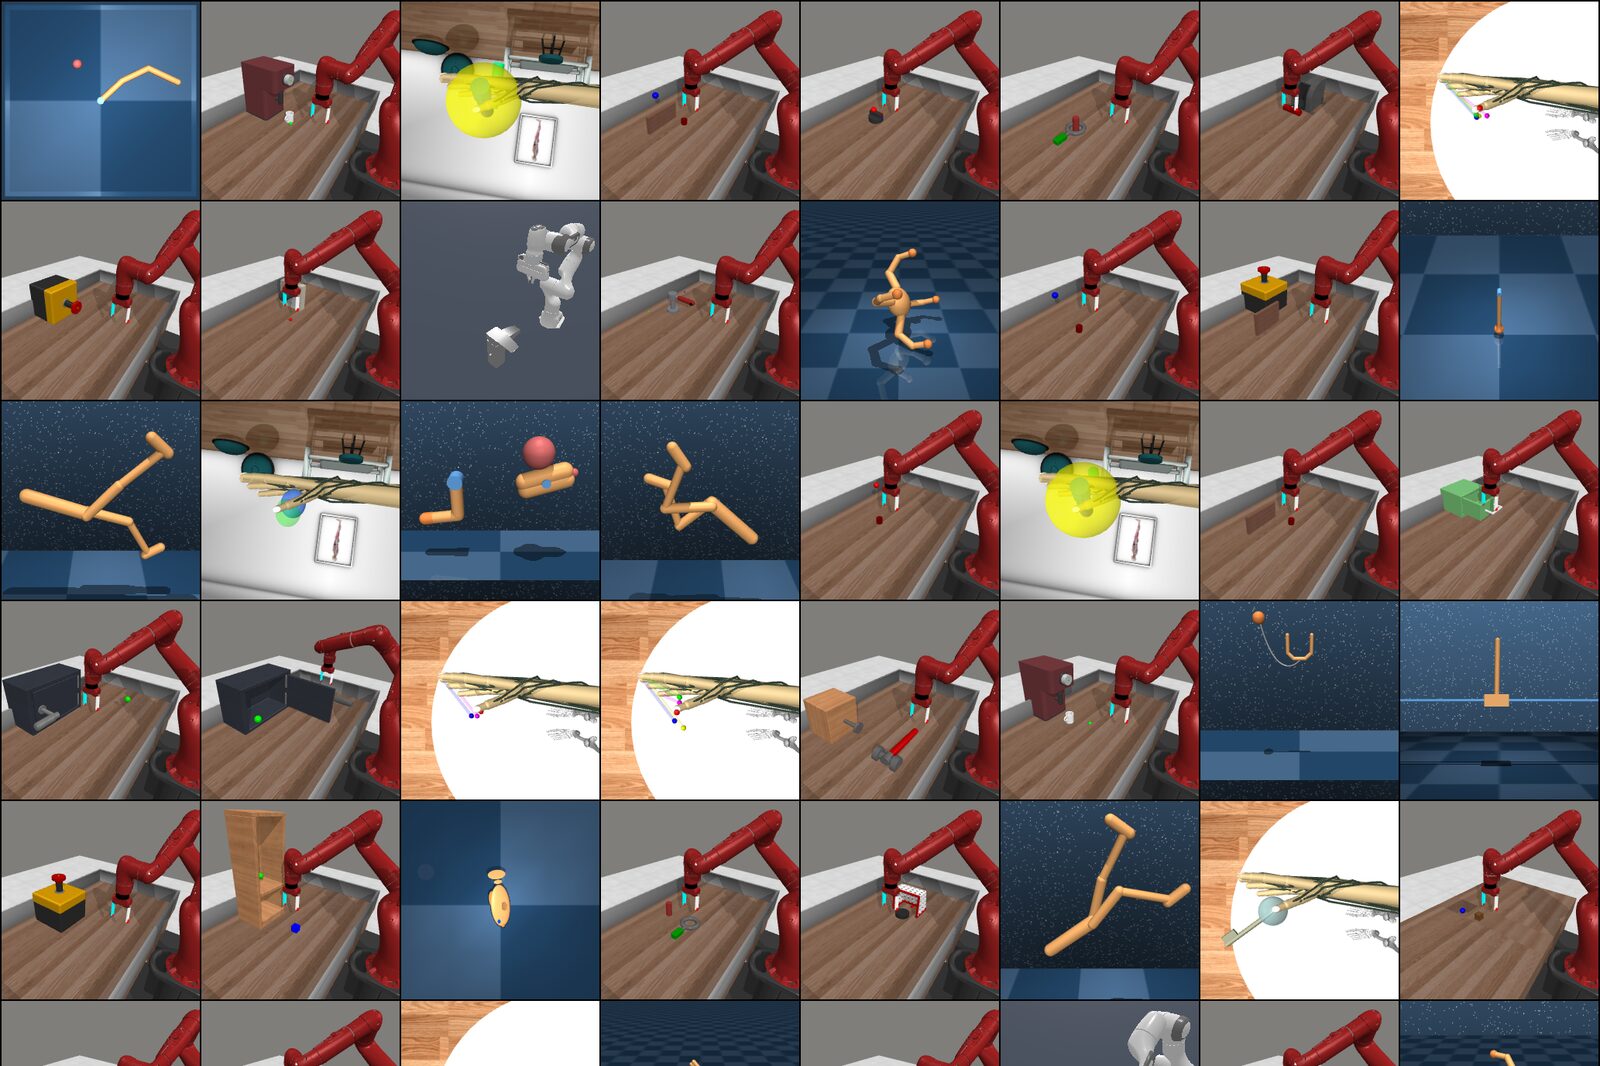
Latent dynamics models learn a compact state and plan or train inside it. TD-MPC2 plans through such a model with no image decoder; these are initial states from its 104 continuous-control tasks. Paper figure: Nicklas Hansen et al. / arXiv. Licence: CC BY 4.0.Appears on: Latent-Dynamics World Models
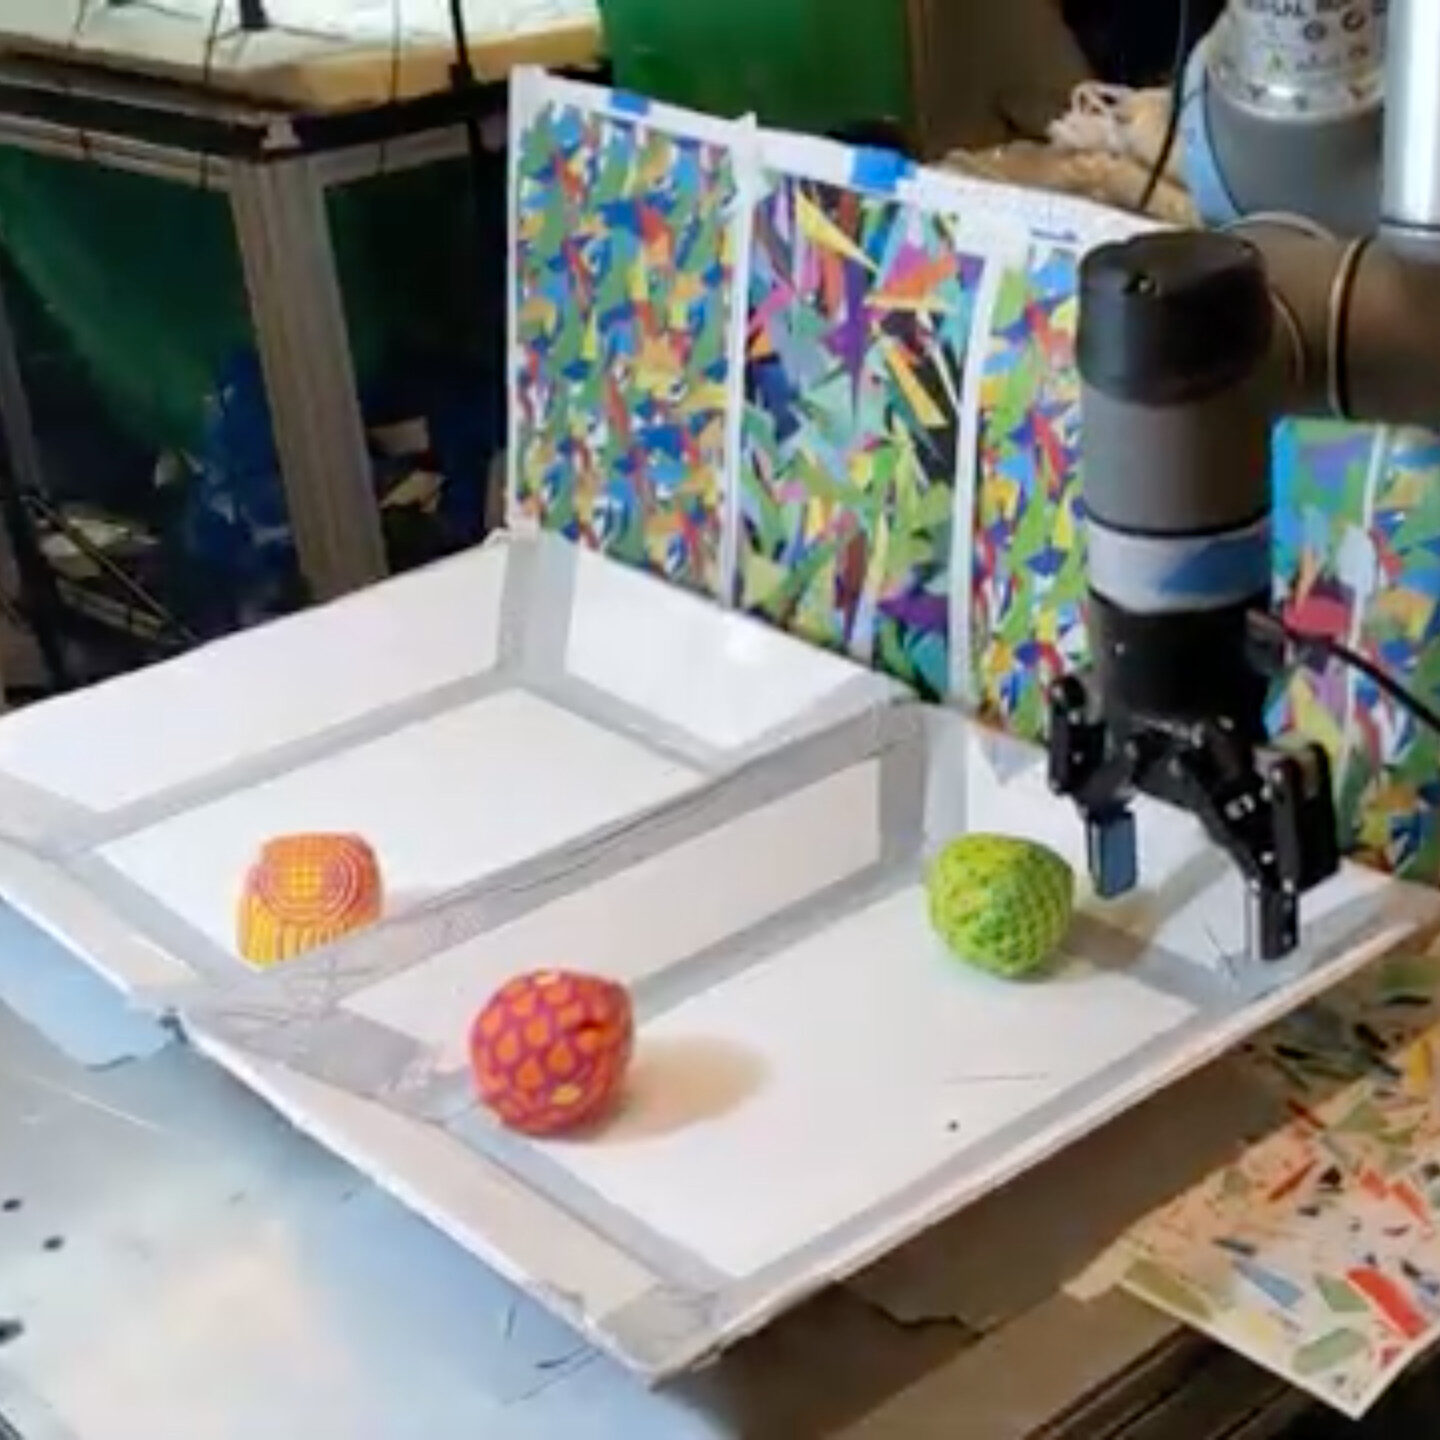
DayDreamer's UR5 learned multi-object visual pick and place from third-person camera images and sparse rewards within a few hours of autonomous operation, training a Dreamer world model on the real robot without a simulator. Photo: Philipp Wu et al. / arXiv. Licence: CC BY 4.0.Appears on: Latent-Dynamics World Models
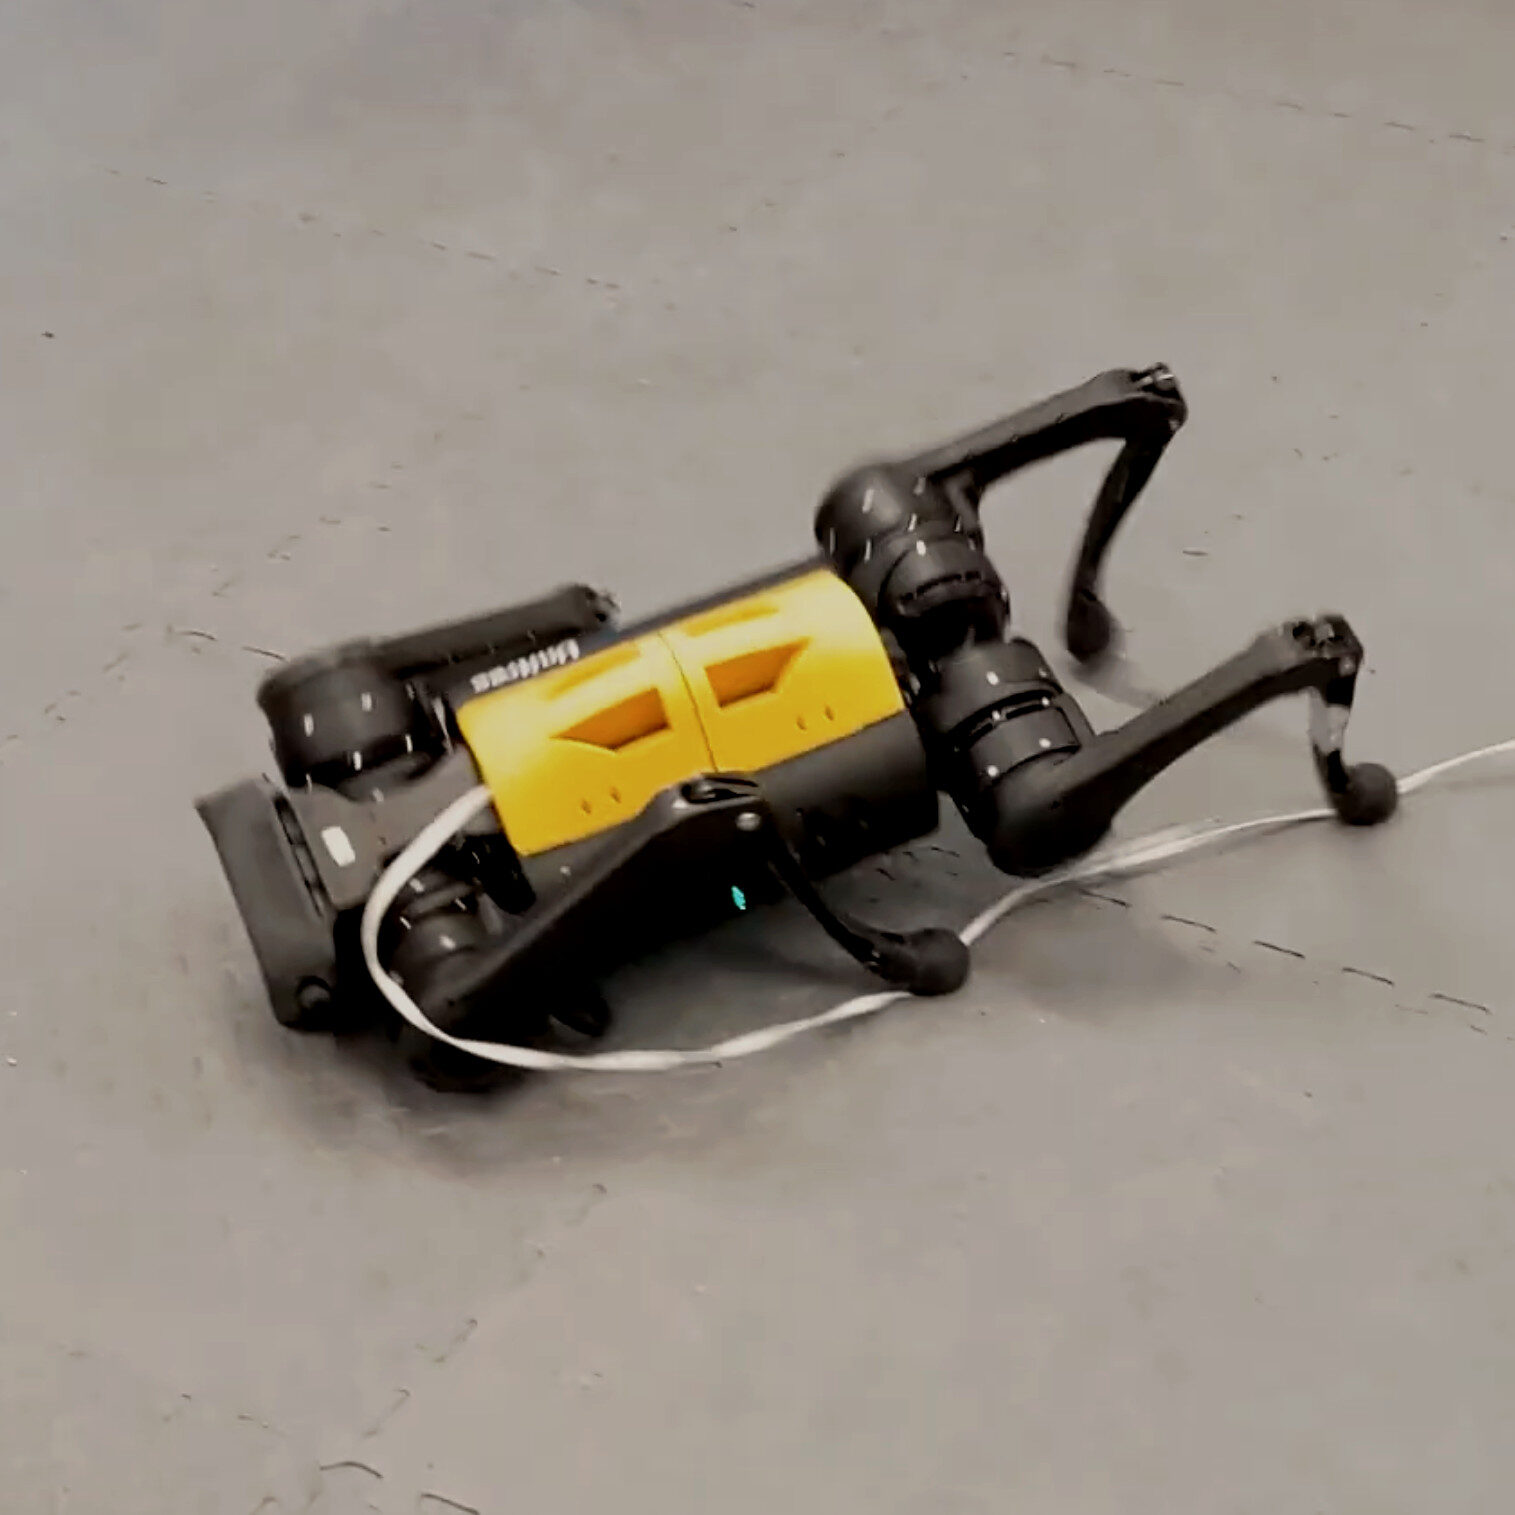
With a Dreamer-style world model, a Unitree A1 that started on its back learned to roll over, stand up and walk in about one hour of real-world training. A frame from the DayDreamer experiment. Photo: Philipp Wu et al. / arXiv. Licence: CC BY 4.0.Appears on: Model-Based Robot Learning
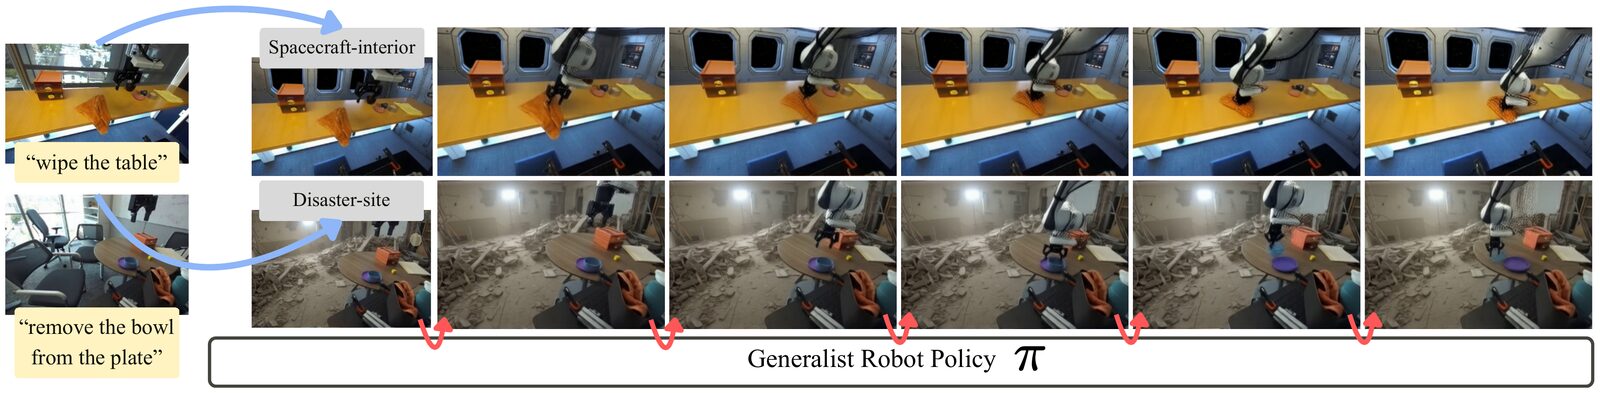
A neural simulator can stage scenes no lab has. RoboWorld turns real robot images into spacecraft interiors and disaster sites and runs closed-loop policy evaluation inside the generated rollouts. Paper figure: Byeongguk Jeon et al. / arXiv. Licence: CC BY 4.0.Appears on: Model-Based Robot Learning
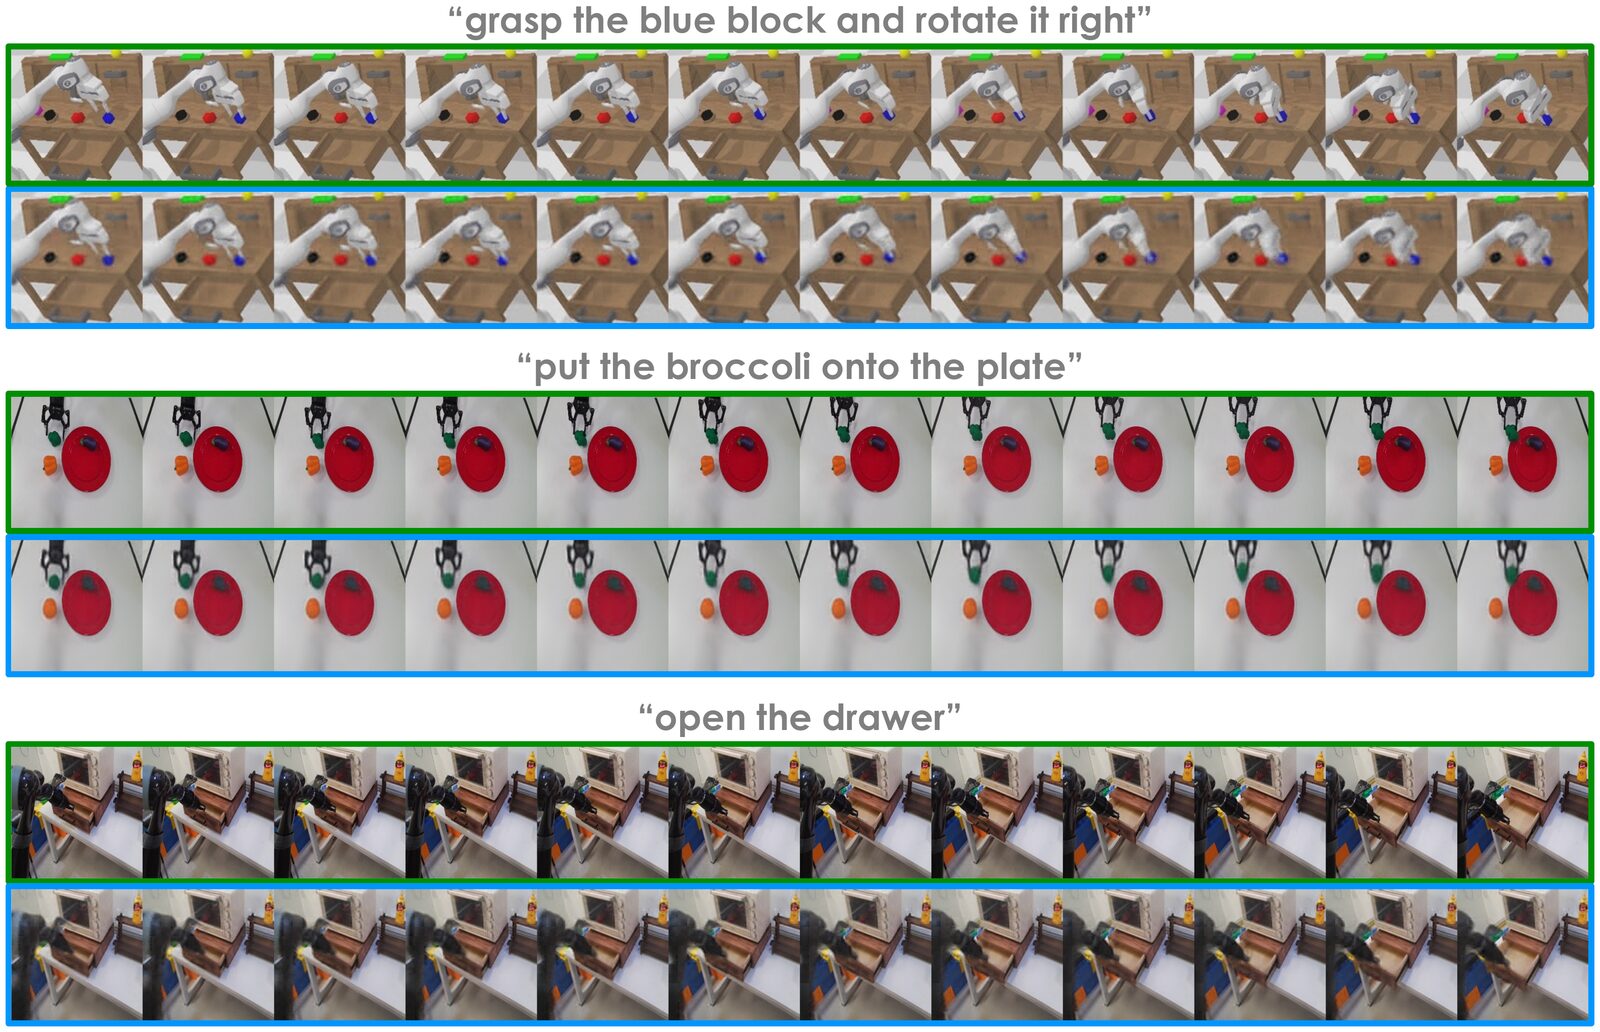
A video world model predicts future frames of a robot task from the current view and a language instruction. GR-1's predicted frames (blue) beneath the ground truth (green) for three instructions. Paper figure: Hongtao Wu et al. / arXiv. Licence: CC BY 4.0.Appears on: Generative Video World Models
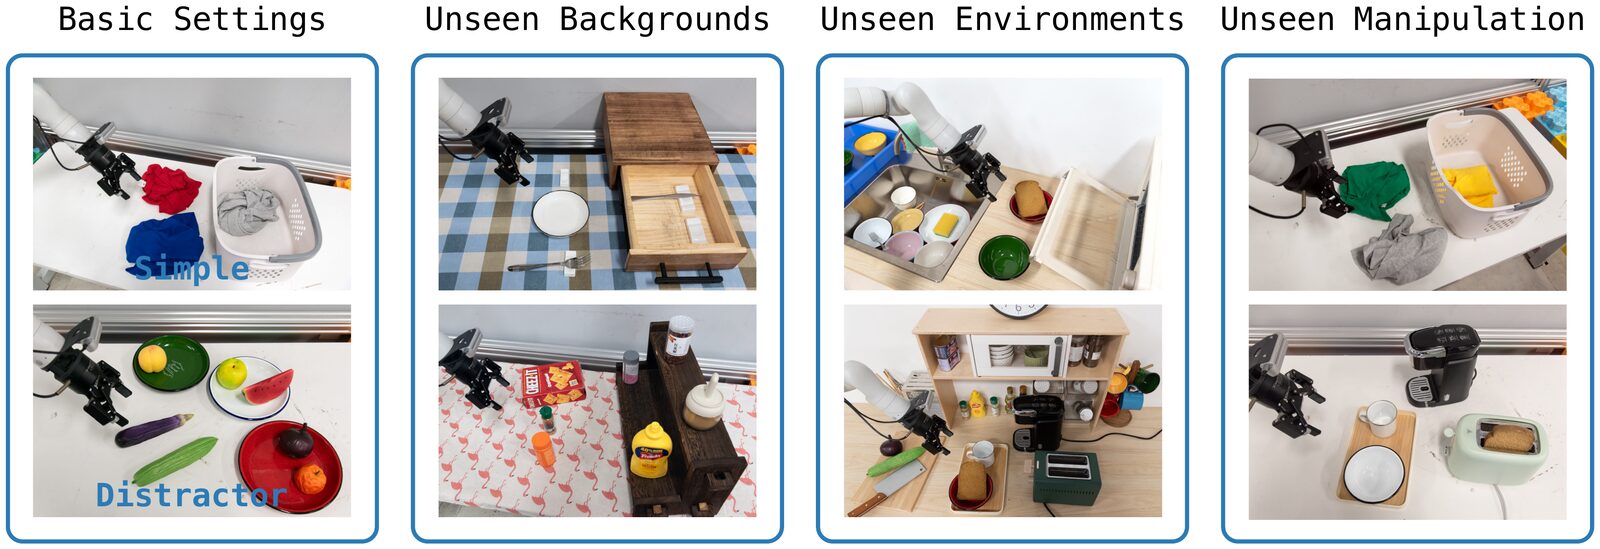
GR-2 pre-trains on web-scale video, then fine-tunes on robot data to generate video and predict actions, with 97.7% average success across more than 100 tasks. Its test settings run from basic scenes to unseen backgrounds and environments. Paper figure: Chi-Lam Cheang et al. / arXiv. Licence: CC BY 4.0.Appears on: Generative Video World Models
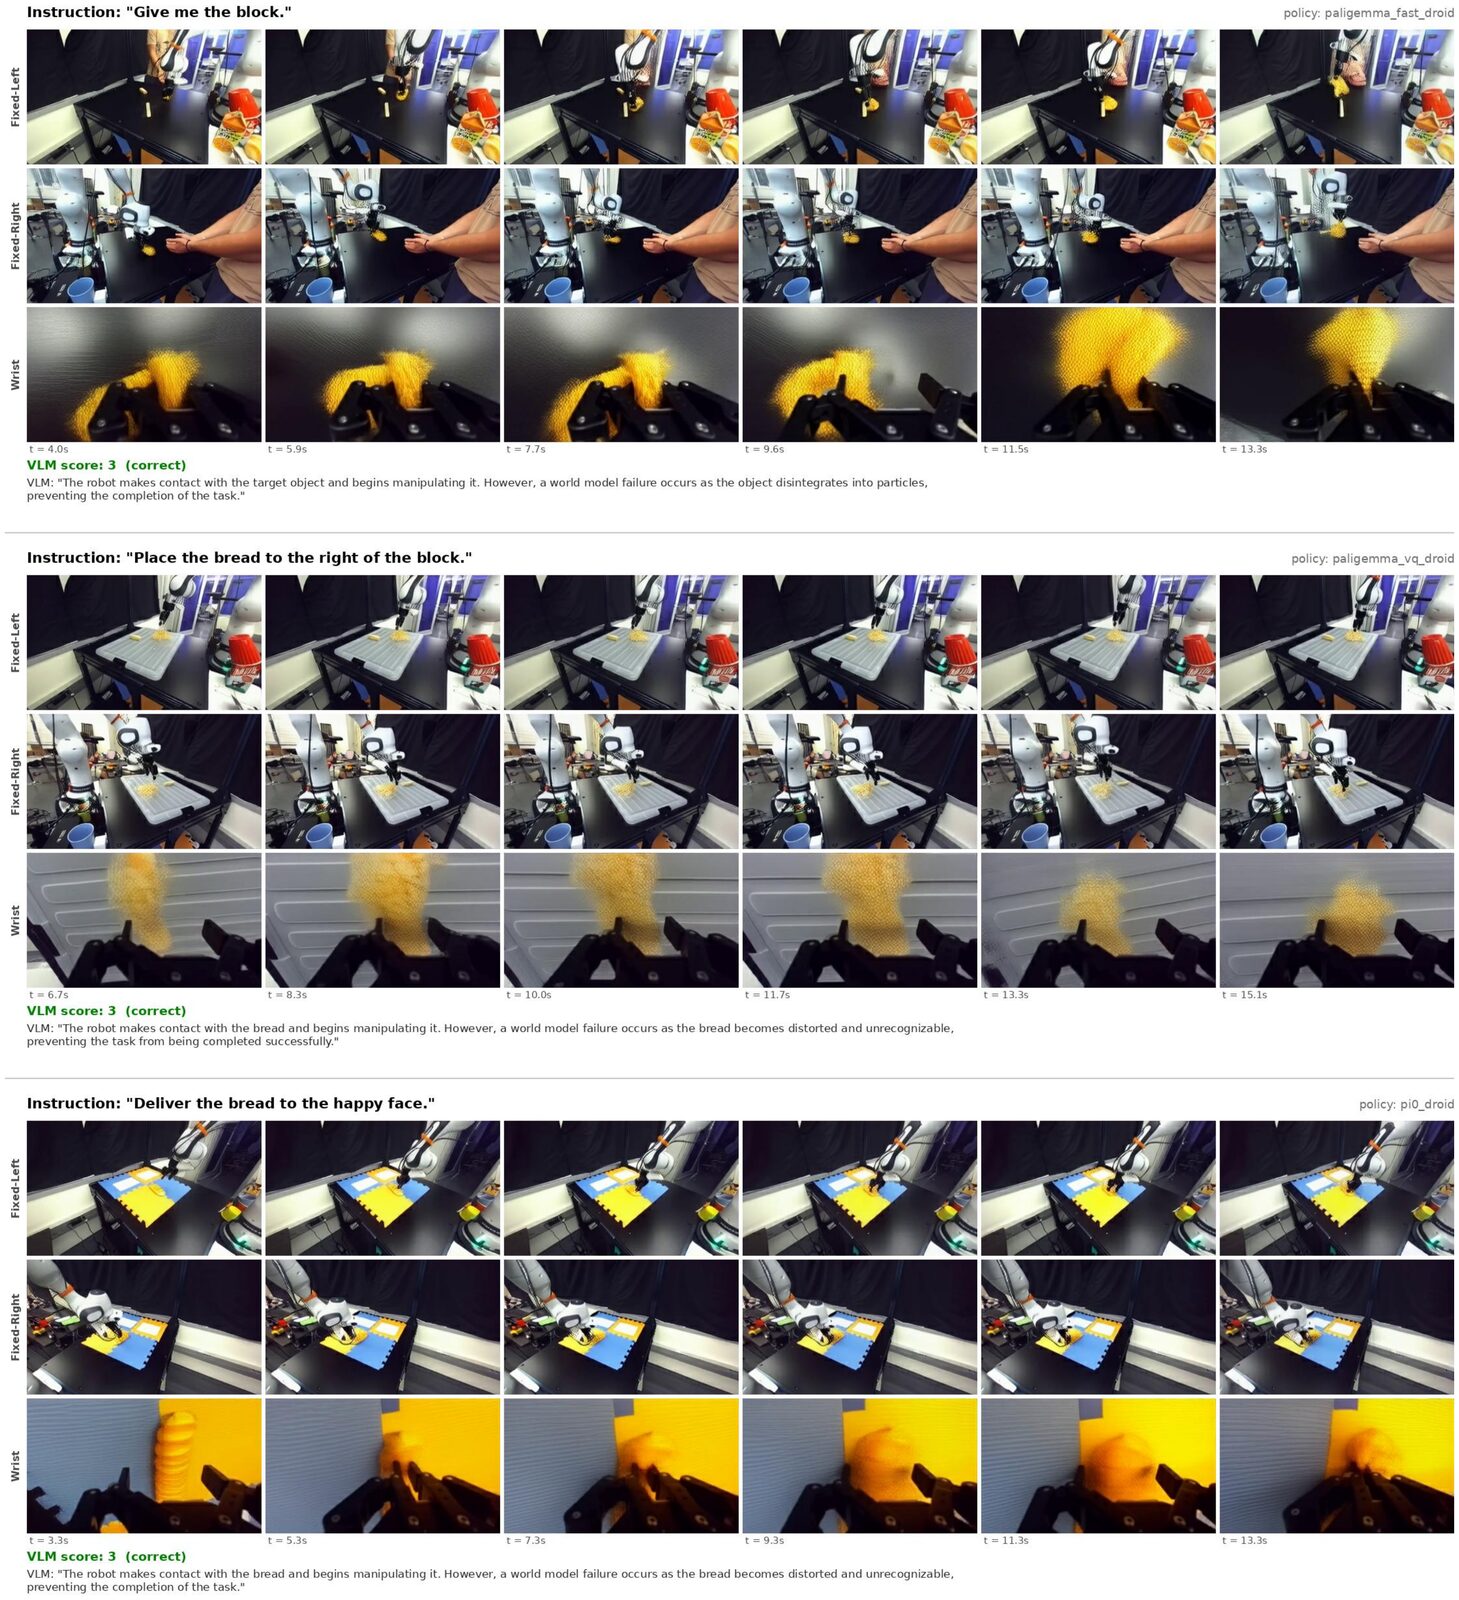
Video world models still fail at contact: after the robot touches it, the manipulated object disintegrates or morphs into artifacts. RoboWorld's VLM evaluator catches such rollouts and gives them a dedicated score. Paper figure: Byeongguk Jeon et al. / arXiv. Licence: CC BY 4.0.Appears on: Generative Video World Models
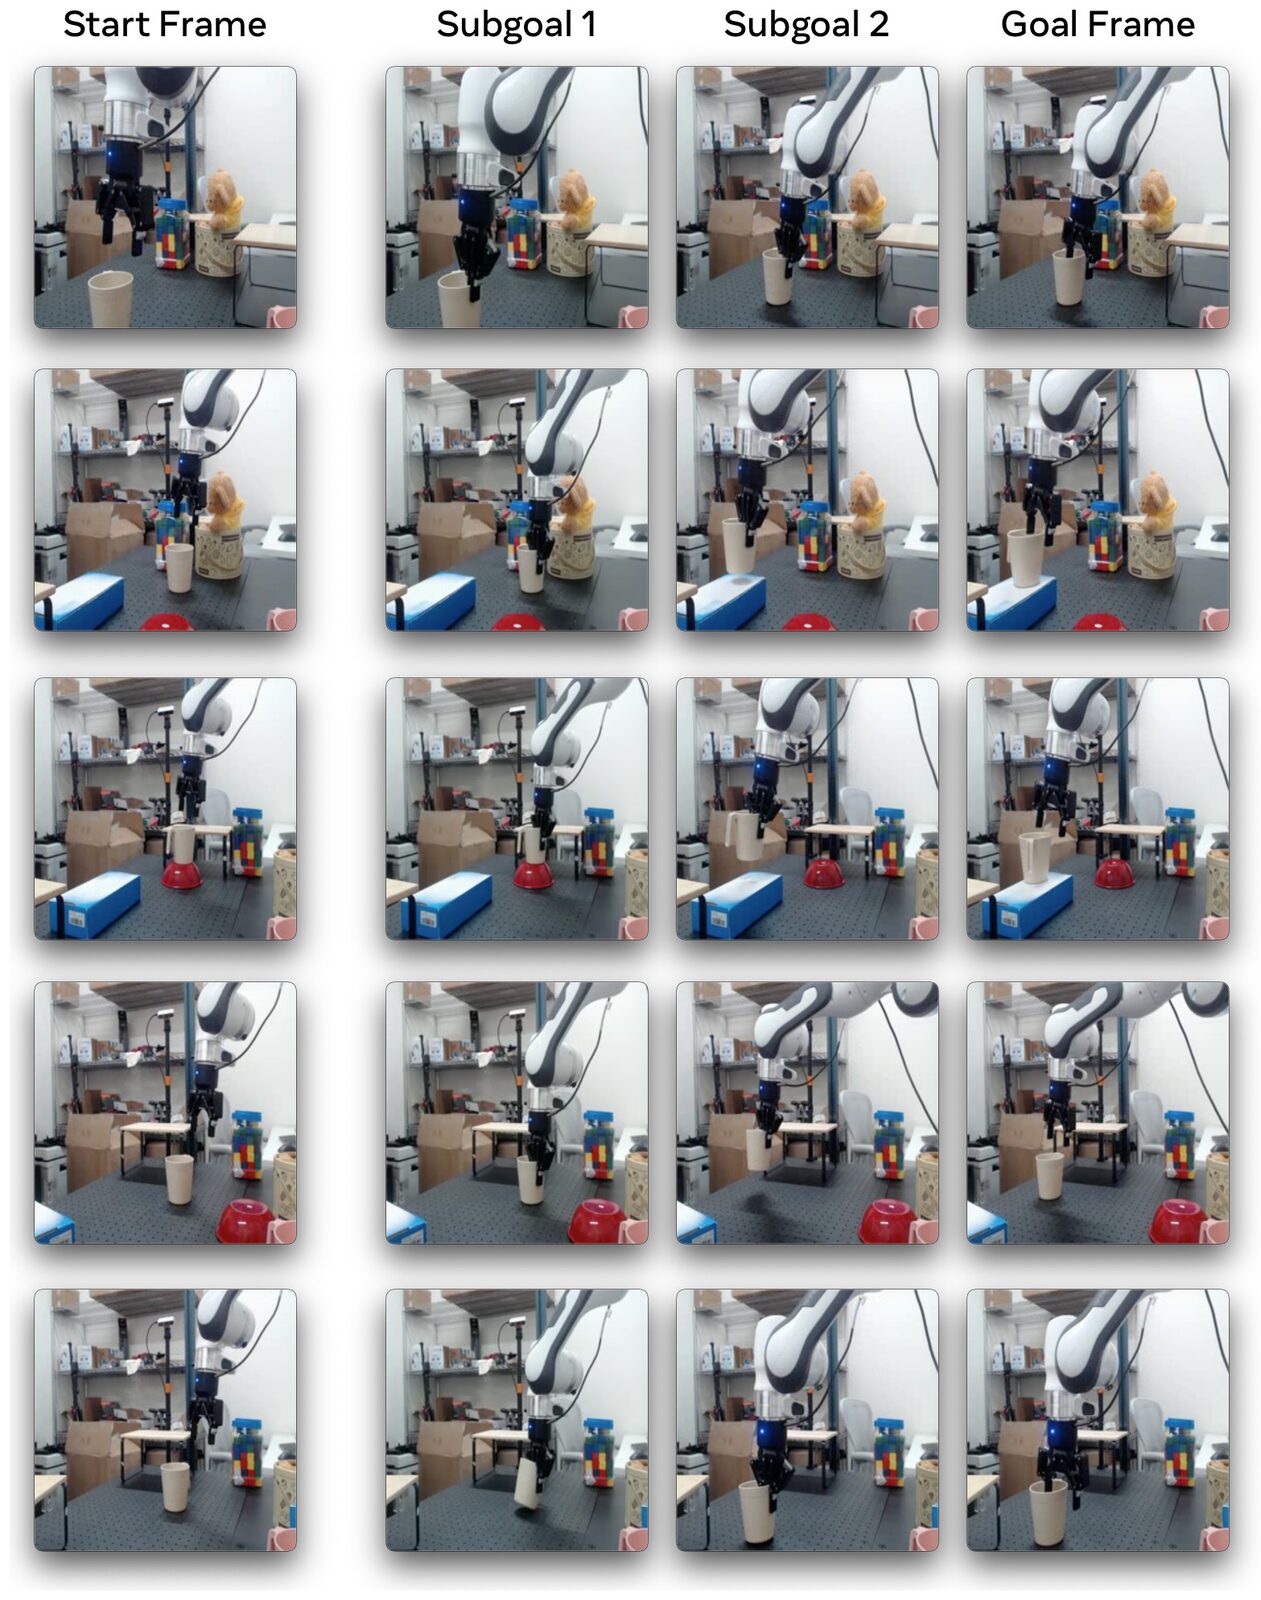
V-JEPA 2-AC plans in embedding space: on Franka arms in labs absent from its training data, it reaches image goals by comparing predicted representations. Pick and place adds two subgoal images between the start and goal frames. Paper figure: Mido Assran et al. / arXiv. Licence: CC BY 4.0.Appears on: JEPA and the Non-Generative Counterargument
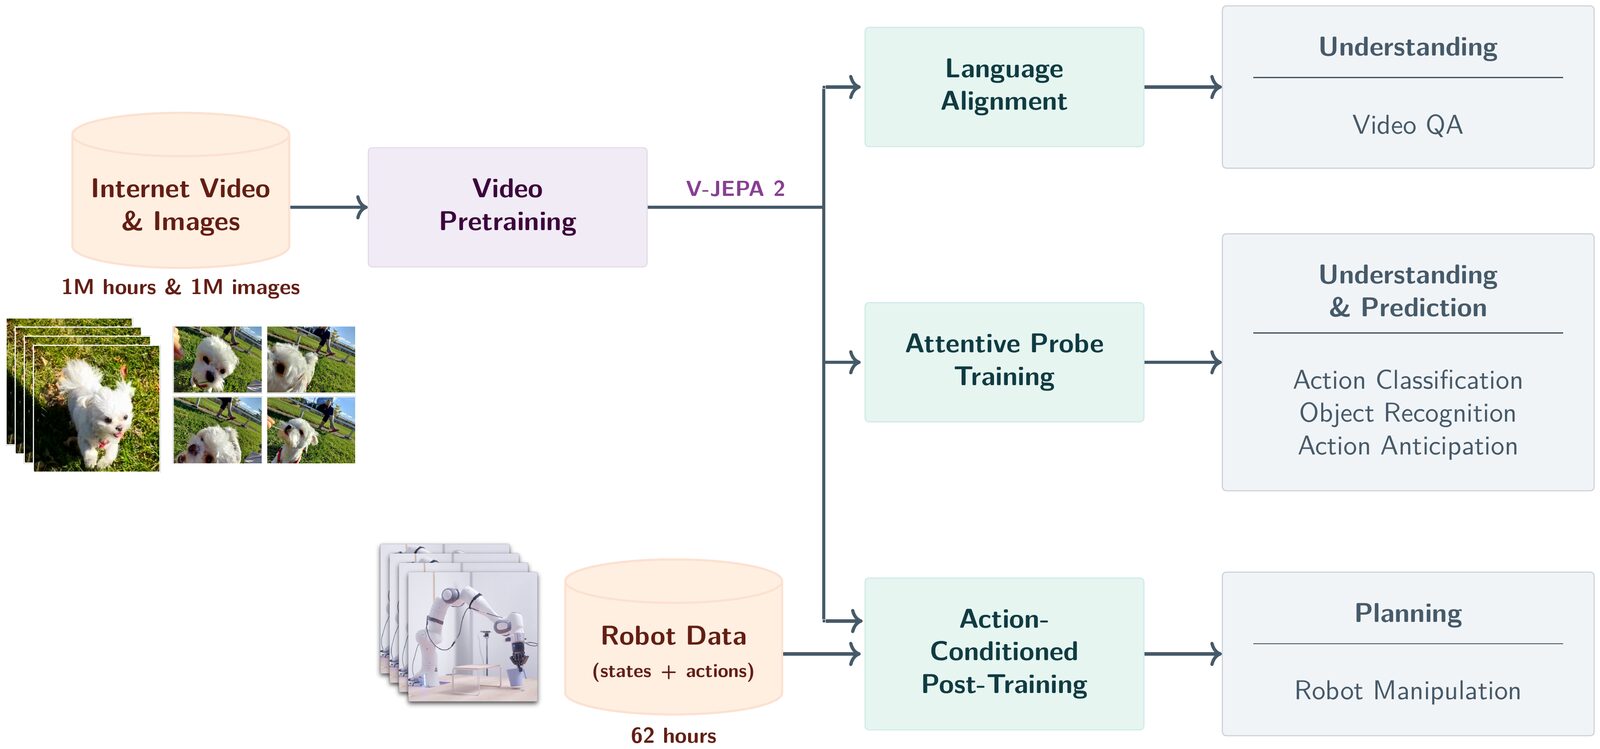
V-JEPA 2 learns from video first and actions second: masked representation prediction on over 1 million hours of internet video and images, then an action-conditioned predictor trained on under 62 hours of robot video. Paper figure: Mido Assran et al. / arXiv. Licence: CC BY 4.0.Appears on: JEPA and the Non-Generative Counterargument
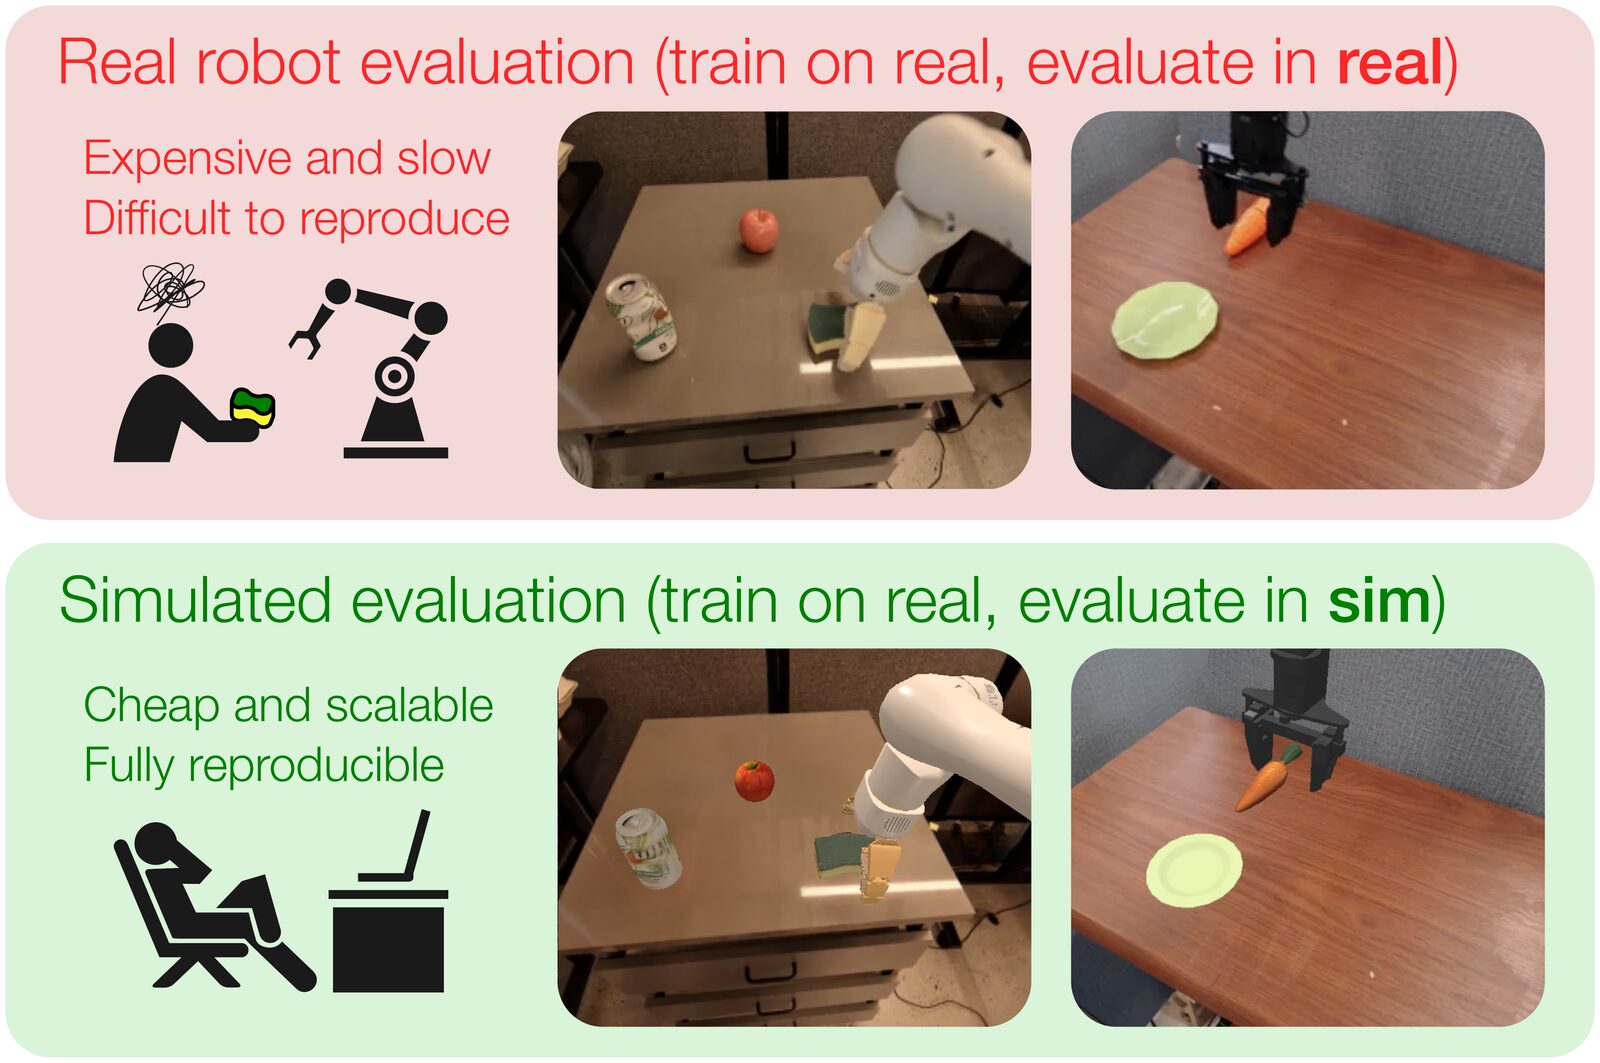
A cheaper evaluator is useful only if it agrees with reality. SIMPLER builds simulated scenes matched to real ones and checks whether simulated policy performance correlates with real performance; a learned simulator should meet the same test. Paper figure: Xuanlin Li et al. / arXiv. Licence: CC BY 4.0.Appears on: World Model Evaluation for Robotics
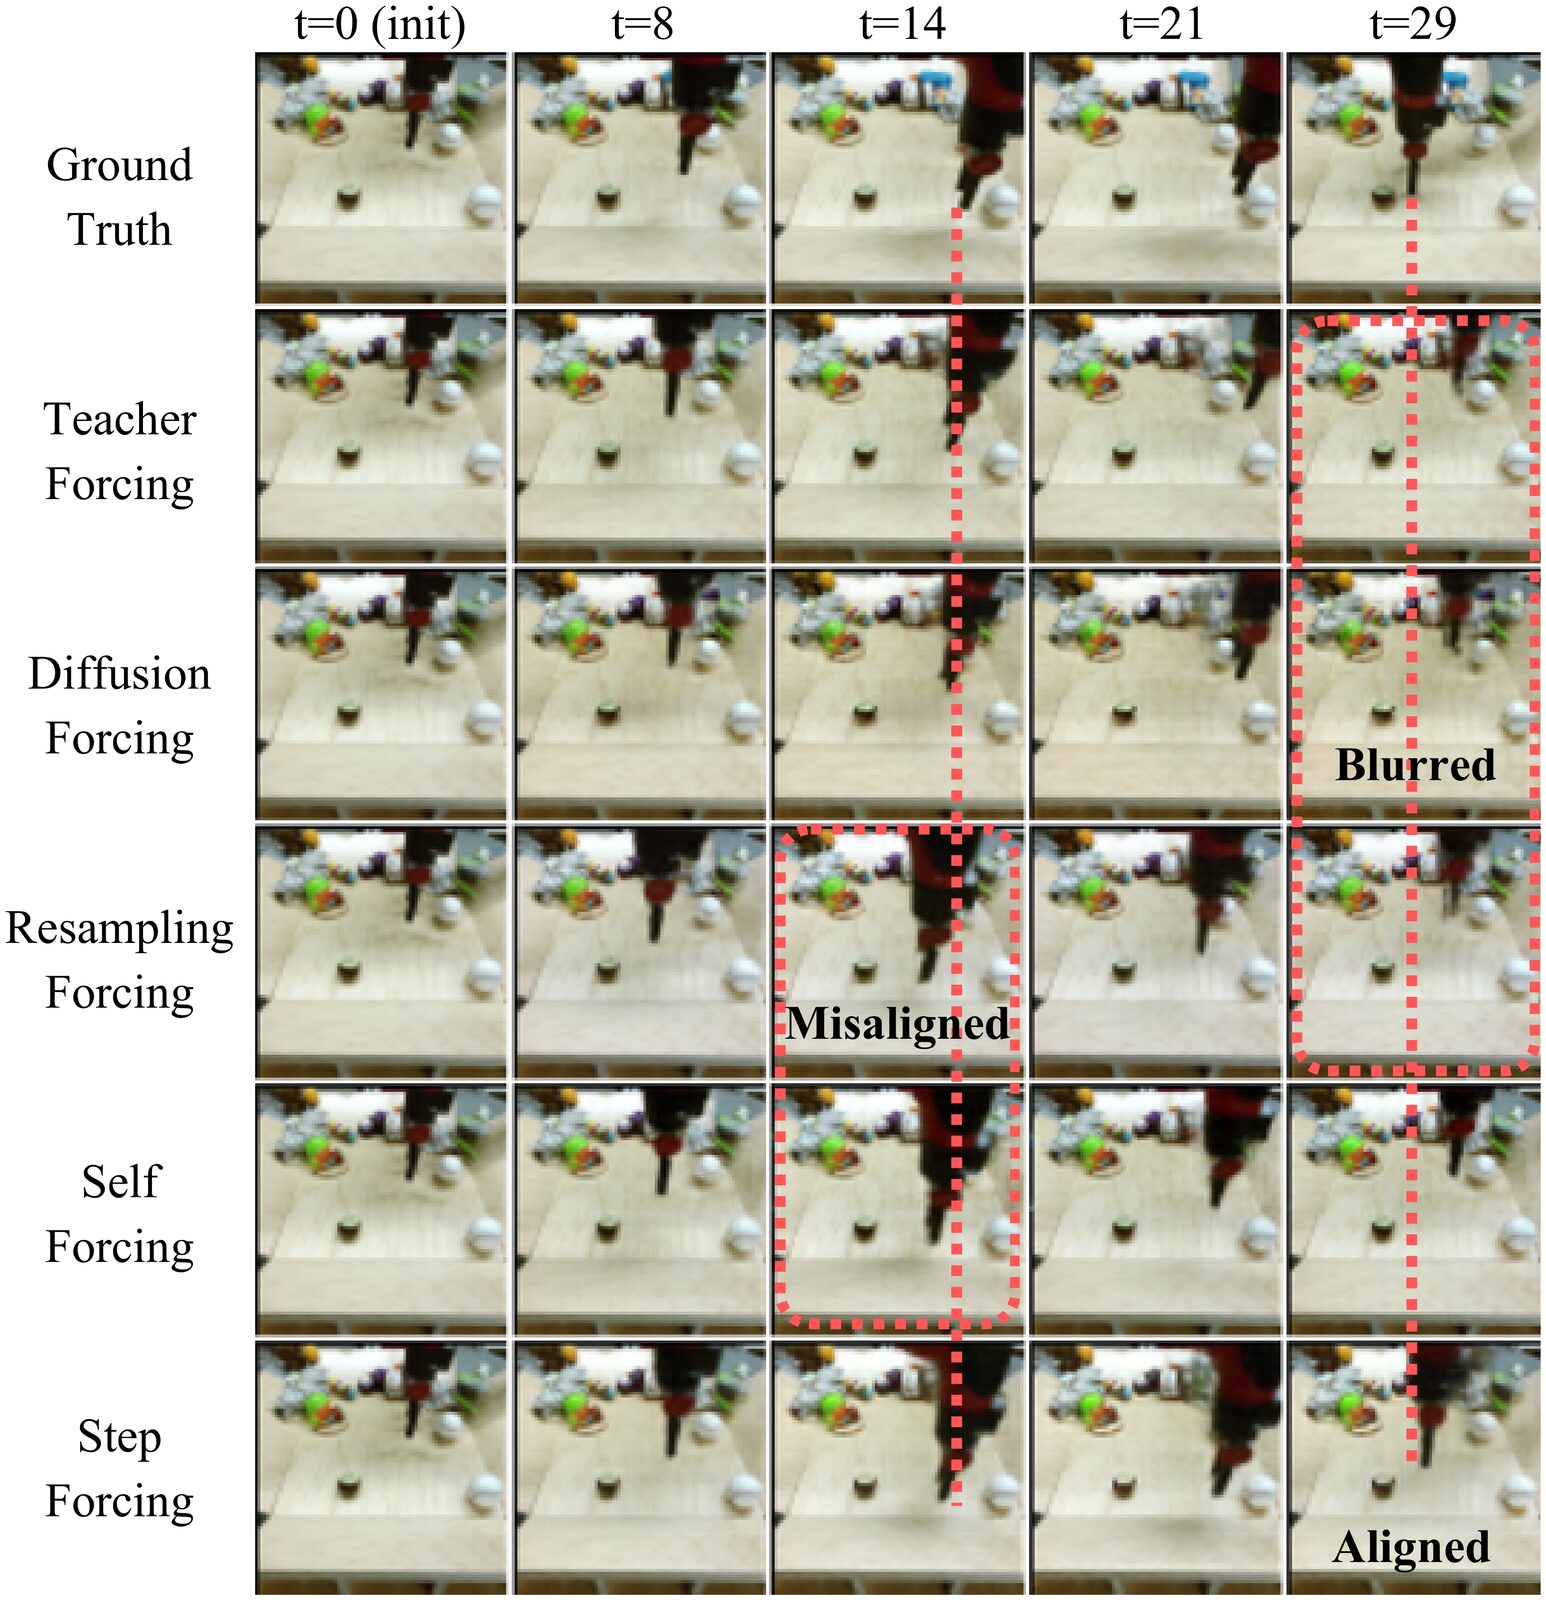
Autoregressive rollouts can drift in ways one frame hides. On BAIR robot pushing, the RoboWorld authors mark other forcing schemes misaligned or blurred within 29 steps, while their step forcing stays aligned with the ground truth. Paper figure: Byeongguk Jeon et al. / arXiv. Licence: CC BY 4.0.Appears on: World Model Evaluation for Robotics
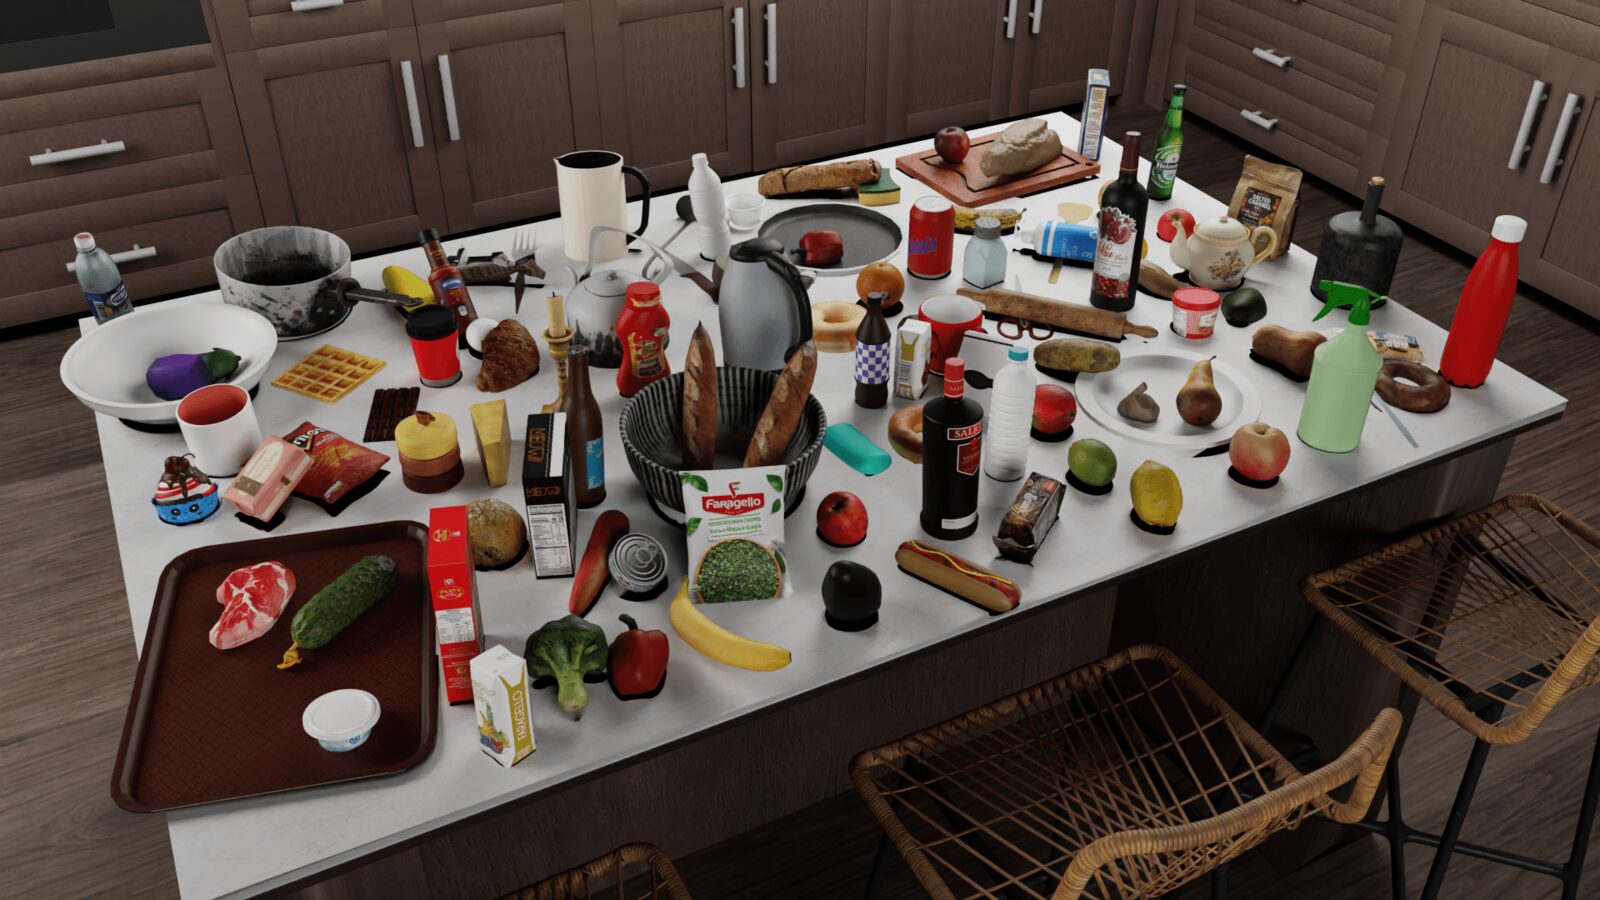
Generative simulation authors content and leaves dynamics to the physics engine. RoboCasa's library holds 2,509 objects in 153 categories, drawn from Objaverse and the text-to-3D service Luma.ai; a small subset is shown here. Paper figure: Soroush Nasiriany et al. / arXiv. Licence: CC BY 4.0.Appears on: Generative Simulation
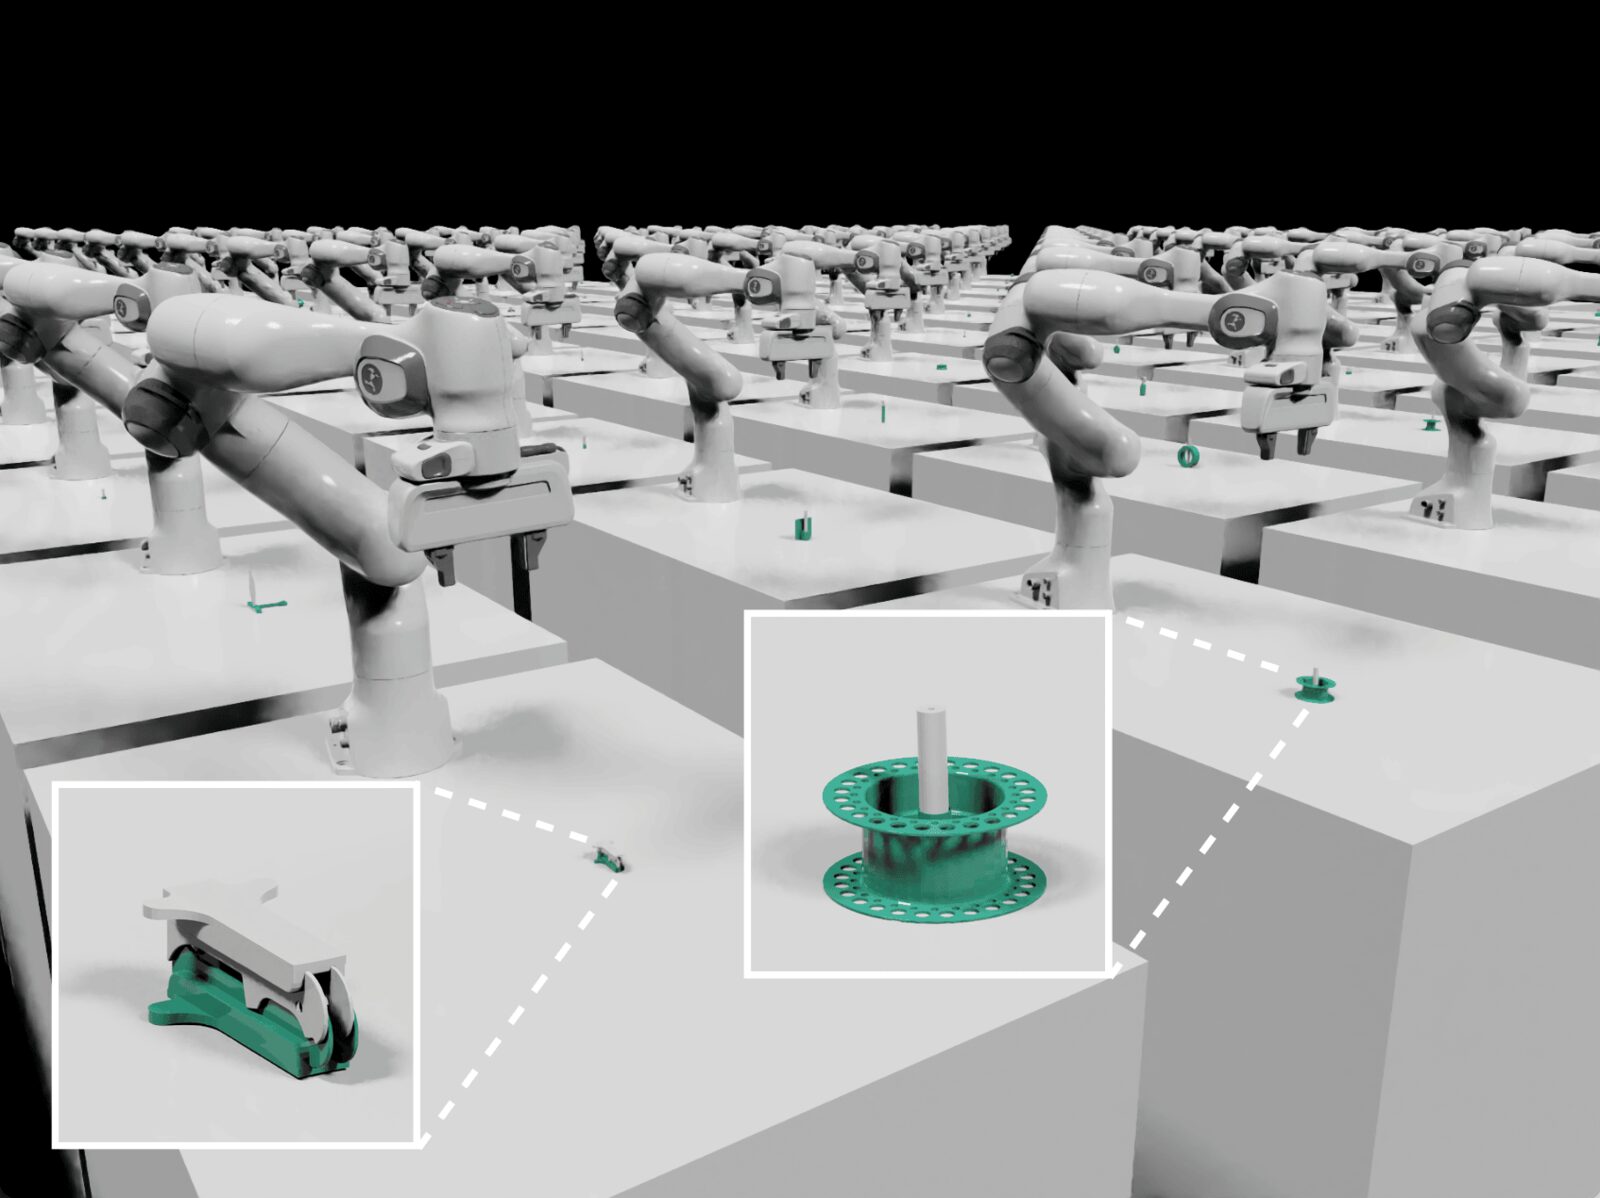
A physics simulator integrates explicit geometry, dynamics and contact rules, and steps many copies at once. Assembly environments in Isaac Lab, each an arm with a part to insert, run in parallel on the GPU. Paper figure: NVIDIA et al. / arXiv. Licence: CC BY 4.0.Appears on: World Models vs Physics Simulators
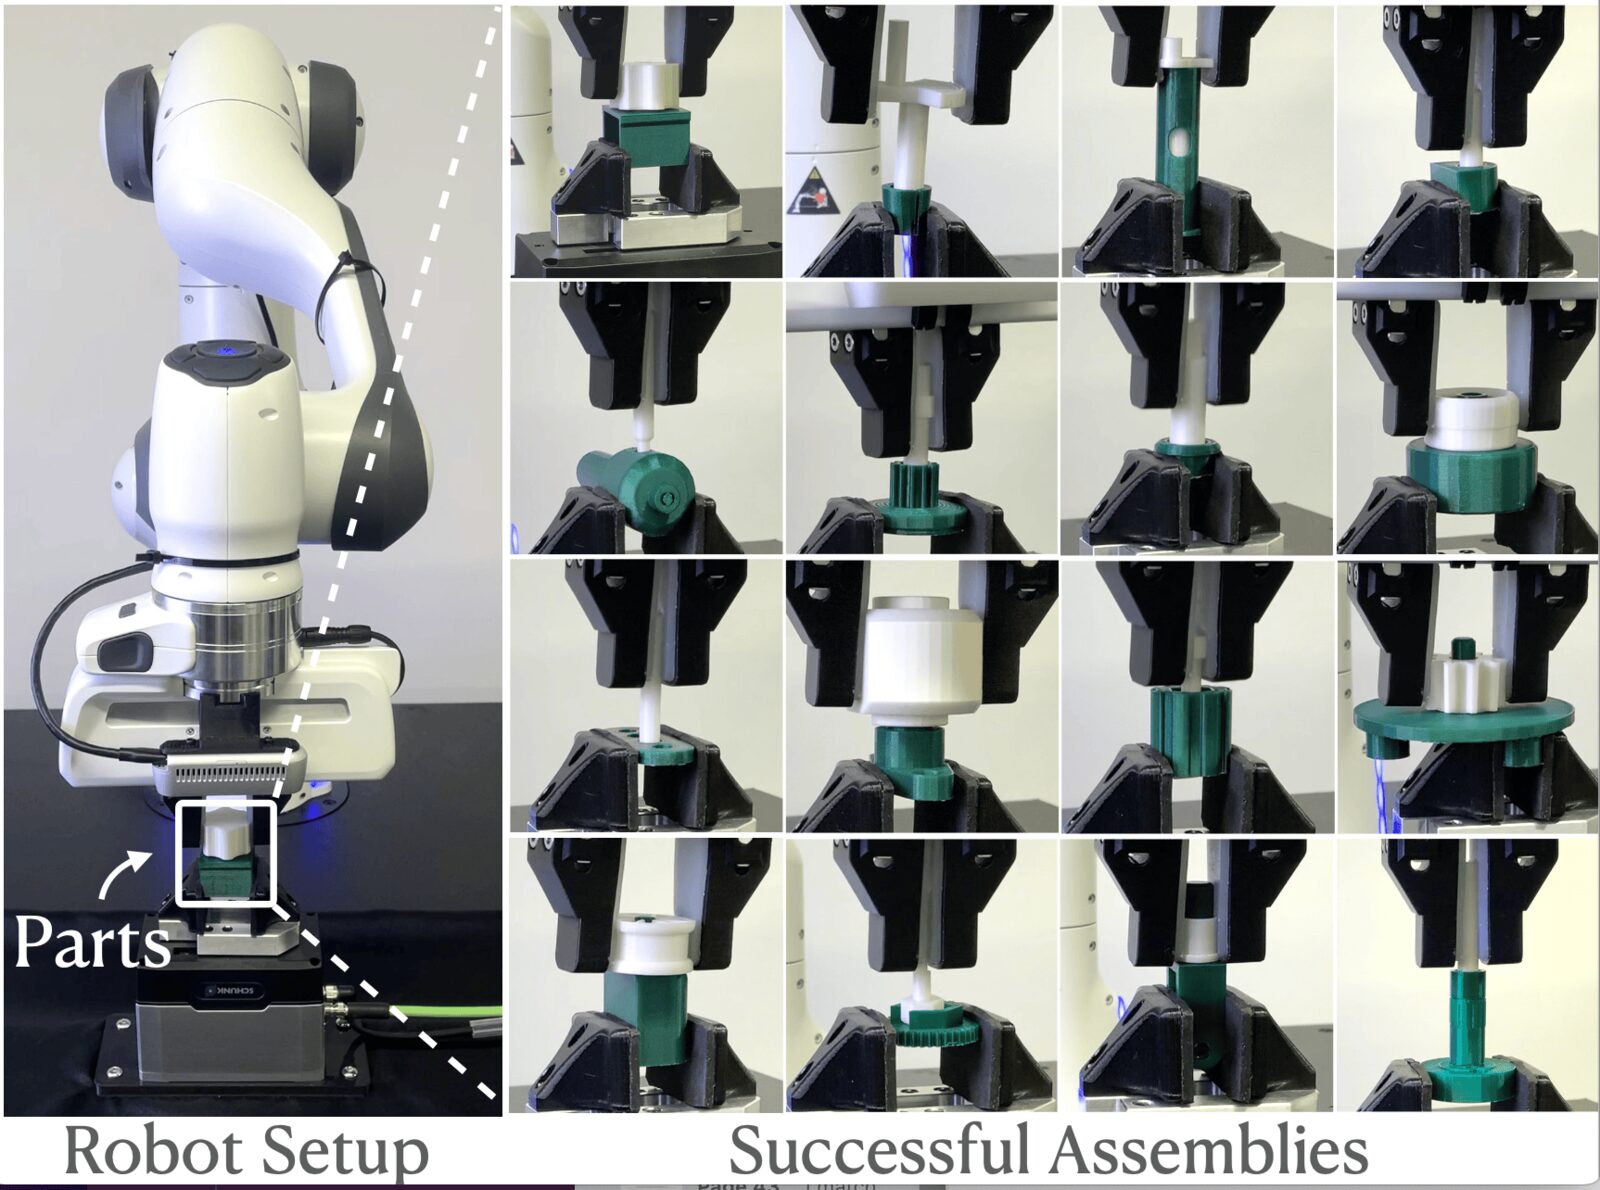
Either kind of simulator earns trust only against the same real tasks. The Isaac Lab assembly tasks on a real arm, with its successful assemblies. Paper figure: NVIDIA et al. / arXiv. Licence: CC BY 4.0.Appears on: World Models vs Physics Simulators
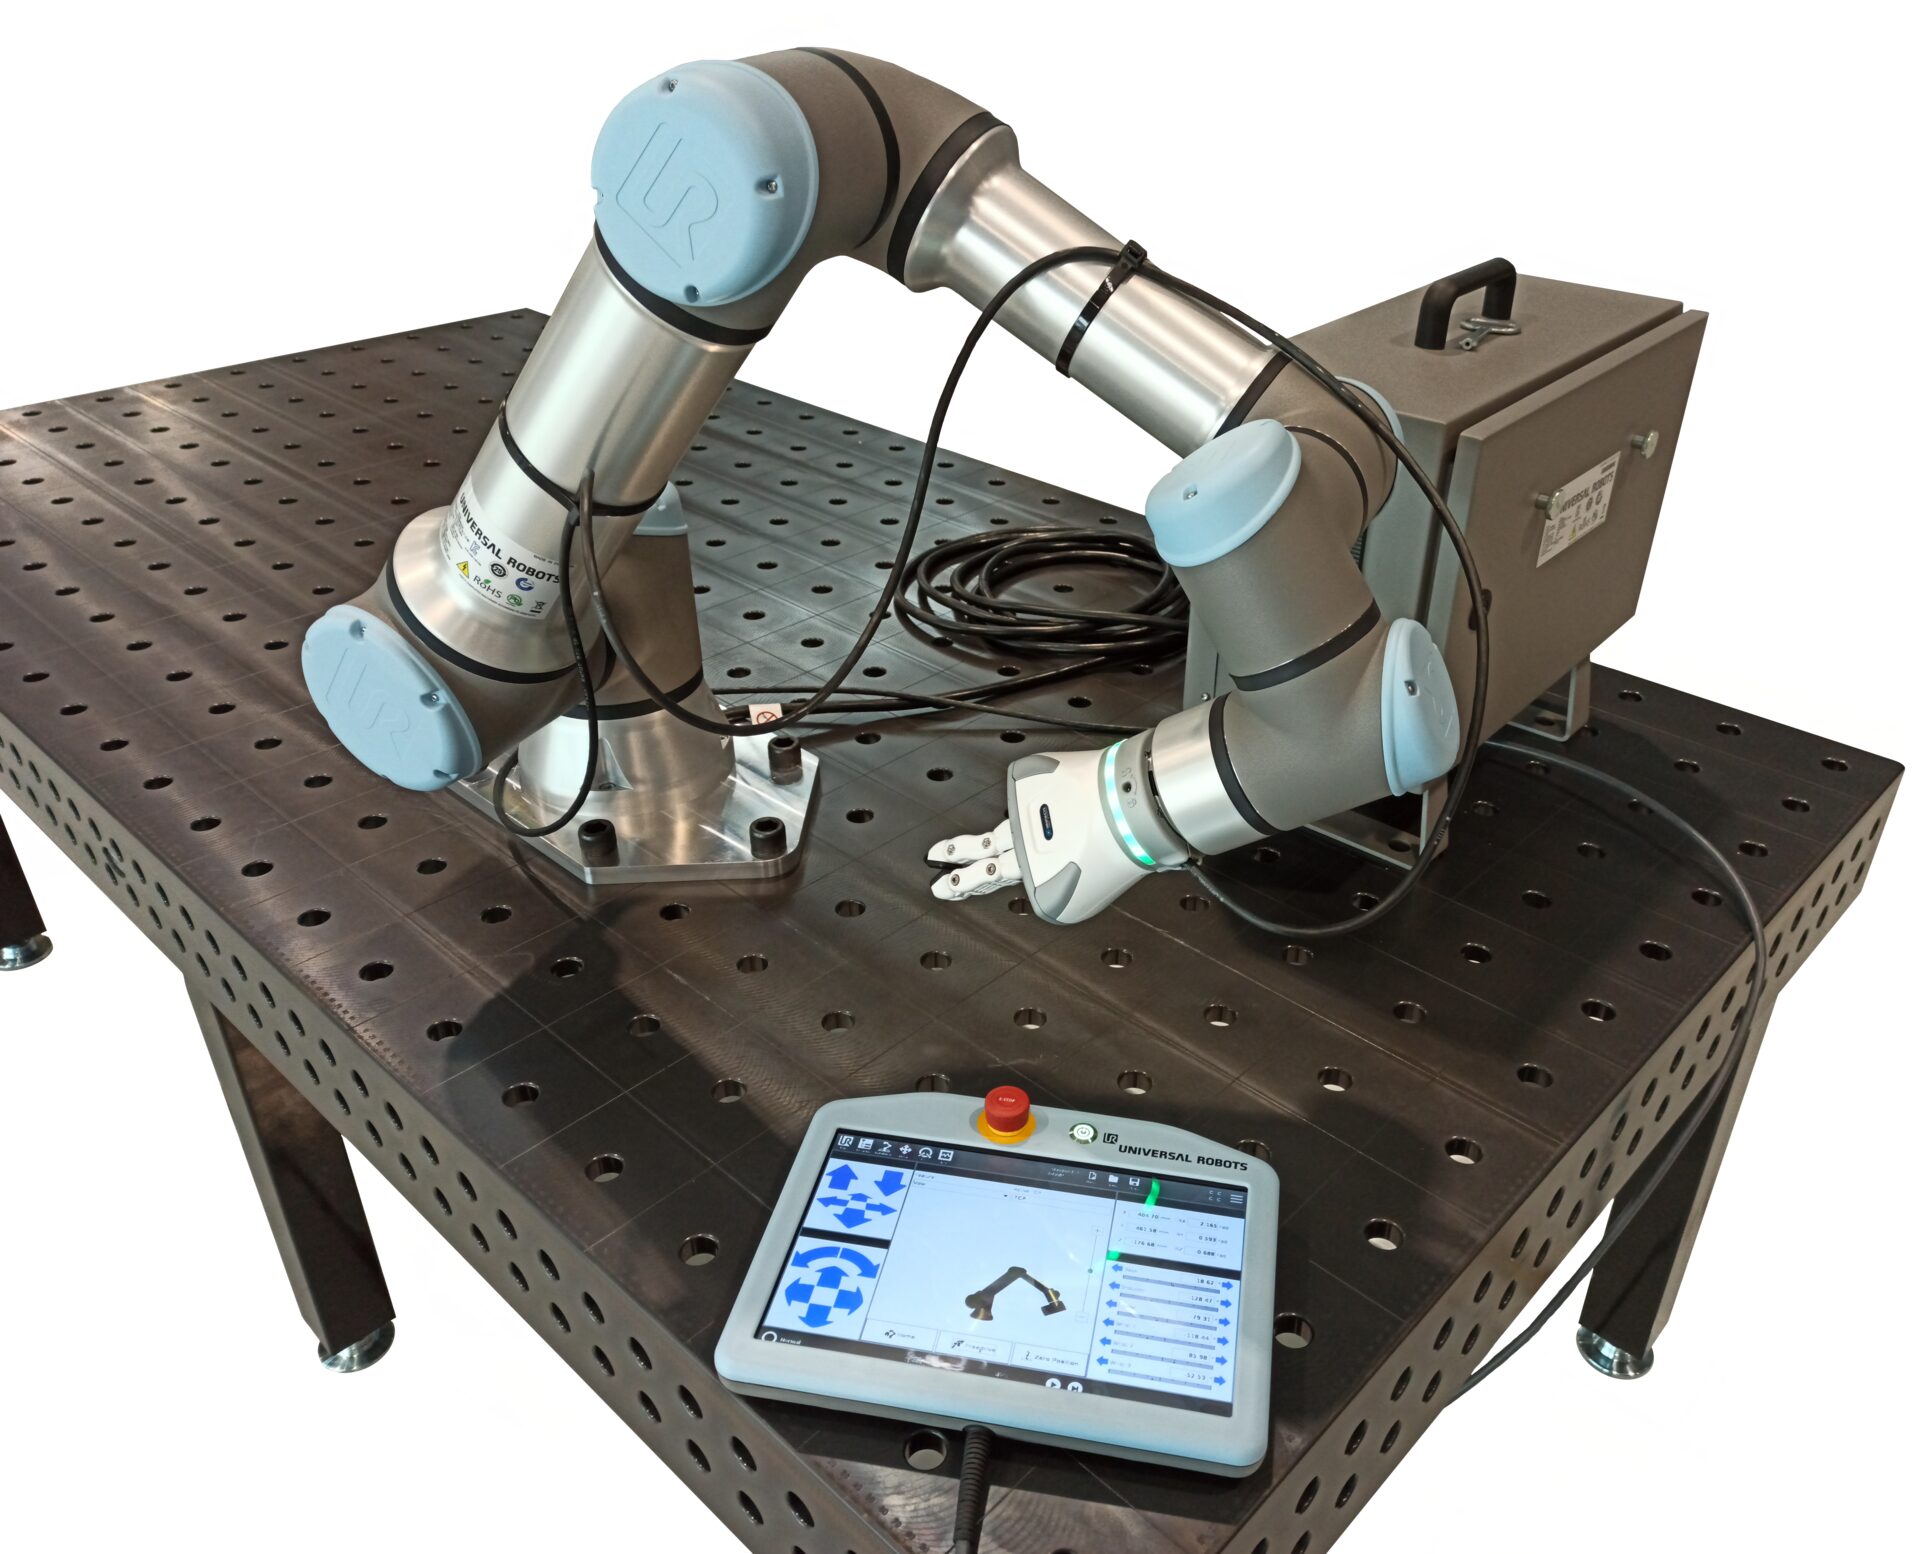
A Universal Robots UR16e, a six-joint serial arm. Forward kinematics composes one transform per joint, so its six joint angles fix the pose of the tool flange. Photo: Auledas / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Kinematics
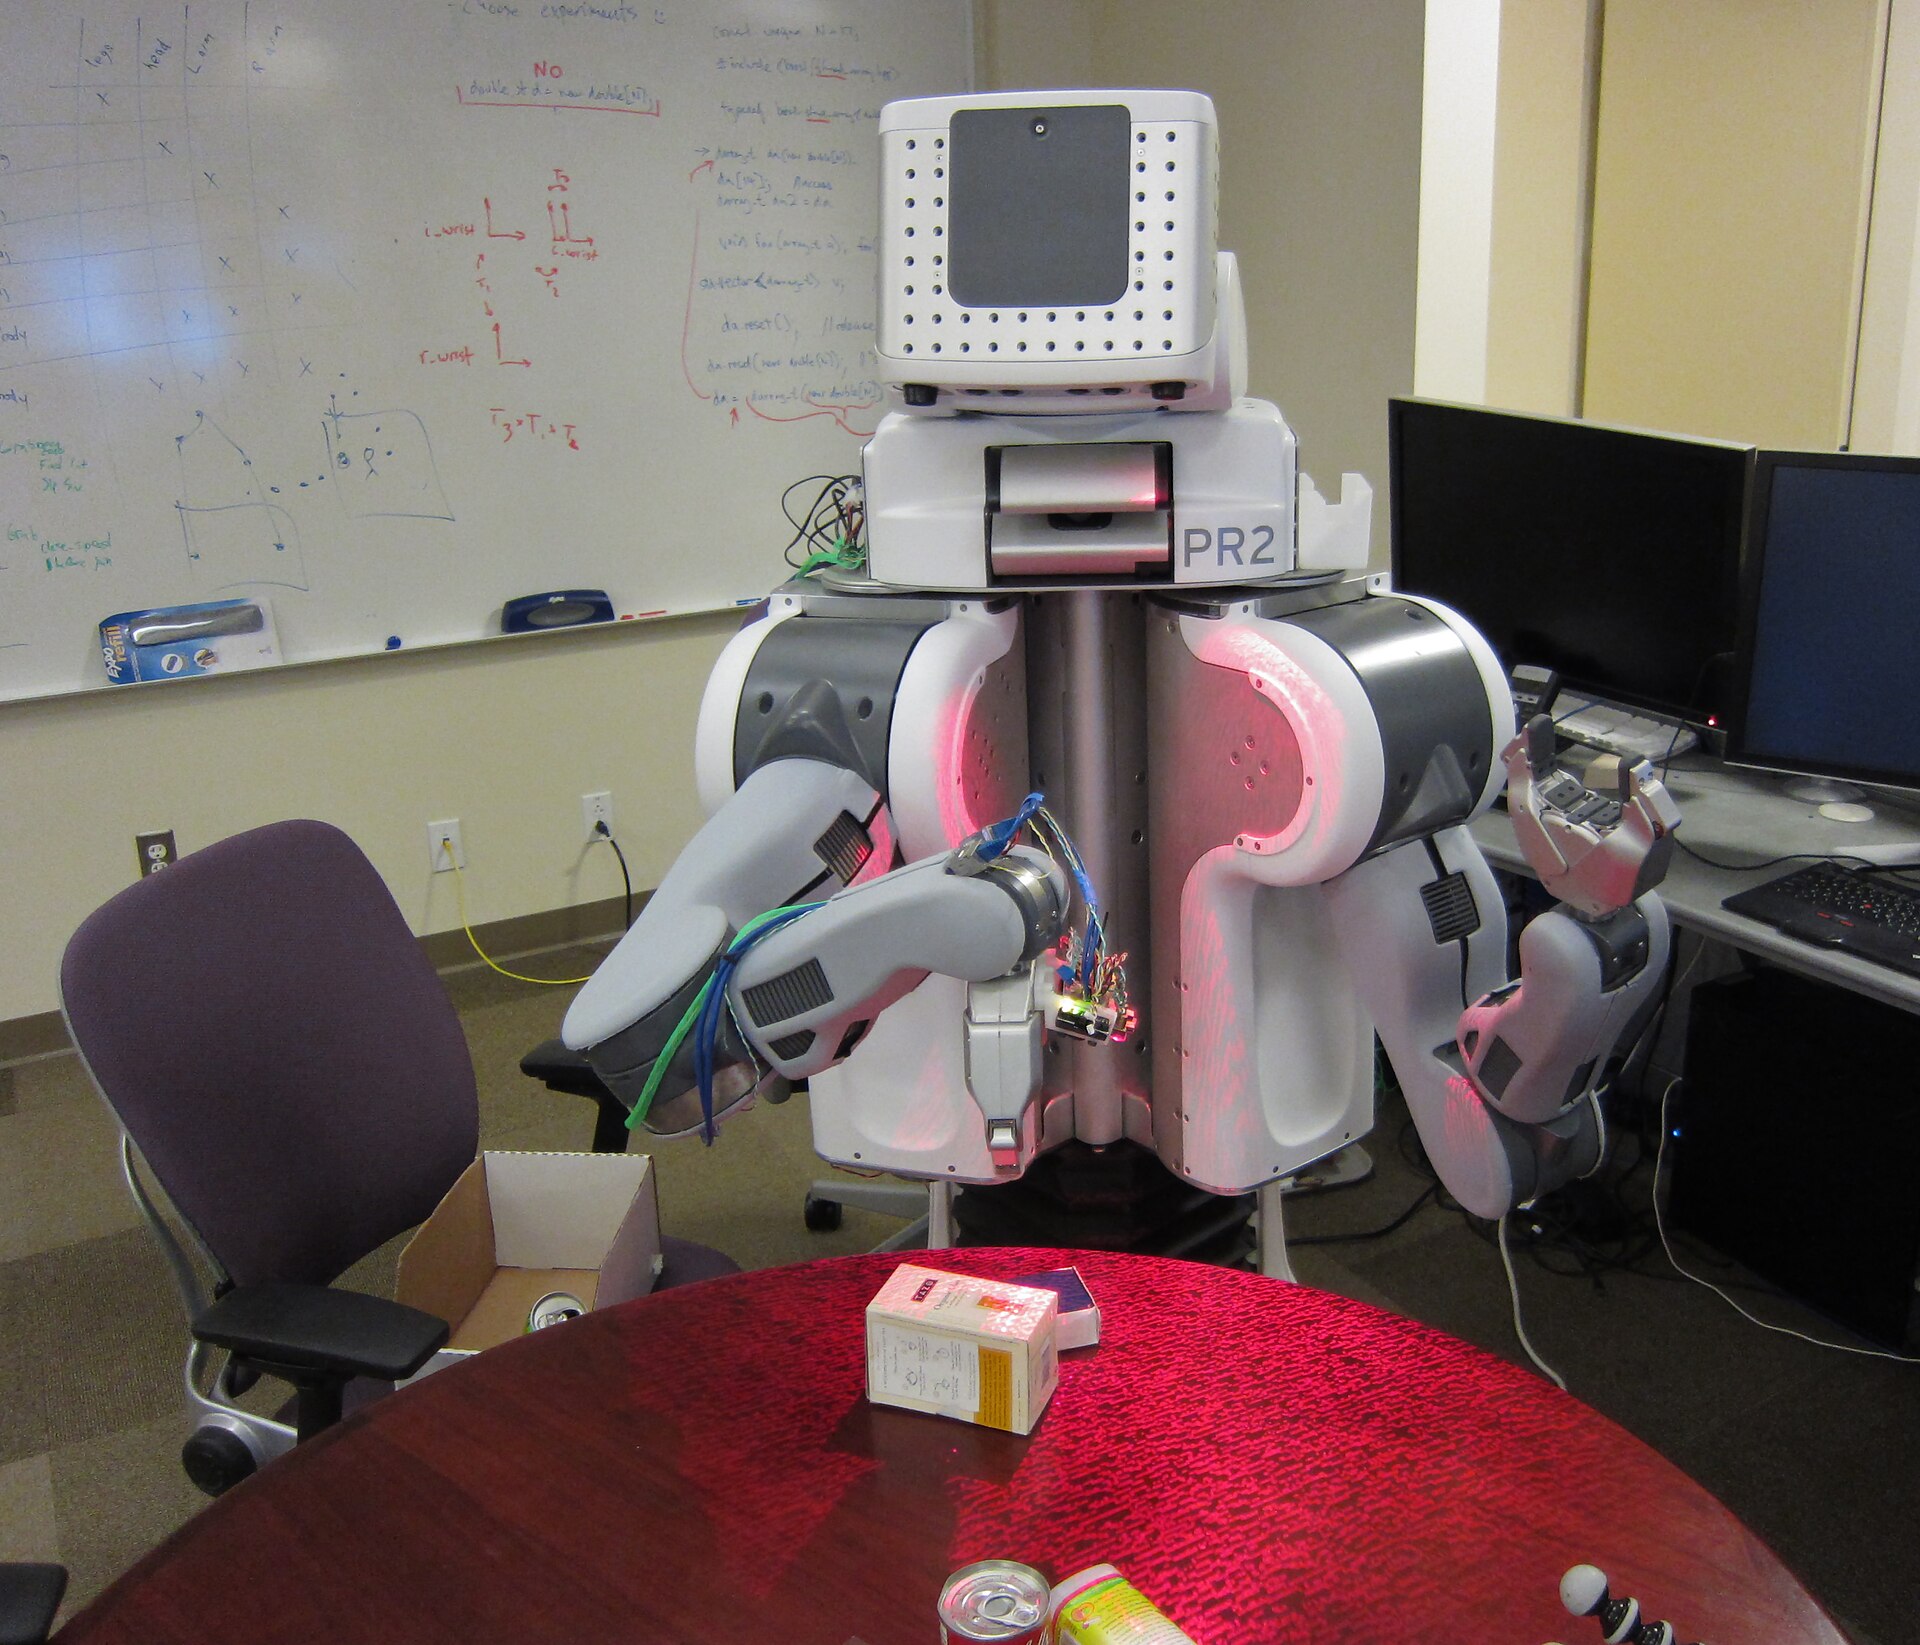
A Willow Garage PR2 in 2010. The TrajOpt benchmark below planned 198 arm problems and 96 full-body problems for this robot in simulated MoveIt scenes. Photo: Steve Jurvetson / Wikimedia Commons. Licence: CC BY 2.0.Appears on: Motion Planning
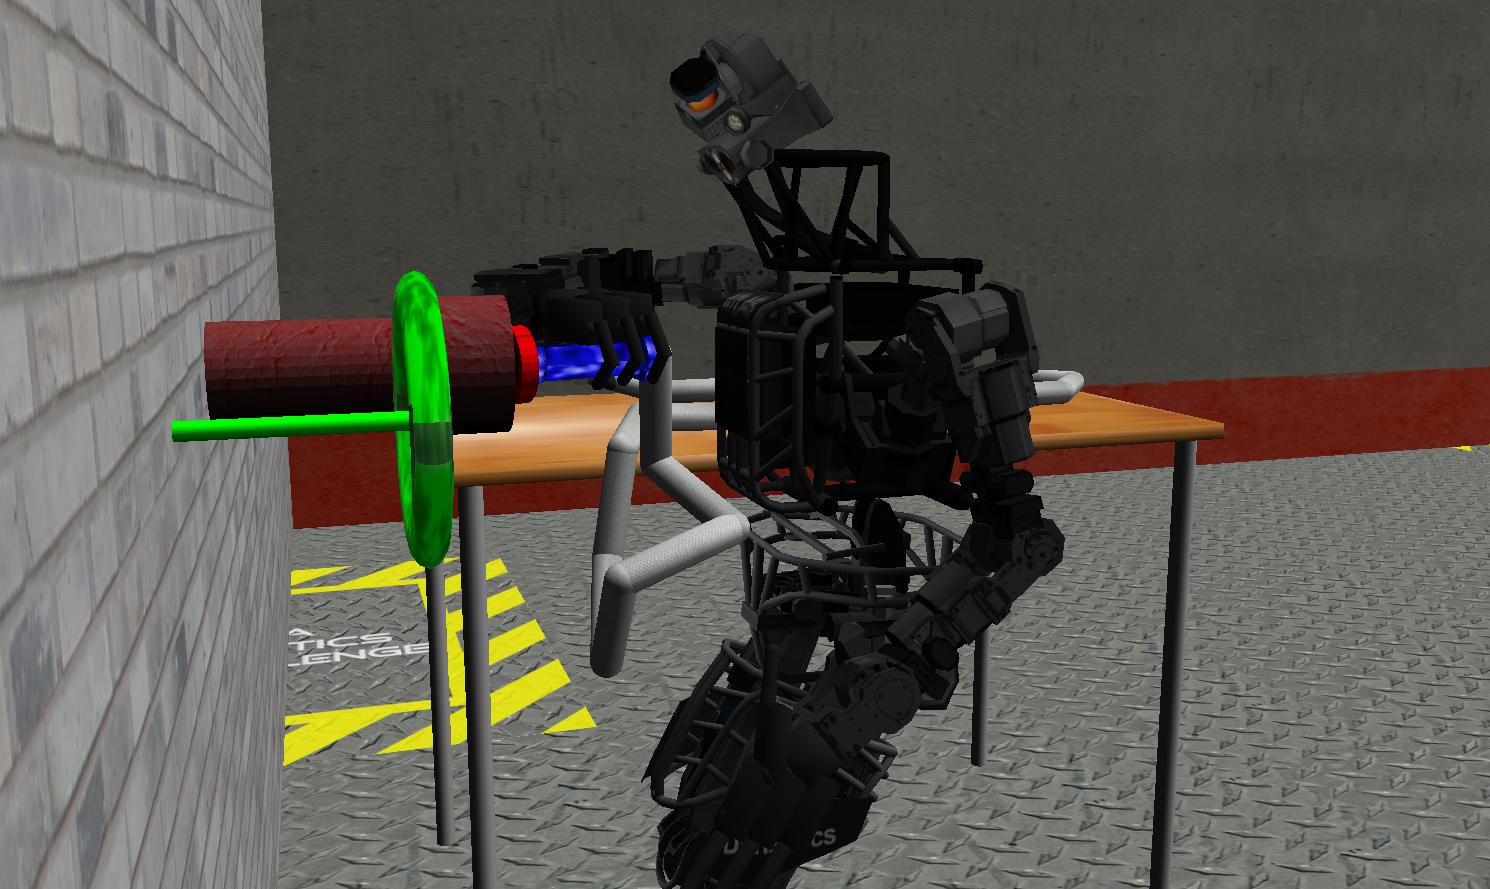
A 2013 Defense Department rendering of a simulated Atlas connecting a hose, a DARPA Robotics Challenge task. TrajOpt planned statically stable walking for this 34-DoF humanoid. Photo: U.S. Department of Defense / Wikimedia Commons. Licence: Public domain.Appears on: Motion Planning
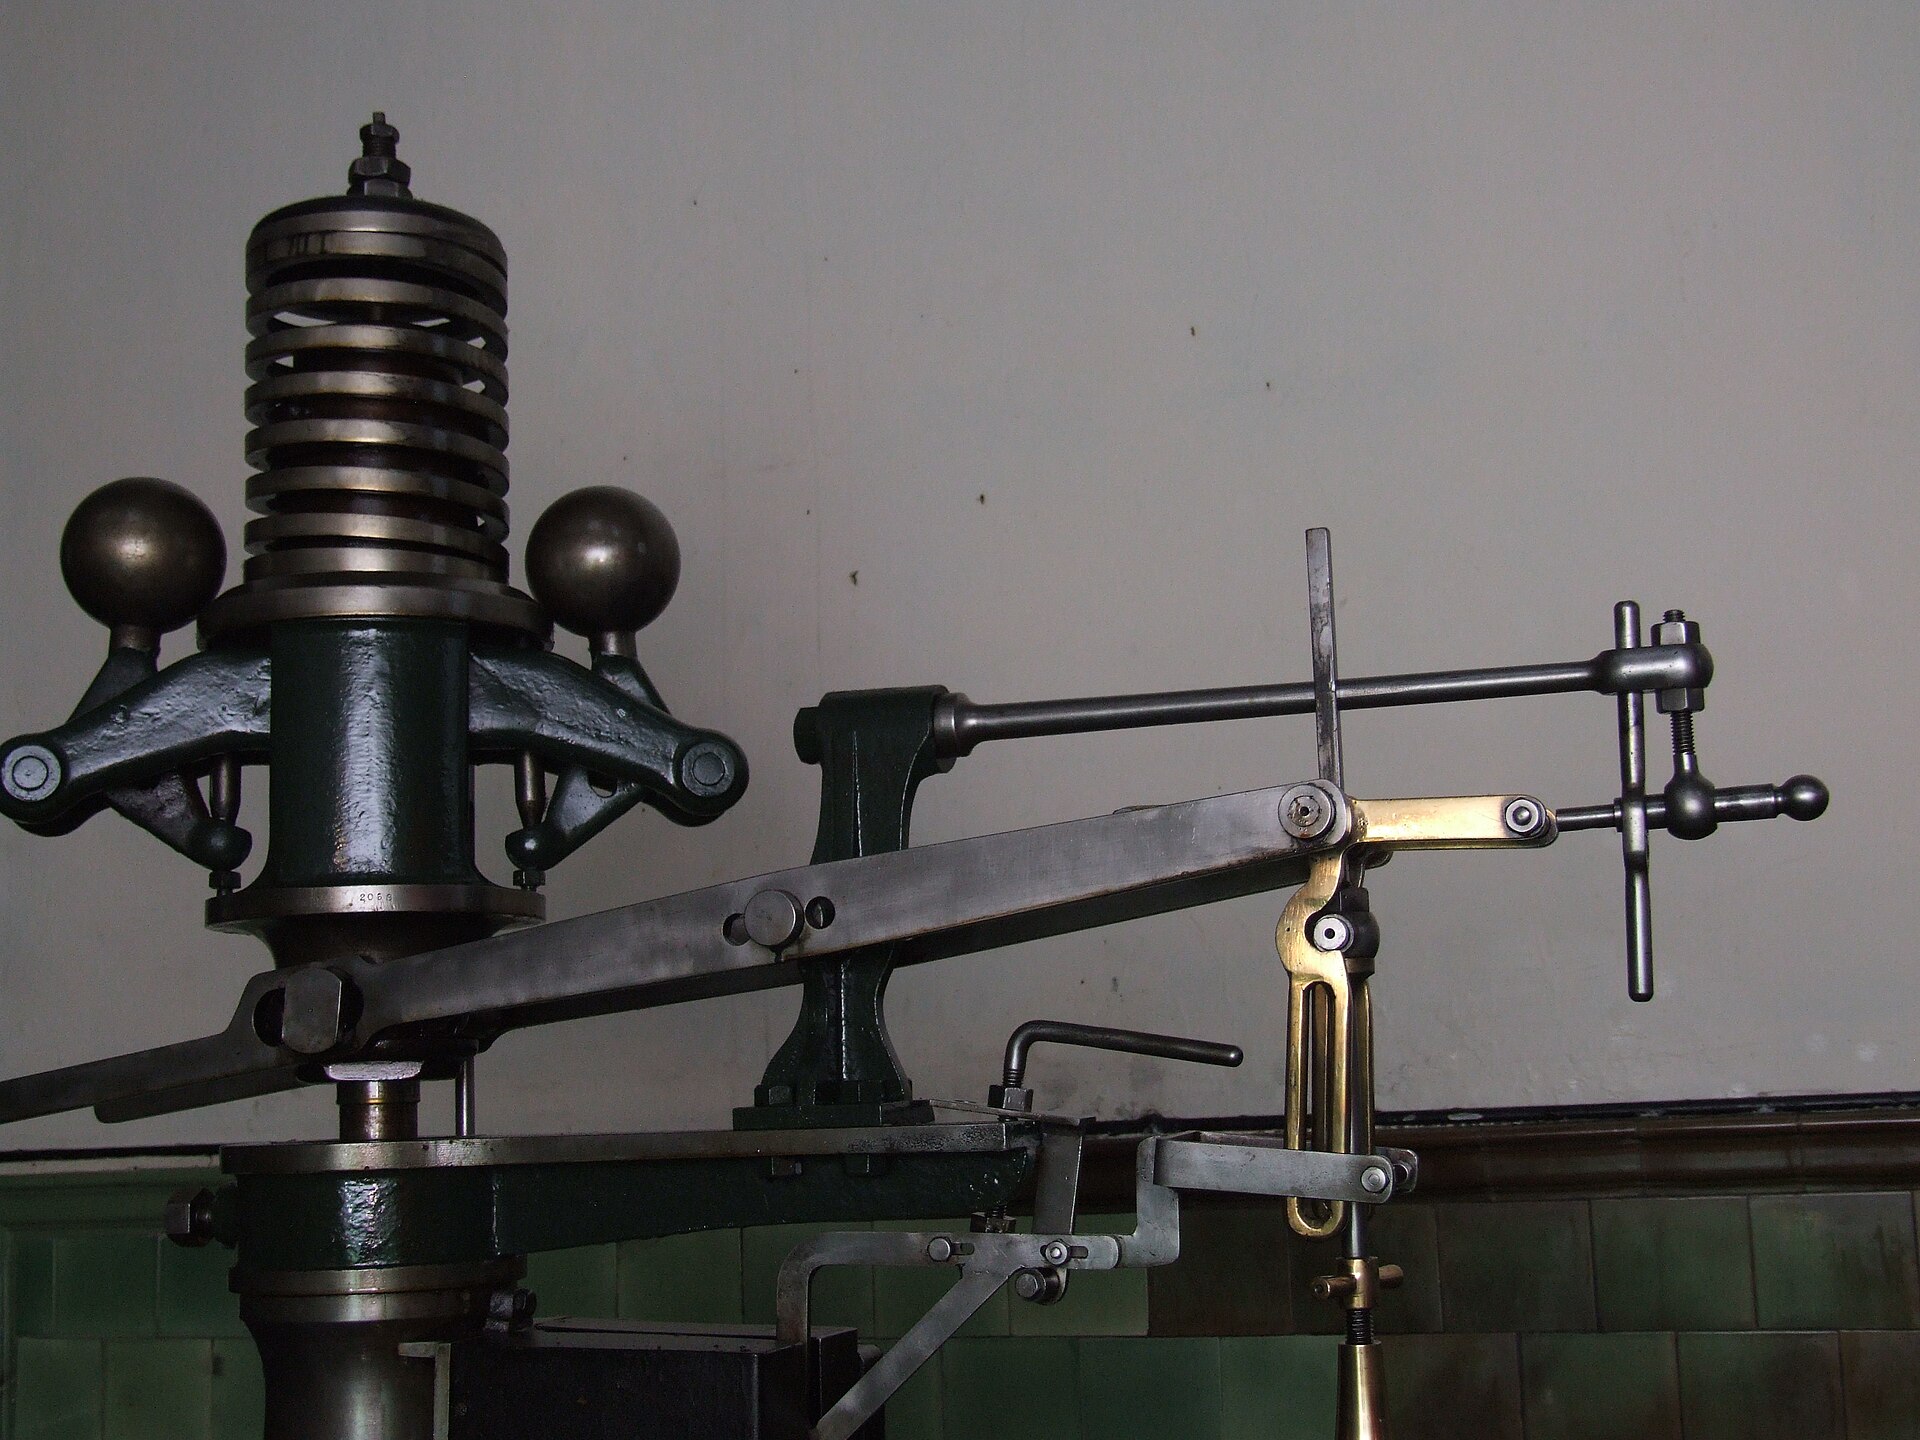
The centrifugal governor of the mill engine at Queen Street Mill, Burnley. As the engine speeds up the balls swing outward and the linkage closes the steam valve, a mechanical feedback loop. Photo: Clem Rutter / Wikimedia Commons. Licence: CC BY 3.0.Appears on: Control
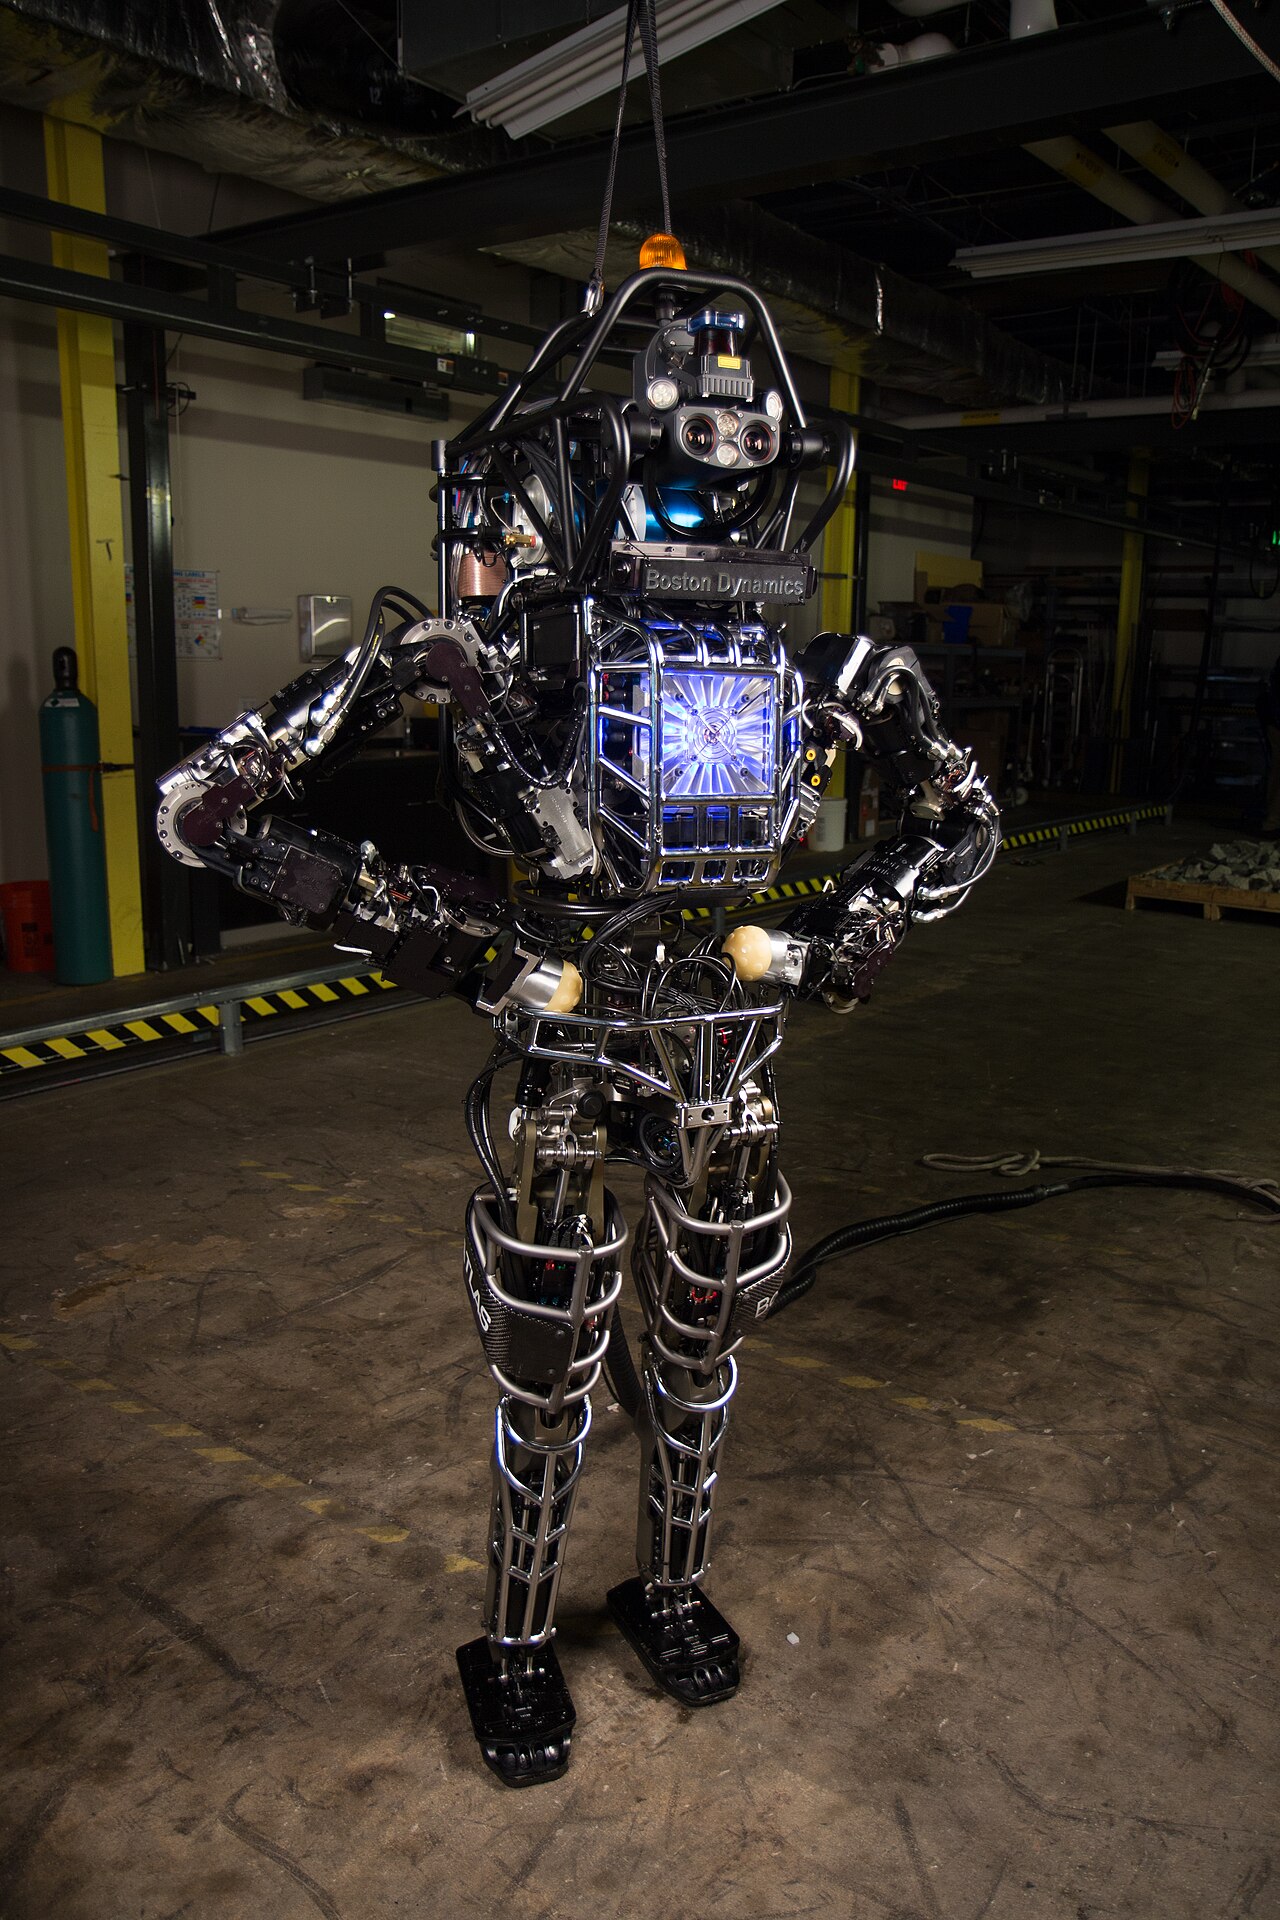
The hydraulic Atlas during 2013 testing, before its hands were fitted. Kuindersma and colleagues built its controller from optimizations running from footstep placement down to whole-body control. Photo: DARPA / Wikimedia Commons. Licence: Public domain.Appears on: Control
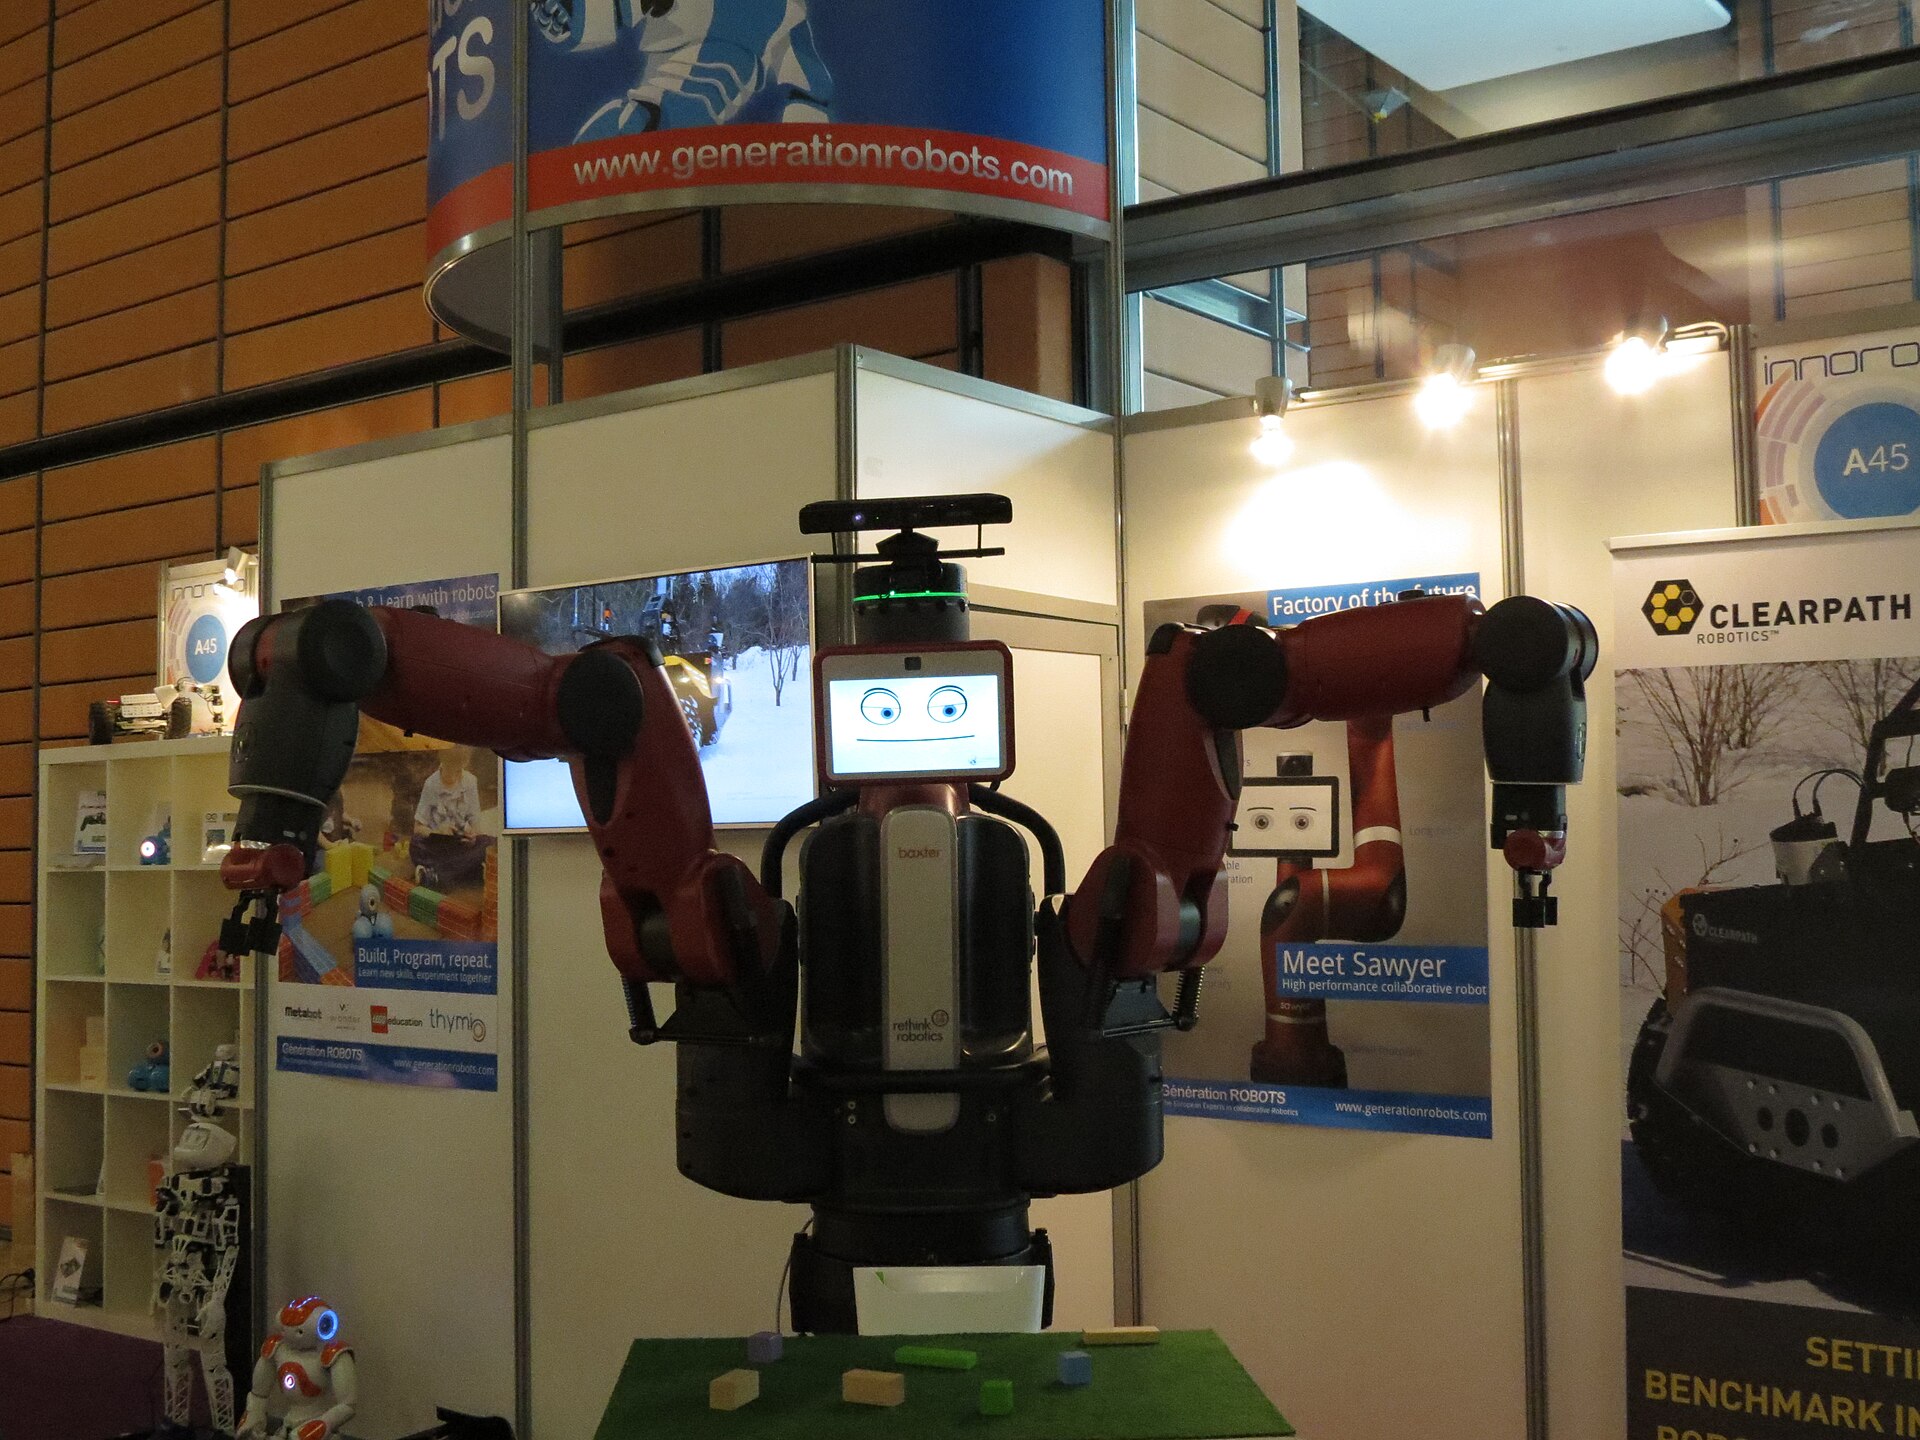
Rethink Robotics' Baxter at Innorobo 2015. Its joints drive through series elastic actuators, so a measured spring deflection gives the arm the force channel a stiff geared arm lacks. Photo: Scailyna / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Control
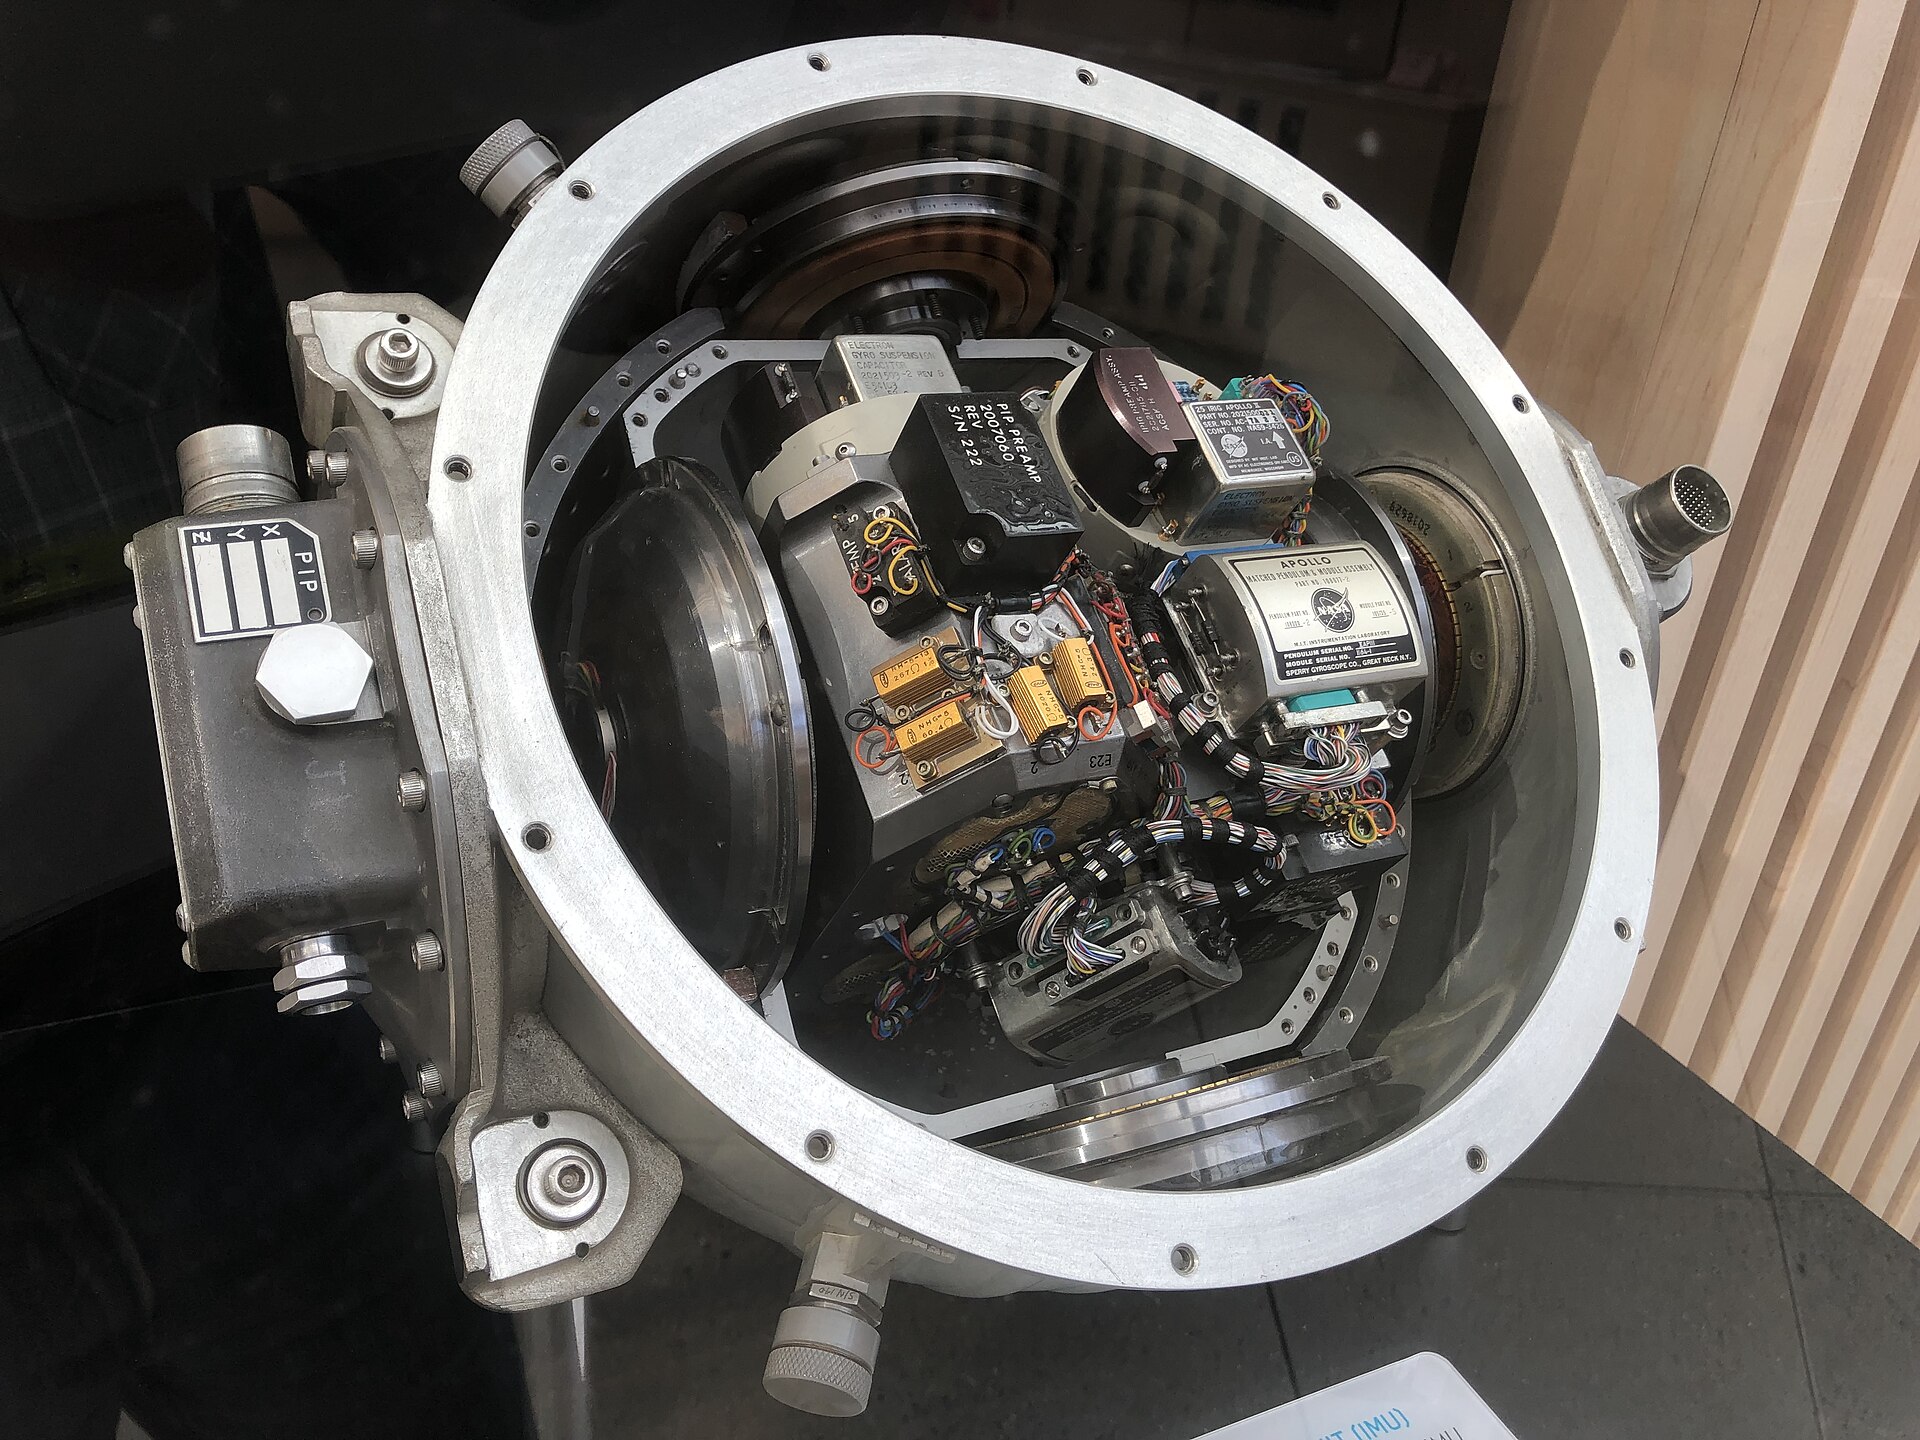
An Apollo inertial measurement unit at Draper's 2019 Hack the Moon exhibit. Its gyroscopes and accelerometers integrate motion and drift over time, so an estimator must correct them with outside measurements. Photo: ArnoldReinhold / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: State Estimation
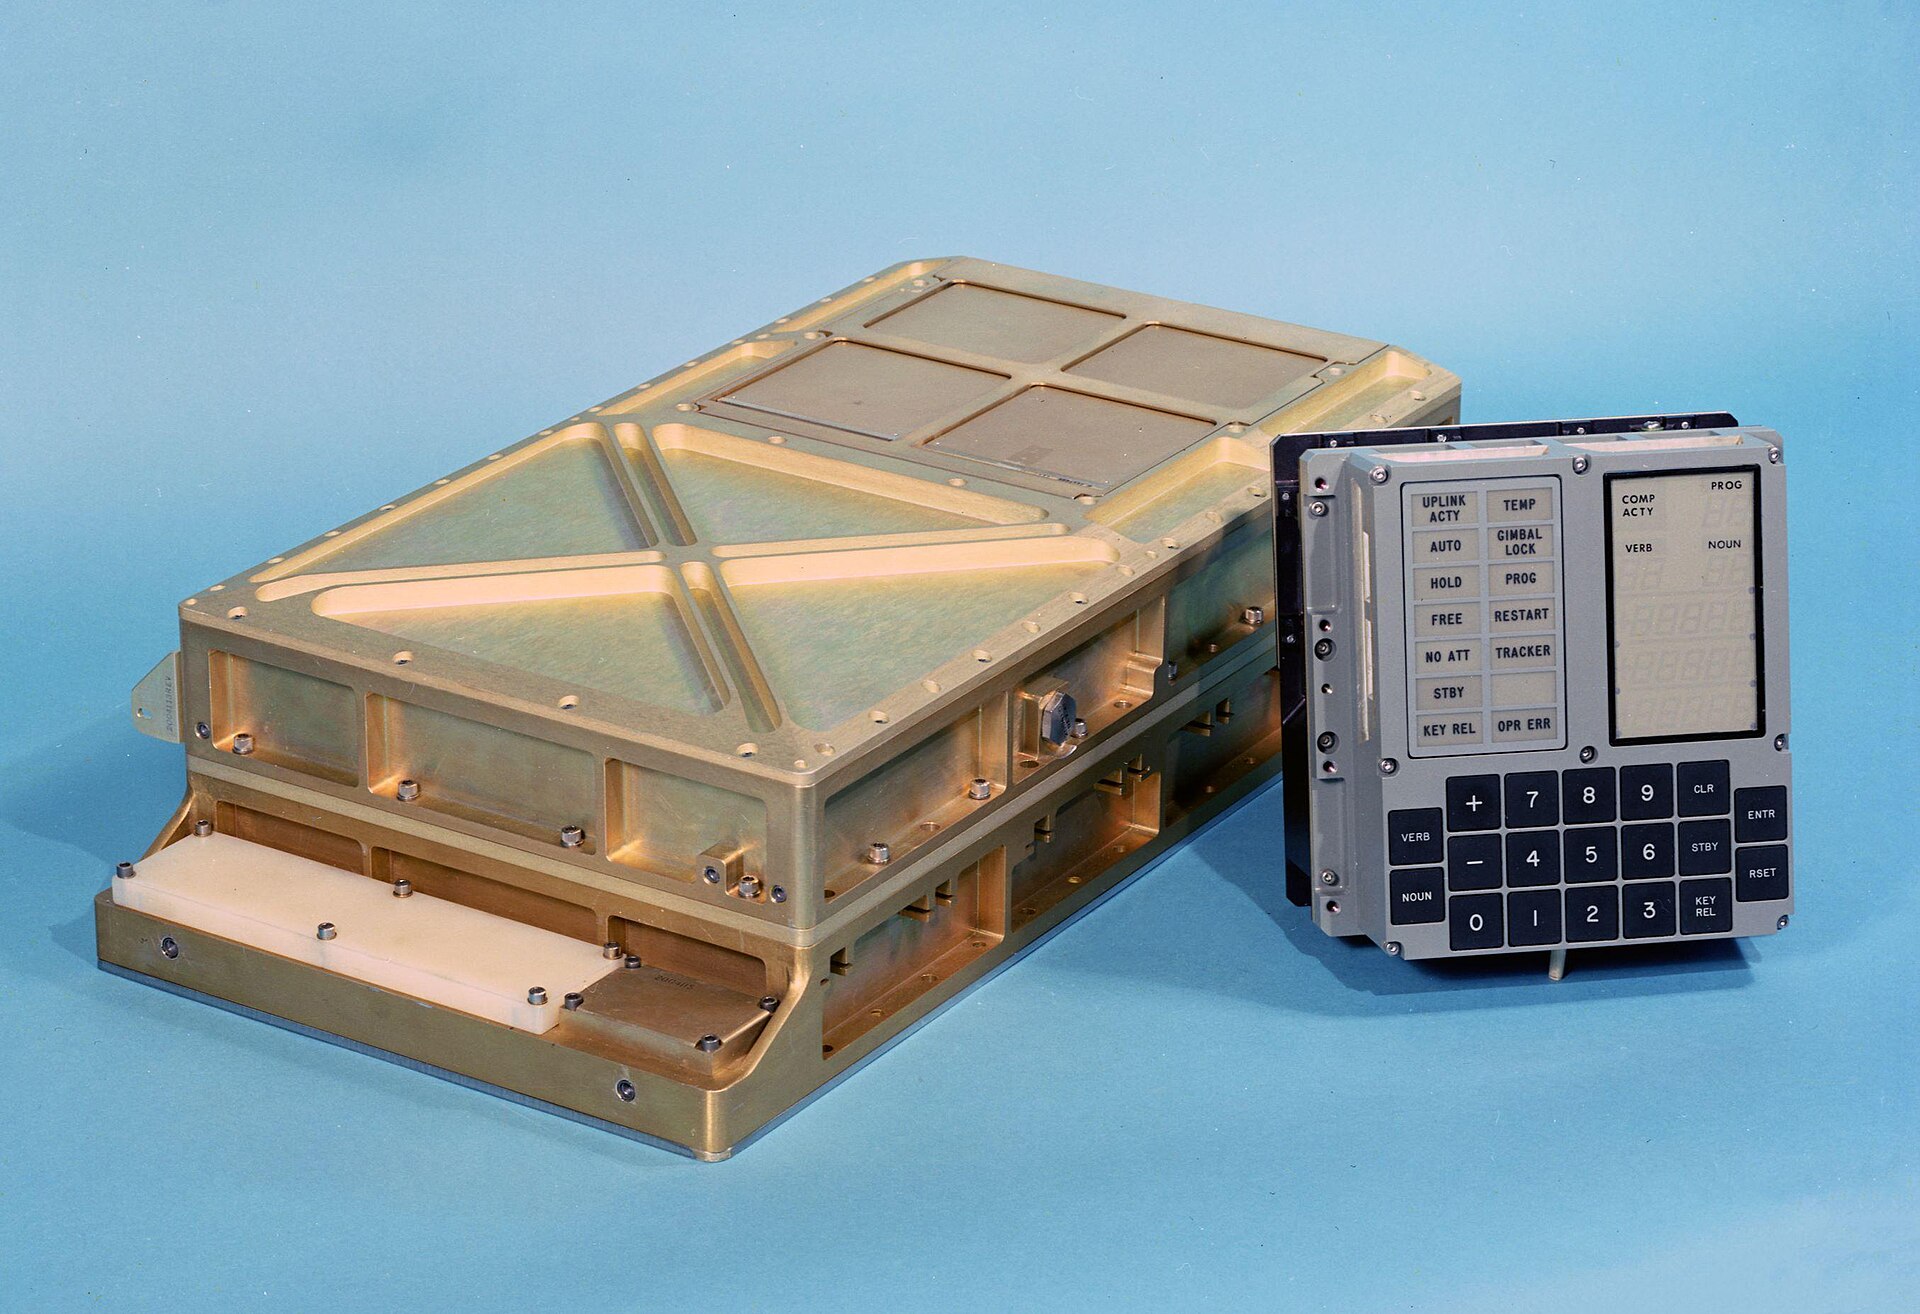
The Apollo Guidance Computer and its display and keyboard. Apollo used Potter's square-root form of the Kalman filter, with ground radar as primary navigation and the onboard system as backup. Photo: NASA / Wikimedia Commons. Licence: Public domain.Appears on: State Estimation
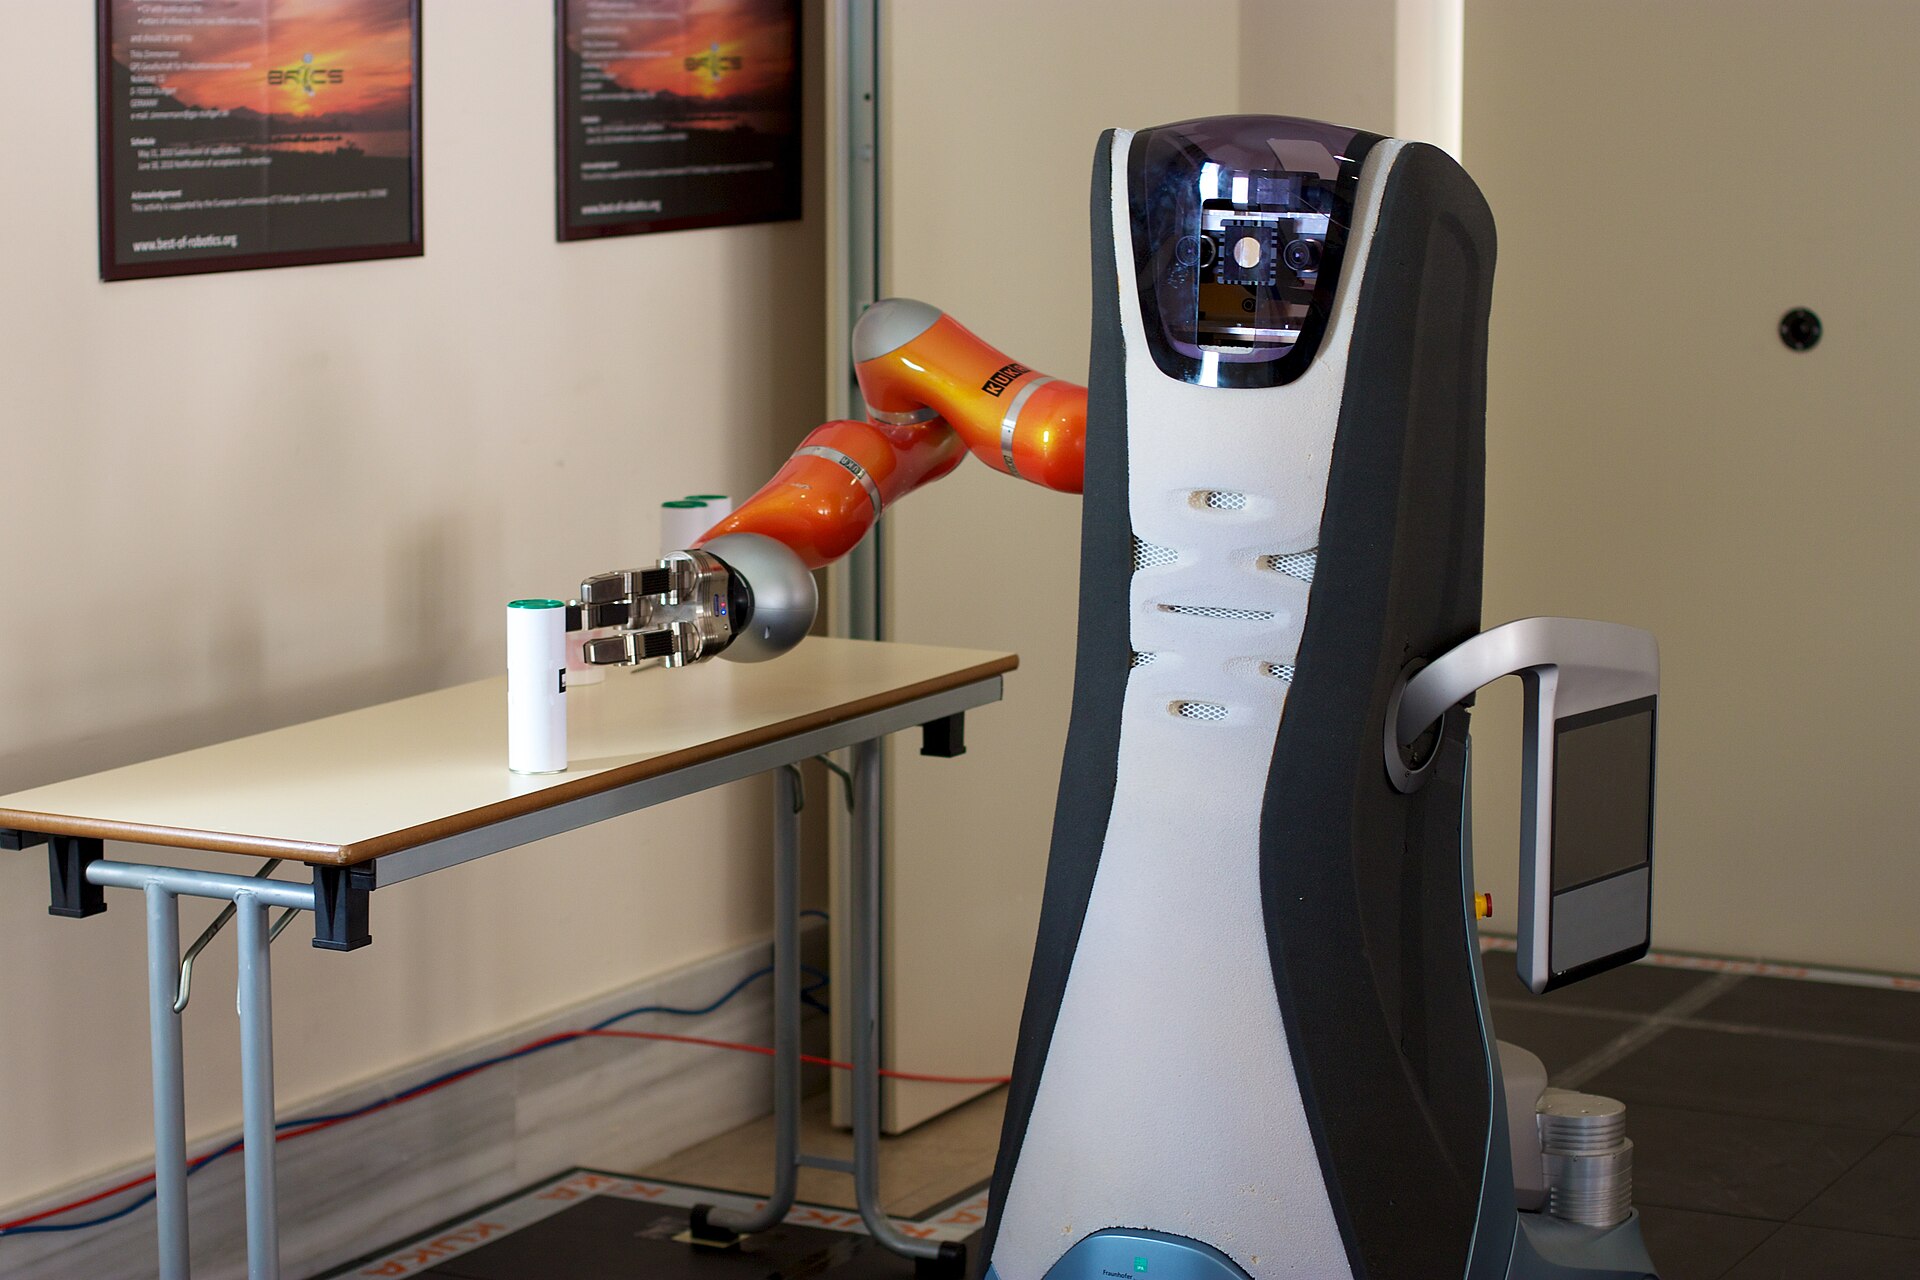
A Care-O-bot service robot grasping a cylinder in 2010. A grasp planner chooses where its fingertips touch so the hold resists pushes and pulls from every direction. Photo: Jiuguang Wang / Wikimedia Commons. Licence: CC BY-SA 2.0.Appears on: Grasp Planning
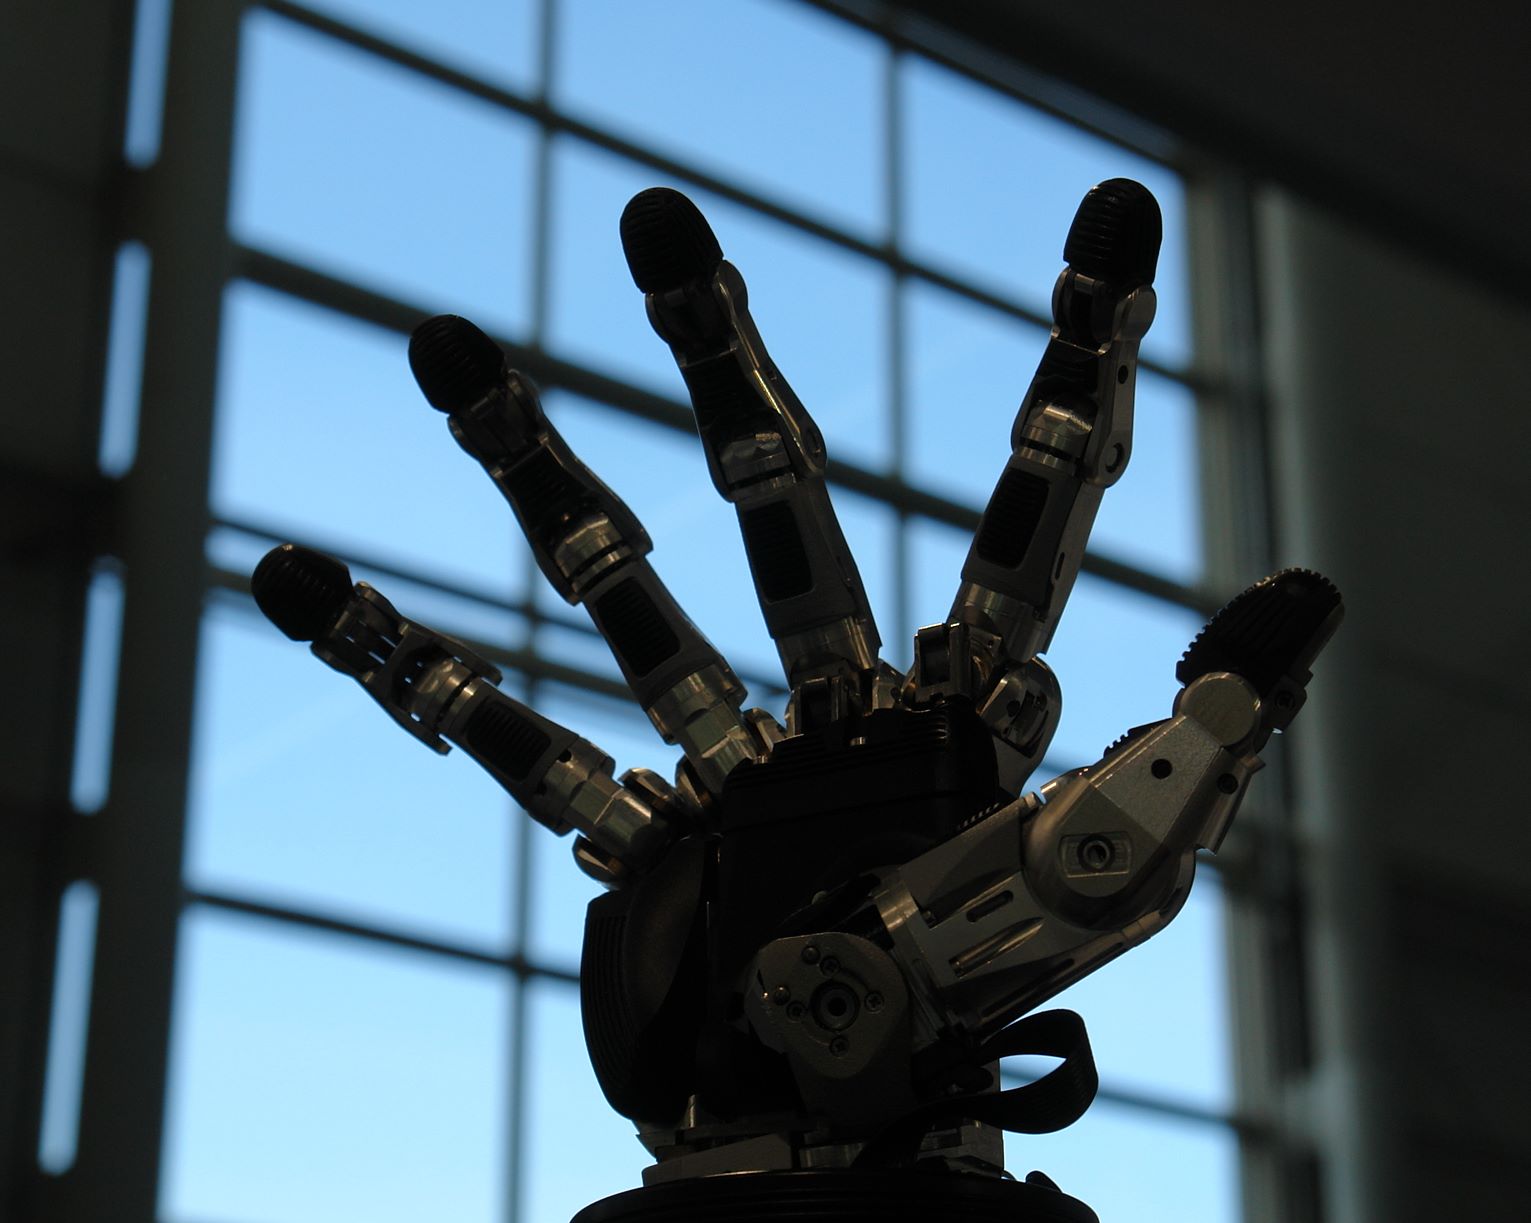
The Schunk SVH, a servo-electric five-finger hand. Every fingertip or phalanx that touches an object is one contact, and the contact model fixes which forces it can transmit. Photo: NearEMPTiness / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Grasp Planning
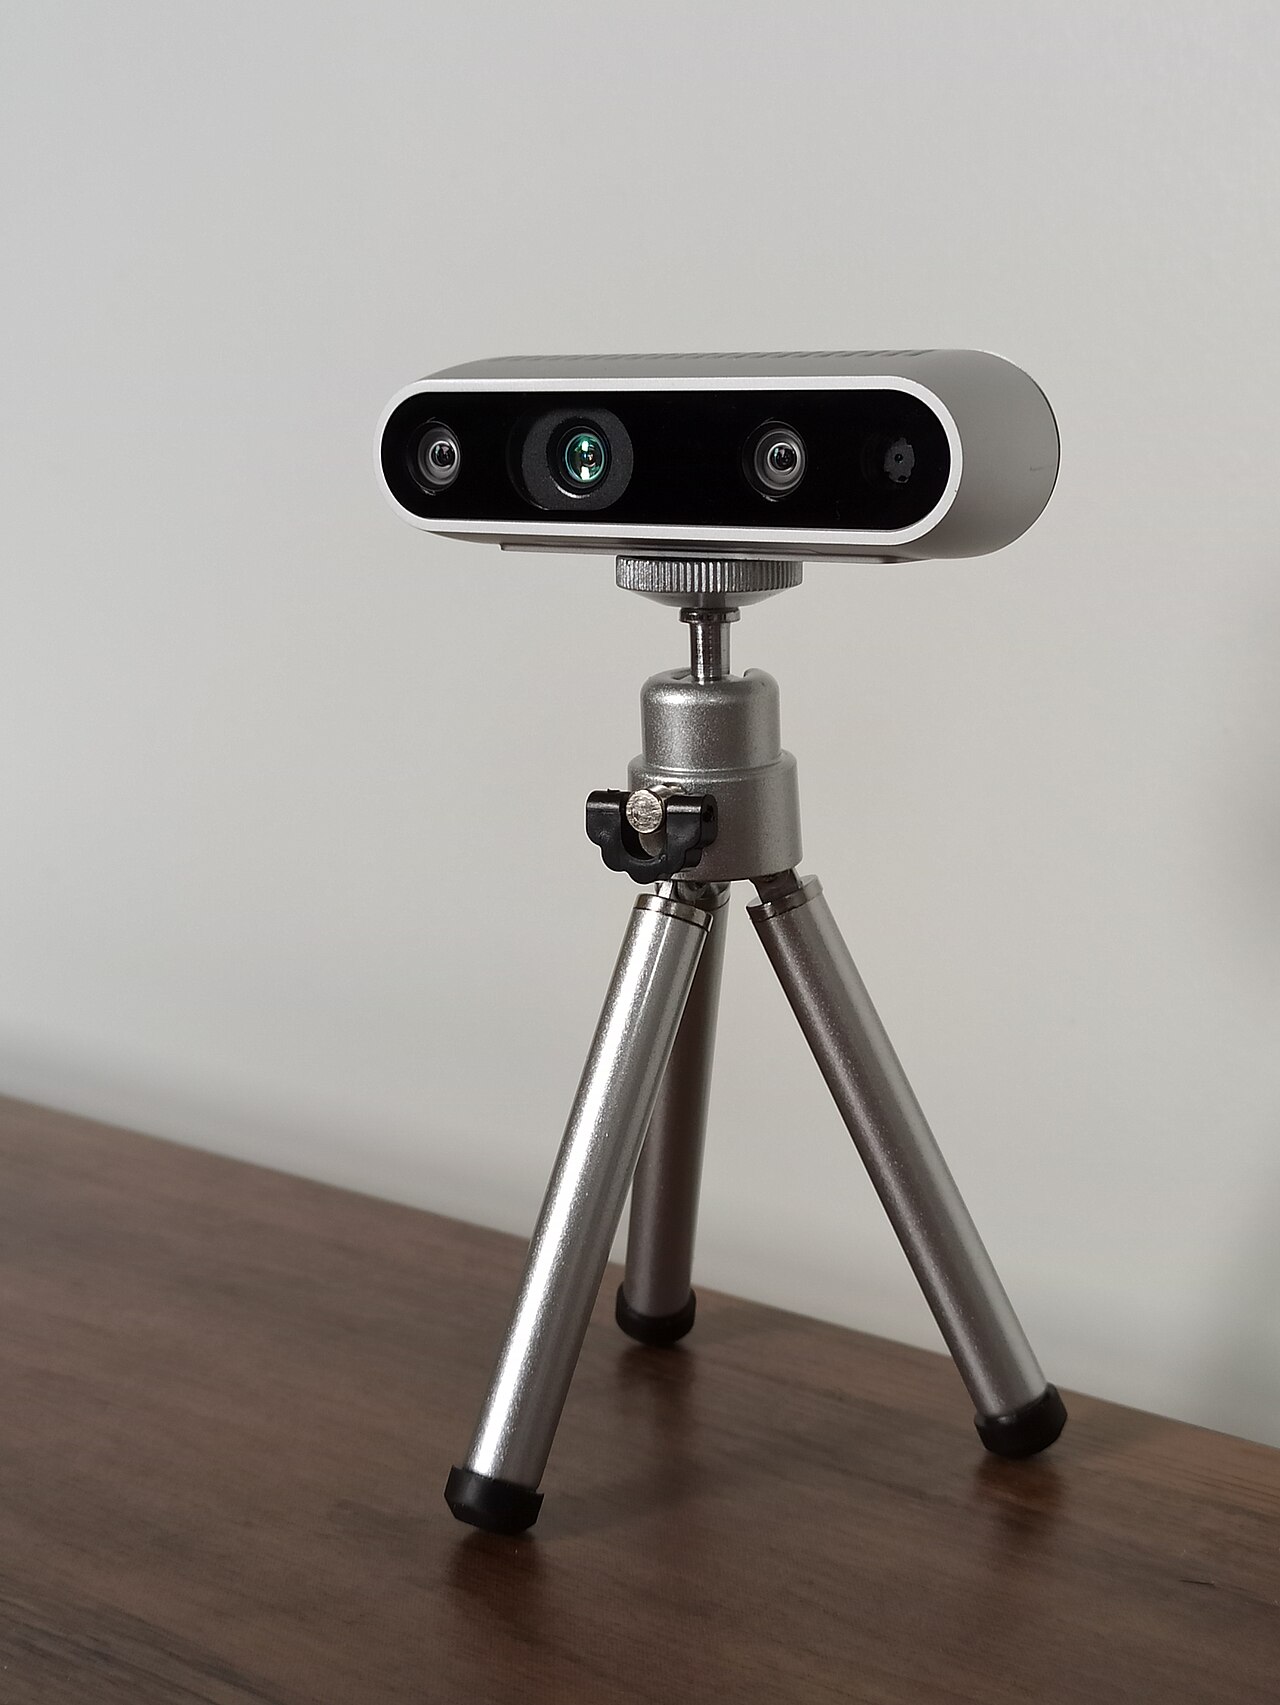
An Intel RealSense D435, an active stereo camera common on manipulation rigs. Its projector adds texture so matching works on blank surfaces, and its depth error grows with the square of distance. Photo: Marc Auledas / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Perception for Manipulation
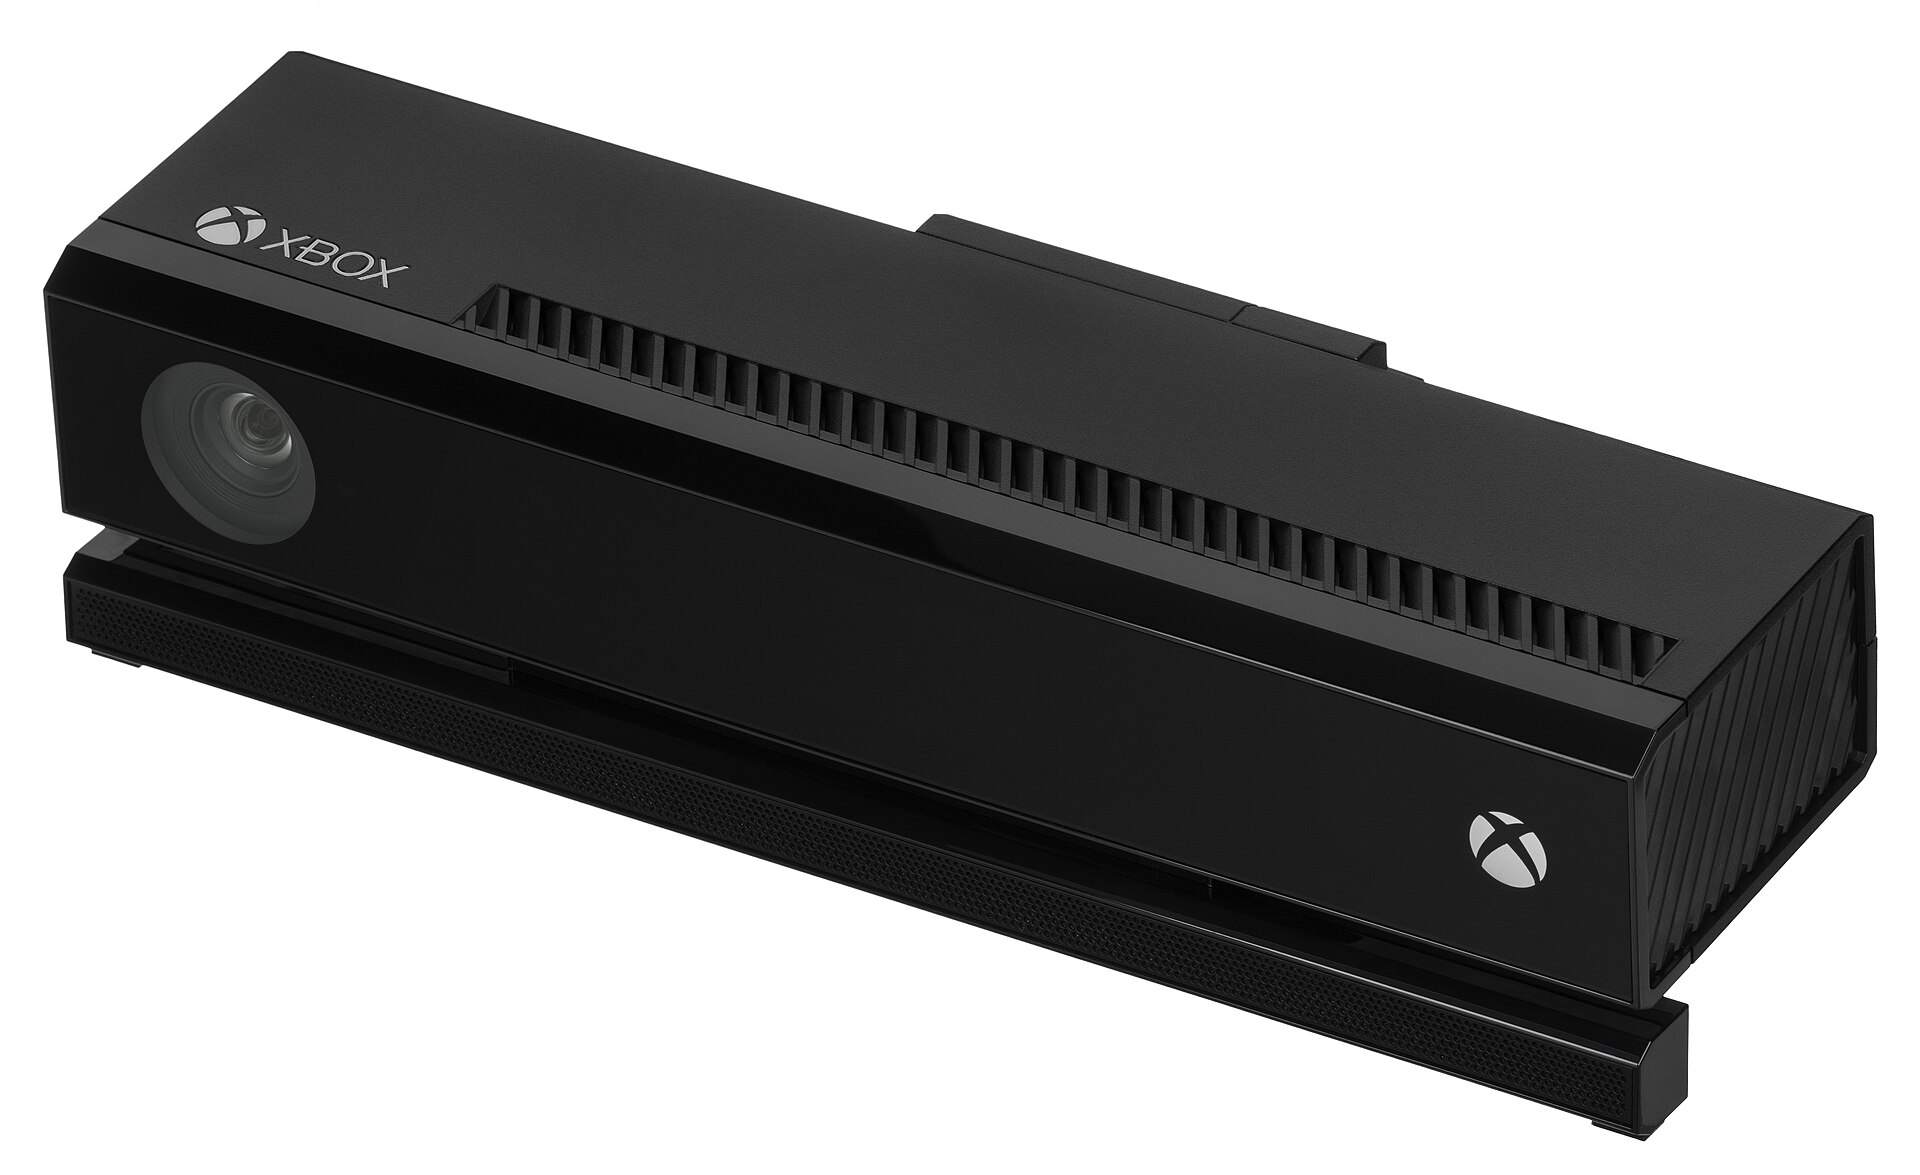
The Kinect for Xbox One measured depth by time of flight, the principle its successor Azure Kinect kept. Multi-path light and weak infrared returns invalidate pixels on both. Photo: Evan-Amos / Wikimedia Commons. Licence: Public domain.Appears on: Perception for Manipulation
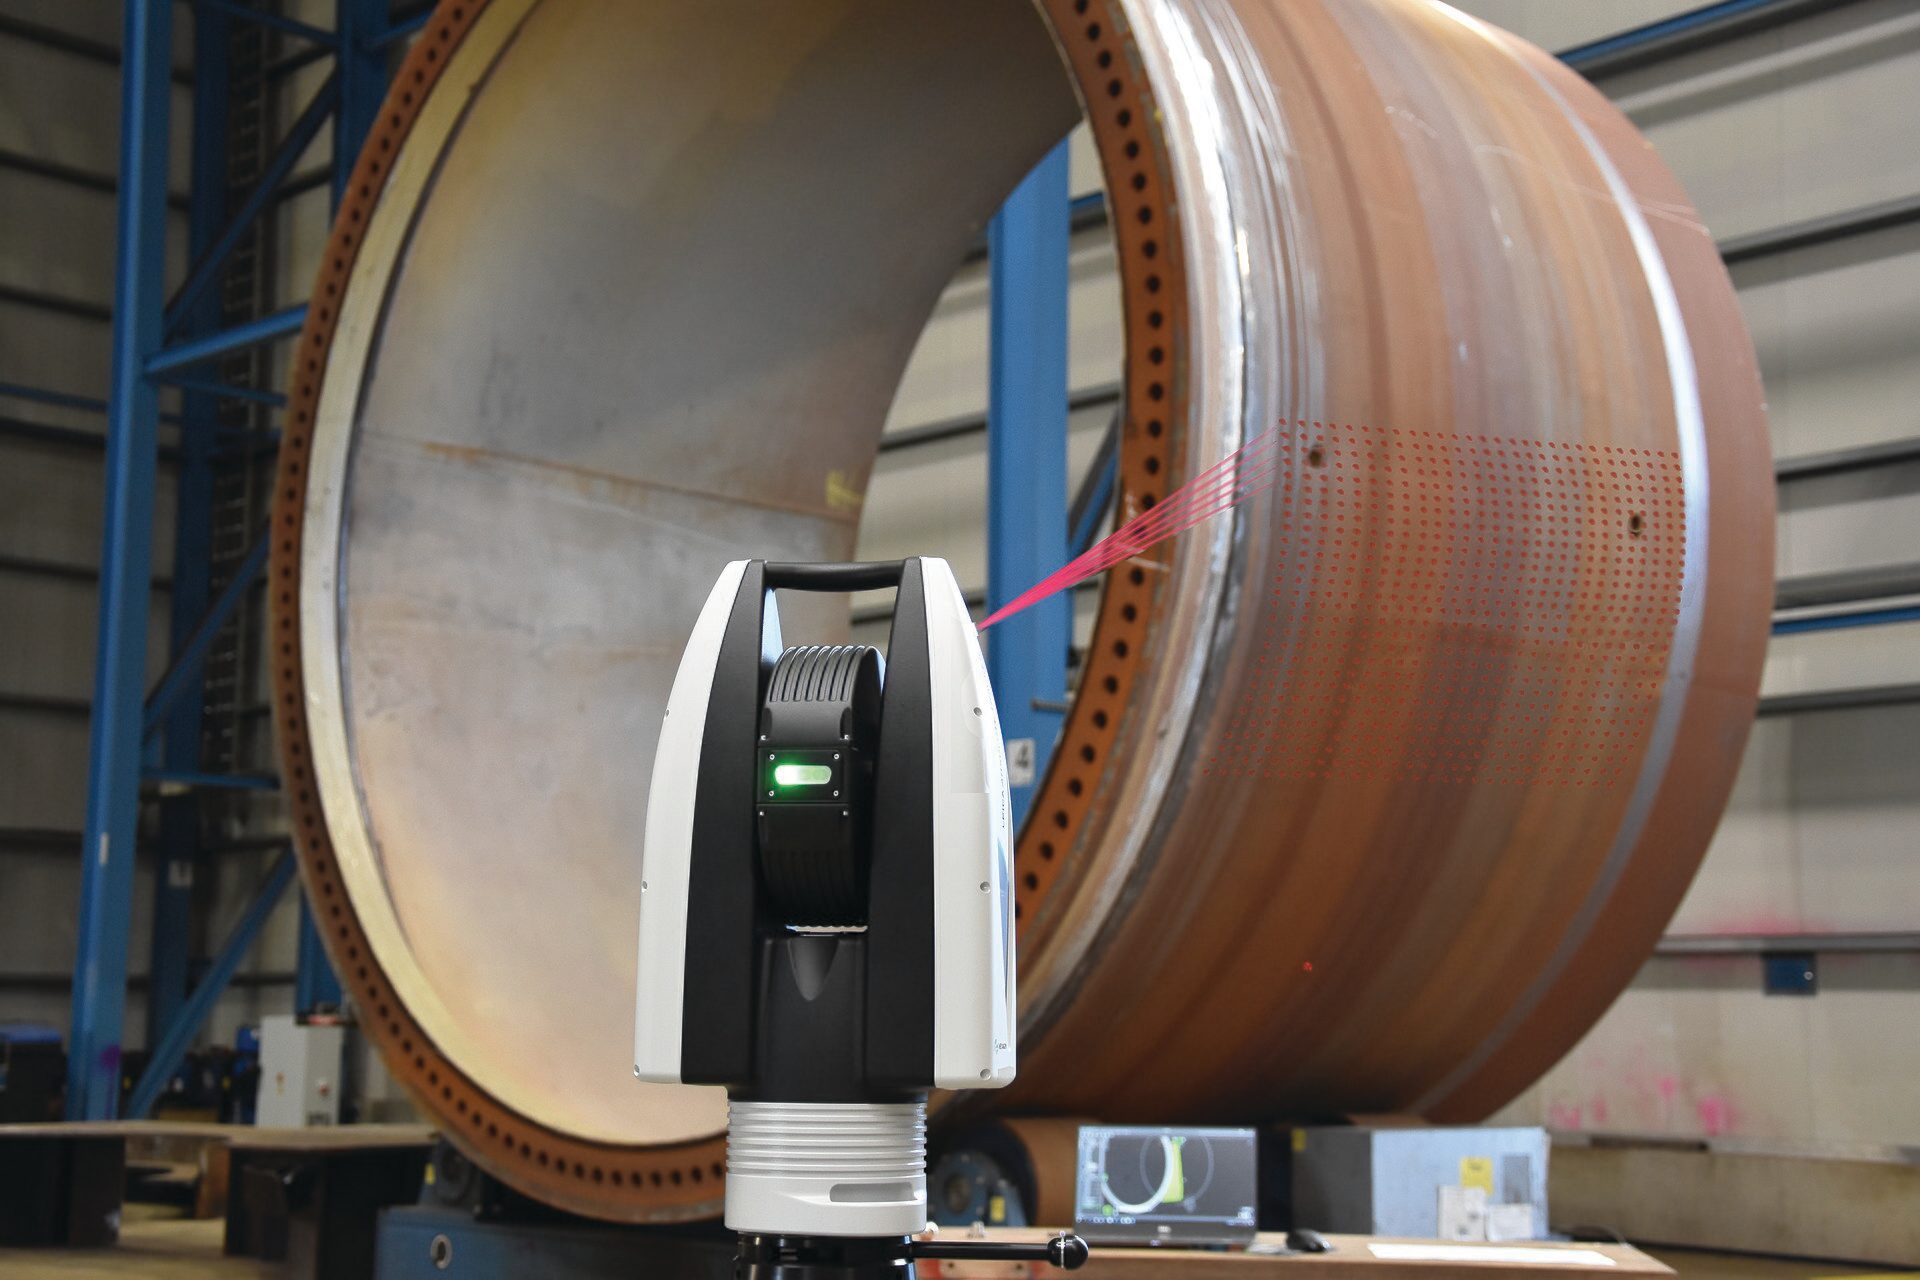
A Leica ATS600 laser tracker measuring a large steel part. Kinematic calibration relies on external instruments like this for its measurement step, recording where the tool really is. Photo: FanchonH / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Robot Calibration
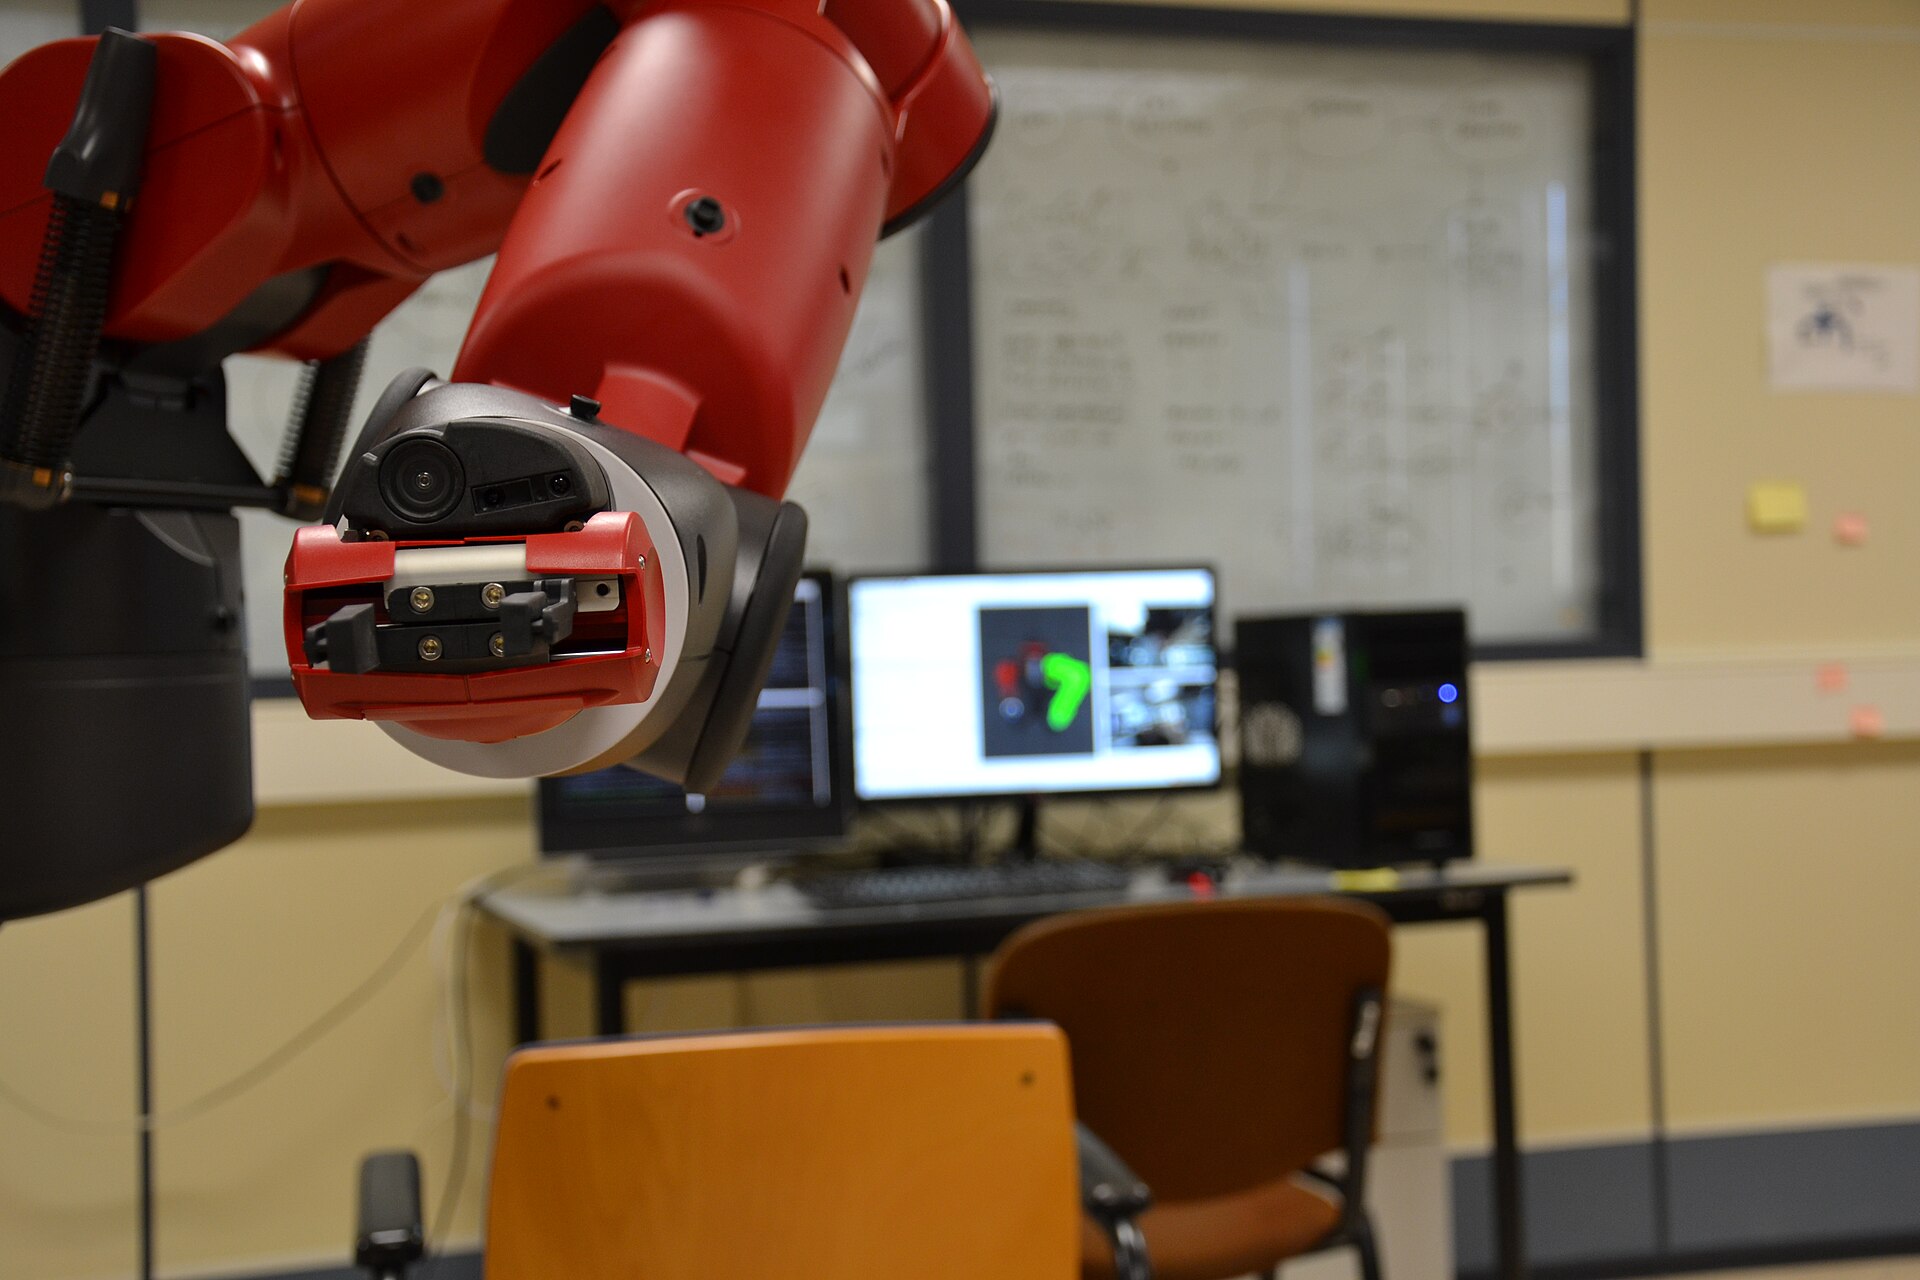
Baxter's wrist carries a camera beside its gripper. Hand-eye calibration solves AX = XB for the fixed transform between that camera and the gripper. Photo: Gustavo A. Casañ / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Robot Calibration
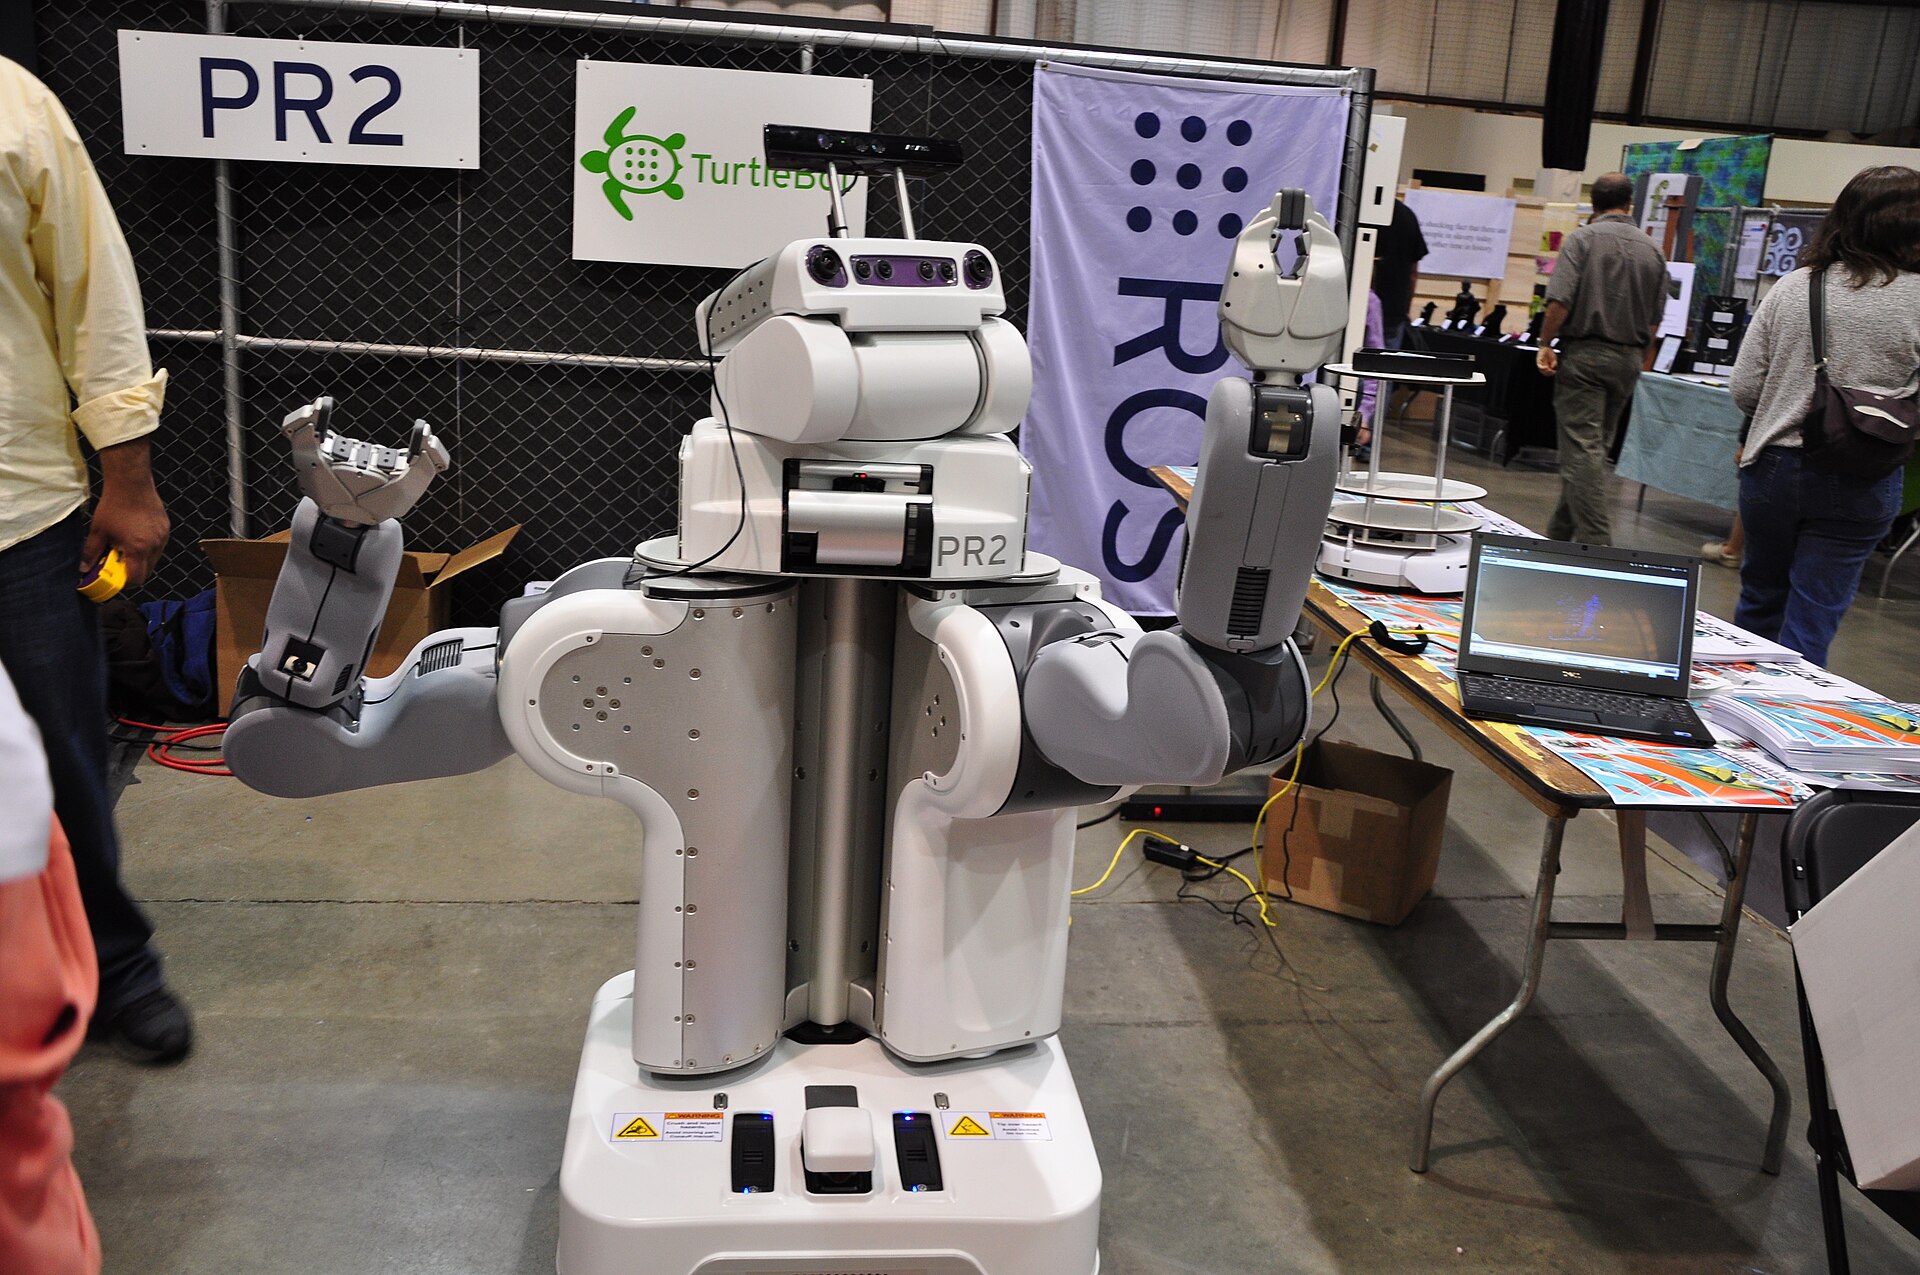
A Willow Garage PR2 under the ROS banner at Maker Faire 2011. Willow Garage developed ROS alongside this robot, and ROS 2 is its rebuild for production use. Photo: Timothy Vollmer / Wikimedia Commons. Licence: CC BY 2.0.Appears on: ROS 2 for Machine Learning Engineers
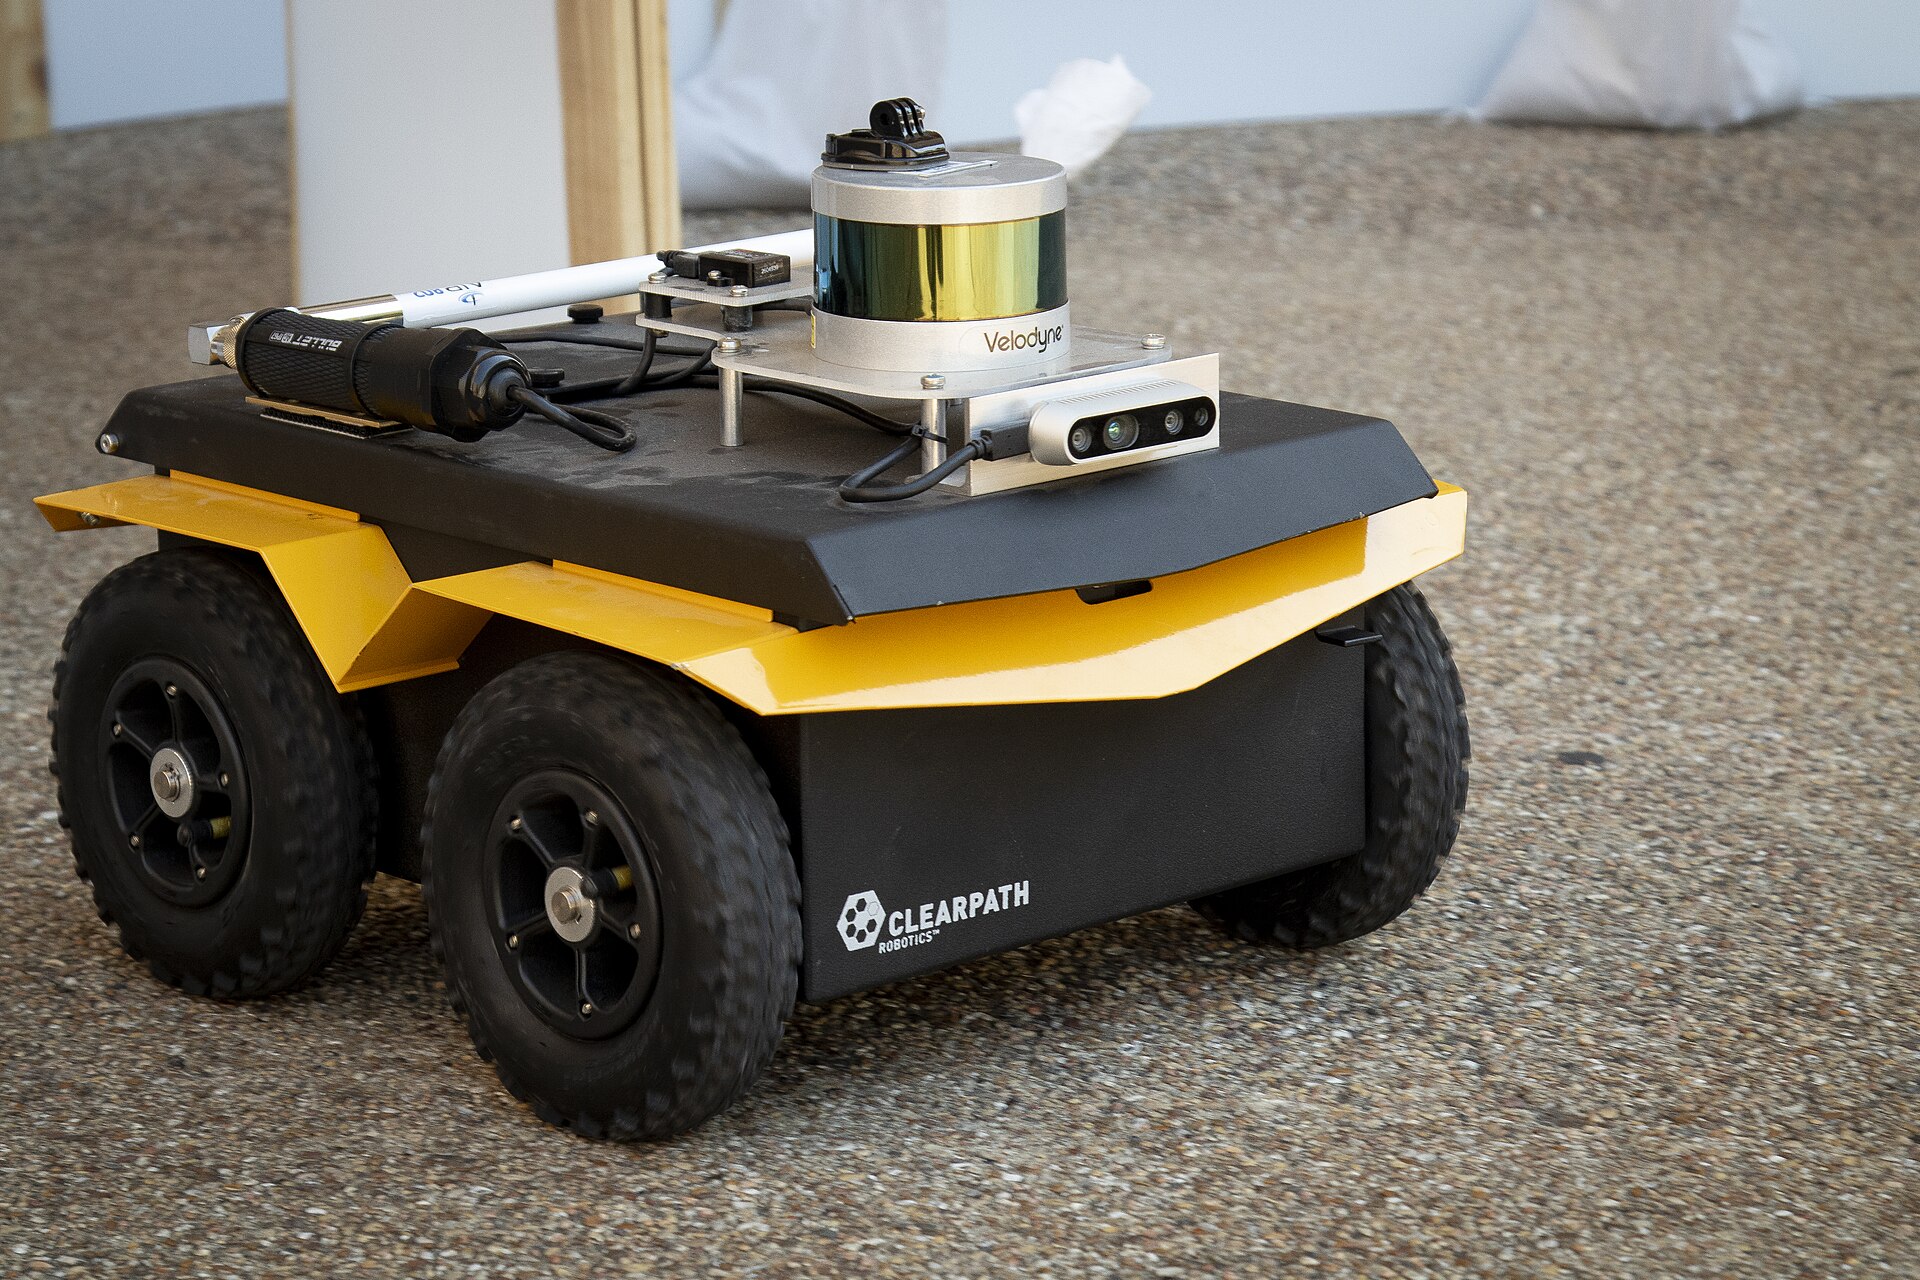
A Clearpath Jackal at the University of Texas robotics center in 2020. Wheeled research bases like it run Nav2, whose planner, controller and recovery servers are ordinary ROS 2 nodes. Photo: U.S. Army / Luke J. Allen / Wikimedia Commons. Licence: Public domain.Appears on: ROS 2 for Machine Learning Engineers
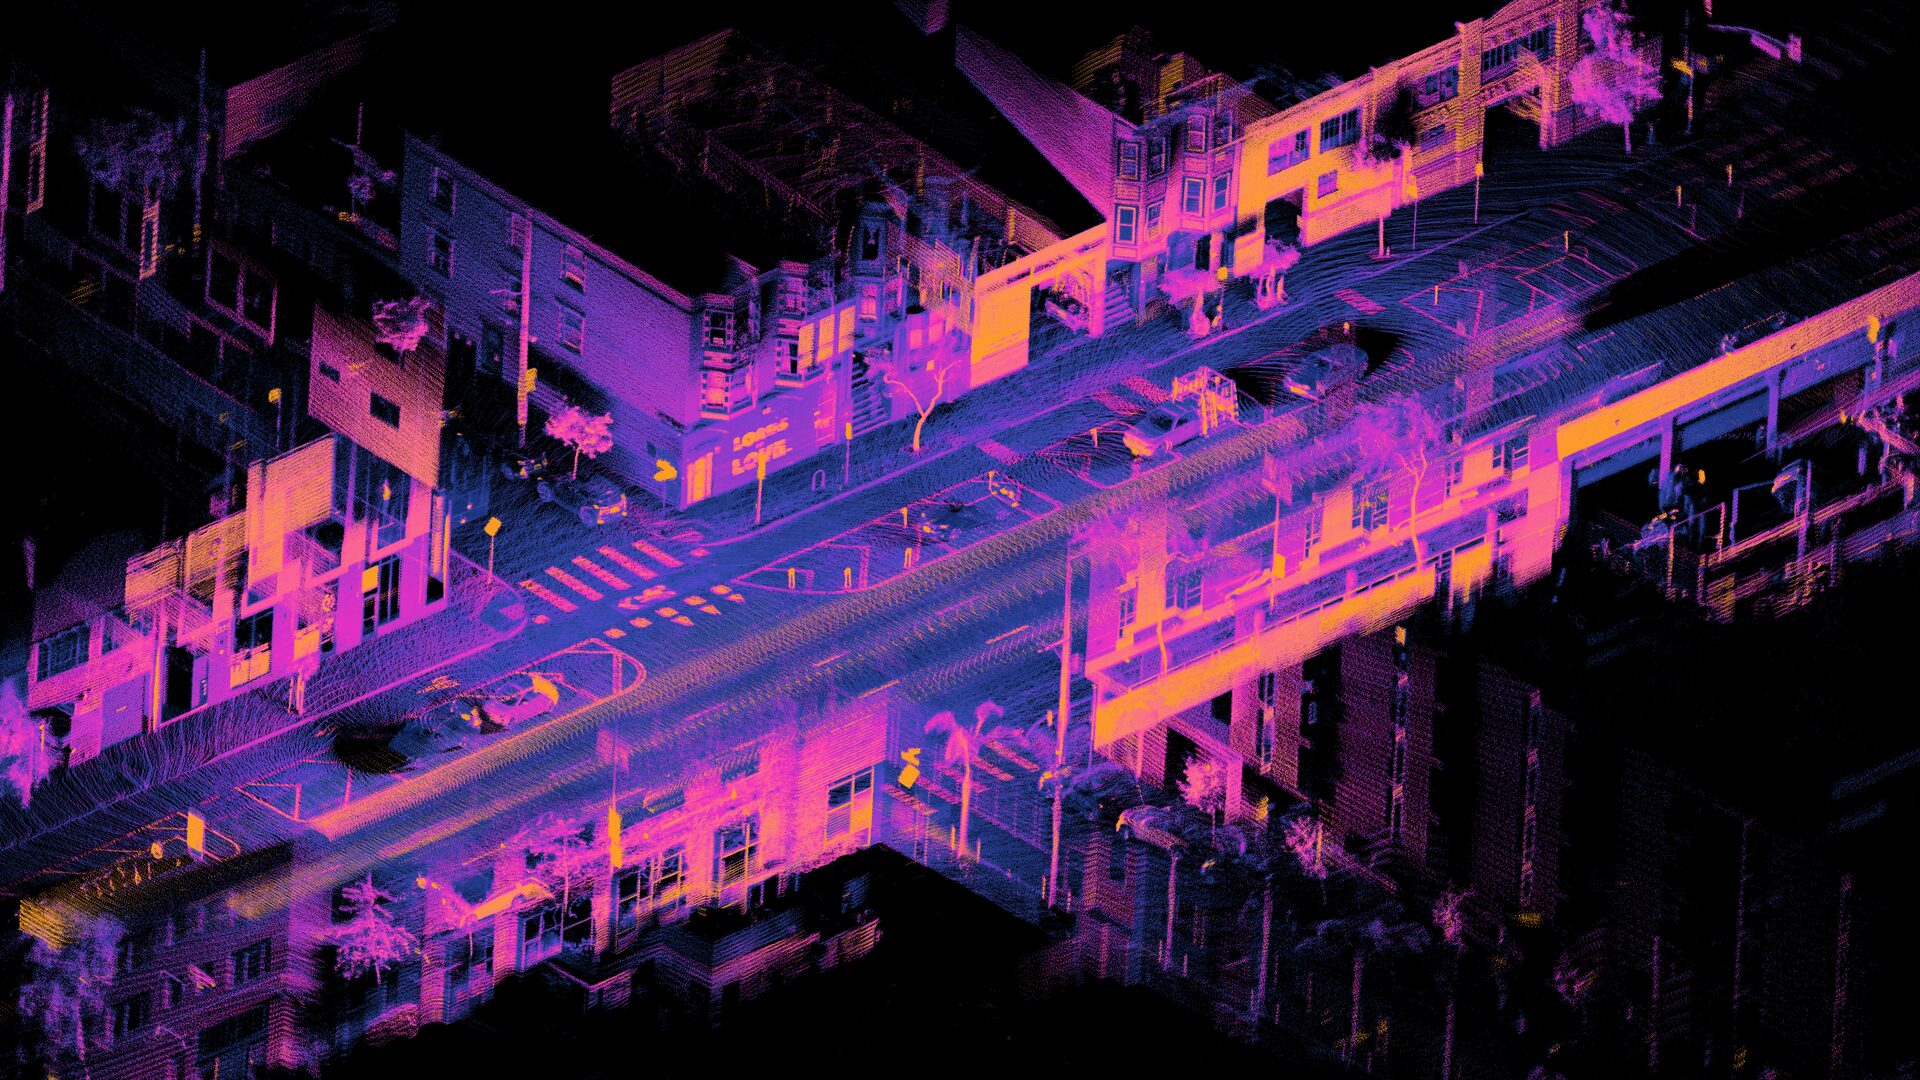
About 23 million lidar points of a San Francisco intersection, captured in 18 seconds by an Ouster OS1 on a moving car and registered by SLAM. A point cloud is the first rung of the ladder below. Photo: Daniel L. Lu / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Scene Representation and Mapping
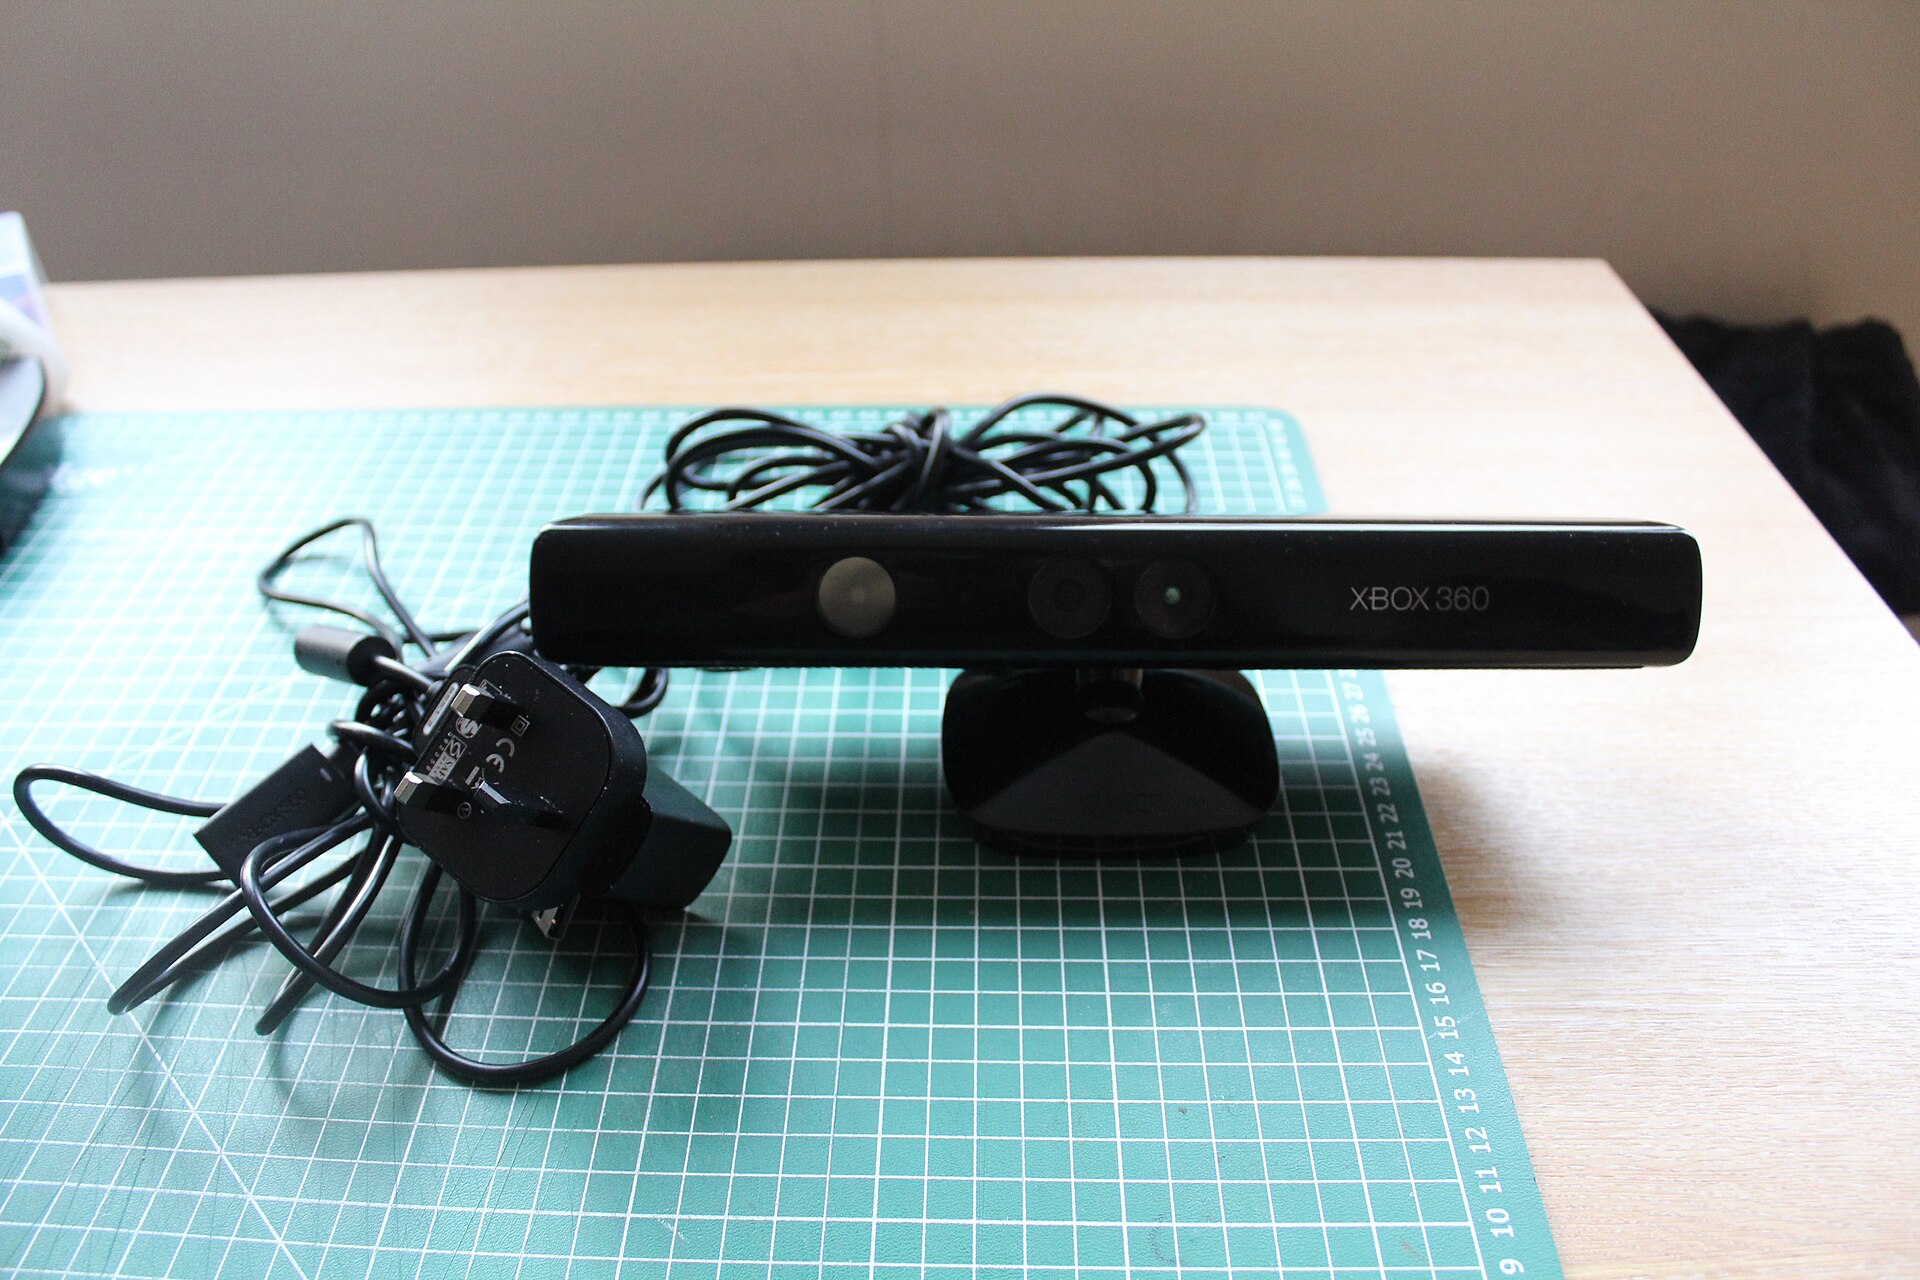
A first-generation Kinect for Xbox 360. KinectFusion fused this sensor's 640×480 depth frames at 30 Hz into a truncated signed-distance volume on one GPU. Photo: Antonio Roberts / Wikimedia Commons. Licence: CC BY-SA 2.0.Appears on: Scene Representation and Mapping
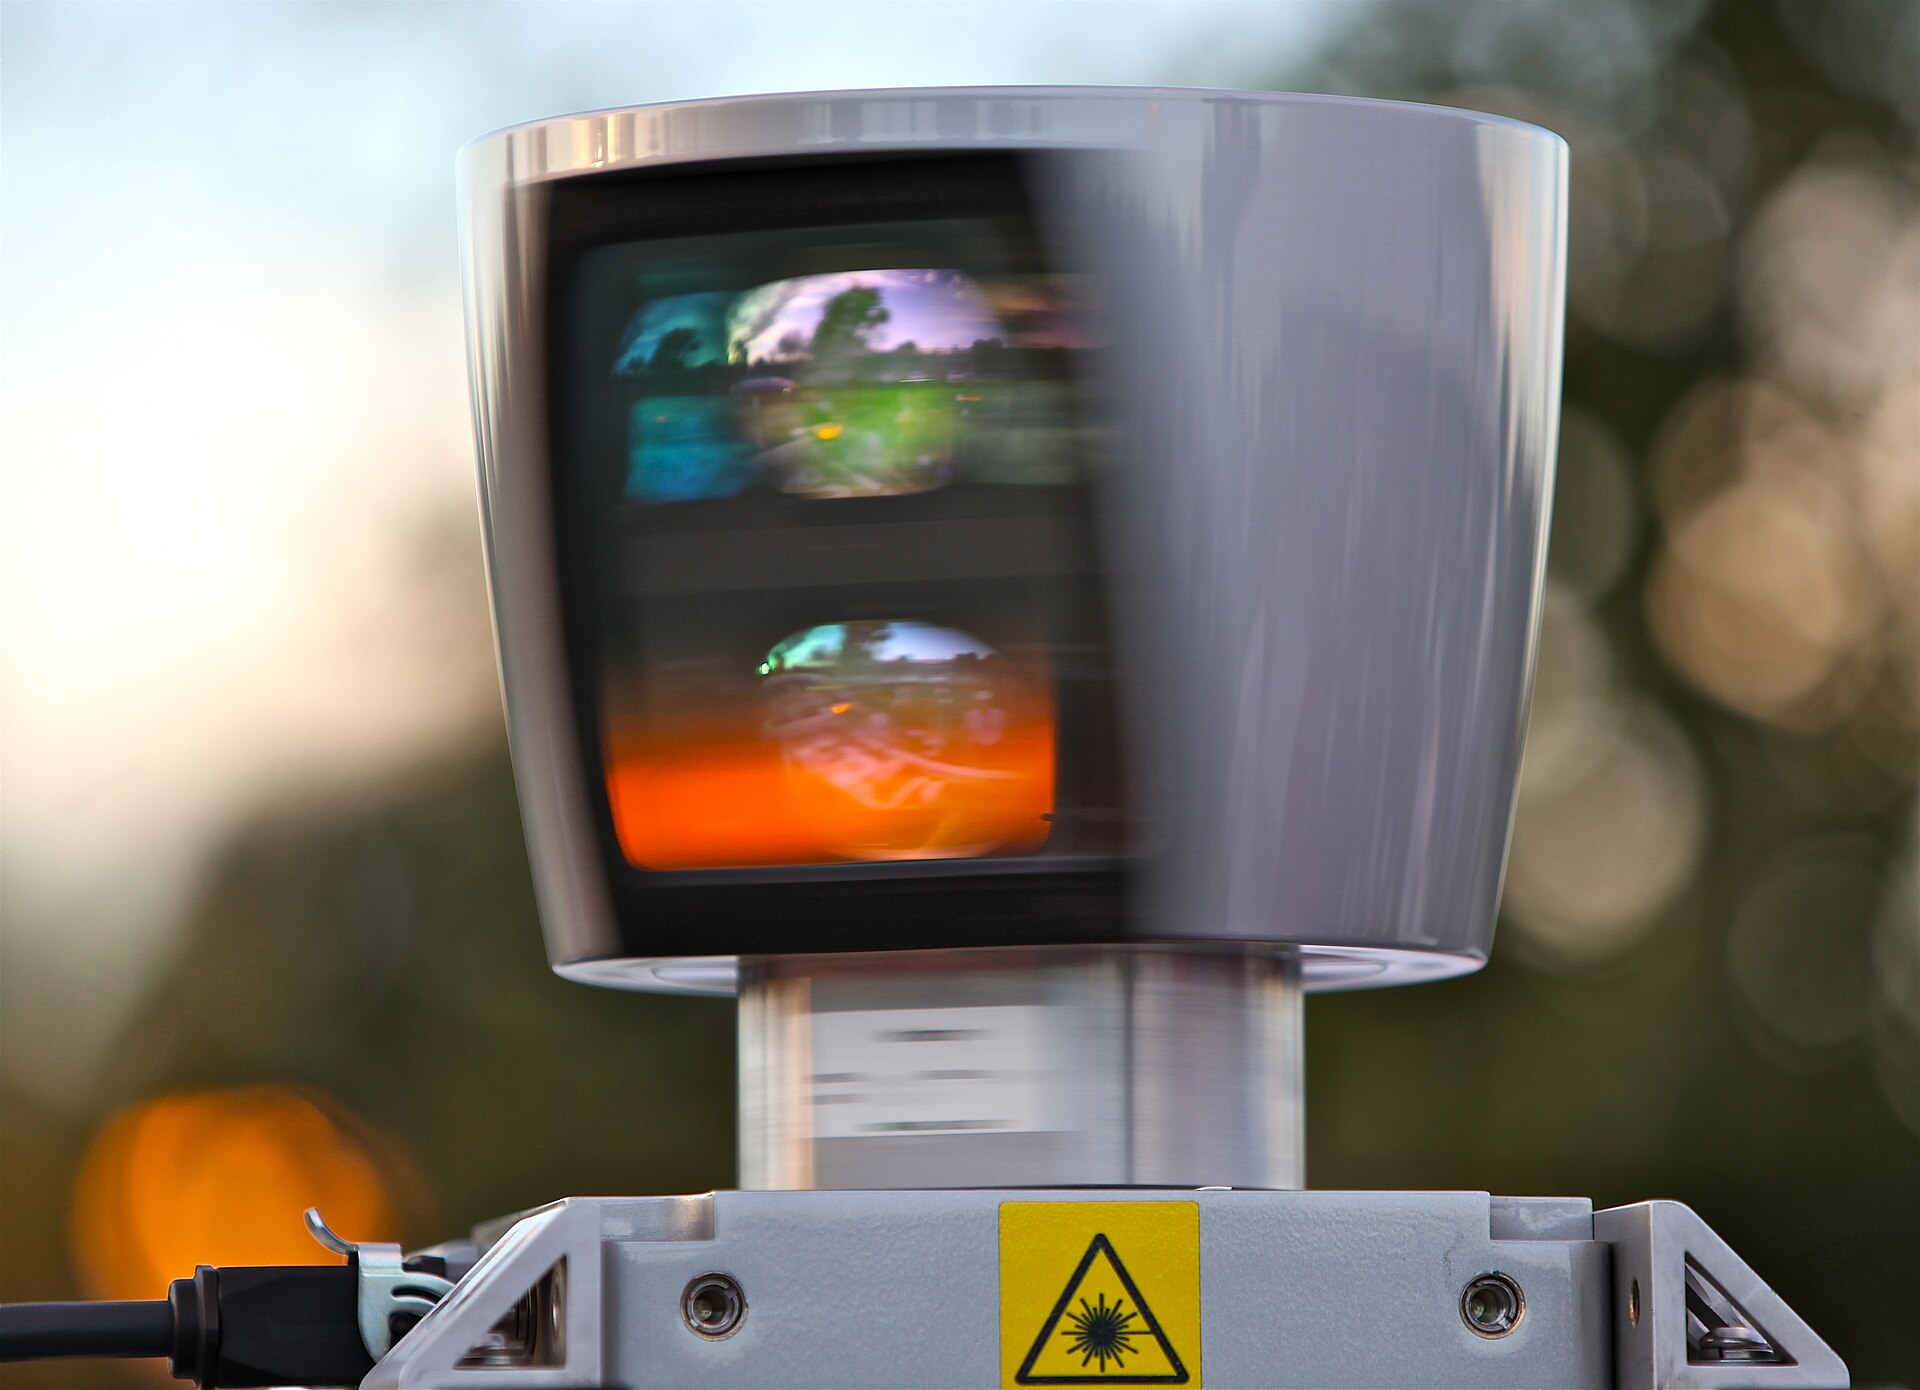
A Velodyne HDL-64E on Junior 2, Stanford's autonomous Volkswagen, in 2009. Its 64 spinning beams return over a million points a second, the raw input of a lidar SLAM front end. Photo: Steve Jurvetson / Wikimedia Commons. Licence: CC BY 2.0.Appears on: Scene Representation and Mapping
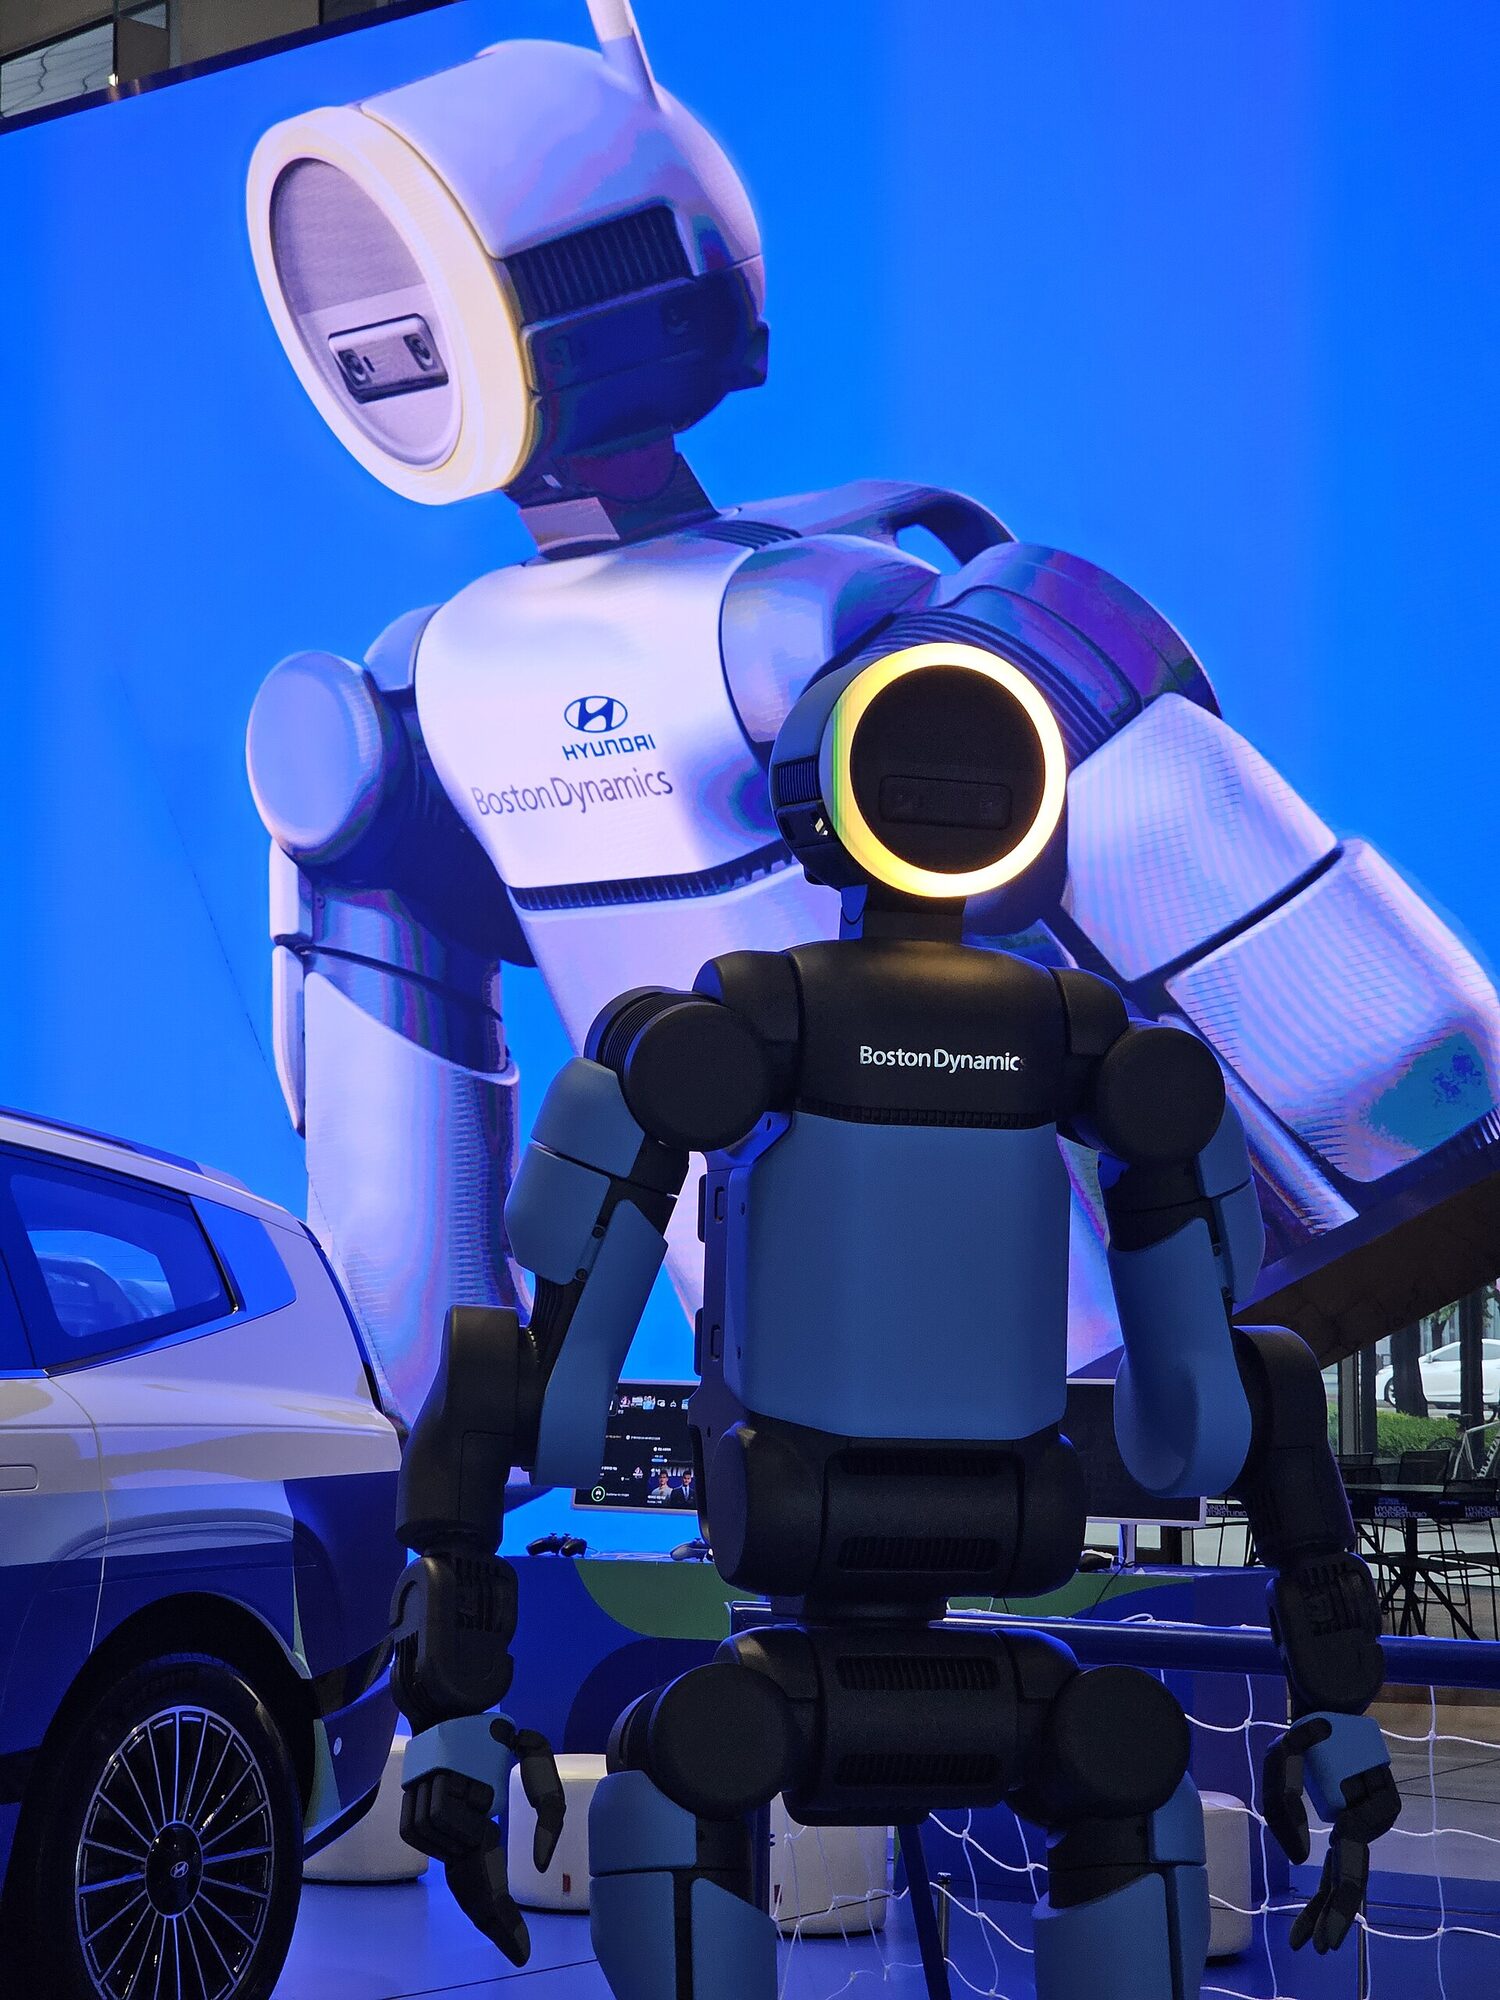
The electric Atlas on display at Hyundai Motorstudio Goyang in July 2026. ZEST trains motion-imitation policies on motion capture, video and animation and deploys them on this robot zero-shot. Photo: Damian B Oh / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Humanoid Whole-Body Control
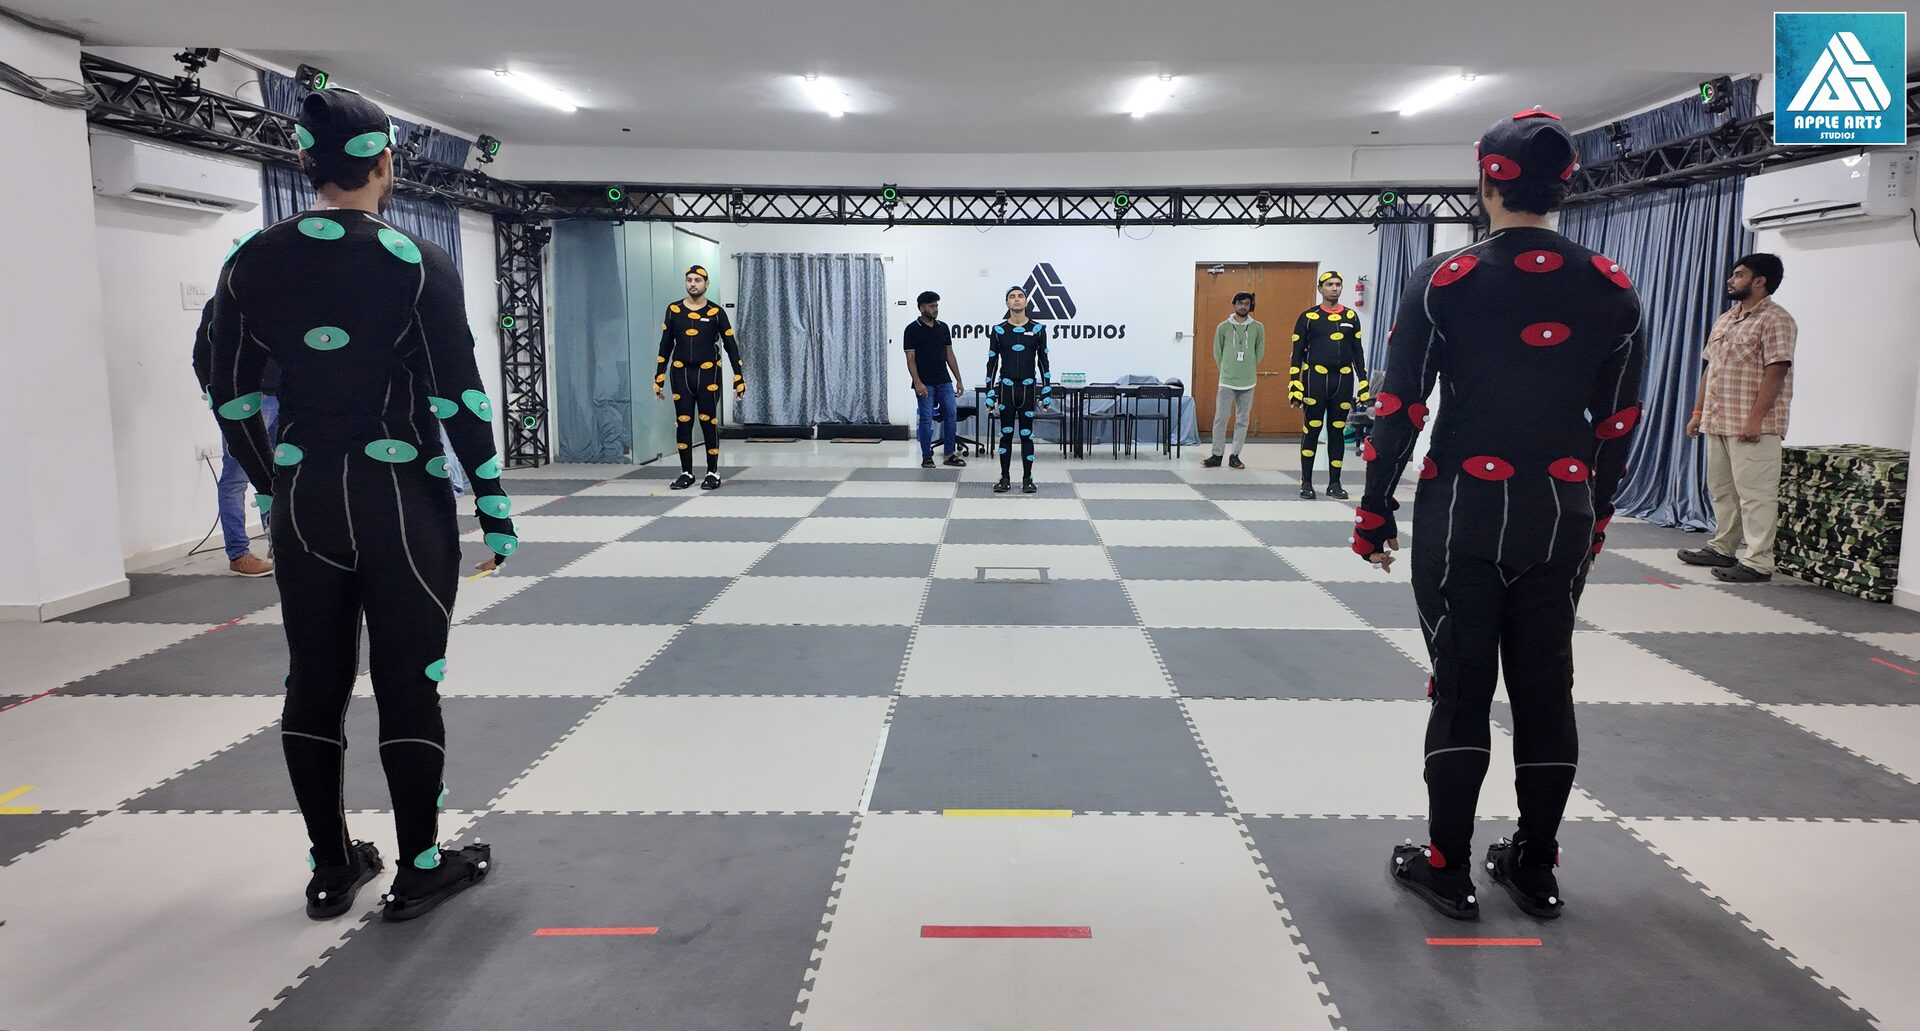
Optical motion capture records body movement from reflective suit markers seen by a ring of cameras. AMASS pooled 15 such datasets, over 40 hours and 11,000 motions, into one body model that humanoid tracking policies learn to imitate. Photo: Applearts123 / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Humanoid Whole-Body Control
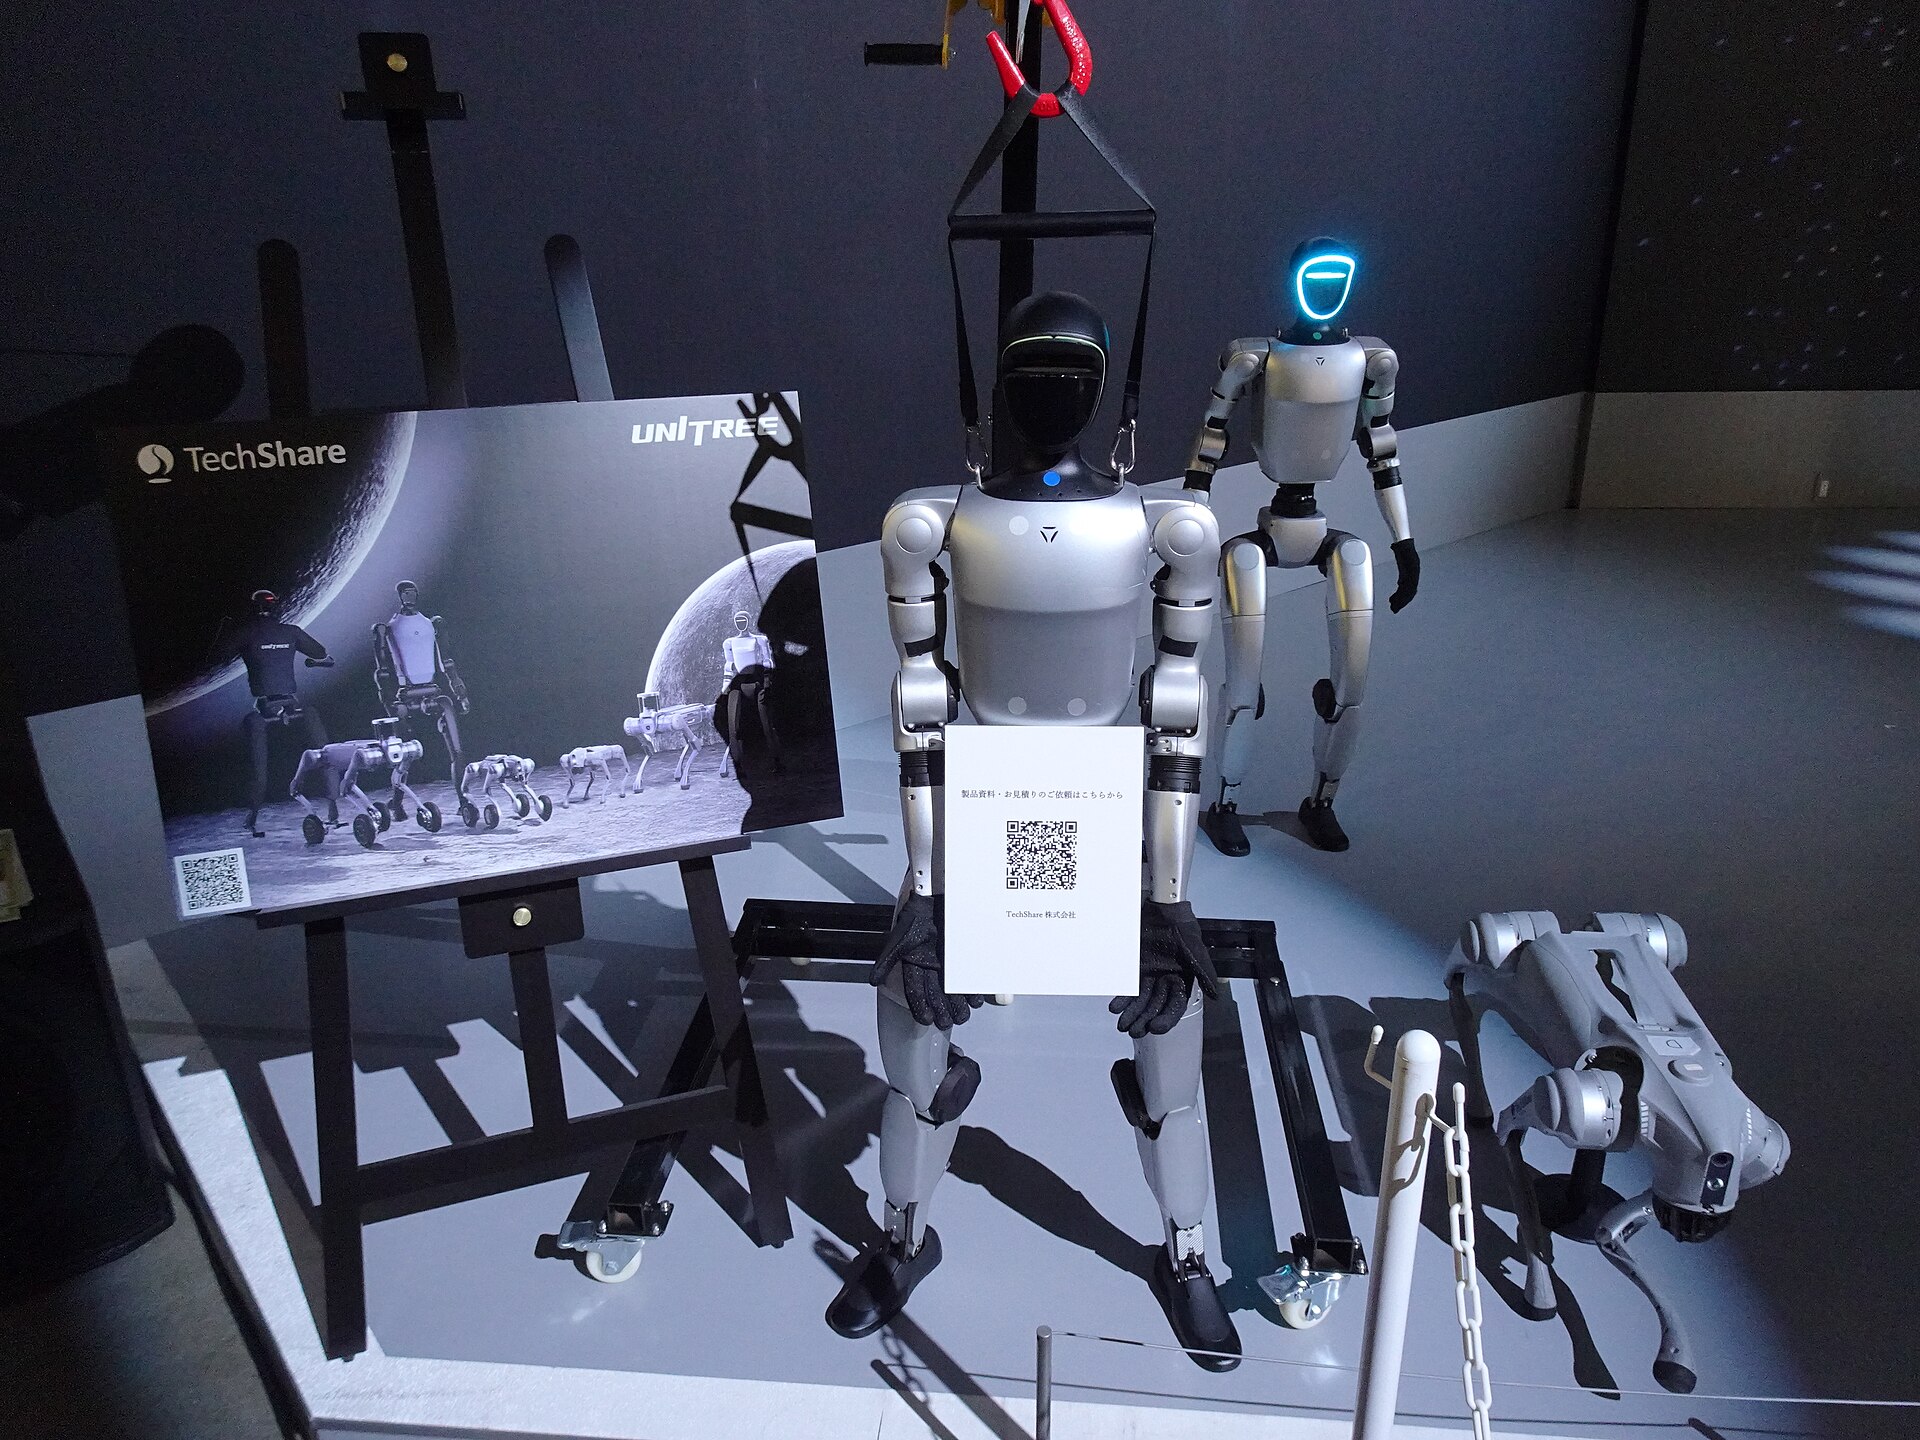
Unitree robots at Japan Mobility Show 2025, with a G1 behind the hoisted humanoid. GR00T N1.7 drives the G1 through GEAR-SONIC, which decodes its latent action tokens into leg, arm and hand commands at 50 Hz. Photo: RuinDig/Yuki Uchida / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Humanoid Whole-Body Control
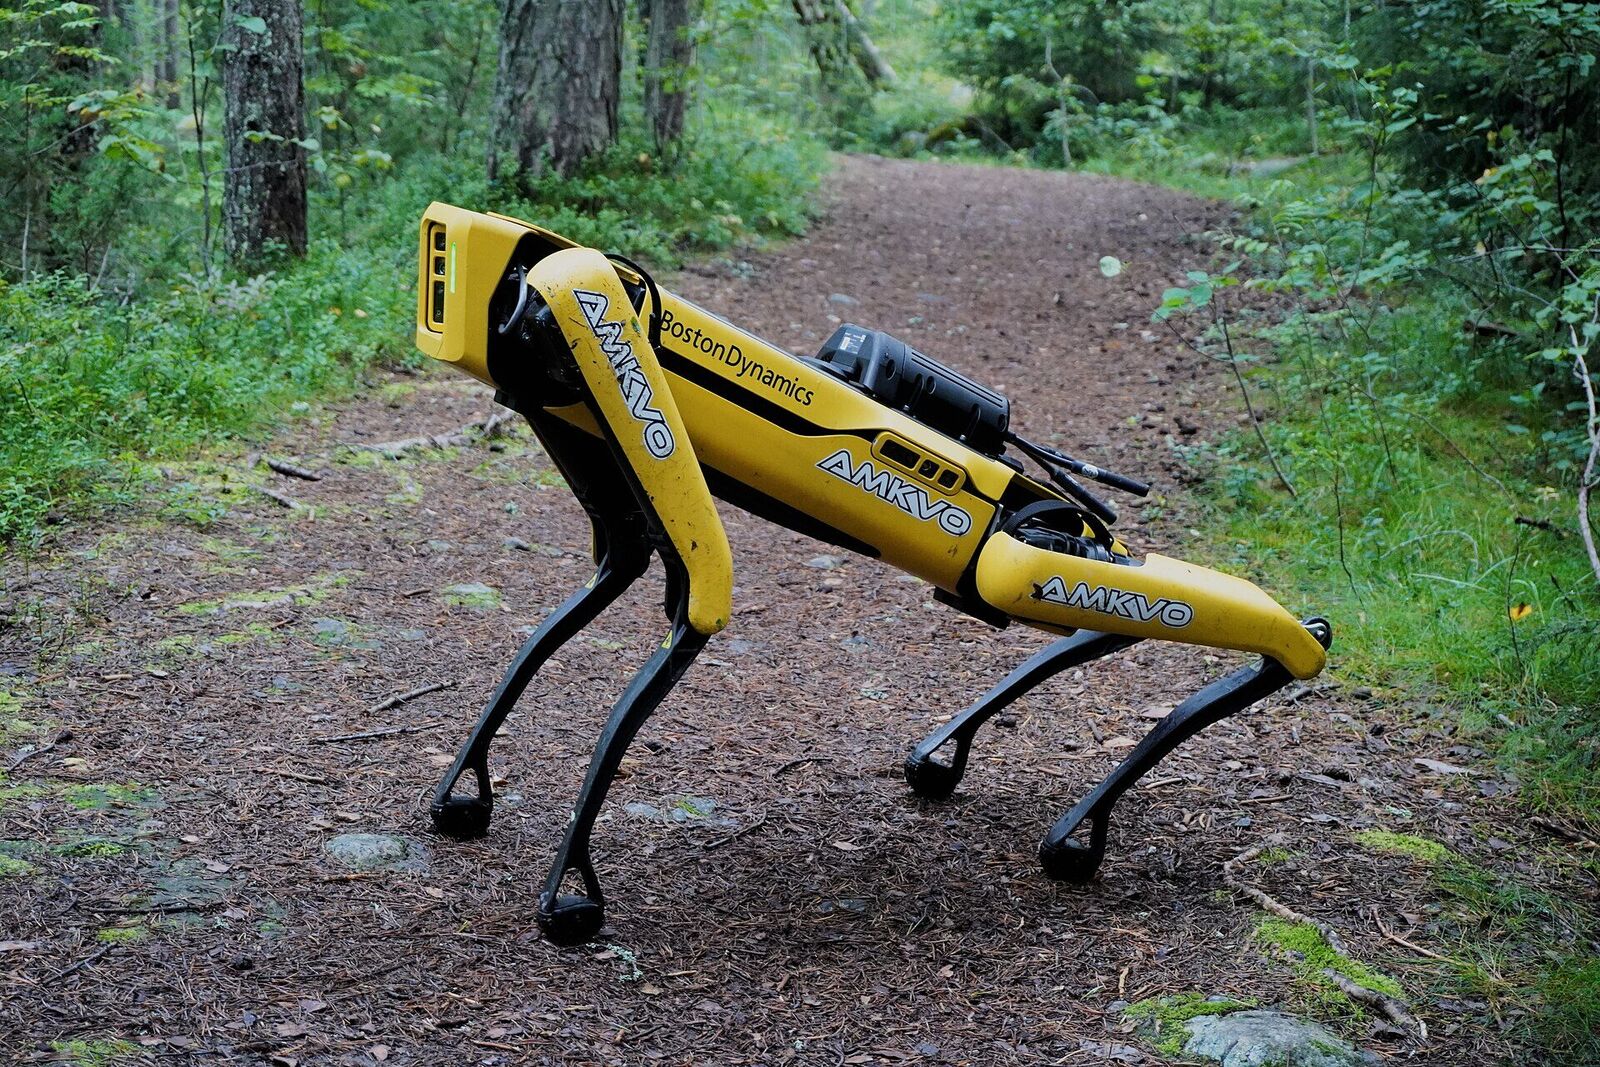
Spot, the Boston Dynamics quadruped, outdoors in 2023. Boston Dynamics ships its learned locomotion policy to Spot by software update and reports fewer falls on slick and irregular ground. Photo: Jonte / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Legged Locomotion Lineage
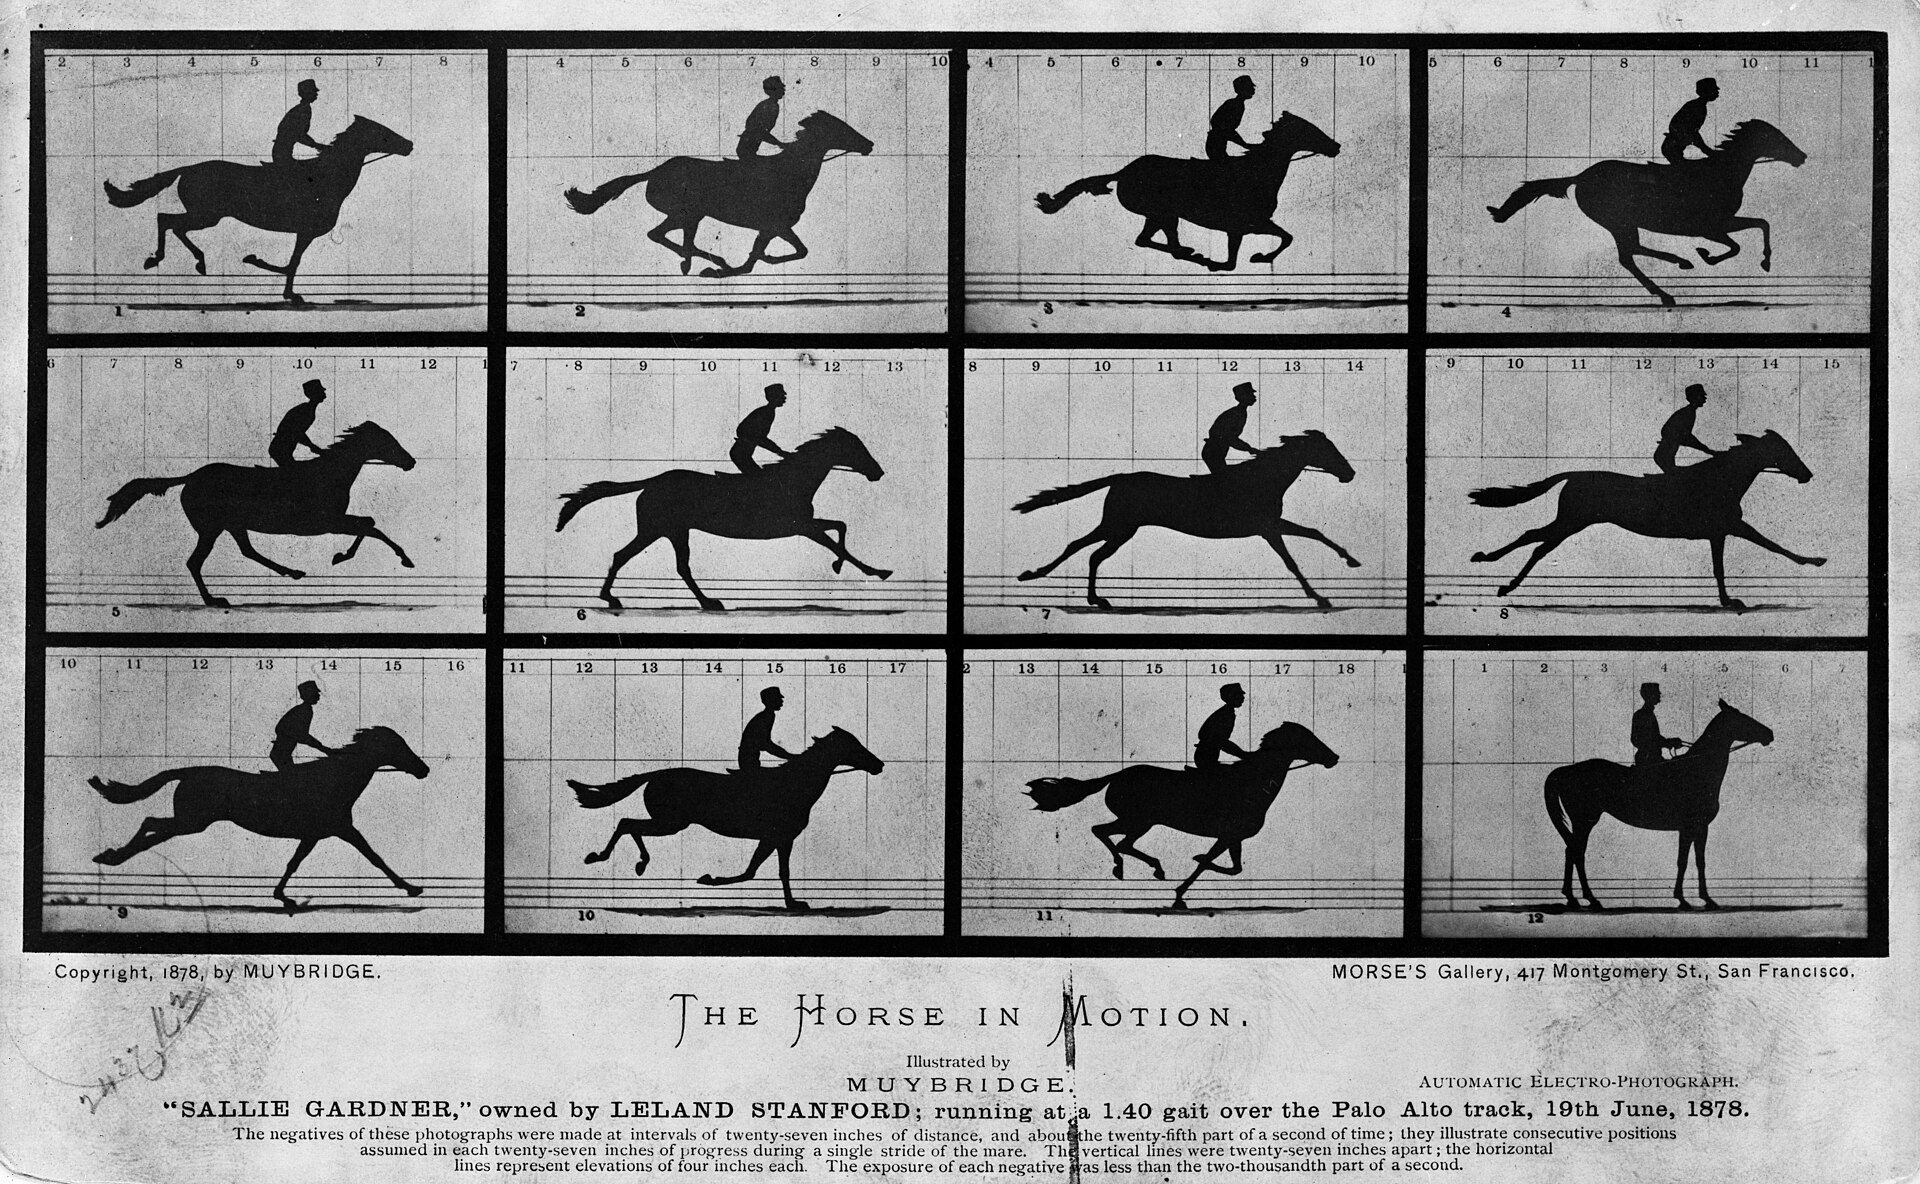
Eadweard Muybridge's 1878 sequence of a galloping horse caught all four hooves off the ground. A gait is such a footfall timing pattern; Walk These Ways commands it to a robot as phase offsets between foot pairs. Photo: Eadweard Muybridge / Wikimedia Commons. Licence: Public domain.Appears on: Legged Locomotion Lineage
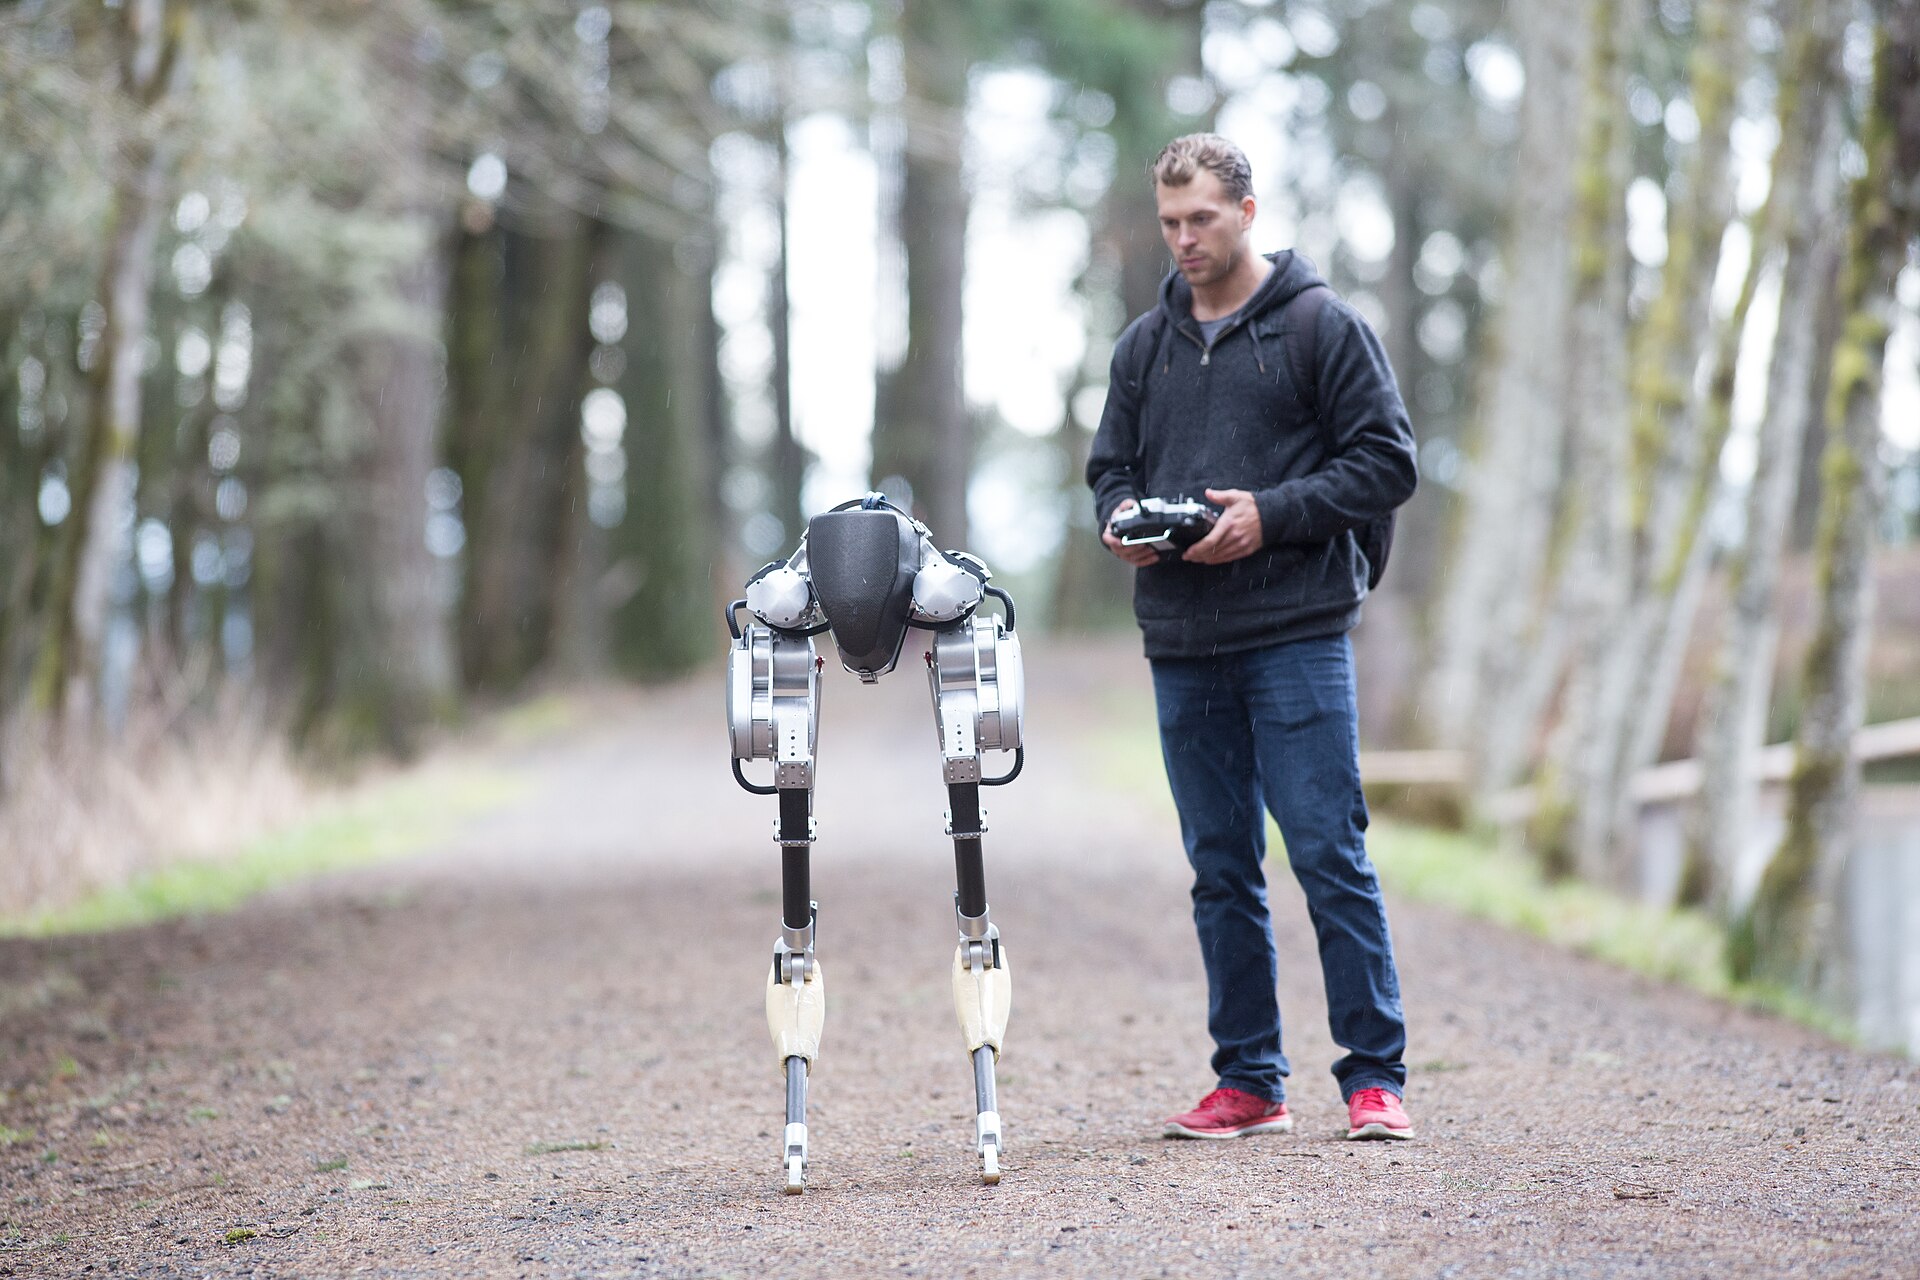
Cassie, the bipedal robot built at Oregon State University, walking in a research forest in 2017. Learned controllers later ran Cassie through a 400-meter dash and composed periodic rewards into standing, walking, hopping, running and skipping. Photo: Oregon State University / Wikimedia Commons. Licence: CC BY-SA 2.0.Appears on: Legged Locomotion Lineage
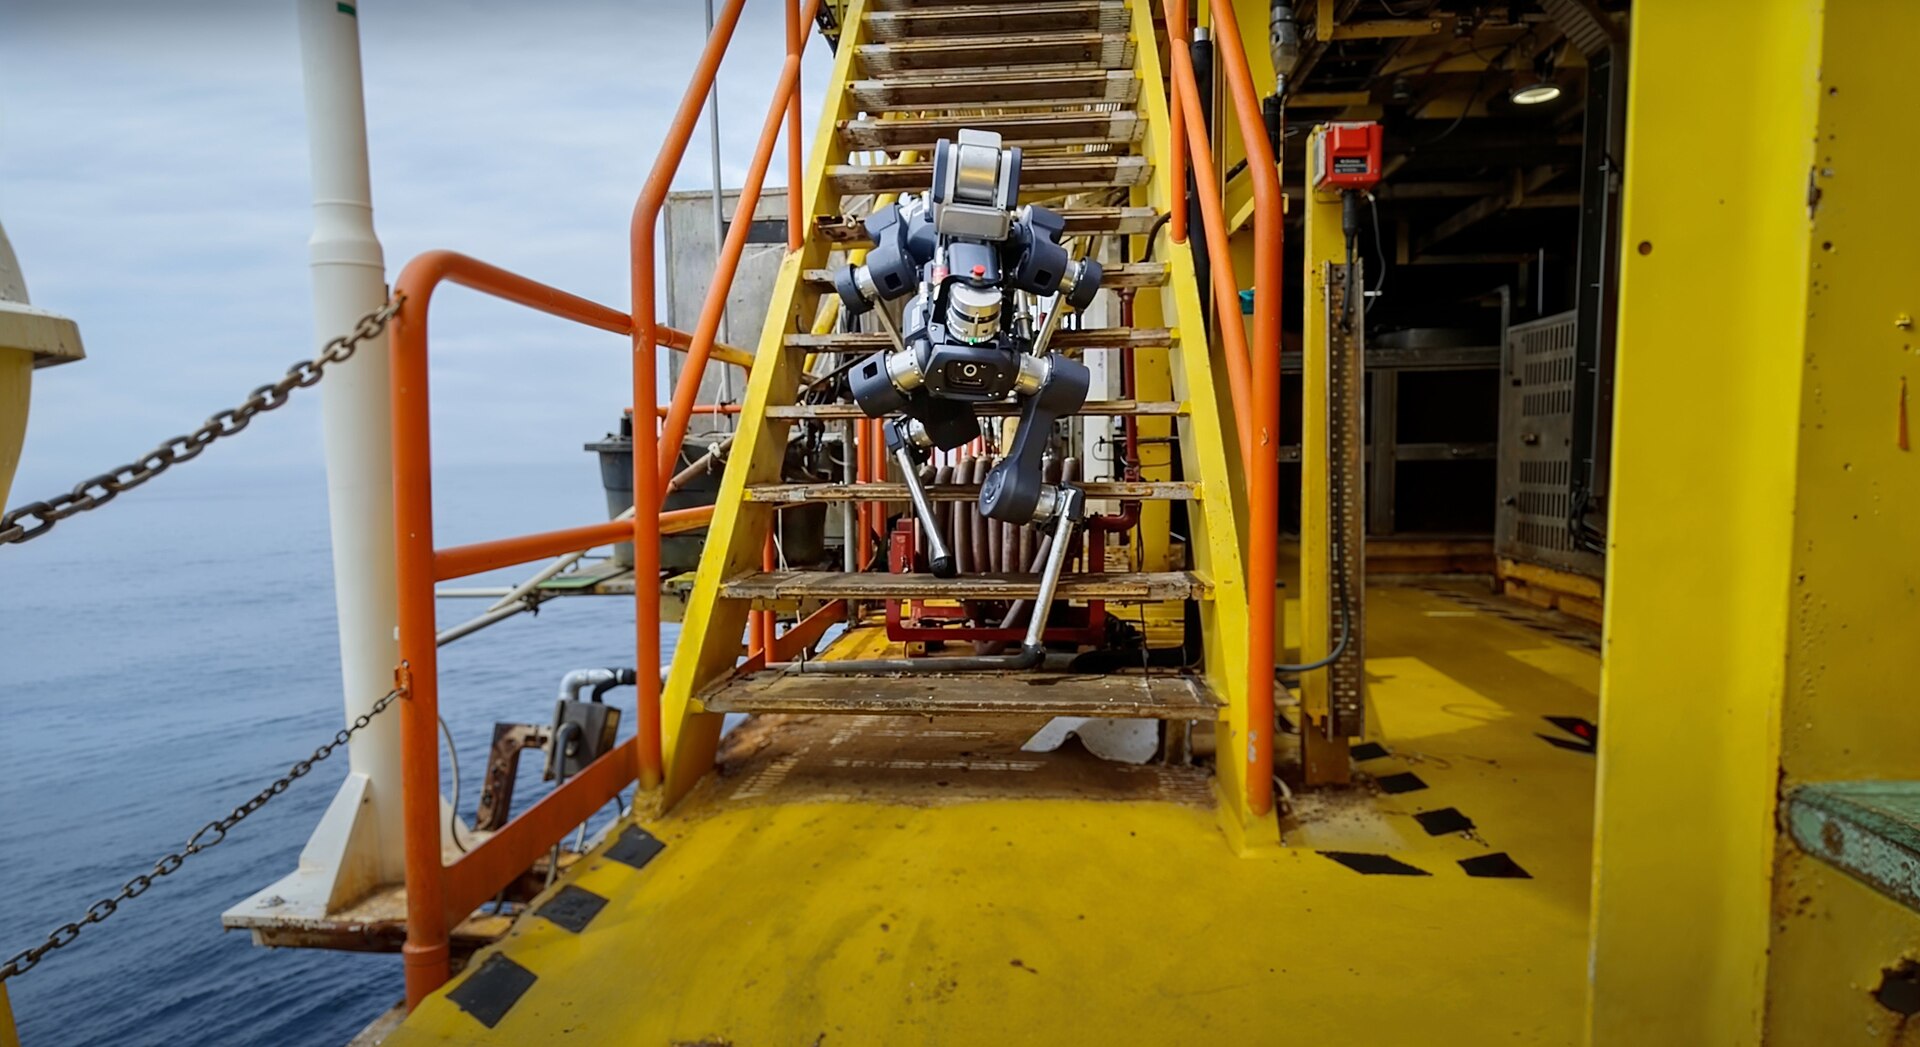
ANYmal X descending stairs on an offshore rig during an inspection round in 2022. The ANYmal line is where simulation-trained locomotion policies first transferred to hardware, in 2019. Photo: Cvoellmy / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Why RL Won Locomotion but Not Manipulation
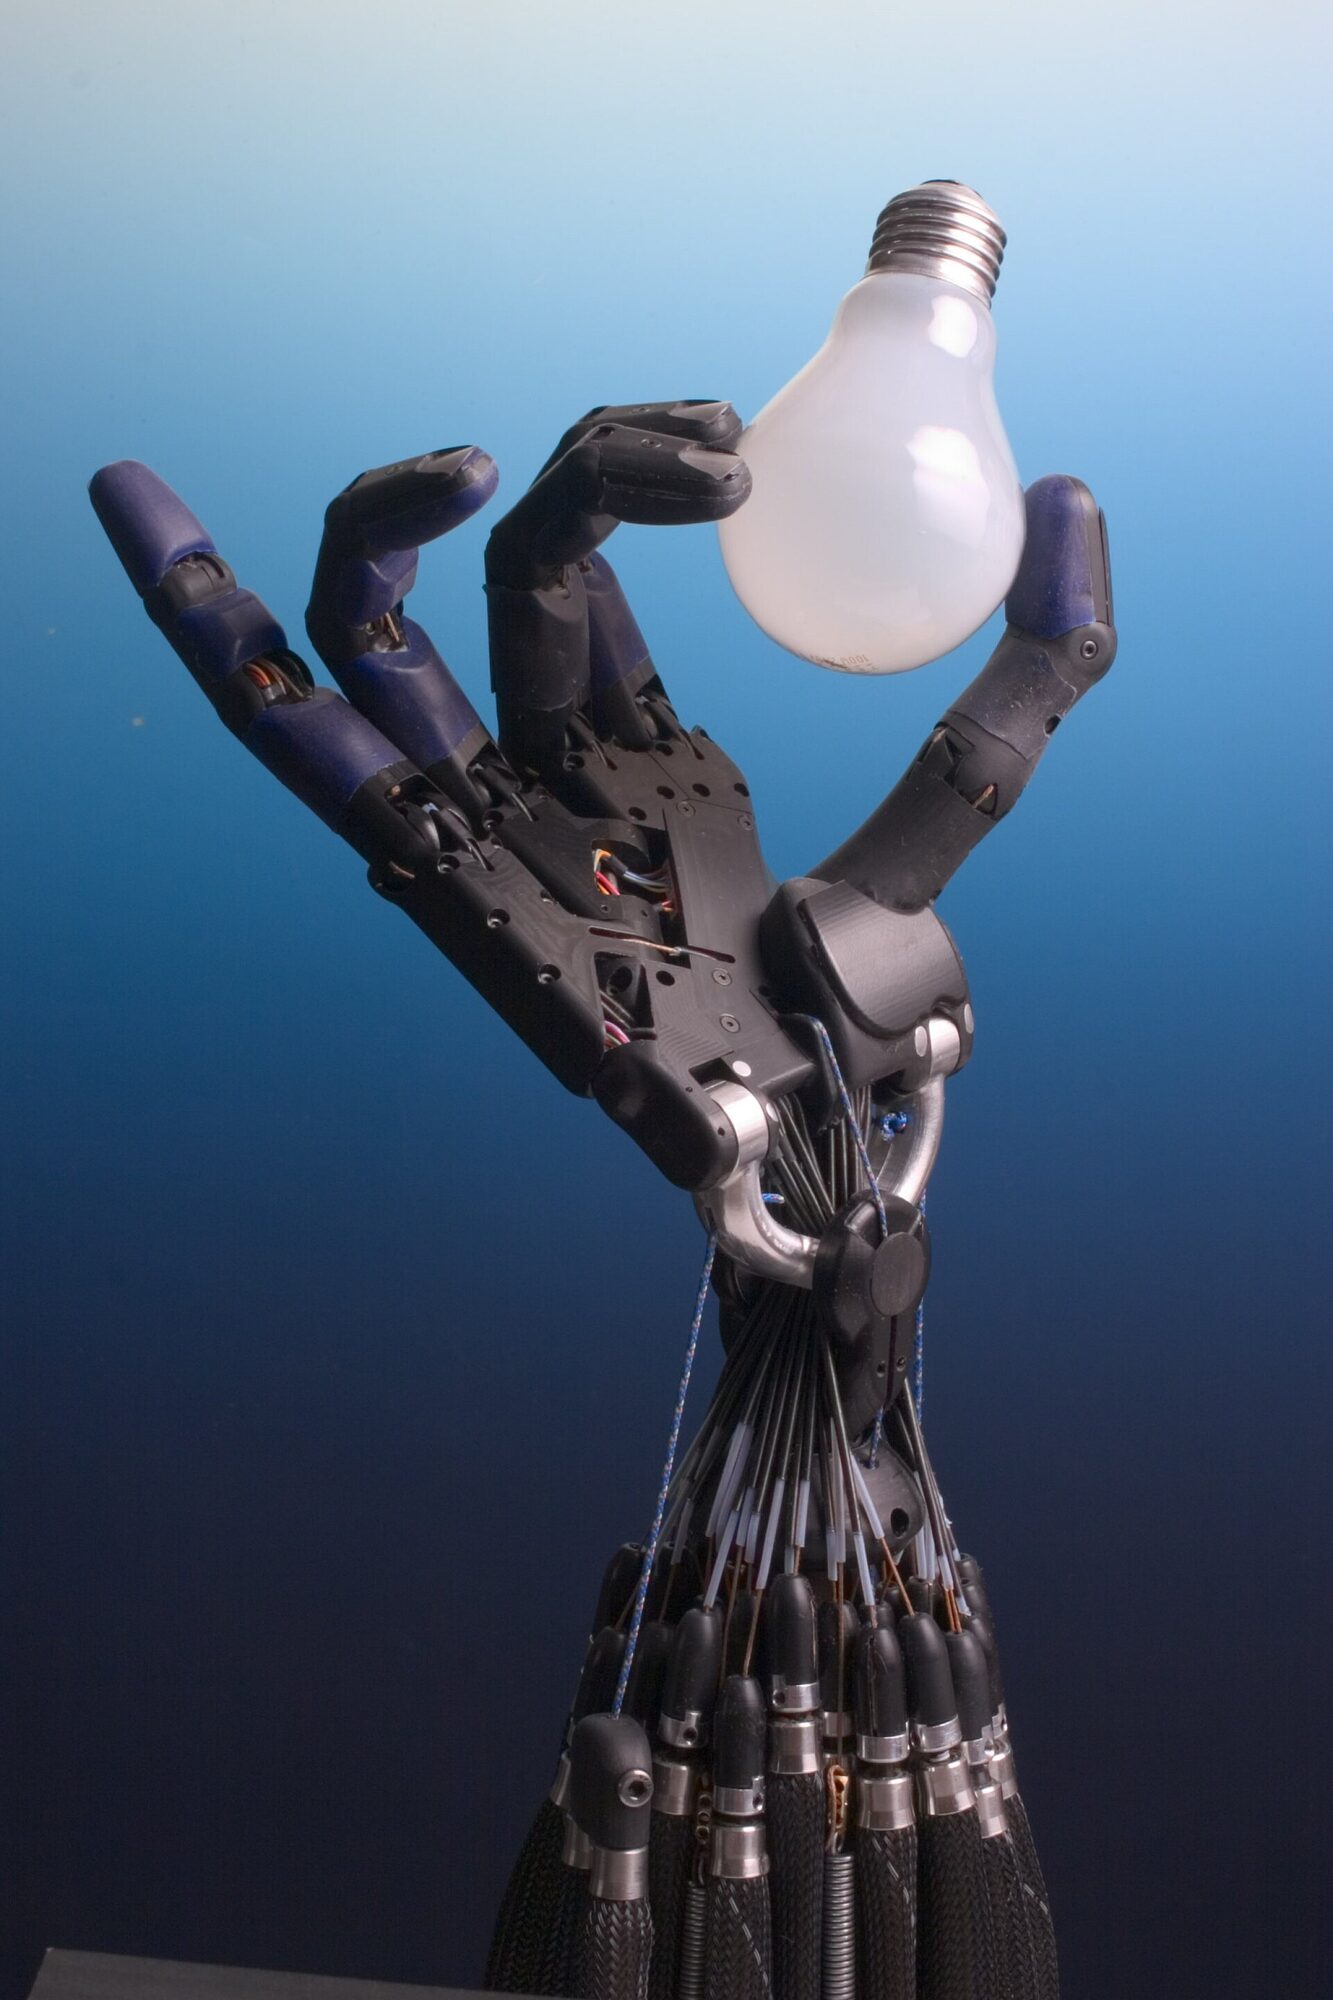
The Shadow Dexterous Hand holding a light bulb in 2007. Each fingertip is a contact whose geometry and friction a simulator must get right; a modified Shadow hand ran the Rubik's cube policy trained with automatic domain randomization. Photo: Richard Greenhill and Hugo Elias, Shadow Robot Company / Wikimedia Commons. Licence: CC BY-SA 3.0.Appears on: Why RL Won Locomotion but Not Manipulation
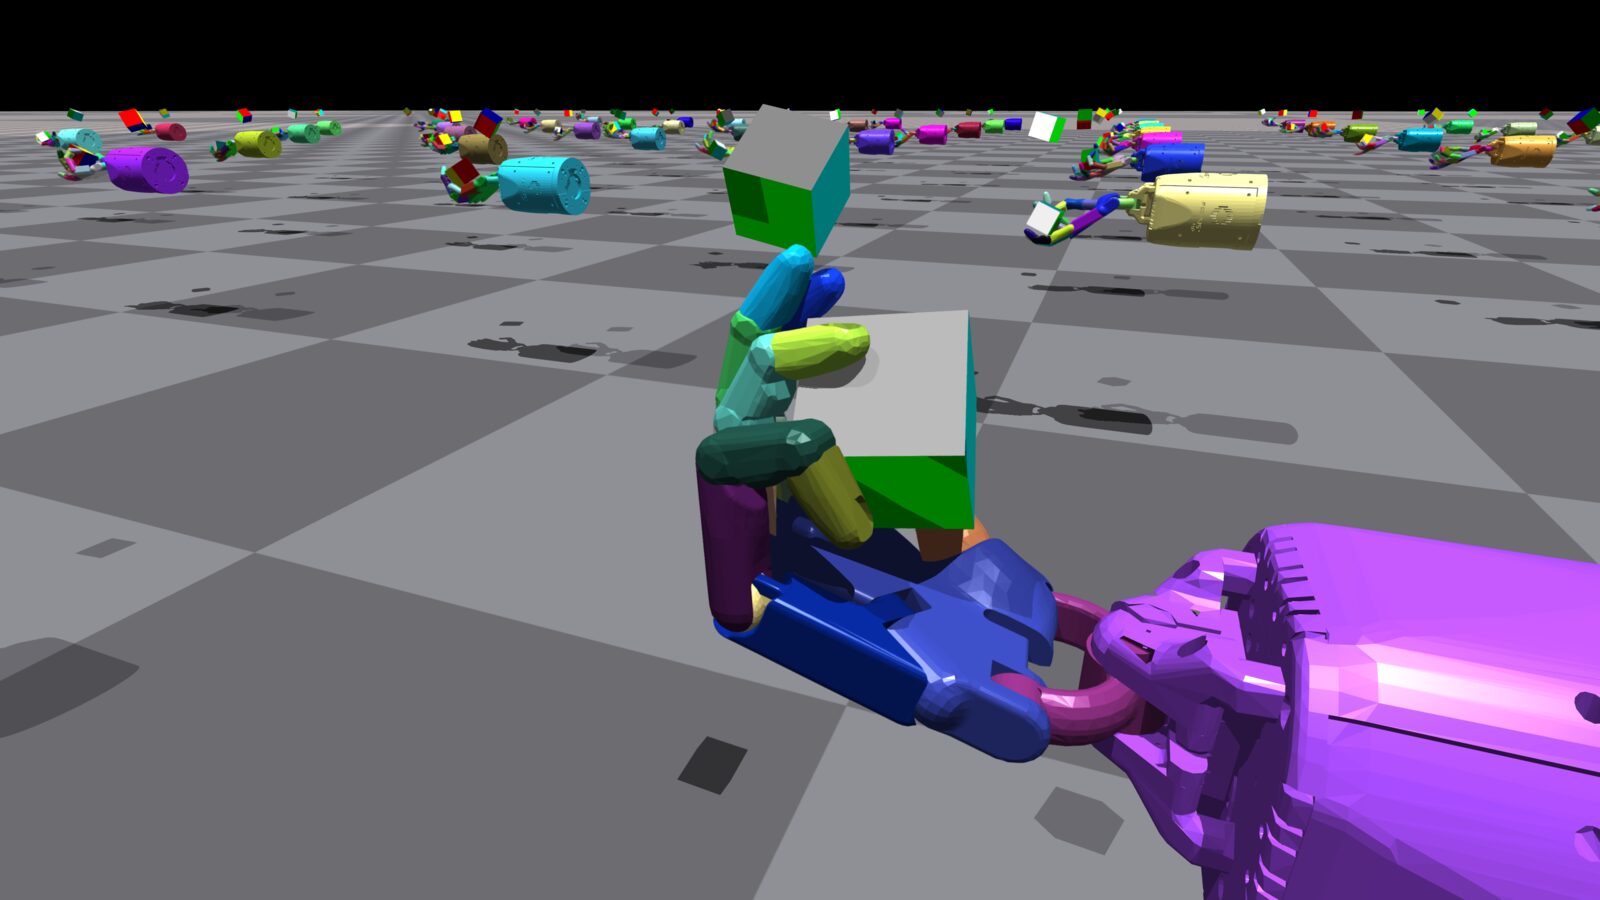
Isaac Gym's Shadow Hand task, rendered with many copies of the same hand and cube stepped together on one GPU. Its authors report 2 to 3 orders of magnitude improvement over a CPU simulator feeding a GPU network. Paper figure: Viktor Makoviychuk et al. / arXiv. Licence: CC BY 4.0.Appears on: Massively Parallel Sim RL
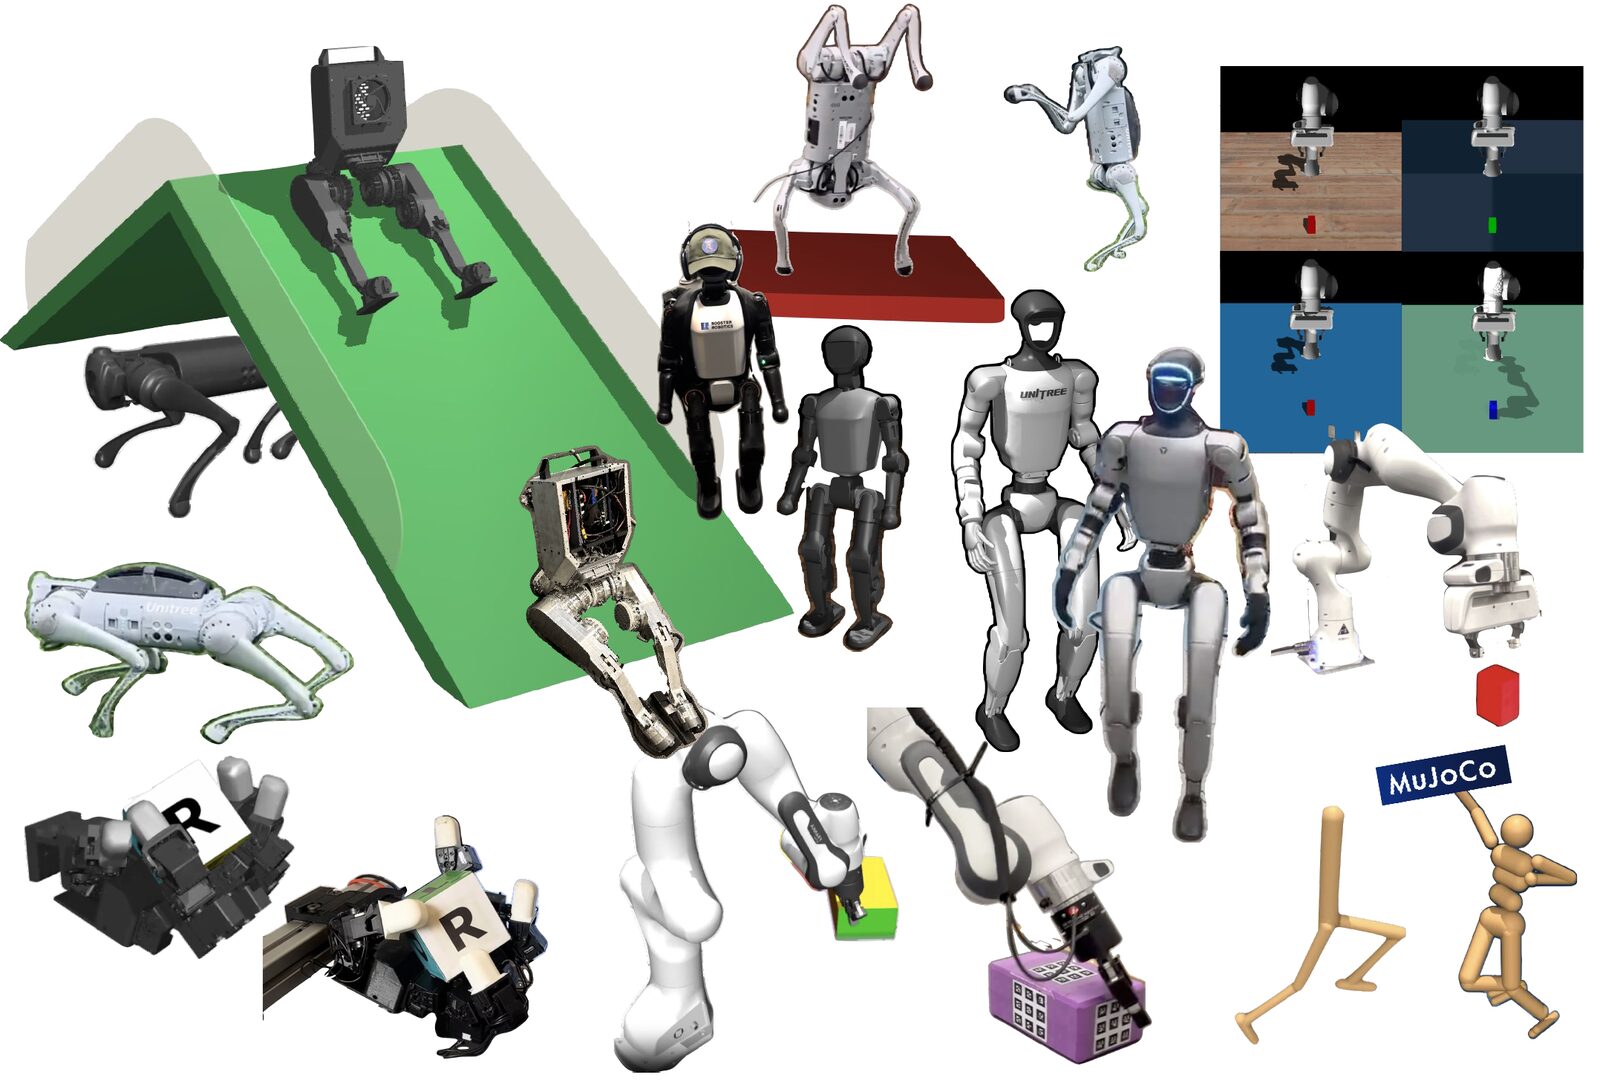
MuJoCo Playground environments that transferred to real hardware: the Berkeley Humanoid, Unitree Go1 and G1, the LEAP hand and a Franka arm. The framework runs MuJoCo on the GPU through MJX, with sim-to-real transfer as an express goal. Paper figure: Kevin Zakka et al. / arXiv. Licence: CC BY 4.0.Appears on: Massively Parallel Sim RL
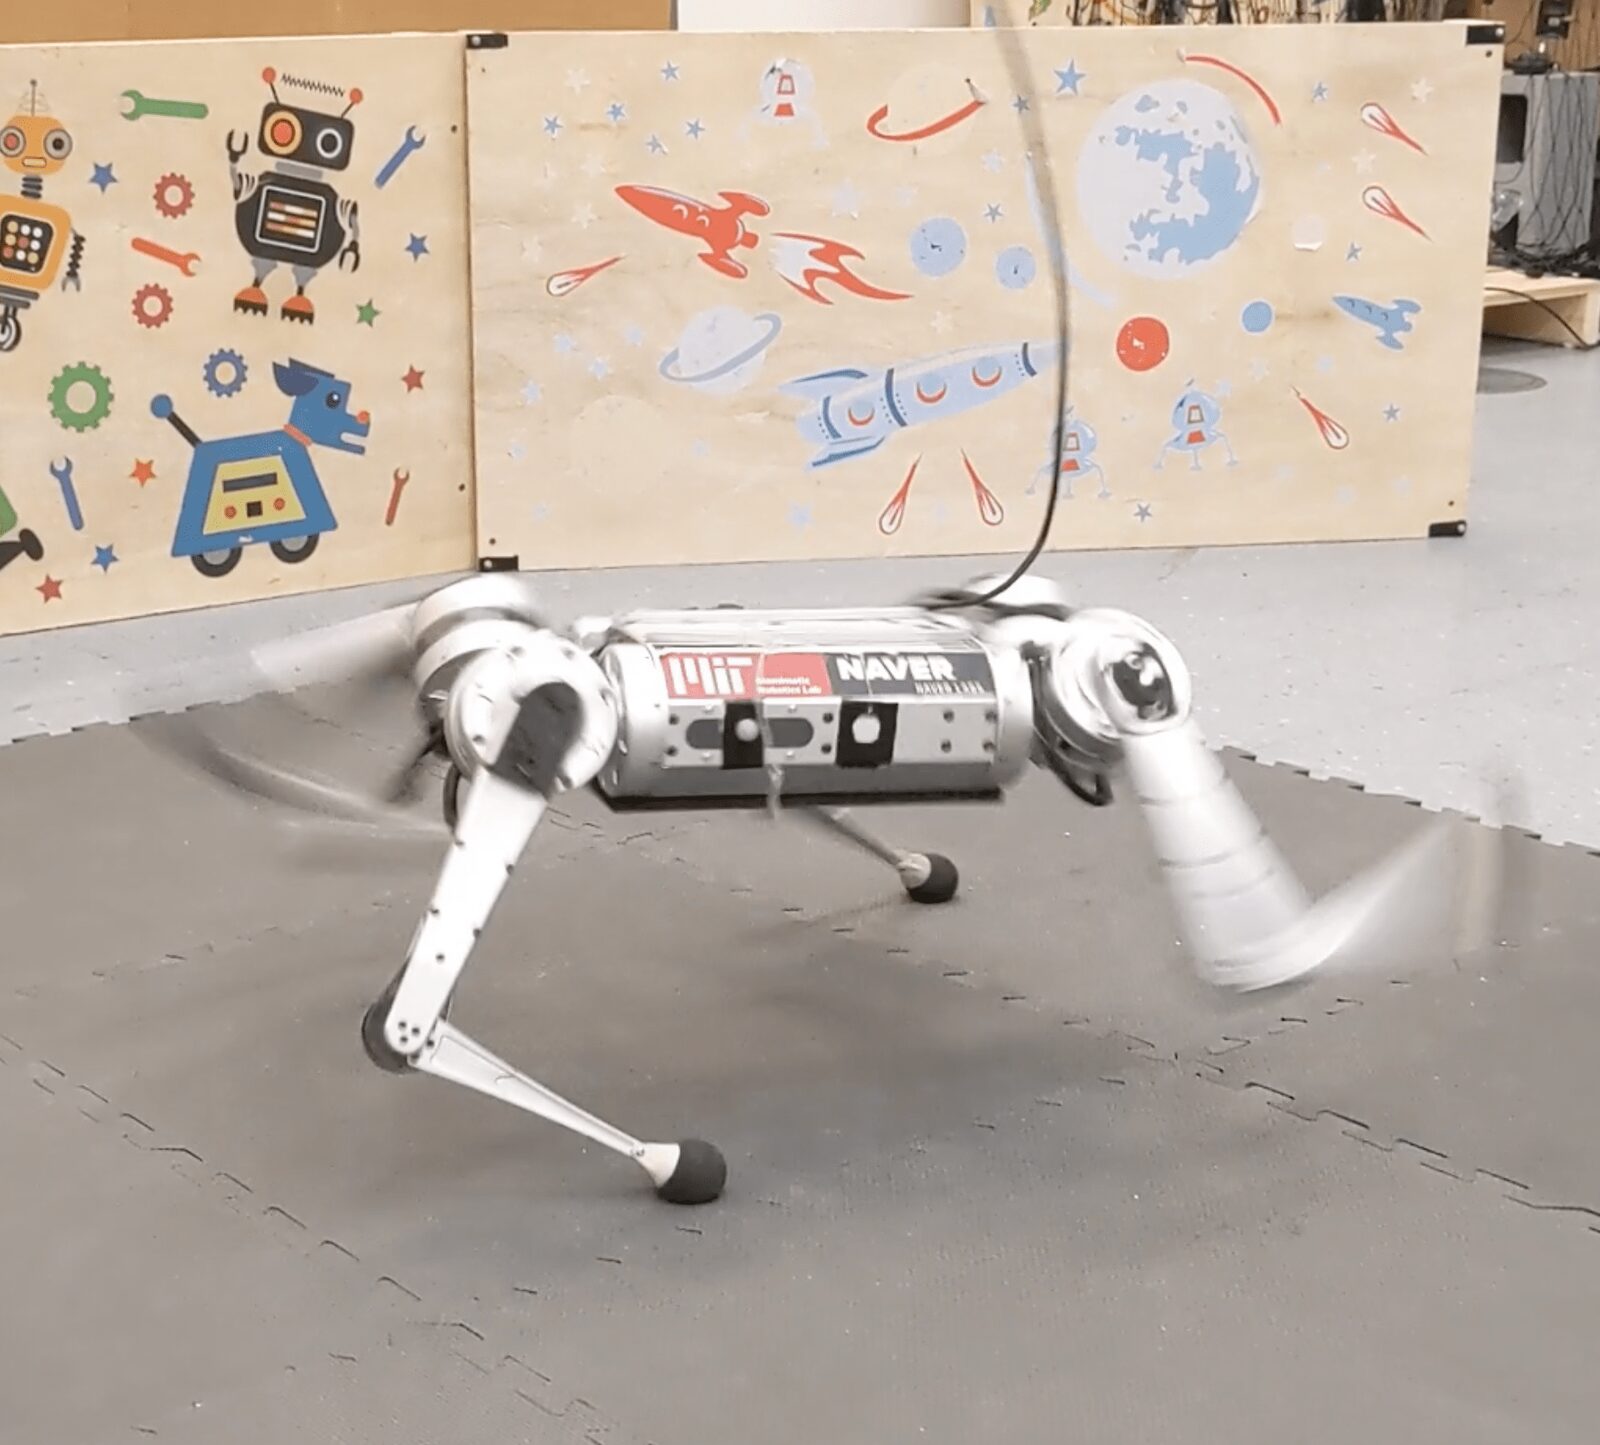
The MIT Mini Cheetah spinning at 5.7 rad/s under a policy trained in simulation, 90% of the 6.28 rad/s yaw rate a model-based controller reached on the robot. The same network sprints at 3.9 m/s. Photo: Gabriel B. Margolis et al. / arXiv. Licence: CC BY 4.0.Appears on: Reward Design and the MPC Debate
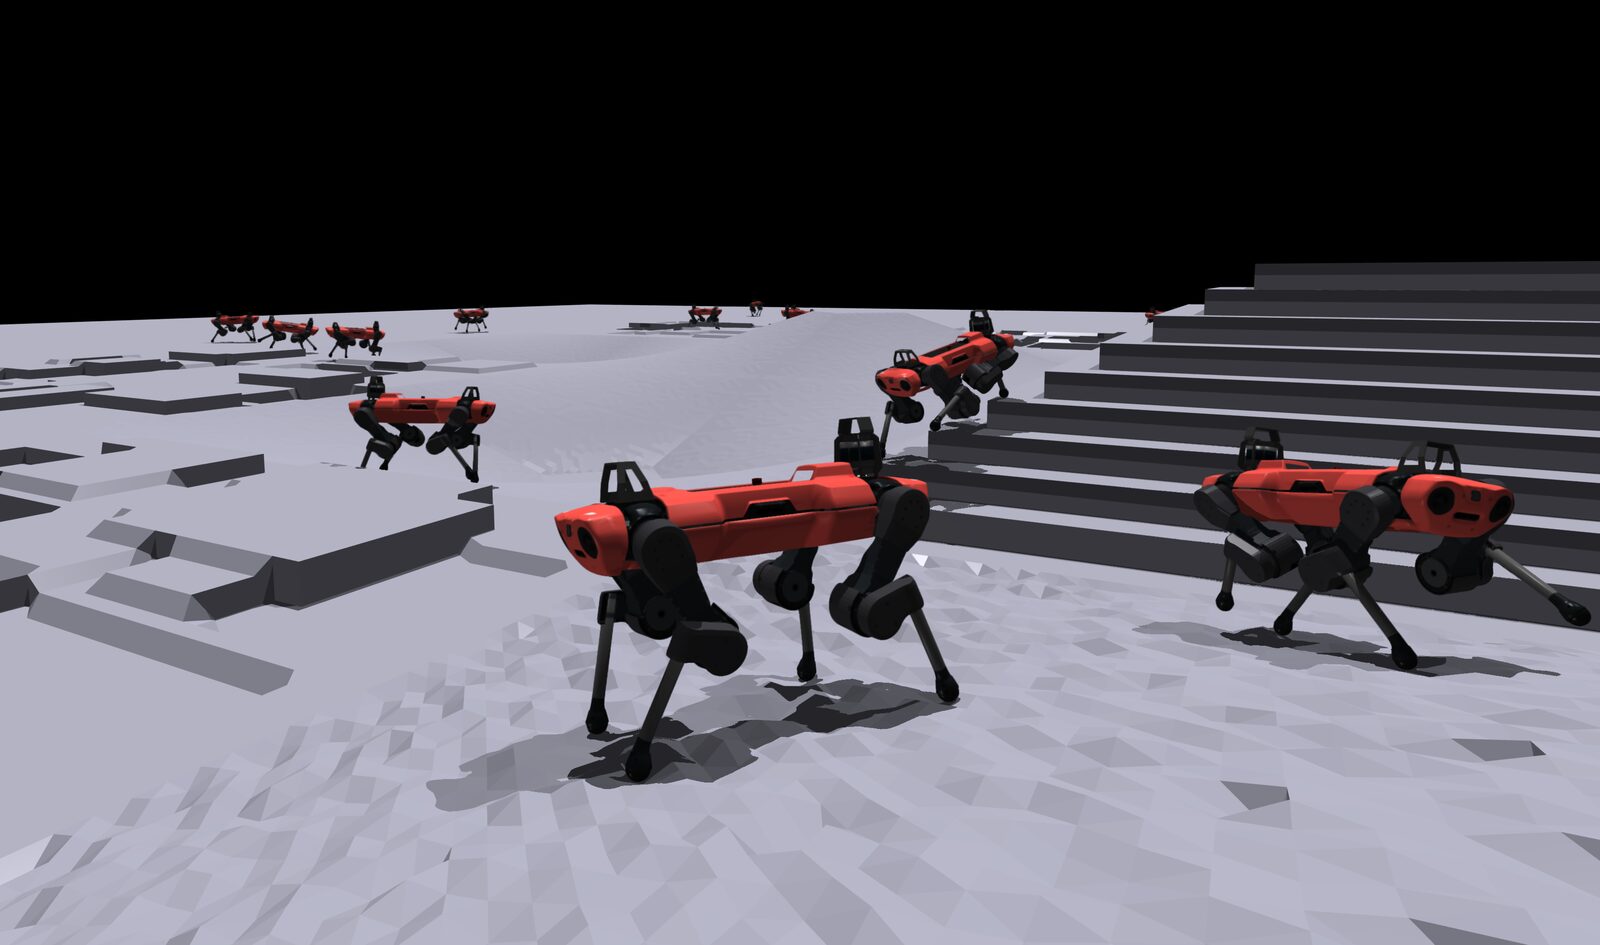
ANYmal robots training in parallel on Isaac Gym stairs and slopes, laid out as tiles of rising difficulty. The curriculum promotes robots that cross a tile and demotes those that cover under half the commanded distance. Paper figure: Viktor Makoviychuk et al. / arXiv. Licence: CC BY 4.0.Appears on: Reward Design and the MPC Debate
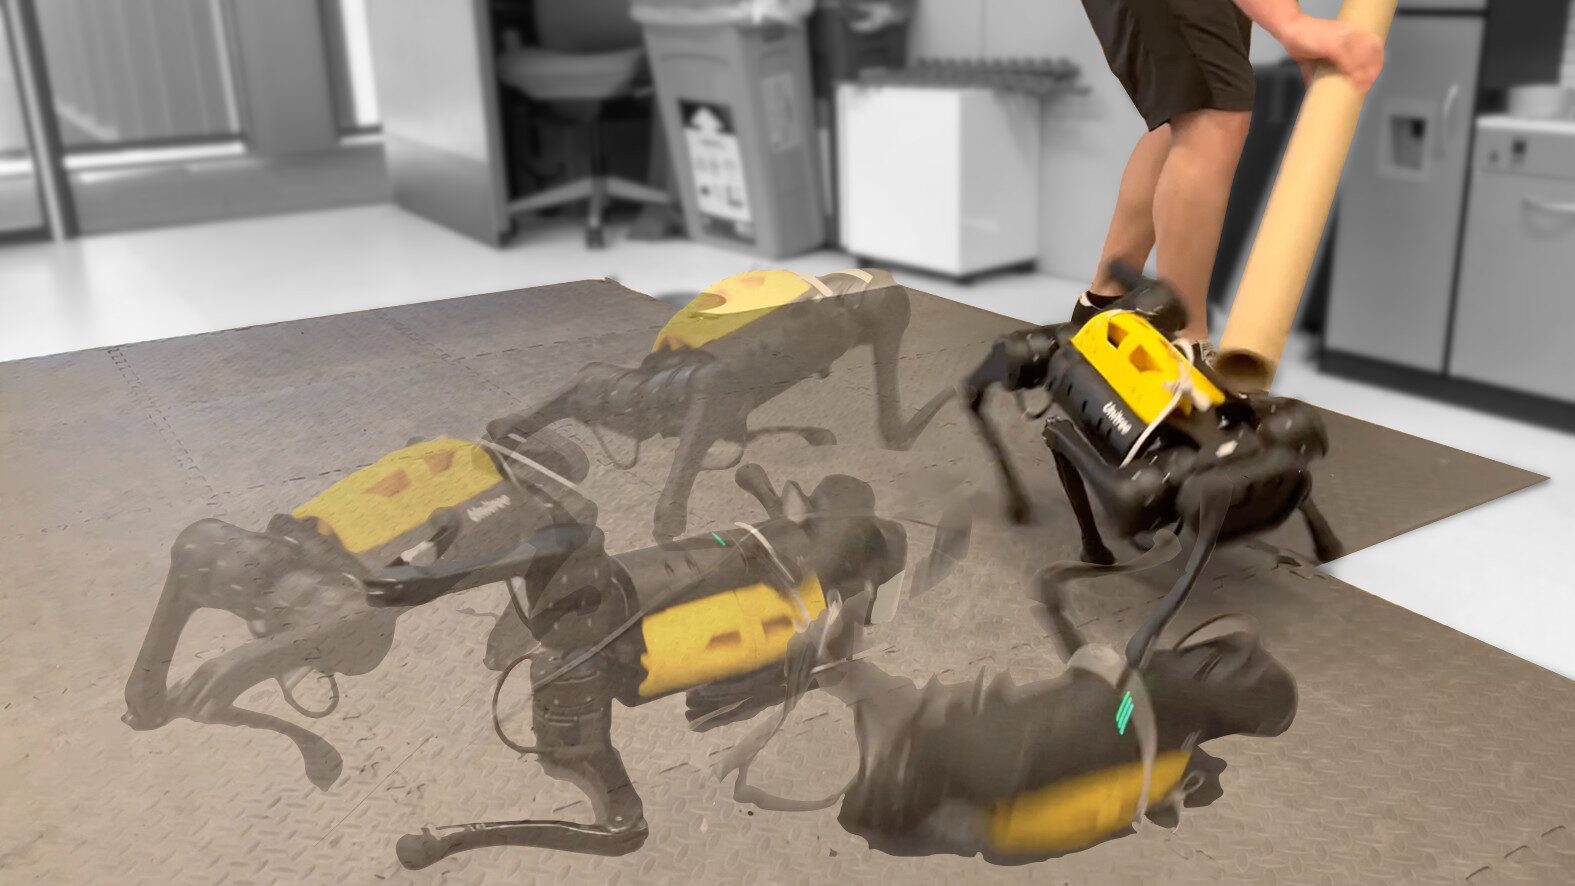
DayDreamer's Unitree A1 learned to roll over, stand and walk in one hour on the real robot with no simulator. Within ten more minutes of pushes it learned to withstand them or roll back onto its feet. Photo: Philipp Wu et al. / arXiv. Licence: CC BY 4.0.Appears on: RL for Robotics
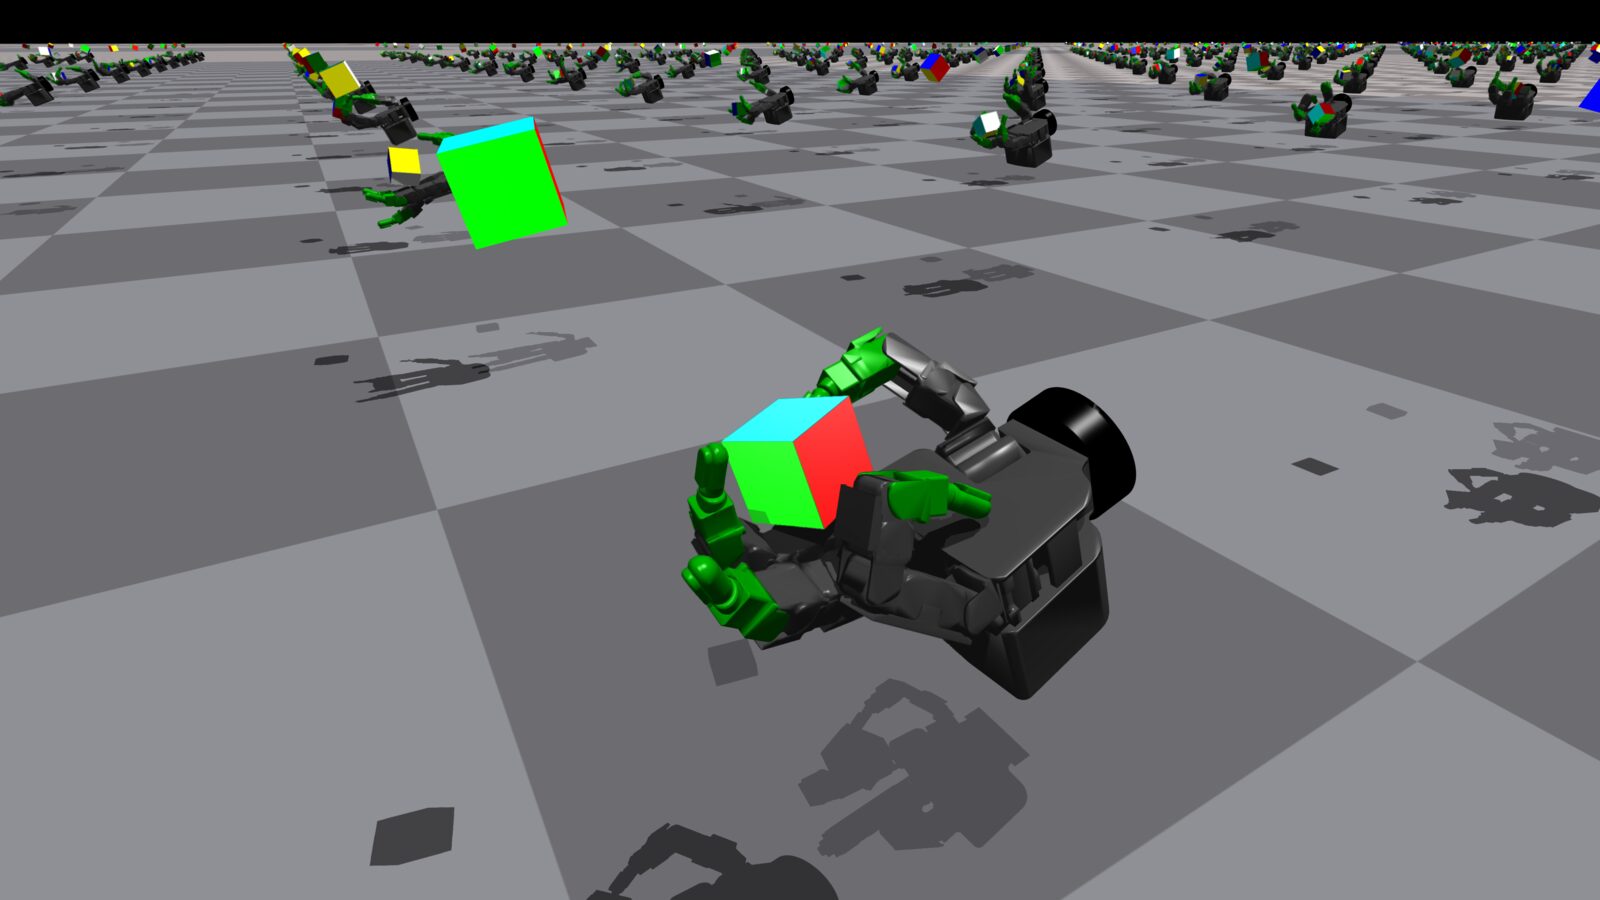
Isaac Gym's Allegro hand task, one hand and cube per environment, all stepped together on a GPU. When steps cost this little, training stability becomes the scarce resource, which is why GPU-simulation work defaulted to PPO. Paper figure: Viktor Makoviychuk et al. / arXiv. Licence: CC BY 4.0.Appears on: RL for Robotics
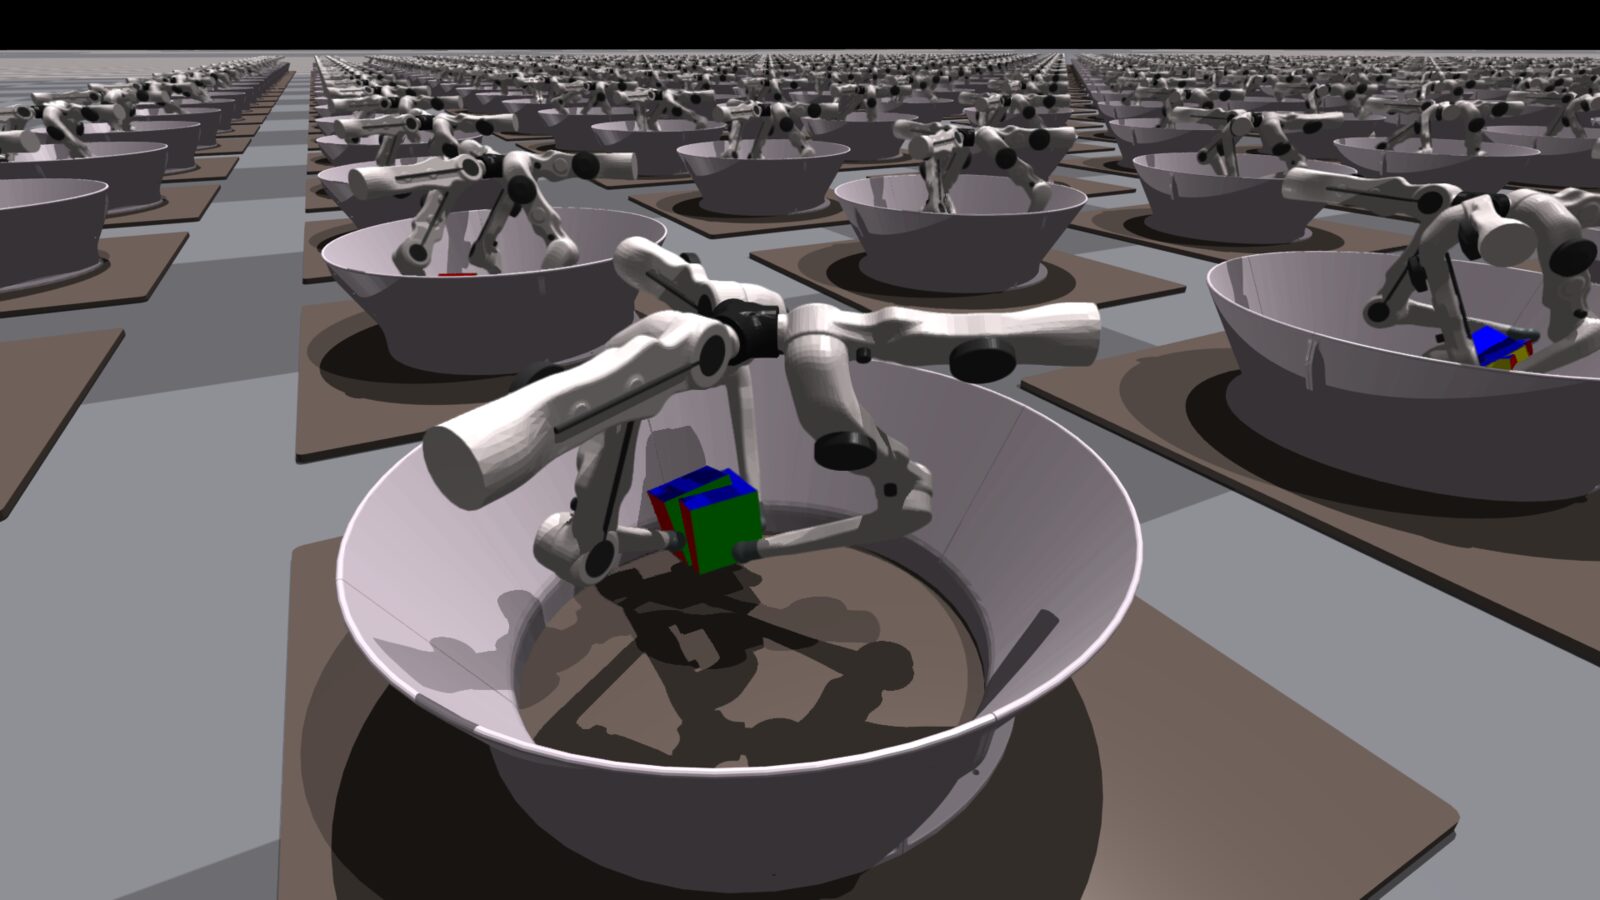
TriFinger, three robot fingers over a round arena, rendered in Isaac Gym. The real benchmark pairs reproducible hardware with simulation for debugging, so offline-RL policies trained on its fixed datasets meet the same robot every time. Paper figure: Viktor Makoviychuk et al. / arXiv. Licence: CC BY 4.0.Appears on: Offline Reinforcement Learning for Robotics
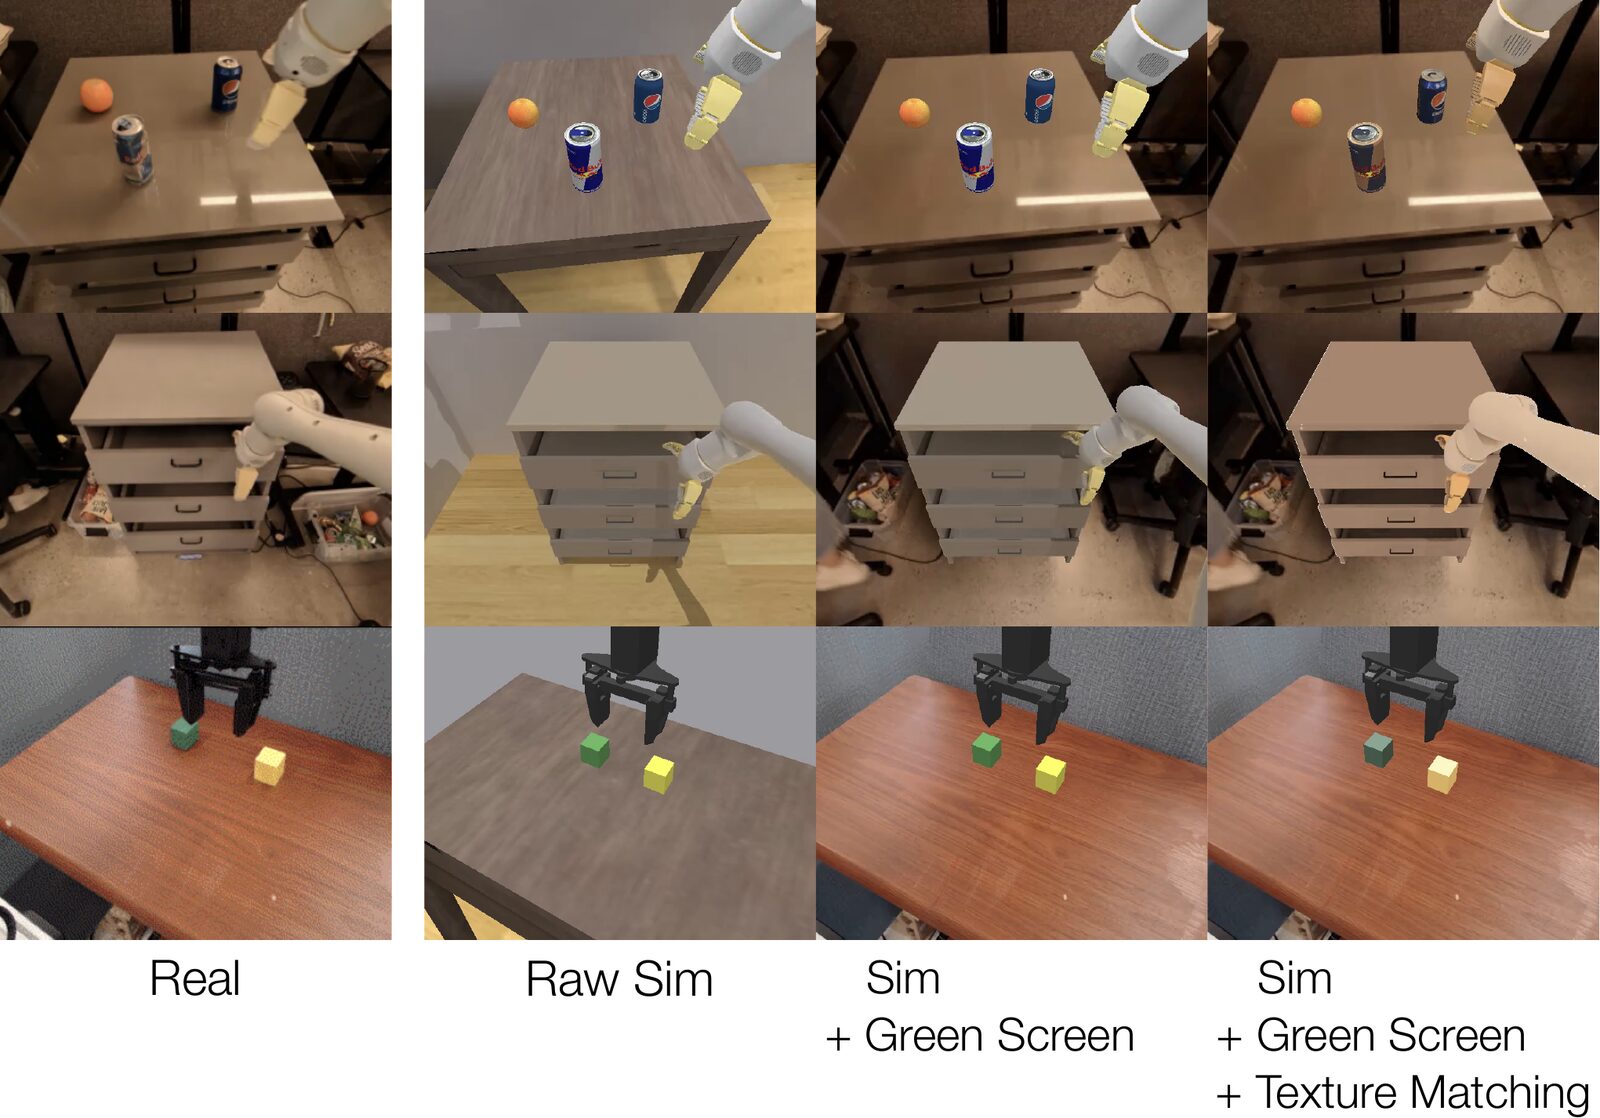
SIMPLER matches its simulated scenes to real camera views, from raw simulation to a green-screened real background with matched textures. The authors checked simulated rankings against paired real evaluations before trusting them. Paper figure: Xuanlin Li et al. / arXiv. Licence: CC BY 4.0.Appears on: Offline Reinforcement Learning for Robotics
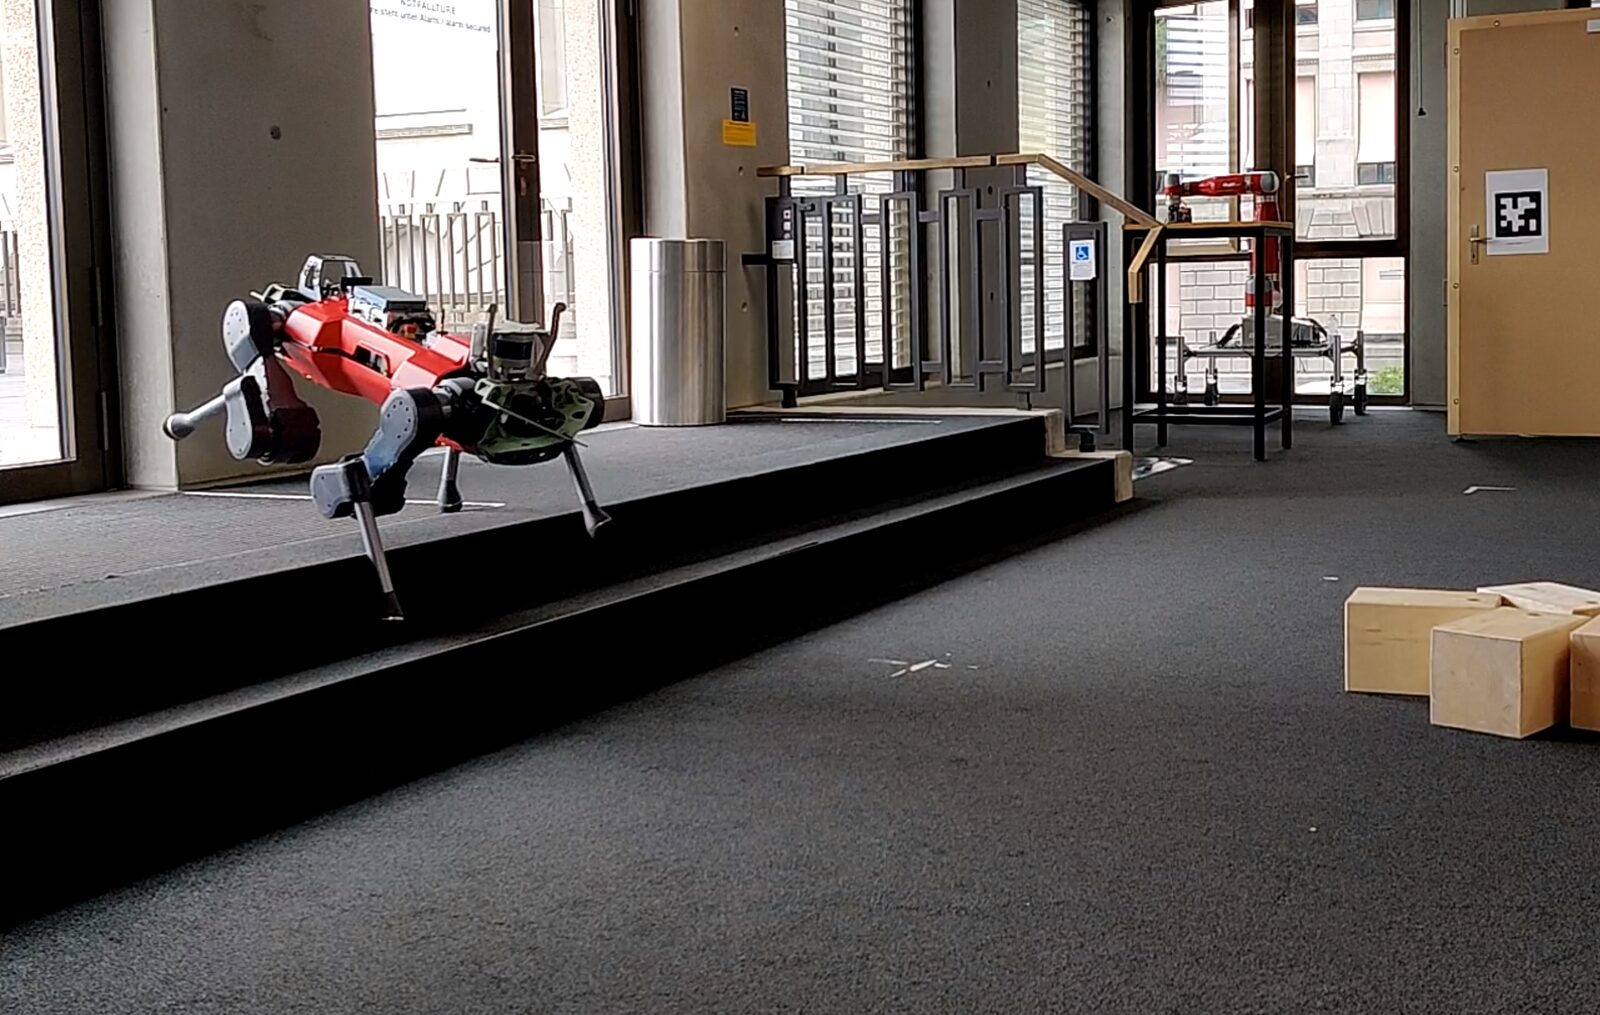
A real ANYmal climbing indoor steps with a rough-terrain policy trained in Isaac Gym. The Isaac Gym paper shows the same policy on simulated terrain beside this hardware test. Photo: Viktor Makoviychuk et al. / arXiv. Licence: CC BY 4.0.Appears on: Sim-to-Real Transfer
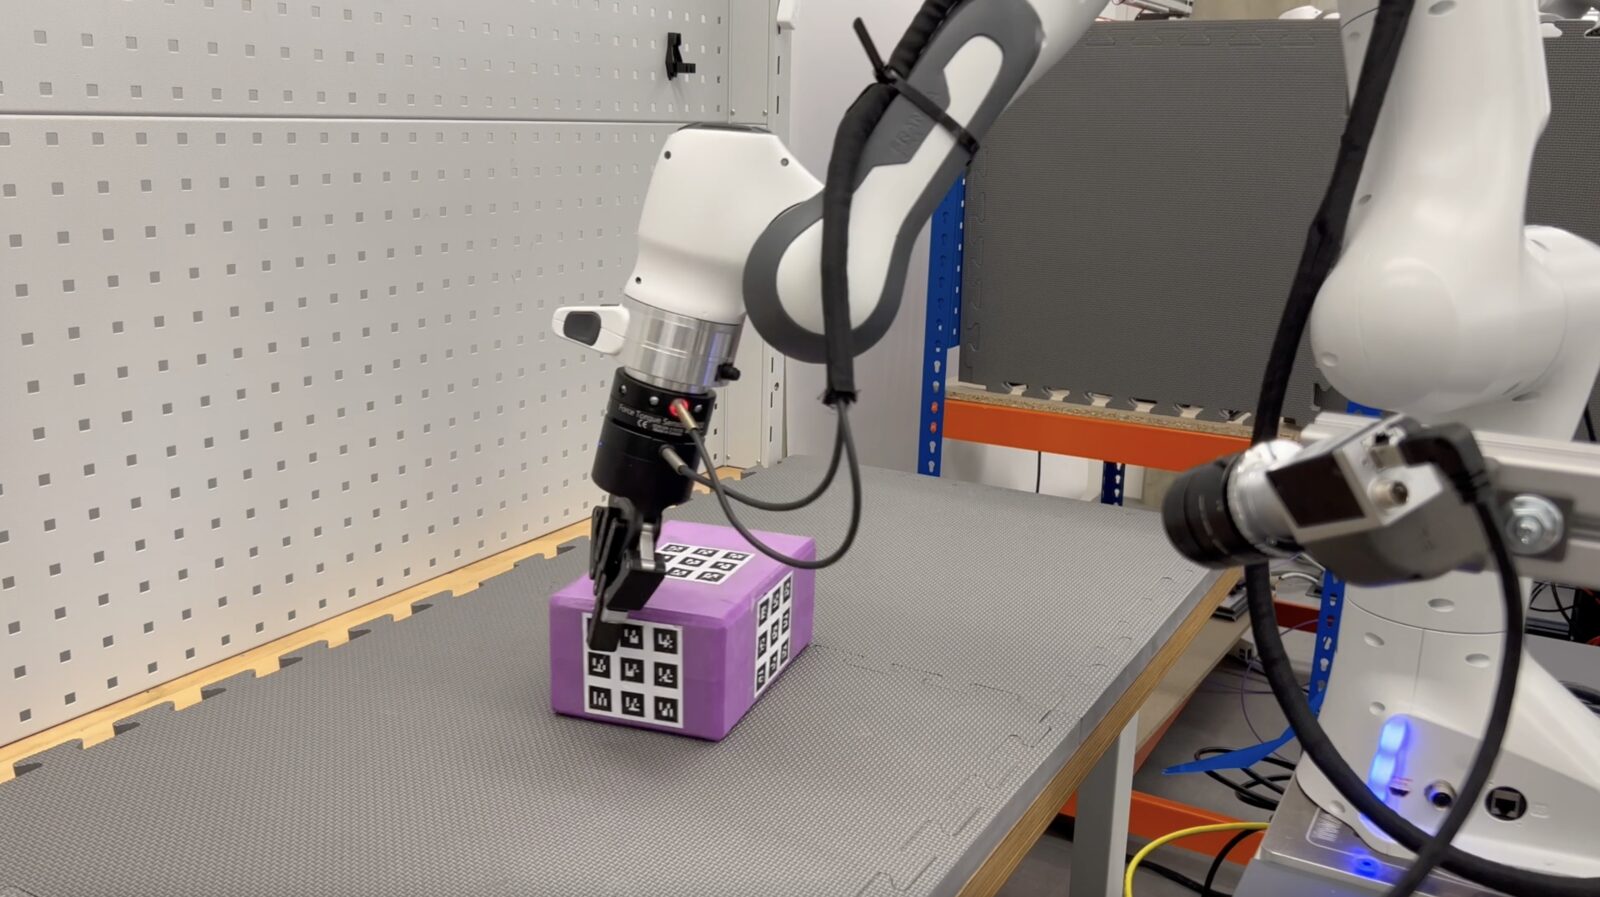
A Franka Panda pushes a yoga block to a goal with a MuJoCo Playground policy trained under domain randomization and transferred zero-shot. Early policies moved fast enough to trip the arm's force limit, so the authors added torque penalties. Photo: Kevin Zakka et al. / arXiv. Licence: CC BY 4.0.Appears on: Sim-to-Real Transfer
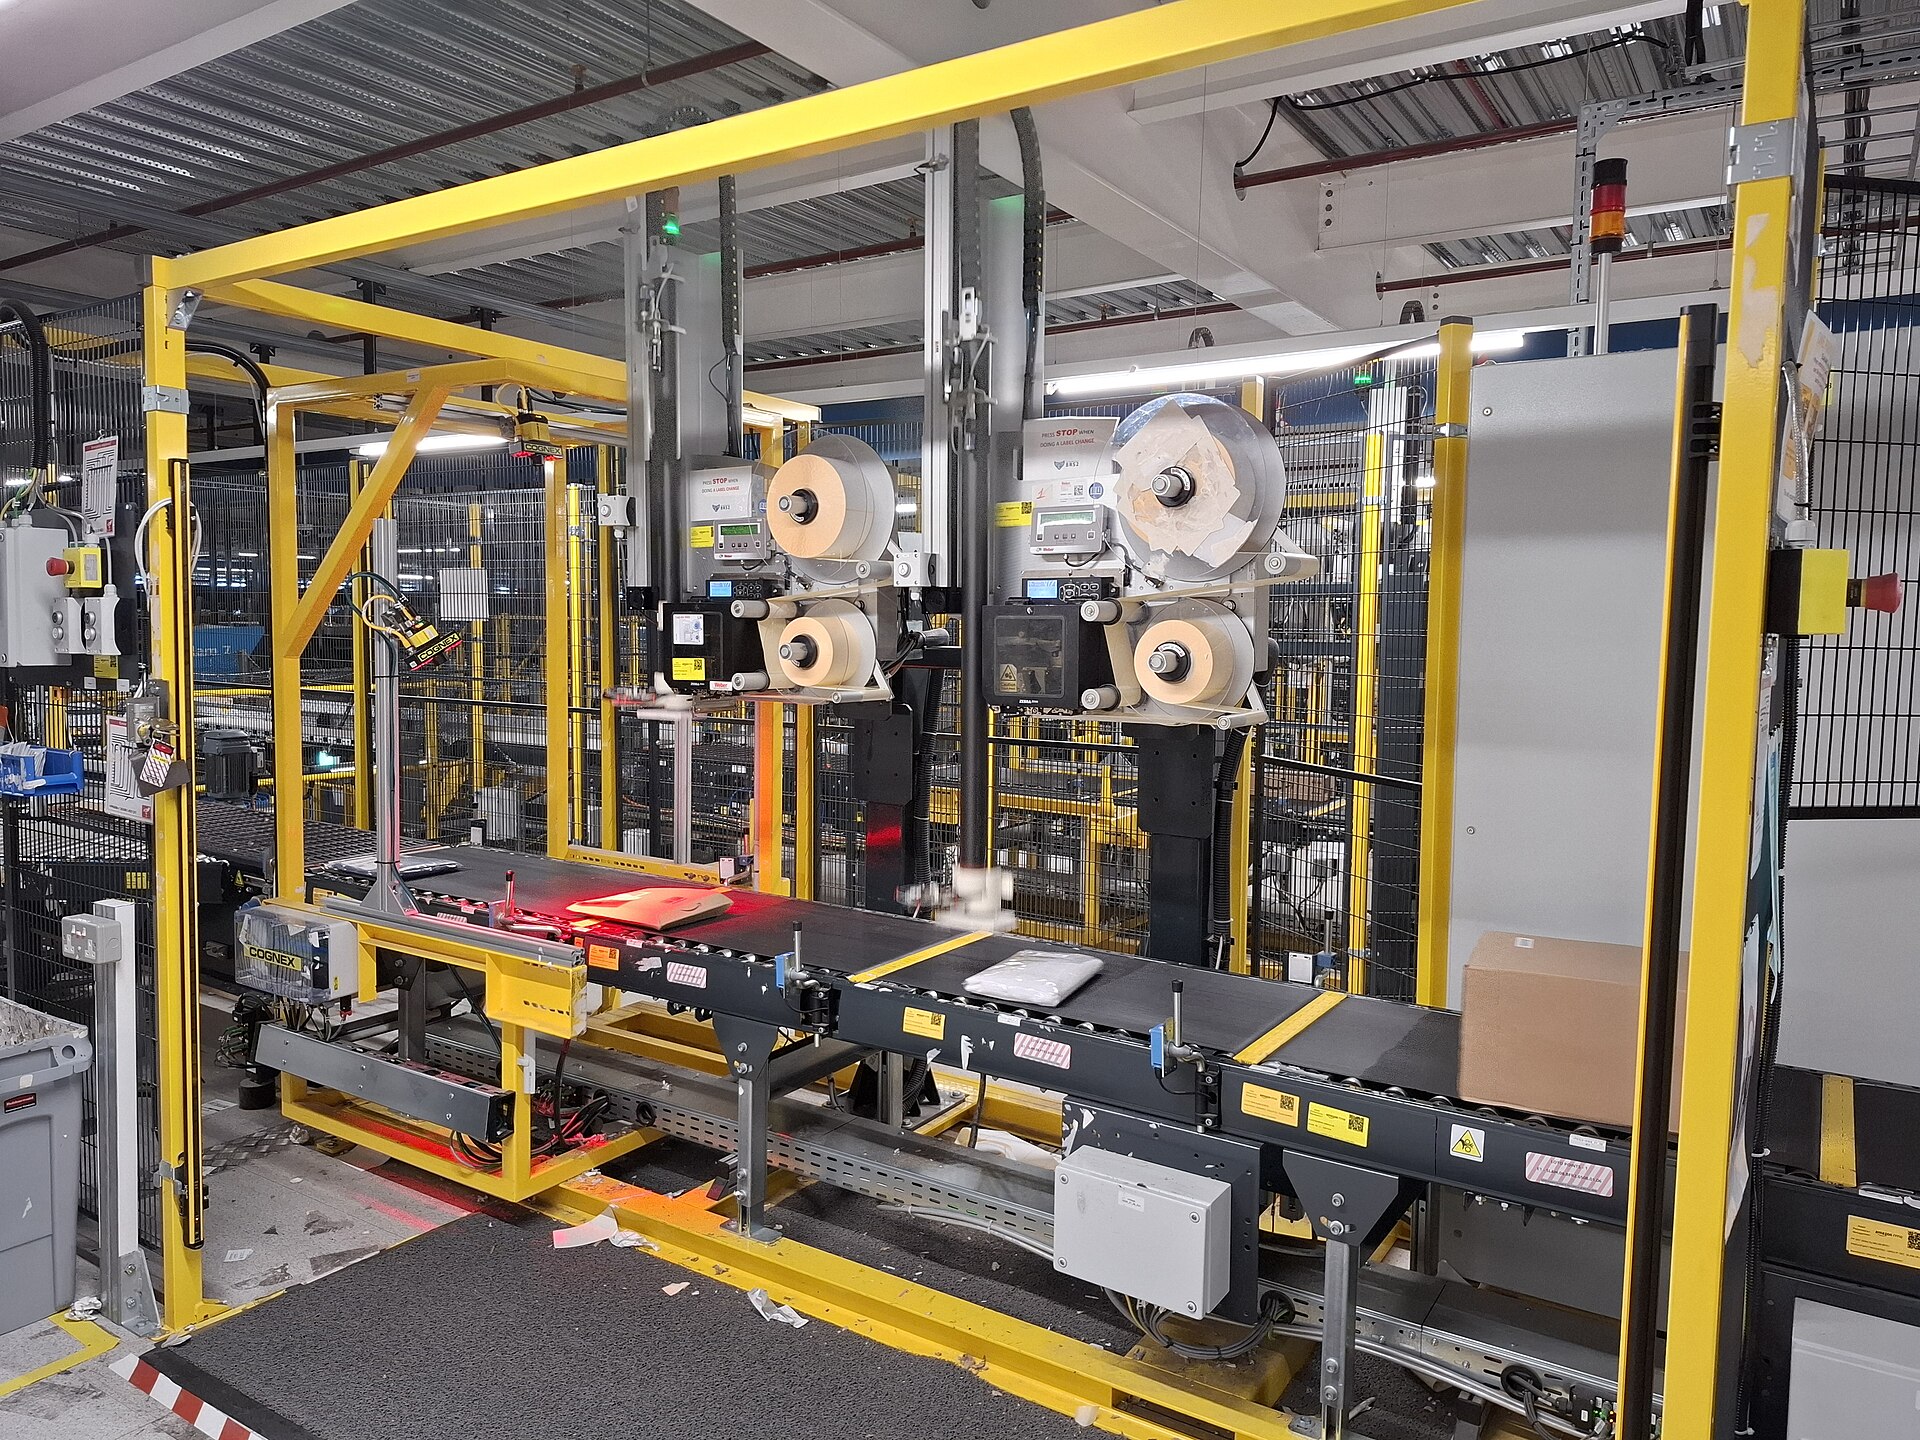
A parcel labelling line at Amazon's Swindon fulfilment centre in 2025. Fixed automation repeats one narrow task and has to finish it nearly every time, the product end of the gap. Photo: Auledas / Wikimedia Commons. Licence: CC BY 4.0.Appears on: The Reliability Gap
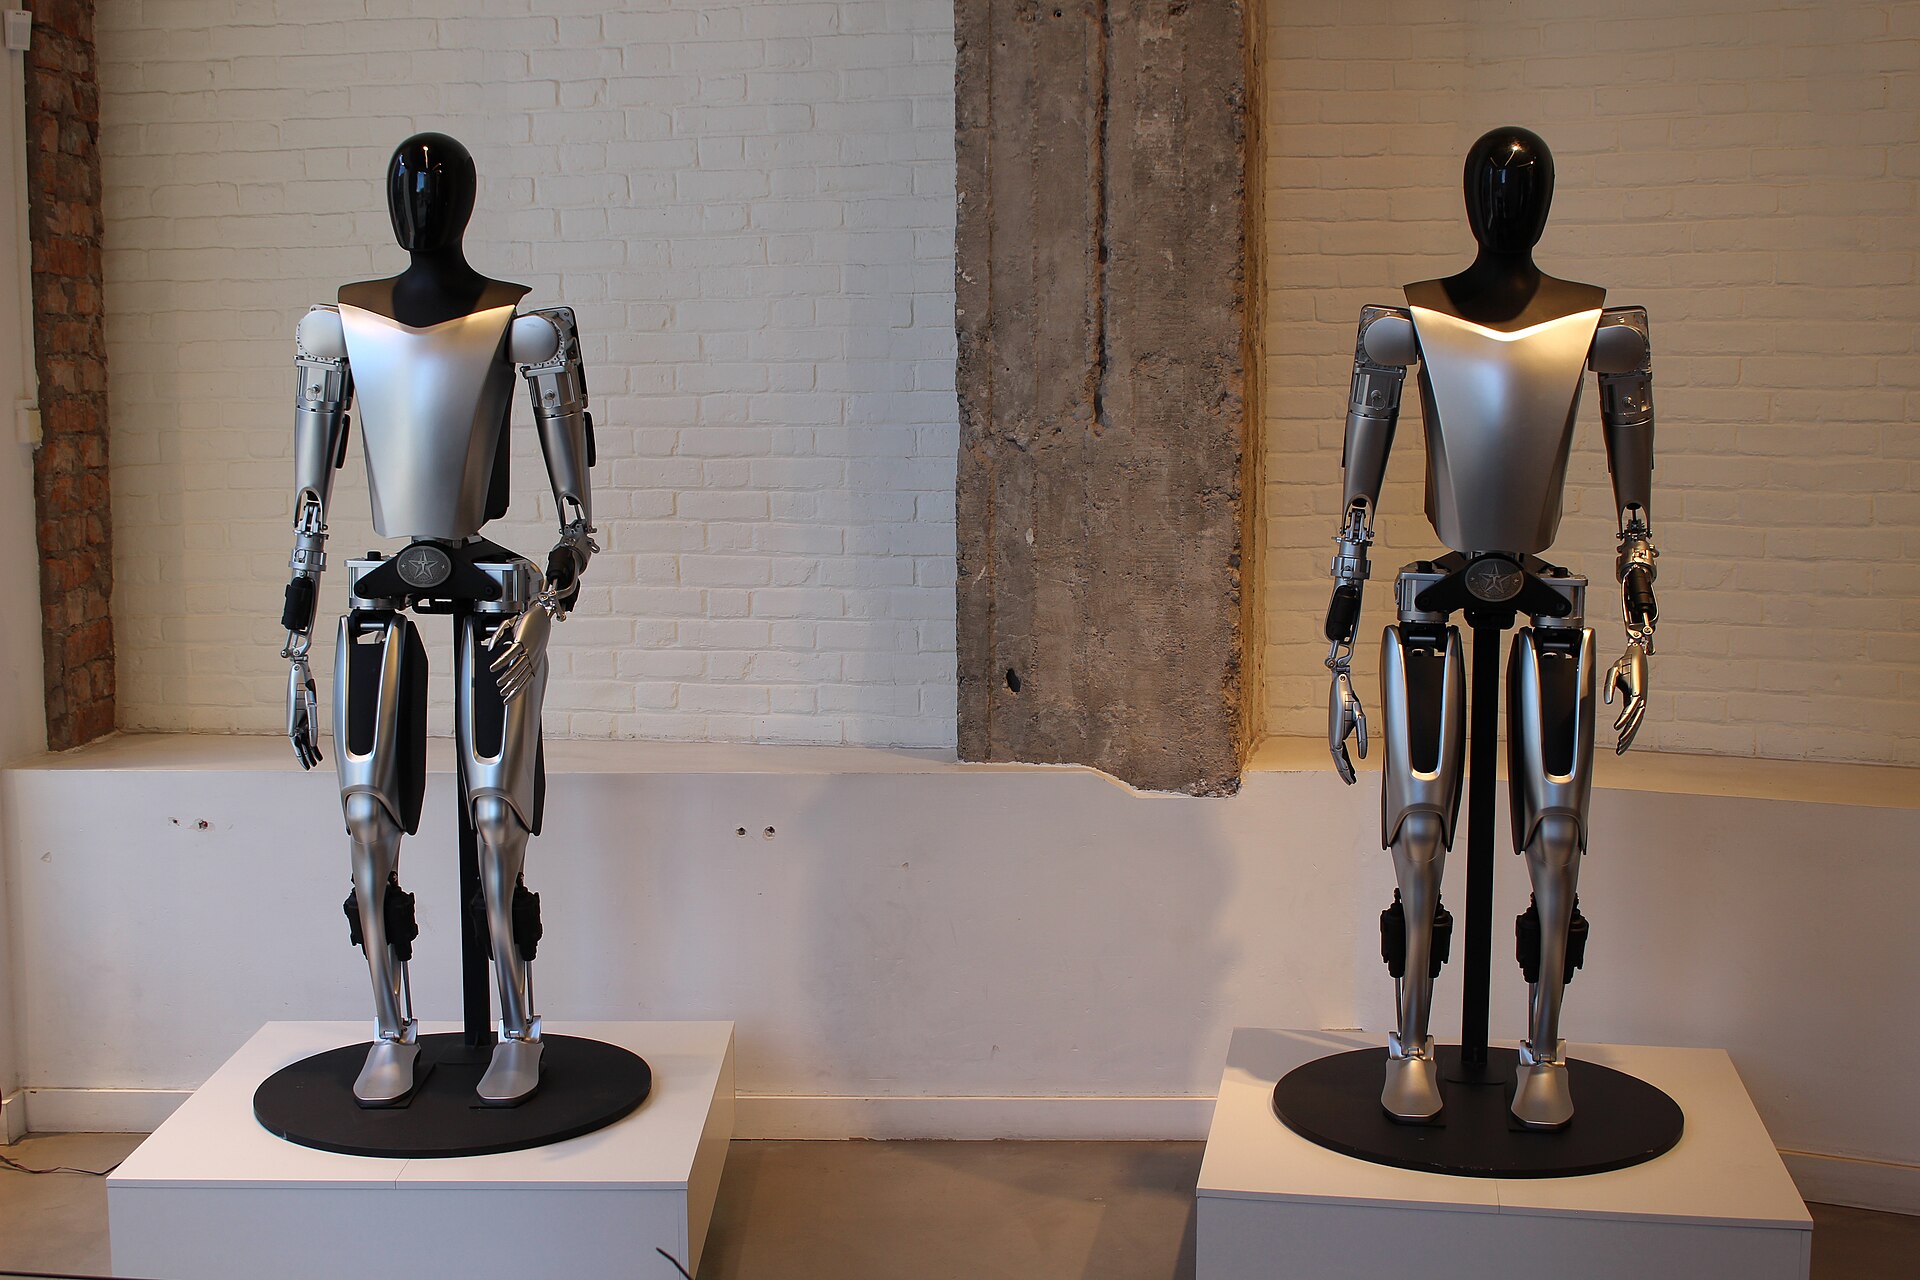
Two Tesla Optimus humanoids on display in Stockholm in 2024. Tesla's 2026 updates list both of its Optimus production lines as still under construction. Photo: Ulf Klingström / Wikimedia Commons. Licence: Public domain.Appears on: The Reliability Gap
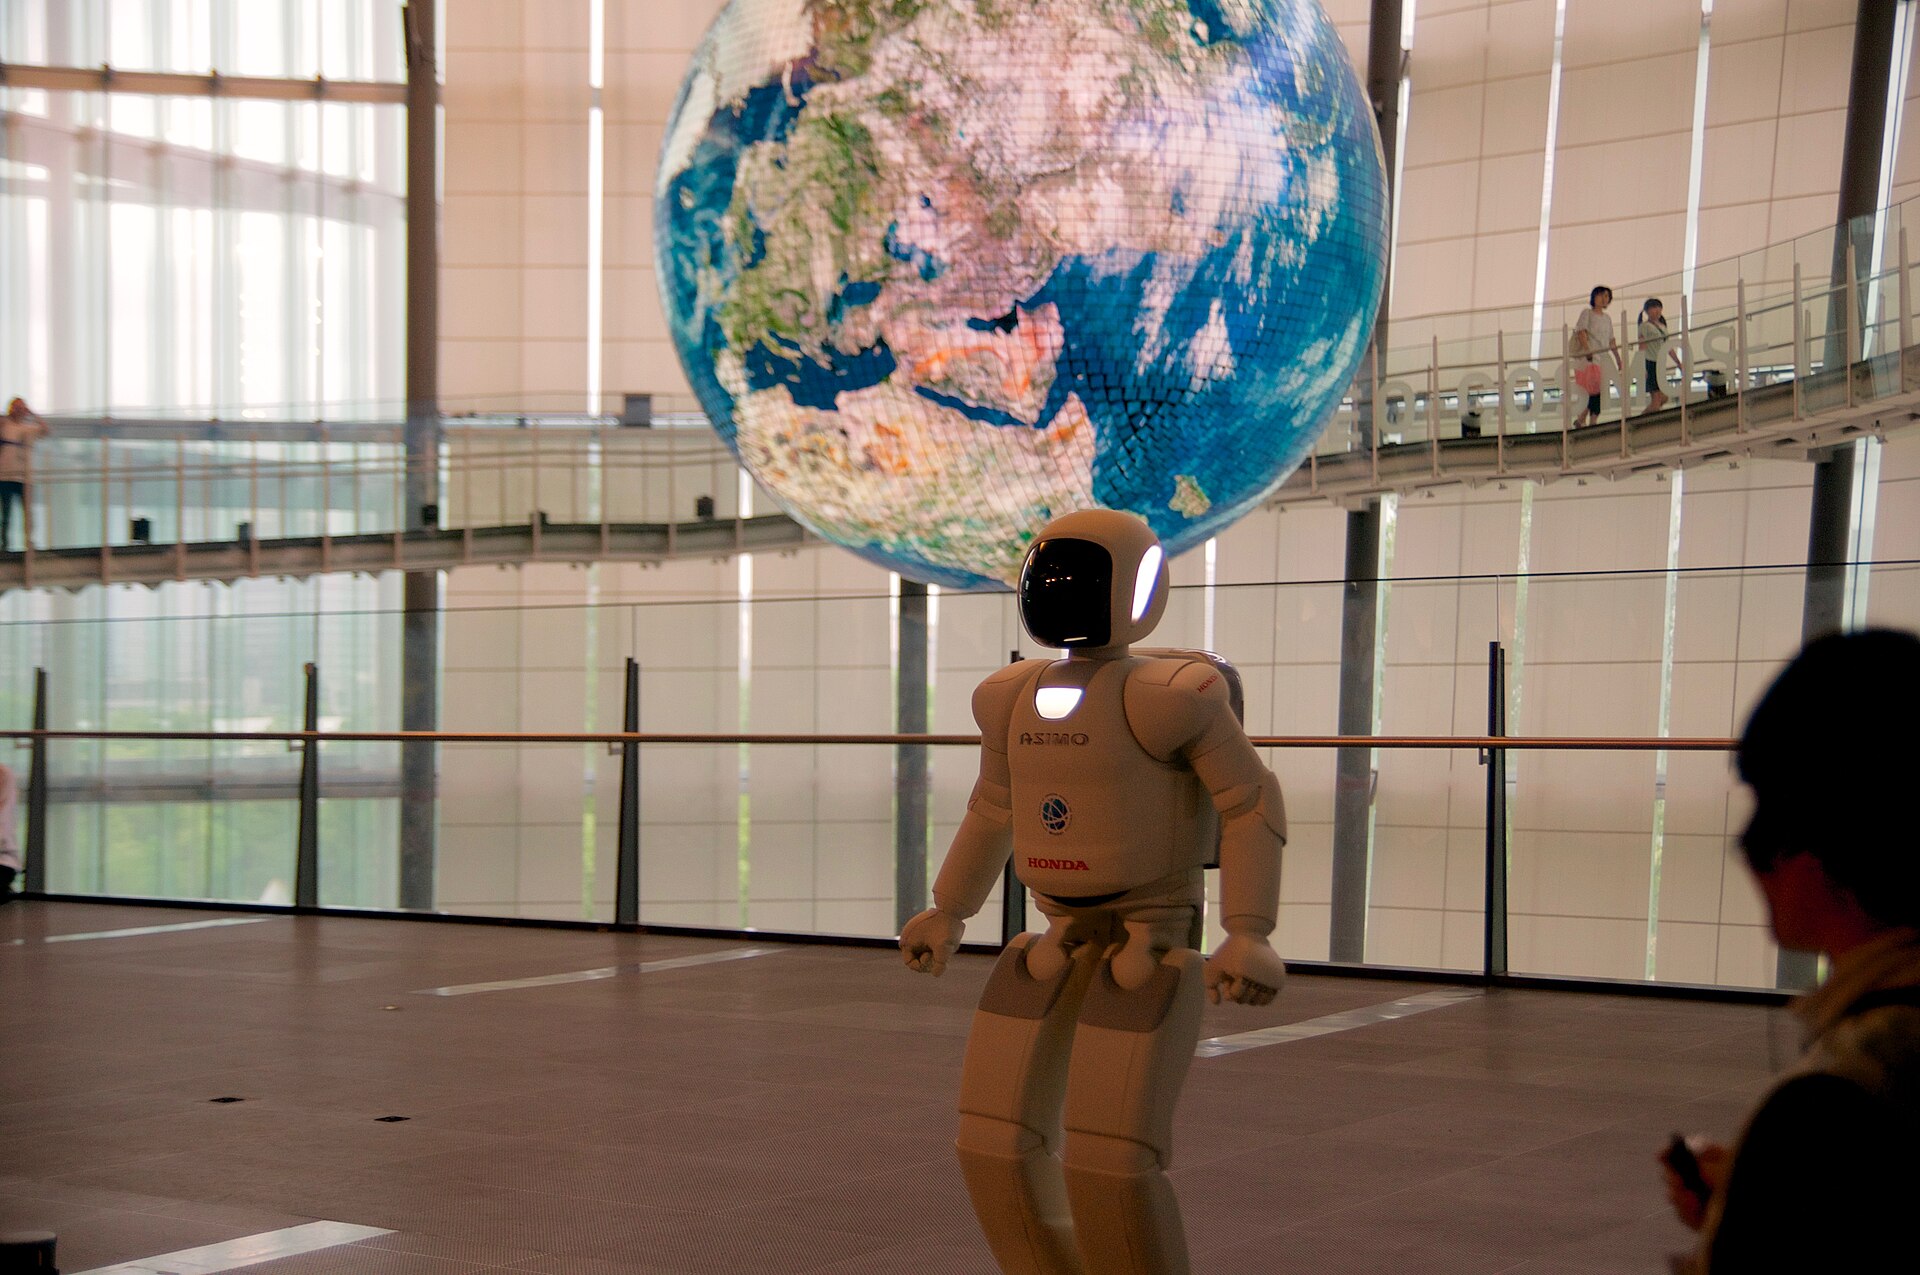
Honda's ASIMO performing at Miraikan, Tokyo, in 2016. The bear case holds that capital arrives on demonstrations like this one and deployment evidence arrives late. Photo: Sylvain Kalache / Wikimedia Commons. Licence: CC BY 2.0.Appears on: The Bear Case
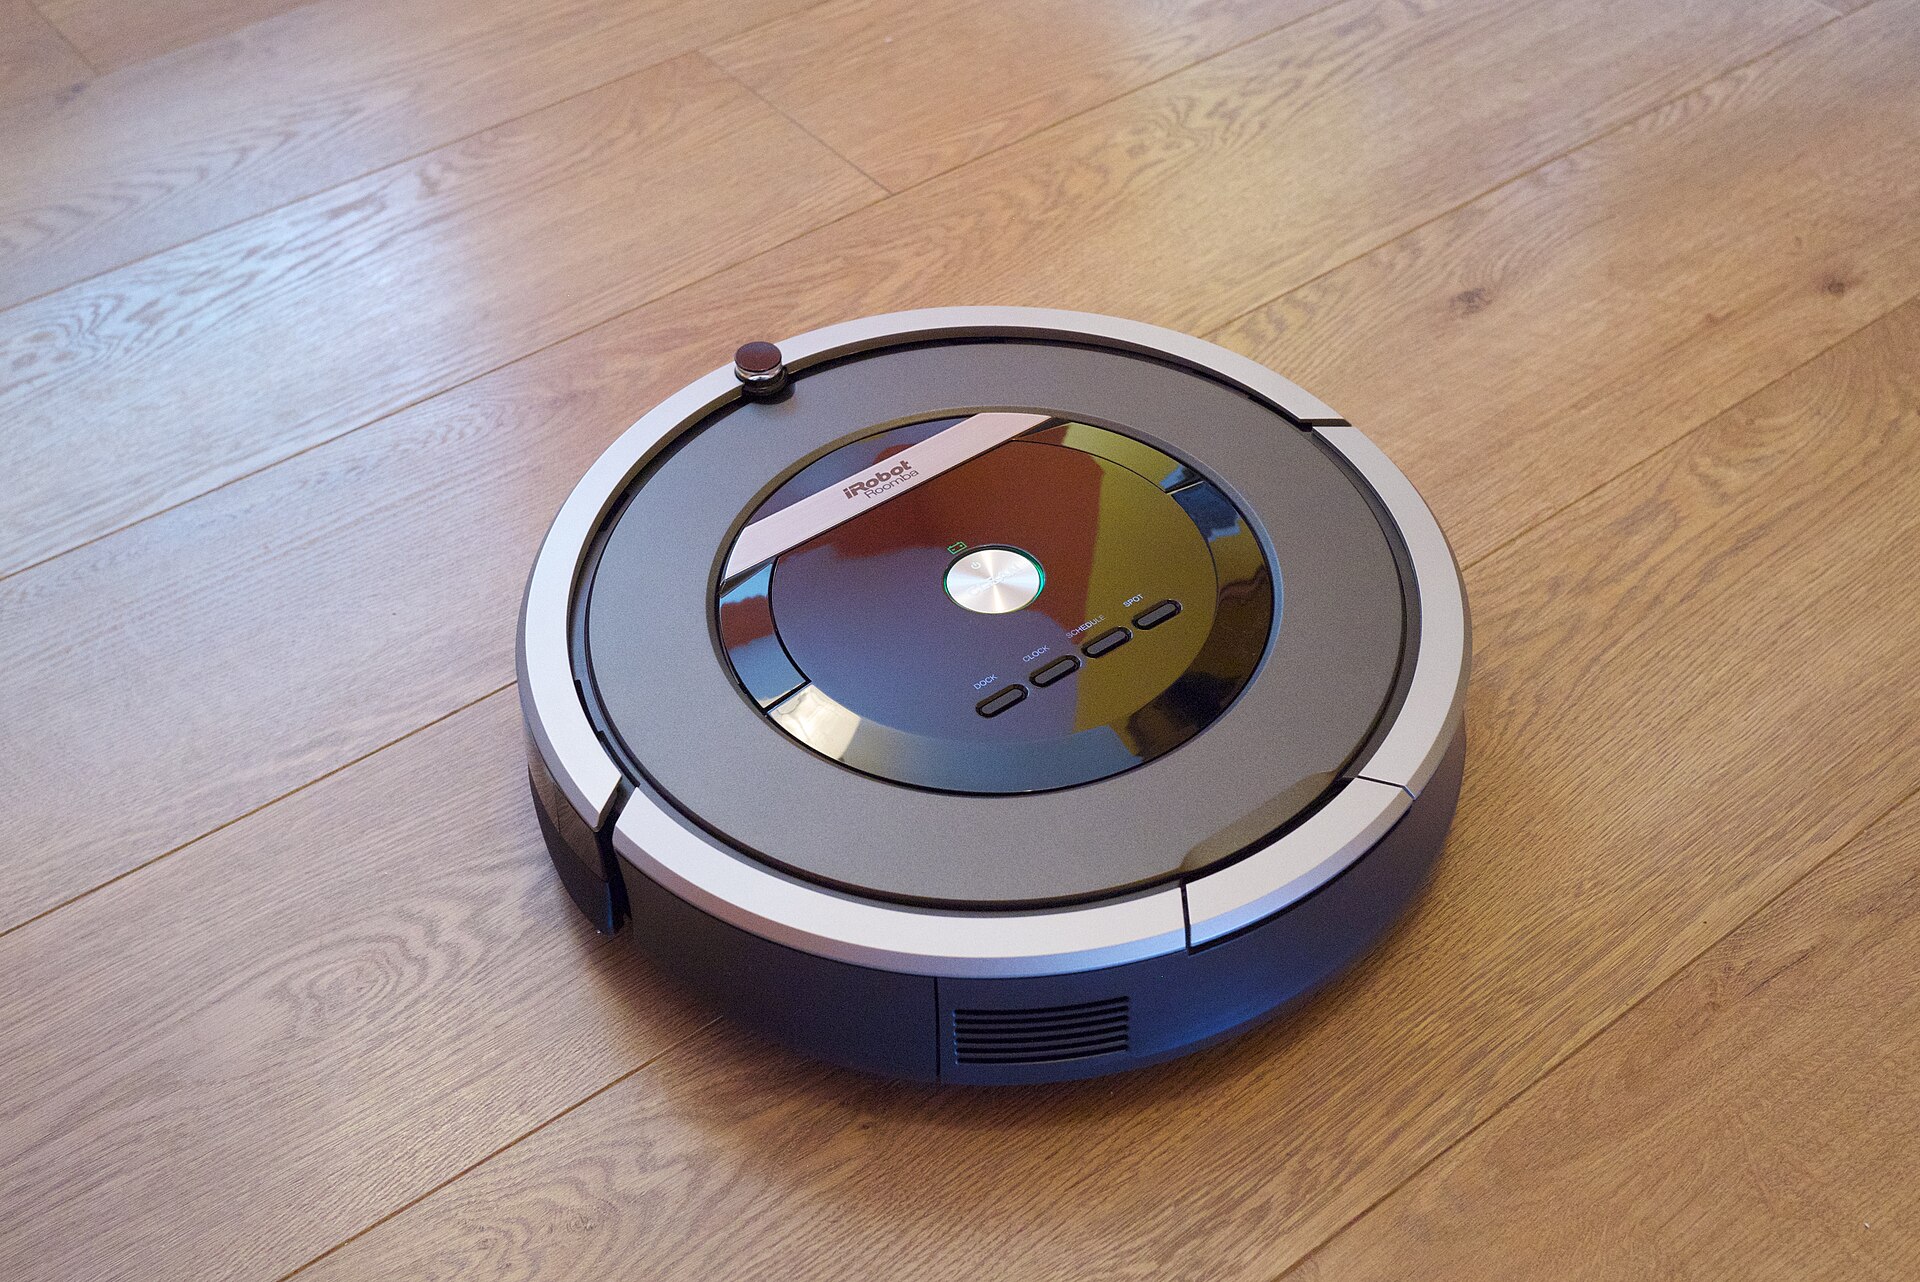
An iRobot Roomba 870 in 2014. Rodney Brooks co-founded iRobot, which makes the Roomba, so his forecasts come from someone who has shipped robots. Photo: Kārlis Dambrāns / Wikimedia Commons. Licence: CC BY 2.0.Appears on: The Bear Case
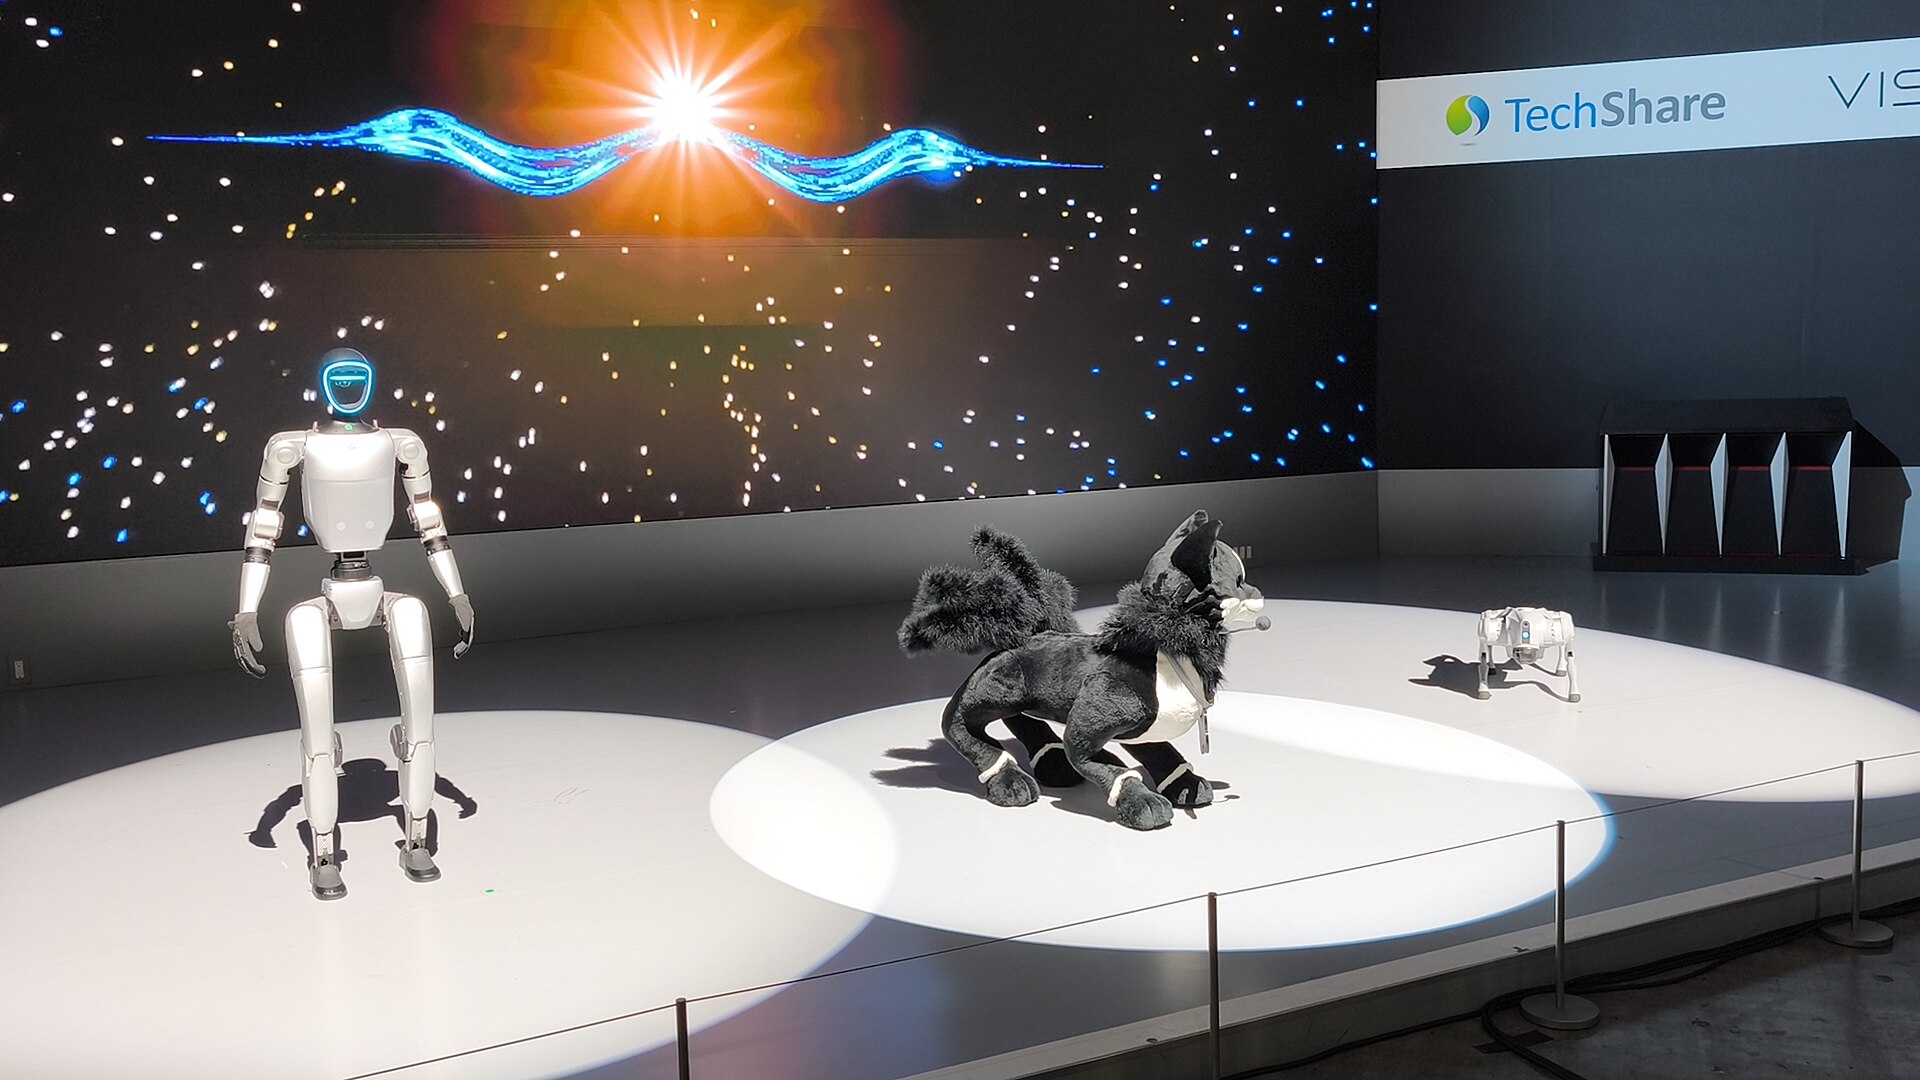
A Unitree G1 humanoid on stage at the Japan Mobility Show 2025. Unitree is one of five backers of the humanoid thesis, one of six rival bets on how robot intelligence gets built. Photo: RuinDig/Yuki Uchida / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Competing Theses
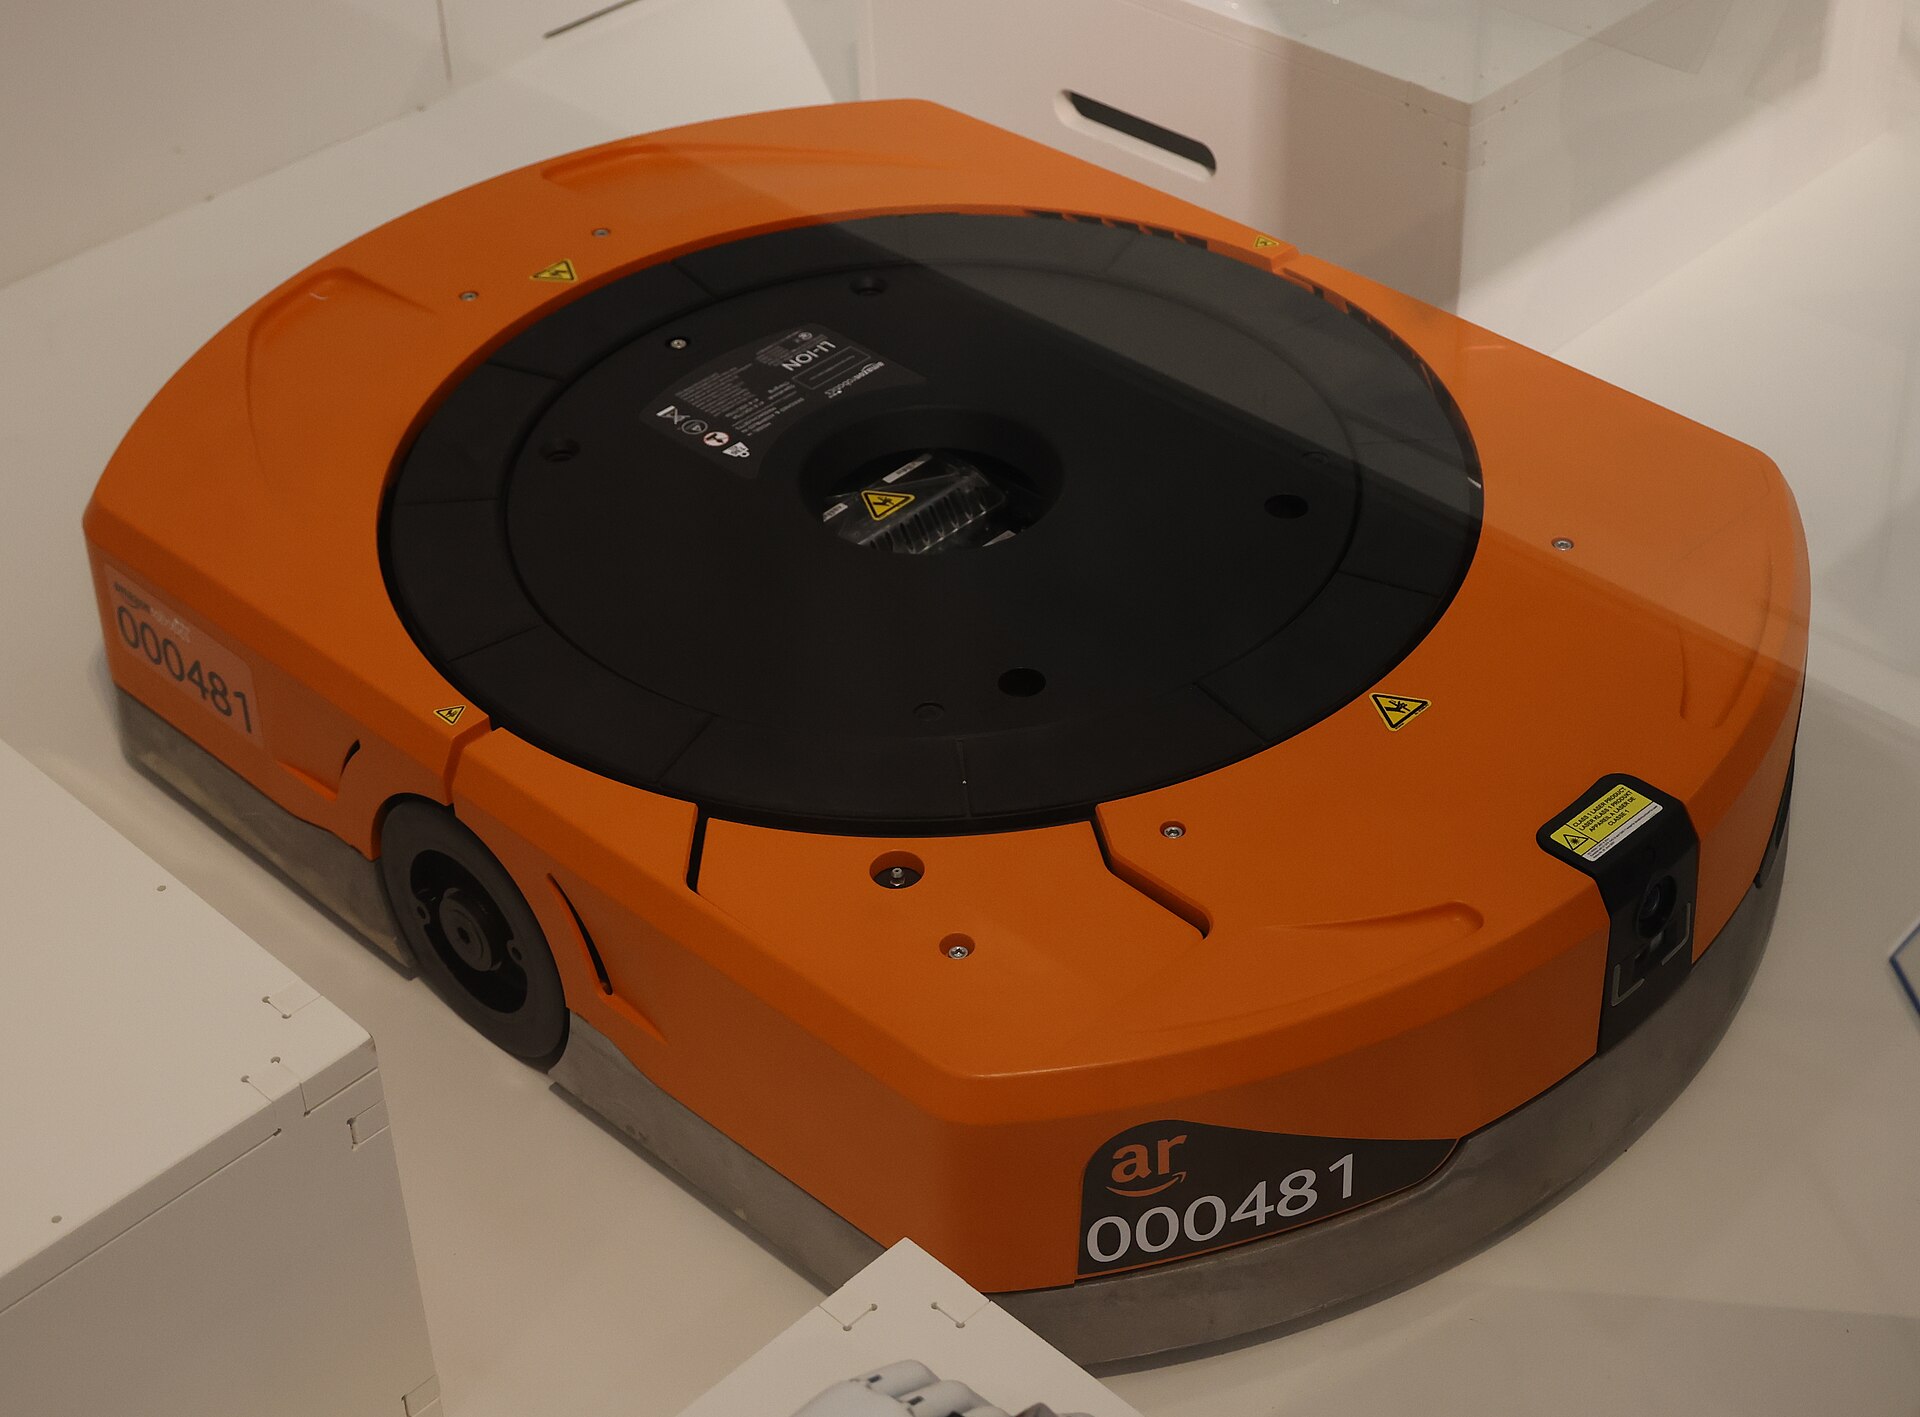
An Amazon warehouse drive unit, photographed in 2023. Amazon has deployed its millionth robot, and the task-specific side bets that purpose-built machines like this one win on cost per task. Photo: Geni / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Competing Theses
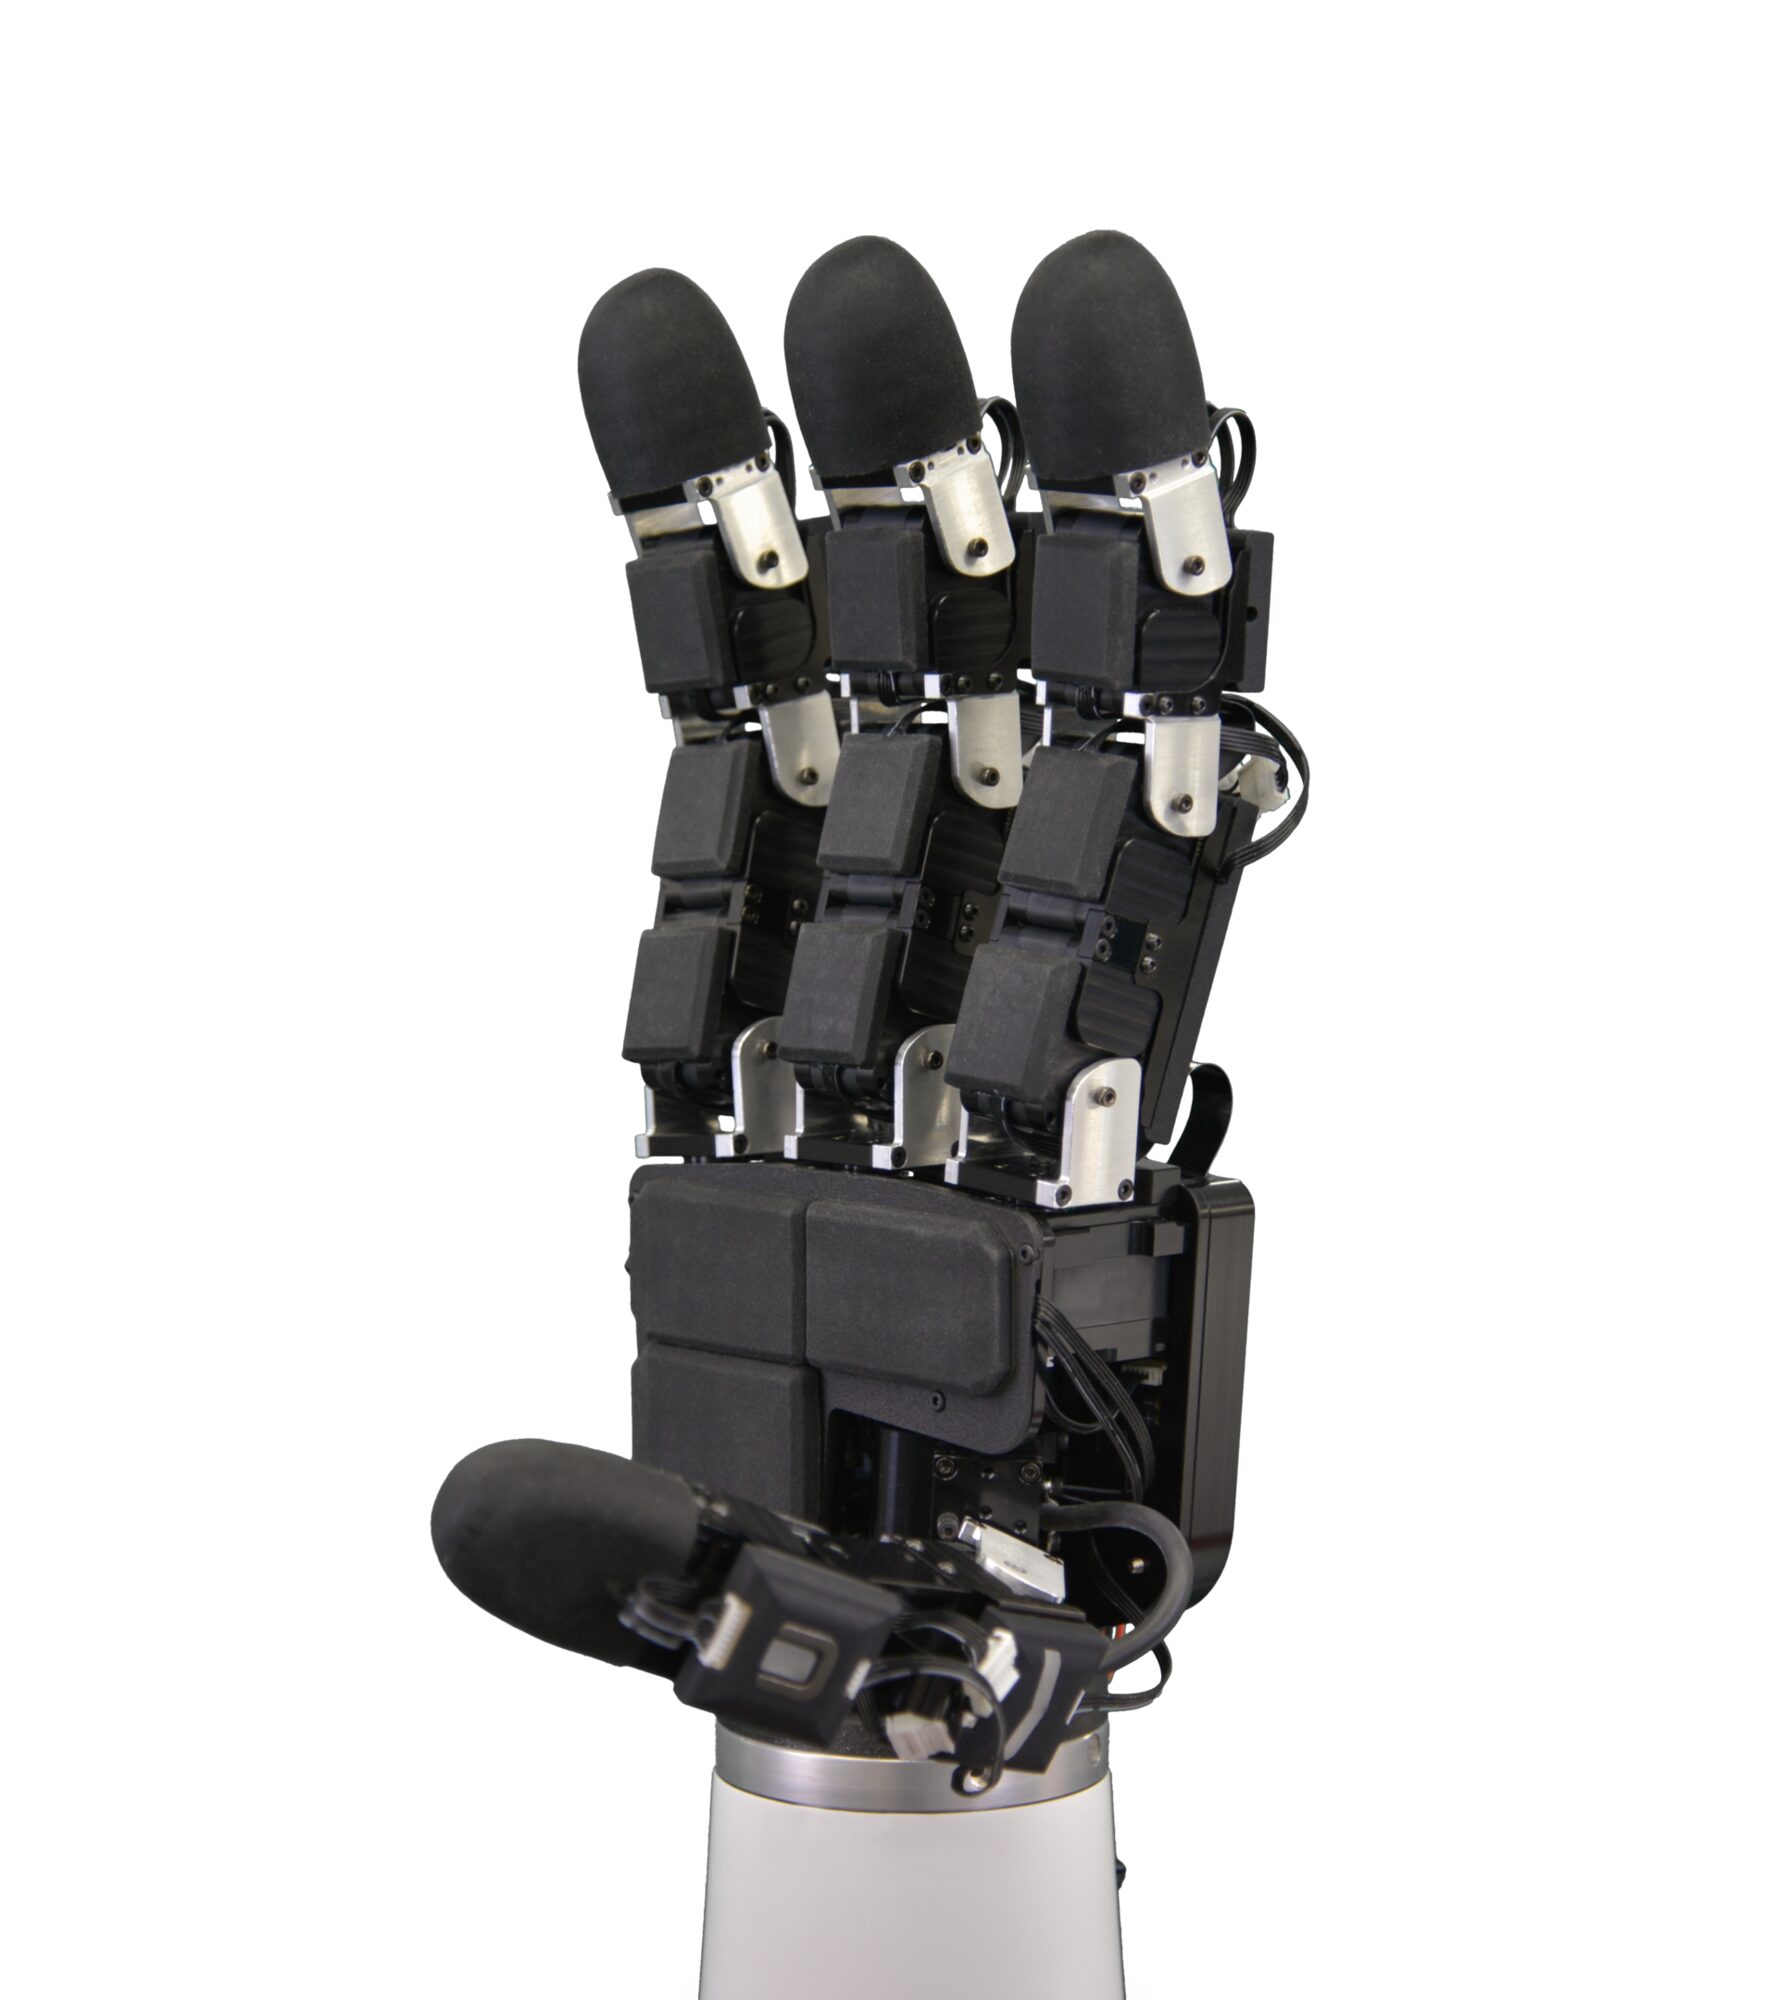
XELA Robotics' uSkin tactile sensors on every finger segment of an Allegro hand, 2021. They measure the contact that cameras lose once the fingers close. Photo: XELA Robotics / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Dexterity
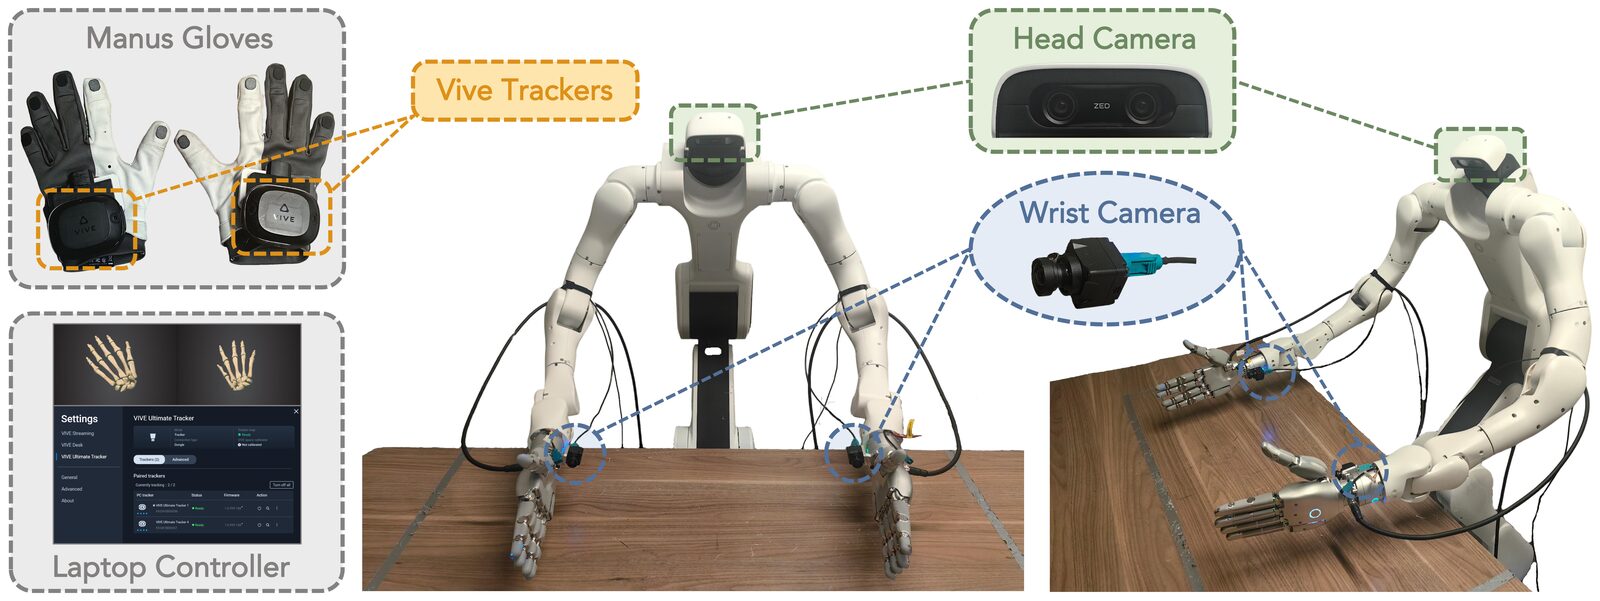
The T-Rex rig: a bimanual robot with two 22-DoF Sharpa Wave hands, a head camera and two wrist cameras, and the gloves and trackers that teleoperate it. Paper figure: Dantong Niu et al. / arXiv. Licence: CC BY 4.0.Appears on: Dexterity
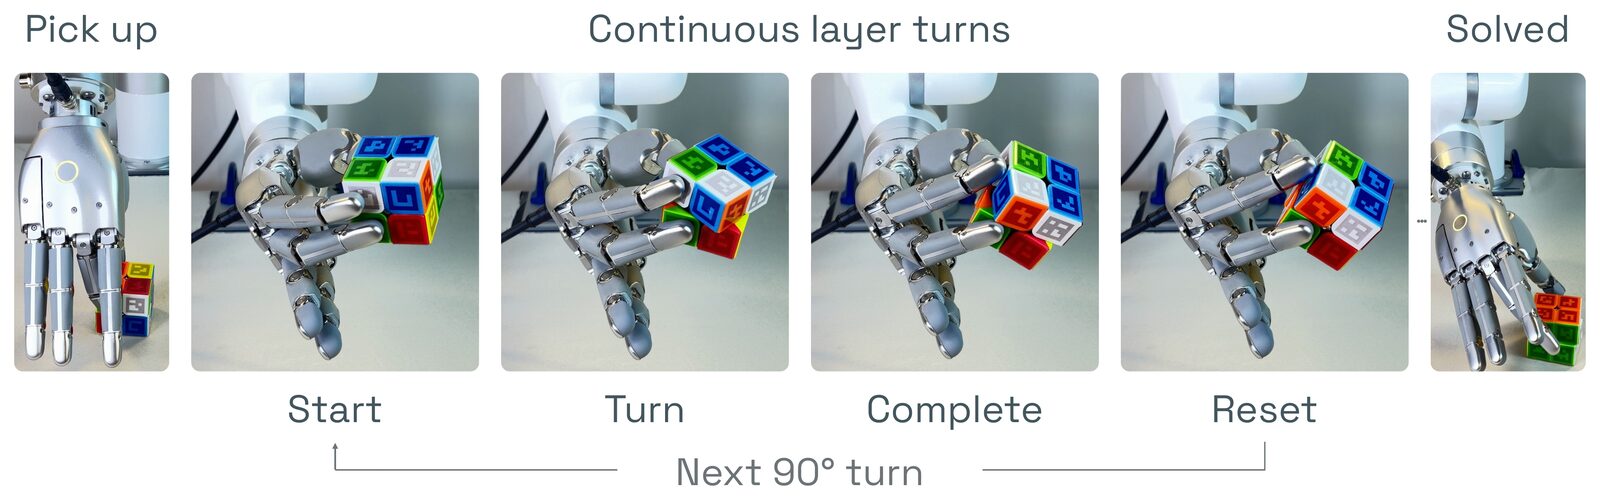
FINGR picks up a 2×2×2 cube, turns one layer at a time inside a single real hand and resets its fingers between turns until the cube is solved. Paper figure: Yutong Liang et al. / arXiv. Licence: CC BY 4.0.Appears on: Dexterity
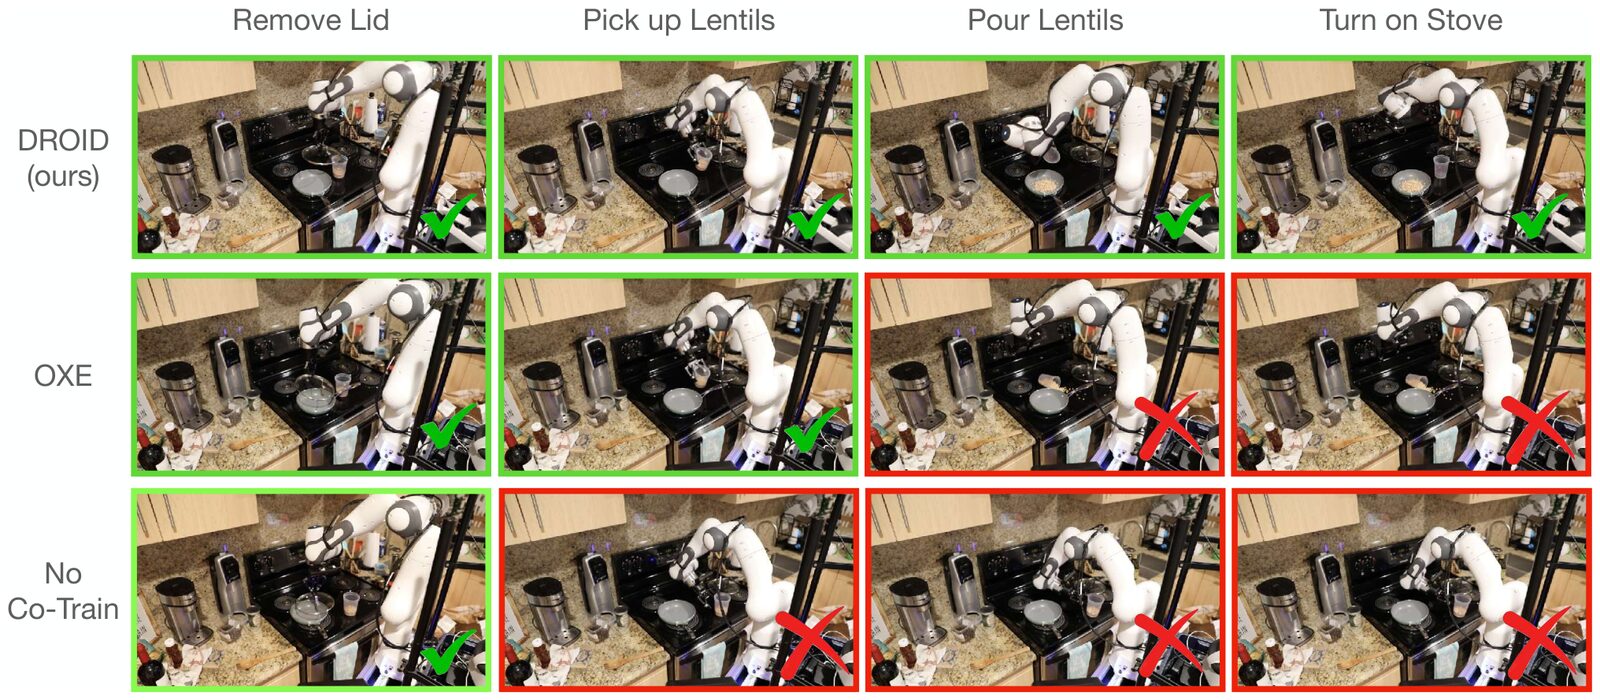
One cooking task in a home kitchen with unseen distractors, under three training mixes. Only the policy co-trained on DROID's in-the-wild data finishes all four steps. Paper figure: Alexander Khazatsky et al. / arXiv. Licence: CC BY 4.0.Appears on: Generalization
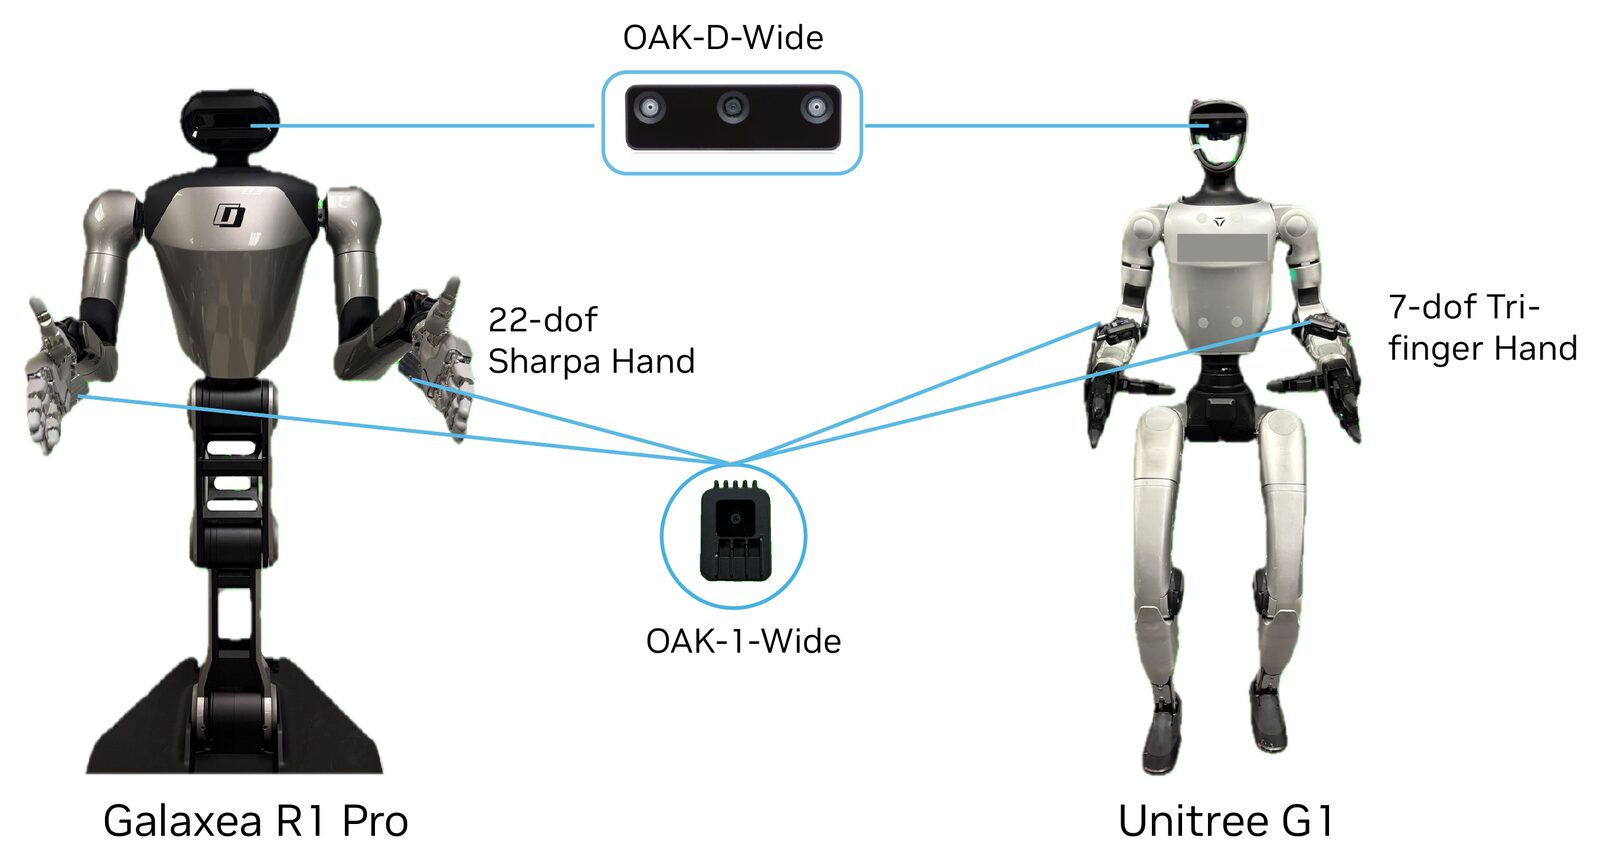
EgoScale's two robots: a Galaxea R1 Pro with 22-DoF Sharpa hands and a Unitree G1 with 7-DoF tri-finger hands. On the G1, human-video pretraining added over 30 points of absolute success on both evaluated tasks. Paper figure: Ruijie Zheng et al. / arXiv. Licence: CC BY 4.0.Appears on: Generalization
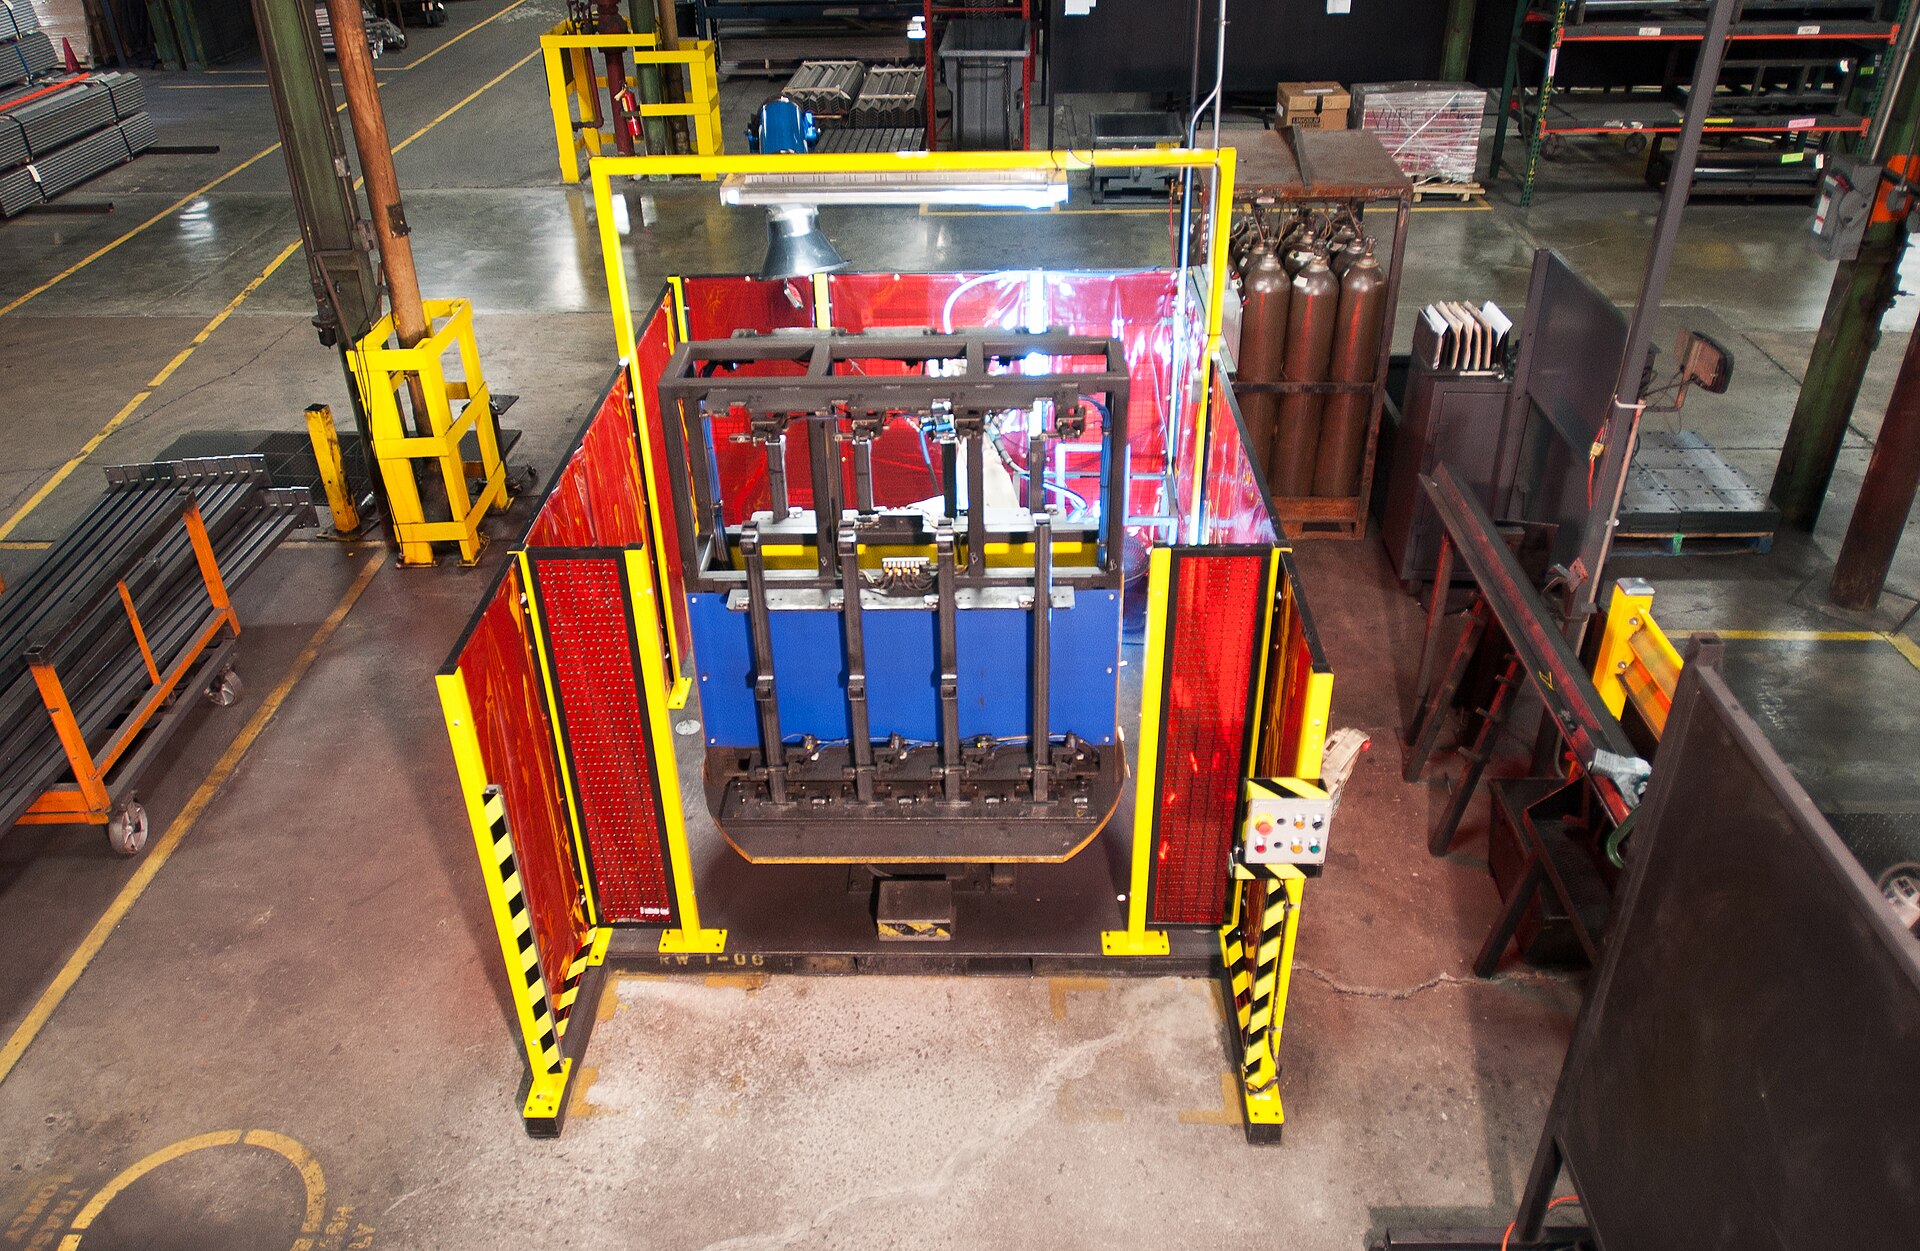
A robotic weld cell behind machine guarding and weld curtains. Fencing people out is the oldest safeguard; robots that work without a fence use one of four collaborative modes. Photo: WireCrafters / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Safety and Assurance
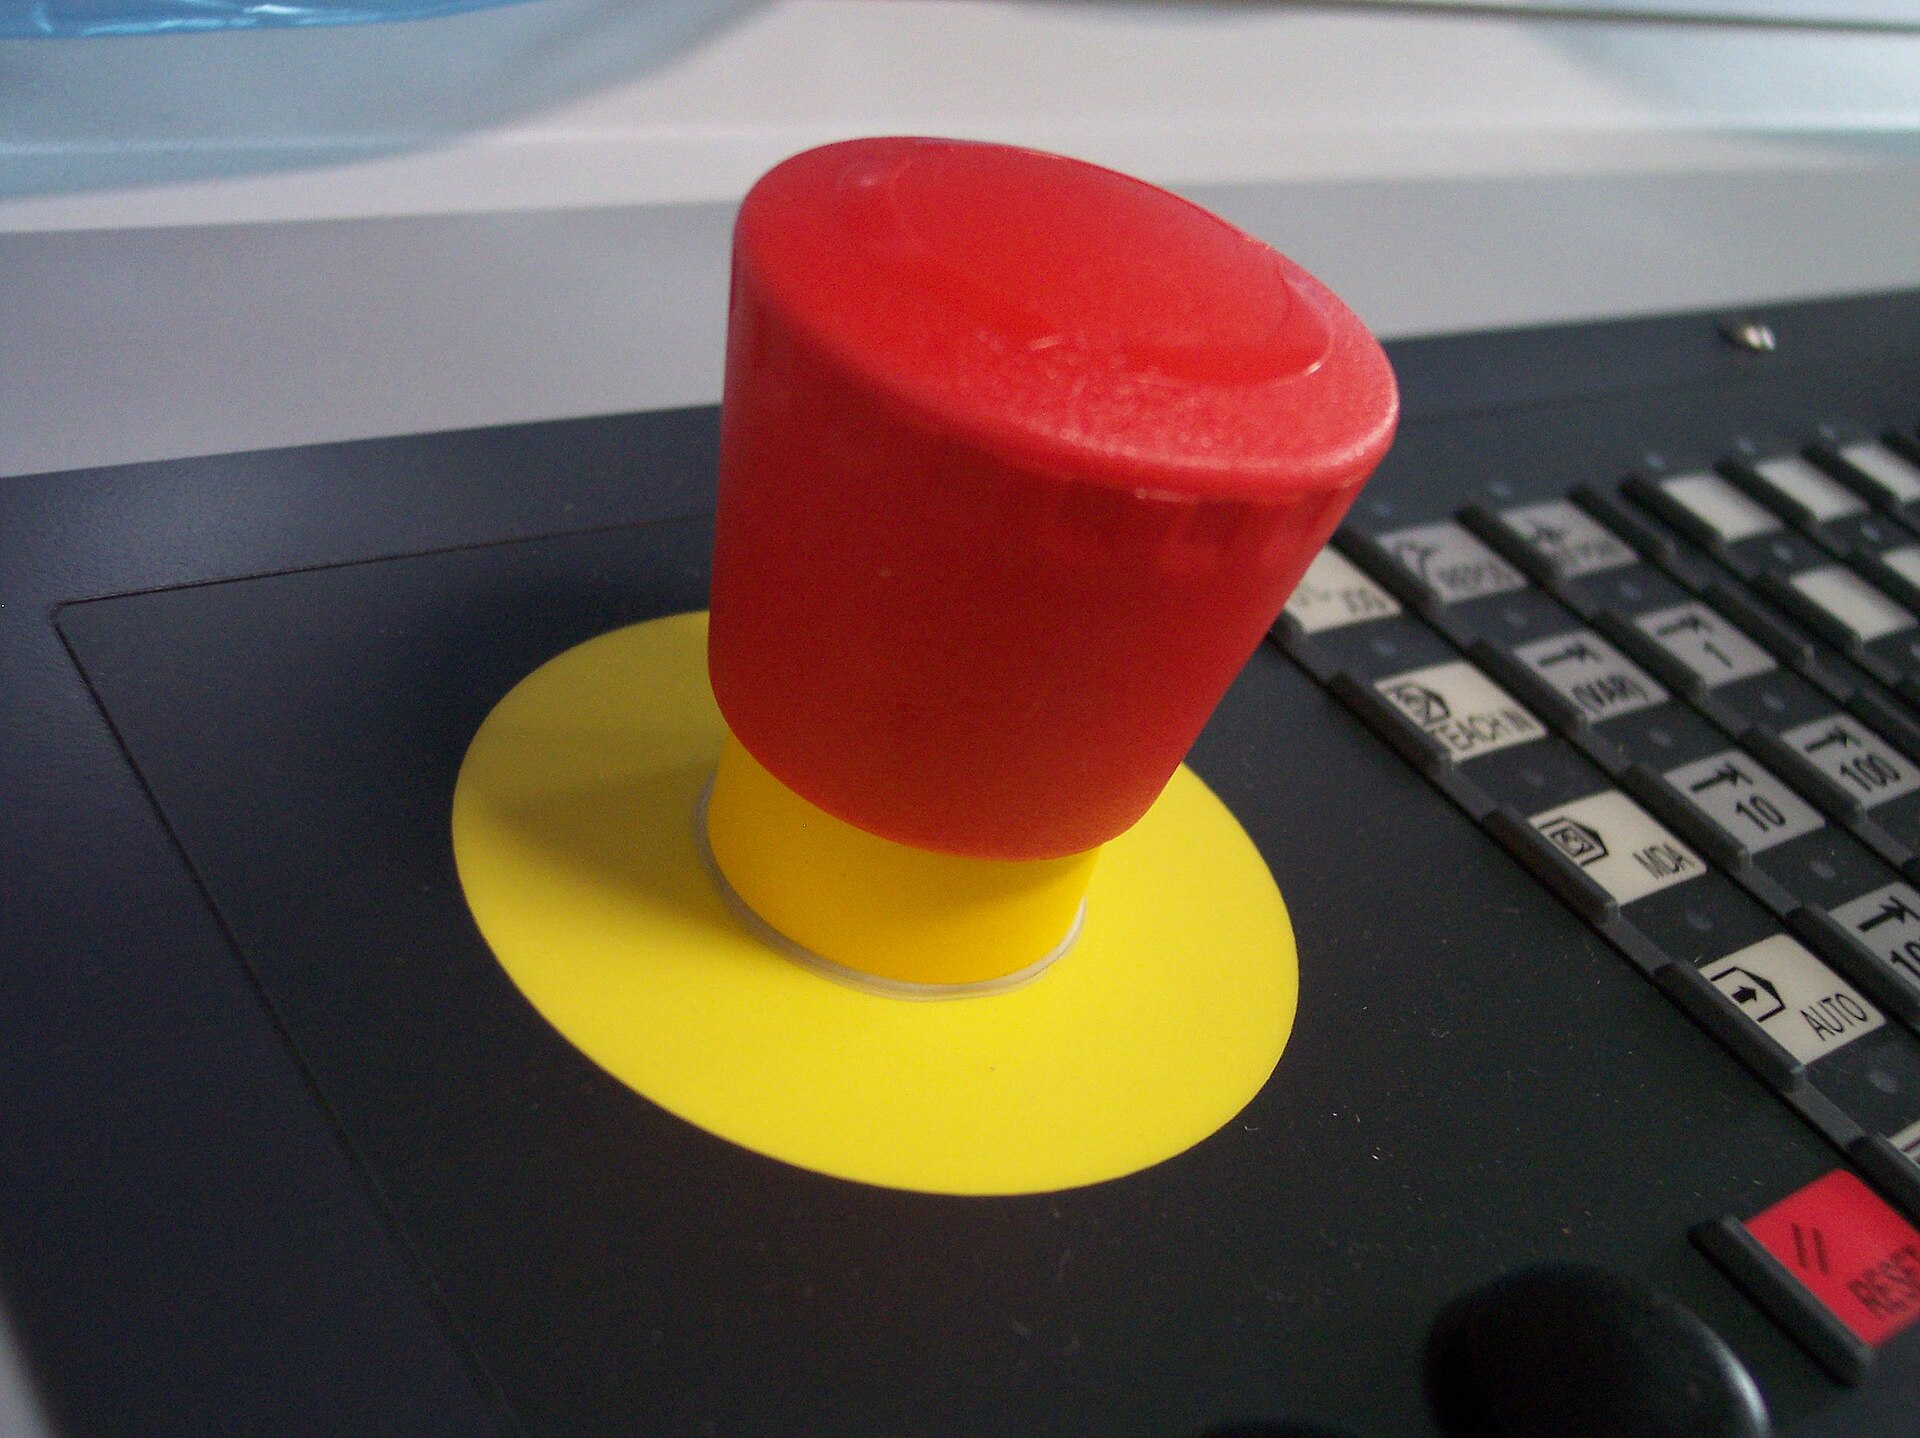
A Siemens emergency-stop actuator on a machine control panel. It acts only after a person has seen the hazard and pressed it. Photo: Stahlkocher / Wikimedia Commons. Licence: CC BY-SA 3.0.Appears on: Safety and Assurance
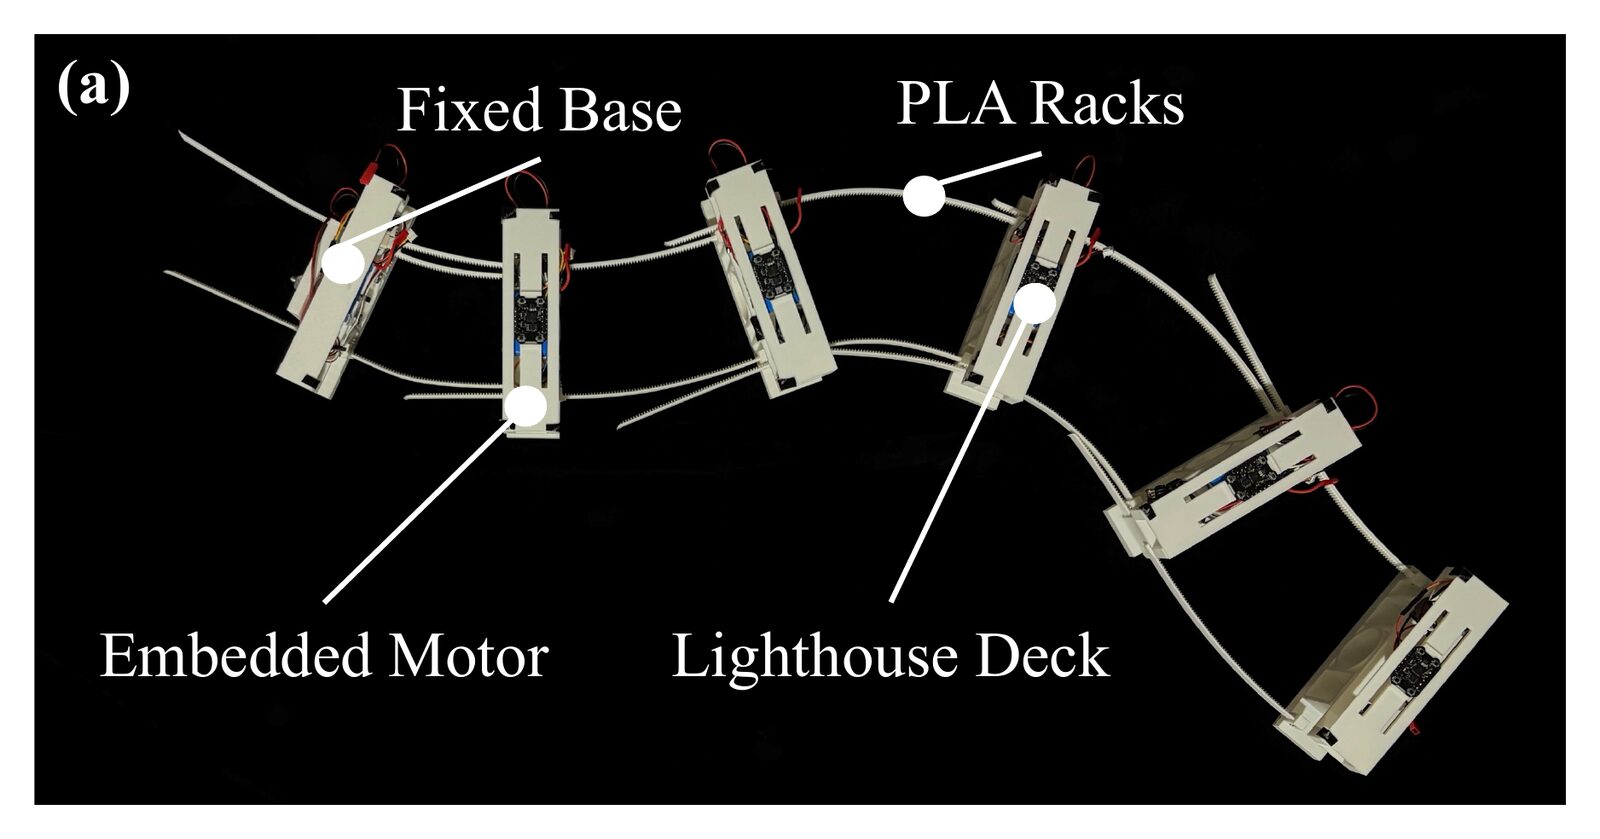
Cai and colleagues' hyper-redundant robot: five segments that extend and bend as their motors drive paired flexible racks. Weighted barrier functions kept it clear of obstacles while correcting its tracking. Paper figure: Zijian Cai et al. / arXiv. Licence: CC BY 4.0.Appears on: Safety and Assurance
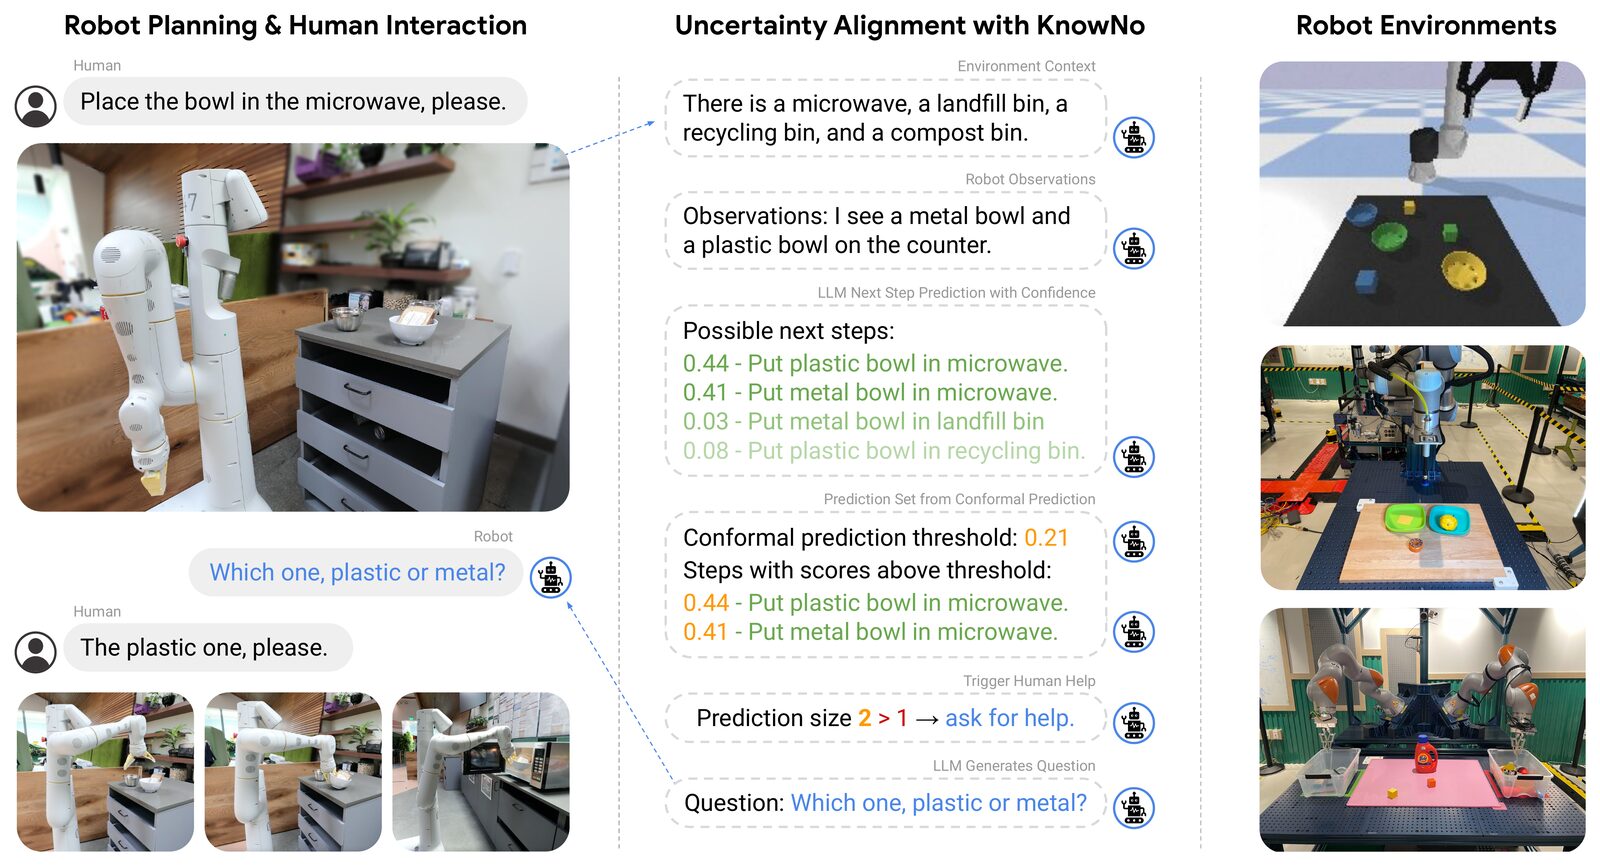
Told to put the bowl in the microwave with a plastic and a metal bowl in view, KnowNo keeps two plans above its conformal threshold and asks which bowl is meant. Paper figure: Allen Z. Ren et al. / arXiv. Licence: CC BY 4.0.Appears on: Safety and Assurance
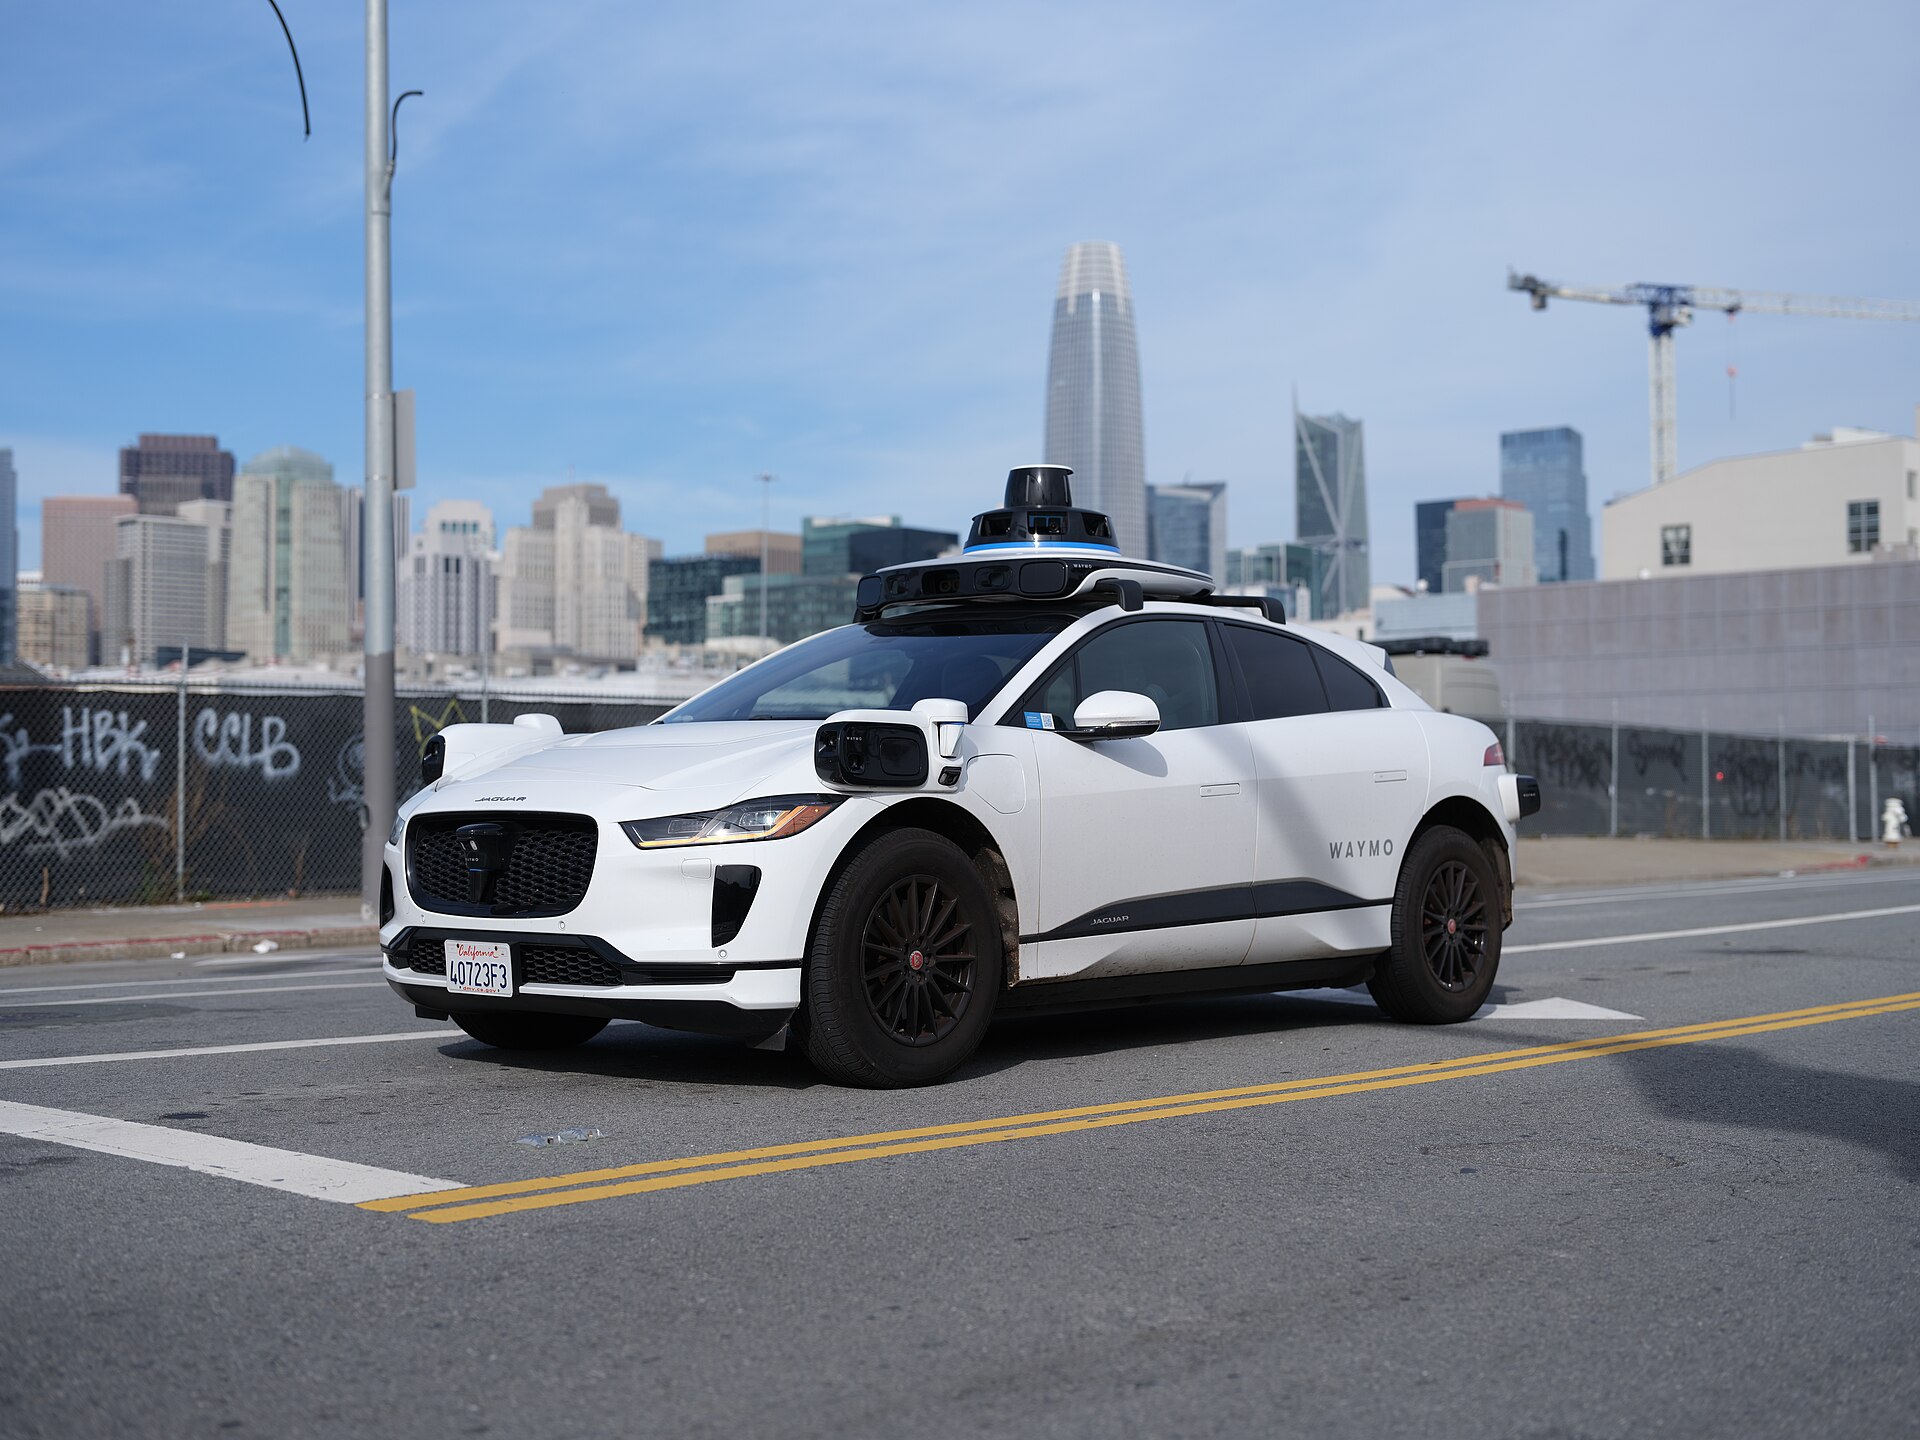
A Waymo Jaguar I-Pace driving itself through San Francisco in 2023. Waymo's 2025 study of 56.7 million rider-only miles found statistically significant crash reductions against human benchmarks in every outcome it could test. Photo: Dllu / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Autonomous Vehicles
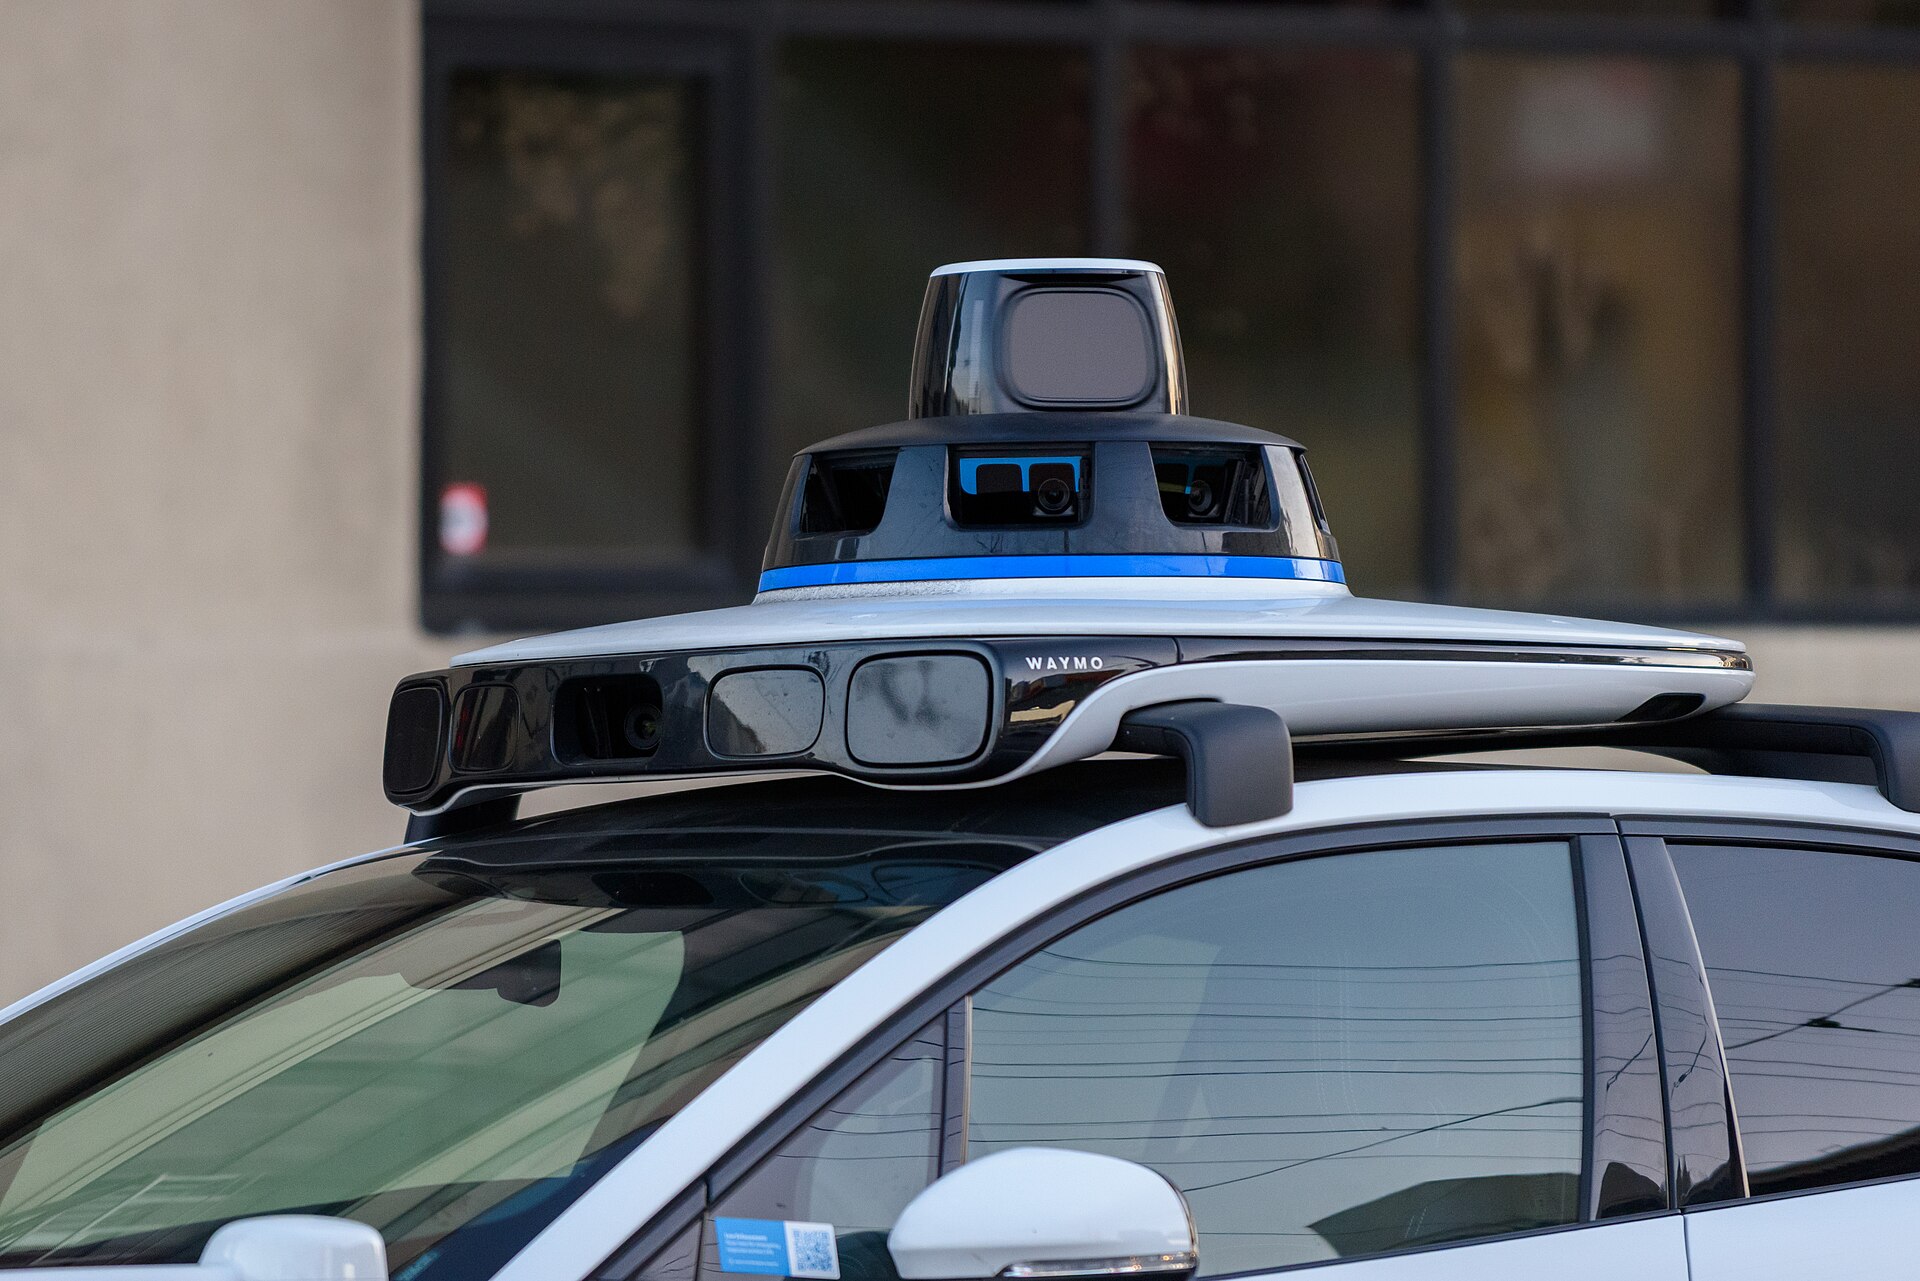
The roof sensor package of a Waymo I-Pace in San Francisco, 2025. Waymo fuses lidar, camera and radar, paying for active range sensing that works in the dark and measures geometry directly. Photo: 9yz / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Autonomous Vehicles
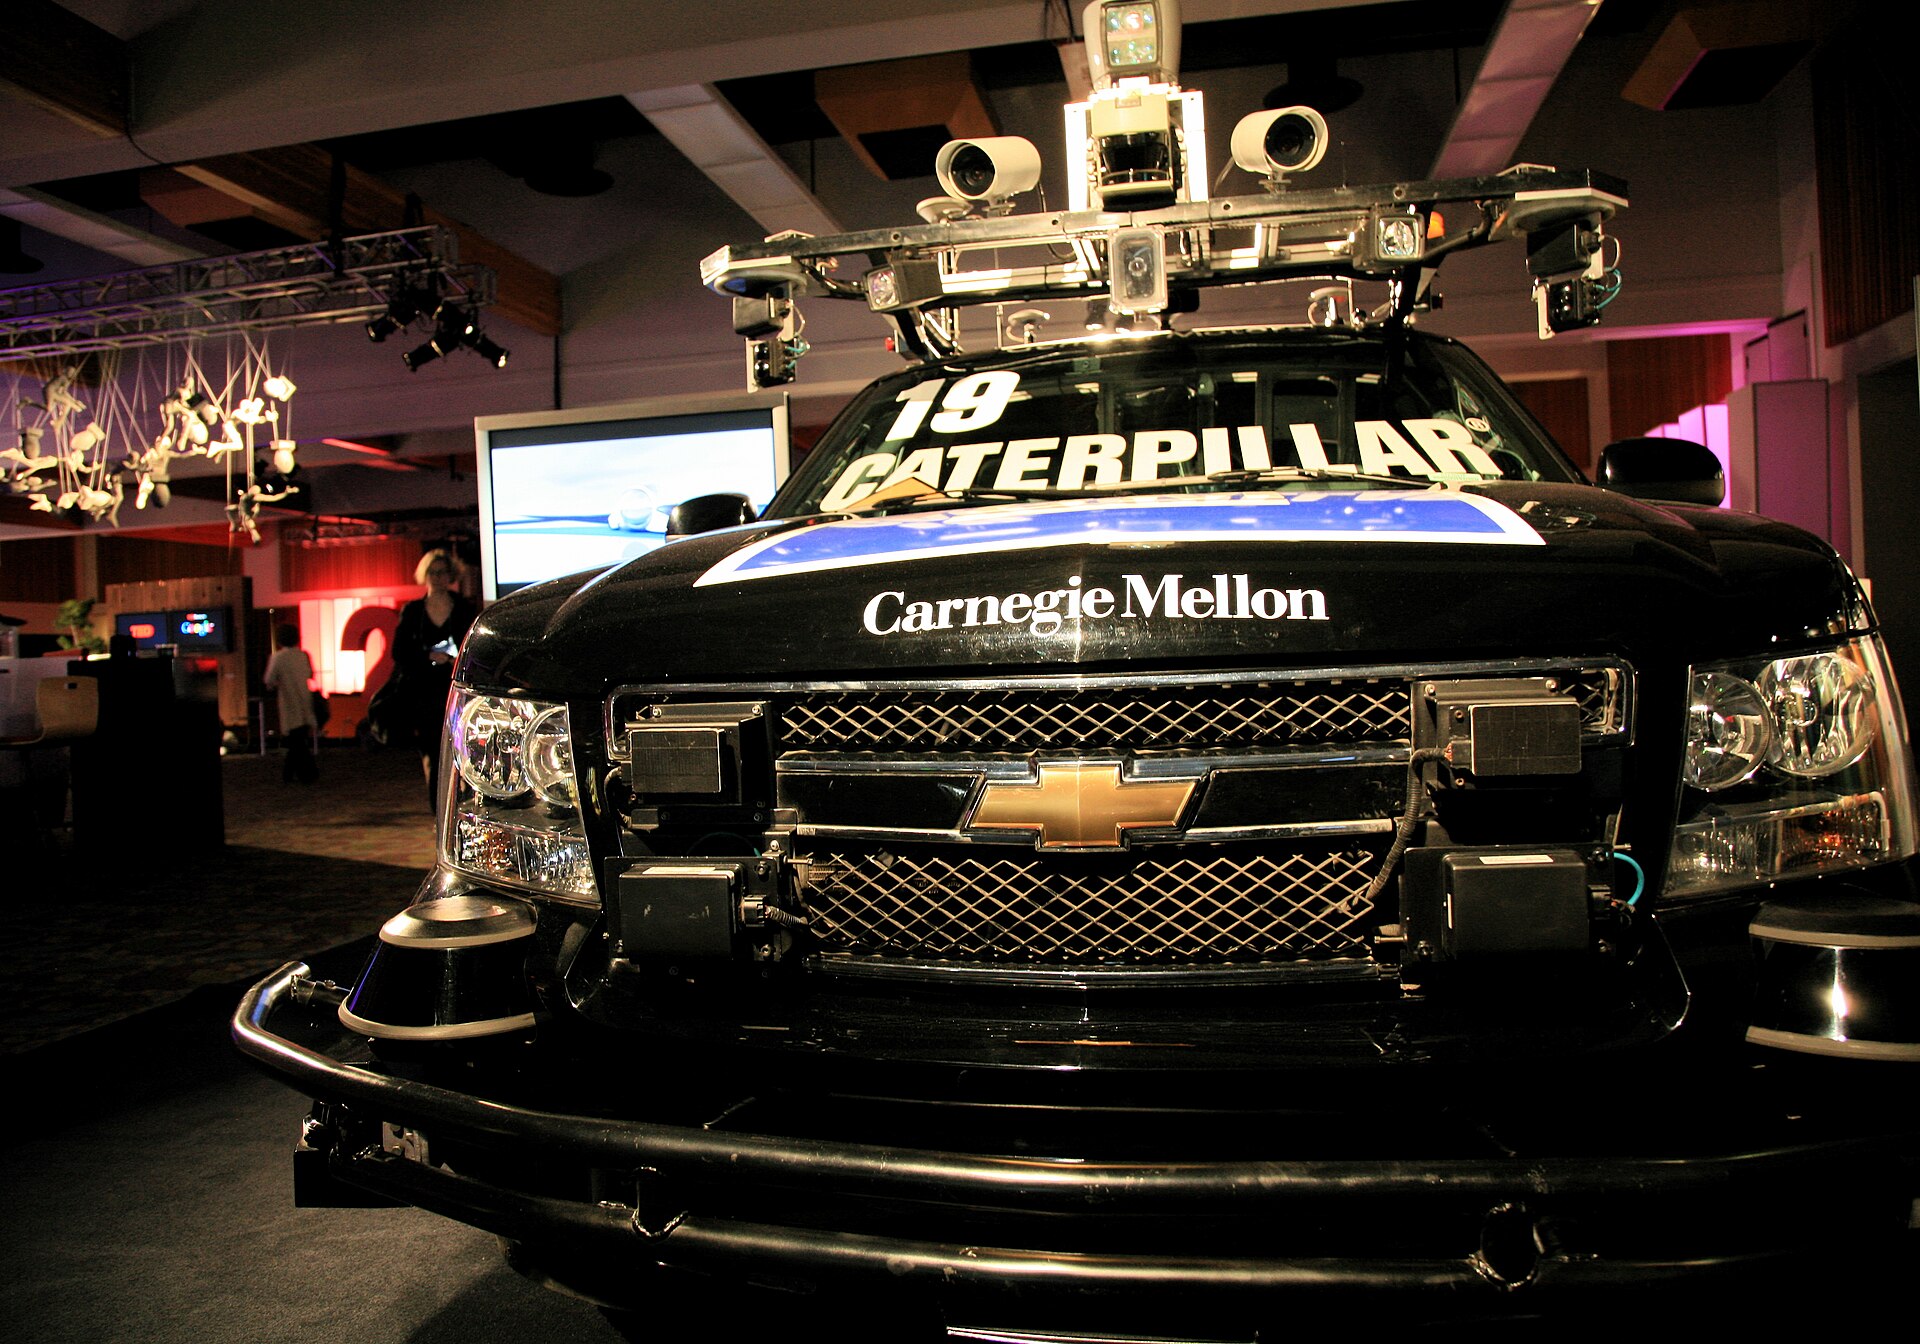
Carnegie Mellon's Boss, winner of the 2007 DARPA Urban Challenge, on display in 2008. Route planning, behaviour decisions and local motion planning, the classical toolbox of its era, remain live production components. Photo: Steve Jurvetson / Wikimedia Commons. Licence: CC BY 2.0.Appears on: Autonomous Vehicles
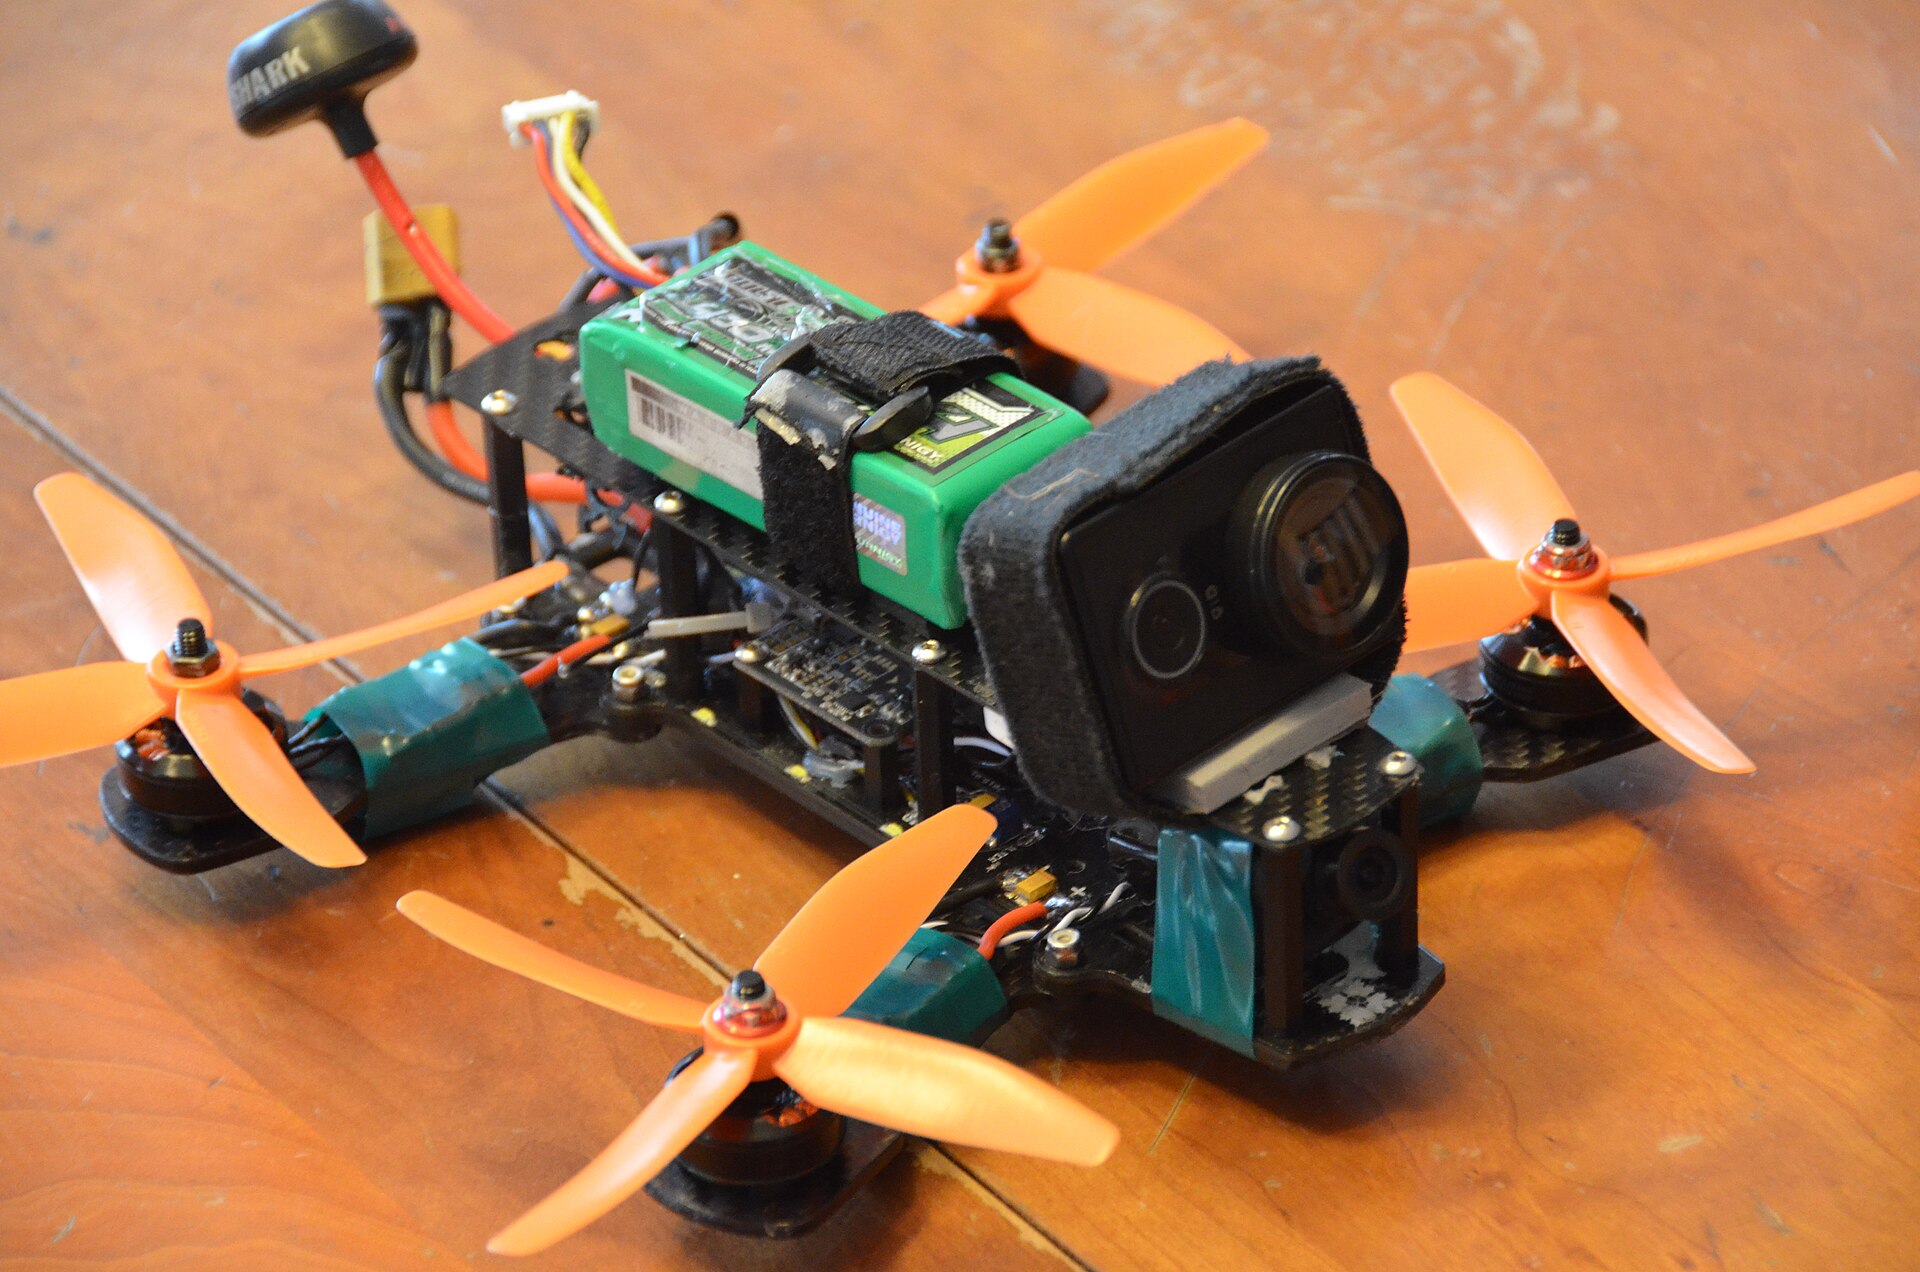
A Minion 220 racing quadrotor with its forward camera, 2016. Machines of this class exceed 100 km/h, and in 2023 a reinforcement-learning system beat three human world champions at racing them. Photo: Commanderbryce / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Drones and Aerial Robotics
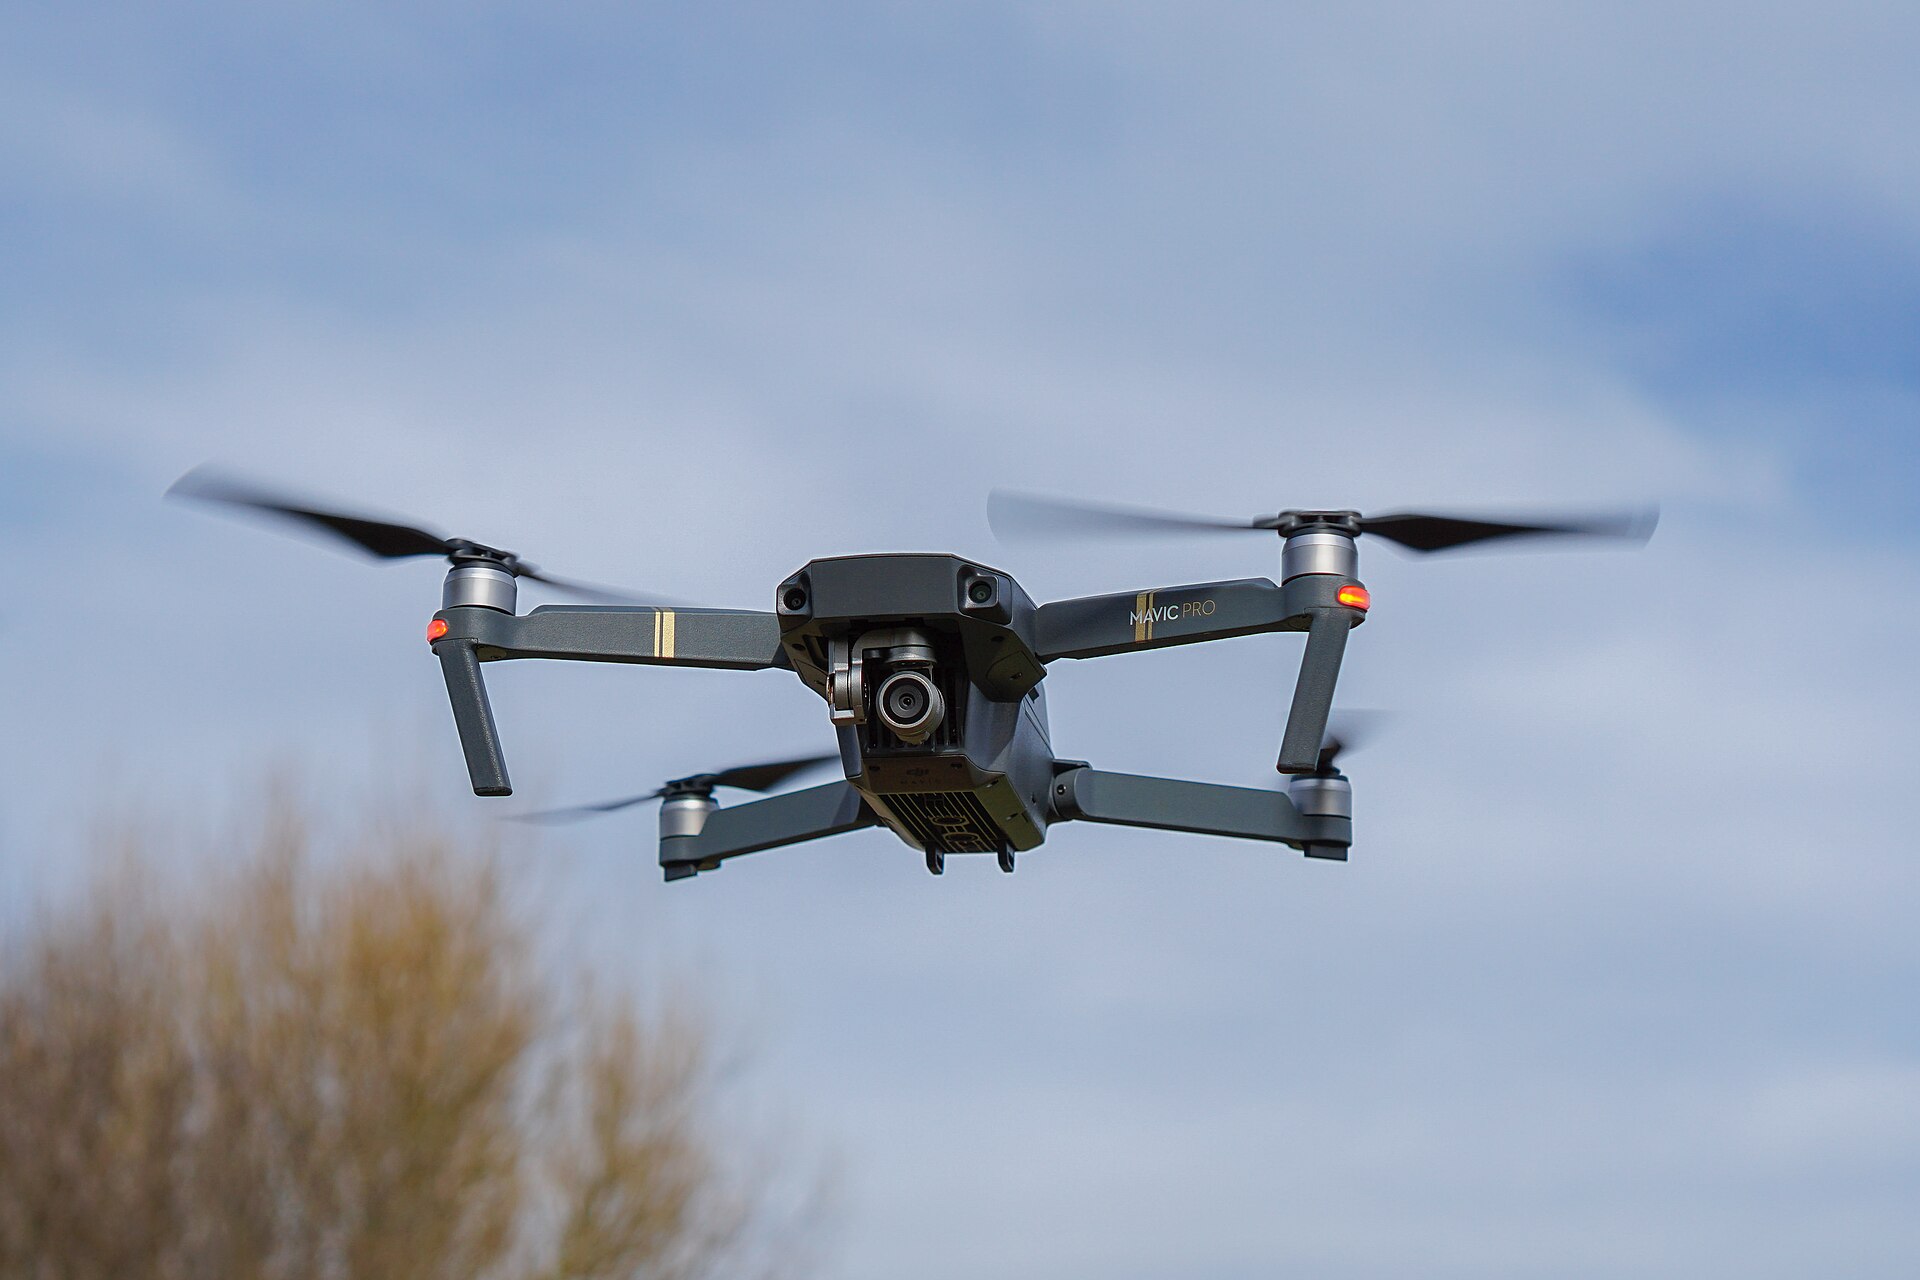
A DJI Mavic Pro in flight, 2017. On an autonomous drone, visual-inertial odometry fuses camera features with inertial measurements into the pose and velocity the controller needs, with no GPS or motion capture. Photo: Sinky / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Drones and Aerial Robotics
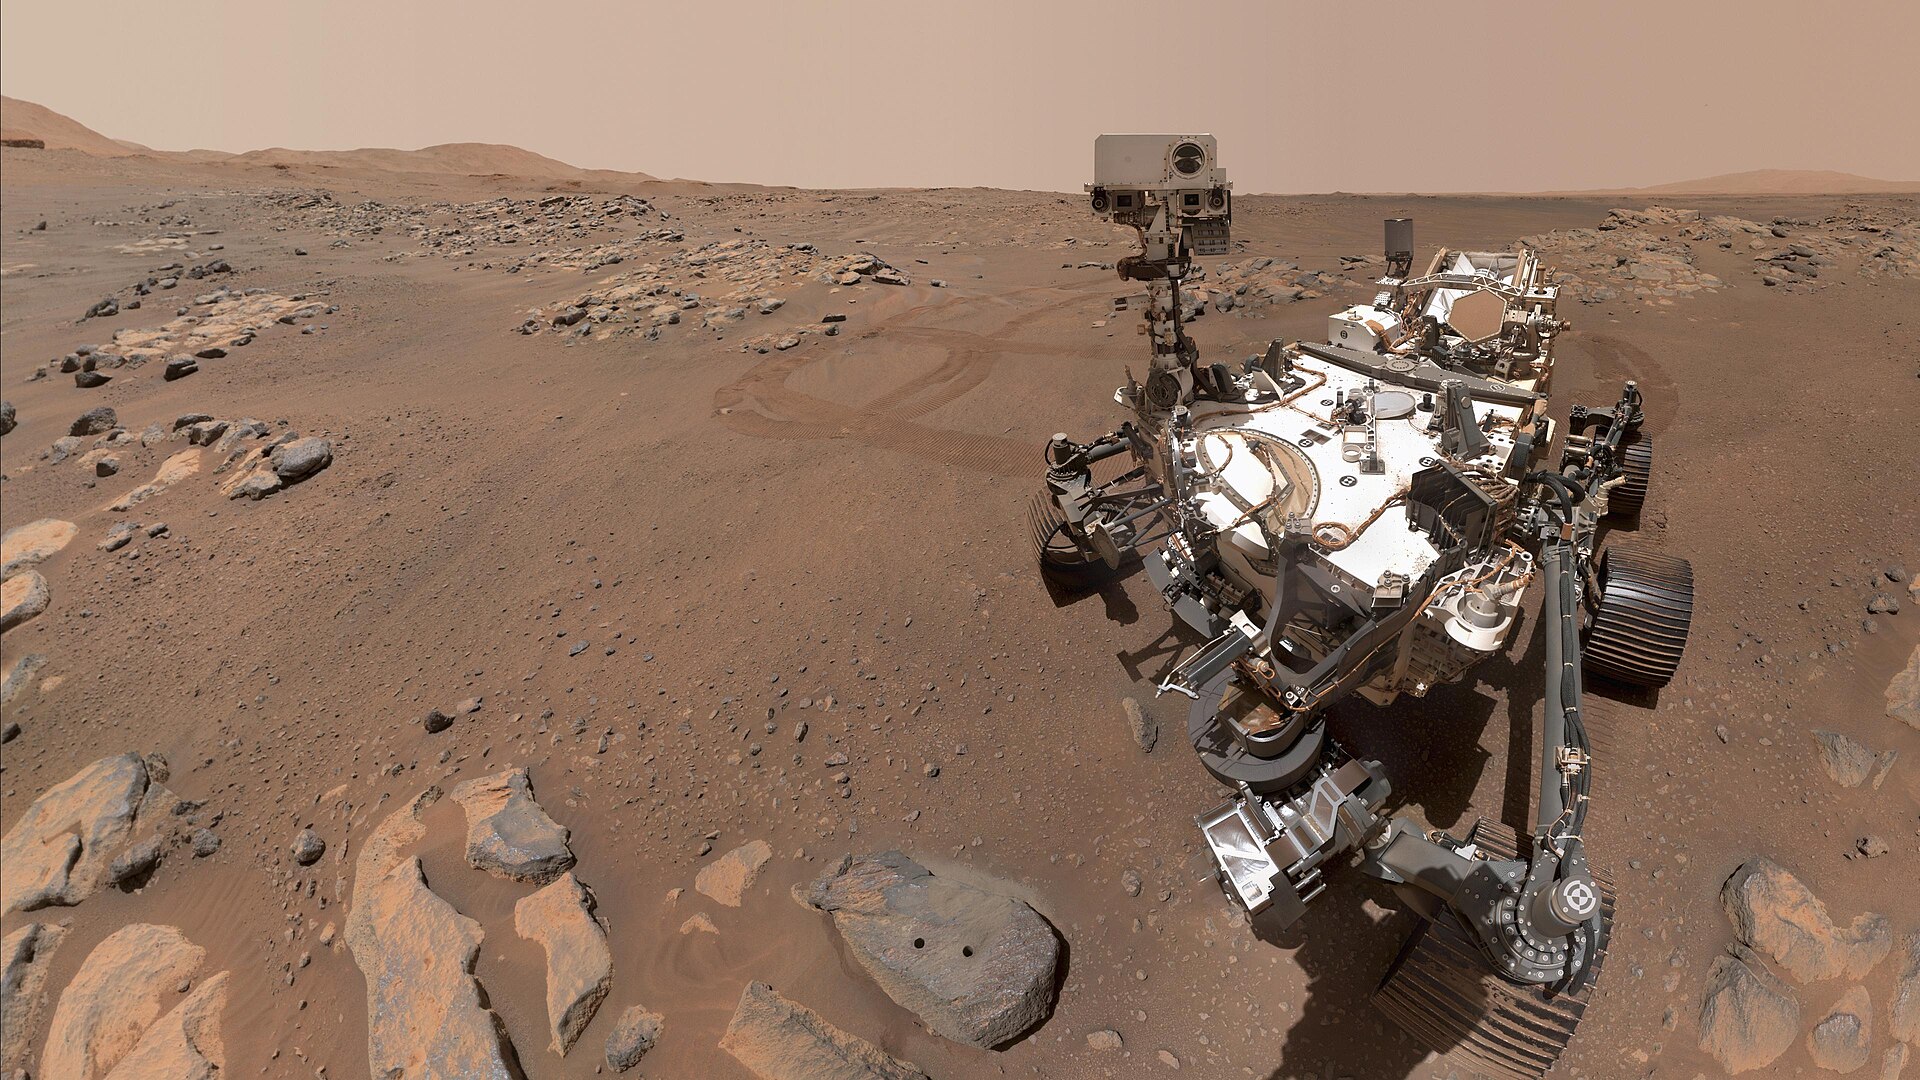
Perseverance beside the rock Rochette on sol 198, September 2021, with two drill holes where its arm took cores. In its first Mars year, its AutoNav system evaluated 88 percent of the 17.7 km the rover drove. Photo: NASA / Wikimedia Commons. Licence: Public domain.Appears on: Space Robotics
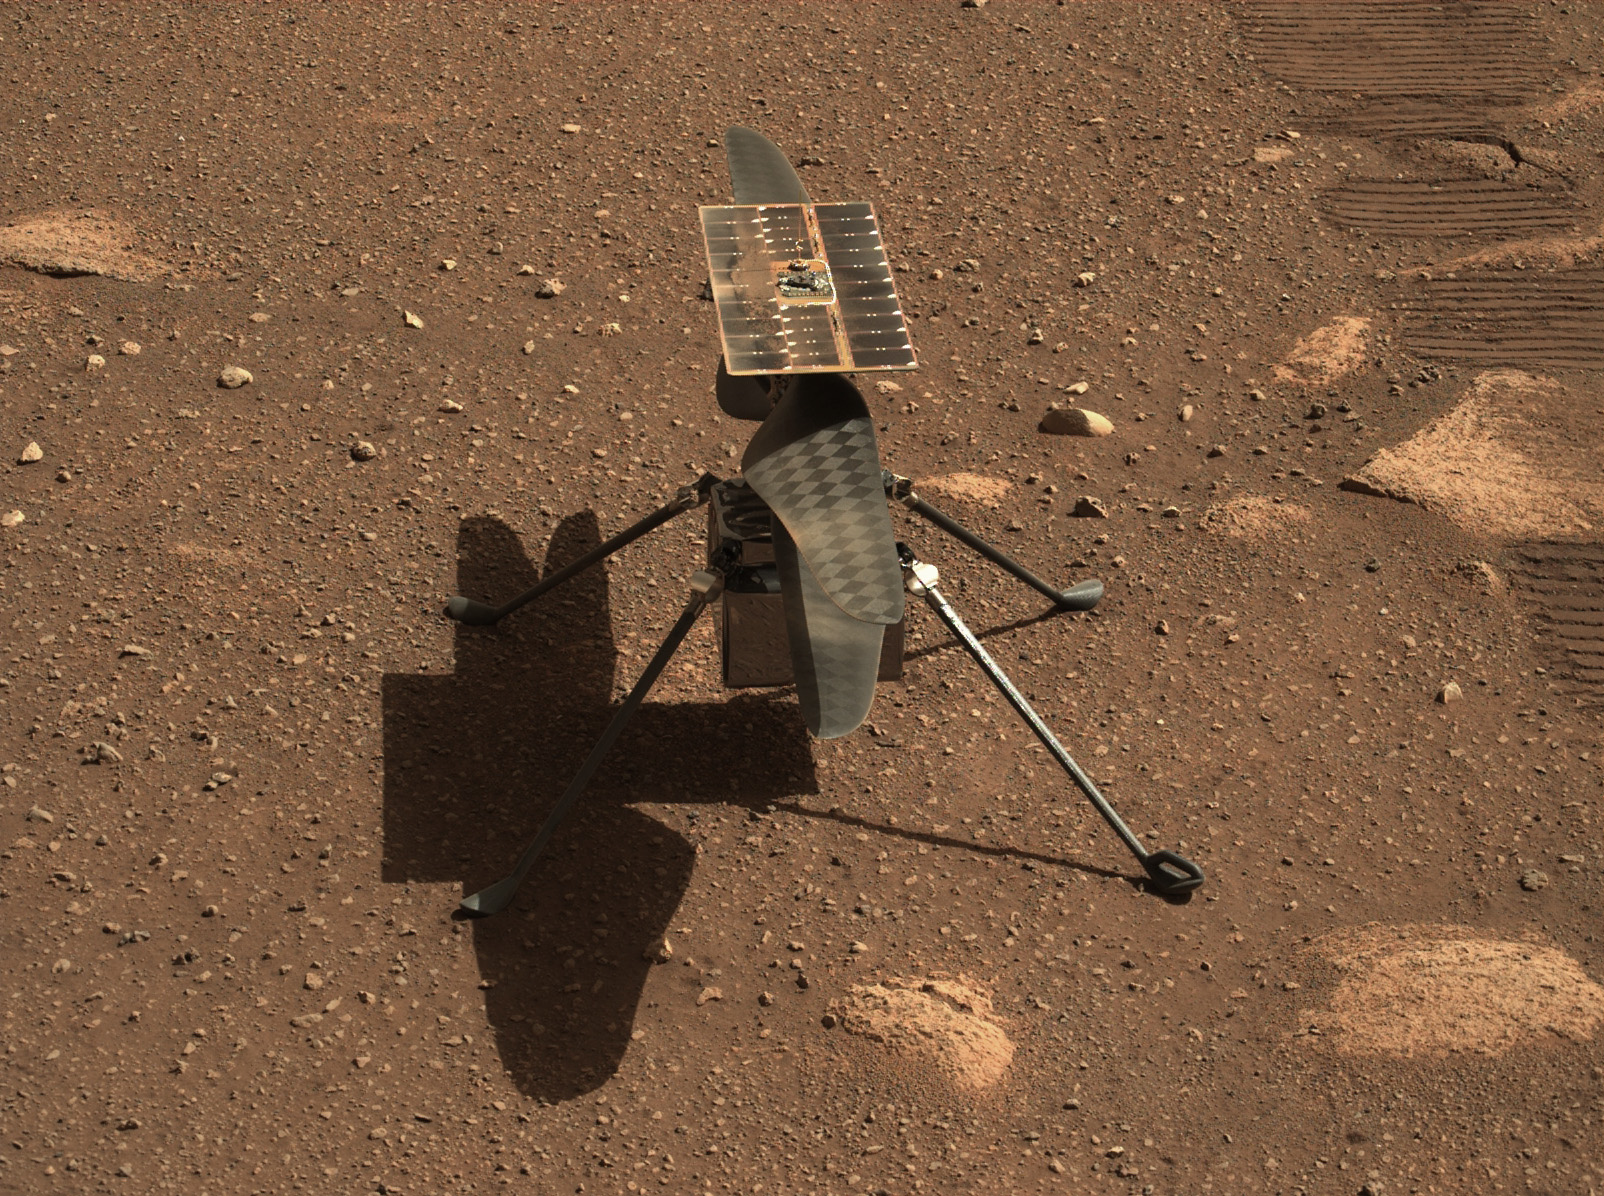
Ingenuity on Mars, photographed by Perseverance on 5 April 2021, two weeks before its first flight. Qualified for five flights in thirty days, it flew 72 times over almost three years. Photo: NASA/JPL-Caltech/ASU/MSSS / Wikimedia Commons. Licence: Public domain.Appears on: Space Robotics
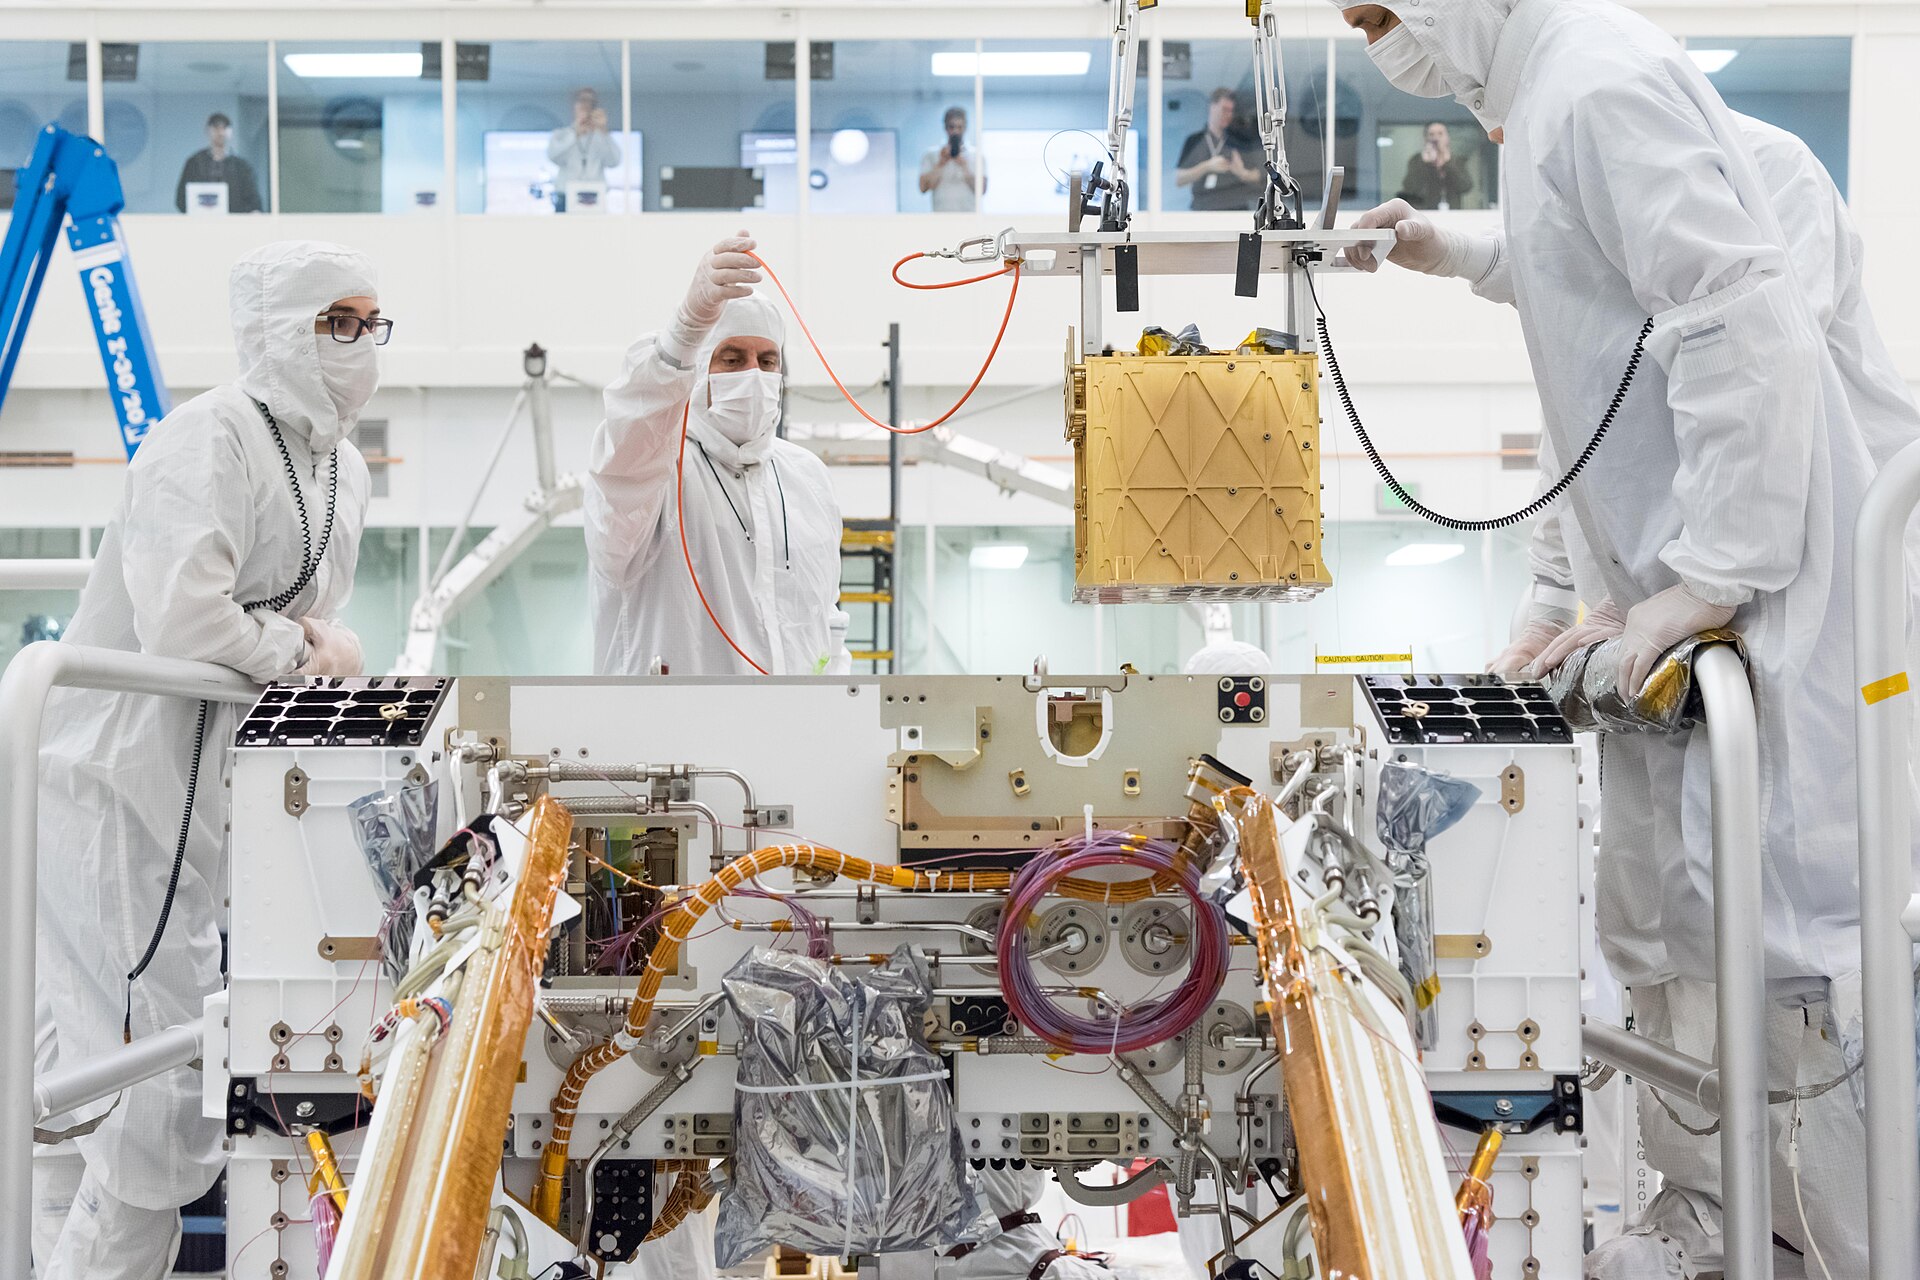
Mars 2020 team members install MOXIE in Perseverance's chassis. On Mars it made 122 grams of oxygen from atmospheric carbon dioxide across sixteen runs, about twice NASA's original production goals. Photo: NASA / Wikimedia Commons. Licence: Public domain.Appears on: Space Robotics
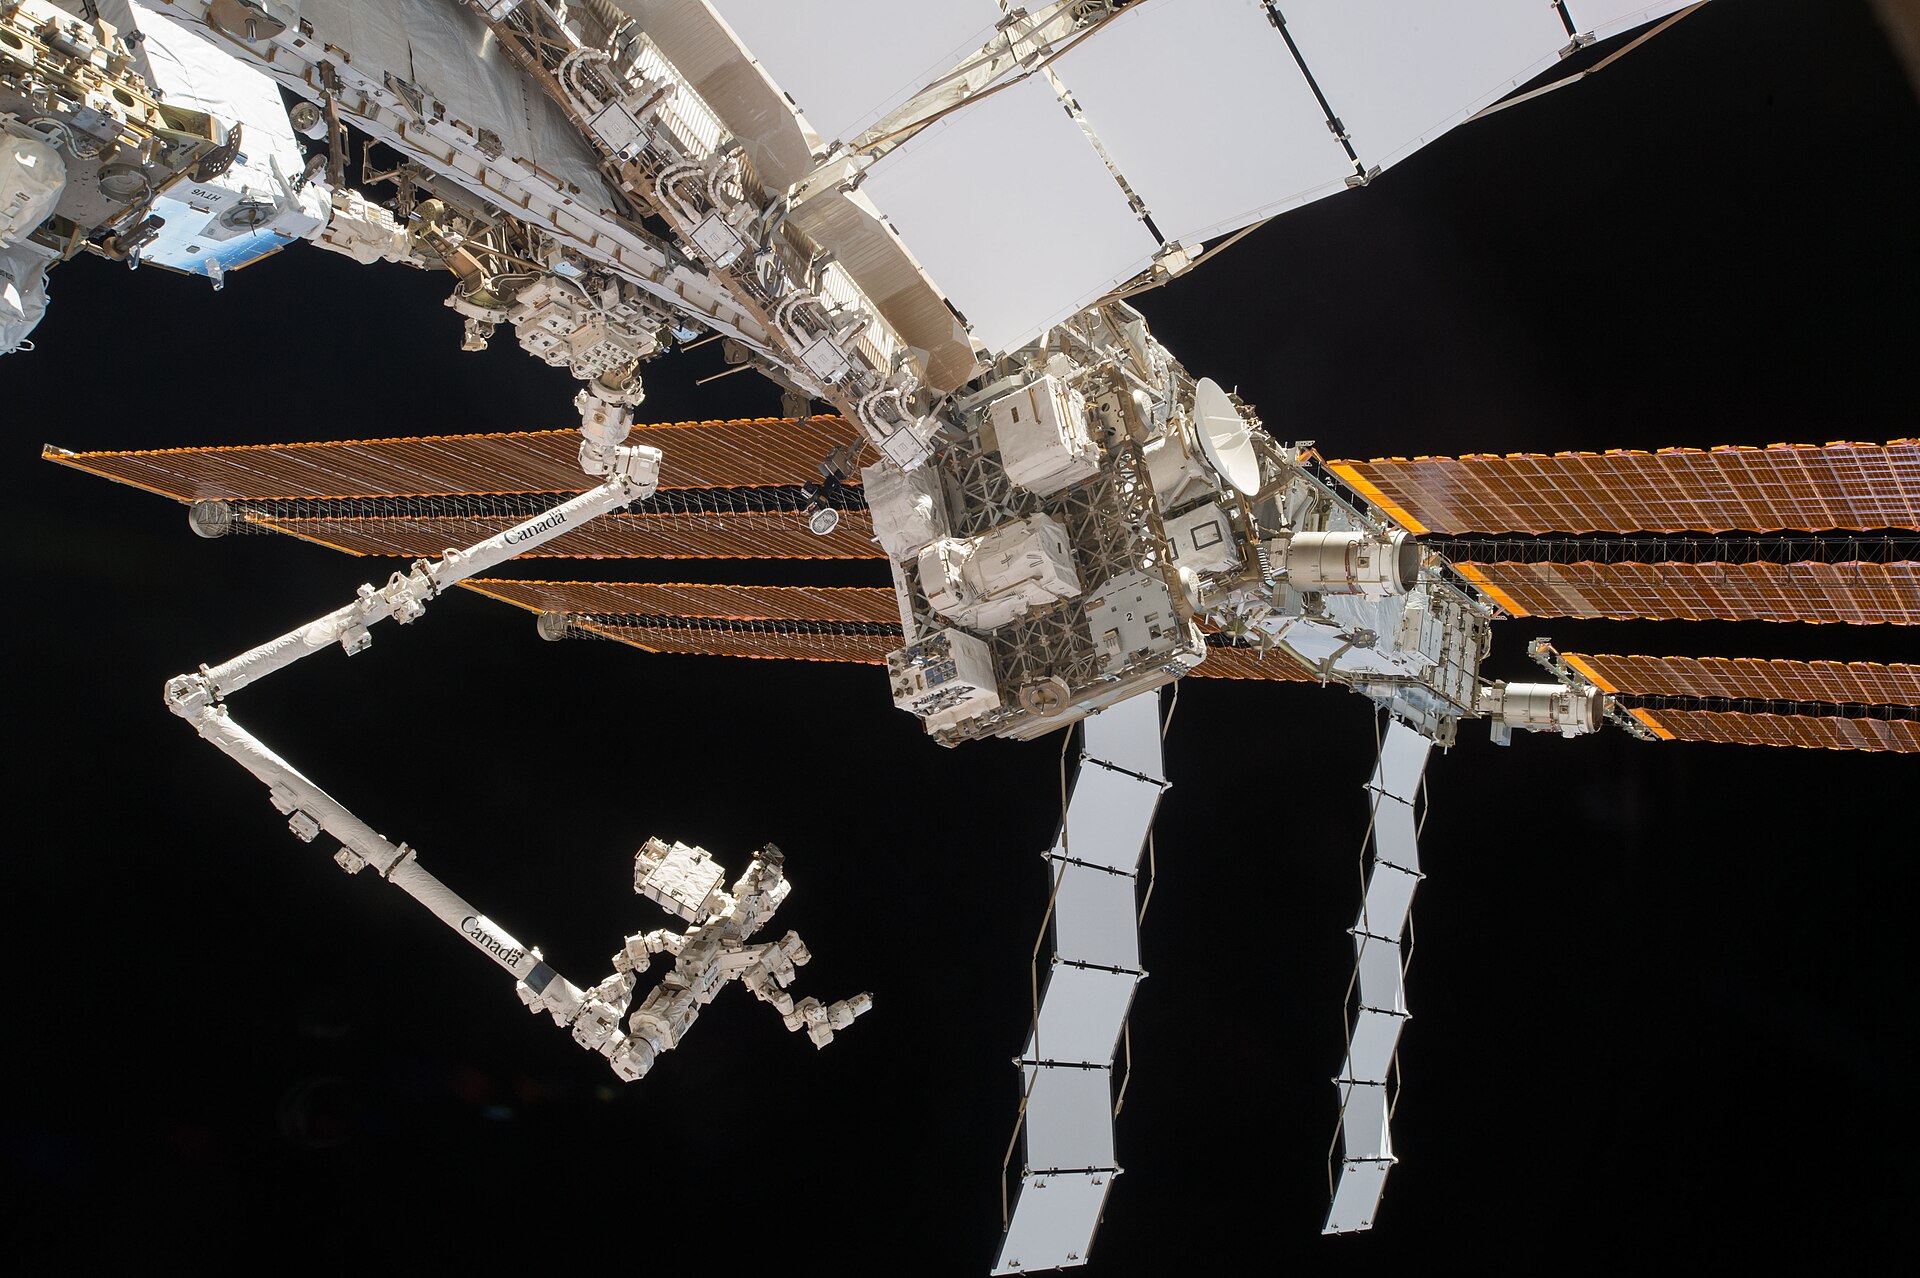
Dextre on the end of Canadarm2 in January 2017, during weeks spent swapping the station's batteries. Ground crews plan and fly every such task by teleoperation. Photo: NASA / Wikimedia Commons. Licence: Public domain.Appears on: Space Robotics
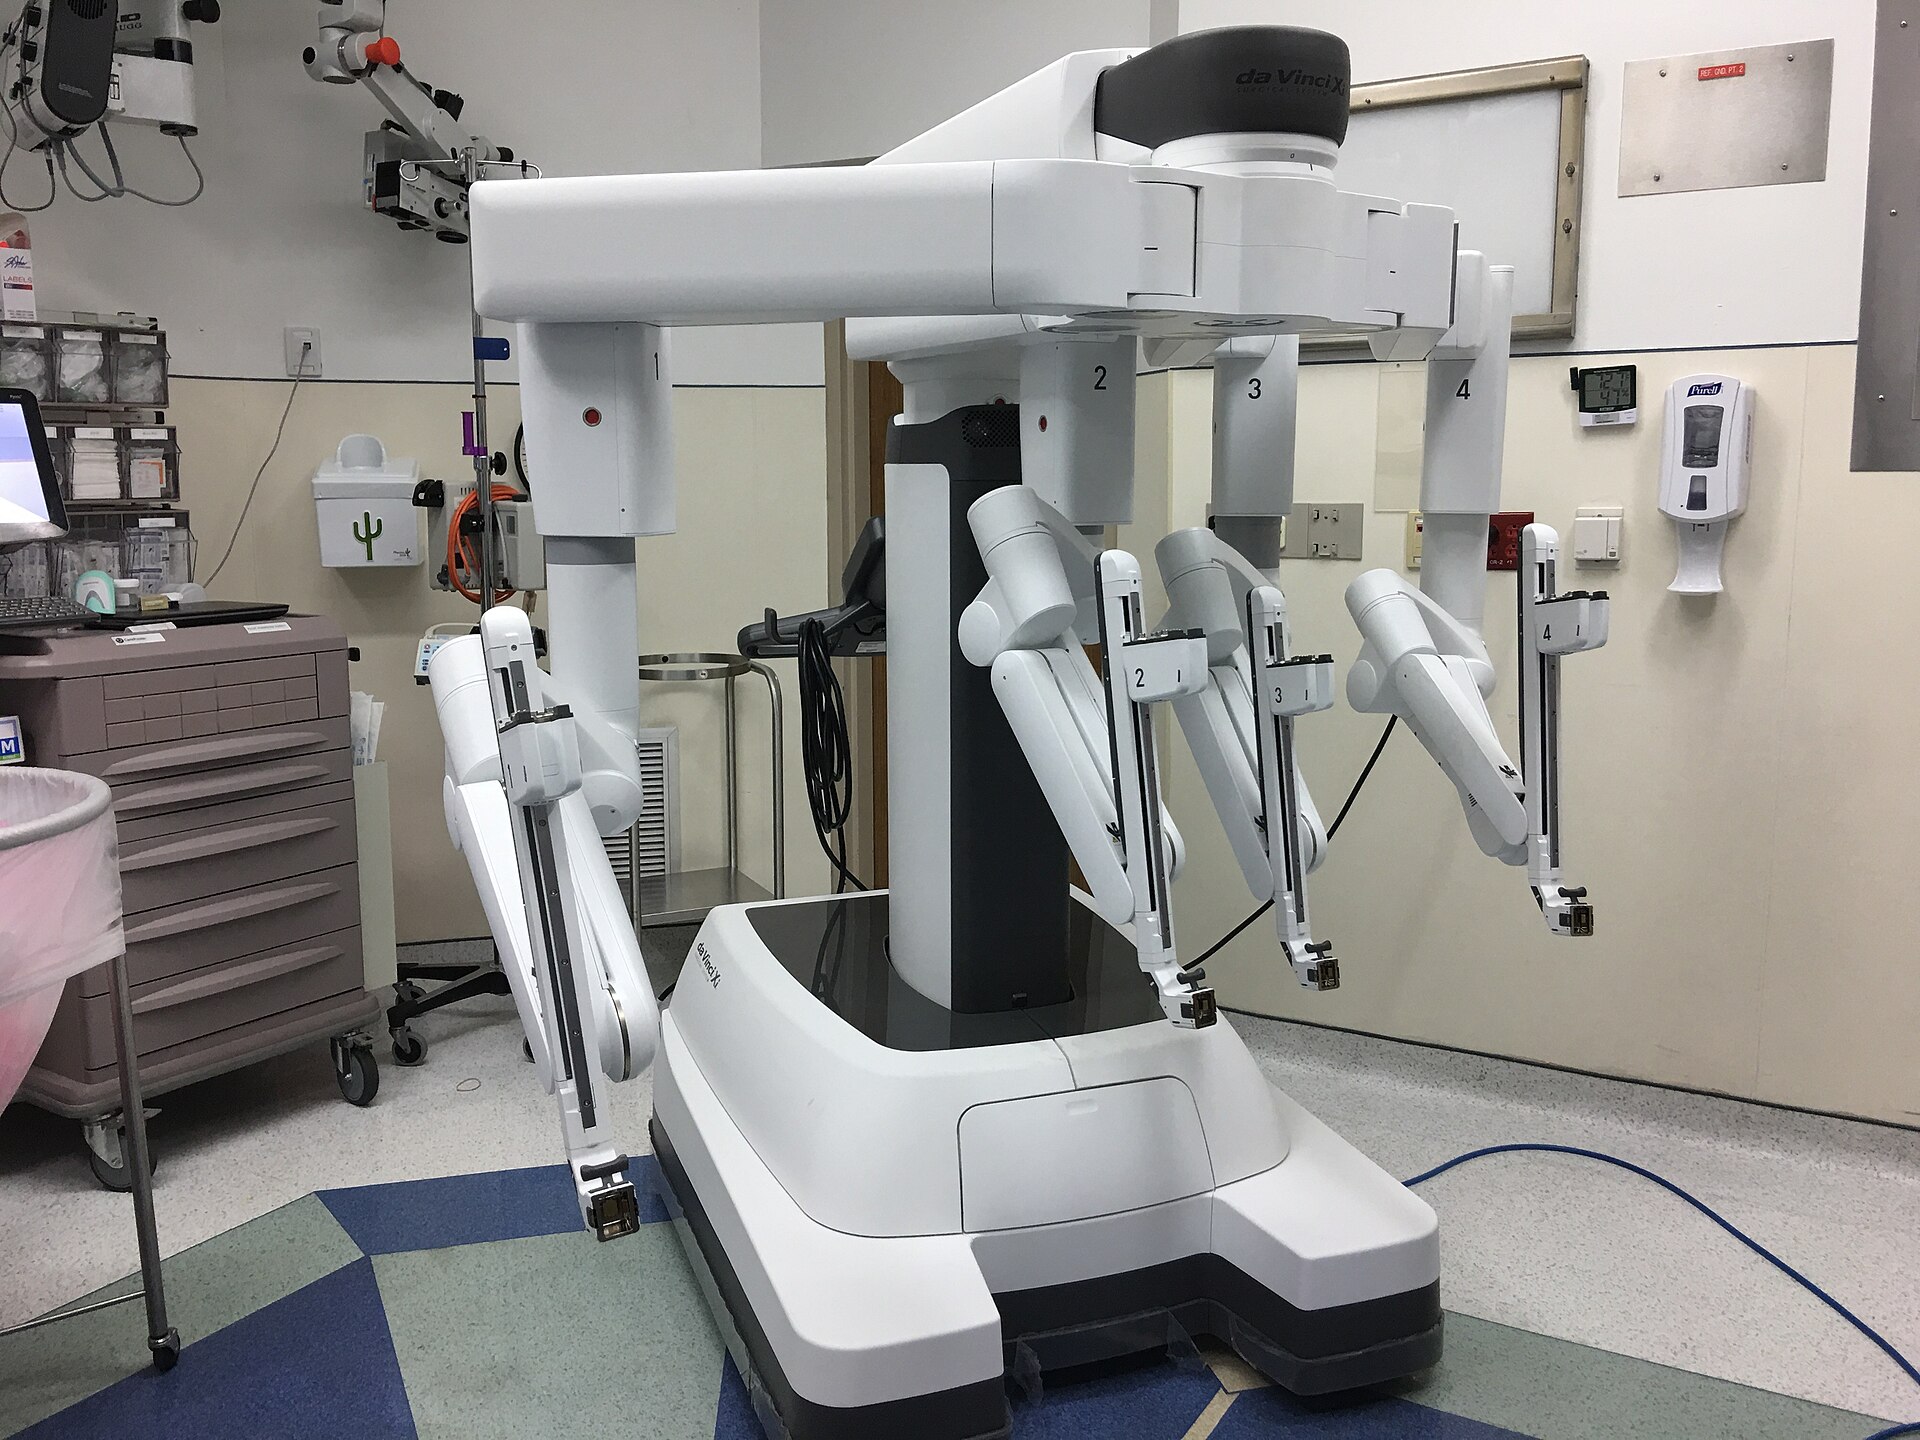
A da Vinci Xi patient-side cart with its four instrument arms, 2018. Every motion its arms make is a surgeon’s command. Photo: Alvarogarciamd / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Surgical Robotics
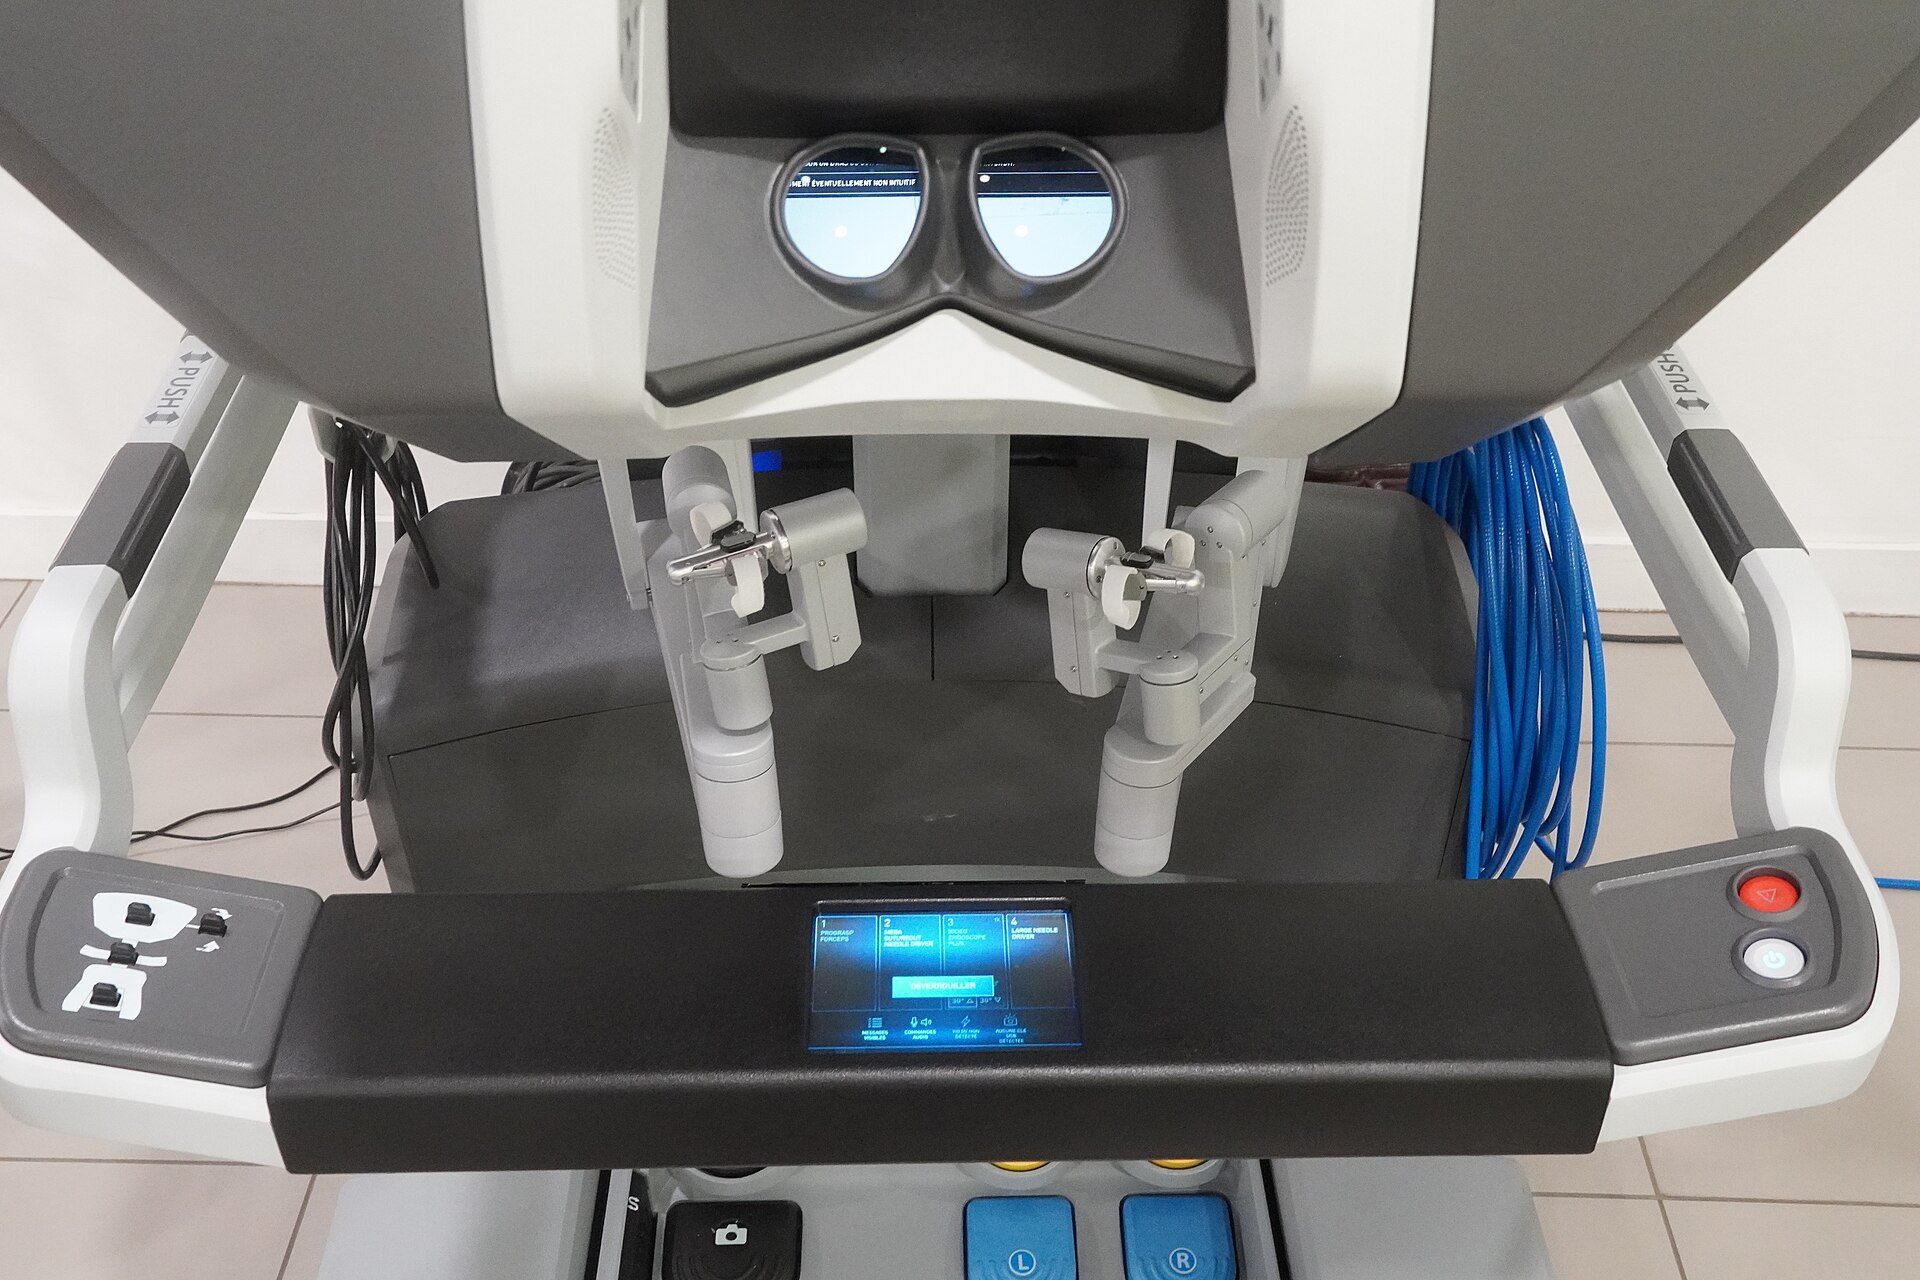
The stereo viewer and hand controllers of a da Vinci Xi surgeon console. Motion scaling and tremor filtering sit between these grips and the instruments, and the surgeon remains planner and controller: Level 0 autonomy. Photo: A.BourgeoisP / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Surgical Robotics
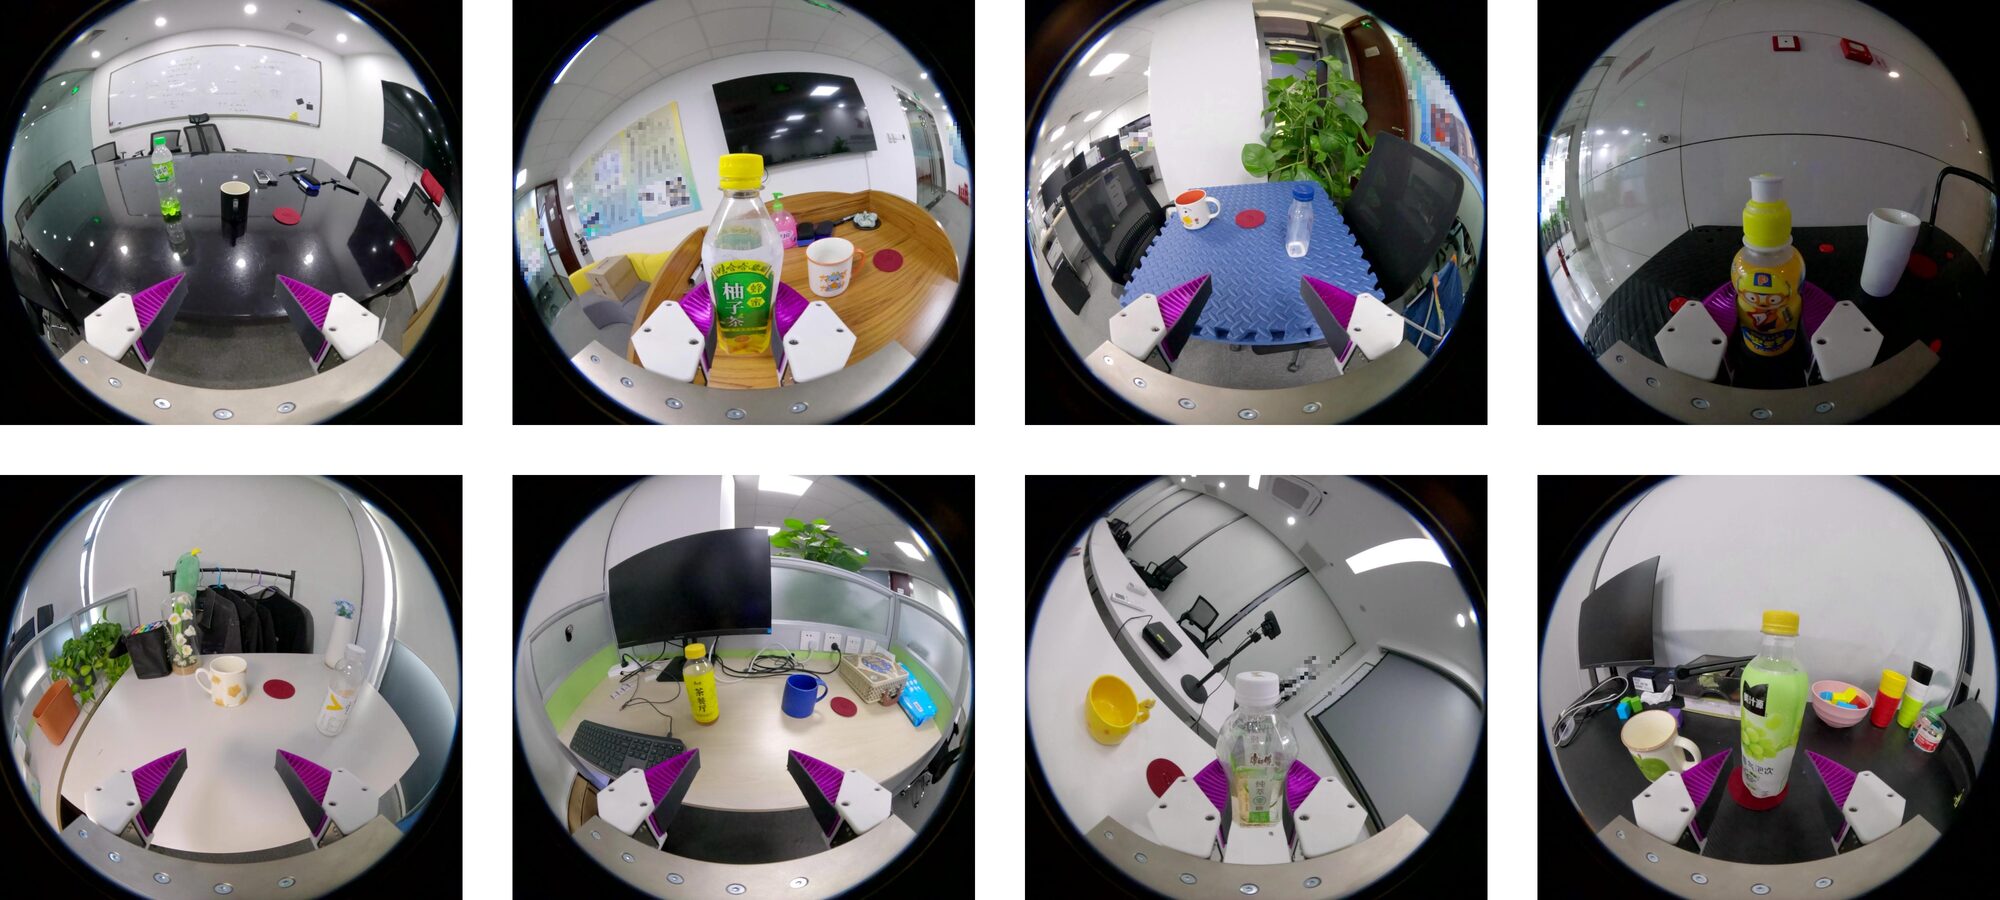
The eight test environments in Lin and colleagues' data-scaling study, seen through the gripper's fisheye camera. None was in the training data, and every task was tested in all eight. Paper figure: Fanqi Lin et al. / arXiv. Licence: CC BY 4.0.Appears on: The Data Bottleneck
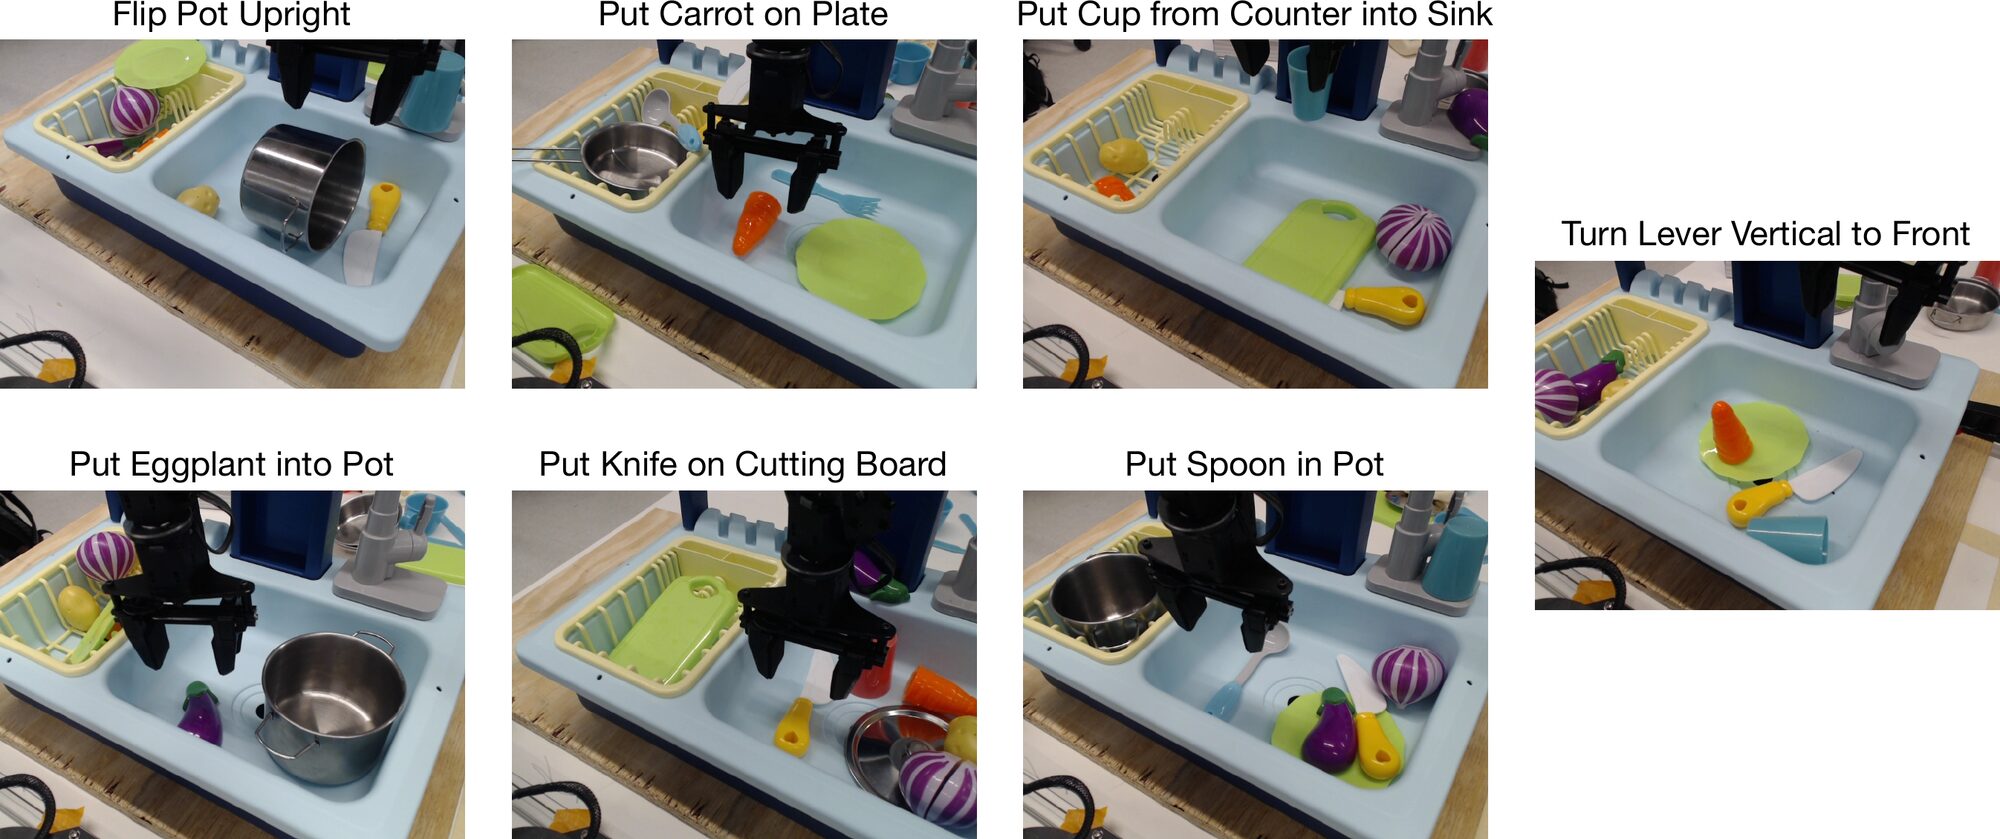
Seven BridgeData V2 tasks in one toy-sink scene, such as putting a carrot on a plate, each recorded on a WidowX 250. Paper figure: Moo Jin Kim et al. / arXiv. Licence: CC BY 4.0.Appears on: Major Datasets
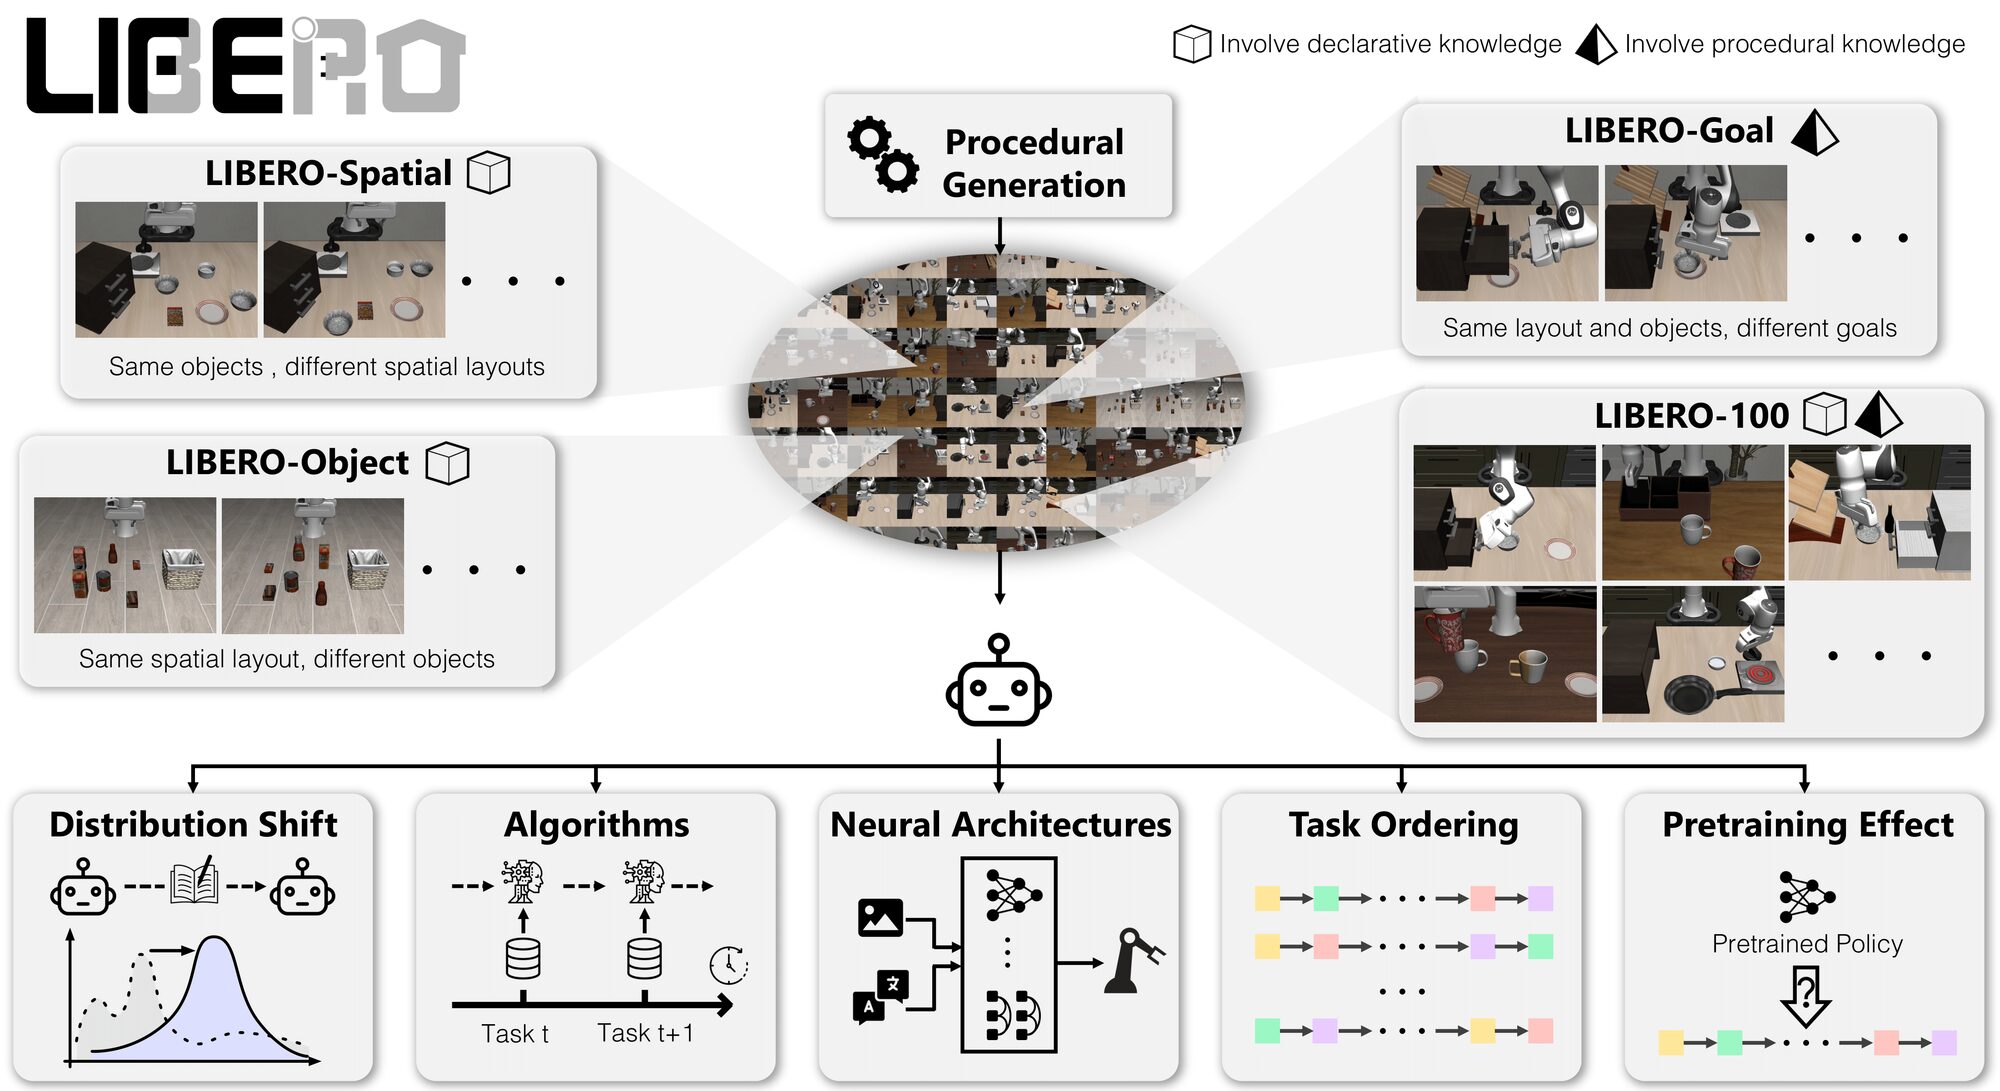
LIBERO's simulated task suites. LIBERO-Spatial changes only the layout, LIBERO-Object only the objects and LIBERO-Goal only the goal, and LIBERO-100 holds 100 more varied tasks. Paper figure: Bo Liu et al. / arXiv. Licence: CC BY 4.0.Appears on: The Evaluation Crisis
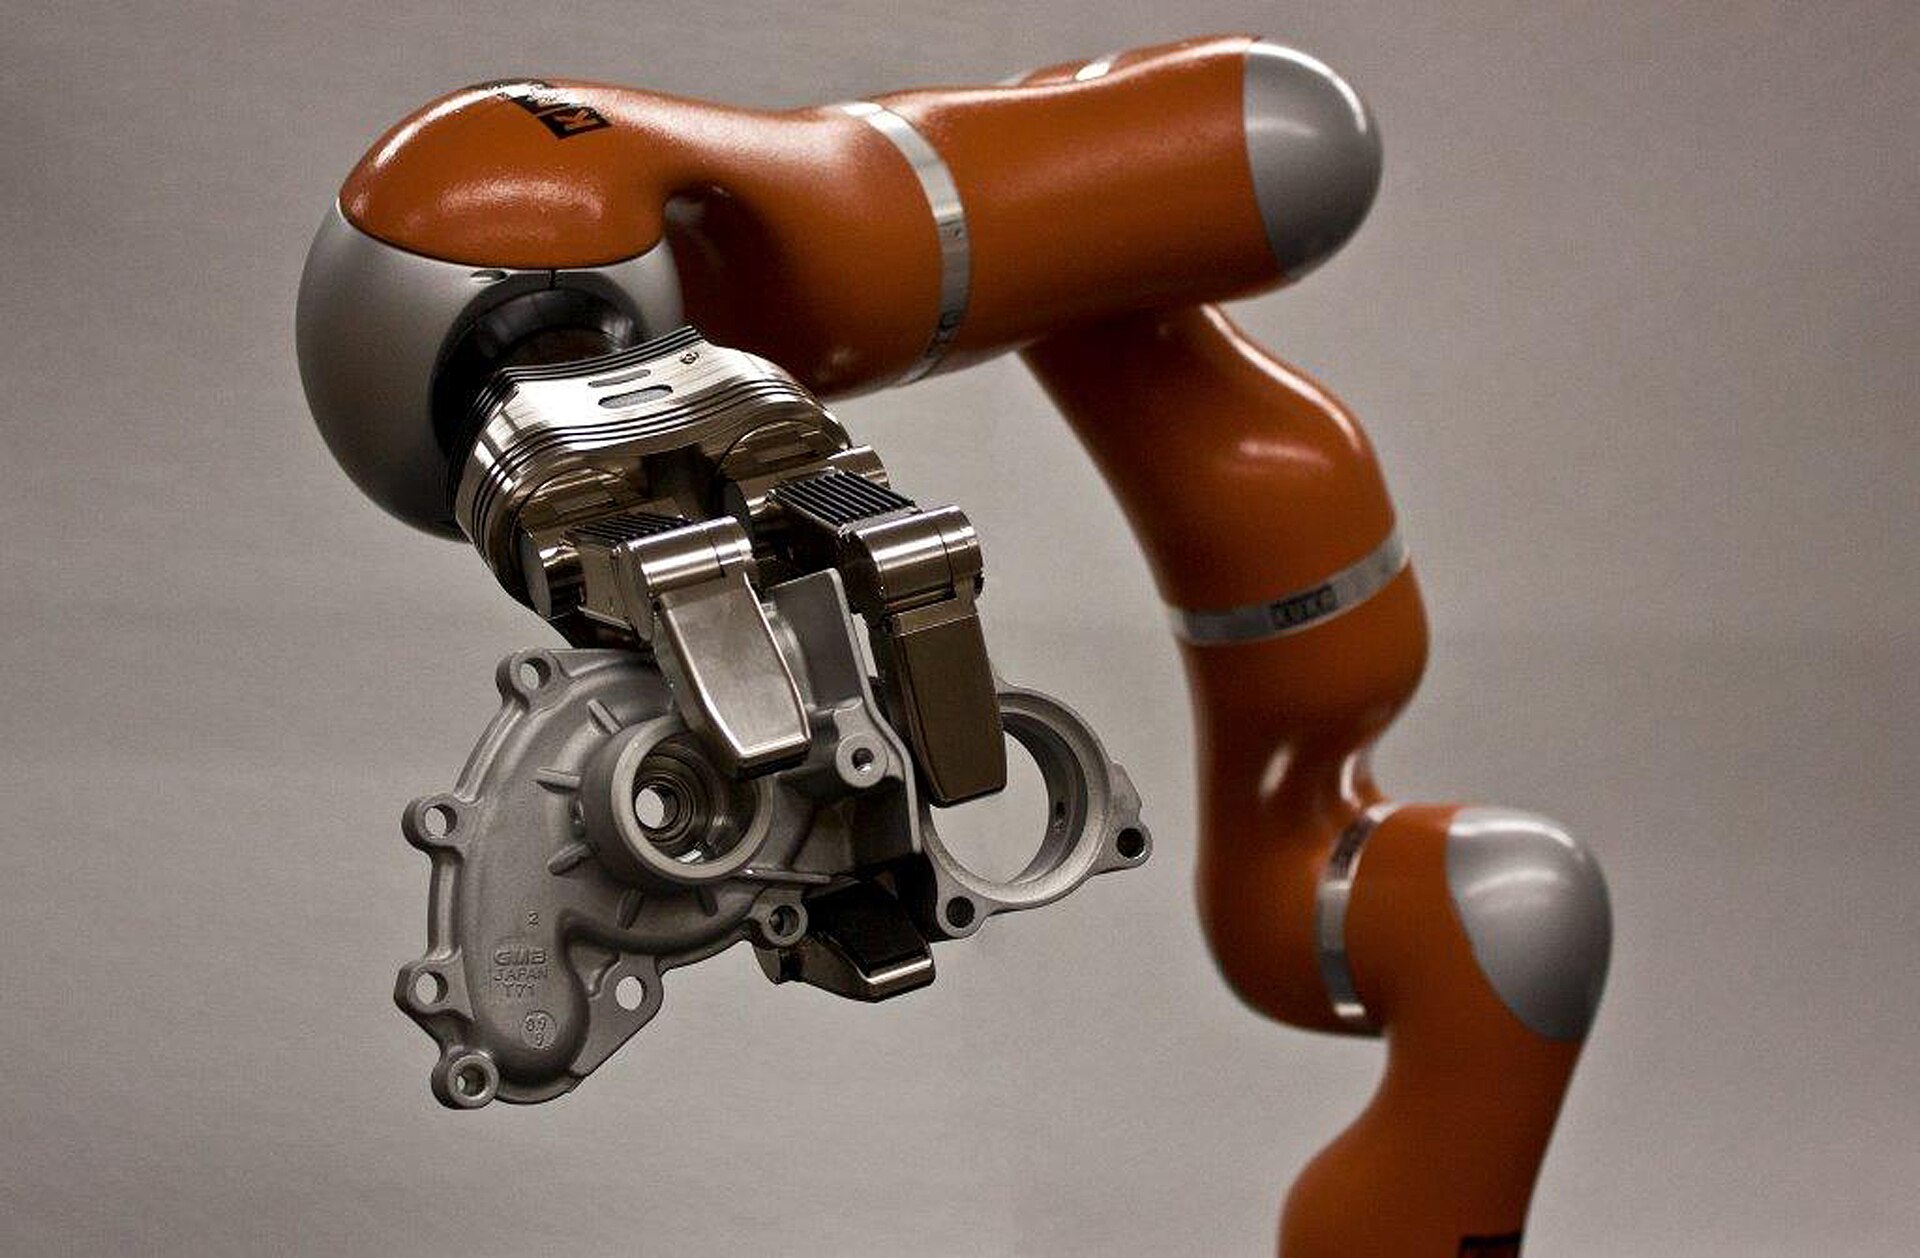
A seven-DoF arm and a three-fingered hand on NIST's Dexterous Manipulation Testbed in 2013, used to measure manipulation for manufacturing tasks. Photo: National Institute of Standards and Technology / Wikimedia Commons. Licence: Public domain.Appears on: Hardware Taxonomy
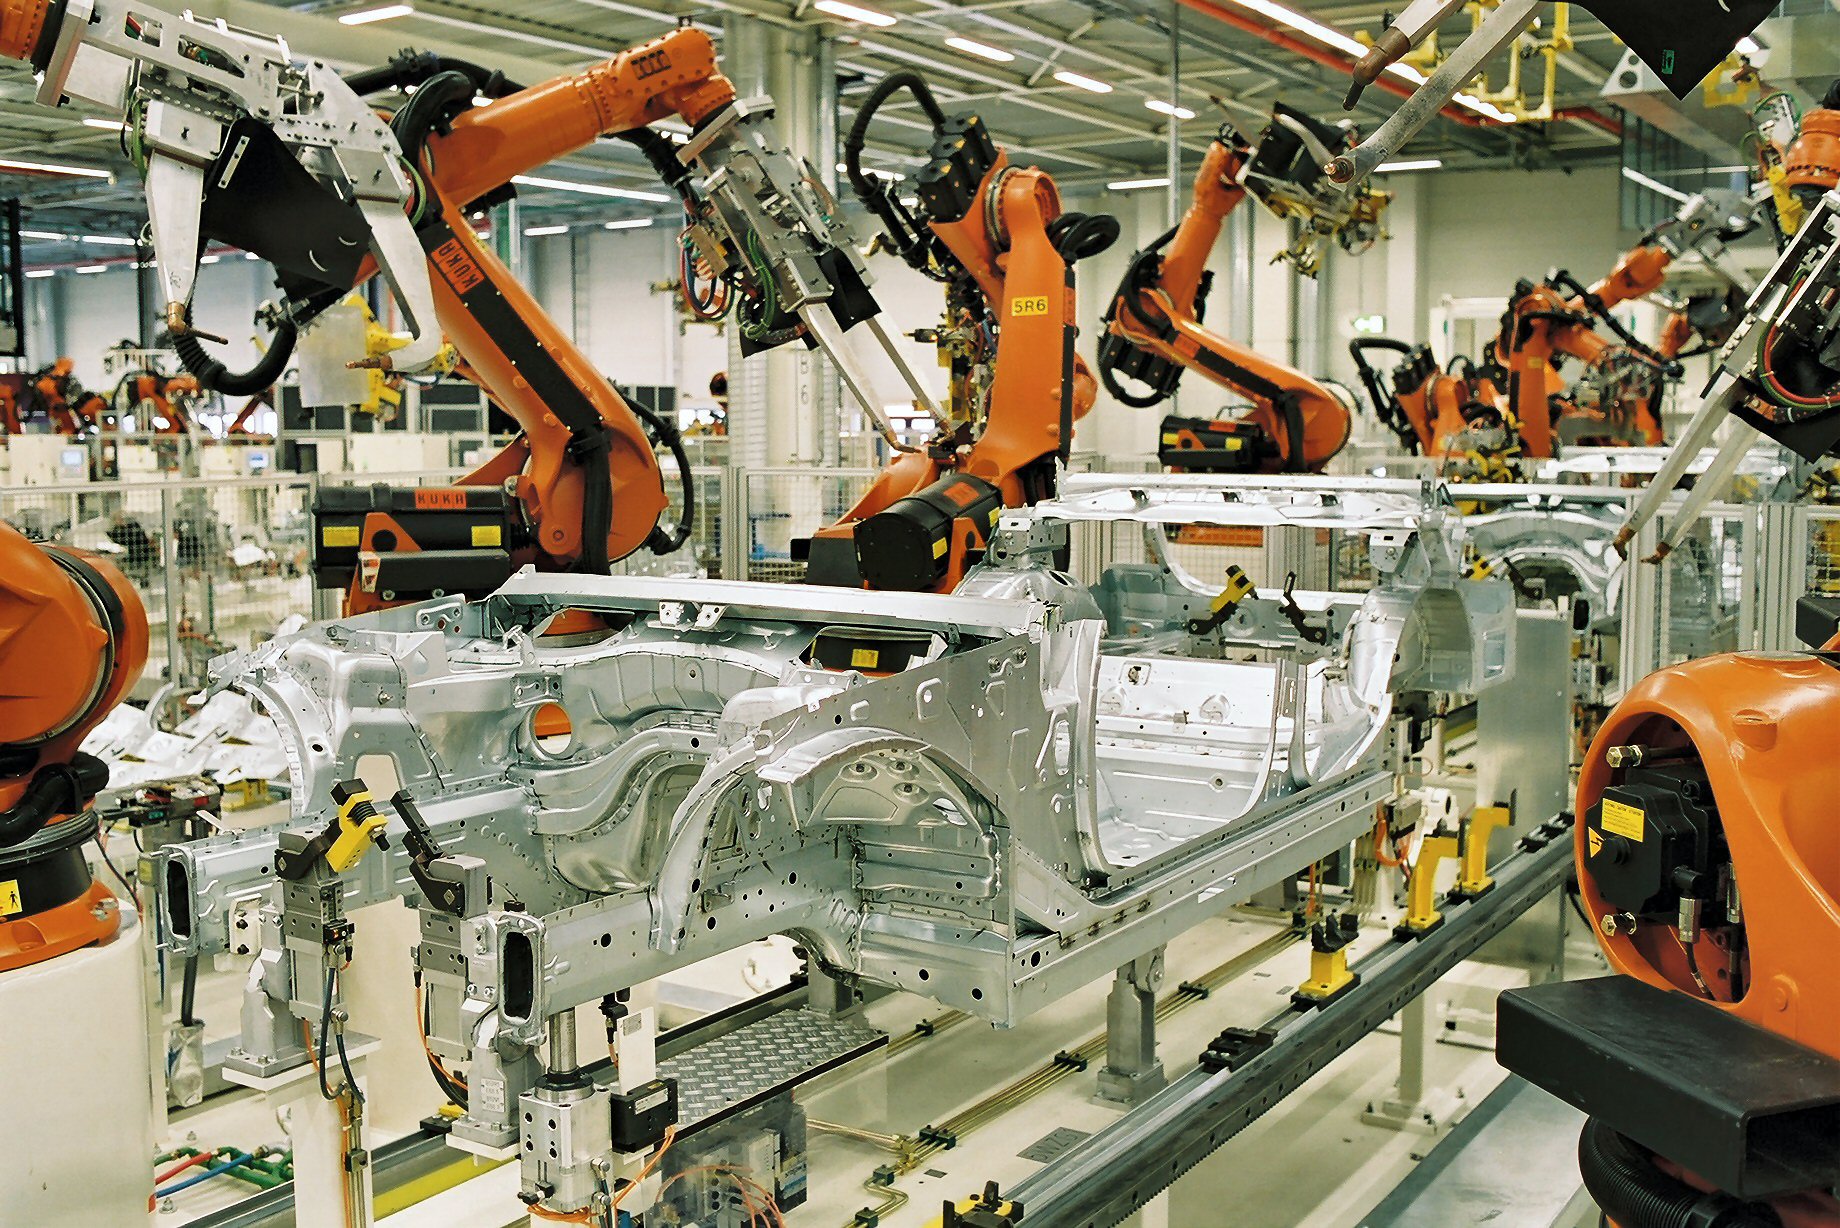
KUKA robots spot-welding BMW 3 Series bodies at the Leipzig plant in 2005. Fixed cells repeating one motion like this make up most of the installed base. Photo: BMW Werk Leipzig / Wikimedia Commons. Licence: CC BY-SA 2.0.Appears on: Industrial Deployment
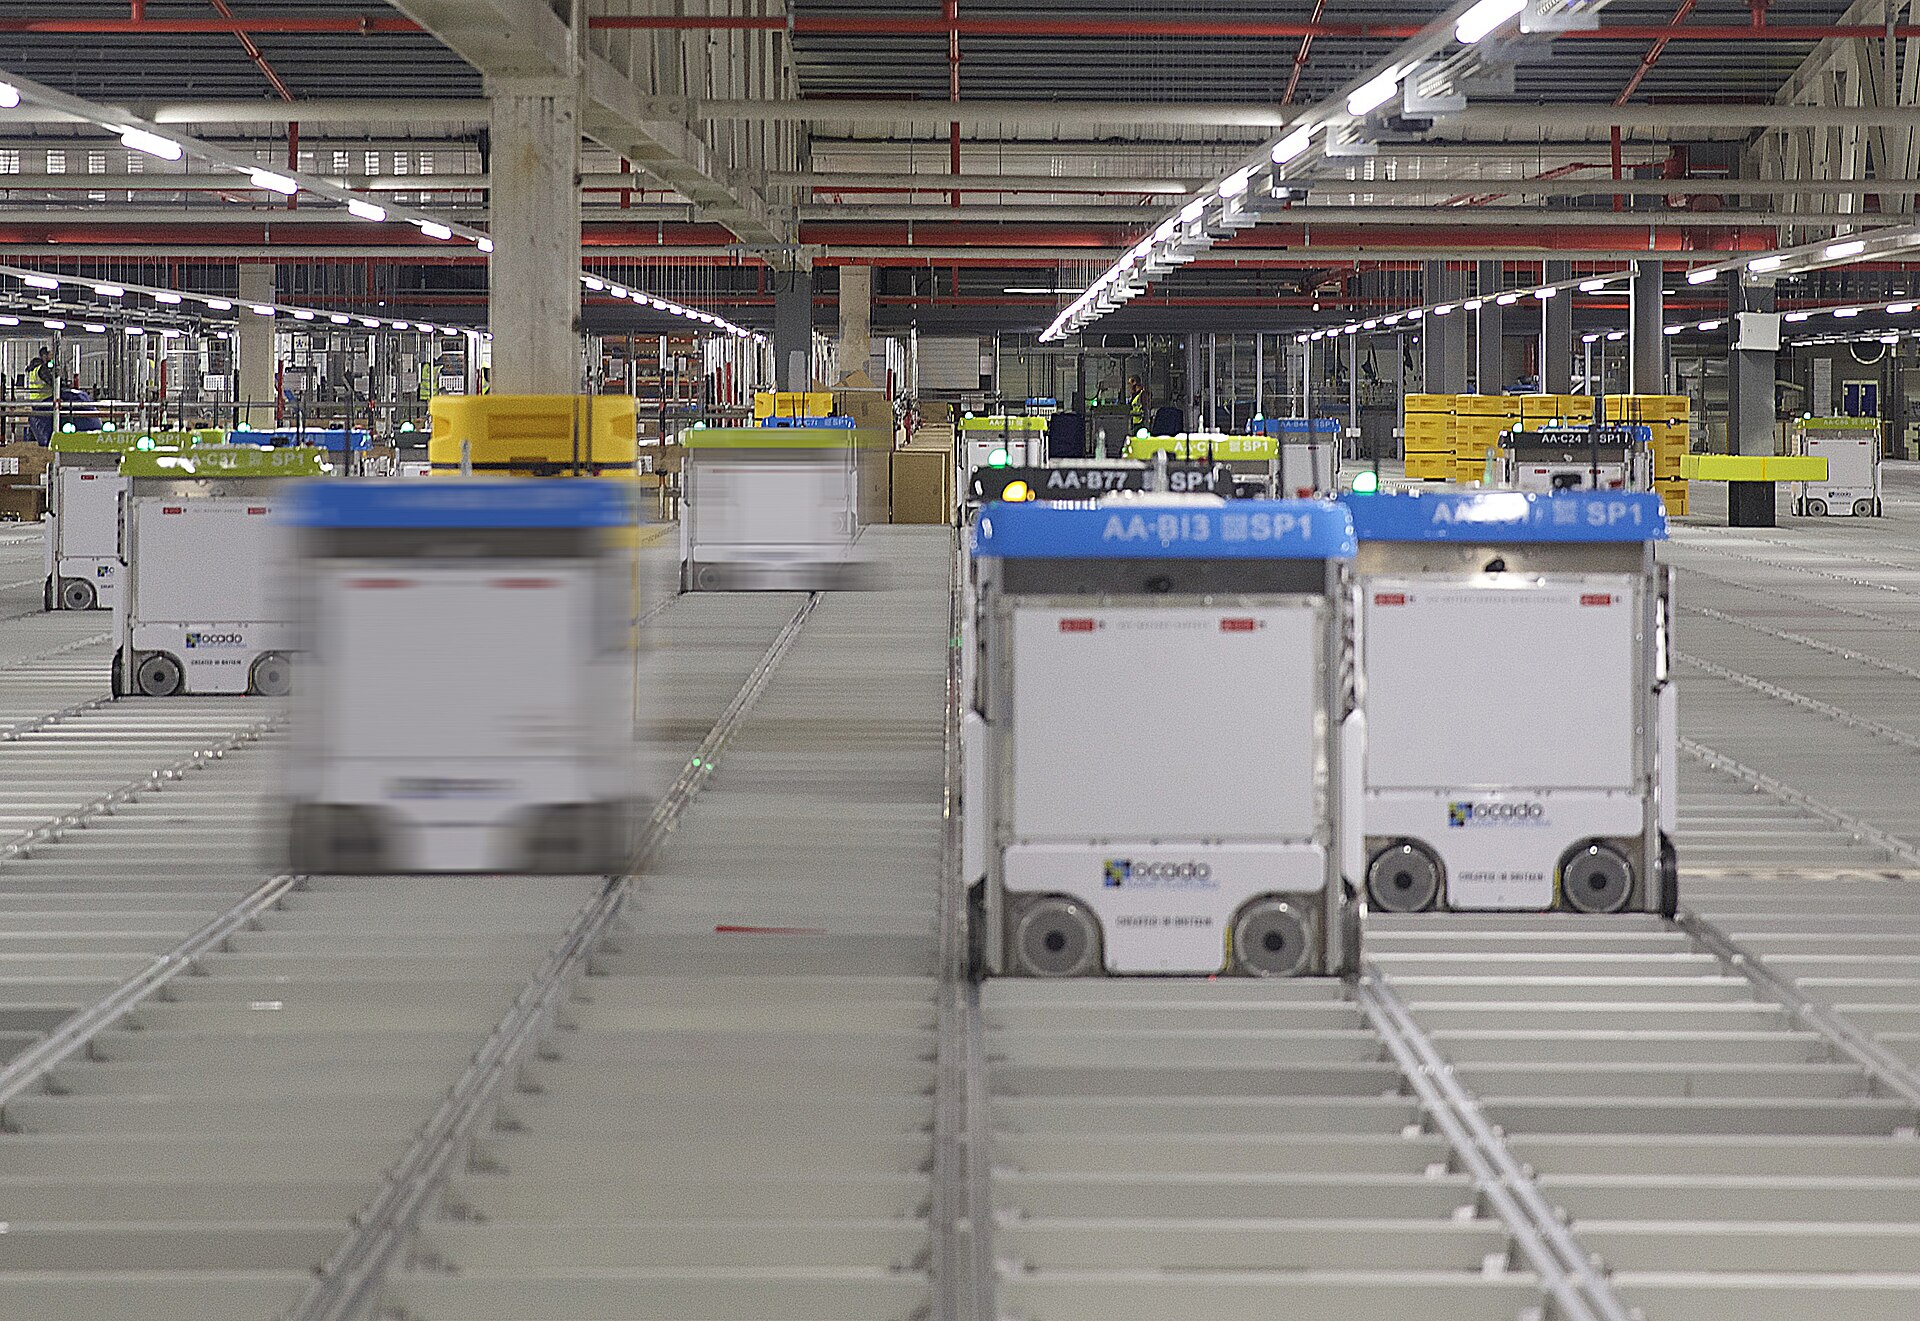
Bots on the storage grid of an Ocado warehouse in 2017. They run on top of the grid and fetch bins from the stacks inside it. Photo: Techwords / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Industrial Deployment
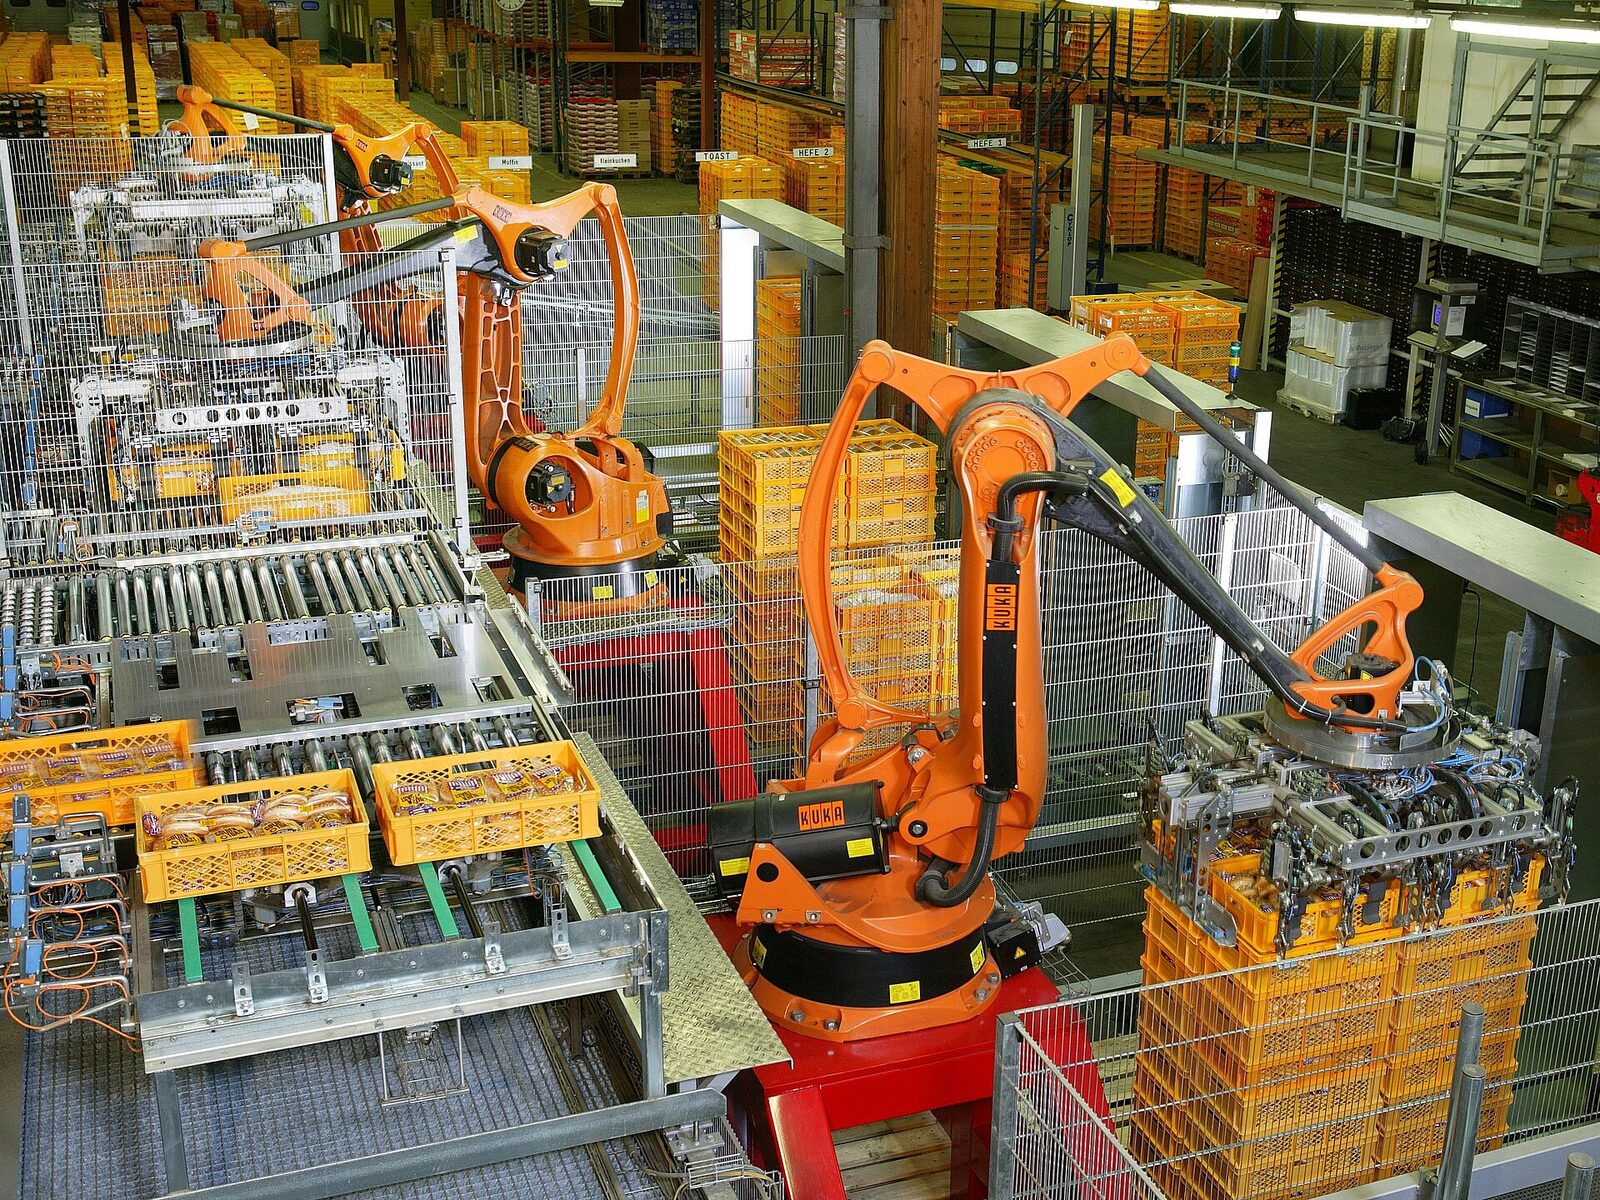
KUKA robots palletising bread crates at a German bakery in 2005. The grippers, conveyors and safety fence around them are part of the cell's cost. Photo: KUKA Roboter GmbH / Wikimedia Commons. Licence: Public domain.Appears on: Industrial Deployment
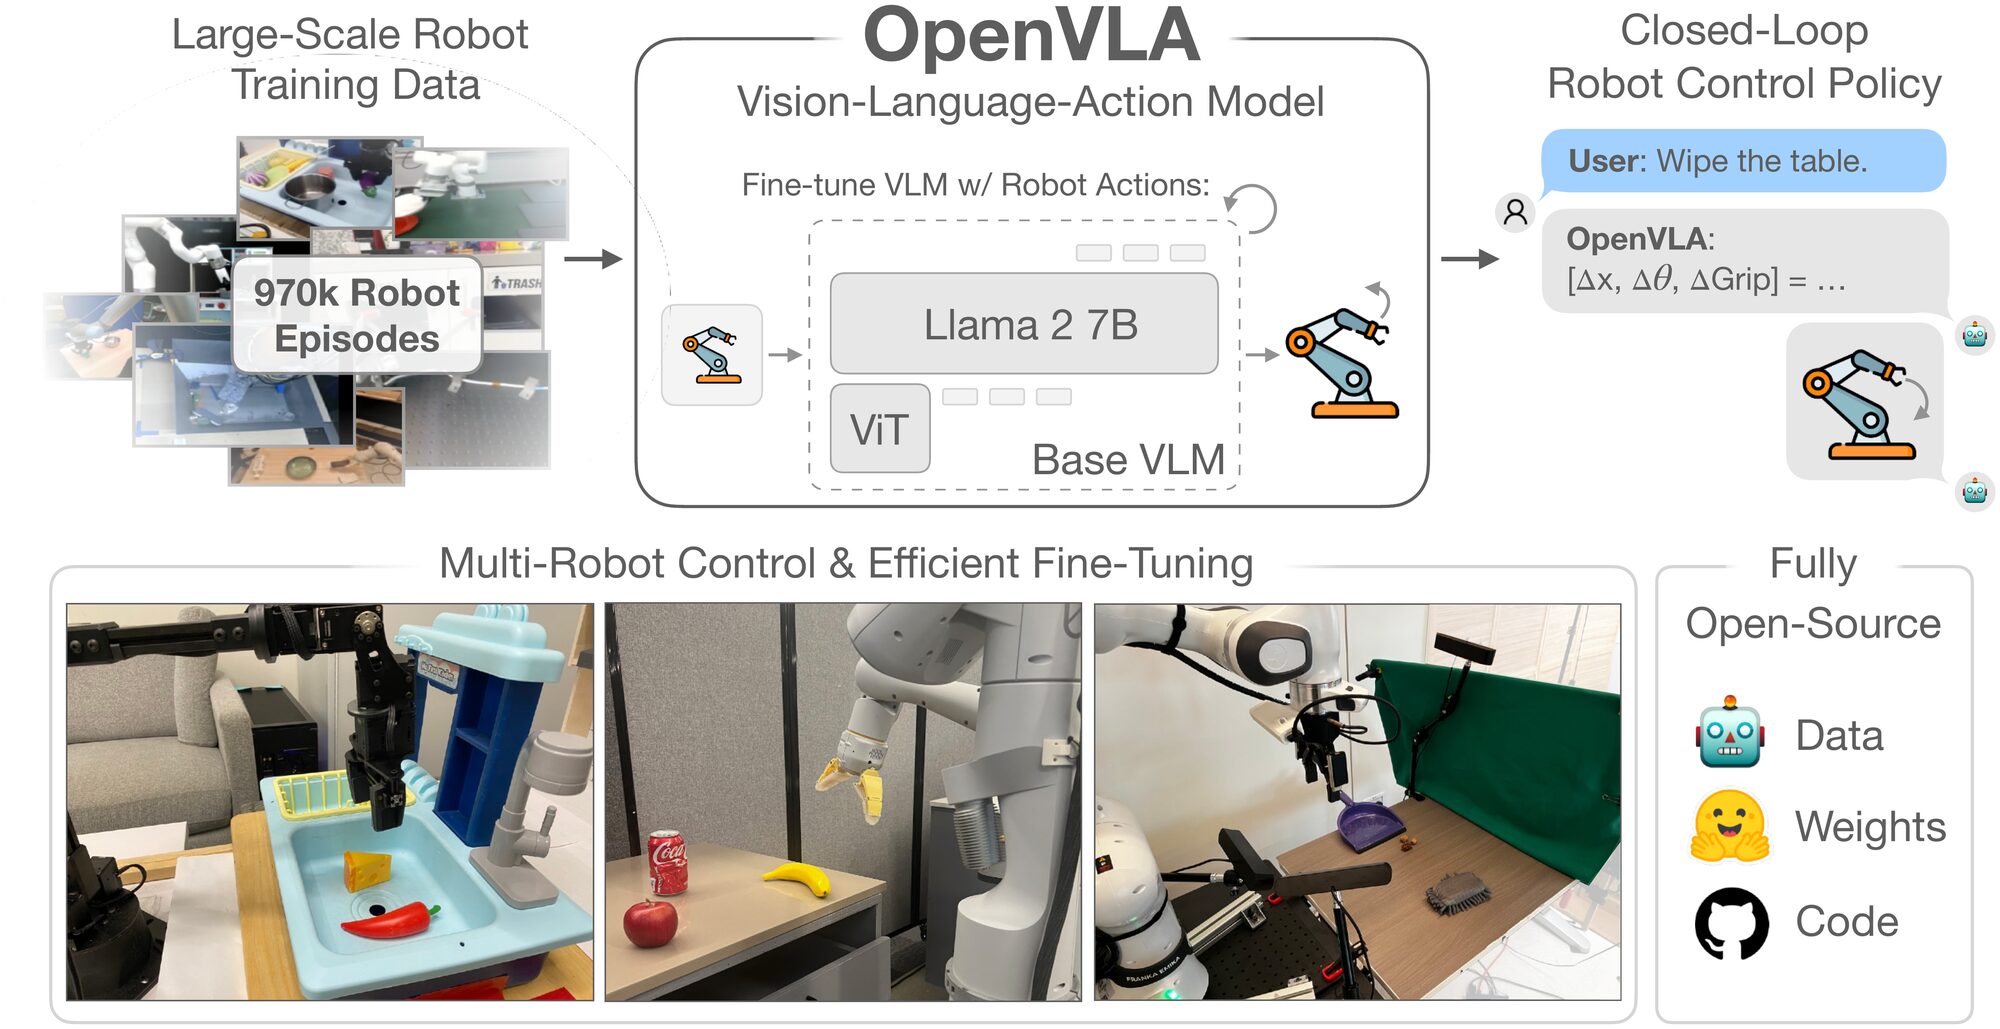
OpenVLA's overview traces one path through the stack: 970k robot episodes, a 7B vision-language-action model and closed-loop control of several robots. Paper figure: Moo Jin Kim et al. / arXiv. Licence: CC BY 4.0.Appears on: The Robot Learning Stack
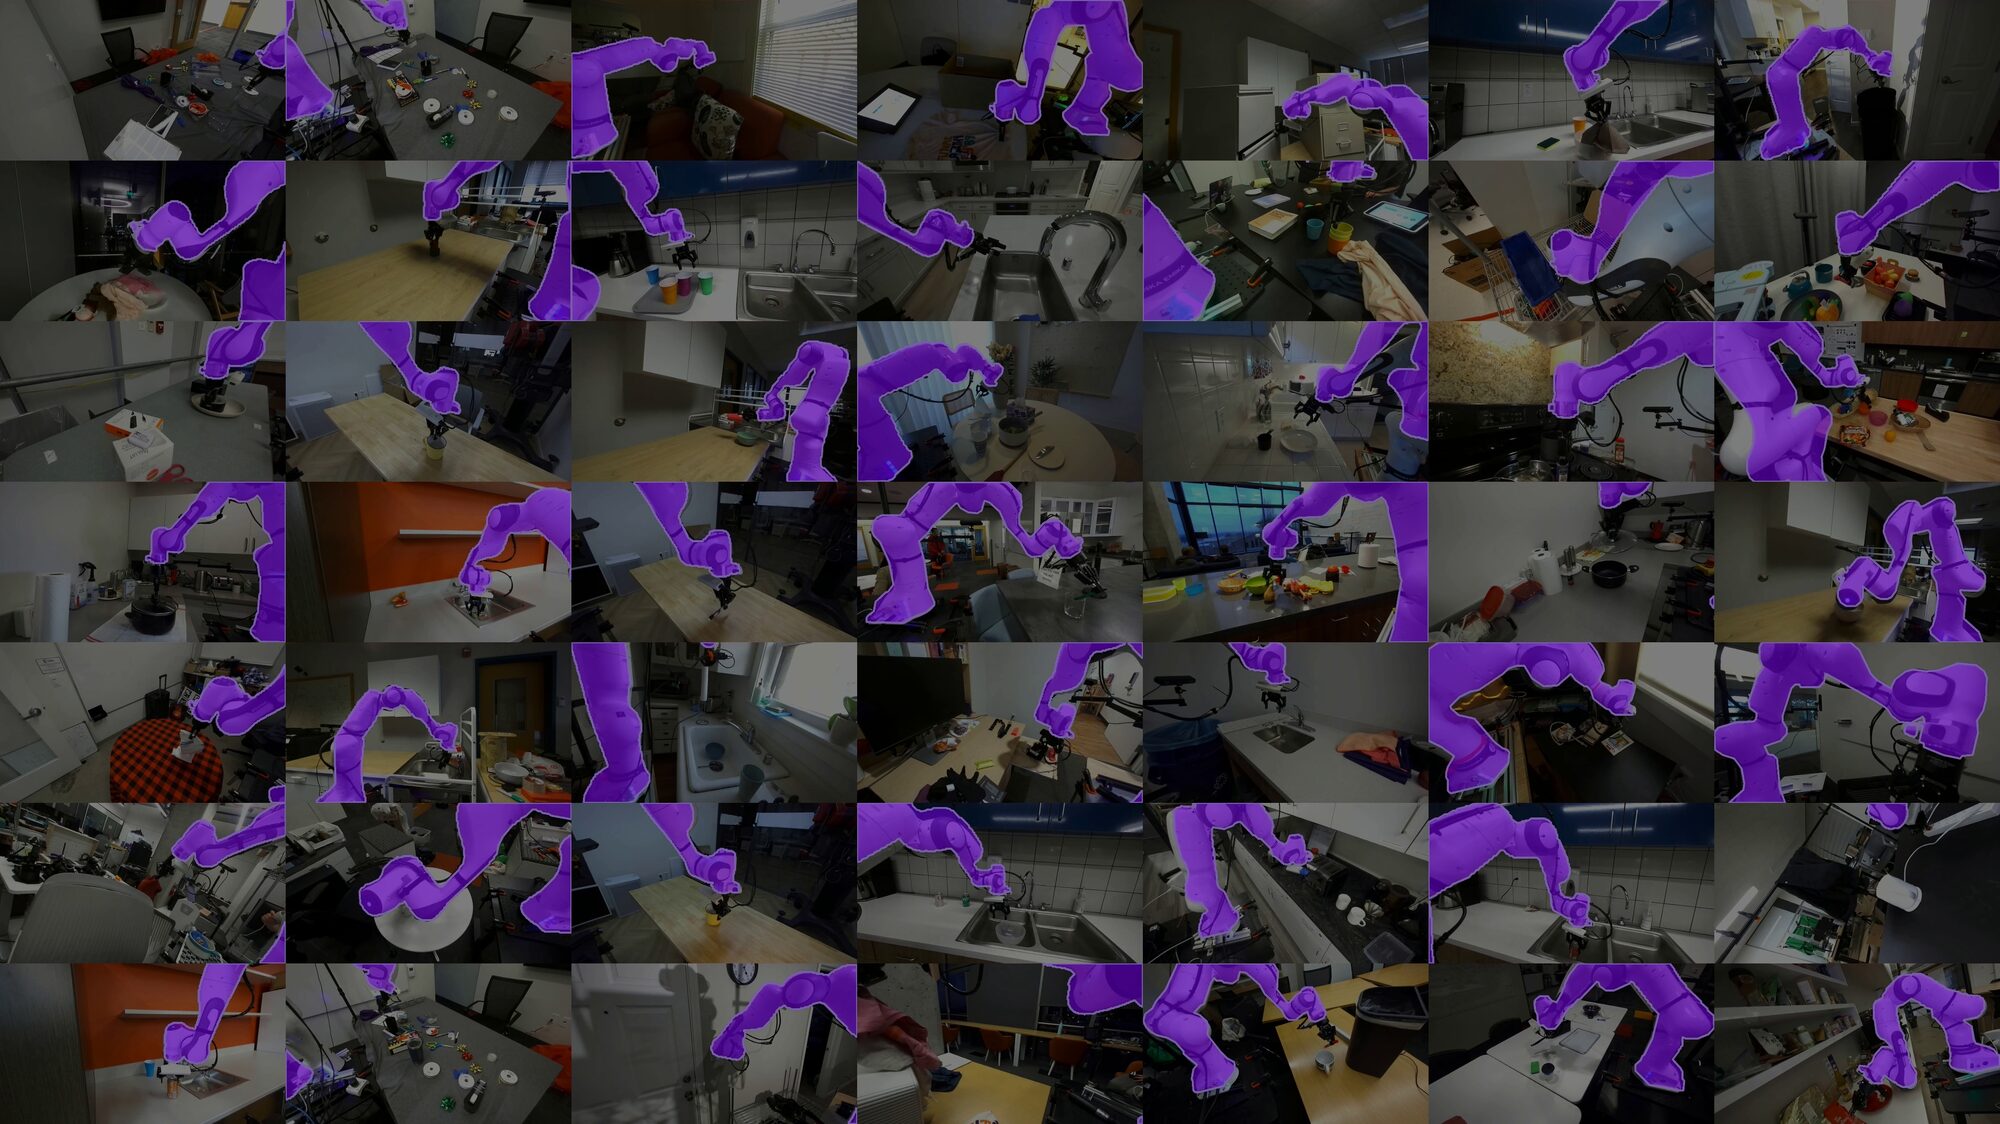
DROID frames with the robot's mesh rendered from the estimated camera-to-base transform. Where the mask covers the real arm, the calibration holds; a moved camera shows as a mask that misses. Paper figure: Alexander Khazatsky et al. / arXiv. Licence: CC BY 4.0.Appears on: The Robot Learning Stack
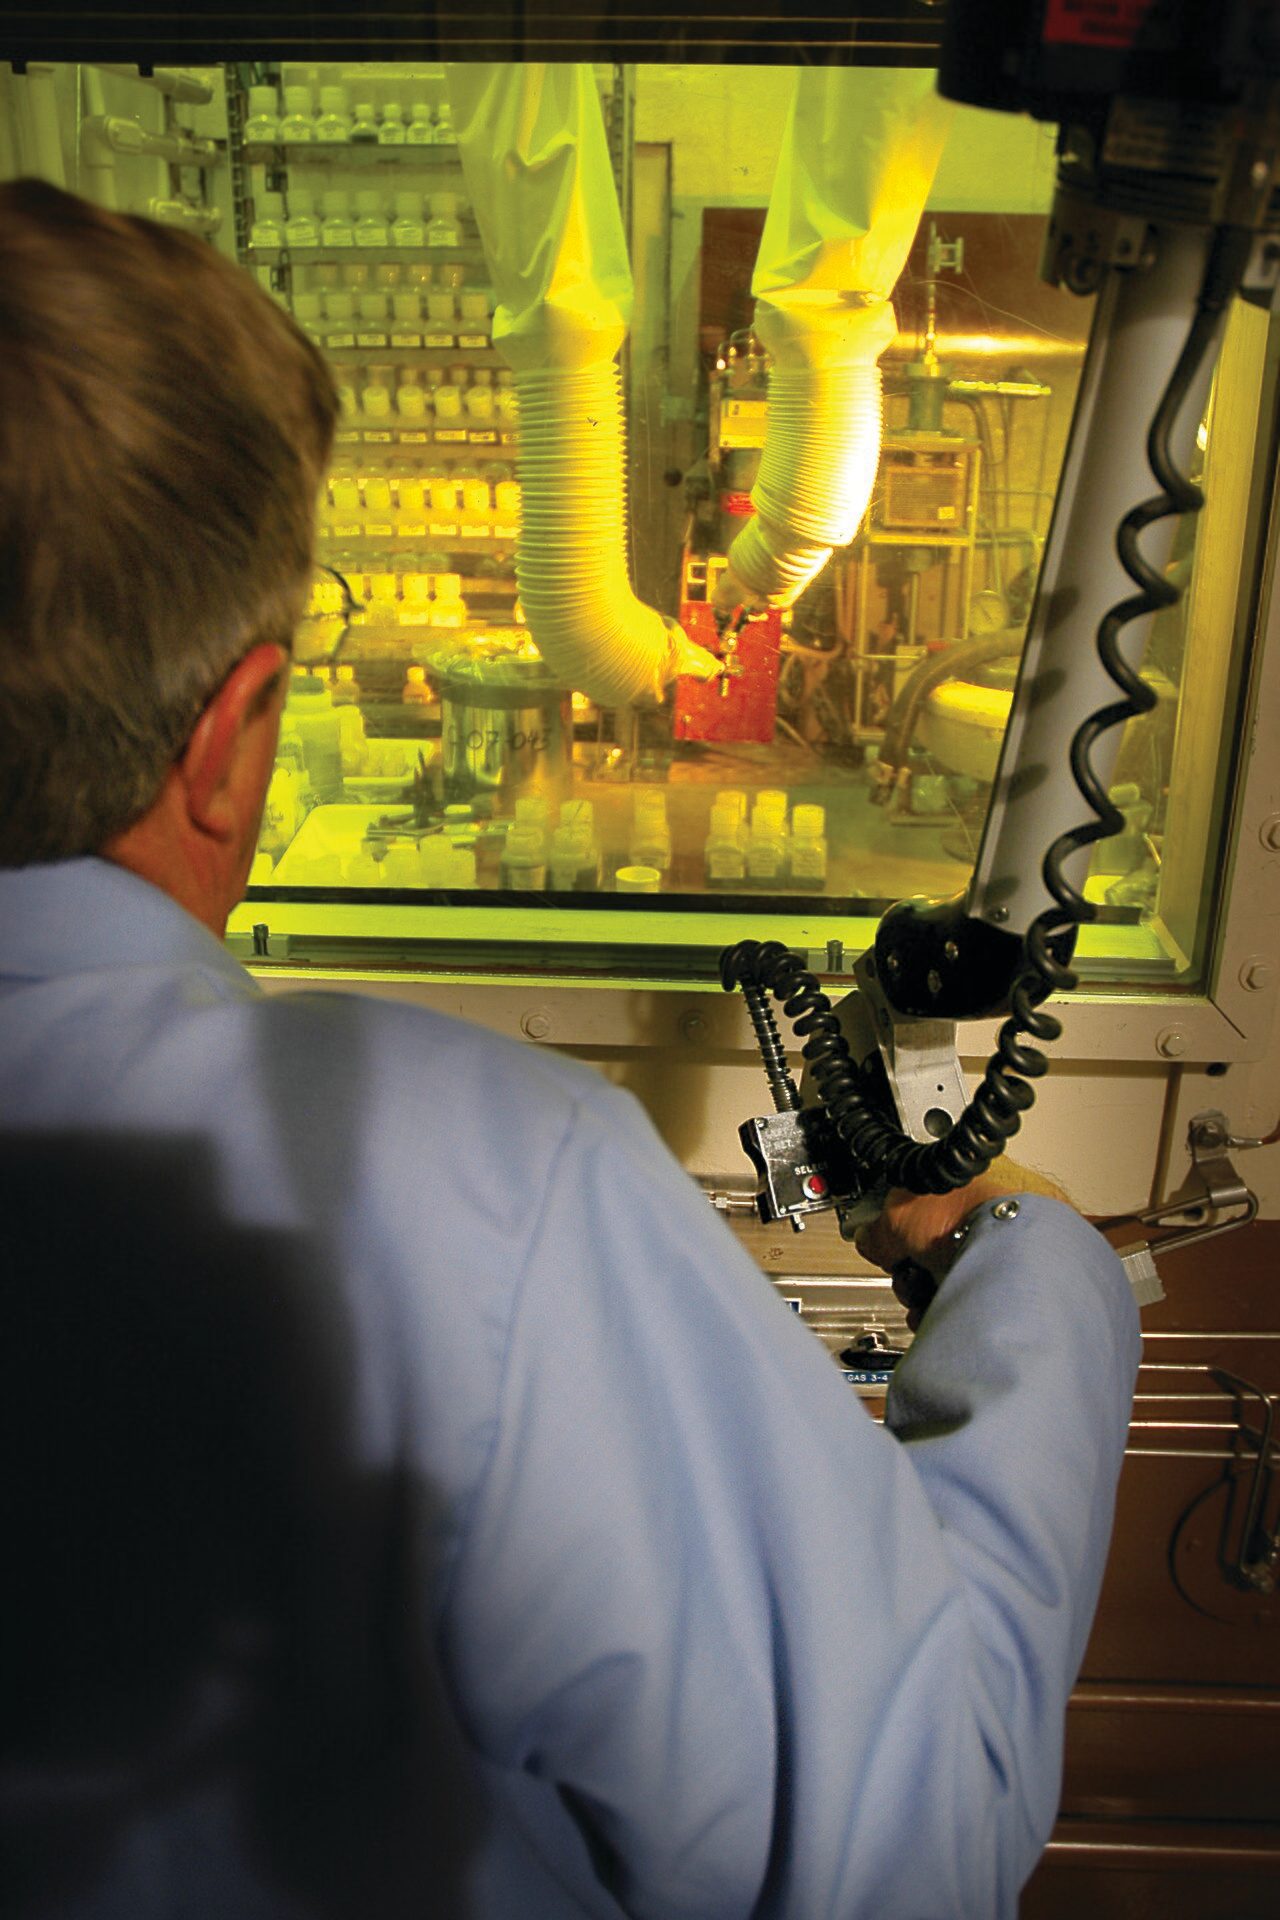
A researcher at Idaho National Laboratory in 2006 works radioactive material through a leaded-glass window, a handle outside driving tongs inside. ALOHA's leader arm uses the same principle. Photo: Idaho National Laboratory / Wikimedia Commons. Licence: CC BY 2.0.Appears on: Teleoperation Rigs
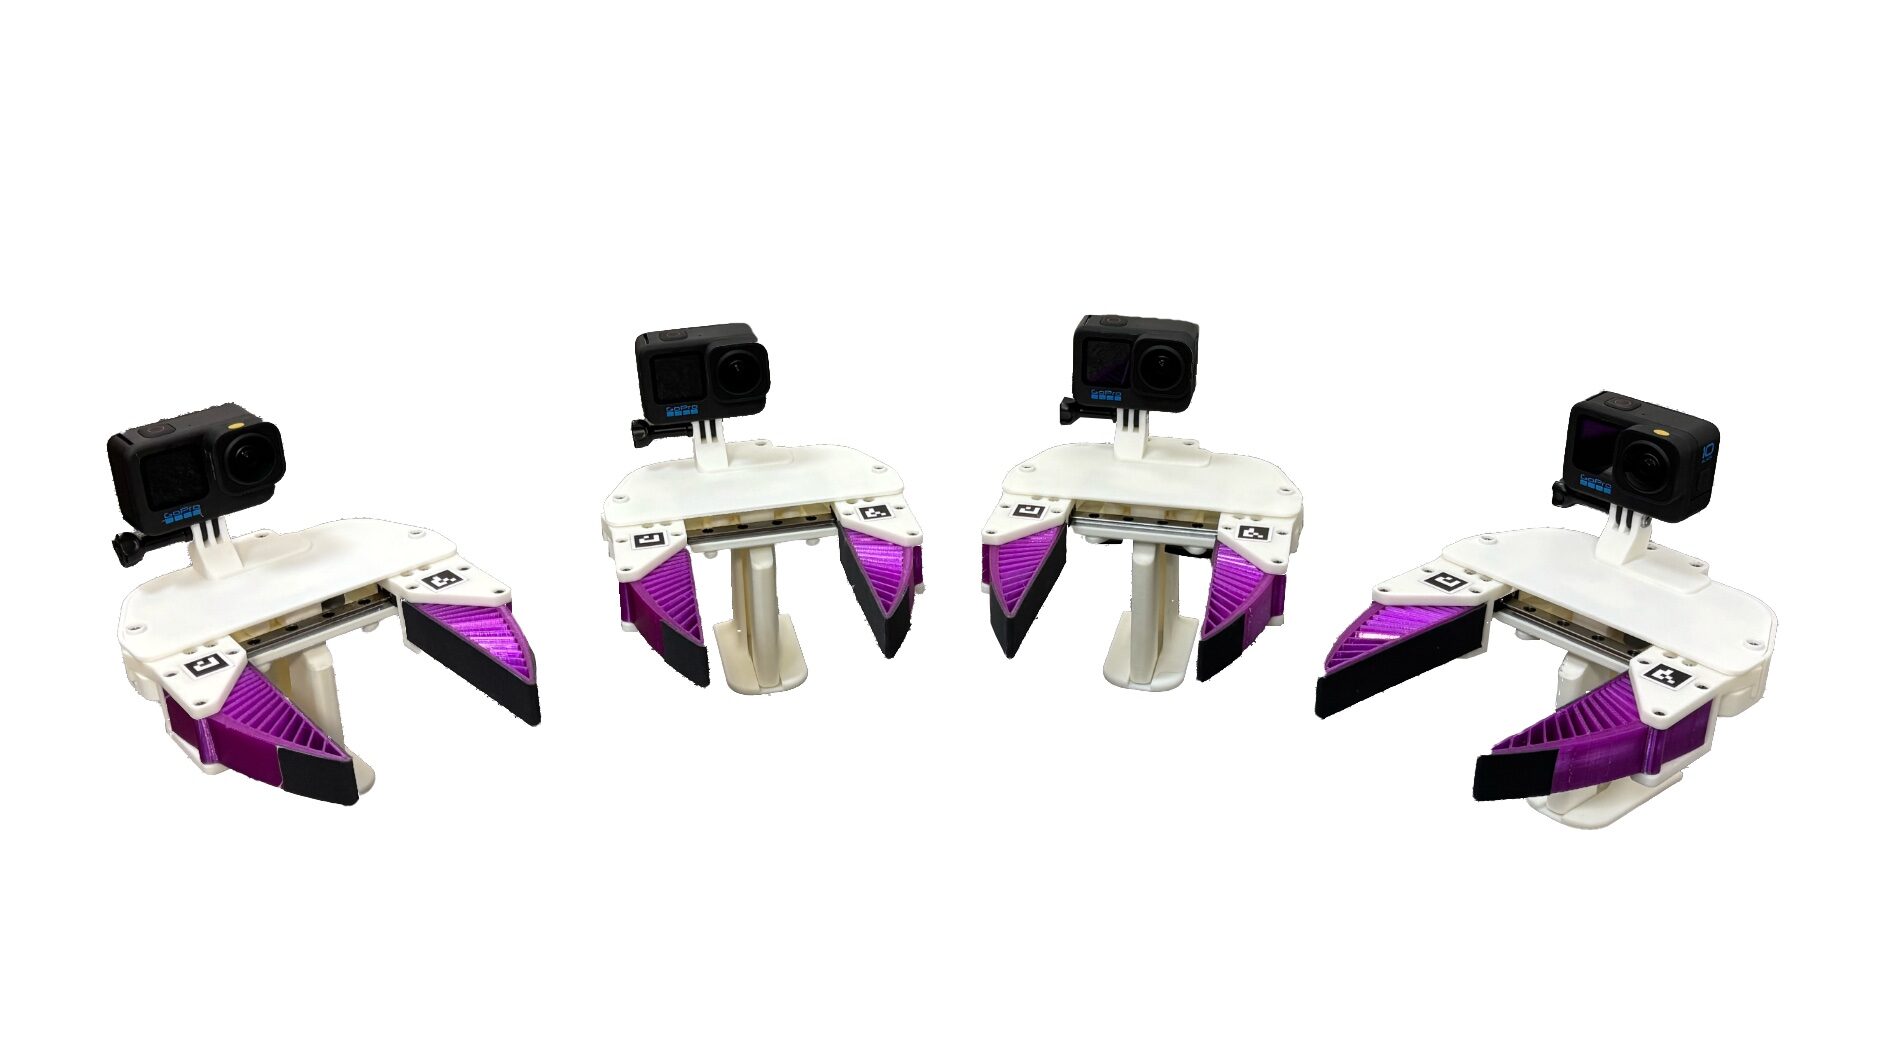
The four UMI handheld grippers used in Lin and colleagues' data-scaling study. A Franka arm with matching purple fingers and a wrist GoPro ran the trained policies. Paper figure: Fanqi Lin et al. / arXiv. Licence: CC BY 4.0.Appears on: Teleoperation Rigs
Physical Intelligence logo from Wikimedia Commons, used on the market map. Logo: Physical Intelligence / Wikimedia Commons. Licence: CC BY 4.0.Appears on: Market Map

Covariant logo from the official website, used on the market map. Logo: Covariant / Covariant official website. Licence: Unlicensed.Appears on: Market Map
NVIDIA wordmark from Wikimedia Commons, used on the market map. Logo: NVIDIA / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Hugging Face logo from the official brand page, used on the market map. Logo: Hugging Face / Hugging Face brand page. Licence: Unlicensed.Appears on: Market Map
Figure AI logo from the official website, used on the market map. Logo: Figure AI / Figure AI official website. Licence: Unlicensed.Appears on: Market Map
Agility Robotics logo from Wikimedia Commons, used on the market map. Logo: Agility Robotics / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Tesla mark from Wikimedia Commons, used on the market map. Logo: Tesla / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Unitree Robotics logo from Wikimedia Commons, used on the market map. Logo: Unitree / Wikimedia Commons. Licence: Public domain.Appears on: Market Map

UBTECH Robotics logo from Wikimedia Commons, used on the market map. Logo: UBTECH Robotics Inc. / Wikimedia Commons. Licence: Public domain.Appears on: Market Map

NEURA Robotics logo from Wikimedia Commons, used on the market map. Logo: Neura Robotics GmbH / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Wandercraft logo from Wikimedia Commons, used on the market map. Logo: Wandercraft / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Rainbow Robotics logo from Wikimedia Commons, used on the market map. Logo: Rainbow Robotics / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Berkshire Grey logo from Wikimedia Commons, used on the market map. Logo: Berkshire Grey / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Amazon Robotics logo from Wikimedia Commons, used on the market map. Logo: Amazon.com, Inc. / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Bedrock Robotics logo from Wikimedia Commons, used on the market map. Logo: Bedrock Robotics Inc. / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Intuitive Surgical logo from Wikimedia Commons, used on the market map. Logo: Intuitive Surgical / Wikimedia Commons. Licence: Public domain.Appears on: Market Map

CMR Surgical logo from the official website, used on the market map. Logo: CMR Surgical / CMR Surgical official website. Licence: Unlicensed.Appears on: Market Map
Nuro logo from Wikimedia Commons, used on the market map. Logo: Nuro, Inc. / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
iRobot logo from Wikimedia Commons, used on the market map. Logo: iRobot / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Harmonic Drive Systems logo from the official website, used on the market map. Logo: Harmonic Drive Systems Inc. / Harmonic Drive Systems official website. Licence: Unlicensed.Appears on: Market Map
Nabtesco logo from Wikimedia Commons, used on the market map. Logo: Nabtesco / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Wonik Robotics logo from the official website, used on the market map. Logo: Wonik Robotics / Wonik Robotics official website. Licence: Unlicensed.Appears on: Market Map
OpenAI wordmark from Wikimedia Commons, used on the market map. Logo: OpenAI / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Meta Platforms logo from Wikimedia Commons, used on the market map. Logo: Meta Platforms / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
SwitchBot logo from Wikimedia Commons, used on the market map. Logo: SwitchBot / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Hanson Robotics logo from Wikimedia Commons, used on the market map. Logo: Hanson Robotics Ltd. / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Starship Technologies logo from Wikimedia Commons, used on the market map. Logo: Starship Technologies / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Pollen Robotics logo from Wikimedia Commons, used on the market map. Logo: Pollen Robotics / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Anduril Industries logo from Wikimedia Commons, used on the market map. Logo: Anduril Industries, Inc. / Wikimedia Commons. Licence: Public domain.Appears on: Market Map

ABB logo from Wikimedia Commons, used on the market map. Logo: ABB / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Mitsubishi mark from Wikimedia Commons, used on the market map. Logo: Mitsubishi / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Monarch Tractor logo from Wikimedia Commons, used on the market map. Logo: Monarch Tractor / Wikimedia Commons. Licence: CC BY-SA 4.0.Appears on: Market Map

Skild AI logo from the official website, used on the market map. Logo: Skild AI / Skild AI official website. Licence: Unlicensed.Appears on: Market Map
Generalist AI logo from the official website, used on the market map. Logo: Generalist AI / Generalist AI official website. Licence: Unlicensed.Appears on: Market Map
Dyna Robotics logo from the official website, used on the market map. Logo: Dyna Robotics / Dyna Robotics official website. Licence: Unlicensed.Appears on: Market Map
Sunday Robotics logo from the official website, used on the market map. Logo: Sunday Robotics / Sunday Robotics official website. Licence: Unlicensed.Appears on: Market Map
Field AI logo from the official website, used on the market map. Logo: Field AI / Field AI official website. Licence: Unlicensed.Appears on: Market Map

Genesis AI logo from the official website, used on the market map. Logo: Genesis AI / Genesis AI official website. Licence: Unlicensed.Appears on: Market Map
Rhoda AI logo from the official website, used on the market map. Logo: Rhoda AI / Rhoda AI official website. Licence: Unlicensed.Appears on: Market Map

Mind Robotics logo from the official website, used on the market map. Logo: Mind Robotics / Mind Robotics official website. Licence: Unlicensed.Appears on: Market Map
Google DeepMind logo from Wikimedia Commons, used on the market map. Logo: DeepMind / Wikimedia Commons. Licence: Public domain.Appears on: Market Map
Applied Intuition logo from the official website, used on the market map. Logo: Applied Intuition / Applied Intuition official website. Licence: Unlicensed.Appears on: Market Map
XDOF logo from the official website, used on the market map. Logo: XDOF / XDOF official website. Licence: Unlicensed.Appears on: Market Map

Encord logo from the official website, used on the market map. Logo: Encord / Encord official website. Licence: Unlicensed.Appears on: Market Map

Micro1 logo from the official website, used on the market map. Logo: Micro1 / Micro1 official website. Licence: Unlicensed.Appears on: Market Map

1X Technologies logo from the official website, used on the market map. Logo: 1X Technologies / 1X Technologies official website. Licence: Unlicensed.Appears on: Market Map

Apptronik logo from the official website, used on the market map. Logo: Apptronik / Apptronik official website. Licence: Unlicensed.Appears on: Market Map
Boston Dynamics logo from the official website, used on the market map. Logo: Boston Dynamics / Boston Dynamics official website. Licence: Unlicensed.Appears on: Market Map
Fourier logo from the official website, used on the market map. Logo: Fourier / Fourier official website. Licence: Unlicensed.Appears on: Market Map
Galbot logo from the official website, used on the market map. Logo: Galbot / Galbot official website. Licence: Unlicensed.Appears on: Market Map
AgiBot logo from the official website, used on the market map. Logo: AgiBot / AgiBot official website. Licence: Unlicensed.Appears on: Market Map
Sanctuary AI logo from the official website, used on the market map. Logo: Sanctuary AI / Sanctuary AI official website. Licence: Unlicensed.Appears on: Market Map

Humanoid logo from the official website, used on the market map. Logo: Humanoid / Humanoid official website. Licence: Unlicensed.Appears on: Market Map
Spirit AI logo from the official website, used on the market map. Logo: Spirit AI / Spirit AI official website. Licence: Unlicensed.Appears on: Market Map
Galaxea logo from the official website header, used on the market map. Logo: Galaxea / Galaxea official website. Licence: Unlicensed.Appears on: Market Map
EngineAI logo from the official website, used on the market map. Logo: EngineAI / EngineAI official website. Licence: Unlicensed.Appears on: Market Map
RobotEra logo from its brand profile, used on the market map. Logo: RobotEra / Brand.dev profile of robotera.com. Licence: Unlicensed.Appears on: Market Map
TARS Robotics logo from the official website, used on the market map. Logo: TARS Robotics / TARS Robotics official website. Licence: Unlicensed.Appears on: Market Map

X Square Robot logo from the official website, used on the market map. Logo: X Square Robot / X Square Robot official website. Licence: Unlicensed.Appears on: Market Map
Deep Robotics logo from the official website, used on the market map. Logo: Deep Robotics / Deep Robotics official website. Licence: Unlicensed.Appears on: Market Map
Kepler Robot logo from the official website, used on the market map. Logo: Kepler / Kepler official website. Licence: Unlicensed.Appears on: Market Map
LimX Dynamics logo from the official website, used on the market map. Logo: LimX Dynamics / LimX Dynamics official website. Licence: Unlicensed.Appears on: Market Map
Clone Robotics logo from the official website, used on the market map. Logo: Clone Robotics / Clone Robotics official website. Licence: Unlicensed.Appears on: Market Map

Mentee Robotics logo from the official website, used on the market map. Logo: Mentee Robotics / Mentee Robotics official website. Licence: Unlicensed.Appears on: Market Map
Persona AI logo from the official website, used on the market map. Logo: Persona AI / Persona AI official website. Licence: Unlicensed.Appears on: Market Map
Symbotic logo from the official website, used on the market map. Logo: Symbotic / Symbotic official website. Licence: Unlicensed.Appears on: Market Map

Dexterity logo from the official website, used on the market map. Logo: Dexterity / Dexterity official website. Licence: Unlicensed.Appears on: Market Map
Nimble logo from the official website, used on the market map. Logo: Nimble / Nimble official website. Licence: Unlicensed.Appears on: Market Map
Locus Robotics logo from the official website, used on the market map. Logo: Locus Robotics / Locus Robotics official website. Licence: Unlicensed.Appears on: Market Map

Mujin logo from the official website, used on the market map. Logo: Mujin / Mujin official website. Licence: Unlicensed.Appears on: Market Map
RightHand Robotics logo from the official website, used on the market map. Logo: RightHand Robotics / RightHand Robotics official website. Licence: Unlicensed.Appears on: Market Map
Ambi Robotics logo from the official website, used on the market map. Logo: Ambi Robotics / Ambi Robotics official website. Licence: Unlicensed.Appears on: Market Map
Plus One Robotics logo from the official website, used on the market map. Logo: Plus One Robotics / Plus One Robotics official website. Licence: Unlicensed.Appears on: Market Map
Carbon Robotics logo from the official website, used on the market map. Logo: Carbon Robotics / Carbon Robotics official website. Licence: Unlicensed.Appears on: Market Map
Farm-ng logo from the company website as archived before the acquisition, used on the market map. Logo: Farm-ng / Farm-ng official website (Wayback Machine capture). Licence: Unlicensed.Appears on: Market Map

Chef Robotics logo from the official website, used on the market map. Logo: Chef Robotics / Chef Robotics official website. Licence: Unlicensed.Appears on: Market Map

Simbe Robotics logo from the official website, used on the market map. Logo: Simbe Robotics / Simbe Robotics official website. Licence: Unlicensed.Appears on: Market Map

Moon Surgical logo from the official website, used on the market map. Logo: Moon Surgical / Moon Surgical official website. Licence: Unlicensed.Appears on: Market Map
Serve Robotics logo from the official website, used on the market map. Logo: Serve Robotics / Serve Robotics official website. Licence: Unlicensed.Appears on: Market Map

Gecko Robotics logo from the official website, used on the market map. Logo: Gecko Robotics / Gecko Robotics official website. Licence: Unlicensed.Appears on: Market Map
Standard Bots logo from the official website, used on the market map. Logo: Standard Bots / Standard Bots official website. Licence: Unlicensed.Appears on: Market Map

Collaborative Robotics logo from its brand profile, used on the market map. Logo: Collaborative Robotics / Brand.dev profile of co.bot. Licence: Unlicensed.Appears on: Market Map
The Bot Company logo from the official website, used on the market map. Logo: The Bot Company / The Bot Company official website. Licence: Unlicensed.Appears on: Market Map
Weave Robotics logo from the official website, used on the market map. Logo: Weave Robotics / Weave Robotics official website. Licence: Unlicensed.Appears on: Market Map
K-Scale Labs logo from the official website, used on the market map. Logo: K-Scale Labs / Y Combinator company page. Licence: Unlicensed.Appears on: Market Map
Automata logo from the official website, used on the market map. Logo: Automata / Automata official website. Licence: Unlicensed.Appears on: Market Map

Lila Sciences logo from the official website, used on the market map. Logo: Lila Sciences / Lila Sciences official website. Licence: Unlicensed.Appears on: Market Map
Avidbots logo from the official website, used on the market map. Logo: Avidbots / Avidbots official website. Licence: Unlicensed.Appears on: Market Map
Leaderdrive logo from the official website, used on the market map. Logo: Leaderdrive / Leaderdrive official website. Licence: Unlicensed.Appears on: Market Map

Sanhua logo from the official website, used on the market map. Logo: Sanhua / Sanhua official website. Licence: Unlicensed.Appears on: Market Map
Shadow Robot logo from the official website, used on the market map. Logo: Shadow Robot / Shadow Robot official website. Licence: Unlicensed.Appears on: Market Map
Sharpa logo from the official website, used on the market map. Logo: Sharpa / Sharpa official website. Licence: Unlicensed.Appears on: Market Map
XELA Robotics logo from the official website, used on the market map. Logo: XELA Robotics / XELA Robotics official website. Licence: Unlicensed.Appears on: Market Map
Saronic logo from the official website, used on the market map. Logo: Saronic / Saronic official website. Licence: Unlicensed.Appears on: Market Map
Eka Robotics logo from the official website, used on the market map. Logo: Eka Robotics / Eka Robotics official website. Licence: Unlicensed.Appears on: Market Map

Foundry Robotics logo from the official website, used on the market map. Logo: Foundry Robotics / Foundry Robotics official website. Licence: Unlicensed.Appears on: Market Map
Mytra logo from the official website, used on the market map. Logo: Mytra / Mytra official website. Licence: Unlicensed.Appears on: Market Map
Formic logo from the official website, used on the market map. Logo: Formic / Formic official website. Licence: Unlicensed.Appears on: Market Map
Astribot logo from the official website, used on the market map. Logo: Astribot / Astribot official website. Licence: Unlicensed.Appears on: Market Map

Booster Robotics logo from the official website, used on the market map. Logo: Booster Robotics / Booster Robotics official website. Licence: Unlicensed.Appears on: Market Map
Leju Robotics logo from the official website, used on the market map. Logo: Leju Robotics / Leju Robotics official website. Licence: Unlicensed.Appears on: Market Map
PaXini logo from the official website, used on the market map. Logo: PaXini / PaXini official website. Licence: Unlicensed.Appears on: Market Map
Miso Robotics logo from the official website, used on the market map. Logo: Miso Robotics / Miso Robotics official website. Licence: Unlicensed.Appears on: Market Map
Coco logo from the official website, used on the market map. Logo: Coco / Coco official website. Licence: Unlicensed.Appears on: Market Map

Knightscope logo from the official website, used on the market map. Logo: Knightscope / Knightscope official website. Licence: Unlicensed.Appears on: Market Map
Brain Corp logo from the official website, used on the market map. Logo: Brain Corp / Brain Corp official website. Licence: Unlicensed.Appears on: Market Map
Diligent Robotics logo from the official website, used on the market map. Logo: Diligent Robotics / Diligent Robotics official website. Licence: Unlicensed.Appears on: Market Map
Fox Robotics logo from the official website, used on the market map. Logo: Fox Robotics / Fox Robotics official website. Licence: Unlicensed.Appears on: Market Map
Zebra Technologies (Robotics Automation) logo from the official website, used on the market map. Logo: Zebra Technologies / Zebra Technologies (Robotics Automation) official website. Licence: Unlicensed.Appears on: Market Map
Robotphoenix logo from the official website, used on the market map. Logo: Robotphoenix / Robotphoenix official website. Licence: Unlicensed.Appears on: Market Map