The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
The data bottleneck is the shortage of robot training data compared with the text language models learn from. The largest public robot datasets hold hundreds to a few thousand hoursSource 5 Source 6, while Llama 4 Scout trained on about 40 trillion tokensSource 20 and companies report private corpora of 100,000 hours or more from handheld and wearable devicesSource 21 Source 22.
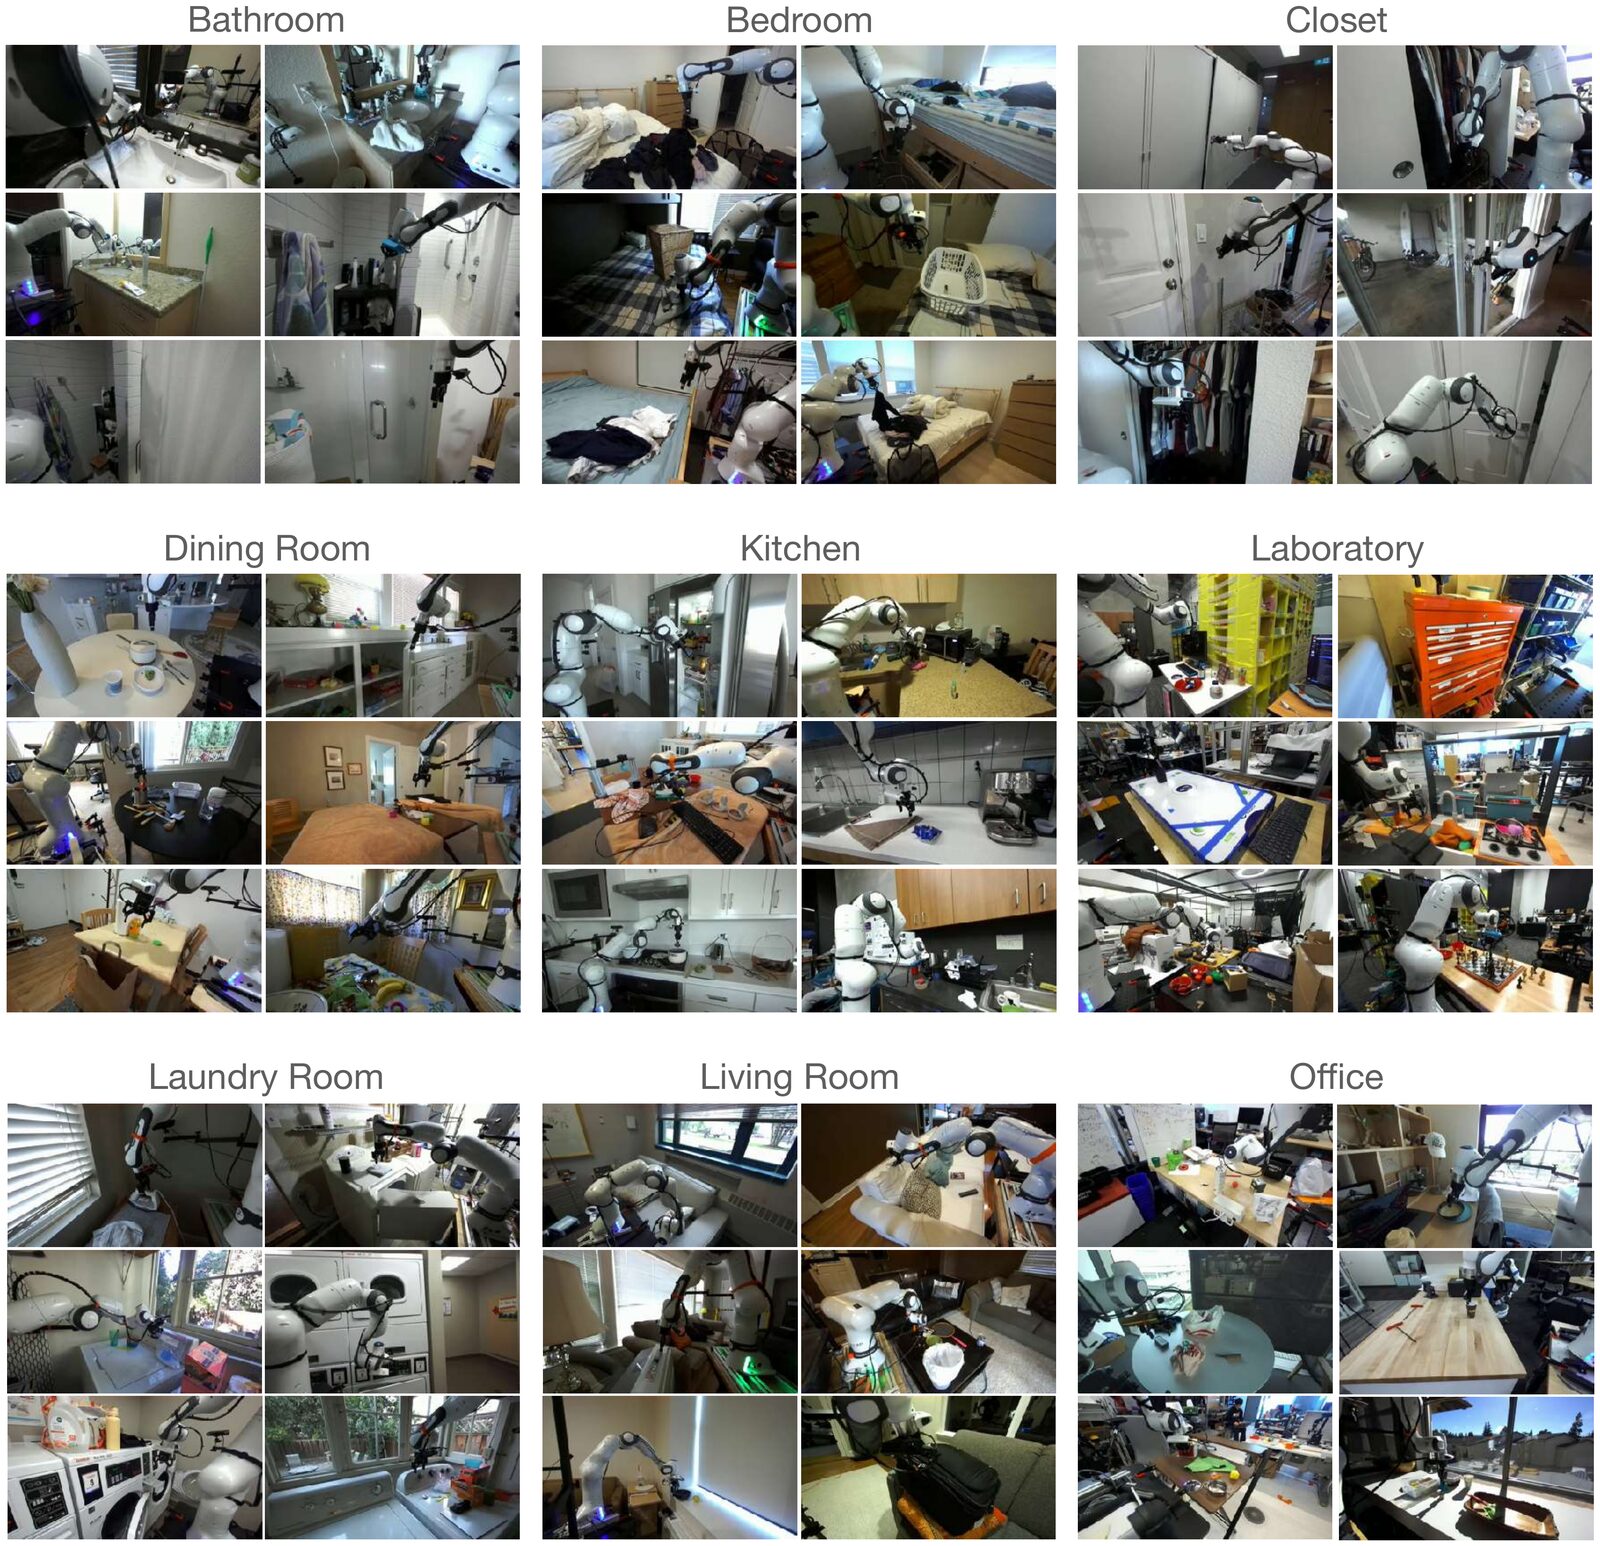
DROID reports 76,000 successful trajectories totaling 350 interaction hours. Fifty data collectors used 18 robots across 13 institutions over 12 months, and the release adds roughly 16,000 unsuccessful trajectories outside that countSource 5. Drag "Robots collecting" to change fleet size at two authored hypothetical rates: 1,000 or 7 productive hours per rig-year.
Guess first
10 part-time robots: 70 hours a year, 143 years to 10,000 hours. Switch to the full-time farm and it takes one year.
The data bottleneck
Robot training data is tiny next to chatbot training text
How much each robot collects
Adjust more
Hours to collect
Datasets to pick out
10 part-time robots collect 70 hours a year: 10,000 hours takes 143 years, 1,000,000 hours takes 14,286 years
robot datahuman videocompany total, not releasedyour robots, one year
Illustrative: chosen collection rates, not a measured farm.
How this was made
The two panels use separate rulers because there is no honest exchange rate between an hour of robot practice and a token of text, so none is drawn. A token is a piece of a word: GPT-3 trained on 300B tokens and Llama 3 on 15T tokens. Both rulers are logarithmic: each labelled step is ten times the one before.
Authored hypothetical: 7 productive hours per rig-year, not a measured DROID productivity rate. DROID reports collectors and elapsed collection time, not annual exposure for each rig. The 10,000-hour and 1,000,000-hour targets are authored hypothetical inputs, not OXE totals or measured frontier requirements. Hours marked “about” on dataset points are estimates. Hours marked “over” are totals Xiaomi and Generalist report for their own models; neither company has released the data, so no one outside can count them.
- Full-time farm: about 4 hours a day each (Dedicated farm hypothetical, 1,000 h/rig/yr): Authored hypothetical: 1,000 productive hours per rig-year. For example, 4 hours on each of 250 working days. This is a teaching input, not measured farm productivity.
- Part-time: 7 hours a year each (Low-rate hypothetical, 7 h/rig/yr): Authored hypothetical: 7 productive hours per rig-year, not a measured DROID productivity rate. DROID reports collectors and elapsed collection time, not annual exposure for each rig.
Current projection: 10 rigs at 70 h/yr, 10,000 h in 143 yr and 1,000,000 h in 14,286 yr. No OXE hour estimate is supplied or plotted here.
Sources for each count: DROID, EgoDex, TRI LBM, AgiBot World, Ego4D, EgoScale, Xiaomi, GEN-0, GEN-1, GPT-3, Llama 3.
Demonstration hours span 350 h (DROID) to 20,854 h (EgoScale) across 6 robot and human datasets, and companies report unreleased totals of 100,000+ h (Xiaomi), 270,000+ h (GEN-0) and 500,000+ h (GEN-1), while pretraining tokens span 300B (GPT-3) to 15T (Llama 3), on separate rulers with no honest hour-to-token exchange rate between them; your 10-rig farm at the low-rate hypothetical rate projects 70 h per year, reaching the authored 10,000-hour target in 143 yr and the authored 1,000,000-hour target in 14,286 yr. No OXE hour estimate is supplied or plotted here.
Datasets and corpora by scale, with the farm projection
| dataset | demonstration hours | pretraining tokens |
|---|---|---|
| DROID | 350 h | n/a |
| EgoDex | 829 h | n/a |
| TRI LBM | ~1,700 h | n/a |
| AgiBot World | 2,976 h | n/a |
| Ego4D | 3,670 h | n/a |
| EgoScale | 20,854 h | n/a |
| OXE | No hour estimate plotted | n/a |
| GPT-3 | n/a | 300B tokens |
| Llama 3 | n/a | 15T tokens |
| your hypothetical farm (10 rigs) | 70 h/yr | n/a |
OXE: over 1 million recorded robot runs on 22 kinds of robot, with no total hours. This chart supplies no hour estimate and does not plot OXE on the hours axis.
Read the reasoning
- Around two decades, which needs roughly 500 farm-hours a year instead of 70Twenty years would require 500 hours a year across the whole farm. This scenario produces only 10 times 7, or 70 hours a year, so it takes much longer.
- Only a few years, on the assumption that each rig collects hundreds of hours a yearThat assumes a higher collection rate than the question supplies. The dedicated-farm hypothetical uses 1,000 hours per rig-year; at 10 rigs, it reaches 10,000 hours in one year.
- Well over a century, on the order of 140 years at that throughputThe arithmetic is 10,000 hours divided by 70 hours a year, roughly 143 years. Both the rate and target are authored hypothetical inputs. Neither measures DROID productivity or OXE duration.the hours axis
For the same 10,000-hour hypothetical target, 10 rigs take about 143 years at 7 hours per rig-year and one year at 1,000 hours per rig-year. The result depends on the assumed rate.
15T
language
tokens, Llama 3 pretraining
350
robots
interaction hours, DROID dataset
32x50
scaling law
envs x demos, Lin et al.
20,854
human video
hours, EgoScale
Two data universes, nine orders of magnitude apart
GPT-3 trained on 300 billion tokens in 2020Source 1 and Llama 3 on over 15 trillion in 2024Source 2, a scale the open FineWeb corpus rebuilds from 96 Common Crawl snapshotsSource 3. Qwen3 trained on 36 trillion tokensSource 23. Ken Goldberg of UC Berkeley calls the difference a 100,000-year data gapSource 24.
Open X-Embodiment pools over a million trajectories across 22 robot embodimentsSource 4. The chart assigns it no hour estimate. Robot data has no crawl: a paid teleoperation operator usually drives each hour. AgiBot World publishes 2,976 hours for 1,001,552 trajectories, about 11 seconds eachSource 6.
Toyota Research Institute's Large Behavior Models trained on about 1,700 hours of its own bimanual data, simulation, UMI and Open X-EmbodimentSource 7. π0 pretrained on 10,000 hours of dexterous manipulation from 7 robot configurations, plus Open X-Embodiment, DROID and BridgeSource 25.
What the scaling laws say: diversity beats density
Scaling laws come from language modelling: loss falls as a power law in model size, dataset size and computeSource 26. A meta-analysis of 327 robotics papers finds power laws there tooSource 27.
Lin et al. collected over 40,000 demonstrations and ran over 15,000 real-world rollouts on imitation learningSource 8. Success with new environments and objects follows a rough power law in the number of training environments and objects; demonstrations per environment saturate past about 50. Their recipe, 32 environments with 50 demonstrations each, reached about 90% success with unseen objects; four operators collected it in one afternoon.
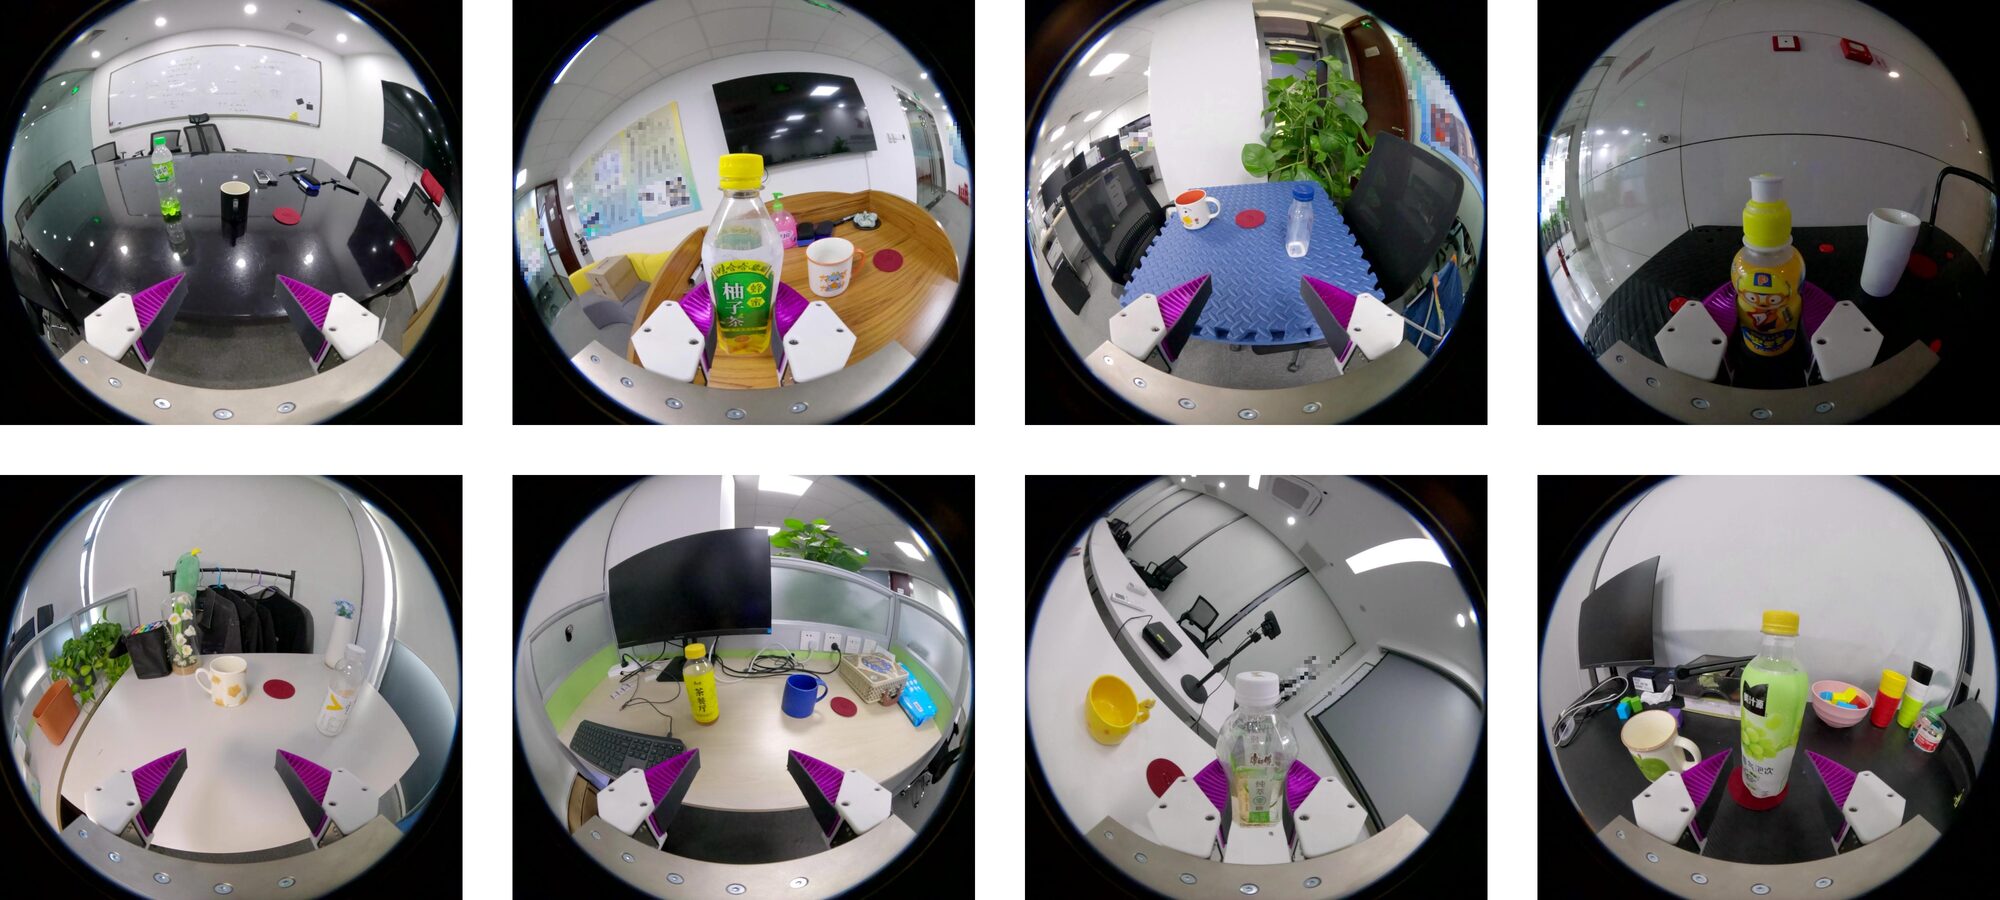
On the AgiBot World stack, Shi et al. split diversity into task, embodiment and expertSource 9. Task diversity mattered more than demonstrations per task. Models pretrained on high-quality single-embodiment data transferred to other robots and scaled better in fine-tuning than multi-embodiment models.
Expert diversity hurt: different operator styles make velocities multimodal. Debiasing them gave GO-1-Pro a 15% gain, which the authors equate to 2.5 times more pretraining dataSource 9.
| Dimension | Effect on performance | Saturation | Source |
|---|---|---|---|
| Environments | strong positive, power law | none found up to 32 envs | Lin et al. 2024 |
| Objects | strong positive, power law | none found | Lin et al. 2024 |
| Demos per environment | positive, saturating | about 50 per env | Lin et al. 2024 |
| Task diversity | strong positive | none found | Shi et al. 2025 |
| Expert diversity | negative unless debiased | multimodal action distributions | Shi et al. 2025 |
| Multi-embodiment pretraining | optional | single-embodiment suffices | Shi et al. 2025 |
Around the bottleneck: data that does not need a robot
UMI collects without a robot: an operator holds a 3D-printed gripper with a GoPro, and its policies deploy zero-shot on real armsSource 10. Apple's EgoDex used Vision Pro hand tracking to record 829 hours of dexterous manipulation with per-joint 3D poses across 194 tasksSource 11. Ego4D holds 3,670 hours of egocentric daily-life video from 931 wearers in 74 locations, without action labelsSource 13. Build AI's Egocentric-100K holds 100,405 hours of head-mounted video of manual labourSource 28.
EgoScale trained a vision-language-action model on 20,854 hours of action-labelled egocentric human video, over twenty times prior efforts. It found a log-linear scaling law between human data scale and validation loss, which correlated with real-robot performanceSource 12. Human pretraining followed by lightweight aligned human-robot mid-training raised average success rate by 54% over a no-pretraining baseline on a 22-DoF dexterous hand. EgoMimic found an extra hour of hand data worth more than an extra hour of robot dataSource 29.
FACT, from Zhi Cao, Jiajun Wu and colleagues at Stanford, the University of Michigan and Microsoft Research (October 2026), was pretrained mostly on about 2,000 hours of human demonstrations recorded with tactile gloves. Fine-tuned on each task, it averaged 41.4% success on seven tasks with two dexterous hands, against 8.6% and 1.4% for T-Rex and π0.5 fine-tuned on the same data. Pretrained without the gloves' force readings, it opened a test-tube cap in none of ten trials instead of eightSource 37.
HiPHI (CoRL 2026) is a motion-capture dataset from Jiahao Ji, Lei Han and colleagues at Noitom Robotics and several universities: 617.5 hours from 132 performers, 245.7 of them with 40 tracked real objects. Retargeted to a Unitree G1, its motions gave the highest simulated tracking success at a matched 3-hour budget against AMASS, LAFAN1, Motion-X++ and BONES-SEED. They led again at 20 hours, a budget LAFAN1 is too short to fill, and policies trained on them ran, crawled and carried a box on a real G1Source 19.
Company corpora reach half a million hours
Generalist AI reports over 270,000 hours of manipulation data for GEN-0, growing by 10,000 hours a week; post-training results improve predictably with more pretraining data and computeSource 30. For GEN-1 it reports over half a million hours from low-cost wearable devices on humans, with no robot data in the base modelSource 22. Xiaomi-Robotics-1 pretrained on over 100,000 hours of trajectories from UMI devices and improved with data and model scaleSource 21.
Sunday trains ACT-1 on glove recordings, converted to robot data with a reported 90% success rateSource 31. Figure reports zero-shot navigation after training only on egocentric human videoSource 32.
Generated and simulated data
GRAIL, from Tianyi Xie, Yuke Zhu and colleagues at NVIDIA and UCLA (June 2026), built over 20,000 humanoid interaction sequences from 3D assets and video models. Policies trained only on them reached 84% pick-up success on a Unitree G1 (five objects, ten trials each) and 90% on stairsSource 14. HumanoidMimicGen, from Kevin Lin, Ajay Mandlekar and colleagues at NVIDIA and UT Austin (May 2026), adapts a few demonstrations to new object poses. Co-training on its data raised average success on four real tasks from 0.51 to 0.71Source 15.
PRISM, from Zihan Wang, Pieter Abbeel, Guanya Shi, Angjoo Kanazawa and colleagues at Amazon FAR, UC Berkeley and Carnegie Mellon (September 2026), turned a few real videos into hundreds of generated variants. Its policy ran on a real humanoid with no real-world fine-tuningSource 16. DexAgent, from Li Fei-Fei, Jiajun Wu and colleagues at Stanford and Columbia (September 2026), turns one egocentric human video into simulated trajectories. Across eleven real tasks, its policies reached 3.5 times the success rate of baselinesSource 17.
MobileVISTA, from Suzannah Wistreich, Jiajun Wu and colleagues at Stanford and the Toyota Research Institute (October 2026), synthesizes images and actions for shifted base poses from demonstrations recorded at one pose. With 50 demonstrations per task and base offsets within 15 cm, its policy stacked a book in 13 of 25 trials, against at most 2 for Canonical-2D, DP3 and a fine-tuned π0.5. At the original pose it stacked 18 of 25, below their 24 and 25Source 18.
Dexterity from Supervised Play, from Botao He, Jitendra Malik and colleagues at Amazon FAR and the University of Maryland (October 2026), starts from 15 minutes of human play on a 22-joint hand. A policy cloned from that play collects data for a world model, then proposes actions for model-predictive control. Asked to rotate a cube to a goal orientation in simulation, the system came within 0.6 radians in 91.4% of 128 trials, where PPO needed about 490 times the data to reach 86.7%, and on the real hand it reached 90.0%Source 38.
Simulation compresses months of interaction into hours but brings the sim-to-real gap covered in massively parallel sim RL. GR00T N1 generated simulated trajectories equal to 6,500 hours of human demonstration in 11 hoursSource 33, and co-training with simulation raised real-world performance by 38% on averageSource 34. A model pretrained only on the synthetic InternData-A1 matched the official π0 on 49 simulated, 5 real-world and 4 long-horizon dexterous tasksSource 35.
Sergey Levine of Physical Intelligence argued in July 2025 that real data is indispensable if robot models are to generalize in the physical world as broadly as language models do in the virtual oneSource 36. Closed-loop learning from any of these sources still meets the covariate shift covered in behavior cloning foundations.
How to read the field's data claims
Convert everything to hours: AgiBot World's million trajectories are 2,976 hours, less than Ego4D's 3,670 hours of passive videoSource 13. Ask for the breakdown by environment, object, task and operator style; those axes outweigh the hour countSource 9. Treat company-reported scale as a claim until the data or an audit is public: AgiBot World's 30% improvement over OXE pretraining has no independent replicationSource 6.
See also
- Major Datasets
The major open robot datasets and what each collected.
- Foundation Models for Robotics
What foundation means in robotics, and what adaptation still costs.
- Cross-Embodiment Transfer
How one policy learns from many robot bodies and from humans.
Linked from
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- Cross-Embodiment Transfer
How one policy learns from many robot bodies and from humans.
- Foundation Models for Robotics
What foundation means in robotics, and what adaptation still costs.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Major Datasets
The major open robot datasets and what each collected.
- Teleoperation Rigs
ALOHA, GELLO, UMI and VR rigs compared on cost and quality.
- Competing Theses
Six bets on how robot intelligence gets built.
- The Bear Case
Why this could be another robotics winter.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
References
Tom B. Brown, Benjamin Mann, Nick Ryder, NeurIPS 2020.
https://arxiv.org/abs/2005.14165
Meta AI, 2024.
https://ai.meta.com/blog/meta-llama-3/
Guilherme Penedo, Hynek Kydlíček, Loubna Ben allal, Anton Lozhkov, Margaret Mitchell, Colin Raffel, and 2 more, NeurIPS 2024.
https://arxiv.org/abs/2406.17557
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
AgiBot-World-Contributors, Qingwen Bu, Jisong Cai, Li Chen, Xiuqi Cui, Yan Ding, and 46 more, 2025.
https://arxiv.org/abs/2503.06669
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Fanqi Lin, Yingdong Hu, Pingyue Sheng, Chuan Wen, Jiacheng You, Yang Gao, ICLR 2025, 2024.
https://arxiv.org/abs/2410.18647
Modi Shi, Li Chen, Jin Chen, Yuxiang Lu, Chiming Liu, Guanghui Ren, and 4 more, 2025.
https://arxiv.org/abs/2507.06219
Cheng Chi, Zhenjia Xu, Chuer Pan, Eric Cousineau, Benjamin Burchfiel, Siyuan Feng, and 2 more, 2024.
https://arxiv.org/abs/2402.10329
Ryan Hoque, Peide Huang, David J. Yoon, Mouli Sivapurapu, Jian Zhang, ICLR 2026, 2025.
https://arxiv.org/abs/2505.11709
Ruijie Zheng, Dantong Niu, Yuqi Xie, Jing Wang, Mengda Xu, Yunfan Jiang, and 9 more, 2026.
https://arxiv.org/abs/2602.16710
Kristen Grauman, Andrew Westbury, Eugene Byrne, CVPR 2022.
https://arxiv.org/abs/2110.07058
Tianyi Xie, Haotian Zhang, Jinhyung Park, Zi Wang, Bowen Wen, Jiefeng Li, and 14 more, 2026.
https://arxiv.org/abs/2606.05160
Kevin Lin, Ajay Mandlekar, Caelan Reed Garrett, Nikita Chernyadev, Yu Fang, Runyu Ding, and 4 more, 2026.
https://arxiv.org/abs/2605.27724
Zihan Wang, Zhen Wu, Pieter Abbeel, Rocky Duan, Jitendra Malik, Carmelo Sferrazza, and 3 more, CoRL 2026.
https://arxiv.org/abs/2609.38172
Youhui Wang, Yunzhu Li, Li Fei-Fei, Jiajun Wu, Huang Huang, 2026.
https://arxiv.org/abs/2609.35318
Suzannah Wistreich, Stephen Tian, Isabella Huang, Vitor Campagnolo Guizilini, Sergey Zakharov, Katherine Liu, and 1 more, 2026.
https://arxiv.org/abs/2610.07511
Jiahao Ji, Ji Ma, Runhan Zhang, Runyi Yu, Wenjia Wang, Weiheng Chi, and 9 more, 2026.
https://arxiv.org/abs/2608.16222
Meta, meta-llama/llama-models (GitHub), 2025.
https://github.com/meta-llama/llama-models/blob/main/models/llama4/MODEL_CARD.md
Xiaomi Robotics Team, Jun Guo, Piaopiao Jin, Jason Li, Peiyan Li, Yingyan Li, and 28 more, 2026.
https://arxiv.org/abs/2607.15330
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
An Yang, Anfeng Li, Baosong Yang, Beichen Zhang, Binyuan Hui, Bo Zheng, and 54 more, 2025.
https://arxiv.org/abs/2505.09388
Ken Goldberg, Science Robotics, 2025.
https://doi.org/10.1126/scirobotics.aea7390
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Jared Kaplan, Sam McCandlish, Tom Henighan, Tom B. Brown, Benjamin Chess, Rewon Child, and 4 more, 2020.
https://arxiv.org/abs/2001.08361
Sebastian Sartor, Neil Thompson, 2024.
https://arxiv.org/abs/2405.14005
Build AI, Hugging Face Datasets, 2025.
https://huggingface.co/datasets/builddotai/Egocentric-100K
Simar Kareer, Dhruv Patel, Ryan Punamiya, Pranay Mathur, Shuo Cheng, Chen Wang, and 2 more, 2024.
https://arxiv.org/abs/2410.24221
Generalist Team, Generalist AI blog, 2025.
https://generalistai.com/blog/gen-0
Sunday Team, Sunday Robotics blog, 2025.
https://www.sunday.ai/blog/no-robot-data
Figure AI, 2025.
https://www.figure.ai/news/project-go-big
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Abhiram Maddukuri, Zhenyu Jiang, Lawrence Yunliang Chen, Soroush Nasiriany, Yuqi Xie, Yu Fang, and 9 more, 2025.
https://arxiv.org/abs/2503.24361
Yang Tian, Yuyin Yang, Yiman Xie, Zetao Cai, Xu Shi, Ning Gao, and 10 more, 2025.
https://arxiv.org/abs/2511.16651
Sergey Levine, Learning and Control (Substack), 2025.
https://sergeylevine.substack.com/p/sporks-of-agi
Zhi Cao, Yining Hong, Jiaolong Yang, Yejin Choi, Li Fei-Fei, Jiajun Wu, and 1 more, 2026.
https://arxiv.org/abs/2610.19155
Botao He, Yiming Dou, Yiannis Aloimonos, Jitendra Malik, Akash Sharma, Ruoshi Liu, 2026.
https://arxiv.org/abs/2610.22340
Spot a factual error or missing qualification? Report a content correction.