Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
A generalist robot policy is one learned model trained to perform many tasks, often on several robot bodiesSource 13.
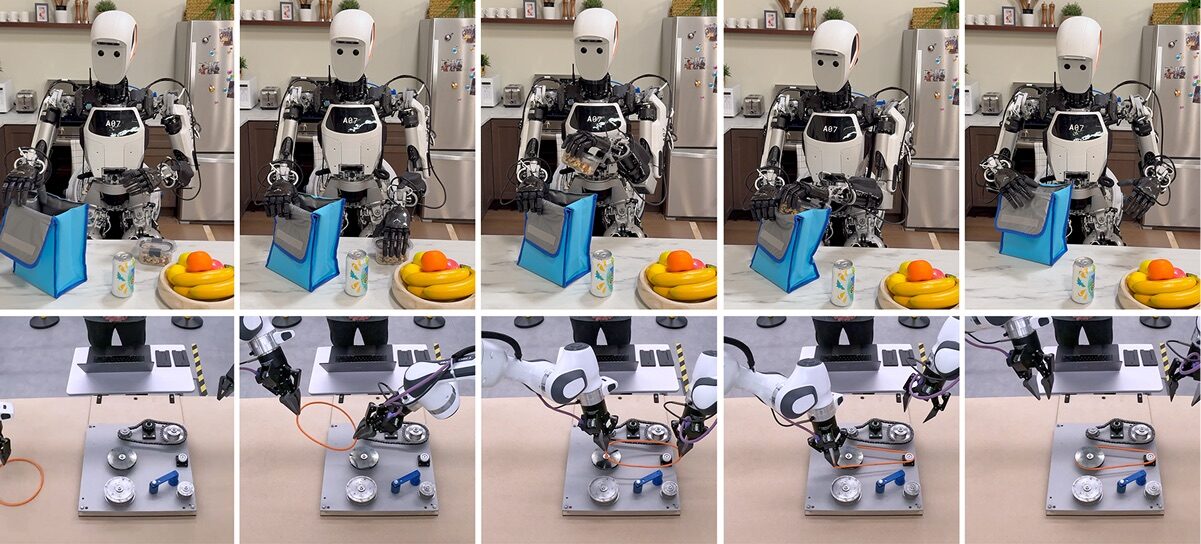
Outside the VLA line and Physical Intelligence's π models, the main 2026 lines are Google DeepMind's Gemini RoboticsSource 3, NVIDIA's GR00T, Figure's Helix, AgiBot's GO series, Skild AI and Generalist AI. Toggle "Downloadable only" to filter the timeline's 13 selected records, an authored selection.
Generalist policies
Thirteen robot brains since 2025; four you can download
Adjust more
13 of 13 shown
HelixFigureFeb 2025
Downloadable: not stated
The February 20, 2025 announcement identifies an open-weight VLM backbone, not a download or license for the trained Helix policy.
Figure reports S2 latent task representations and S1 control of wrist poses, fingers, torso and head orientation, plus task completion; S1 also consumes images and robot state.
Source: Figure AI 2025 (the maker's own report)
How this was made
A robot brain's trained model, often called its weights, is the file you would need to run it yourself. A filled circle means the maker reports a download of that trained model. A hollow circle is either not offered or not disclosed, and the two are kept apart in each card and in the table below; hollow does not mean closed licensing.
This is an authored selection of 13 records, not every generalist policy. Each sits at the month of its primary source; no days are invented. Source types: a paper (arXiv), repository release notes, a lab blog, or a press release. Blog and press entries are vendor-reported: the maker's own claims, with no outside check. Show source type in “Adjust more” draws each as its own shape.
| Model | Maker | Month | Weights | Source type |
|---|---|---|---|---|
| Helix | Figure | Feb 2025 | not disclosed | lab blog, vendor-reported |
| Gemini Robotics 1.0 | Google DeepMind | Mar 2025 | not downloadable | paper (arXiv) |
| GR00T N1 | NVIDIA | Mar 2025 | downloadable | paper (arXiv) |
| AgiBot GO-1 | AgiBot | Mar 2025 report | downloadable | paper (arXiv) |
| π0.5 | Physical Intelligence | Apr 2025 | downloadable | paper (arXiv) |
| Gemini Robotics 1.5 | Google DeepMind | Oct 2025 report | not disclosed | paper (arXiv) |
| π0.6 | Physical Intelligence | Nov 2025 | not downloadable | lab blog, vendor-reported |
| Helix 02 | Figure | Jan 2026 | not disclosed | lab blog, vendor-reported |
| Skild Brain | Skild AI | Jan 2026 announcement | not disclosed | press release, vendor-reported |
| GR00T N1.7 | NVIDIA | Apr 2026 | downloadable | repo release notes |
| AgiBot GO-2 | AgiBot | Apr 2026 HTML date | not disclosed | press release, vendor-reported |
| π0.7 | Physical Intelligence | Apr 2026 | not downloadable | lab blog, vendor-reported |
| Gemini Robotics 2 | Google DeepMind | Jul 2026 | not disclosed | lab blog, vendor-reported |
13 of 13 selected generalist policy records are shown; selected is Helix from Figure (not disclosed, lab blog, vendor-reported). Filled nodes have a reported download; hollow, dim nodes include unavailable and not-disclosed records, and dim nodes do not establish closed licensing.
Current generalist release
- selected
- Helix
- org
- Figure
- released
- Feb 2025
- weights
- not disclosed
- in full
- 13 of 13
Authored selection of 13 records; dates and download status follow each record's primary source.
Gemini Robotics
DeepMind's March 2025 report introduces a Gemini 2.0-based family: Gemini Robotics-ER for spatial and temporal understanding, and Gemini Robotics, which builds on ER to produce robot actionsSource 1. The launch post says Gemini Robotics more than doubles performance on a comprehensive generalization benchmark against other state-of-the-art VLAsSource 14.
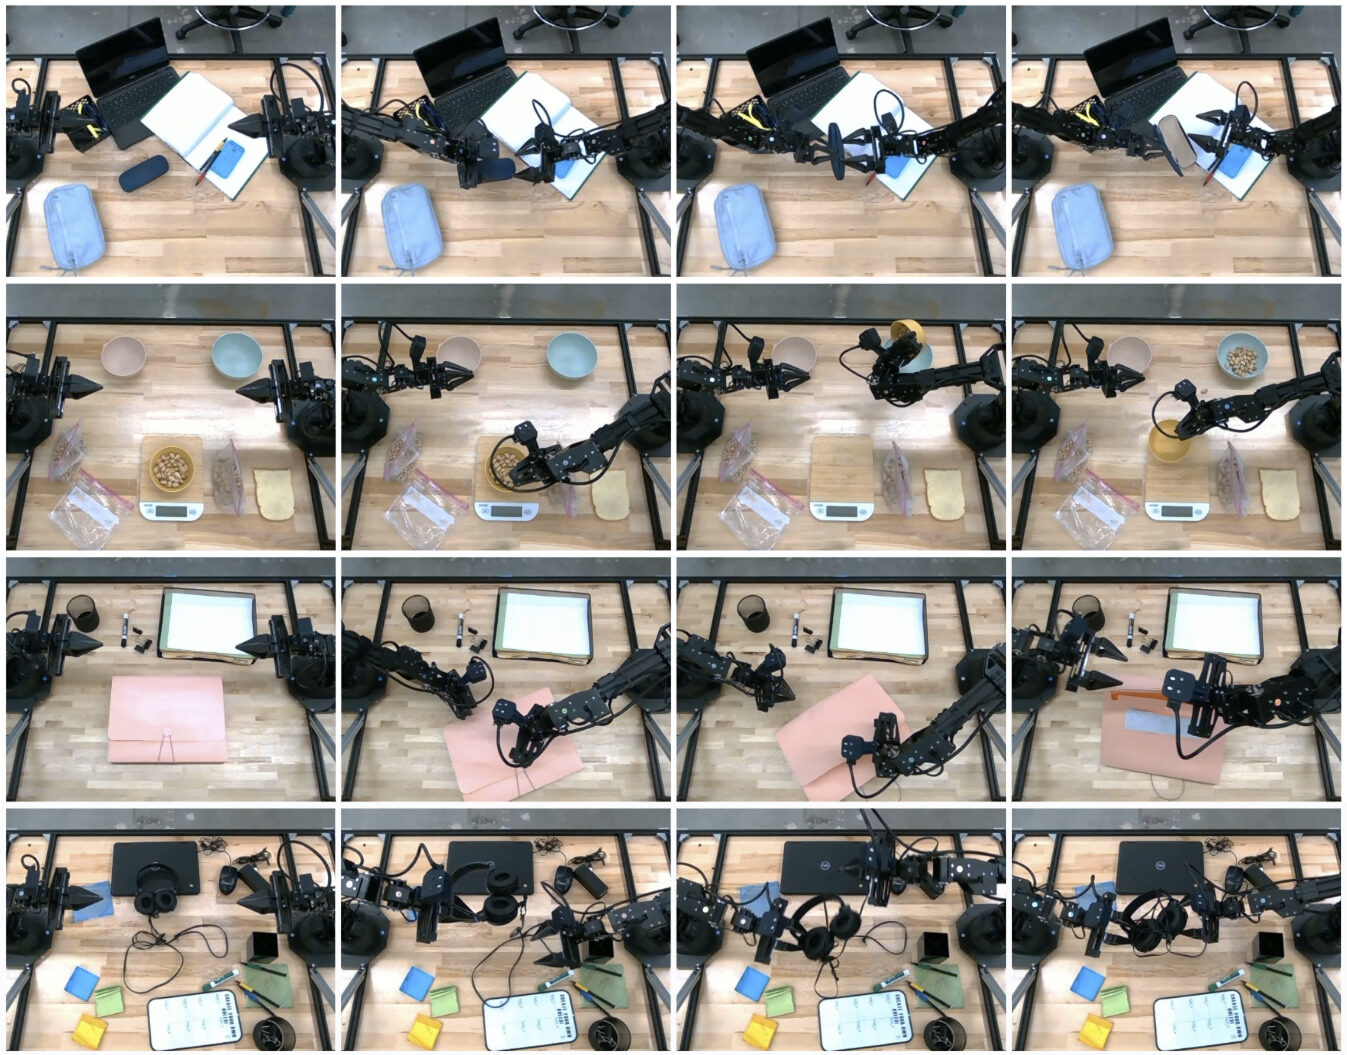
The 1.5 report, first submitted to arXiv on October 2, 2025, interleaves natural-language thinking with VLA actions, introduces Motion Transfer across embodiments and uses the separate GR-ER 1.5 model as an orchestratorSource 2. The launch post, dated September 25, 2025, made ER 1.5 available through the Gemini API and Gemini Robotics 1.5 to select partnersSource 15, after On-Device (June 2025) became the first DeepMind VLA offered for fine-tuning, to trusted testersSource 16.
On July 30, 2026, DeepMind announced Gemini Robotics 2 as three models: a VLA, the embodied-reasoning VLM ER 2, and On-Device 2 for local operation. Apollo 2 walks, crouches and stretches to manipulate objects, and one checkpoint runs Apollo 2 with 22-DoF SharpaWave hands or Inspire hands and Franka Duo with the Robotiq gripper; DeepMind says On-Device 2 adapts to new bi-arm embodiments in a few hours, typically with fewer than 200 examplesSource 3. The ER 2 post adds success detection on raw video feedsSource 17.
DeepMind's image alt text reports whole-body averages on Apollo with Inspire hands of 76.3% for picking from a shelf, 68.4% from a table and 45.7% from the floor. Single-task results on Apollo with Sharpa hands are 92% for unscrewing a bulb, 36% for screwing one in, 44% for tying a trash bag, 40% for Ziplock and 32% for Dustpan. Trial counts and error bars are unexplained, and DeepMind concludes that "the multi-finger dexterous manipulation remains challenging"Source 3.
The 1.5 model card specifies continuous numerical actions but no action-head family, chunk lengths, command rate or parameter countSource 2. The Gemini Robotics 2 announcement also omits them, the VLA went only to early-access partners, and weight and licence terms are undisclosedSource 3. DeepMind validates its Veo-based world-model policy simulator against more than 1,600 real trials of eight Gemini Robotics checkpointsSource 18.
GR00T: the open humanoid line
GR00T N1 (March 2025) couples a VLM backbone to a flow-matching diffusion-transformer action head and links the public GR00T-N1-2B checkpointSource 4. N1.5 freezes the VLM in pretraining and fine-tuningSource 19, and N1.6, which doubles the DiT to 32 layers, outperforms N1.5 in simulation and on real YAM, AgiBot Genie-1 and Unitree G1 robots, NVIDIA reportsSource 20.
The Isaac-GR00T repository lists N1.7 on April 18, 2026, with a Cosmos-Reason2-2B backbone, a 3B-parameter base checkpoint and relative end-effector actions shared by robot and human embodiments; pretraining adds 20K hours of EgoScale human videoSource 5, which the EgoScale paper puts at over 20,854 hoursSource 12. The README's licence section assigns Apache 2.0 to code and the NVIDIA Open Model License to weights, while its introduction calls N1.7 "fully commercially licensable under Apache 2.0"Source 5.
Figure Helix
Figure's February 20, 2025 Helix post pairs S2, an internet-pretrained VLM producing a latent task representation at 7 to 9 Hz, with S1, a visuomotor transformer that reads it with images and robot state at 200 Hz and outputs wrist, finger, torso and head targetsSource 6.
Figure's January 27, 2026 Helix 02 post adds S0, a 10M-parameter whole-body controller that outputs joint-level actuator commands at 1 kHz beneath S1's 200 Hz full-body joint targets. Figure says S0 trains entirely in simulation on over 1,000 hours of retargeted human motion and replaces 109,504 lines of hand-written C++, and describes its dishwasher demonstration as one continuous four-minute task with 61 loco-manipulation actions, no resets and no human interventionSource 7. Neither Helix post gives repeated-trial success tables or release terms for the trained policiesSource 6 Source 7.
Figure's August 25, 2026 Index announcement counts over 16M uploaded videos and commits over $1B over 12 months to data and computeSource 21, and Figure reports that Index pretraining, all else fixed, lifted Helix 2.5's zero-shot success in 30 unseen homes from 9% to 56%Source 22.
AgiBot: GO-1 and GO-2
The AgiBot World report (March 2025) introduces GO-1, whose latent action model learns from consecutive video frames, so training can include unlabeled human video alongside cross-embodiment robot dataSource 8. AgiBot presents GO-2 as closing a "Semantic-Actuation Gap": a lower-frequency System 2 generates structured action sequences, a higher-frequency System 1 combines them with live observations, and teacher forcing trains the executor to follow imperfect reasoning. The announcement gives only relative rates for the two modules and says the work was accepted at CVPR 2026 and ACL 2026Source 9.
AgiBot reports 98.5% average success across the four LIBERO suites, 86.6% zero-shot in LIBERO-Plus environments with disturbances, and 82.9% real-world success for a model trained only on simulation. It claims superiority over π0.5 and GR00T without trial counts, uncertainty, disturbance protocol or comparator versionsSource 9, and on LIBERO-Plus typical VLAs drop from 95% to below 30% under modest perturbationsSource 23.
Skild AI
Skild AI's January 14, 2026 Series C raised $1.4 billion at a valuation of over $14 billion. Skild calls its model "omni-bodied", names simulation and Internet video for pretraining and teleoperation and deployments for post-training, and says the model can control robots without prior knowledge of their body form. Architecture, parameter count, control rate, chunk horizon, benchmark protocol and weight terms are not givenSource 10.
A September 2025 post describes training on 100,000 simulated robotsSource 24. Skild presents S1 (August 18, 2026) as an in-context learner: shown a video of a task, it executes it, and on unseen long-horizon tasks of 4 to 8 minutes Skild reports 66% cumulative per-step success, against 9% for language promptingSource 25. The company also reports passing $100M in annual recurring revenueSource 26.
Generalist AI
Generalist AI says GEN-0 (November 2025) is pretrained on over 270,000 hours of real-world manipulation data, growing by 10,000 hours a weekSource 27. It reports that GEN-1 (April 2026), trained from scratch on half a million hours, reaches 99% average success on tasks where earlier models achieve 64%, with 1 hour of robot data per taskSource 28, and that GEN-1.5 (August 2026) learns a task in context from one 3 to 12 second demonstration, with 59% average one-shot success across 10 tasksSource 29.
Independent evaluation
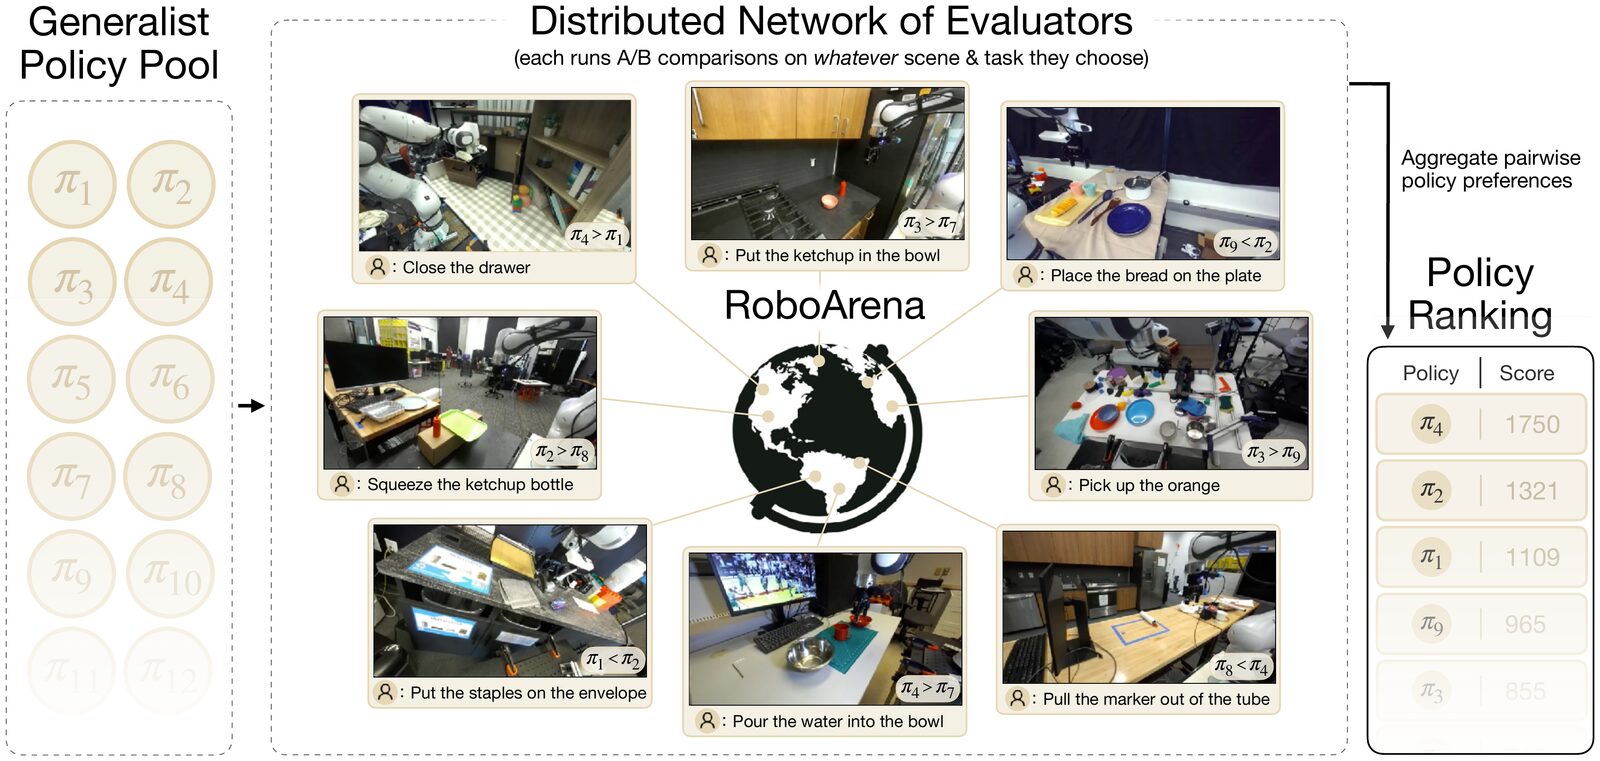
RoboArena ranks generalist policies through double-blind pairwise trials at seven institutions, with more than 600 real-robot episodes across seven policiesSource 30, and TRI evaluates its Large Behavior Models in blind, randomized trials with statistical confidenceSource 13.
Human-video transfer
Physical Intelligence and Georgia Tech co-fine-tune π0.5 on human data, with 3D hand positions as actions, and relevant robot data, and transfer improves with the quantity and diversity of robot pretrainingSource 11. EgoScale adds aligned human-robot mid-training and finds scale and alignment complementarySource 12. Cross-embodiment transfer compares them.
Steertuning, from Lerrel Pinto and colleagues at NYU (October 2026), pretrains a 400M-parameter diffusion policy on egocentric human video alone, then adapts it to a new task from 5 human demonstrations with 2 minutes of LoRA fine-tuning and steering toward the closest demonstration. On a mobile manipulator the authors report 71% average success over 12 new tasks, 9 in a rented home and 3 in their lab. On the lab tasks it succeeded in 25 of 30 trials, against 7 with steering alone and none with the short fine-tune aloneSource 31.
See also
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
Linked from
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Hierarchical Approaches
From SayCan and Code as Policies to the hierarchies in Helix and pi0.5.
- Foundation Models for Robotics
What foundation means in robotics, and what adaptation still costs.
- World Model Evaluation for Robotics
Testing a world model on what a robot needs.
- Major Datasets
The major open robot datasets and what each collected.
- The Reliability Gap
80% task success is a demo; 99.9% is a product.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
References
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Gemini Robotics Team, Abbas Abdolmaleki, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, and 167 more, 2025.
https://arxiv.org/abs/2510.03342
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Figure AI, 2025.
https://www.figure.ai/news/helix
AgiBot-World-Contributors, Qingwen Bu, Jisong Cai, Li Chen, Xiuqi Cui, Yan Ding, and 46 more, 2025.
https://arxiv.org/abs/2503.06669
AgiBot, 2026.
https://www.agibot.com/article/231/detail/56.html
Simar Kareer, Karl Pertsch, James Darpinian, Judy Hoffman, Danfei Xu, Sergey Levine, and 2 more, 2025.
https://www.pi.website/research/human_to_robot
Ruijie Zheng, Dantong Niu, Yuqi Xie, Jing Wang, Mengda Xu, Yunfan Jiang, and 9 more, 2026.
https://arxiv.org/abs/2602.16710
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Carolina Parada, Google DeepMind blog, 2025.
https://deepmind.google/blog/gemini-robotics-brings-ai-into-the-physical-world/
Carolina Parada, Google DeepMind blog, 2025.
https://deepmind.google/blog/gemini-robotics-15-brings-ai-agents-into-the-physical-world/
Carolina Parada, Google DeepMind blog, 2025.
https://deepmind.google/blog/gemini-robotics-on-device-brings-ai-to-local-robotic-devices/
Steven Hansen, The Keyword (blog.google), 2026.
https://blog.google/innovation-and-ai/models-and-research/google-deepmind/gemini-robotics-er-2/
Gemini Robotics Team, Krzysztof Choromanski, Coline Devin, Yilun Du, Debidatta Dwibedi, Ruiqi Gao, and 17 more, 2025.
https://arxiv.org/abs/2512.10675
Johan Bjorck, Valts Blukis, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 32 more, 2025.
https://research.nvidia.com/labs/gear/gr00t-n1_5/
GEAR Team, Allison Azzolini, Johan Bjorck, Valts Blukis, Fernando Castañeda, Rahul Chand, and 53 more, 2025.
https://research.nvidia.com/labs/gear/gr00t-n1_6/
Figure AI, Figure news, 2026.
https://www.figure.ai/news/introducing-index
Figure AI, Figure news, 2026.
https://www.figure.ai/news/helix-2-5-zero-shot-30-home-generalization
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Skild AI Team, Skild AI blog, 2025.
https://www.skild.ai/blogs/omni-bodied
Skild AI Team, Skild AI blog, 2026.
https://www.skild.ai/blogs/s1
Deepak Pathak, Abhinav Gupta, Skild AI blog, 2026.
https://www.skild.ai/blogs/skild-crosses-100m-arr
Generalist Team, Generalist AI blog, 2025.
https://generalistai.com/blog/gen-0
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1.5
Pranav Atreya, Karl Pertsch, Tony Lee, Moo Jin Kim, Arhan Jain, Artur Kuramshin, and 26 more, 2025.
https://arxiv.org/abs/2506.18123
Billy Yan, Isaac Tu, Kelly Lee, Blake Chang, Kenny Ma, Kanad Patel, and 5 more, 2026.
https://arxiv.org/abs/2610.18711
Further reading
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Physical Intelligence, 2025.
https://website.pi-asset.com/pi06star/PI06_model_card.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Laura Graesser, Peng Xu, Google DeepMind blog, 2026.
https://deepmind.google/blog/gemini-robotics-er-1-6/
NVIDIA, NVIDIA Newsroom, 2026.
https://nvidianews.nvidia.com/news/nvidia-and-global-robotics-leaders-take-physical-ai-to-the-real-world
Figure AI, 2025.
https://www.figure.ai/news/project-go-big
OpenDriveLab, GitHub, n.d.; accessed 2026-10-04.
https://github.com/OpenDriveLab/AgiBot-World
Linqing Zhong, Yi Liu, Yifei Wei, Ziyu Xiong, Maoqing Yao, Si Liu, and 1 more, CVPR 2026.
https://arxiv.org/abs/2601.11404
Skild AI Team, Skild AI blog, 2025.
https://www.skild.ai/blogs/building-the-general-purpose-robotic-brain
Spot a factual error or missing qualification? Report a content correction.