Hierarchical Approaches
From SayCan and Code as Policies to the hierarchies in Helix and pi0.5.
Hierarchical approaches are robot architectures in which one level decides what to do next and another decides how to move. In 2022 the high level was a separate planner choosing from a skill librarySource 1.
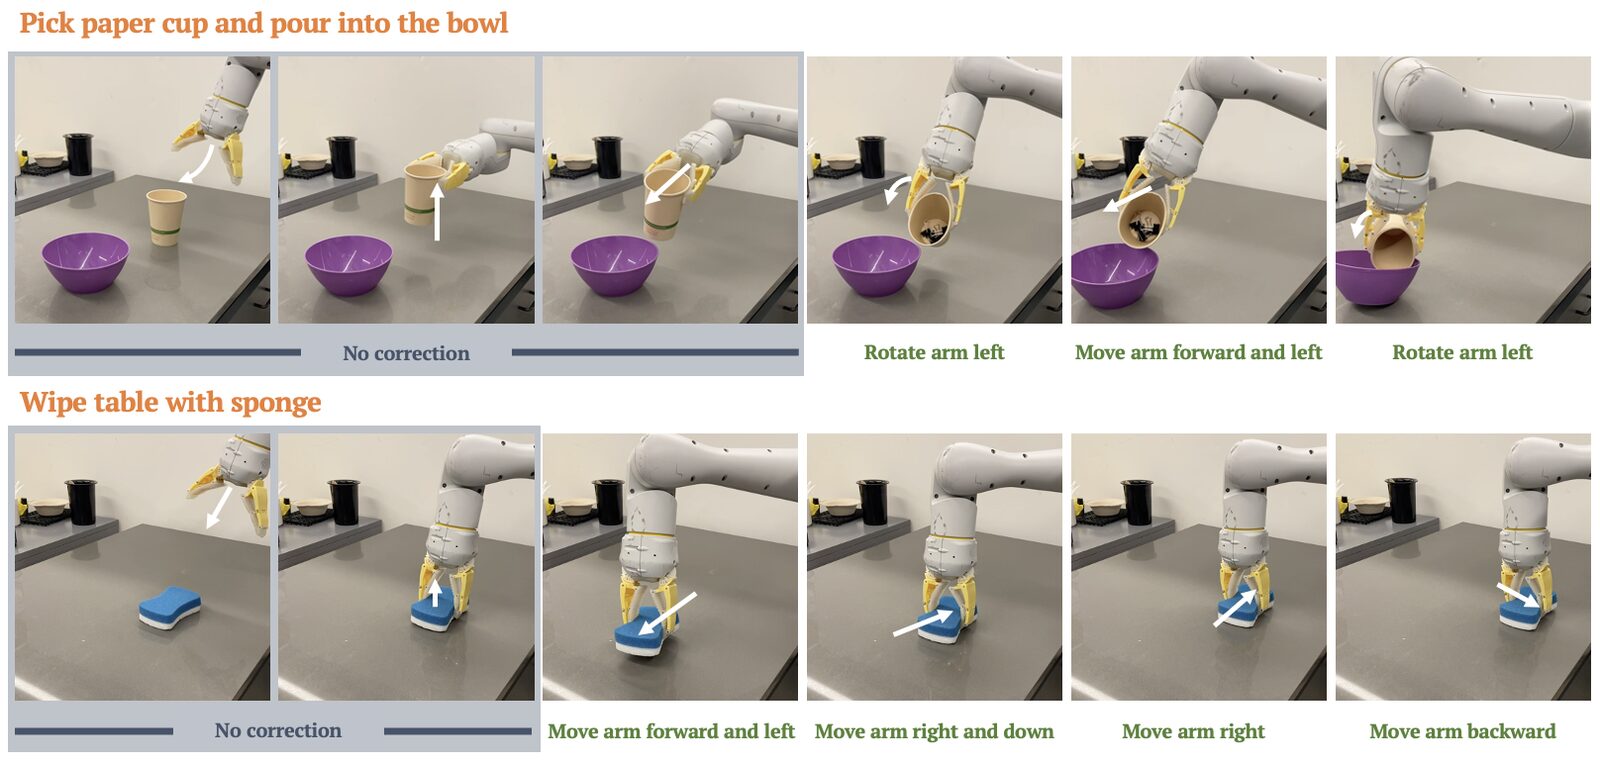
By 2026 the high level can run inside the policy network, as in π0.5Source 8, or as a separate orchestrator such as Gemini Robotics ER 2Source 15. Drag the playhead.
Hierarchical control
Slow decisions on top, fast motor commands underneath
Robot system
Adjust more
A full tick is an update fired; a short broken tick is an update pending, still ahead of the playhead.
- Task instructiononceSchematic1 update, last update: 0 ms
One task instruction at t=0 is the schematic starting condition, not a measured instruction-arrival rate.
- Subtask prediction~1 HzSchematic2 updates, last update: 2000 ms
High-level inference inside the same network emits the next language subtask. The paper states low frequency; the exact rate is not disclosed, 1 Hz shown schematically.
- Chunk inference1 chunk/sSchematic2 updates, last update: 2000 ms
The paper predicts 50 actions and reports 50 Hz target commands for its mobile-manipulator setup. It does not establish one chunk inference per second or how many predicted actions are executed. The 1 chunk/s cadence is schematic.
- Motor commands50 Hz100 updates, last update: 2000 ms
Paper-reported mobile-manipulator target poses and base velocities at 50 Hz, tracked by PD controllers; not an inference-throughput measurement.
π0.5 (Physical Intelligence): One model first writes the next step in words, then turns that step into arm and base moves.
Source: Physical Intelligence et al. 2025How this was made
Each row is one level of the robot's control hierarchy, slowest at the top, drawn on one 2-second clock. A tick marks an update: a new instruction, a new subtask, a new chunk of actions, a new motor command. π0.5 (Physical Intelligence): The same model performs high-level subtask inference and low-level action inference. High-level inference runs less frequently; the numerical inference periods shown here are schematic.
Some rates are stated by the source; the rest are drawn. A rate marked “Schematic” in “Adjust more” is a local drawing assumption, and so is the single task instruction at t = 0. The fastest lane, Motor commands at 50 Hz, ticks 50 times during one Subtask prediction update at ~1 Hz. A lane with more than 120 updates in the 2 seconds is drawn with evenly spaced ticks so the marks stay apart; its counts in “Adjust more” are the full ones.
π0.5 by Physical Intelligence at playhead 2000 ms of 2000 ms has 4 timescale lanes with 105 updates fired; the 50 Hz Motor commands lane ticks 50 times (schematic) during one Subtask prediction update at ~1 Hz (schematic).
Current timescale playhead
- system
- π0.5
- playhead
- 2000 ms
- lanes
- 4
- updates fired
- 105
Illustrative schedule: rates as the sources report them where stated, drawn elsewhere; one task instruction at the start.
2022
separate planners
SayCan, Code as Policies
2024
keypoint interfaces
MOKA, ReKep, RoboPoint
2025
learned hierarchies
Hi Robot, π0.5
2026
multi-rate stacks
Helix 02, GO-2, π0.7
SayCan: scoring usefulness and affordance
LLMs can break high-level tasks into mid-level plans zero-shot, but their steps often fail to map to admissible actionsSource 16. SayCan (2022) scores each skill in a supplied library twice: the LLM rates its description as the next step, and an affordance value estimates whether it can succeed in the current state. The product picks the skill to execute, its description is appended to the prompt, and the loop repeats until a termination option winsSource 1.
On the mobile manipulator, picking uses a multitask language-conditioned behavior-cloning policy, and RL-trained value functions, calibrated before use as probabilities, score skills without a separate model per skill. The skill library bounds the system, feedback reaches the planner only through the values at the current step, and the paper reports difficulty reacting when a skill fails despite a high valueSource 1.
Inner Monologue closed the loop with language feedback such as success detection and scene descriptionsSource 17, and Text2Motion checks geometric feasibility across whole skill sequences, solving 82% of long-horizon problems against 13% for earlier language plannersSource 18.
Code as Policies: the planner writes programs
Code as Policies (2022) prompts a code-writing LLM with example instruction-program pairs to generate Python that calls supplied perception and control APIs. Missing functions are generated recursively; programs can use loops, conditionals, spatial arithmetic and feedback over perception outputs. It assumes feasible instructions and cannot check correctness in advance. Its real robots lift ViLD or MDETR detections to 3D with depth and a pre-registered camera-to-robot transform, and many failures trace to inaccurate detections. Quantitative evaluation covers only a tabletop simulationSource 2.
VoxPoser's LLM-written code queries a VLM to compose 3D value maps, which a model-based planner turns into closed-loop trajectoriesSource 19.
In September 2026, several groups returned to code-writing planners with coding agents that test and repair their own programs. SimEX has the agent build a robot toolbox in simulation and correct the simulator from a few physical trials, and its authors report towel folding, barcode scanning and plate manipulation learned with no demonstrations and 10 minutes of real-robot interactionSource 14. RPG (UC Berkeley and Amazon FAR, October 2026) keeps the weights frozen and revises a symbolic skill library and its system prompt through practice in simulation; on held-out starts of 22 manipulation tasks, success rose from 28.6% to 95.0% after 15 rounds, and the frozen system succeeded in all 30 physical trialsSource 30.
RAX, from Yilun Du, Pieter Abbeel and colleagues at Harvard, UC Berkeley, NVIDIA, MIT and Stanford (October 2026), gives a coding agent no action demonstrations, hand-built action primitives or value functions and keeps its language-model weights fixed; the agent explores online and compiles what worked into control programs. Against the strongest prior learned policy on each of five simulation benchmarks, its mean margin is 37.4 points, from 7.9 on HumanoidArena, where the agent read three teleoperated demonstrations per task and the baselines trained on 100, to 53.4 on RoboDojo. On a real Franka FR3 and a Rainbow RB-Y1 mobile manipulator the agent received only the task text and the robots' tools. Across the paper's experiments, the agents' model calls used more than 100,000 US dollars of API creditsSource 33.
CoEvolve, led from Peking University and Renmin University of China (October 2026), has a multimodal model write the coordination code for two humanoids over frozen SONIC controllers; a verifier checks each executed step, and a rejected step is revised from an accepted checkpoint. With two simulated Unitree G1s carrying a freely supported 0.5 kg payload through corridors in MuJoCo, it finished 8 of 15 runs within an 80-transaction budget across three model backbones, while four adapted baselines given the same GPT-5.4-mini backbone, including CaP-Agent0 and ASPIRE, finished none of their five runs. The authors call these comparisons descriptive because runtime and continuation settings differ, and they report persistent limits in motion precision and contact stabilitySource 34.
The keypoint turn: VLMs emit geometry instead of skill names
MOKA marks candidate points with GroundedSAM masks and prompts a pretrained VLM to select grasp, function and target keypoints, waypoint regions and motion attributes. Calibrated depth from the perception pipeline lifts the points into the robot frame, and a separate grasp sampler and motion pipeline execute them, with no full 6-DoF object poseSource 3.
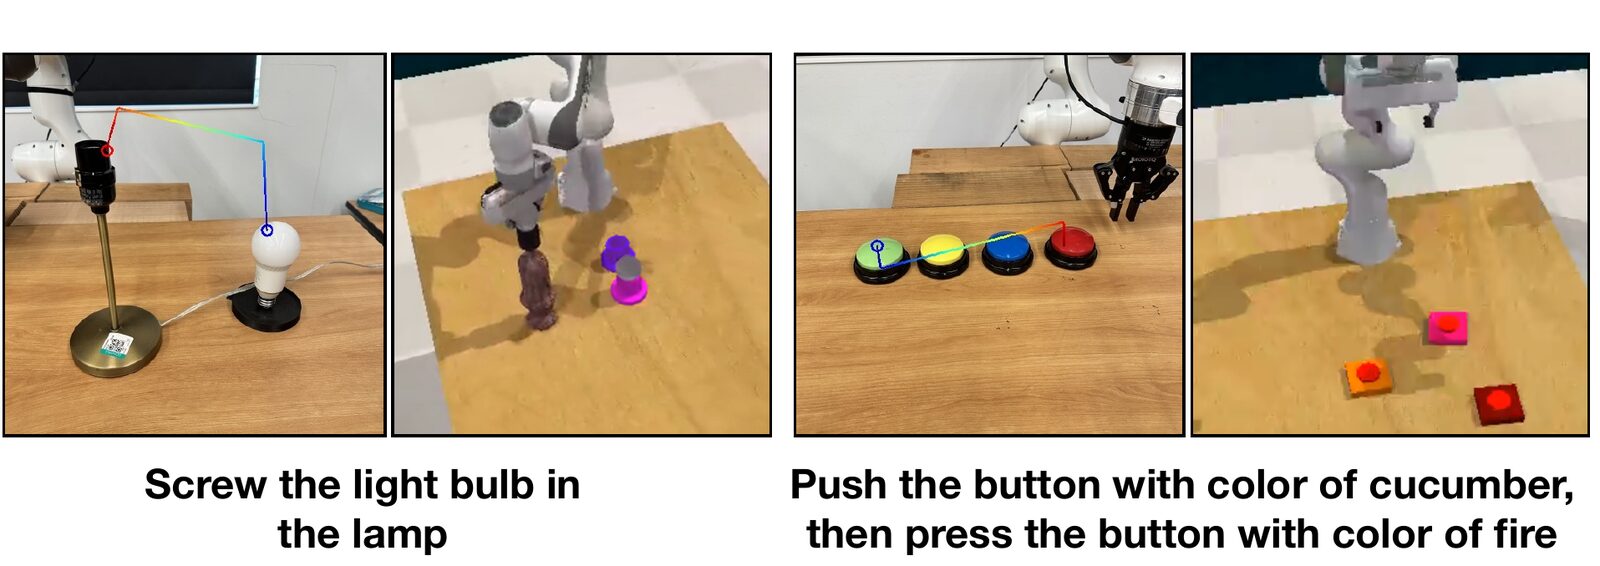
ReKep proposes keypoints from DINOv2 features within SAM masks and calibrated RGB-D. GPT-4o writes stage-wise Python sub-goal and path constraints over them, and a hierarchical solver replans end-effector motion while penalizing violations. Results rest on tracking and rigidity assumptions, and some evaluations use human annotations or disable trackingSource 4.
RoboPoint instruction-tunes a VLM to predict image-space affordance points, co-training synthetic object and free-space data with real-image VQA and LVIS detection data. On Where2Place's 100 real images it reaches 46.77% point-in-mask accuracy against 29.06% for GPT-4o, means of three runs. Its robot experiments add depth, an end-effector offset and a motion plannerSource 5.
Keypoints
An image point becomes a target only with its depth
100% of the reading
Every point on the lit string shows up at the ring in the imageDepth read · target on the handle
Schematic: an illustrative camera, image and toolbox
How this was made
A vision-language model that points answers in the image: MOKA has it pick marked grasp and target points, and RoboPoint predicts image points directly. A point in an image is not yet a place in the room. Every point on the line from the camera's centre through that pixel shows up at the same pixel, so the pixel alone fixes only the line. A calibrated depth reading picks the point on it: the target is the camera's centre plus the depth times the line's direction.
The frame is that geometry made of parts, after Dürer's drawing machine. The grid is the image; the ring is the model's point; the lit string runs from the lens through the ring. The depth camera beside the lens casts a faint beam to the first surface on that line, the toolbox's handle. Paid out to that depth, the string's bead, the arm's target, sits on the handle; paid out short, it hangs in the air, and the arm would close on nothing.
Schematic: the camera, the frame and the toolbox are illustrative, and no distance is claimed.
Point lifting as in MOKA (2024) and RoboPoint (2024).
HAMSTER fine-tunes a high-level VLM to draw a coarse 2D end-effector path, averaging a 20-point success gain over OpenVLA across seven generalization axesSource 20, and Gemini Robotics-ER predicts points, trajectories and graspsSource 21.
Reasoning before acting
ECoT trains a VLA to write a task plan, subtask reasoning, movement descriptions, object bounding boxes and the gripper's pixel position before its action tokens; its synthetic annotations reuse existing Bridge V2 data. Over 314 trials per approach it beats OpenVLA trained on the same data by 28 percentage points, 66% versus 44% in the in-distribution camera view and 64% versus 30% out of distribution, reported as means with one standard errorSource 6.
ECoT's main evaluation holds high-level reasoning fixed for five steps, and a separate variant predicts four future gripper positions, which the authors call an imperfect proxy for how the policy would behave; they name reasoning-token generation as a speed limitationSource 6.
RT-H predicts a fine-grained language motion and then actions conditioned on itSource 22, and CoT-VLA predicts future image frames as visual goals before a short action sequence, beating the best prior VLA by 17% on real tasksSource 23. In Toyota Research Institute's 2026 co-training study, though, conditioning actions on chain-of-thought traces did not improve performance in its simulation benchmarkSource 31.
Learned and orchestrated hierarchies, 2025 to 2026
Figure's Helix pairs a 7B VLM at 7 to 9 Hz with an 80M-parameter visuomotor policy at 200 Hz, trained end-to-endSource 24. GR00T N1 runs its VLM at 10 Hz and its action module at 120 HzSource 25, and Fast-in-Slow partially shares parameters between the two, reaching 117.7 Hz with eight-action chunksSource 26.
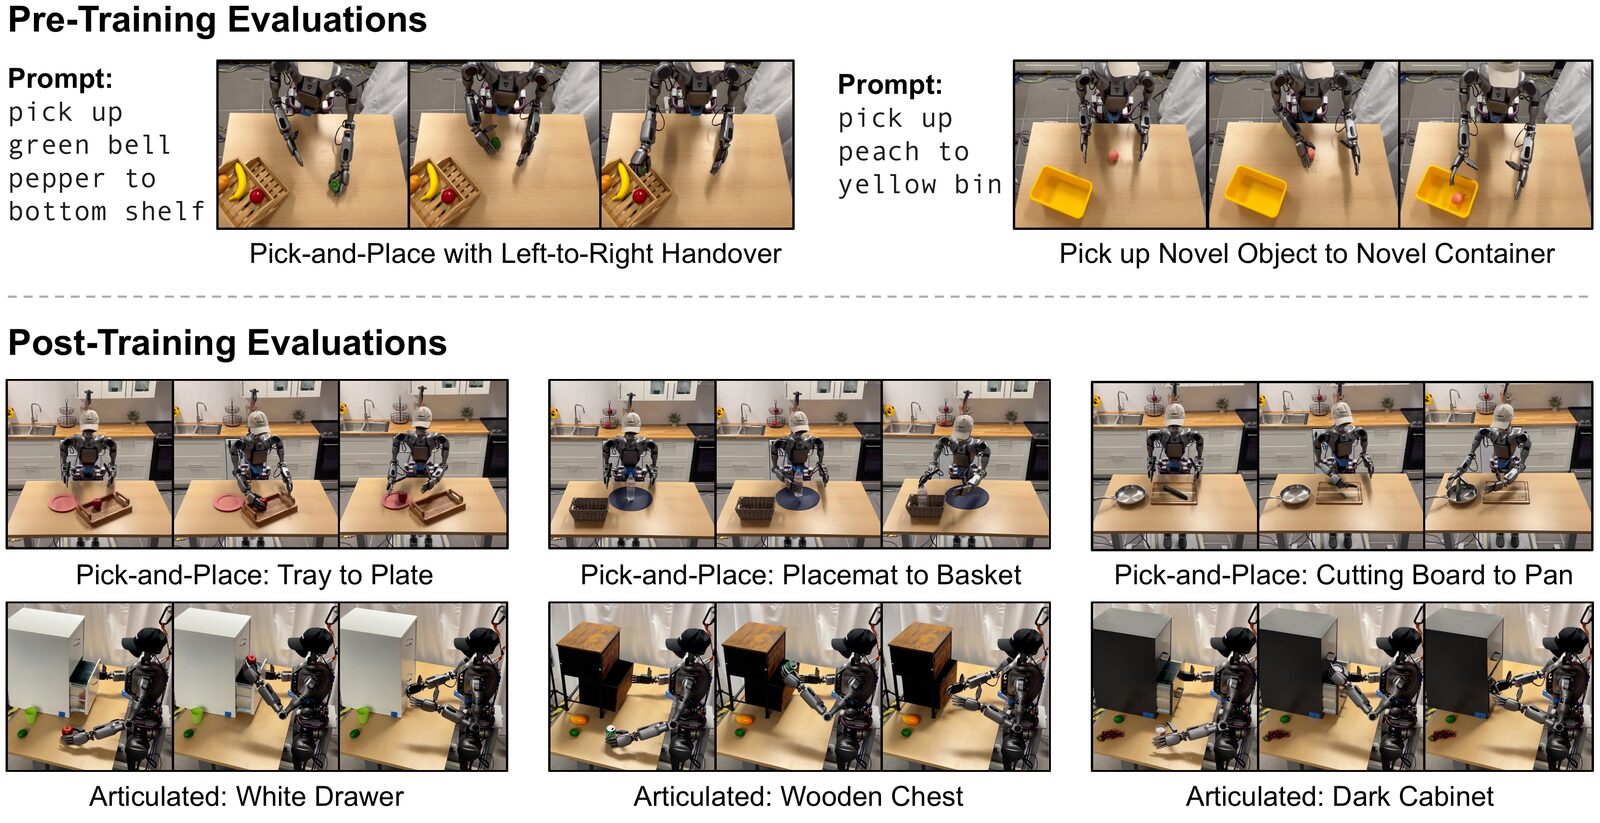
π0.5 co-trains on robot data, semantic subtask labels and multimodal web tasks. At inference the same model predicts a language subtask and then actions conditioned on it, running the high level less oftenSource 8.
Hi Robot trains two policies from PaliGemma: a high-level VLM that turns images and open-ended instructions into simpler language commands, and a low-level π0 VLA that also reads robot state. The high level reruns after one second or on new human feedback, and users can intervene by text or speech or return to the prior task. Training mixes human-labelled demonstrations with synthetic interactions, with one high-level policy per domain, across table bussing, sandwich making and grocery shopping, and the authors report missing high-level memory, low-level instruction violations and trouble recovering dropped objectsSource 7.
π0.7 can condition actions on subgoal images from a BAGEL-initialized world model; subtask and image generation run in separate threads, and the VLA uses the latest outputsSource 12. In π0.6-MEM, a high-level policy predicts the next language subtask and an updated memory summary, and the low-level policy acts on the subtask and a shorter observation historySource 13. VISTA's high-level world-model planner raises the same VLA from 14% to 69% in novel scenariosSource 27.
AgiBot describes GO-2 as a unified system with an asynchronous two-module hierarchy, a lower-frequency System 2 that generates action intents and a higher-frequency System 1 that combines them with observations, and gives no numerical ratesSource 11. Figure's Helix 02 adds S0, a 10M-parameter network that outputs actuator commands at 1 kHz, beneath S1's 200 Hz full-body joint targetsSource 10.
With thinking on, Gemini Robotics 1.5 appends natural-language reasoning before acting, and its agentic system adds a separate GR-ER 1.5 orchestrator whose useful thinking budget depends on the taskSource 9. In Gemini Robotics 2, DeepMind calls ER 2 the robot's high-level brain; it coordinates with the VLA and tracks multi-minute tasksSource 15.
Robo-COP (Stanford and NVIDIA, October 2026) updates the VLA under an orchestrator during deployment, adopting each fine-tuning update only after it improves the skills it was trained for. Across ten simulated RoboLab tasks, mean held-out success rose from 64.8% with a frozen policy to 73.8%, against 65.8% for fine-tuning on a fixed schedule, and from 38.3% to 50.0% on three real tasksSource 32.
The verdict
Both designs persist. In a controlled 2026 study on a real ALOHA, the best hierarchy placed 12 of 15 fruits, against 9 for a naive hierarchy and 3 for a flat VLASource 28. In-network hierarchy can fail too: in a waypoint pipeline adapted from π0.5, erasing waypoint endpoints barely changed success, and token-by-token planning took 57 VLM forward passes before the authors' fixes cut planning latency 8.7-foldSource 29.
See also
- Motion Planning
Configuration space, RRT and its variants, and trajectory optimization.
- Competing Theses
Six bets on how robot intelligence gets built.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
Linked from
- Humanoid Whole-Body Control
How humanoids track retargeted human motion.
- Perception for Manipulation
How camera images become an object's position and orientation.
- Competing Theses
Six bets on how robot intelligence gets built.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
- Surgical Robotics
From da Vinci to Hugo and OTTAVA, authorized one indication at a time.
References
Michael Ahn, Anthony Brohan, Noah Brown, Yevgen Chebotar, Omar Cortes, Byron David, and 39 more, 2022.
https://arxiv.org/abs/2204.01691
Jacky Liang, Wenlong Huang, Fei Xia, Peng Xu, Karol Hausman, Brian Ichter, and 2 more, ICRA 2023, 2022.
https://arxiv.org/abs/2209.07753
Fangchen Liu, Kuan Fang, Pieter Abbeel, Sergey Levine, 2024.
https://arxiv.org/abs/2403.03174
Wenlong Huang, Chen Wang, Yunzhu Li, Ruohan Zhang, Li Fei-Fei, 2024.
https://arxiv.org/abs/2409.01652
Wentao Yuan, Jiafei Duan, Valts Blukis, Wilbert Pumacay, Ranjay Krishna, Adithyavairavan Murali, and 2 more, 2024.
https://arxiv.org/abs/2406.10721
Michał Zawalski, William Chen, Karl Pertsch, Oier Mees, Chelsea Finn, Sergey Levine, CoRL 2024.
https://arxiv.org/abs/2407.08693
Lucy Xiaoyang Shi, Brian Ichter, Michael Equi, Liyiming Ke, Karl Pertsch, Quan Vuong, and 9 more, ICML 2025.
https://arxiv.org/abs/2502.19417
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Gemini Robotics Team, Abbas Abdolmaleki, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, and 167 more, 2025.
https://arxiv.org/abs/2510.03342
AgiBot, 2026.
https://www.agibot.com/article/231/detail/56.html
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Marcel Torne, Karl Pertsch, Homer Walke, Kyle Vedder, Suraj Nair, Brian Ichter, and 11 more, 2026.
https://www.pi.website/download/Mem.pdf
Jiaheng Hu, Roberto Martin-Martin, Peter Stone, Rocky Duan, Zhenyu Jiang, Guanya Shi, 2026.
https://arxiv.org/abs/2609.38982
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Wenlong Huang, Pieter Abbeel, Deepak Pathak, Igor Mordatch, 2022.
https://arxiv.org/abs/2201.07207
Wenlong Huang, Fei Xia, Ted Xiao, Harris Chan, Jacky Liang, Pete Florence, and 11 more, 2022.
https://arxiv.org/abs/2207.05608
Kevin Lin, Christopher Agia, Toki Migimatsu, Marco Pavone, Jeannette Bohg, 2023.
https://arxiv.org/abs/2303.12153
Wenlong Huang, Chen Wang, Ruohan Zhang, Yunzhu Li, Jiajun Wu, Li Fei-Fei, 2023.
https://arxiv.org/abs/2307.05973
Yi Li, Yuquan Deng, Jesse Zhang, Joel Jang, Marius Memmel, Raymond Yu, and 6 more, 2025.
https://arxiv.org/abs/2502.05485
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Suneel Belkhale, Tianli Ding, Ted Xiao, Pierre Sermanet, Quon Vuong, Jonathan Tompson, and 3 more, 2024.
https://arxiv.org/abs/2403.01823
Qingqing Zhao, Yao Lu, Moo Jin Kim, Zipeng Fu, Zhuoyang Zhang, Yecheng Wu, and 9 more, 2025.
https://arxiv.org/abs/2503.22020
Figure AI, 2025.
https://www.figure.ai/news/helix
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Hao Chen, Jiaming Liu, Chenyang Gu, Zhuoyang Liu, Renrui Zhang, Xiaoqi Li, and 5 more, 2025.
https://arxiv.org/abs/2506.01953
Qian Long, Yueze Wang, Jiaxi Song, Junbo Zhang, Peiyan Li, Wenxuan Wang, and 10 more, 2026.
https://arxiv.org/abs/2602.10983
Jiaheng Hu, Mohit Shridhar, Caden Lu, Dhruv Shah, Hao-Tien Lewis Chiang, Jie Tan, and 1 more, 2026.
https://arxiv.org/abs/2606.10267
Chuanliang Xie, Boyu Ma, Gen Li, Yizhou Liu, Houwang Chen, Xinyu Zhou, and 1 more, 2026.
https://arxiv.org/abs/2609.30833
Yen-Jen Wang, Haozhe Jiang, Shuying Deng, Haoru Xue, Weirui Ye, Rocky Duan, and 4 more, 2026.
https://arxiv.org/abs/2610.02204
Fanqi Lin, Kushal Arora, Jean Mercat, Haruki Nishimura, Paarth Shah, Chen Xu, and 6 more, 2026.
https://arxiv.org/abs/2602.01067
Xilun Zhang, Maggie Wang, Erik Bauer, Hong-Xing Yu, Huang Huang, Jiajun Wu, and 1 more, 2026.
https://arxiv.org/abs/2610.09228
Runhan Huang, Xiangcheng Zhang, Haoyu Chen, Yitong Li, Yen-Jen Wang, Bohan Lyu, and 14 more, 2026.
https://arxiv.org/abs/2610.22496
Zicheng Liu, Haochen Wu, Jiawei He, Suyun Zhao, Huan Yang, Cheng Chi, and 1 more, 2026.
https://arxiv.org/abs/2610.23288
Further reading
Zeyu Shen, Haoxiang You, Yilang Liu, Zhicheng Zheng, Lihan Zha, Kashu Yamazaki, and 13 more, 2026.
https://arxiv.org/abs/2609.27308
Shifeng Bao, Fanding Huang, Yihan Lin, Youhe Feng, Guanlin Li, Chen Zhao, and 4 more, 2026.
https://arxiv.org/abs/2609.37583
An-Chieh Cheng, Isabella Liu, Edmund Bu, Johan Bjorck, Hongxu Yin, Zhengyi Luo, and 4 more, 2026.
https://arxiv.org/abs/2609.39207
Jiayuan Gu, Sean Kirmani, Paul Wohlhart, Yao Lu, Montserrat Gonzalez Arenas, Kanishka Rao, and 11 more, 2023.
https://arxiv.org/abs/2311.01977
Huajie Tan, Enshen Zhou, Zhiyu Li, Yijie Xu, Yuheng Ji, Xiansheng Chen, and 29 more, 2026.
https://arxiv.org/abs/2601.14352
Jason Lee, Jiafei Duan, Haoquan Fang, Yuquan Deng, Shuo Liu, Boyang Li, and 13 more, 2025.
https://arxiv.org/abs/2508.07917
Kendra Byrne, Fei Xia, Google Developers Blog, 2025.
https://developers.googleblog.com/building-the-next-generation-of-physical-agents-with-gemini-robotics-er-15/
Steven Hansen, The Keyword (blog.google), 2026.
https://blog.google/innovation-and-ai/models-and-research/google-deepmind/gemini-robotics-er-2/
Wenli Xiao, Jia Xie, Tonghe Zhang, Haotian Lin, Letian Fu, Haoru Xue, and 11 more, 2026.
https://arxiv.org/abs/2606.19980
Saksham Singh, Zheyuan Hu, Max Sobol Mark, Jeffrey Yu, Zackory Erickson, Aviral Kumar, 2026.
https://arxiv.org/abs/2609.22085
Spot a factual error or missing qualification? Report a content correction.