Perception for Manipulation
How camera images become an object's position and orientation.
Perception for manipulation turns camera and depth data into object poses in the robot's own frame, through calibration, depth sensing, detection, segmentation and pose estimation, and grasp planning computes grasps against those poses. DOPE's pose network was accurate enough for a real robot to grasp known household objects in clutterSource 28.
An illustrative positioning budget
Try the transparent bottle under "Adjust more": the depth term then dominates the budget.
Camera alignment
A tiny camera tilt becomes a bigger miss farther away
Adjust more
The tilt's miss is one of three errors a robot stacks up before it grasps. The filled bars are those three, set by the controls above; the outlined bar is their root-sum-of-squares total. The dashed line marks the 15 mm model band, and hatching covers totals over 30 mm, above the model band.
composed 11.32 mm · depth term 10.00 mm at 2.0% · model band within model band
The opaque box case uses an authored depth floor of 2% of the fixed nominal range; it is not a measured property of that material. The slider is at or above that floor, so the slider is what the budget uses.
Slide the target away: the same tilt misses by more0.5 degrees at 0.50 metres · misses by 4.4 millimetres
Schematic: the tilt and the miss are drawn far larger than they are
How this was made
The drawing is the hand-eye term of the budget: a line of sight tilted by an angle θ from the true one misses by e = d · tan θ at distance d, about 1.7 mm at 10 cm and 17 mm at 1 m for one degree. At 0.5 degrees and 0.50 m the miss is 4.36 mm. The tilt runs from 0 to 3 degrees in steps of 0.1 and the distance from 0.15 to 1.5 m in steps of 0.05 m; both open at 0.5. The drawing is an optical bench: the camera tilts in a yoke, set by the micrometer under its tail, and its line of sight, the lit beam, lands on the scale of a target staff that slides along the rail. The peg on the staff sits on the rail's own line, where the robot assumes the camera looks. The miss is drawn 9 times steeper than the distance, so the drawn tilt is far larger than the real one; a miss above 32 mm passes over the staff's top.
The depth term here is modelled as range-independent, evaluated once at a fixed 0.5 m standoff, so the percentage you set converts to the same millimetres at every working distance. This authored simplification isolates the chosen ray-to-plane term; it does not describe how every real depth sensor changes with range. Root-sum-of-squares is an authored rule here: these slider values are not established standard deviations, and the instrument does not establish independence or a real-system error bound. The opaque-case floor borrows the ±2% Z-accuracy entry for D410/D415 and D43x at ranges up to 2 m, 80% ROI and HD resolution. The datasheet's factory KPIs reflect typical conditions; these active models use a texture-less white target, default 150 mW laser power and auto exposure. This is not an opaque-object measurement or a standard deviation Source 4. The model chooses multipliers 1, 3 and 8 for its opaque, specular and transparent cases; none is a measured material-specific floor. Its 15 mm and 30 mm bands are authored comparison thresholds, not predictions of grasp success or collision.
A camera's assumed line of sight is tilted 0.5 degrees from the true one; at 0.50 m the gap between them, the miss, is 4.36 mm, and at 1.5 m it is 13.09 mm.
Current camera tilt and miss
- tilt
- 0.5 deg
- distance
- 0.50 m
- miss
- 4.36 mm
At an authored angle of 0.5 degrees and axial distance 0.50 m, the model's root-sum-of-squares magnitude is 11.32 mm against its 15 mm comparison band. depth sensing contributes 78% of the sum of squared inputs. Model band: within model band.
Current authored budget and model band
- hand-eye
- 0.5 deg
- distance
- 0.50 m
- depth
- 2.0%
- pose
- 3.0 mm
- composed
- 11.32 mm
- model band
- within model band
The instrument combines authored hand-eye, depth and pose magnitudes by root-sum-of-squares, with depth fixed at a 0.5 m standoff and the hand-eye term growing with working distance up to 1.5 m. Its 15 mm and 30 mm bands are teaching thresholds: a 90 mm opening around a 60 mm part leaves mm per side, and one reported assembly task had only 0.5 mm contact clearanceSource 27.
2000
Zhang calibration
planar target; motion need not be known
1989
hand-eye solver
Tsai and Lenz solve the camera-to-gripper transform
1992
visual-servo formulation
Espiau, Chaumette and Rives; image-feature feedback
2023
promptable masks
SAM; SA-1B: 1.1 billion masks on 11 million images
Calibration: what a pixel means
A camera maps a 3D point onto a 2D sensor, and its intrinsics describe that mapping: focal length in pixels on each axis, the principal point and lens distortion. Zhang's 2000 method shows the camera a planar target at several unmeasured orientations. It models radial distortion and gives a closed-form solution followed by maximum-likelihood nonlinear refinement. Zhang contrasts it with classical techniques that need expensive equipment such as two or three orthogonal planesSource 1.
Hand-eye calibration: what a pixel means to the robot
Extrinsics place the camera relative to something else. Hand-eye calibration finds the flange-to-camera transform for a wrist camera, or base-to-camera for a fixed one. Shiu and Ahmad cast it as , where is a robot motion, the camera's observed motion of a static target and the unknown transformSource 29. Tsai and Lenz gave an efficient closed-form technique that solves rotation first, then translationSource 2.
Park and Martin derived closed-form exact and least-squares solutions with Lie theorySource 30. OpenCV's hand-eye calibration defaults to the Tsai and Lenz method, needs at least two motions with non-parallel rotation axes, so three poses, and strongly recommends many moreSource 31.
Tsai and Lenz's error analysis shows the lever arm: a 3 mrad rotation error at a 5 in camera-to-target distance gives a 15 mil translation errorSource 2. The instrument's hand-eye term is a ray-to-plane offset at separation for a ray inclined by to the plane's normal, about 1.7 mm at 10 cm and 17 mm at 1 m for one degree:
Depth sensing: what fails, and on what
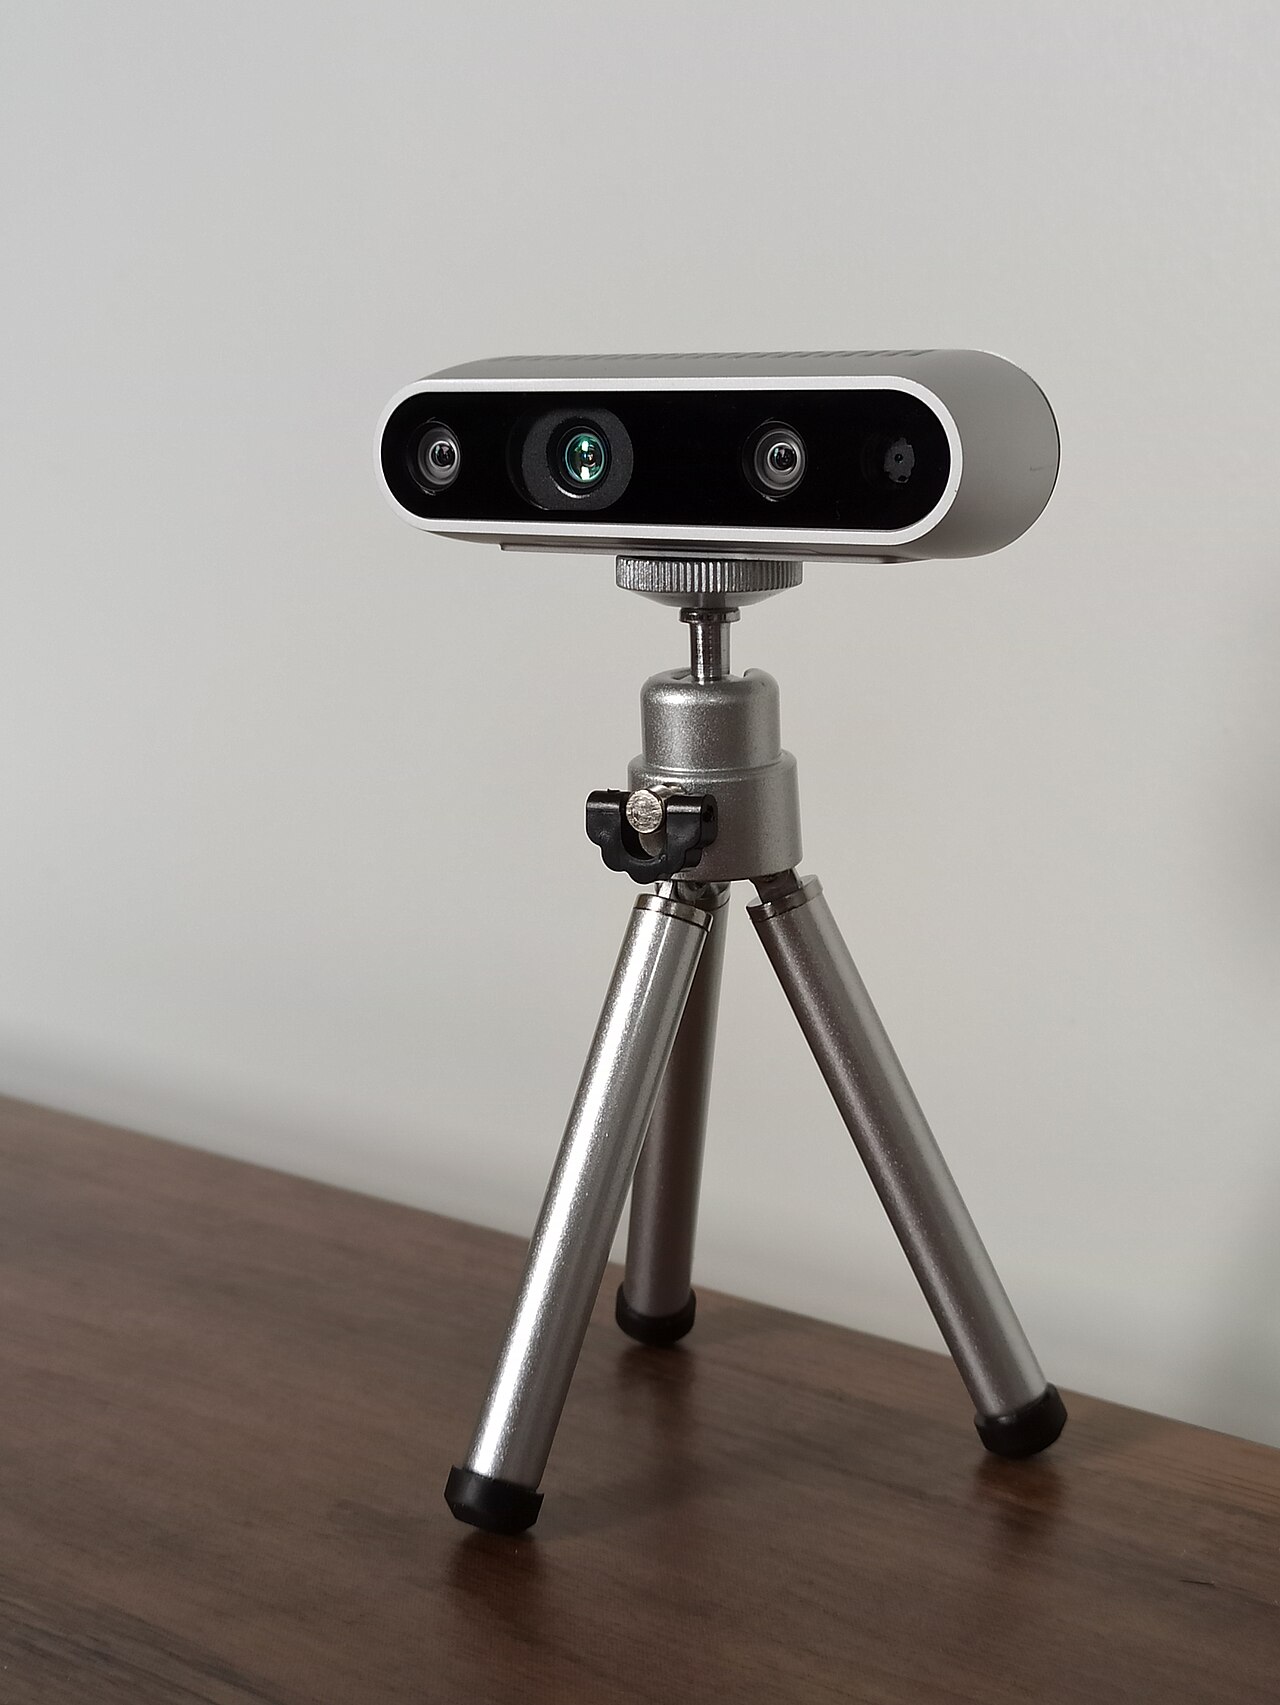
Stereo triangulates features matched between two images, so a featureless surface gives it nothing to match. Intel's RGBD depth cameras add an active texture projector to make matching unambiguousSource 3.
The March 2026 RealSense D400 datasheet lists ±2% Z-accuracy up to 2 m for D410/D415 and D43x over an 80% region of interest at HD resolution. Accuracy compares valid pixels with ground truth over 80% of the depth field of view, and factory KPIs reflect typical conditions; these models are tested on a texture-less white target at the default 150 mW laser power and auto exposureSource 4.
RealSense's D415/D435 tuning guide says D400 depth error scales with the square of distance. It advises moving closer while staying outside the minimum operating distance, MinZ. It describes resolution and range trade-offs when changing MinZ, and notes that focus and differing left and right views limit very-near matchingSource 5.
Learned models now estimate depth from images, alone or with a sparse sensor: Depth Pro predicts metric monocular depth without camera intrinsics, a 2.25-megapixel map in 0.3 seconds on a standard GPUSource 33.
For industrial 3D scanning, the PhoXi 3D Scanner L page lists 0.200 mm calibration accuracy and 0.190 mm temporal noise (both 1 σ), an 870 to 2150 mm scanning range and 250 to 2750 ms scanning time. These are separate specification fields for one modelSource 7.
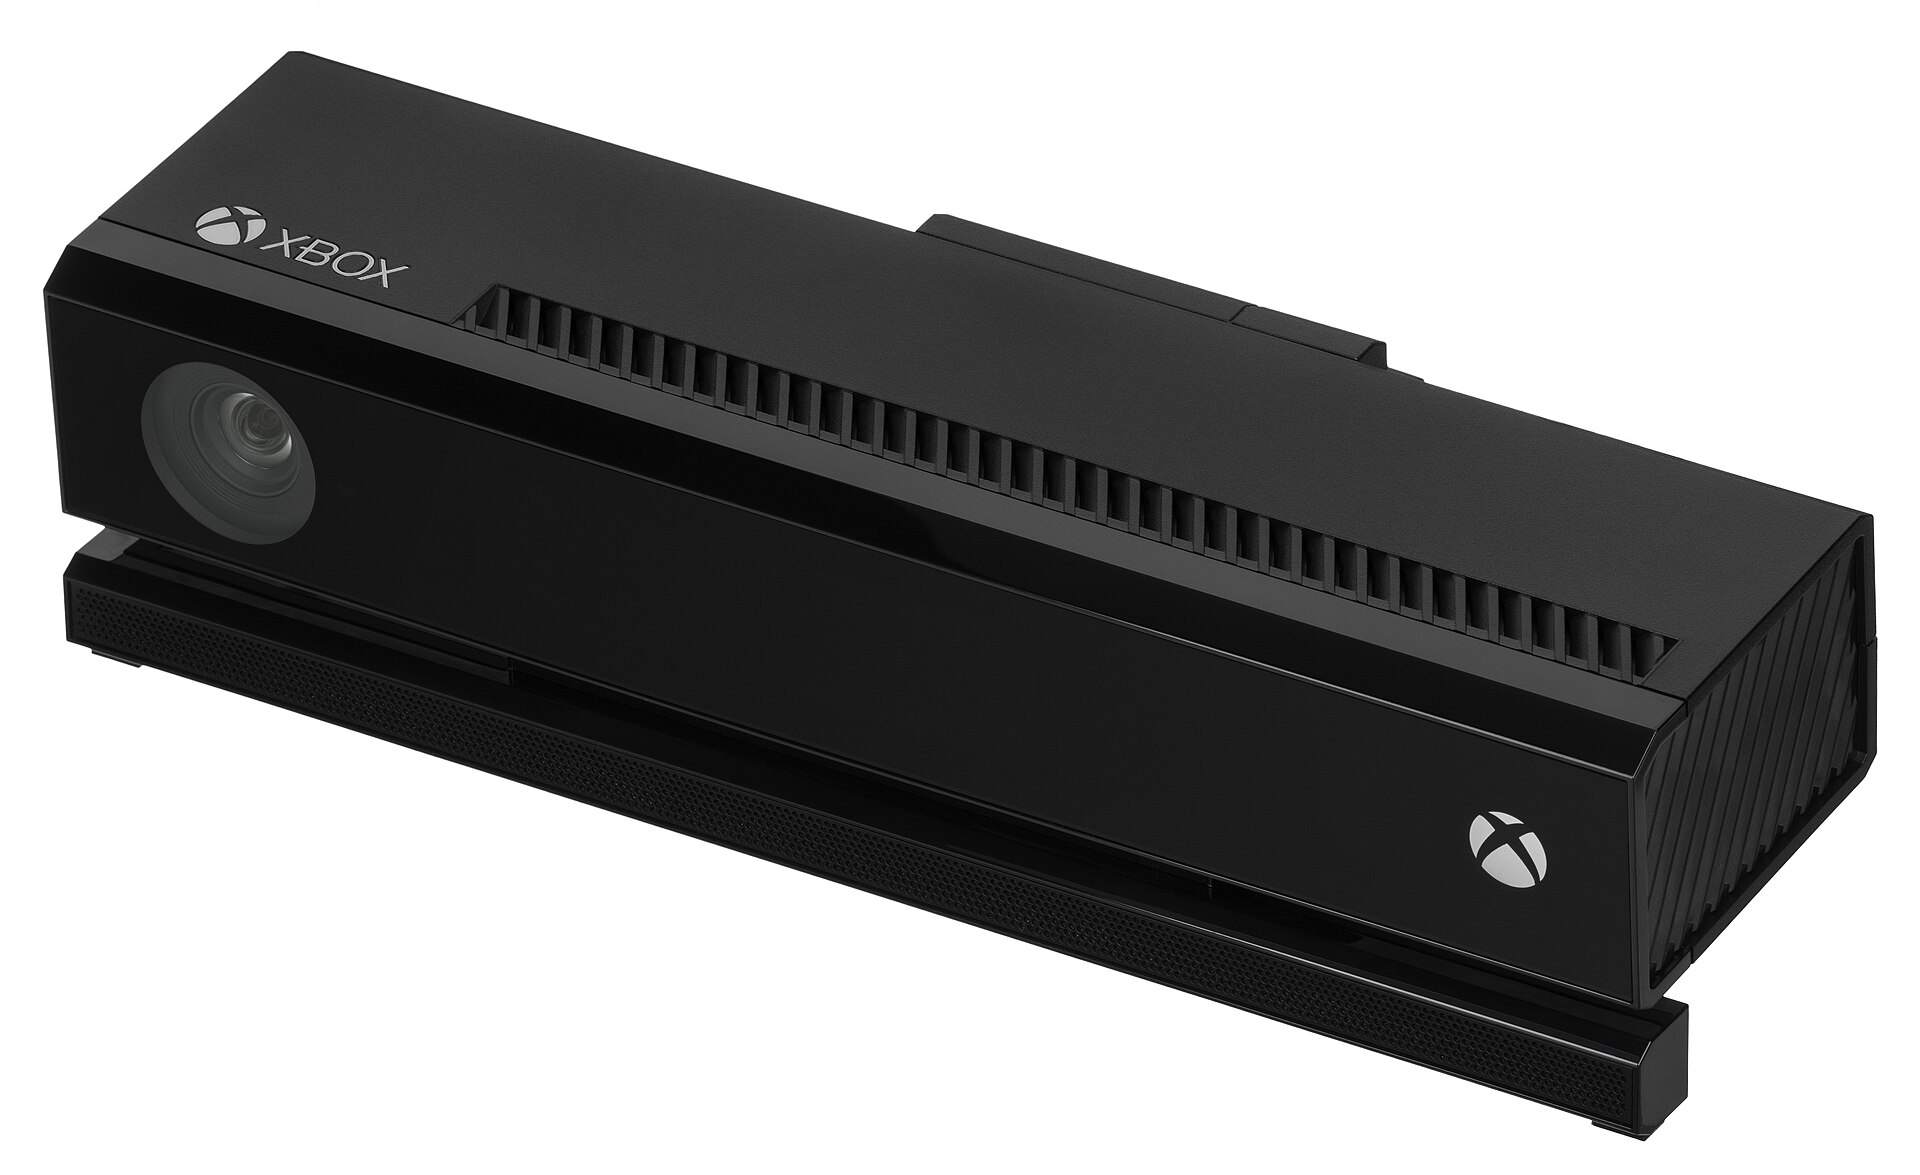
Time of flight casts its own modulated near-infrared light and measures its round trip per pixel. Multi-path interference lets one pixel integrate light that arrived by several routes. The Azure Kinect DK documentation lists five causes of invalid depth: outside the IR illumination mask, saturated IR signal, low IR signal, filter outlier and multi-path interference. Invalid pixels carry depth zero. Ambiguous depth arises when light reflects from one wall onto another in a corner, and where foreground and background mix at object edges. Fast motion can increase edge invalidationSource 6. Microsoft announced the end of Azure Kinect DK production in August 2023, and support for its Sensor SDK ended in August 2024Source 44.
The failure taxonomy that decides how a cell is built
- ClearGrasp starts from the observation that transparent objects "often appear as noisy or distorted approximations of the surfaces that lie behind them". It infers surface normals, transparent-surface masks and occlusion boundaries, then replaces the returned depthSource 8.
- Specular reflections can saturate D400 images, and the D400f column says "Saturation mitigated"Source 4. Azure Kinect invalidates saturated IR pixelsSource 6.
- Dark surfaces and low light weaken the signal. Azure Kinect invalidates a pixel whose IR signal is too weak to generate depthSource 6. RealSense ties D4xx depth quality to the input images and warns of grainy low-light images, underexposure and overexposure. For its projected-pattern example, reducing background light with the projector on can raise the pattern's signal-to-noise ratioSource 5.
- RealSense names fences and wire grids as scenes where left-right correspondence can become ambiguous. Its D4 processor compares the best and second-best match scores, and raising DSSecondPeakThreshold rejects more matches as zero depthSource 5.
- Azure Kinect notes that a surface invalidated by multi-path from one camera view can reappear from anotherSource 6.
The 2% figure is measured on a texture-less white target with the projector at default powerSource 4, and the PhoXi page publishes no target condition for its 0.200 mm figureSource 7. Accuracy for transparent or specular surfaces is not disclosed in either datasheet.
Depth yields a point cloud, an unordered set that a network must process without depending on input order. PointNet uses a shared per-point encoder and a symmetric pooling functionSource 13. PointNet++ applies PointNet within radius neighbourhoods around sampled centroids, in coordinates relative to each centroid, building local features at growing scales. Density-adaptive variants combine scales where small neighbourhoods hold too few samplesSource 14.
Detection: from pixels to candidate objects
Classical detectors return boxes over a class list fixed at training time. Mask R-CNN extends Faster R-CNN with a branch that predicts an object mask in parallel with box recognitionSource 34.
Open-vocabulary detection removes the fixed list. Grounding DINO adds language-vision fusion to the DINO detector's feature enhancer, query selection and decoder and accepts category names or referring expressions. It performs weakly on referring expressions without REC training data. Its Swin-L model reports 52.5 AP on COCO 2017 validation after pretraining on O365, OpenImage and GoldG without COCO training imagesSource 9.
DINOv2 learns image and patch features by self-supervised pretraining on the curated LVD-142M dataset. Its transfer evaluations freeze the encoder and train linear heads for classification and segmentation, and linear or DPT heads for depthSource 10.
Segmentation: the grounding layer
A box around a mug also contains the table behind it, so a grasp planner needs the surface region that per-pixel labelling provides. Segment Anything (SAM, 2023) makes segmentation promptable; its default ViT-H model was trained on SA-1B, reported as 1.1 billion automatically generated masks on 11 million images. Point, box and mask prompts condition the decoder, and an ambiguous point can return several candidate masks for a part or a whole object. Fine structures and boundaries remain failure cases, and the heavy image encoder prevents overall real-time performanceSource 11.
SAM 2 extends prompting to video with a streaming memory of earlier predictions and prompted frames. Objects are inferred independently, and failures persist after shot changes or long occlusions, in crowded scenes and on thin, fast-moving detailsSource 12.
Grounded SAM feeds Grounding DINO's open-set boxes to SAMSource 35, and CNOS segments unseen objects by matching DINOv2 descriptors of SAM proposals against references built from CAD modelsSource 36.
Promptable segmentation supplies object masks to MOKA and ReKep, two keypoint interfaces with different perception stacks. MOKA proposes marked candidate points from GroundedSAM masks, then prompts a pretrained VLM to select grasp, function and target keypoints, waypoint regions and motion attributes. Calibrated depth lifts the points into the robot frame, and a separate grasp sampler and motion pipeline produce actions; the prompted method trains no robot policySource 24.
ReKep proposes semantic keypoints from DINOv2 features within SAM masks and calibrated RGB-D geometry. A large vision-language model writes Python sub-goal and path constraints from a marked image and an instruction, and a solver repeatedly plans end-effector motion from tracked keypoints. The solver penalizes constraint violations without guaranteeing physical feasibility, and rigidity assumptions and tracking failures remain limitations. Some evaluations use human annotations or disable trackingSource 25.
RoboPoint instruction-tunes a VLM to predict image-space affordance points from synthetic object and free-space data mixed with real-image VQA and LVIS detection data. It needs no external detector at test time, though its robot pipeline adds depth, an end-effector offset and a motion plannerSource 26.
Dense Object Nets learns a descriptor for each RGB pixel, self-supervised by matches from static RGB-D reconstructions, and demonstrates correspondence across viewpoints and moderately deformable configurations. Class-consistent training generalizes across sufficiently similar hats, shoes and mugs, while instance-specific training distinguishes objects; for grasping, the gripper's 6-DoF orientation needs further informationSource 15.
6-DoF pose estimation, and how to read a claim about it
Pose estimation turns a mask into a rigid body with a position and orientation, and methods divide by what they assume about the object. Instance-level methods train on specific objects: PoseCNN localizes each object's centre, predicts its distance and regresses a rotation quaternion, with a loss that handles symmetric objectsSource 16. DOPE, trained only on synthetic domain-randomized and photorealistic data, performs competitively with a network trained on real and synthetic dataSource 28.
Category-level methods such as NOCS estimate the pose and size of unseen instances in known categories with no exact CAD model at training or test timeSource 37. Novel-object methods drop per-object training. MegaPose uses render-and-compare against a CAD model supplied at test timeSource 18, and FoundationPose works from a CAD model or a few reference images and reports results comparable to instance-level methodsSource 17.
To read a pose result, check its evaluation protocol. Hinterstoisser and colleagues evaluate a model with ground-truth pose and estimate by averaging distances between corresponding transformed model pointsSource 20:
An estimate is correct when , where is the model's diameter and a chosen coefficient; their LINEMOD evaluation uses Source 20. For the symmetry-aware pose error, each ground-truth-transformed point is matched to its nearest estimated-pose point before averagingSource 20:
They apply this rule to objects that are ambiguous, or look ambiguous from some views, naming "cup", "bowl", "box" and "glue"Source 20.
The BOP Challenge 2023 report scores 6-DoF localization differently: each dataset score averages the VSD, MSSD and MSPD recalls, each over several thresholds with a strict test , and averages seven core datasets (LM-O, T-LESS, ITODD, HB, YCB-V, TUD-L, IC-BIN) on a 0 to 100 scale. Seen and unseen tracks share the method, with object identities and instance counts supplied at test time, and the 2D-detection averages over objects firstSource 19.
From 2017 to 2023, seen-object accuracy rose from 56.9 to 85.6 , a relative gain of over 50 percent. The endpoints are Vidal's point-pair-feature method with ICP and no training images, and GPose2023 with object-specific networks trained on PBR and real imagesSource 19.
For unseen objects, GenFlow-MultiHypo16 led 2023's Task 4 with 67.4 , against 69.8 for the best 2020 seen-object entry, CosyPose, and the report calls these comparable across distinct tracks; average image times were 34.58 and 13.74 seconds on unmatched hardware. Task 4 still supplies mesh models for onboarding, capped at 5 minutes per object on one GPU with no real images of the objects, and GenFlow fails under heavy occlusionSource 19.
In the BOP 2024 report, the best unseen-object method, FreeZeV2.1, is 22% more accurate on BOP-Classic-Core than GenFlow and 4% behind GPose2023, but takes 24.9 against 2.7 seconds per image, and the report names 2D detection as the main bottleneck for unseen objectsSource 38.
Visual servoing: image-based and position-based control
Visual servoing uses vision inside the control loop, and Hutchinson, Hager and Corke's 1996 tutorial divides such systems into position-based and image-based classesSource 39. Espiau, Chaumette and Rives's 1992 paper applies a task-function framework to image-based control, with a task function designed for regulation that need not be the raw feature difference. Its interaction matrix relates feature rates to the camera's translational and rotational velocity in the camera frame. Convergence depends on task and model conditions, and neglecting target motion can leave a tracking errorSource 21.
For a fixed goal and motionless target, Chaumette and Hutchinson's Part I writes , with the camera's six-component spatial velocity. Image-based visual servoing (IBVS) uses image features, and position-based visual servoing (PBVS) uses estimated pose. The IBVS point-feature interaction matrix still uses depth and camera intrinsics, estimated from current depths or depths at the desired poseSource 22.
Redundant-feature IBVS is locally asymptotically stable when the interaction matrices have full rank and the estimated pseudoinverse times the true matrix meets a positivity condition; coarse estimates can change the camera path, while poor ones can make the system unstable. Large displacements can meet local minima or singularities, PBVS points can leave the field of view, and in PBVS pose-estimation errors affect final accuracySource 22.
Part II (2007) adds switching and planning methods that address visibility, occlusions and joint limits, for eye-in-hand and eye-to-hand systemsSource 23. Bateux and colleagues fine-tuned a CNN to estimate the relative pose between current and desired images and kept a pose-based control lawSource 40.
Learned servoing can also aim the camera. EyeRobot 2.0, from Ken Goldberg (UC Berkeley) and colleagues (October 2026), swivels the two eye viewpoints of a single stereo camera to fixate a 3D point, with a gaze-servoing policy and a fixation selector both trained with RL on real data. It beat passive stereo by 40% in real trials and, when a grasped object hid the wrist views, more than doubled the success of policies that had them, 48% against 22%Source 43.
Separate model error from geometric error
Hand-eye accuracy depends on noise and motion range, so Enebuse and colleagues advise accounting for both when benchmarking or calibratingSource 32. A detector can keep stable image coordinates while the robot misses because the camera transform drifted, so each stage is checked in its own output first. The calibration guide defines the checks to rerun after a camera remount, and the ROS 2 guide shows where images, transforms and timestamps meet at runtime.
What the end-to-end models replaced
End-to-end vision-language-action (VLA) policies absorb the explicit pipeline into weights. Gemini Robotics is a VLA model that controls robots directly, built on an embodied-reasoning model that can detect objects, point, and predict trajectories, grasps and 3D bounding boxesSource 41. Such a policy needs no detector class or CAD model for a new object, and it has no hand-eye residual to re-solve when it misses a grasp by 8 mm.
Some frontier systems keep geometric intermediates explicit, as the keypoint interfaces did while a learned model produced the geometry: MolmoAct encodes observations into depth-aware perception tokens and generates editable trajectory traces before predicting low-level actionsSource 42.
See also
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Hardware Taxonomy
A buyer's guide from SO-101 to Jetson Thor.
Linked from
- Hierarchical Approaches
From SayCan and Code as Policies to the hierarchies in Helix and pi0.5.
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
References
Z. Zhang, IEEE Trans. Pattern Analysis and Machine Intelligence, 2000.
https://doi.org/10.1109/34.888718
R. Y. Tsai, R. K. Lenz, IEEE Trans. Robotics and Automation, 1989.
https://doi.org/10.1109/70.34770
Leonid Keselman, John Iselin Woodfill, Anders Grunnet-Jepsen, Achintya Bhowmik, CVPR Workshops 2017.
https://doi.org/10.1109/CVPRW.2017.167
RealSense, RealSense, as of 2026-08-22.
https://www.realsenseai.com/wp-content/uploads/2026/03/RealSense-D400-Series-Datasheet-Mar-2026.pdf
Anders Grunnet-Jepsen, John N. Sweetser, John Woodfill, RealSense documentation, as of 2026-08-22.
https://dev.realsenseai.com/docs/tuning-depth-cameras-for-best-performance/
Microsoft, Microsoft Learn, 2019; accessed 2026-08-22.
https://learn.microsoft.com/en-us/previous-versions/azure/kinect-dk/depth-camera
Photoneo, Photoneo, as of 2026-08-22.
https://www.photoneo.com/products/phoxi-scan-l/
Shreeyak Sajjan, Matthew Moore, Mike Pan, Ganesh Nagaraja, Johnny Lee, Andy Zeng, and 1 more, ICRA 2020.
https://doi.org/10.1109/ICRA40945.2020.9197518
Shilong Liu, Zhaoyang Zeng, Tianhe Ren, Feng Li, Hao Zhang, Jie Yang, and 6 more, arXiv 2024.
https://arxiv.org/abs/2303.05499
Maxime Oquab, Timothée Darcet, Théo Moutakanni, Huy Vo, Marc Szafraniec, Vasil Khalidov, and 20 more, arXiv 2023.
https://arxiv.org/abs/2304.07193
Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, and 6 more, arXiv 2023.
https://arxiv.org/abs/2304.02643
Nikhila Ravi, Valentin Gabeur, Yuan-Ting Hu, Ronghang Hu, Chaitanya Ryali, Tengyu Ma, and 12 more, arXiv 2024.
https://arxiv.org/abs/2408.00714
Charles R. Qi, Hao Su, Kaichun Mo, Leonidas J. Guibas, CVPR 2017.
https://arxiv.org/abs/1612.00593
Charles R. Qi, Li Yi, Hao Su, Leonidas J. Guibas, NeurIPS 2017.
https://arxiv.org/abs/1706.02413
Peter R. Florence, Lucas Manuelli, Russ Tedrake, CoRL 2018.
https://arxiv.org/abs/1806.08756
Yu Xiang, Tanner Schmidt, Venkatraman Narayanan, Dieter Fox, RSS 2018.
https://arxiv.org/abs/1711.00199
Bowen Wen, Wei Yang, Jan Kautz, Stan Birchfield, CVPR 2024.
https://arxiv.org/abs/2312.08344
Yann Labbé, Lucas Manuelli, Arsalan Mousavian, Stephen Tyree, Stan Birchfield, Jonathan Tremblay, and 4 more, CoRL 2022.
https://arxiv.org/abs/2212.06870
Tomas Hodan, Martin Sundermeyer, Yann Labbé, Van Nguyen Nguyen, Gu Wang, Eric Brachmann, and 4 more, arXiv preprint, 2024.
https://arxiv.org/abs/2403.09799
Stefan Hinterstoisser, Vincent Lepetit, Slobodan Ilic, Stefan Holzer, Gary Bradski, Kurt Konolige, and 1 more, Computer Vision – ACCV 2012 (LNCS, published 2013).
https://doi.org/10.1007/978-3-642-37331-2_42
B. Espiau, F. Chaumette, P. Rives, IEEE Trans. Robotics and Automation, 1992.
https://doi.org/10.1109/70.143350
François Chaumette, Seth Hutchinson, IEEE Robotics and Automation Magazine, 2006.
https://doi.org/10.1109/MRA.2006.250573
François Chaumette, Seth Hutchinson, IEEE Robotics and Automation Magazine, 2007.
https://doi.org/10.1109/MRA.2007.339609
Fangchen Liu, Kuan Fang, Pieter Abbeel, Sergey Levine, 2024.
https://arxiv.org/abs/2403.03174
Wenlong Huang, Chen Wang, Yunzhu Li, Ruohan Zhang, Li Fei-Fei, 2024.
https://arxiv.org/abs/2409.01652
Wentao Yuan, Jiafei Duan, Valts Blukis, Wilbert Pumacay, Ranjay Krishna, Adithyavairavan Murali, and 2 more, 2024.
https://arxiv.org/abs/2406.10721
Tyler Ga Wei Lum, Kushal Kedia, C. Karen Liu, Jeannette Bohg, CoRL 2026.
https://arxiv.org/abs/2606.26428
Jonathan Tremblay, Thang To, Balakumar Sundaralingam, Yu Xiang, Dieter Fox, Stan Birchfield, Conference on Robot Learning (CoRL) 2018.
https://arxiv.org/abs/1809.10790
Y. C. Shiu, S. Ahmad, IEEE Trans. Robotics and Automation, 1989.
https://doi.org/10.1109/70.88014
F. C. Park, B. J. Martin, IEEE Trans. Robotics and Automation, 1994.
https://doi.org/10.1109/70.326576
OpenCV, OpenCV 4.x Documentation, as of 2026-10-04.
https://docs.opencv.org/4.x/d9/d0c/group__calib3d.html
Ikenna Enebuse, Babul K. S. M. Kader Ibrahim, Mathias Foo, Ranveer S. Matharu, Hafiz Ahmed, PLOS ONE, 2022.
https://doi.org/10.1371/journal.pone.0273261
Aleksei Bochkovskii, Amaël Delaunoy, Hugo Germain, Marcel Santos, Yichao Zhou, Stephan R. Richter, and 1 more, arXiv preprint (ICLR 2025), 2024.
https://arxiv.org/abs/2410.02073
Kaiming He, Georgia Gkioxari, Piotr Dollár, Ross Girshick, arXiv preprint (ICCV 2017).
https://arxiv.org/abs/1703.06870
Tianhe Ren, Shilong Liu, Ailing Zeng, Jing Lin, Kunchang Li, He Cao, and 11 more, 2024.
https://arxiv.org/abs/2401.14159
Van Nguyen Nguyen, Thibault Groueix, Georgy Ponimatkin, Vincent Lepetit, Tomas Hodan, ICCV 2023 R6D Workshop.
https://arxiv.org/abs/2307.11067
He Wang, Srinath Sridhar, Jingwei Huang, Julien Valentin, Shuran Song, Leonidas J. Guibas, arXiv preprint (CVPR 2019).
https://arxiv.org/abs/1901.02970
Van Nguyen Nguyen, Stephen Tyree, Andrew Guo, Mederic Fourmy, Anas Gouda, Taeyeop Lee, and 13 more, 2025.
https://arxiv.org/abs/2504.02812
S. Hutchinson, G. D. Hager, P. I. Corke, IEEE Transactions on Robotics and Automation, 1996.
https://doi.org/10.1109/70.538972
Quentin Bateux, Eric Marchand, Jürgen Leitner, François Chaumette, Peter Corke, 2018 IEEE International Conference on Robotics and Automation (ICRA).
https://doi.org/10.1109/ICRA.2018.8461068
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Jason Lee, Jiafei Duan, Haoquan Fang, Yuquan Deng, Shuo Liu, Boyang Li, and 13 more, 2025.
https://arxiv.org/abs/2508.07917
Kush Hari, Justin Kerr, Nidhya Shivakumar, Samarth Mahapatra, Carmelo Sferrazza, Jiahui Lei, and 4 more, 2026.
https://arxiv.org/abs/2610.03710
Microsoft, Azure Kinect Sensor SDK repository, GitHub, 2024.
https://github.com/microsoft/Azure-Kinect-Sensor-SDK/blob/3c79d56c2aa082d62ebae6ccf217191e6d4e2cfa/microsoft-support.md
Further reading
Jeffrey Mahler, Jacky Liang, Sherdil Niyaz, Michael Laskey, Richard Doan, Xinyu Liu, and 2 more, RSS 2017.
https://arxiv.org/abs/1703.09312
Radu Horaud, Fadi Dornaika, The International Journal of Robotics Research 14(3), pp. 195-210, 1995.
https://inria.hal.science/inria-00590039/document
Konstantinos Daniilidis, Int. J. Robotics Research, 1999.
https://doi.org/10.1177/02783649922066213
RealSense, RealSense press release, 2025.
https://www.realsenseai.com/news-insights/news/realsense-completes-spin-out-from-intel-raises-50-million-to-accelerate-ai-powered-vision-for-robotics-and-biometrics/
Bowen Wen, Matthew Trepte, Joseph Aribido, Jan Kautz, Orazio Gallo, Stan Birchfield, arXiv preprint (CVPR 2025).
https://arxiv.org/abs/2501.09898
Haotong Lin, Sida Peng, Jingxiao Chen, Songyou Peng, Jiaming Sun, Minghuan Liu, and 4 more, arXiv preprint (CVPR 2025), 2024.
https://arxiv.org/abs/2412.14015
Hongjie Fang, Hao-Shu Fang, Sheng Xu, Cewu Lu, IEEE Robotics and Automation Letters, 2022.
https://arxiv.org/abs/2202.08471
Qiyu Dai, Jiyao Zhang, Qiwei Li, Tianhao Wu, Hao Dong, Ziyuan Liu, and 2 more, arXiv preprint (ECCV 2022).
https://arxiv.org/abs/2208.03792
Matthias Minderer, Alexey Gritsenko, Neil Houlsby, 2023.
https://arxiv.org/abs/2306.09683
Tianhe Ren, Qing Jiang, Shilong Liu, Zhaoyang Zeng, Wenlong Liu, Han Gao, and 10 more, 2024.
https://arxiv.org/abs/2405.10300
Oriane Siméoni, Huy V. Vo, Maximilian Seitzer, Federico Baldassarre, Maxime Oquab, Cijo Jose, and 20 more, arXiv technical report, 2025.
https://arxiv.org/abs/2508.10104
Nicolas Carion, Laura Gustafson, Yuan-Ting Hu, Shoubhik Debnath, Ronghang Hu, Didac Suris, and 32 more, 2025.
https://arxiv.org/abs/2511.16719
Jiehong Lin, Lihua Liu, Dekun Lu, Kui Jia, arXiv preprint (CVPR 2024), 2023.
https://arxiv.org/abs/2311.15707
Taeyeop Lee, Bowen Wen, Minjun Kang, Gyuree Kang, In So Kweon, Kuk-Jin Yoon, arXiv preprint (CVPR 2025).
https://arxiv.org/abs/2503.18673
SAM 3D Team, Xingyu Chen, Fu-Jen Chu, Pierre Gleize, Kevin J Liang, Alexander Sax, and 17 more, 2025.
https://arxiv.org/abs/2511.16624
Tomas Hodan, Martin Sundermeyer, Bertram Drost, Yann Labbe, Eric Brachmann, Frank Michel, and 2 more, ECCV 2020 Workshops.
https://arxiv.org/abs/2009.07378
Yann Labbé, Justin Carpentier, Mathieu Aubry, Josef Sivic, arXiv preprint (ECCV 2020).
https://arxiv.org/abs/2008.08465
Laura Graesser, Peng Xu, Google DeepMind blog, 2026.
https://deepmind.google/blog/gemini-robotics-er-1-6/
Spot a factual error or missing qualification? Report a content correction.