Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
A vision-language-action (VLA) model is a robot policy built by adapting a vision-language model, pretrained on web-scale images and text, to output robot actions; earlier behavior cloning and Diffusion Policy learned from robot data alone. The design question is how to get actions out of a model that outputs textSource 2.
Action tokens
Each arm movement becomes seven words a language model writes
Adjust more
All 256 slots for forward/back, from -1 to 1; the lit slot is this moment’s.
Up close, the forward/back rack: its slider sits in notch 120, and the needle marks the smooth command, -0.056.
The seven words for this moment, in order:
- forward/backword 120
- left/rightword 141
- up/downword 108
- rollword 147
- tiltword 149
- turnword 182
- open/closeword 19
Scrub the moment, or write the next oneAt moment 8 of 16, the forward/back nudge -0.056 lands in slot 120 of 256 and is written as word 120
Illustrative: a made-up movement, not recorded robot data.
How this was made
In the symbols robotics papers use, the seven motions are Δx, Δy and Δz (forward/back, left/right, up/down), Δroll, Δpitch and Δyaw (roll, tilt, turn) and grip (open/close). Each is a number on [-1, 1], cut into 256 uniform bins, and each bin is one vocabulary token. Now: Δx = -0.056 at step 7, bin 120 of 255, token <a120>; reconstructs to -0.0586 (error +0.0025).
7 sequential decodes per control step: token n+1 cannot start until token n has been emitted.
A toy chunk with fixed [-1, 1] bounds and synthetic token labels, after the action tokenization of RT-1, RT-2 and OpenVLA; the token names are stand-ins, not any model’s real vocabulary. The racks are a schematic: one notch is one bin, and the close-up magnifies the 15 bins around the chosen one.
Along the forward/back (Δx) motion of the 16-step action chunk, the continuous command runs from 0.183 at t = 0 to 0.183 at t = 15, and at the current step 7 the value -0.056 falls in bin 120 of 255; the slider on the forward/back rack sits in that notch, the setter writes the seven racks one after another, and the chunk is a fixed synthetic example rather than measured robot data.
Sampled action value along the selected dimension
| step | value | bin | playhead |
|---|---|---|---|
| 0 | 0.183 | 151 | off |
| 3 | 0.620 | 207 | off |
| 6 | 0.200 | 153 | off |
| 7 | -0.056 | 120 | playhead |
| 9 | -0.496 | 64 | off |
| 12 | -0.507 | 63 | off |
| 15 | 0.183 | 151 | off |
On the Δx axis the continuous action -0.056 at step 7 falls in bin 120 of 255 and reconstructs to -0.0586 with quantization error +0.0025; the 256-bin strip is a uniform grid on [-1, 1], not a learned codebook.
Current bin assignment
- dimension
- Δx
- step
- 7
- action
- -0.056
- bin
- 120 of 255
- reconstructed
- -0.0586 (+0.0025)
Toy movement with every nudge kept between -1 and 1, and made-up word labels.
RT-1: actions become tokens
RT-1 (2022) conditions an ImageNet-pretrained EfficientNetSource 10 on the instruction through FiLMSource 11, and TokenLearnerSource 12 cuts each of six images to eight tokens for a 19M-parameter decoder-only transformer; the full system has 35M parametersSource 1.
Its 11 action coordinates are seven arm variables (translation, rotation and gripper opening), three base variables and a mode switch that can also end the episode. Each is discretized into 256 bins spaced uniformly within its bounds and trained with categorical cross-entropySource 1. Drag “Moment in the movement” to watch each motion's value land in one of 256 bins.
The data covers about 130k episodes over more than 700 tasks, collected over 17 months with 13 robots, and the paper reports 3,000 real-world evaluation trialsSource 1.
256
bins per dim
uniform quantization
11
action dims
arm includes gripper; 3 base, 1 mode
~130k
episodes
700+ tasks, 13 robots
3 Hz
control rate
reported RT-1 robot setup
RT-1 predicts one action at a time at 3 Hz, with a fixed 280 ms wait, the maximum observed latency of all components, to keep action timing consistentSource 1.
RT-2: actions become text
RT-2 (2023) writes each action dimension's 256 bin indices as strings in a vision-language model's token stream: PaLI-X already has a token for every integer up to 1000, while PaLM-E overwrites its 256 least frequently used tokens. The backbone, up to 55B parameters, is co-fine-tuned on robot trajectories and the original web vision-language data, which the authors report generalizes better than robot data aloneSource 2.
That web knowledge shows up as emergent object choice, such as picking the smallest object, and multi-stage reasoning, such as using a rock as an improvised hammerSource 2. Gemini Robotics 1.5 interleaves actions with natural-language reasoningSource 13.
In a May 2025 research note, Danny Driess and colleagues at Physical Intelligence call this tokenization "not suitable for high-frequency, precise, or fluent motions," likening it to "controlling your arm by verbally saying which muscles should contract"Source 7. The same lab's FAST paper locates the failure in simple per-dimension, per-timestep binning; its compressed tokens match diffusion VLAs on 10k hours of robot data while training up to 5 times fasterSource 14.
Open X-Embodiment and RT-X: pooling the data
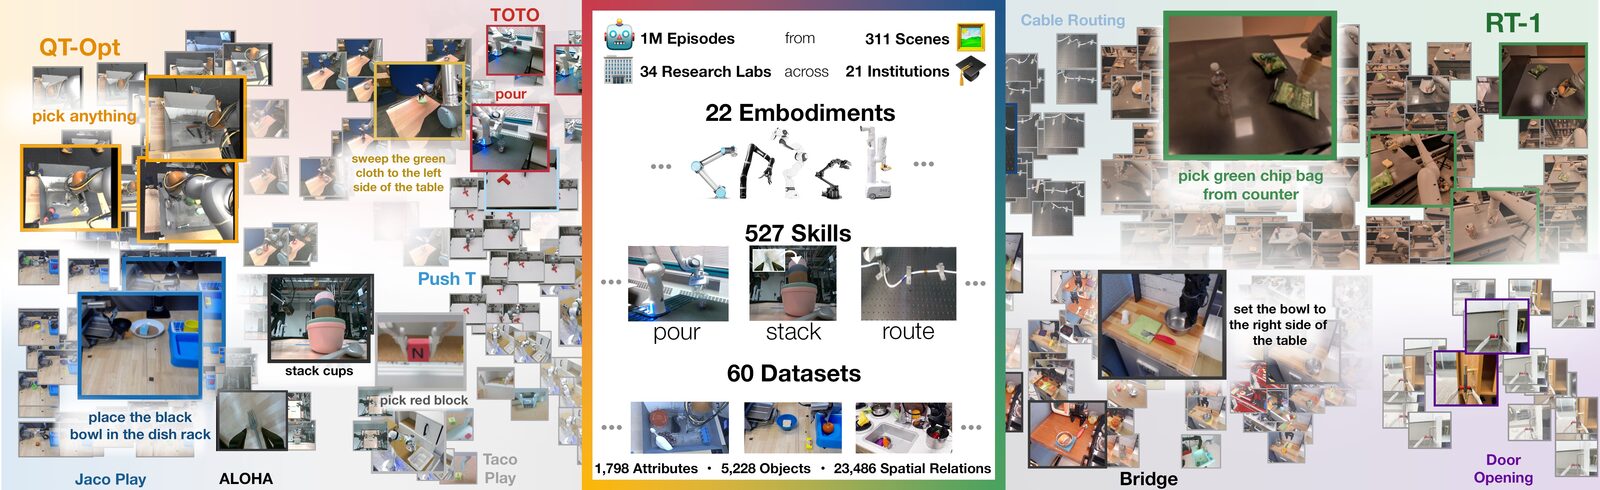
Open X-Embodiment pools more than one million real robot trajectories spanning 22 embodiments, 527 skills and 160,266 tasks; its abstract names 21 institutions, and its dataset description covers 60 datasets from 34 labs. RT-1-X and RT-2-X trained on a nine-embodiment subset. RT-1-X beat the original methods on four of five small-data domains but underperformed RT-1 in the large-data setting, where the higher-capacity RT-2-X outperformed both. RT-2-X gained Google Robot skills from WidowX Bridge data, a cross-embodiment transfer, and performed roughly on par with RT-2 on unseen objects, backgrounds and environmentsSource 3.
In February 2026, Toyota Research Institute researchers compared 89 co-trained policies over 58,000 simulated and 2,835 real rollouts. Vision-language and cross-embodiment co-training substantially improved generalization, while discrete action-token variants brought no significant benefitSource 29. Xiaomi-Robotics-1 (July 2026) pretrains on over 100,000 hours of UMI handheld-gripper and egocentric trajectories and reports 57.4% on RoboCasa365 against a previous best of 46.6%; its authors say code and checkpoints will be releasedSource 30.
Moritz Reuss's October 2025 post, which he presents as his personal selection and opinion, says "OXE is mostly low-quality data" and "we still lack good methods to quantify data quality in imitation learning"Source 8.
Octo and OpenVLA: the open models
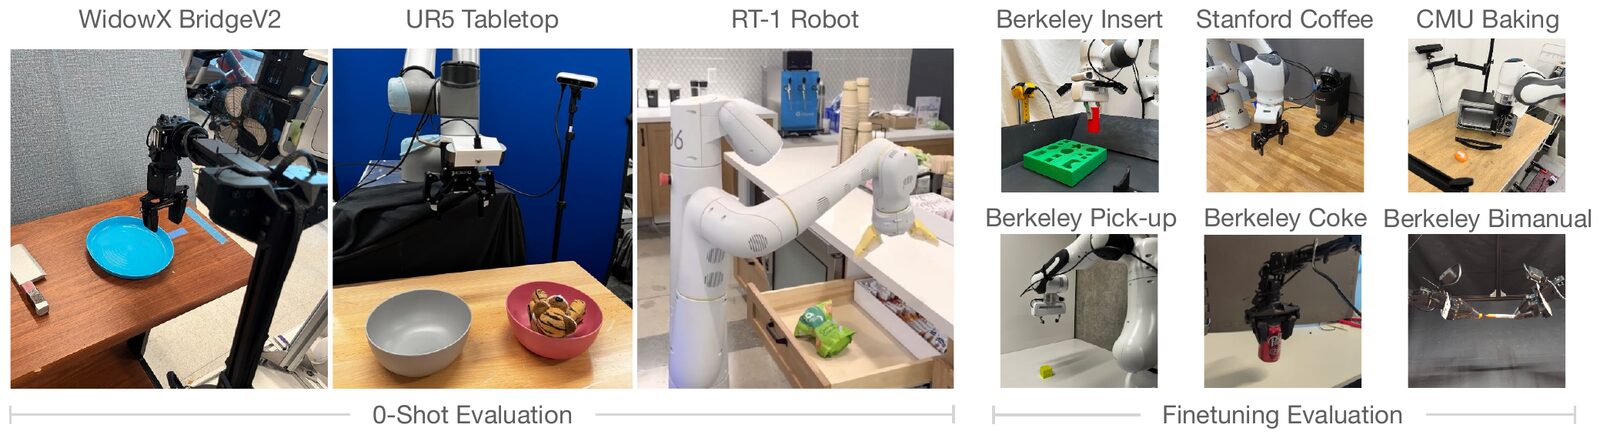
Two 2024 releases made the recipe reproducible outside Google. Octo ships 27M- and 93M-parameter checkpoints trained on 800k Open X-Embodiment trajectories; learned readout tokens in a block-wise-masked transformer feed a lightweight diffusion head that outputs action chunks, and fine-tuning can add a new sensor or output while retaining the transformer weightsSource 4. In zero-shot WidowX evaluation, Octo reports a "25% higher success rate" with goal images than with language, and the authors suggest goal images carry more task information; only 56% of its pretraining data has language annotationsSource 4.
OpenVLA builds on the Prismatic VLMSource 15, with a Llama 2 7B backboneSource 16 and fused DINOv2Source 17 and SigLIPSource 18 features. Trained on 970k robot demonstrations, it predicts seven coordinates for position, orientation and gripper, each split into 256 uniform bins between the training data's 1st and 99th quantiles instead of its minimum and maximum; bin indices replace the 256 least-used Llama tokens and are predicted autoregressivelySource 5 Source 6.
Its headline result is 16.5 points higher absolute task success than RT-2-X (55B) with "7x fewer parameters", over 29 tasks on two embodiments: 17 WidowX tasks with ten trials each and 12 Google-robot tasks with five, from matched initial robot and object states, with partial credit on some tasksSource 5. Among later open models, SmolVLA trains on one GPU, deploys on consumer GPUs or CPUs and decouples action prediction from execution with asynchronous inferenceSource 19.
The discrete-token throughput problem
OpenVLA's original formulation decodes seven action tokens sequentially per timestepSource 6. RT-2 runs at 1 to 3 Hz for the 55B PaLI-X variant and about 5 Hz for the 5B variant, queried over the network from a multi-TPU cloud serviceSource 2. OpenVLA runs at about 6 Hz on one RTX 4090 in bfloat16, without compilation or speculative decoding, and its quantization analysis notes that slower inference changes the controller dynamicsSource 5.
π0 instead adds a flow-matching expert that outputs action chunks at up to 50 HzSource 20, and PD-VLA decodes in parallel by fixed-point iteration with no retraining, reaching 2.52 times the execution frequencySource 21. OpenVLA-OFT (2025) combines bidirectional parallel decoding, action chunking, continuous actions and an L1-trained MLP head; its ALOHA variant, OFT+, adds FiLM for language groundingSource 6.
On LIBEROSource 22, OFT raises average success over four ten-task suites from 76.5% to 97.1% with an added wrist image and proprioceptive state, fine-tuned per suite and scored over 500 episodes each. On an A100, averaged over 100 one-image queries, L1 OFT generates 109.7 actions per second against OpenVLA's 4.2, and 71.4 with the added inputsSource 6. LIBERO-Plus finds that such models drop from 95% to below 30% under modest perturbations and tend to ignore language instructions completelySource 23.
Real ALOHA runs use three images, robot state and absolute joint targets at 25 Hz, down from the platform's 50 Hz, and OFT+ executes all 25 actions before replanning, against eight on LIBERO. ALOHA tasks such as folding clothes are scored for partial completion, LIBERO for binary successSource 6.
In the one-image LIBERO comparison with parallel decoding and eight-step chunks, L1 OFT averages 95.3% against 95.4% for a diffusion head using 50 denoising steps, and 90.7% against 91.1% on LIBERO-Long; the diffusion variants trained longer and converged and inferred more slowly. The demonstrations follow one consistent strategy per task, and the authors leave multimodal demonstrations and large-scale pretraining openSource 6. Removing ACT's CVAE objective barely changes scripted-data results but cuts human-data success from 35.3% to 2%; its chunk-size ablation is in action chunkingSource 9.
State of the field
Action interfaces, data mixtures, inputs and execution protocols differ across these studies, so read token-generation and robot-control rates separatelySource 2 Source 5. With LIBERO near its ceiling, ranking needs harder tests (evaluation crisis): RoboArena compares generalist policies in double-blind pairs on DROID robots at seven institutionsSource 24, and SIMPLER's simulated scores correlate with real performanceSource 25.
Yiqing Xu and Jiajun Wu at Stanford (October 2026) asked 50 people to describe demonstrated tasks; their instructions grew only from 9.1 words for one-event tasks to 15.8 words for tasks of three or more events. On 120 simulated RoboLab tasks with 10 rollouts each, π0.5 fine-tuned on DROID succeeded 38.0% of the time with fully explicit commands, 4.5 points less when told the outcome instead of the action and 15.2 points less when told only the intent. Issuing a fully specified task one step at a time helped all three policies testedSource 31.
A 2026 selection rule
Choosing a VLA means choosing a prior (the visual, language and robot experience in the backbone) and a control interface (the action, horizon, frame and measured rate). OFT changed both throughput and success without replacing OpenVLASource 6. Write down the required semantic novelty, embodiment data, action contract and latency budget, pick the prior with the foundation-model guide and the output with the action-space guide, then compare only models whose contracts match; generalist policies and RL fine-tuning cover the rest.
GR00T N1 separates the two, with a vision-language System 2 over a diffusion-transformer System 1Source 26. π0.7 conditions on language plus strategy metadata and subgoal images, and Physical Intelligence reports zero-shot cross-embodiment laundry foldingSource 27. Google DeepMind's Gemini Robotics 2 controls full humanoids, including a 22-degree-of-freedom hand, and is available only to early-access partnersSource 28.
See also
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
Linked from
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- Humanoid Whole-Body Control
How humanoids track retargeted human motion.
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- Major Datasets
The major open robot datasets and what each collected.
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
- Perception for Manipulation
How camera images become an object's position and orientation.
- Competing Theses
Six bets on how robot intelligence gets built.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
- Space Robotics
Robots where repair is impossible, from Mars to orbit.
References
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Joseph Dabis, Chelsea Finn, and 45 more, 2022.
https://arxiv.org/html/2212.06817v2
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, and 48 more, 2023.
https://arxiv.org/abs/2307.15818
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Octo Model Team, Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, and 14 more, 2024.
https://arxiv.org/html/2405.12213v2
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, and 5 more, 2025.
https://www.pi.website/research/knowledge_insulation
Moritz Reuss, 2025.
https://mbreuss.github.io/blog_post_iclr_26_vla.html
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Mingxing Tan, Quoc V. Le, ICML 2019.
https://arxiv.org/abs/1905.11946
Ethan Perez, Florian Strub, Harm de Vries, Vincent Dumoulin, Aaron Courville, AAAI 2018.
https://arxiv.org/abs/1709.07871
Michael S. Ryoo, AJ Piergiovanni, Anurag Arnab, Mostafa Dehghani, Anelia Angelova, NeurIPS 2021.
https://arxiv.org/abs/2106.11297
Gemini Robotics Team, Abbas Abdolmaleki, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, and 167 more, 2025.
https://arxiv.org/abs/2510.03342
Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, and 3 more, 2025.
https://arxiv.org/abs/2501.09747
Siddharth Karamcheti, Suraj Nair, Ashwin Balakrishna, Percy Liang, Thomas Kollar, Dorsa Sadigh, ICML 2024.
https://arxiv.org/abs/2402.07865
Hugo Touvron, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Yasmine Babaei, and 62 more, 2023.
https://arxiv.org/abs/2307.09288
Maxime Oquab, Timothée Darcet, Théo Moutakanni, Huy Vo, Marc Szafraniec, Vasil Khalidov, and 20 more, arXiv 2023.
https://arxiv.org/abs/2304.07193
Xiaohua Zhai, Basil Mustafa, Alexander Kolesnikov, Lucas Beyer, ICCV 2023.
https://arxiv.org/abs/2303.15343
Mustafa Shukor, Dana Aubakirova, Francesco Capuano, Pepijn Kooijmans, Steven Palma, Adil Zouitine, and 8 more, 2025.
https://arxiv.org/abs/2506.01844
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Wenxuan Song, Jiayi Chen, Pengxiang Ding, Han Zhao, Wei Zhao, Zhide Zhong, and 6 more, IROS 2025.
https://arxiv.org/abs/2503.02310
Bo Liu, Yifeng Zhu, Chongkai Gao, Yihao Feng, Qiang Liu, Yuke Zhu, and 1 more, 2023.
https://arxiv.org/abs/2306.03310
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Pranav Atreya, Karl Pertsch, Tony Lee, Moo Jin Kim, Arhan Jain, Artur Kuramshin, and 26 more, 2025.
https://arxiv.org/abs/2506.18123
Xuanlin Li, Kyle Hsu, Jiayuan Gu, Karl Pertsch, Oier Mees, Homer Rich Walke, and 10 more, 2024.
https://arxiv.org/abs/2405.05941
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Fanqi Lin, Kushal Arora, Jean Mercat, Haruki Nishimura, Paarth Shah, Chen Xu, and 6 more, 2026.
https://arxiv.org/abs/2602.01067
Xiaomi Robotics Team, Jun Guo, Piaopiao Jin, Jason Li, Peiyan Li, Yingyan Li, and 28 more, 2026.
https://arxiv.org/abs/2607.15330
Yiqing Xu, Jiajun Wu, 2026.
https://arxiv.org/abs/2610.17746
Further reading
Danny Driess, Fei Xia, Mehdi S. M. Sajjadi, Corey Lynch, Aakanksha Chowdhery, Brian Ichter, and 16 more, 2023.
https://arxiv.org/abs/2303.03378
Ankit Goyal, Hugo Hadfield, Xuning Yang, Valts Blukis, Fabio Ramos, 2025.
https://arxiv.org/abs/2510.13054
Joey Hejna, Chethan Bhateja, Yichen Jiang, Karl Pertsch, Dorsa Sadigh, 2024.
https://arxiv.org/abs/2408.14037
Qixiu Li, Yaobo Liang, Zeyu Wang, Lin Luo, Xi Chen, Mozheng Liao, and 12 more, 2024.
https://arxiv.org/abs/2411.19650
Jinliang Zheng, Jianxiong Li, Zhihao Wang, Dongxiu Liu, Xirui Kang, Yuchun Feng, and 9 more, 2025.
https://arxiv.org/abs/2510.10274
Spot a factual error or missing qualification? Report a content correction.