What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
A world model is a model that predicts how an environment evolves in a form useful for a robot's decisions. Hou and colleagues' 2026 survey applies this functional definition to visual, latent, structured and symbolic predictions.Source 1
Ha and Schmidhuber's 2018 world model learned "a compressed spatial and temporal representation of the environment"Source 13. Switch "What it imagines" between pictures, a compressed summary and plain facts; "Adjust more" lists six example groups. The six groups are this article's authored selection, not an exhaustive or universally agreed scientific taxonomy.
Six kinds of world model
Robot imaginations: some predict pictures, others compact summaries
What it imagines
Adjust more
Used for
Policy learning
Not used for
Planning
Evaluation
Data generation
Illustrative schematic: drawn by hand, not a model's output.
Selected: Latent dynamics. Imagines a compressed summary. Predicts: Next latent state + reward + continuation flag. Latent-dynamics world model (Dreamer-style), used for policy learning.
How this was made
On the left is what the robot sees now: an arm above a cup on a table, about to pick the cup up. On the right are the three forms an imagined next moment can take: the next picture itself, a compressed summary (a short list of numbers, drawn as beads), or plain facts about the objects. The marked form is the one the selected group predicts; “Adjust more” lists the six groups and their uses.
What each group predicts and what it is used for:
Latent-dynamics world model (Dreamer-style): Next latent state + reward + continuation flag. Used for policy learning.
Decoder-free latent model for planning (TD-MPC-style): Next latent state + reward; no reconstruction, no decoder. Used for policy learning and planning.
Action-conditioned generative video model: Future pixels conditioned on the current frame(s) + action/text. Used for policy learning, evaluation and data generation.
Non-generative joint-embedding predictor (JEPA): Future representation, never pixels. Used for planning.
Unified world-action model: Future frames and action chunks from one backbone. Used for policy learning.
Symbolic / structured world model: Transitions over predicates, object relations, occupancy. Used for planning.
Dreamer-style models also learn a decoder that turns a summary back into a picture, but they use it only as a training signal; TD-MPC-style and JEPA models have no decoder at all. The uses are this article's reading of each group against the survey's four: policy learning, planning, evaluation and data generation.
The six groups are this article's selection, not an exhaustive taxonomy. The arm, the cup, the beads and the facts are drawn by hand to show the form each prediction takes; none of them is a model's output.
Latent dynamics (Dreamer-style), one of 3 groups out of 6 that imagine a compressed summary, predicts the next latent, a reward and a continue signal, and draws pictures only during training; of the 4 uses, it serves policy learning.
Current world-model group
- group
- Latent dynamics
- imagines
- a compressed summary
- predicts
- Next latent state + reward + continuation flag
- used for
- 1 of 4: policy learning
Original schematic; the drawings are illustrative.
6
example groups
selected in this article
150+
DreamerV3 tasks
one fixed hyperparameter set
317M
TD-MPC2 params
one offline agent, 80 tasks
>1M
V-JEPA 2 video
video hours; action-free pretraining
A model counts only if it predicts the effect of actions
Hou and colleagues count a model only if it predicts how the future changes under robot-relevant actions and supports embodied decision-making. In their words, "a model does not qualify as a world model in our sense simply because it generates plausible future images or videos". The survey names weak action conditioning a technical bottleneck, since it allows futures with no causal tie to the pending actionSource 1. A second 2026 survey likewise defines a world model as "an action-conditioned predictive system"Source 14.
Six example groups
| Paradigm | What it predicts | In what space | Trained on | Primary use | Representative systems |
|---|---|---|---|---|---|
| Latent-dynamics world model (Dreamer-style) | Next latent state + reward + continuation flag | Learned compact latent (stochastic + deterministic); decoded to pixels during training | The agent's own interaction data | Policy optimization on imagined rollouts; sample-efficient RL | DreamerV3, DayDreamer, Robotic World Model |
| Decoder-free latent model for planning (TD-MPC-style) | Next latent state + reward; no reconstruction, no decoder | Implicit latent trained only for value/reward prediction | Interaction data | Latent-space planning: MPPI or policy-seeded gradient ascent | TD-MPC, TD-MPC2, Dream-MPC |
| Action-conditioned generative video model | Future pixels conditioned on the current frame(s) + action/text | Pixel or VAE-latent video space | Internet video + robot trajectories | Data generation, policy evaluation, RL post-training, interactive worlds | Cosmos 3, Genie 3, Odyssey, Interactive World Simulator |
| Non-generative joint-embedding predictor (JEPA) | Future representation, never pixels | Learned embedding space; masked/future embedding prediction | Internet video + a small action-labeled robot set | Zero-shot planning by energy minimization over latent goals | V-JEPA, V-JEPA 2, V-JEPA 2-AC |
| Unified world-action model | Future frames and action chunks from one backbone | Shared backbone; parallel generative and action heads | Robot trajectories + video | Policy with world-modeling as auxiliary objective / implicit lookahead | Cosmos Policy, WorldVLA, DreamZero |
| Symbolic / structured world model | Transitions over predicates, object relations, occupancy | Discrete/relational or 3D-occupancy space | Curated or perception-grounded data | Long-horizon task planning without pixel-space error accumulation | OccWorld, symbolic-abstraction hybrids |
Latent dynamics: predict a compact state, dream in it
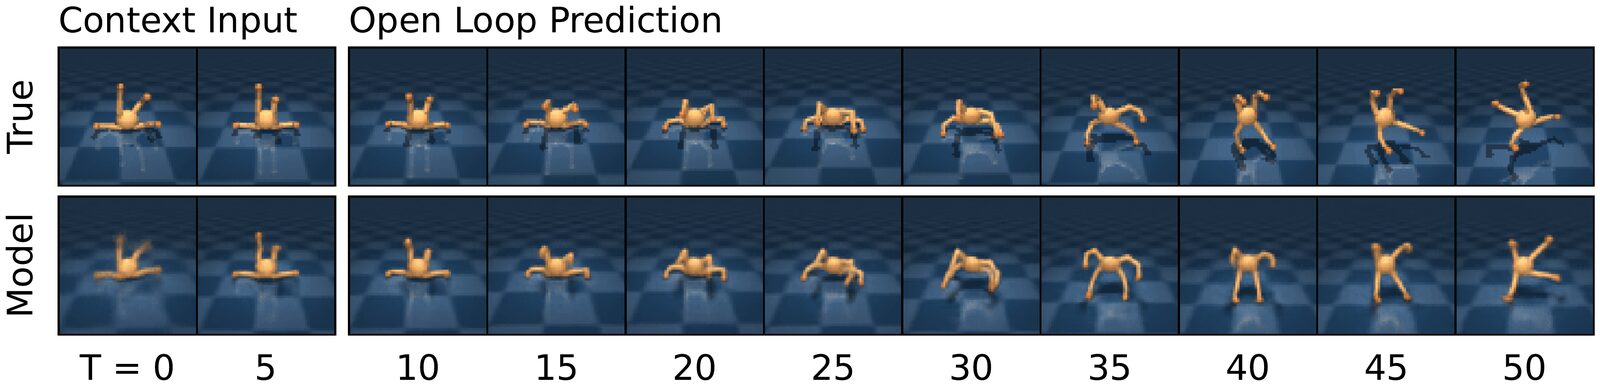
DreamerV3 uses a recurrent state-space model with stochastic latents and reconstructs inputs; its actor and critic learn from imagined trajectories, and the critic also receives a loss on replay-buffer trajectories. It ran more than 150 tasks in eight domains with fixed hyperparametersSource 2. Hafner and colleagues' 2025 Nature article calls it, to their knowledge, the first algorithm to collect Minecraft diamonds from scratch without human data or adaptive curriculaSource 15, in an environment with abstract crafting actions, accelerated block breaking and sparse intermediate rewardsSource 2. See the latent-dynamics explanation.
Dreamer 4 draws most knowledge from unlabeled video, needing little action-labeled dataSource 16. DayDreamer taught a Unitree A1 to roll off its back, stand and walk in about one hour of real training with no simulator or reset policy, though a PD controller and manual repositioning remainedSource 4.
Decoder-free latent: no image, just value
TD-MPC2 learns joint-embedding, reward and value predictions without reconstructing observations, and its MPPI planner scores sampled action sequences by latent rollouts plus a terminal value. Its 317M-parameter model trained offline on 545M transitions from 240 single-task agents, a run distinct from the 104-task online benchmarkSource 3.
Generative video: predict the pixels
These models predict future pixels from frames plus an action or text condition; see generative video. NVIDIA presents Cosmos 3 as one Mixture-of-Transformers for understanding, generation, policy and forward and inverse dynamicsSource 5. DeepMind reports that Genie 3 renders text-prompted worlds navigable in real time at 24 fps and 720p, largely consistent for a few minutes, with constrained agent actions among its limitsSource 6.
JEPA: predict the representation, never the pixels
V-JEPA trains "solely using a feature prediction objective"Source 17. V-JEPA 2 pretrains action-free on over a million hours of video plus images. V-JEPA 2-AC freezes the encoder and trains an action-conditioned predictor on under 62 hours of filtered left-camera Droid video, which carries no reward, task-type or success labels but includes Franka Panda teleoperationSource 7.
The same weights and code ran zero-shot on Franka Panda arms in two labs absent from Droid, with hand-chosen cameras and, for pick-and-place, two subgoal imagesSource 7. See the JEPA module.
Unified world-action: one backbone, two heads
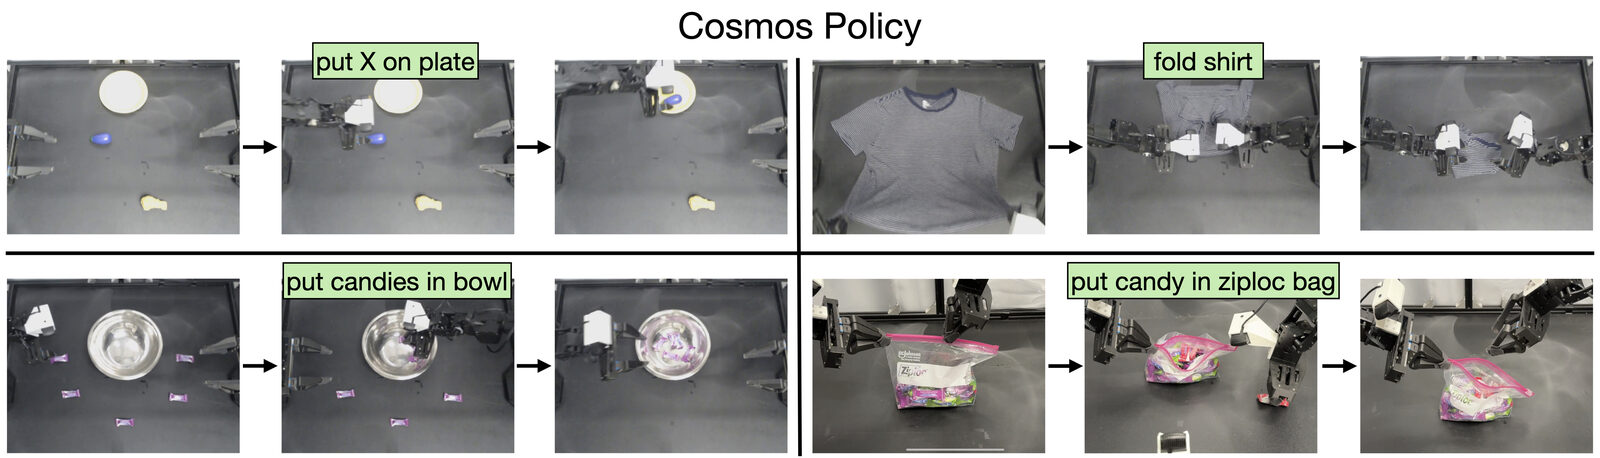
A world-action model (WAM) uses a pretrained video backbone to predict both future states and robot actionsSource 18; unlike a VLA, it learns physical dynamicsSource 19. WorldVLA interleaves action and image tokens and reports that the objectives improve each otherSource 8, and Cosmos Policy post-trains Cosmos-Predict2 into a policy with no architectural modificationsSource 9. NVIDIA reports that DreamZero runs a 14B video-diffusion model as a 7 Hz closed-loop policy with over twice the generalization of state-of-the-art VLAs on real robotsSource 19. Fast-WAM stays competitive while skipping test-time future generation, and removing video co-training hurts far moreSource 20.
Symbolic and structured: predict predicates
These models predict transitions over predicates, object relations or 3D occupancy; OccWorld, from autonomous driving, predicts how scene occupancy evolves and plans competitively without instance or map supervisionSource 10. PointWorld predicts the 3D point flows that a sequence of robot actions produces, and at 0.1 s per inference it drives model-predictive control on a real Franka arm with no demonstrationsSource 30. Silver and colleagues treat learned operators as "a lossy abstraction of the transition model"Source 21, and VisualPredicator, which invents its predicates online, generalizes better out of distributionSource 22.
Two boundary cases
A physics engine is a world model
MuJoCo is an explicit, hand-specified state-transition model: given a state and an action, it predicts the next stateSource 11. TD-MPC2 and classical MPC therefore share one pattern, with learned or derived dynamics.
A 3D Gaussian Splatting twin is not
A 3DGS reconstruction is a learned renderer that predicts a scene from a new camera poseSource 12; its dynamics come from the physics engine underneath, so alone it fails the functional cut. PhysGaussian adds dynamics by evolving the Gaussians with a Material Point Method solverSource 23, and World Labs' Marble exports splats with collider meshes "intended for coarse physics simulation"Source 24. See generative simulation.
Video models serve evaluation and data; latent models plan without images
Google DeepMind reports a Veo-based simulator predicted policies' relative performance, checked against 1,600+ real evaluations of eight Gemini Robotics checkpointsSource 25. The Interactive World Simulator sustains over 10 minutes of interaction at 15 FPS on one RTX 4090, and policies trained on its data matched those trained on as much real dataSource 26. Decoder-free latent and JEPA models plan without showing an image.
Three tests before believing a world-model claim
The intervention test varies the action with history fixed, since "action-marginalized" hallucination is a measured failure modeSource 27. The ranking test asks whether the model orders policies as reality does. The transfer test repeats both across objects, contacts, viewpoints and horizons: in controlled scaling experiments, video models failed out of distribution and showed "case-based" generalizationSource 28. Visual quality counts last, since in six major video generators physical understanding was "severely limited, and unrelated to visual realism"Source 29.
Hou and colleagues separate learned simulation for reinforcement learning, rollout evaluation and video generation for supervisionSource 1. The evaluation guide, model-based robot learning and world models versus simulators go further.
Self-check
Read the reasoning
- It qualifies: it predicts the scene from any camera pose, which is a predictionThis is the most common misreading of the real-to-sim literature. A 3DGS twin is a learned renderer: it predicts appearance from a new viewpoint and has no answer to what happens under an action. The survey’s functional cut is explicit on this: generating plausible future images alone does not qualify a model as a world model.
- It is a learned renderer bolted onto a physics engine: appearance is learned, dynamics are notThis is the correct division of labor. The splat supplies appearance while a conventional physics engine still supplies dynamics, and the reconstruction freezes the scene it captured: articulated objects, deformables, and lighting changes each need extra machinery on top.
- It fails the cut because nothing hand-specified counts as a world modelOnly action-dependence determines the cut; learned dynamics are not required. MuJoCo is an explicit, hand-specified state-transition model and it qualifies: given a state and an action it predicts the next state. The 3DGS twin fails for having no action answer, not for lacking weights.
Ask what happens under an action: a renderer that only answers where the camera goes fails the functional cut, whatever the video looks like.
See also
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
Linked from
- Foundation Models for Robotics
What foundation means in robotics, and what adaptation still costs.
- Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
- Competing Theses
Six bets on how robot intelligence gets built.
References
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap, 2023.
https://arxiv.org/abs/2301.04104
Nicklas Hansen, Hao Su, Xiaolong Wang, ICLR 2024, 2023.
https://arxiv.org/abs/2310.16828
Philipp Wu, Alejandro Escontrela, Danijar Hafner, Ken Goldberg, Pieter Abbeel, CoRL 2022.
https://arxiv.org/abs/2206.14176
NVIDIA, Aditi, Niket Agarwal, Arslan Ali, Jon Allen, Martin Antolini, and 289 more, 2026.
https://research.nvidia.com/labs/cosmos-lab/cosmos3/technical-report.pdf
Jack Parker-Holder, Shlomi Fruchter, Google DeepMind, 2025.
https://deepmind.google/blog/genie-3-a-new-frontier-for-world-models/
Mahmoud Assran, Adrien Bardes, David Fan, Quentin Garrido, Russell Howes, Mojtaba Komeili, and 23 more, 2025.
https://arxiv.org/abs/2506.09985
Jun Cen, Chaohui Yu, Hangjie Yuan, Yuming Jiang, Siteng Huang, Jiayan Guo, and 6 more, 2025.
https://arxiv.org/abs/2506.21539
Moo Jin Kim, Yihuai Gao, Tsung-Yi Lin, Yen-Chen Lin, Yunhao Ge, Grace Lam, and 5 more, 2026.
https://arxiv.org/abs/2601.16163
Wenzhao Zheng, Weiliang Chen, Yuanhui Huang, Borui Zhang, Yueqi Duan, Jiwen Lu, 2023.
https://arxiv.org/abs/2311.16038
Emanuel Todorov, Tom Erez, Yuval Tassa, IROS 2012.
https://doi.org/10.1109/IROS.2012.6386109
Bernhard Kerbl, Georgios Kopanas, Thomas Leimkühler, George Drettakis, ACM Trans. Graph. 42(4), author manuscript (2023).
https://arxiv.org/abs/2308.04079
Fangyuan Wang, Ziyuan Wang, Guorui Pei, Mengshi Zhang, Canxi Liang, Jun Hu, and 12 more, 2026.
https://arxiv.org/abs/2606.00113
Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap, Nature 640, 647-653, 2025.
https://doi.org/10.1038/s41586-025-08744-2
Danijar Hafner, Wilson Yan, Timothy Lillicrap, 2025.
https://arxiv.org/abs/2509.24527
Adrien Bardes, Quentin Garrido, Jean Ponce, Xinlei Chen, Michael Rabbat, Yann LeCun, and 2 more, 2024.
https://arxiv.org/abs/2404.08471
Moritz Reuss, NVIDIA Technical Blog, 2026.
https://developer.nvidia.com/blog/pretrained-to-imagine-fine-tuned-to-act-the-rise-of-world-action-models/
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
Tianyuan Yuan, Zibin Dong, Yicheng Liu, Hang Zhao, 2026.
https://arxiv.org/abs/2603.16666
Tom Silver, Rohan Chitnis, Joshua Tenenbaum, Leslie Pack Kaelbling, Tomas Lozano-Perez, IROS 2021.
https://arxiv.org/abs/2103.00589
Yichao Liang, Nishanth Kumar, Hao Tang, Adrian Weller, Joshua B. Tenenbaum, Tom Silver, and 2 more, ICLR 2025, 2024.
https://arxiv.org/abs/2410.23156
Tianyi Xie, Zeshun Zong, Yuxing Qiu, Xuan Li, Yutao Feng, Yin Yang, and 1 more, CVPR 2024, 2023.
https://arxiv.org/abs/2311.12198
World Labs, World Labs, 2025.
https://www.worldlabs.ai/blog/marble-world-model
Gemini Robotics Team, Krzysztof Choromanski, Coline Devin, Yilun Du, Debidatta Dwibedi, Ruiqi Gao, and 17 more, 2025.
https://arxiv.org/abs/2512.10675
Yixuan Wang, Rhythm Syed, Fangyu Wu, Mengchao Zhang, Aykut Onol, Jose Barreiros, and 4 more, 2026.
https://arxiv.org/abs/2603.08546
Nicklas Hansen, Xiaolong Wang, 2026.
https://arxiv.org/abs/2606.27326
Bingyi Kang, Yang Yue, Rui Lu, Zhijie Lin, Yang Zhao, Kaixin Wang, and 2 more, ICML 2025, 2024.
https://arxiv.org/abs/2411.02385
Saman Motamed, Laura Culp, Kevin Swersky, Priyank Jaini, Robert Geirhos, 2025.
https://arxiv.org/abs/2501.09038
Wenlong Huang, Yu-Wei Chao, Arsalan Mousavian, Ming-Yu Liu, Dieter Fox, Kaichun Mo, and 1 more, 2026.
https://arxiv.org/abs/2601.03782
Further reading
Nicklas Hansen, Hao Su, Xiaolong Wang, 2025.
https://arxiv.org/abs/2511.19584
Google, Google (The Keyword), 2026.
https://blog.google/innovation-and-ai/models-and-research/google-deepmind/project-genie/
Oliver Cameron, Odyssey, 2025.
https://odyssey.ml/introducing-odyssey-2
Lorenzo Mur-Labadia, Matthew Muckley, Amir Bar, Mido Assran, Koustuv Sinha, Mike Rabbat, and 3 more, 2026.
https://arxiv.org/abs/2603.14482
Lucas Maes, Quentin Le Lidec, Damien Scieur, Yann LeCun, Randall Balestriero, 2026.
https://arxiv.org/abs/2603.19312
AMD, AMD press release, 2026.
https://ir.amd.com/news-events/press-releases/detail/1299/amd-to-acquire-world-labs-to-advance-the-future-of-ai-compute
Spot a factual error or missing qualification? Report a content correction.