World Model Evaluation for Robotics
Testing a world model on what a robot needs.
World-model evaluation is the testing of a robotics world model against the decisions a robot must make, from one-step action responses to agreement with real policy rankings. Image metrics cannot establish that: on Physics-IQ, physical understanding in video generators was "unrelated to visual realism"Source 6.
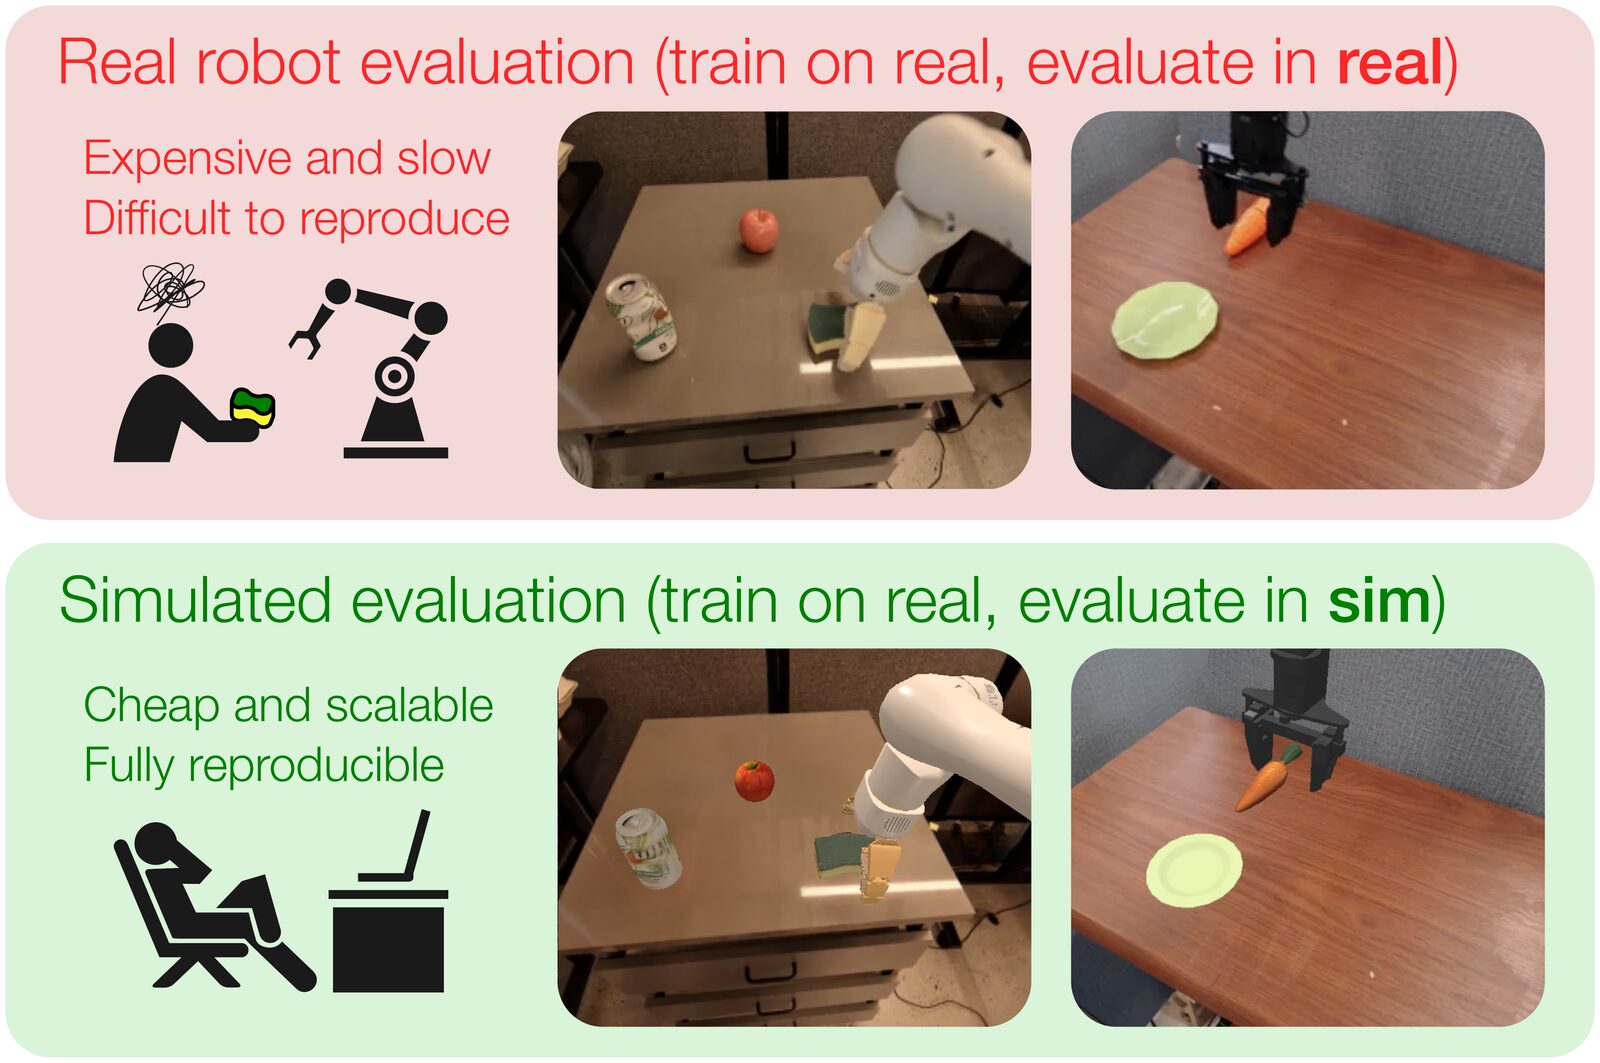
The central failure is action indifference: smooth, photorealistic futures that ignore the robot's action. A 2026 survey of robot world models rates controllability above visual plausibilitySource 1, and the closed-loop World-in-World benchmark found it mattered more than visual quality for task successSource 7.
Self-check
Read the reasoning
- Its policy ranking agrees with repeated real-world policy trialsThis directly validates the intended use. The neural evaluator may still be imperfect, but its ordering is calibrated against the decision it will support.
- Its generated frames receive the highest perceptual sharpness scoreSharpness may improve human inspection, but it does not show that the model preserves action consequences or ranks policies the way the real robot does.
- It can generate the longest uninterrupted videoDuration is useful only if errors remain bounded and actions stay causal. A long action-insensitive rollout can be less useful than a short calibrated one.
Validate the downstream decision: a policy evaluator must preserve real policy ordering. Attractive frames alone do not establish that.
Perception scores miss function, so each use needs its own test
WorldArena scores 14 models separately as data engines, policy evaluators and action planners, and reports a "significant perception-functionality gap"Source 8. NVIDIA reports its DreamGen Bench video scores tracking downstream policy successSource 9. 1X saw unchanged policy weights degrade within days after subtle lighting or background changesSource 10.
Level 1: open models often fail to follow a changed action
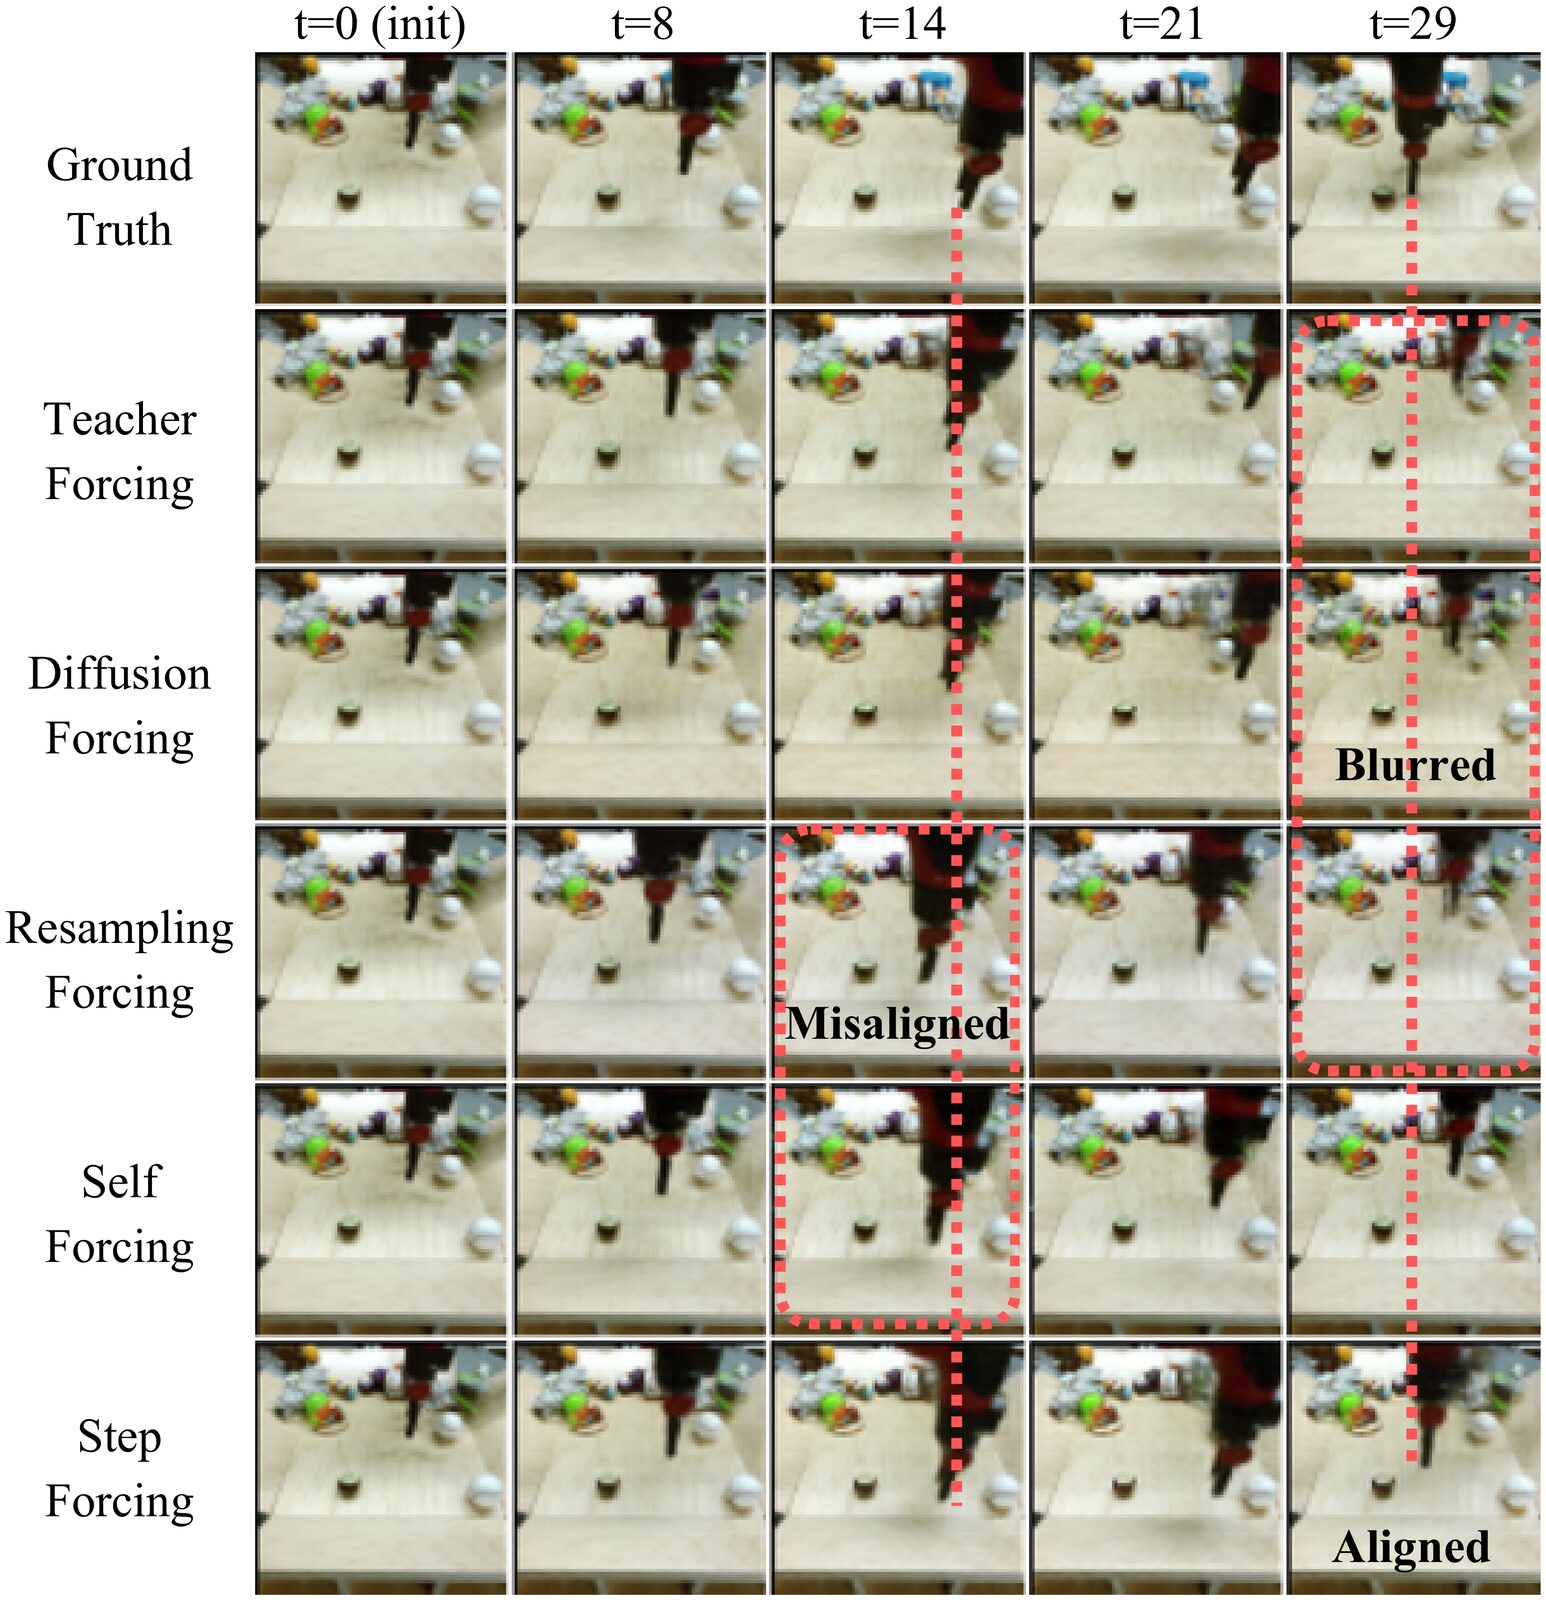
Build matched counterfactuals: fix the observation, noise, prompt and history, and change one action dimension. WorldEval found raw action inputs often yield videos that ignore the actionSource 12, and IRASim and Ctrl-World add frame-level action conditioningSource 13 Source 14. Across six open action-conditioned world models and more than 18,000 test instances, WorldSimProbe found systematic degradation in how actions are realizedSource 30.
Level 2: pooled video metrics hide physical errors
Roll out autoregressively, score task events such as grasp, slip and release, and report error per horizon. Fréchet Video Distance "increases only slightly with large temporal corruption"Source 15. WorldModelBench uses 67K human labels to catch violations such as objects changing sizeSource 16, and video models trained on simple physics failed out of distribution, copying the closest training exampleSource 17.
Level 3: the progress scorer needs its own test
Many evaluators pair a video generator with a vision-language scorer, as WorldGym does, so each half needs its own testSource 18. GVL fixes poor naive VLM value prediction by ordering shuffled frames, scoring more than 300 real tasksSource 19. Runway and DreamDojo used human graders instead, Runway collecting over 16,000 ratingsSource 20 Source 21.
Level 4: the best simulators order policies as real trials do
A policy evaluator must reproduce reality's ordering, measured as Pearson correlation and Mean Maximum Rank Violation (MMRV)Source 20. Real comparisons often rest on 10 to 50 trials, and adding trials after peeking risks p-hacking; the STEP sequential test cuts trials by up to 32%Source 22.
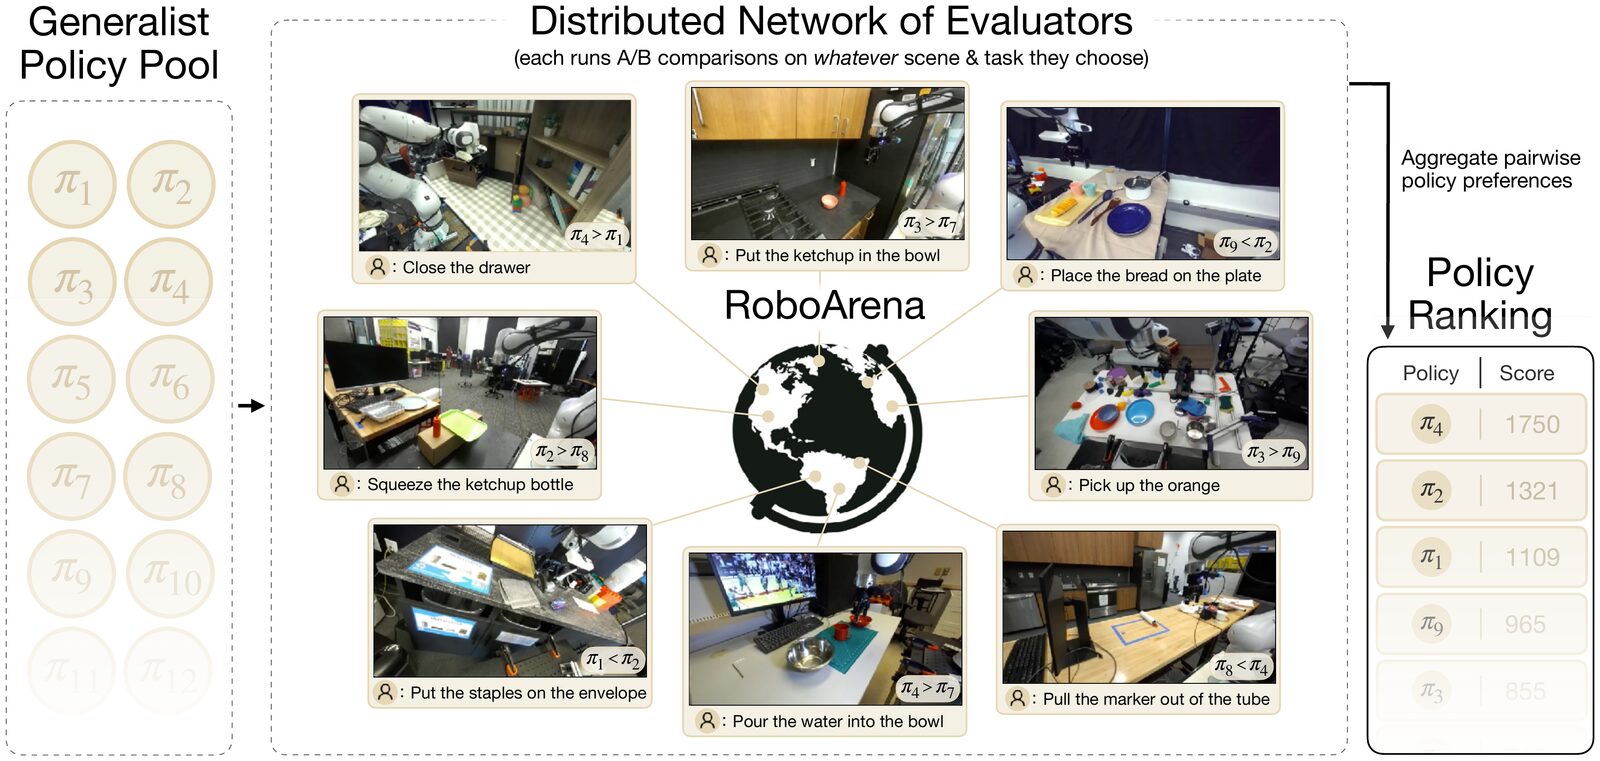
Google DeepMind reports its Veo simulator ranked eight Gemini Robotics checkpoints against more than 1,600 real evaluations at MMRV 0.03, though its absolute success predictions ran lowSource 23. WorldGym reached r = 0.78Source 18, and NVIDIA reports r = 0.995 for DreamDojoSource 21. Runway reports Pearson 0.95 and MMRV 0.033 over eight RoboArena policies, testing ranking onlySource 20. PolaRiS found that Ctrl-World "produces heavy hallucinations during object interaction", mis-ranking policies at MMRV 0.22Source 24.
Physics simulation sets the bar. In June 2026, Yuke Zhu and colleagues reported that SimFoundry, which rebuilds a real scene in simulation from video, predicted real results across 7 tasks and 5 policy architectures at mean Pearson 0.911 and MMRV 0.018Source 5. PolaRiS reports r = 0.9 against real trialsSource 24, and X2Real 0.84Source 25.
Level 5: planning and fine-tuning in a world model improved outcomes
IRASim planning raised Push-T IoU from 0.637 to 0.961Source 13, and fine-tuning on Ctrl-World's imagined successes raised policy success by 44.7%Source 14. Post-training on action-observation data helped more than a stronger pretrained video generatorSource 7.
SIMPLER's test, whether simulated and real policy performance correlate under matched visual and physical conditions, applies to learned simulators tooSource 2. RoboArena widens real evaluation beyond one laboratorySource 4.
Saturated benchmarks hide robustness gaps
Use a factorial matrix to expose shifts one "unseen" split could conceal. RoboLab-120 sorts 120 tasks into visual, procedural and relational axes and measures sensitivity to controlled perturbationsSource 26:
| Shift | Example | Failure it exposes |
|---|---|---|
| Visual | lighting, texture, distractors | representation dependence |
| Geometric | object pose, camera pose, layout | spatial grounding |
| Physical | mass, friction, compliance | dynamics fidelity |
| Semantic | new object or instruction | pretrained knowledge transfer |
| Policy | architecture or checkpoint family | evaluator overfitting |
| Embodiment | arm, gripper or control convention | action-space dependence |
LIBERO-Plus used such perturbations to uncover gaps a saturated benchmark hidSource 3, and PolaRiS found nearly all tested policies scoring 90 to 95% on LIBERO, poorly correlated with real performanceSource 24.
Disjoint data and blind trials guard against leakage
Foundation models can see the benchmark in pretraining video, and scorers can share a backbone with the policy. Ctrl-World trains on DROIDSource 14, which spans 564 scenesSource 27, and Runway's RoboArena ranking put pi05_droid firstSource 20. X2Real enforces "strictly disjoint training-evaluation pipelines"Source 25, and TRI compared policies in blind, randomized trialsSource 28.
A credible report pins the benchmark version and the real anchor
A credible report states the use case, action representation, horizon and real anchor, and separates generator from scorer error. It names the benchmark version: Physics-IQ Verified refined 57.6% of samples and shifted rankings at Kendall's τ = 0.46Source 29. By 1X's arithmetic, with a 15% real gap between two policies, a 70%-accurate world model picks the better one 90% of the timeSource 11.
See also
- Safety and Assurance
What ships is a verifiable safety layer around the learned policy.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
Linked from
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
References
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Xuanlin Li, Kyle Hsu, Jiayuan Gu, Karl Pertsch, Oier Mees, Homer Rich Walke, and 10 more, 2024.
https://arxiv.org/abs/2405.05941
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Pranav Atreya, Karl Pertsch, Tony Lee, Moo Jin Kim, Arhan Jain, Artur Kuramshin, and 26 more, 2025.
https://arxiv.org/abs/2506.18123
Nadun Ranawaka, Josiah Wong, Wei-Lin Pai, Wei-Teng Chu, Tianyuan Dai, Masoud Moghani, and 12 more, 2026.
https://arxiv.org/abs/2606.28276
Saman Motamed, Laura Culp, Kevin Swersky, Priyank Jaini, Robert Geirhos, 2025.
https://arxiv.org/abs/2501.09038
Jiahan Zhang, Muqing Jiang, Nanru Dai, Taiming Lu, Arda Uzunoglu, Shunchi Zhang, and 11 more, ICLR 2026 (Oral), 2025.
https://arxiv.org/abs/2510.18135
Yu Shang, Zhuohang Li, Yiding Ma, Weikang Su, Xin Jin, Ziyou Wang, and 15 more, 2026.
https://arxiv.org/abs/2602.08971
Joel Jang, Seonghyeon Ye, Zongyu Lin, Jiannan Xiang, Johan Bjorck, Yu Fang, and 22 more, 2025.
https://arxiv.org/abs/2505.12705
Jack Monas, Eric Jang, 1X Technologies, 2024.
https://www.1x.tech/discover/1x-world-model
Yaxuan Li, Yichen Zhu, Junjie Wen, Chaomin Shen, Yi Xu, 2025.
https://arxiv.org/abs/2505.19017
Fangqi Zhu, Hongtao Wu, Song Guo, Yuxiao Liu, Chilam Cheang, Tao Kong, ICCV 2025, 2024.
https://arxiv.org/abs/2406.14540
Yanjiang Guo, Lucy Xiaoyang Shi, Jianyu Chen, Chelsea Finn, 2025.
https://arxiv.org/abs/2510.10125
Songwei Ge, Aniruddha Mahapatra, Gaurav Parmar, Jun-Yan Zhu, Jia-Bin Huang, CVPR 2024.
https://arxiv.org/abs/2404.12391
Dacheng Li, Yunhao Fang, Yukang Chen, Shuo Yang, Shiyi Cao, Justin Wong, and 7 more, 2025.
https://arxiv.org/abs/2502.20694
Bingyi Kang, Yang Yue, Rui Lu, Zhijie Lin, Yang Zhao, Kaixin Wang, and 2 more, ICML 2025, 2024.
https://arxiv.org/abs/2411.02385
Julian Quevedo, Ansh Kumar Sharma, Yixiang Sun, Varad Suryavanshi, Percy Liang, Sherry Yang, 2025.
https://arxiv.org/abs/2506.00613
Yecheng Jason Ma, Joey Hejna, Ayzaan Wahid, Chuyuan Fu, Dhruv Shah, Jacky Liang, and 12 more, 2024.
https://arxiv.org/abs/2411.04549
Andy Chen, Lucas Eager Leavitt, Rik Heijdens, Robin Kahlow, Runway Research, 2026.
https://runway.com/research/accelerating-robot-policy-evaluation
Shenyuan Gao, William Liang, Kaiyuan Zheng, Ayaan Malik, Seonghyeon Ye, Sihyun Yu, and 24 more, 2026.
https://arxiv.org/abs/2602.06949
David Snyder, Asher James Hancock, Apurva Badithela, Emma Dixon, Patrick Miller, Rares Andrei Ambrus, and 3 more, RSS 2025.
https://arxiv.org/abs/2503.10966
Gemini Robotics Team, Krzysztof Choromanski, Coline Devin, Yilun Du, Debidatta Dwibedi, Ruiqi Gao, and 17 more, 2025.
https://arxiv.org/abs/2512.10675
Arhan Jain, Mingtong Zhang, Kanav Arora, William Chen, Marcel Torne, Muhammad Zubair Irshad, and 8 more, 2025.
https://arxiv.org/abs/2512.16881
Lian Ruan, Jade Yang, Sherphylan Gao, Felix Gao, Kyson Liang, Galen Liu, and 20 more, 2026.
https://arxiv.org/abs/2609.27449
Jenai Xuning Yang, Rishit Dagli, Alex Zook, Hugo Hadfield, Ankit Goyal, Stan Birchfield, and 2 more, Robotics: Science and Systems XXII (2026).
https://arxiv.org/abs/2604.09860
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Tim Rädsch, Yuki M Asano, Hilde Kuehne, Stefan Bauer, Priyank Jaini, Robert Geirhos, and 1 more, 2026.
https://arxiv.org/abs/2606.18943
Peterson Co, Sicheng Hu, Chunxuan Jiao, Hongyang Cheng, Yulin Luo, Yijie Xu, and 14 more, 2026.
https://arxiv.org/abs/2608.09298
Further reading
Jack Parker-Holder, Shlomi Fruchter, Google DeepMind, 2025.
https://deepmind.google/blog/genie-3-a-new-frontier-for-world-models/
Yixuan Wang, Rhythm Syed, Fangyu Wu, Mengchao Zhang, Aykut Onol, Jose Barreiros, and 4 more, 2026.
https://arxiv.org/abs/2603.08546
Byeongguk Jeon, Seonghyeon Ye, JaeHyeok Doo, Sungdong Kim, Minjoon Seo, Hyungmok Son, and 1 more, 2026.
https://arxiv.org/abs/2607.01060
Spot a factual error or missing qualification? Report a content correction.