Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
Generative simulation is the use of generative models to author a simulator's tasks, scenes, assets and rewards while a physics engine, itself an unlearned world model, keeps the dynamicsSource 1. A 2026 survey finds the field shifting "from visual realism toward interaction readiness"Source 9.
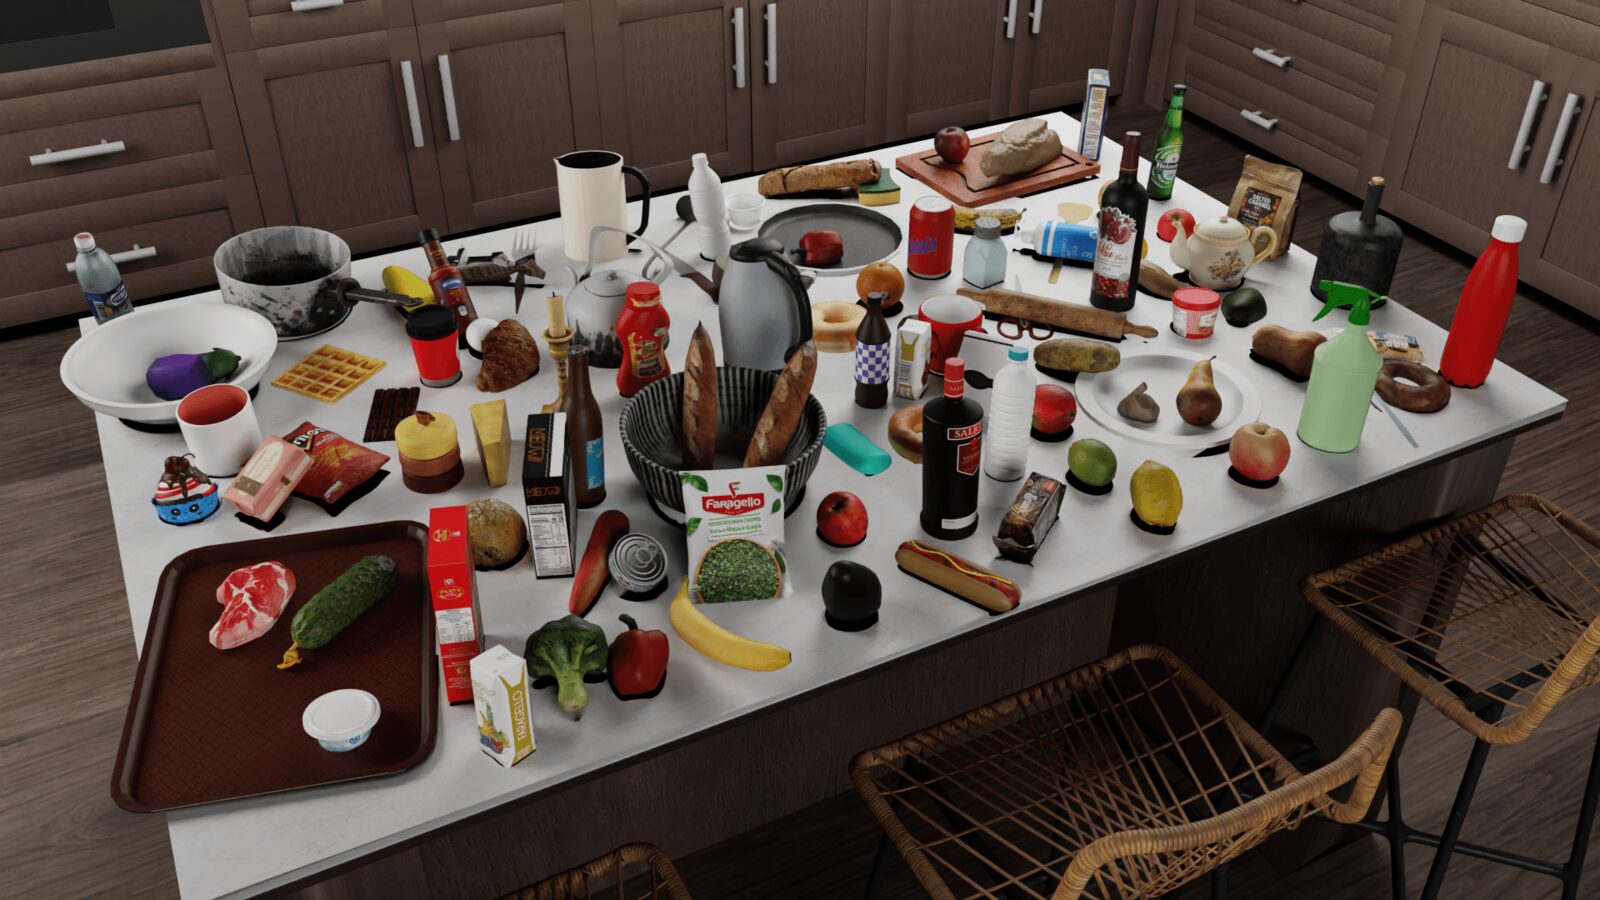
A rendered scene has no dynamics, and realism does not supply them: on Physics-IQ, physical understanding in video generators was "unrelated to visual realism"Source 10. Try it: push the mug as a picture only, then as a picture plus physics.
The push test
A realistic picture of a mug cannot be pushed
What is in the scene?
Adjust more
Pushed, but it is only a picture: no weight or friction, so it stays putmug moved 0 centimetres
illustrative, not measured
How this was made
The scene has three layers, drawn as a push bench. The picture is what a renderer or a generative model draws: here, the light a projector throws onto the plate. The physics proxy adds what a solver needs: the real mug, with its shape, a mass of 0.3 kilograms and a friction coefficient of 0.5 at its felt pad. The simulation layer is the solver, which turns each push into motion.
“Picture plus physics” sets the mug on the plate from its stand; “Adjust more” switches each layer on its own. Each push is an authored impulse held for 0.1 seconds, 4 newtons by default and 1 to 10 newtons with the push-strength slider, which cocks the plunger further. Friction stops the mug after d = v²/(2μg), so the default push slides it 18.1 centimetres; the bench plays the slide 4 times slower than real time. The table is 50 centimetres long and the mug stops at its end.
Nothing moves. A renderer is not a simulator: the rendered mug has no collision hull, friction or integrator to answer the push. The numbers are authored for this schematic, not measured on a real mug.
With only the picture, a push of 4 newtons leaves the mug at 0 centimetres: a picture has no shape, weight or friction for a solver to push against.
Current push-test layers
- picture
- on
- shape, weight and friction
- off
- physics solver
- on
- push strength
- 4 newtons
- moved
- 0.0 cm
- pushes that moved it
- 0
120
kitchen scenes
RoboCasa, RSS 2024
100
tasks
systematic evaluation suite
2,500+
3D objects
150+ categories
2,500
RoboCasa365
kitchens, ICLR 2026
The first three figures are from the 2024 RoboCasa releaseSource 3. RoboCasa365 reports a separate, larger setSource 4.
A physics engine keeps generated content physically consistent
Generative video learns physics from pixels, and a plausible future can ignore the pending action; the 2026 world-model survey calls visual plausibility a weak proxy for control utilitySource 7. Generative simulation moves the model off that path: a solver executes the generated task, layout, mesh or reward, so a mug with the wrong friction still cannot fall upward.
RoboGen automates task proposal, but humans still inspect the results
RoboGen runs a propose-generate-learn cycle: GPT-4 proposes tasks from a robot type and a sampled object, generates scene configurations, decomposes each task into sub-tasks, picks a learning method and supplies rewards or target-shape supervisionSource 1.
Locomotion, presented as an RL task, uses cross-entropy-method planning with the ground-truth simulator. Manipulation uses SAC with motion-planned primitives. Prompt design, in-context examples and human inspection of scenes, rewards, and learned skills remain. The authors name large-scale skill verification and sim-to-real transfer as openSource 1.
GenSim used GPT-4 to expand a benchmark tenfold to over 100 tasks, and pretrained policies beat baselines by 25% on unseen real long-horizon tasksSource 11. RoboTwin 2.0 repairs generated task code with simulation in the loop; a VLA trained on its data plus 10 real demonstrations improved 367% over the 10-demo baselineSource 12.
Holodeck builds rooms from prompts but does not test manipulation
Holodeck (CVPR 2024) uses GPT-4 to build AI2-THOR environments from text prompts. It selects Objaverse objects and proposes soft relational constraints, and a depth-first-search solver enforces collision and room boundaries while satisfying as many soft constraints as possibleSource 2.
Holodeck's evaluation, a navigation model pretrained on ProcTHOR-10K, fine-tuned in generated scenes and tested in artist-designed NoveltyTHOR rooms, does not test physically valid manipulation. The authors report trouble with complex layouts and with assets missing from ObjaverseSource 2.
Objaverse supplies 800K+ models without physical propertiesSource 13. SceneSmith (ICML 2026) adds text-to-3D assets, articulated retrieval and physical-property estimation, with 3 to 6 times more objects than prior methods, under 2% collisions and 96% of objects stableSource 14.
More generated demonstrations raised RoboCasa success from 26.3% to 47.6%
RoboCasa's 120 kitchen scenes combine 10 floor plans with 12 styles from architectural references. It holds 2,509 objects and 153 categories, plus 100 tasks: 25 atomic tasks and 75 composite tasks; GPT-4 and Gemini 1.5 drafted the composite blueprints, with human filtering, editing and code. Objects come from Objaverse and Luma.ai text-to-3D, textures from MidJourney, and MimicGen adapts human demonstrations and keeps successful trajectoriesSource 3. MimicGen itself turned about 200 human demonstrations into over 50K across 18 tasksSource 15.
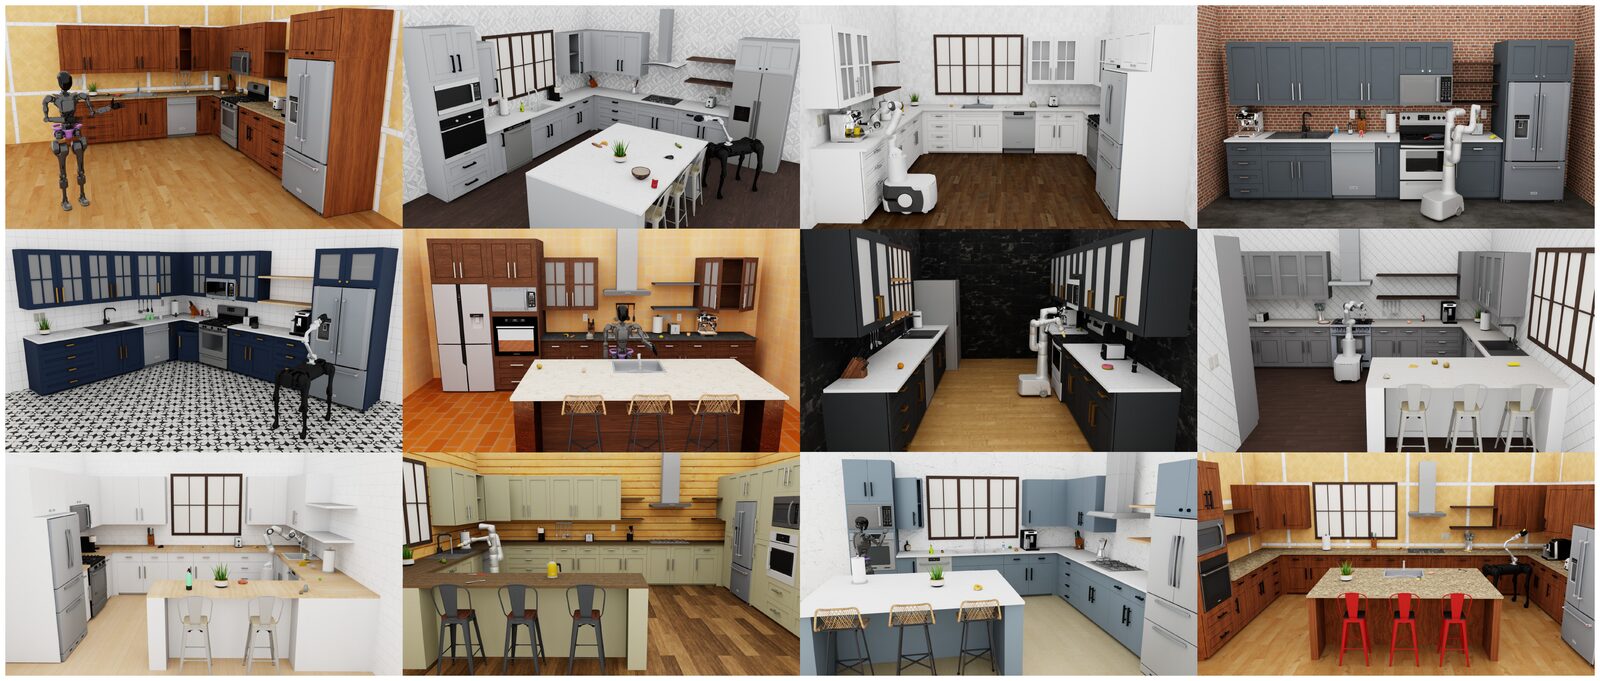
The scaling study trains a language-conditioned BC-Transformer for a Franka Panda on an Omron mobile base on 24 atomic tasks, excluding navigation, with 100, 300, or 3,000 generated demonstrations per task using Objaverse objects and AI-generated textures. Tested with curated textures, unseen objects and 50 trials per task in five kitchens, two in unseen styles, success is 26.3%, 35.0%, and 47.6% respectively. Individual tasks do not improve monotonicallySource 3. RoboCasa365 extends the platform to 365 tasks in 2,500 kitchens, with 600+ hours of human and 1,600+ hours of synthetic demonstrations for multi-task, foundation-model and lifelong-learning benchmarksSource 4.
Generators expand a few demonstrations or one image into training data
Isaac Lab Mimic splits human demonstrations into object-centric subtasks, transforms them and recombines them for new poses, from as little as one demonstration, across parallel environments. Results depend on SkillGen's trial counts, environment counts and planner settings, trading speed against success and motion qualitySource 6. SkillGen turned 60 human demonstrations into over 24K, and its agents were 24% more successful on averageSource 16. NVIDIA generated 780,000 simulated trajectories for GR00T N1, equal to 6,500 hours of human demonstration, in 11 hoursSource 17.
GRS starts from one real RGB-D image. SAM2 segments it, depth and a calibrated robot-frame transform give bounding boxes, and a vision-language model matches objects to supplied simulation-ready assets. A router revises generated task code and tests until an oracle policy completes the task. Experiments cap repair attempts, exclude runtime-error cases from the reported reward average and document failures that bypass intended behavior, and sim-to-real transfer is future workSource 5.
Generative simulation borrows its physics from the engine
The push figure separates three layers. Appearance renders the mug, as a reconstruction, texture or video frame might; a physics proxy adds collision geometry, mass and friction; and the simulator integrates the push, sliding the mug by every time. Cosmos-Transfer1 generates the first layer from segmentation, depth and edge inputsSource 18, and in the taxonomy's verdict on Gaussian Splatting twins, a real-time radiance-field renderer supplies only layer oneSource 19. Generative video tries to learn layer three, and generative simulation borrows layers two and three from an engine.
Generated content still needs physical and human checks
- Scenes are only as physically correct as their asset parameters: a text-to-3D mug's mass, friction and center of mass are estimates, and generated assets "often overlook rich and important physical properties"Source 20. Calibration is partly automated: Scalable Real2Sim identifies collision geometry and inertial parameters from joint-torque sensors and a cameraSource 21, and DrEureka constructs domain-randomization distributionsSource 22. Articulate-Anything raised articulation success to 75%, from 8.7% to 12.2% for prior workSource 23. The 3D-generation survey still names "the gap between geometric quality and physical validity" a main bottleneckSource 9.
- Task fitness may miss human intent. Eureka notes that its task metric may not match the behavior a person wants, and its authors call a generated PushBlock reward "amenable to post-hoc human inspection and editing" without requiring such inspection or comparing reward hackingSource 8. Text2Reward's generated rewards matched or beat expert rewards on 13 of 17 manipulation tasksSource 24. See reward design.
- Scene diversity has specific design sources. Holodeck's authors document cultural biases from the LLM and asset retrieval, with only qualitative evidence that new prompts helpSource 2. RoboCasa's authors drew floor plans and styles from home-design and architecture magazinesSource 3.
Policies trained on generated variations now transfer to real robots
Learned world models hold narrow roles in evaluation and data generation (generative video), while generative models author tasks, scenes, assets and supervision for physics enginesSource 1 Source 2 Source 3. Policies trained on digital cousins reached 90% zero-shot sim-to-real success against 25% for exact digital twinsSource 25. In 2026, SimFoundry's object, scene and task cousins raised zero-shot real success by 17%, 21% and 40%Source 26.
Liqian Ma, Danfei Xu and colleagues at Georgia Tech (October 2026) train a rater network by meta-gradients to learn which simulator settings produce useful co-training data for a real taskSource 31. With 10 real demonstrations per task and Diffusion Policy on a Franka Panda, MetaGenSim data gave 58 full-task successes in 80 real trials over four tasks, against 23 for uniformly sampled simulation data and 26 for real data aloneSource 31. Data from settings an expert aligned by hand gave 57Source 31.
Generators propose content and the engine integrates contact
A generator proposes layouts, tasks, textures and initial states; an asset pipeline checks for interpenetrating parts and attaches physical properties, as Infinigen-Articulated does for 18 articulated categoriesSource 27. Generated 3D worlds follow the same split: World Labs' Marble exports worlds as Gaussian splats and as meshes, including low-fidelity collider meshes for coarse physics simulationSource 29. The engine integrates contacts, a supervisor labels outcomes, and the dataset records which component produced every field. Engines now model more of the contact: Newton 1.0 adds SDF-based collision and hydroelastic contact for tight-tolerance assembly such as connector insertionSource 30.
Check asset scale and collision geometry before dynamics, static stability before rollouts and contact parameters against real measurements before claiming transfer. Steerable scene generation enforces feasibility "via projection and simulation" and releases over 44 million scenesSource 28. Keep failed scenes as adversarial tests; the simulator comparison gives the selection rule.
See also
- Massively Parallel Sim RL
GPU-parallel simulation with Isaac Lab, Newton, MJX and Brax.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
Linked from
- Why RL Won Locomotion but Not Manipulation
Walking is cheap to simulate; contact-rich manipulation is not.
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- World Model Evaluation for Robotics
Testing a world model on what a robot needs.
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- Motion Planning
Configuration space, RRT and its variants, and trajectory optimization.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
References
Yufei Wang, Zhou Xian, Feng Chen, Tsun-Hsuan Wang, Yian Wang, Katerina Fragkiadaki, and 3 more, ICML 2024.
https://arxiv.org/abs/2311.01455
Yue Yang, Fan-Yun Sun, Luca Weihs, Eli VanderBilt, Alvaro Herrasti, Winson Han, and 8 more, CVPR 2024.
https://arxiv.org/abs/2312.09067
Soroush Nasiriany, Abhiram Maddukuri, Lance Zhang, Adeet Parikh, Aaron Lo, Abhishek Joshi, and 2 more, RSS 2024.
https://arxiv.org/abs/2406.02523
Soroush Nasiriany, Sepehr Nasiriany, Abhiram Maddukuri, Yuke Zhu, ICLR 2026.
https://robocasa.ai/assets/robocasa365_iclr26.pdf
Alex Zook, Fan-Yun Sun, Josef Spjut, Valts Blukis, Stan Birchfield, Jonathan Tremblay, 2024.
https://arxiv.org/abs/2410.15536
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Yecheng Jason Ma, William Liang, Guanzhi Wang, De-An Huang, Osbert Bastani, Dinesh Jayaraman, and 3 more, ICLR 2024.
https://arxiv.org/abs/2310.12931
Tianwei Ye, Yifan Mao, Minwen Liao, Jian Liu, Chunchao Guo, Dazhao Du, and 3 more, 2026.
https://arxiv.org/abs/2604.26509
Saman Motamed, Laura Culp, Kevin Swersky, Priyank Jaini, Robert Geirhos, 2025.
https://arxiv.org/abs/2501.09038
Lirui Wang, Yiyang Ling, Zhecheng Yuan, Mohit Shridhar, Chen Bao, Yuzhe Qin, and 3 more, 2023.
https://arxiv.org/abs/2310.01361
Tianxing Chen, Zanxin Chen, Baijun Chen, Zijian Cai, Yibin Liu, Zixuan Li, and 20 more, 2025.
https://arxiv.org/abs/2506.18088
Matt Deitke, Dustin Schwenk, Jordi Salvador, Luca Weihs, Oscar Michel, Eli VanderBilt, and 4 more, 2022.
https://arxiv.org/abs/2212.08051
Nicholas Pfaff, Thomas Cohn, Sergey Zakharov, Rick Cory, Russ Tedrake, ICML 2026 (Spotlight).
https://arxiv.org/abs/2602.09153
Ajay Mandlekar, Soroush Nasiriany, Bowen Wen, Iretiayo Akinola, Yashraj Narang, Linxi Fan, and 2 more, CoRL 2023.
https://arxiv.org/abs/2310.17596
Caelan Garrett, Ajay Mandlekar, Bowen Wen, Dieter Fox, 2024.
https://arxiv.org/abs/2410.18907
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
NVIDIA, Hassan Abu Alhaija, Jose Alvarez, Maciej Bala, Tiffany Cai, Tianshi Cao, and 34 more, 2025.
https://arxiv.org/abs/2503.14492
Bernhard Kerbl, Georgios Kopanas, Thomas Leimkühler, George Drettakis, ACM Trans. Graph. 42(4), author manuscript (2023).
https://arxiv.org/abs/2308.04079
Ziang Cao, Zhaoxi Chen, Liang Pan, Ziwei Liu, NeurIPS 2025 (Spotlight).
https://arxiv.org/abs/2507.12465
Nicholas Pfaff, Evelyn Fu, Jeremy Binagia, Phillip Isola, Russ Tedrake, 2025.
https://arxiv.org/abs/2503.00370
Yecheng Jason Ma, William Liang, Hung-Ju Wang, Sam Wang, Yuke Zhu, Linxi Fan, and 2 more, RSS 2024.
https://arxiv.org/abs/2406.01967
Long Le, Jason Xie, William Liang, Hung-Ju Wang, Yue Yang, Yecheng Jason Ma, and 4 more, ICLR 2025, 2024.
https://arxiv.org/abs/2410.13882
Tianbao Xie, Siheng Zhao, Chen Henry Wu, Yitao Liu, Qian Luo, Victor Zhong, and 2 more, ICLR 2024, 2023.
https://arxiv.org/abs/2309.11489
Tianyuan Dai, Josiah Wong, Yunfan Jiang, Chen Wang, Cem Gokmen, Ruohan Zhang, and 2 more, CoRL 2024.
https://arxiv.org/abs/2410.07408
Nadun Ranawaka, Josiah Wong, Wei-Lin Pai, Wei-Teng Chu, Tianyuan Dai, Masoud Moghani, and 12 more, 2026.
https://arxiv.org/abs/2606.28276
Abhishek Joshi, Beining Han, Jack Nugent, Max Gonzalez Saez-Diez, Yiming Zuo, Jonathan Liu, and 9 more, 2025.
https://arxiv.org/abs/2505.10755
Nicholas Pfaff, Hongkai Dai, Sergey Zakharov, Shun Iwase, Russ Tedrake, 2025.
https://arxiv.org/abs/2505.04831
World Labs, World Labs, 2025.
https://www.worldlabs.ai/blog/marble-world-model
Philipp Reist, Miguel Zamora Mora, JC Chang, Rishabh Chadha, Mohammad Mohajerani, 2026.
https://developer.nvidia.com/blog/newton-adds-contact-rich-manipulation-and-locomotion-capabilities-for-industrial-robotics
Liqian Ma, Vaibhav Saxena, Utkarsh Aashu Mishra, Shuo Cheng, Yongxin Chen, Danfei Xu, 2026.
https://arxiv.org/abs/2610.19479
Further reading
Stone Tao, Fanbo Xiang, Arth Shukla, Yuzhe Qin, Xander Hinrichsen, Xiaodi Yuan, and 17 more, 2024.
https://arxiv.org/abs/2410.00425
Matt Deitke, Eli VanderBilt, Alvaro Herrasti, Luca Weihs, Jordi Salvador, Kiana Ehsani, and 5 more, 2022.
https://arxiv.org/abs/2206.06994
Marcel Torne, Anthony Simeonov, Zechu Li, April Chan, Tao Chen, Abhishek Gupta, and 1 more, 2024.
https://arxiv.org/abs/2403.03949
Genesis AI, PyPI, version 1.4.3 as of 2026-10-08.
https://pypi.org/project/genesis-world/
Tianyi Xie, Haotian Zhang, Jinhyung Park, Zi Wang, Bowen Wen, Jiefeng Li, and 14 more, 2026.
https://arxiv.org/abs/2606.05160
World Labs, World Labs, 2026.
https://www.worldlabs.ai/blog/atlas
Spot a factual error or missing qualification? Report a content correction.