World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
Learned world models and physics simulators both predict what an action does: MuJoCo computes it from explicit geometry, dynamics and contact rulesSource 1, while a learned model predicts it from data. Physics suits mechanics that can be specified and actions no dataset covers, learning suits appearance and contact that are costly to model, and many systems combine the two.
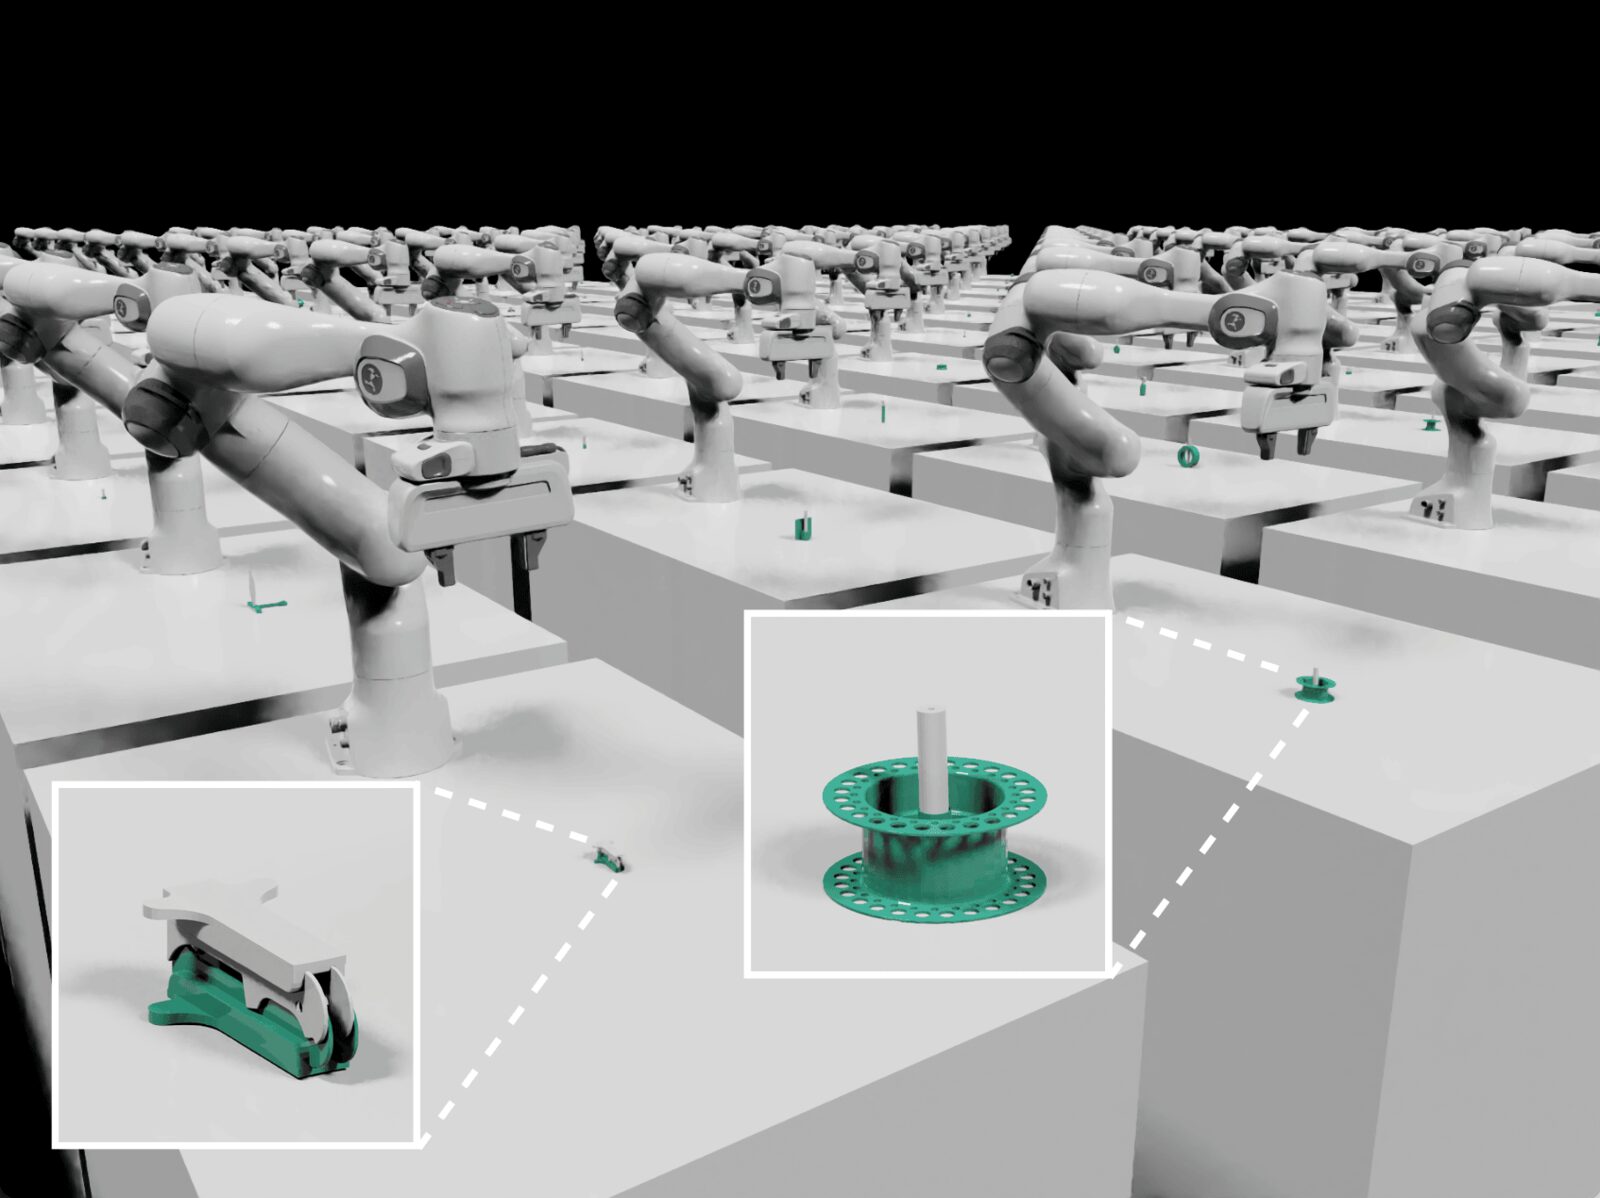
Hwangbo and colleagues kept ANYmal's rigid-body physics and learned an "actuator net" for its 12 joints. The hybrid simulator ran about a thousand times faster than real timeSource 17.
Self-check
Read the reasoning
- Replace the entire physics simulator with an unconstrained video world modelThis discards useful geometry and asks limited robot data to relearn every transition. It also makes forces and constraints harder to inspect.
- Learn an actuator residual while retaining explicit geometry and physicsThis targets the measured mismatch and keeps known structure intact. The residual can be validated directly against held-out hardware trajectories.
- Randomize the rendered texturesTexture randomization can improve visual transfer, but it does not correct a systematic actuator-dynamics error.
Keep trustworthy structure explicit and spend learned capacity on the residual you can measure.
They solve different specification problems
MuJoCo models articulated bodies, constraints and contact with explicit equations and parametersSource 1. Isaac Lab wraps GPU simulation, sensors, task definitions and batched environments into a robot-learning workflowSource 2. Disney Research, Google DeepMind and NVIDIA gave their Newton GPU engine to the Linux Foundation in September 2025Source 18. NVIDIA reports that MuJoCo Warp speeds up MJX by 252x on locomotion and 475x on manipulation on an RTX PRO 6000 Blackwell GPUSource 29.
A learned world model estimates transitions from observations and actions, often in a latent or video space, and trades parameter error for dataset and generalization error. Hansen and Wang call hallucination "inherently a data coverage issue"Source 19. A 2026 survey lists simulation among a world model's roles, with planning, policy learning, evaluation and data generationSource 3.
Comparison by engineering property
| Property | Physics simulator | Learned world model |
|---|---|---|
| Dynamics source | equations and parameters | observed transitions |
| Counterfactual coverage | broad within modeled mechanics | strongest near training support |
| State access | explicit positions, forces and contacts | latent or generated observations |
| Debugging | inspect parameters and constraints | inspect errors and sensitivity indirectly |
| Appearance | authored assets and renderers | learned from image or video data |
| Adaptation | identify parameters or modify models | fine-tune on new trajectories |
| Failure mode | wrong assumptions or parameters | action collapse, drift, hallucination |
| Compute pattern | many small integration steps | large neural inference calls |
A latent planner needs seconds per action, a video planner minutes
The table compares the query cost of four representations on one machine; the FLOP row is a derived order-of-magnitude estimate. For a physics baseline, Isaac Gym steps thousands of environments in parallel on one GPU and trained robot tasks 2 to 3 orders of magnitude faster than CPU-simulator pipelinesSource 20.
| Quantity | 8B text LLM (decode) | Latent WM (V-JEPA 2-AC) | AR / diffusion WM (Cosmos Predict) | Explicit 3D world (3DGS) |
|---|---|---|---|---|
| Model memory | ~16 GB fp16 (8B params x 2 bytes, derived); ~5 GB at 4-bit weights (derived) | ~2.6 GB fp16, derived from the stated 1B encoder + 0.3B predictor params | 32.5 to 56.4 GB required VRAM (Predict2 Video2World, 2B to 14B); Predict1 14B card lists >80 GB with the prompt upsampler offloaded | 0; the scene is an asset, not weights |
| Runtime state per step | KV cache, ~128 KB per token (derived: 32 layers x 8 KV heads x 128-dim) | block-causal context: patch features, actions and poses of the current and earlier steps | latents plus KV, grows with clip length | splat set; 0.3 to 0.7 GB per scene (dataset averages, Table 1) |
| Single-GPU fit | fits a 24 GB-class GPU (~16 GB fp16 weights, derived) | 24 GB class, easy | 14B needs 56.38 GB (fits an 80 GB H100); 2B needs 32.54 GB, vendor recommends >=32 GB | any rasterizer GPU; the scene asset grows with splat count |
| Unit of work | 1 token | 1 latent step | 1 clip x N denoise steps | 1 camera view |
| Sequence tokens in that unit | 1 | 256 patch tokens per frame (derived from the stated 16 x 16 patch grid) plus action and pose tokens | token count scales with clip length, resolution and tokenizer compression (4x8x8 to 8x16x16 factors in the paper) | 0 transformer tokens |
| Parallel multiplier | batching shares weights | CEM samples, 10^2 to 10^3 (the paper uses 800) | one clip at a time; denoise-pass count not stated by the cited sources | 1 raster pass |
| Latency to useful output | weight-bandwidth-bound per token (authored reasoning; no benchmark cited) | about 16 s per planned action (800 samples x 10 refinements) | Predict2: about 26 s (2B, GB200) to over 30 min (14B, DGX Spark) per 480p, 16 fps clip; Predict1 14B: about 10 min per 5 s clip on one H100 with offloading | under 30 ms per frame |
| Approx. FLOP per unit vs 8B token | 1x | ~10x per latent step; ~10^5x per planned action (800 samples x 10 refinements) | ~10^5 to 10^6x per frame | near 0 transformer FLOP |
| Bottleneck | weight bandwidth | batched predictor GEMMs | denoise FLOPs plus KV traffic | splat sorting and fill rate |
| Scaling with horizon | KV grows linearly with context | context grows with each predicted step; the paper plans one step ahead | linear in tokens times steps | free; the asset already exists |
| Scaling with batch | linear KV, then compute-bound | batched CEM is the intended mode | usually batch 1 per clip | extra cameras render nearly free |
As the decode reference, Llama 3 8BSource 10 holds about 16 GB of fp16 weights. Its 32 layers and 8 grouped-query key-value headsSource 11 give a KV cache of about 128 KB per token.
In the latent column, V-JEPA 2-AC's cross-entropy planner takes about 16 seconds per action with 800 samples over 10 iterations. A Cosmos video planner took about 4 minutes with 80 samples, roughly 15x slower, and both looked one step aheadSource 12. LeWorldModel plans up to 48x faster than foundation-model world modelsSource 21.
Clip generators run far slower than interactive world models
In the costlier video column, Cosmos Predict1 spans diffusion models at 7B to 14B and autoregressive models at 4B to 13BSource 13. NVIDIA measured Predict2's 14B Video2World at 56 GB of VRAM and about 85 seconds per 480p clip on a GB200, over 30 minutes on a DGX SparkSource 14. The Predict1 14B card lists over 80 GB for a five-second 1280x704 clip with the prompt upsampler offloadedSource 15. Such offline clip generators cannot serve as 24 fps runtimes, and a policy calling one per action step inherits their latency.
DeepMind reports that Genie 3 runs at 24 fps and 720pSource 22, and the Interactive World Simulator holds 15 FPS for over 10 minutes on one RTX 4090Source 23. DreamZero controls a robot at 7 Hz from a 14B video modelSource 24.
Gaussian splats render in milliseconds but carry no dynamics
3D Gaussian Splatting renders rasterizable primitives in tens of milliseconds or less per frame, with no weights or tokens, and stores the scene as an asset of 1 to 5 million GaussiansSource 16. A splat shows what a view looks like; physics must say what an action does.
Physics stays ahead for untried actions and checkable safety limits
Planning, as in model-based RL, queries actions the dataset did not take. A physics engine integrates them while its modeled regime holds; a learned model must extrapolate, and a planner can exploit its errors by picking actions with spuriously high predicted reward. Across six video generators, physical understanding was "severely limited, and unrelated to visual realism"Source 25. Safety constraints also favor explicit state: joint limits, collision geometry, force bounds and signed distances can be checked directly, while a predicted video may imply a collision without the quantity a monitor needs.
Untried actions
A planner finds where its learned model is wrong
Where the planner may search
Lit: the learned model. Posts: the actions triedPast the data · scored high, really low
Schematic: one action, an illustrative reward and model
How this was made
Planning asks a model about actions the dataset never took. A physics engine computes them while its modelled regime holds; a learned model has to extrapolate, and a planner can exploit its errors by picking actions with spuriously high predicted reward.
The drawing is that search on a fairing bench. The template's top edge is the real reward for every action, from left to right. The batten, lit, is the learned model: clamped at the seven actions that were tried, all on the data strip at the left, it lies along the real edge between them, and past the last clamp it carries on along its last slope, as a draftsman's spline does. The carriage reads the batten and stops where it is highest, then drops a probe onto the template to read what that action really returns. Searching everywhere, it runs past the data to the far end, where the batten is highest and the real edge is low. With the stop raised at the data's edge, it keeps to actions near what was tried, and the batten and the template agree there.
Schematic: one action, an illustrative reward curve and a model that fits the tried actions exactly; no number is claimed. Real planners search many action dimensions at once, which leaves far more room outside the data.
The article's argument about untried actions, drawn as a schematic.
Learning captures appearance and contact that are costly to model
A learned visual model can absorb from video the textures, reflections, cables and clutter that are expensive to render; deformable contacts, unmodeled actuators and wear also resist parameterization. Robotic World Model aims a neural simulator at policy optimizationSource 4, and RoboWorld at policy evaluation, with task-progress scoring and rankings validated against real robotsSource 9.
Four hybrid patterns
Learn appearance, keep dynamics
Real-to-sim systems reconstruct a scene's appearance and keep a physics engine for motion and contact, as RoboGSim does with Gaussian splattingSource 5. SplatSim's splat-rendered simulator gave zero-shot RGB policies 86.25% success, against 97.5% when trained on real dataSource 26. The pattern suits rigid-body tasks and is weaker for friction or tool compliance. PhysTwin extends it to deformables, building spring-mass twins of ropes, stuffed animals, cloth and delivery packages from videos and rendering them with Gaussian splatsSource 27.
Generate content, keep the engine
Generative simulation uses models to author objects, layouts, tasks and assets inside a physics engine, so the generator supplies coverage while the engine keeps contact causal. RoboCasa supplies large-scale everyday manipulation environmentsSource 6, and RoboCasa365 extends it to training and benchmarking generalist robotsSource 7.
Learn residual dynamics
Residual models start from explicit dynamics and learn the measured difference, such as actuator delay or contact impulses. With a named error to fit, this is the most conservative hybridSource 17. ASAP trains a delta action model on real Unitree G1 data and beats system-identification, domain-randomization and delta-dynamics baselines on tracking errorSource 28. A residual fitted to nominal walking may still fail on a fall.
Pretrain in simulation, adapt dynamics on hardware
SimDist trains a world model on simulated experience, then on real data updates only the latent dynamics, keeping the encoder, reward model and value function. Its authors say this reduces adaptation to supervised system identification, and it kept improving with experience on contact-rich manipulation and quadruped locomotionSource 30.
Evaluation must use the same real anchor
Both simulator types can be wrong in correlated ways: a policy may exploit contact softness in physics or visual shortcuts in a world model. SIMPLER builds matched environments and correlates simulated with real policy performanceSource 8. Apply that test to both types with several policy families and held-out environments, scored on the same real outcome (world-model evaluation).
Choose by what can be specified and what the data cover
Use explicit physics when state and mechanics can be specified, counterfactuals are broad, constraints need inspection or parallel stepping matters most (parallel simulation for RL). Use a learned world model when real observations hold structure that is costly to author, data cover the decisions of interest and validation can anchor model error. Use a hybrid for a localized mismatch, as ANYmal's simulator didSource 17; classical control and latent dynamics cover the two ends.
See also
- Massively Parallel Sim RL
GPU-parallel simulation with Isaac Lab, Newton, MJX and Brax.
- Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
Linked from
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Massively Parallel Sim RL
GPU-parallel simulation with Isaac Lab, Newton, MJX and Brax.
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
References
Emanuel Todorov, Tom Erez, Yuval Tassa, IROS 2012.
https://doi.org/10.1109/IROS.2012.6386109
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Chenhao Li, Andreas Krause, Marco Hutter, 2025.
https://arxiv.org/abs/2501.10100
Xinhai Li, Jialin Li, Ziheng Zhang, Rui Zhang, Fan Jia, Tiancai Wang, and 3 more, 2024.
https://arxiv.org/abs/2411.11839
Soroush Nasiriany, Abhiram Maddukuri, Lance Zhang, Adeet Parikh, Aaron Lo, Abhishek Joshi, and 2 more, RSS 2024.
https://arxiv.org/abs/2406.02523
Soroush Nasiriany, Sepehr Nasiriany, Abhiram Maddukuri, Yuke Zhu, ICLR 2026.
https://robocasa.ai/assets/robocasa365_iclr26.pdf
Xuanlin Li, Kyle Hsu, Jiayuan Gu, Karl Pertsch, Oier Mees, Homer Rich Walke, and 10 more, 2024.
https://arxiv.org/abs/2405.05941
Byeongguk Jeon, Seonghyeon Ye, JaeHyeok Doo, Sungdong Kim, Minjoon Seo, Hyungmok Son, and 1 more, 2026.
https://arxiv.org/abs/2607.01060
Meta AI, 2024.
https://ai.meta.com/blog/meta-llama-3/
Aaron Grattafiori, Abhimanyu Dubey, Abhinav Jauhri, 2024.
https://arxiv.org/abs/2407.21783
Mahmoud Assran, Adrien Bardes, David Fan, Quentin Garrido, Russell Howes, Mojtaba Komeili, and 23 more, 2025.
https://arxiv.org/abs/2506.09985
NVIDIA, 2025.
https://github.com/nvidia-cosmos/cosmos-predict2/blob/main/documentations/performance.md
NVIDIA, 2025.
https://catalog.ngc.nvidia.com/orgs/nvidia/cosmos/models/cosmos-1.0-diffusion-14b-video2world
Bernhard Kerbl, Georgios Kopanas, Thomas Leimkühler, George Drettakis, ACM Trans. Graph. 42(4), author manuscript (2023).
https://arxiv.org/abs/2308.04079
Jemin Hwangbo, Joonho Lee, Alexey Dosovitskiy, Dario Bellicoso, Vassilios Tsounis, Vladlen Koltun, and 1 more, Science Robotics 4(26), 2019.
https://arxiv.org/abs/1901.08652
The Linux Foundation, Linux Foundation press release, 2025.
https://www.linuxfoundation.org/press/linux-foundation-announces-contribution-of-newton-by-disney-research-google-deepmind-and-nvidia-to-accelerate-open-robot-learning
Nicklas Hansen, Xiaolong Wang, 2026.
https://arxiv.org/abs/2606.27326
Viktor Makoviychuk, Lukasz Wawrzyniak, Yunrong Guo, Michelle Lu, Kier Storey, Miles Macklin, and 5 more, 2021.
https://arxiv.org/abs/2108.10470
Lucas Maes, Quentin Le Lidec, Damien Scieur, Yann LeCun, Randall Balestriero, 2026.
https://arxiv.org/abs/2603.19312
Jack Parker-Holder, Shlomi Fruchter, Google DeepMind, 2025.
https://deepmind.google/blog/genie-3-a-new-frontier-for-world-models/
Yixuan Wang, Rhythm Syed, Fangyu Wu, Mengchao Zhang, Aykut Onol, Jose Barreiros, and 4 more, 2026.
https://arxiv.org/abs/2603.08546
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
Saman Motamed, Laura Culp, Kevin Swersky, Priyank Jaini, Robert Geirhos, 2025.
https://arxiv.org/abs/2501.09038
Mohammad Nomaan Qureshi, Sparsh Garg, Francisco Yandun, David Held, George Kantor, Abhisesh Silwal, 2024.
https://arxiv.org/abs/2409.10161
Hanxiao Jiang, Hao-Yu Hsu, Kaifeng Zhang, Hsin-Ni Yu, Shenlong Wang, Yunzhu Li, 2025.
https://arxiv.org/abs/2503.17973
Tairan He, Jiawei Gao, Wenli Xiao, Yuanhang Zhang, Zi Wang, Jiashun Wang, and 12 more, RSS 2025.
https://arxiv.org/abs/2502.01143
Philipp Reist, Miguel Zamora Mora, JC Chang, Rishabh Chadha, Mohammad Mohajerani, 2026.
https://developer.nvidia.com/blog/newton-adds-contact-rich-manipulation-and-locomotion-capabilities-for-industrial-robotics
Jacob Levy, Tyler Westenbroek, Kevin Huang, Fernando Palafox, Patrick Yin, Shayegan Omidshafiei, and 3 more, RSS 2026.
https://arxiv.org/abs/2603.15759
Further reading
NVIDIA, Arslan Ali, Junjie Bai, Maciej Bala, Yogesh Balaji, Aaron Blakeman, and 83 more, 2025.
https://arxiv.org/abs/2511.00062
Danijar Hafner, Wilson Yan, Timothy Lillicrap, 2025.
https://arxiv.org/abs/2509.24527
1X AI Team, 1X Technologies, 2026.
https://www.1x.tech/discover/world-model-self-learning
Nadun Ranawaka, Josiah Wong, Wei-Lin Pai, Wei-Teng Chu, Tianyuan Dai, Masoud Moghani, and 12 more, 2026.
https://arxiv.org/abs/2606.28276
Spot a factual error or missing qualification? Report a content correction.