Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
Scene representation is how a robot stores what it knows about its surroundings so that planners, controllers and other consumers can query itSource 8. Representations range from point clouds and occupancy grids to signed-distance fields, meshes and neural fields such as radiance fields and Gaussian splatsSource 8 Source 23.
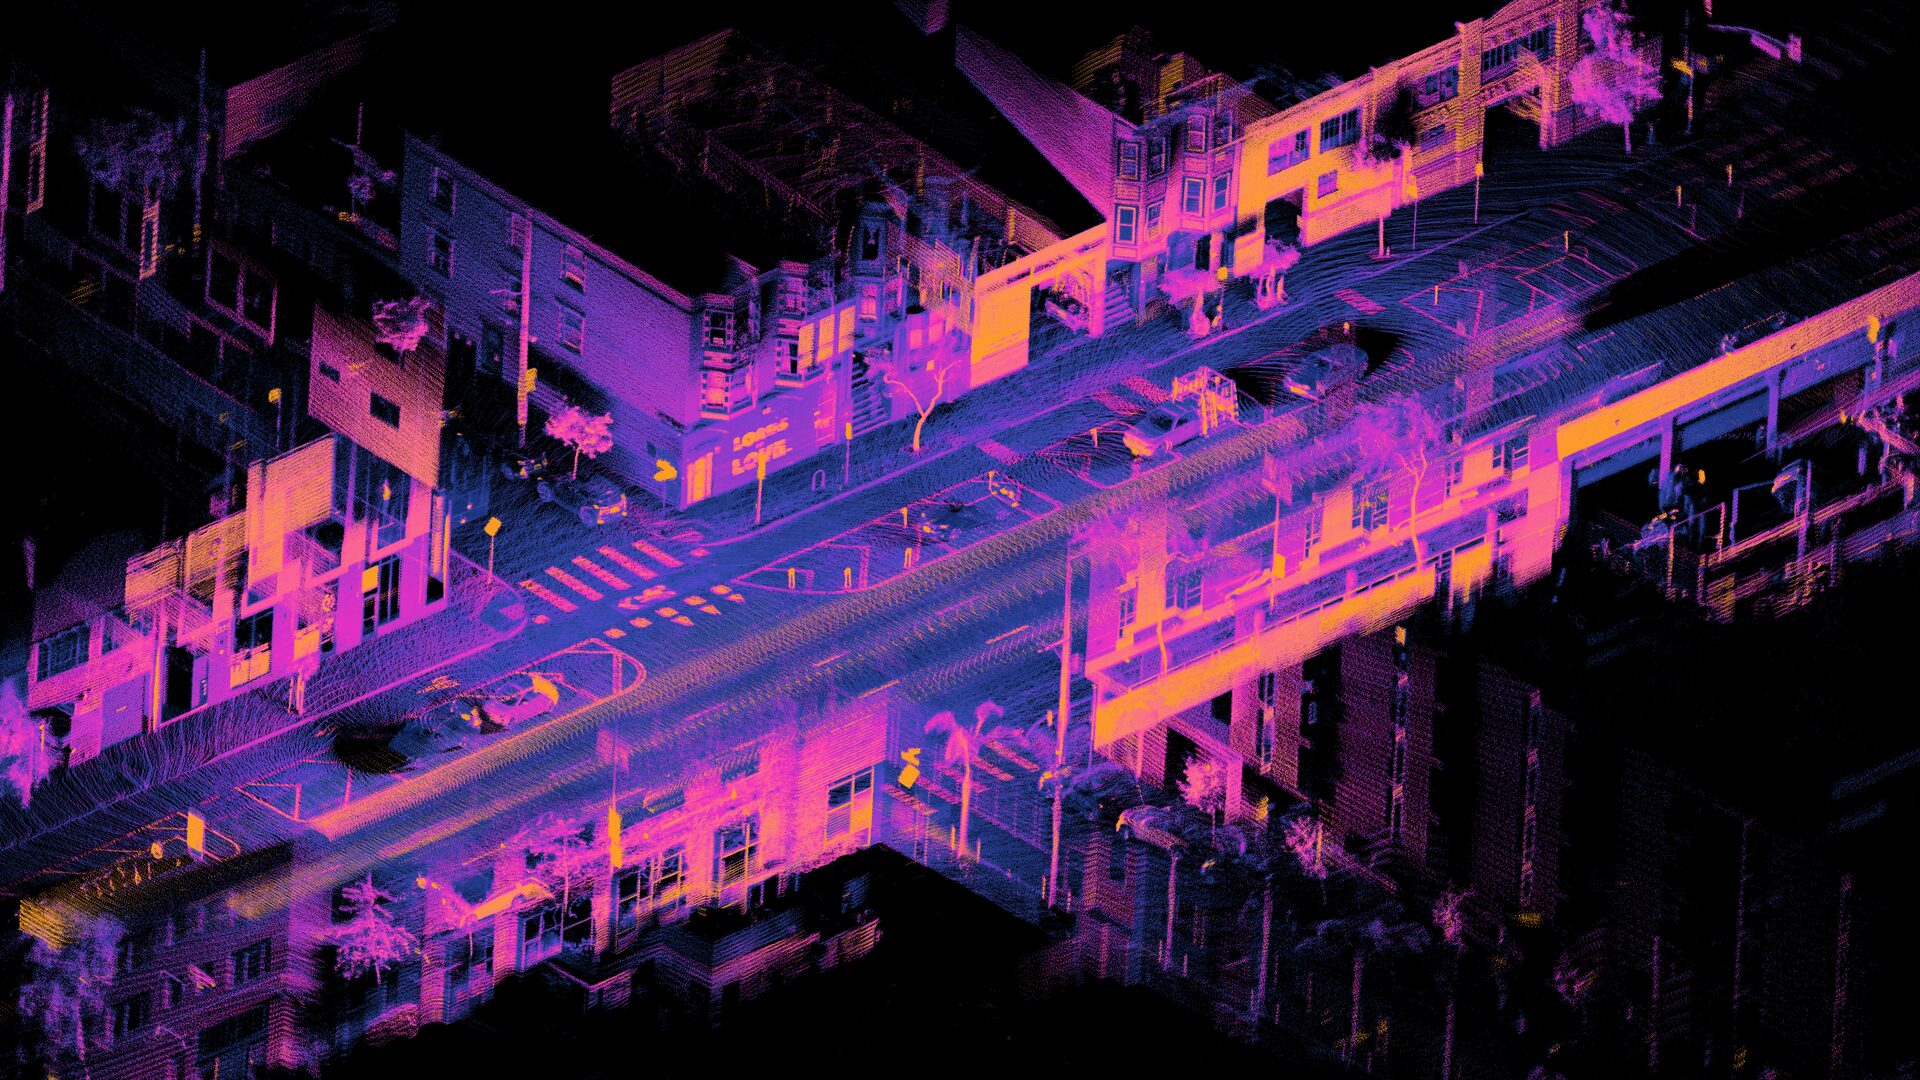
The ladder, and what each rung can answer
Three queries separate the rungs: whether a cell is free for a planner, which way a surface faces for a contact solver, and what the scene looks like from a viewpoint the sensor never occupied. Cadena and colleagues judge representations by storage size, construction cost and usefulness for the taskSource 8.
Scene representations
Each way of storing a room answers different questions
Engineers call this an occupancy grid
More detail: sharper picture, more storage, same answers.
Adjust more
Storage for this room: 2.2 KB, in 2,250 voxels at 20 cm spacing
What it can answer
Can the robot move here?Yes
Which way does the surface face?No
What does it look like from here?No
something thereunknownemptythe real room, faint
Schematic: a made-up room seen from above, not measured
How this was made
Synthetic scene: a 3.0 by 3.0 by 2.0 m cell holding a 2 cm post, a transparent bottle and an occluder (the box), with the sensor (the camera) at the near edge. Footprints come from declared storage models, volumetric stores billed over the whole volume and surface stores over the observed area only, which is why a narrow-band signed-distance field holds fewer cells than the occupancy grid it resembles and its cost grows more slowly as the spacing shrinks Source 2. The bottle is drawn 16 cm behind its true face, where a depth sensor reports it, and the thin post survives only while the spacing resolves it. Behind the occluder the occupancy grid keeps an explicit unknown, where the Gaussian splat renders geometry nothing measured Source 1.
An occupancy grid stores: One occupancy probability per voxel, held as log-odds and updated by every ray that passes through. Behind the occluder it holds: An explicit unknown label, held apart from free and from occupied, which is the property the planner needs.
Storage for this room as an occupancy grid, coarse to fine: 667 voxels (667 B) at 30 cm; 2,250 voxels (2.2 KB) at 20 cm; 5,333 voxels (5.2 KB) at 15 cm; 18,000 voxels (18 KB) at 10 cm. The three answers are the same at every spacing.
Can the robot move here? (Is this cell free): yes; free, occupied and unknown are three distinct cell states.
Which way does the surface face? (Surface normal for contact): no; the surface sits somewhere inside an occupied voxel and the grid never says where.
What does it look like from here? (Render a novel view): no; no appearance is stored, only occupancy.
Stored as an occupancy grid at 20 cm, the same scene costs 2.2 KB across 2,250 voxels, and answers 1 of the 3 queries: free space yes, a contact normal no, a novel view no.
Current representation, resolution and footprint
- representation
- Occupancy grid
- resolution
- 20 cm
- footprint
- 2.2 KB
- voxels
- 2,250
- answers
- 1 of 3
Point clouds and occupancy grids
A point cloud is an unordered set of 3D points, and PointNet requires invariance to the order in which they arriveSource 22. A region without points is either empty or unobserved, and the store cannot say which.
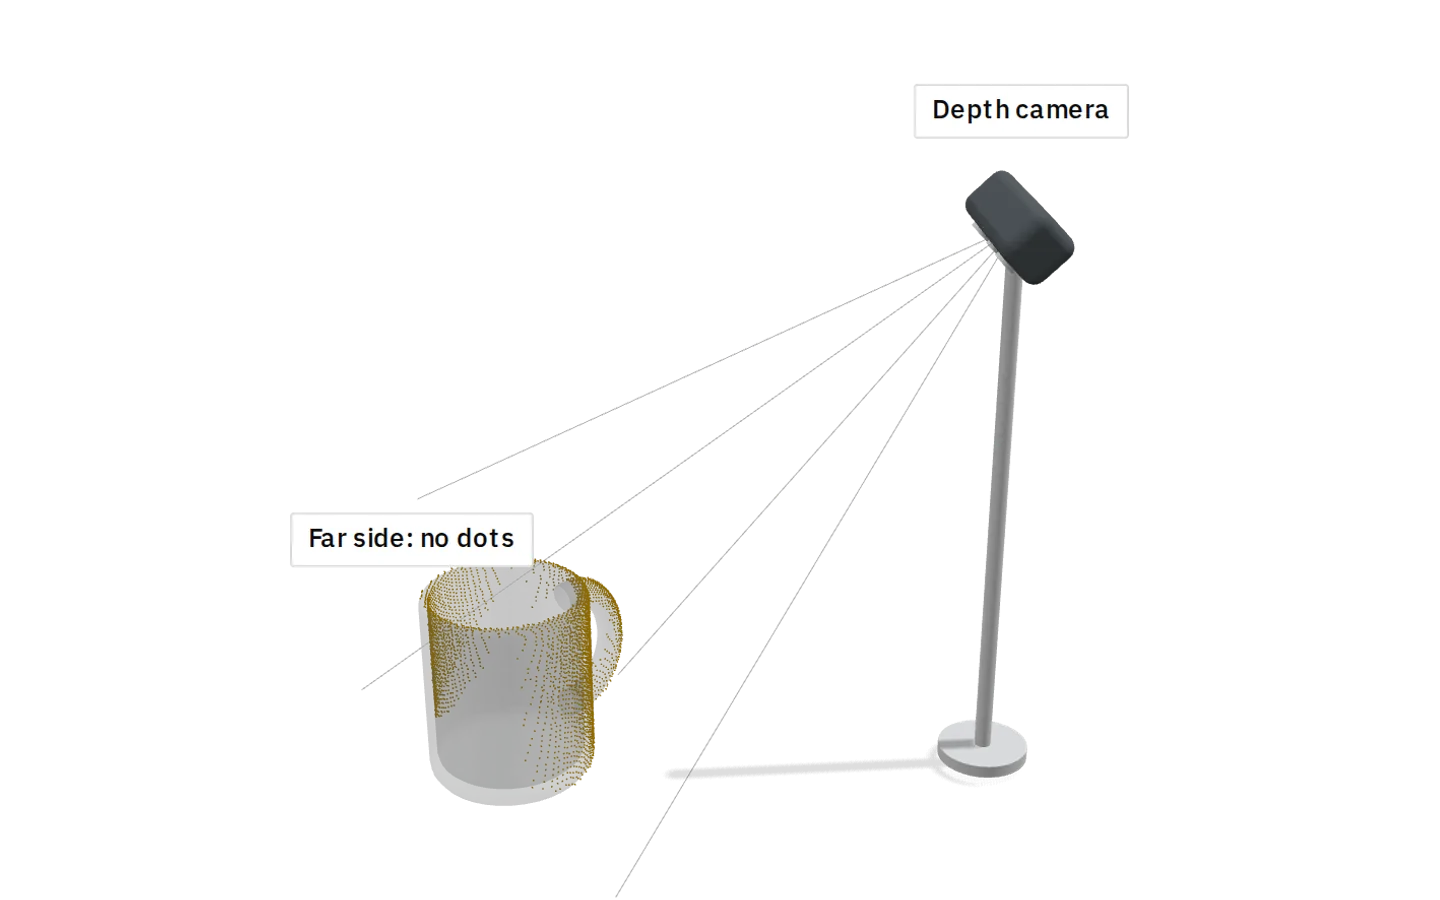
Moravec and Elfes projected wide-angle sonar readings from different sensors and robot positions onto a 2D occupancy grid. Each reading marked a probably empty beam interior and an uncertain reflecting point near the measured range, and overlapping readings refined these constraints. Zero represented unknown occupancy, and negative and positive values probably empty and probably occupied cellsSource 1. OctoMap carries the three states into 3D in a compressed octreeSource 24. Step through the figure below to see one mug stored four ways.
What does a robot actually see?
Loading…
A depth camera also measures how far away each point is. Each point becomes a dot, but only on the side it sees.
A robot can store a mug as dots, cubes, a skin or soft blobs, and each suits a different job.
How this was made
The steps in words
- A depth camera also measures how far away each point is. Each point becomes a dot, but only on the side it sees.
- Cubes split space into a grid. Each box is either part of the mug or empty. Blocky, but simple.
- A skin joins points on the surface into small flat triangles, giving the smooth, exact shape a robot needs to plan its grip.
- Soft blobs overlap into one surface. Each blob can also carry colour, so together they can look like a photo.
- Same mug, four ways to store it. Each trades detail against speed and memory. These are scene representations.
Signed-distance fields
Curless and Levoy fuse range images into a cumulative weighted signed distance function and recover the surface at its zero crossing, truncating distance ramps and weights near observed points. Their hole-filling construction marks empty space with negative and unseen space with positive , both at zero weightSource 2. KinectFusion uses the opposite sign: positive toward visible free space and negative on the non-visible sideSource 3.
KinectFusion fused 11-bit, 640×480 Kinect depth frames at 30 Hz, tracking each frame against the global model by coarse-to-fine ICP and mapping at the sensor rate on a commodity GPU. A large plane filling most of the view can cause drift or tracking failure. Its projective TSDF caps visible-space values at the truncation distance , leaves non-visible points beyond unmeasured and is exact at the surface, so fusion yields an approximate pseudo-Euclidean distance. Normals come from numerical derivatives near the zero level set, and ray marching finds surfaces by trilinear interpolationSource 3.
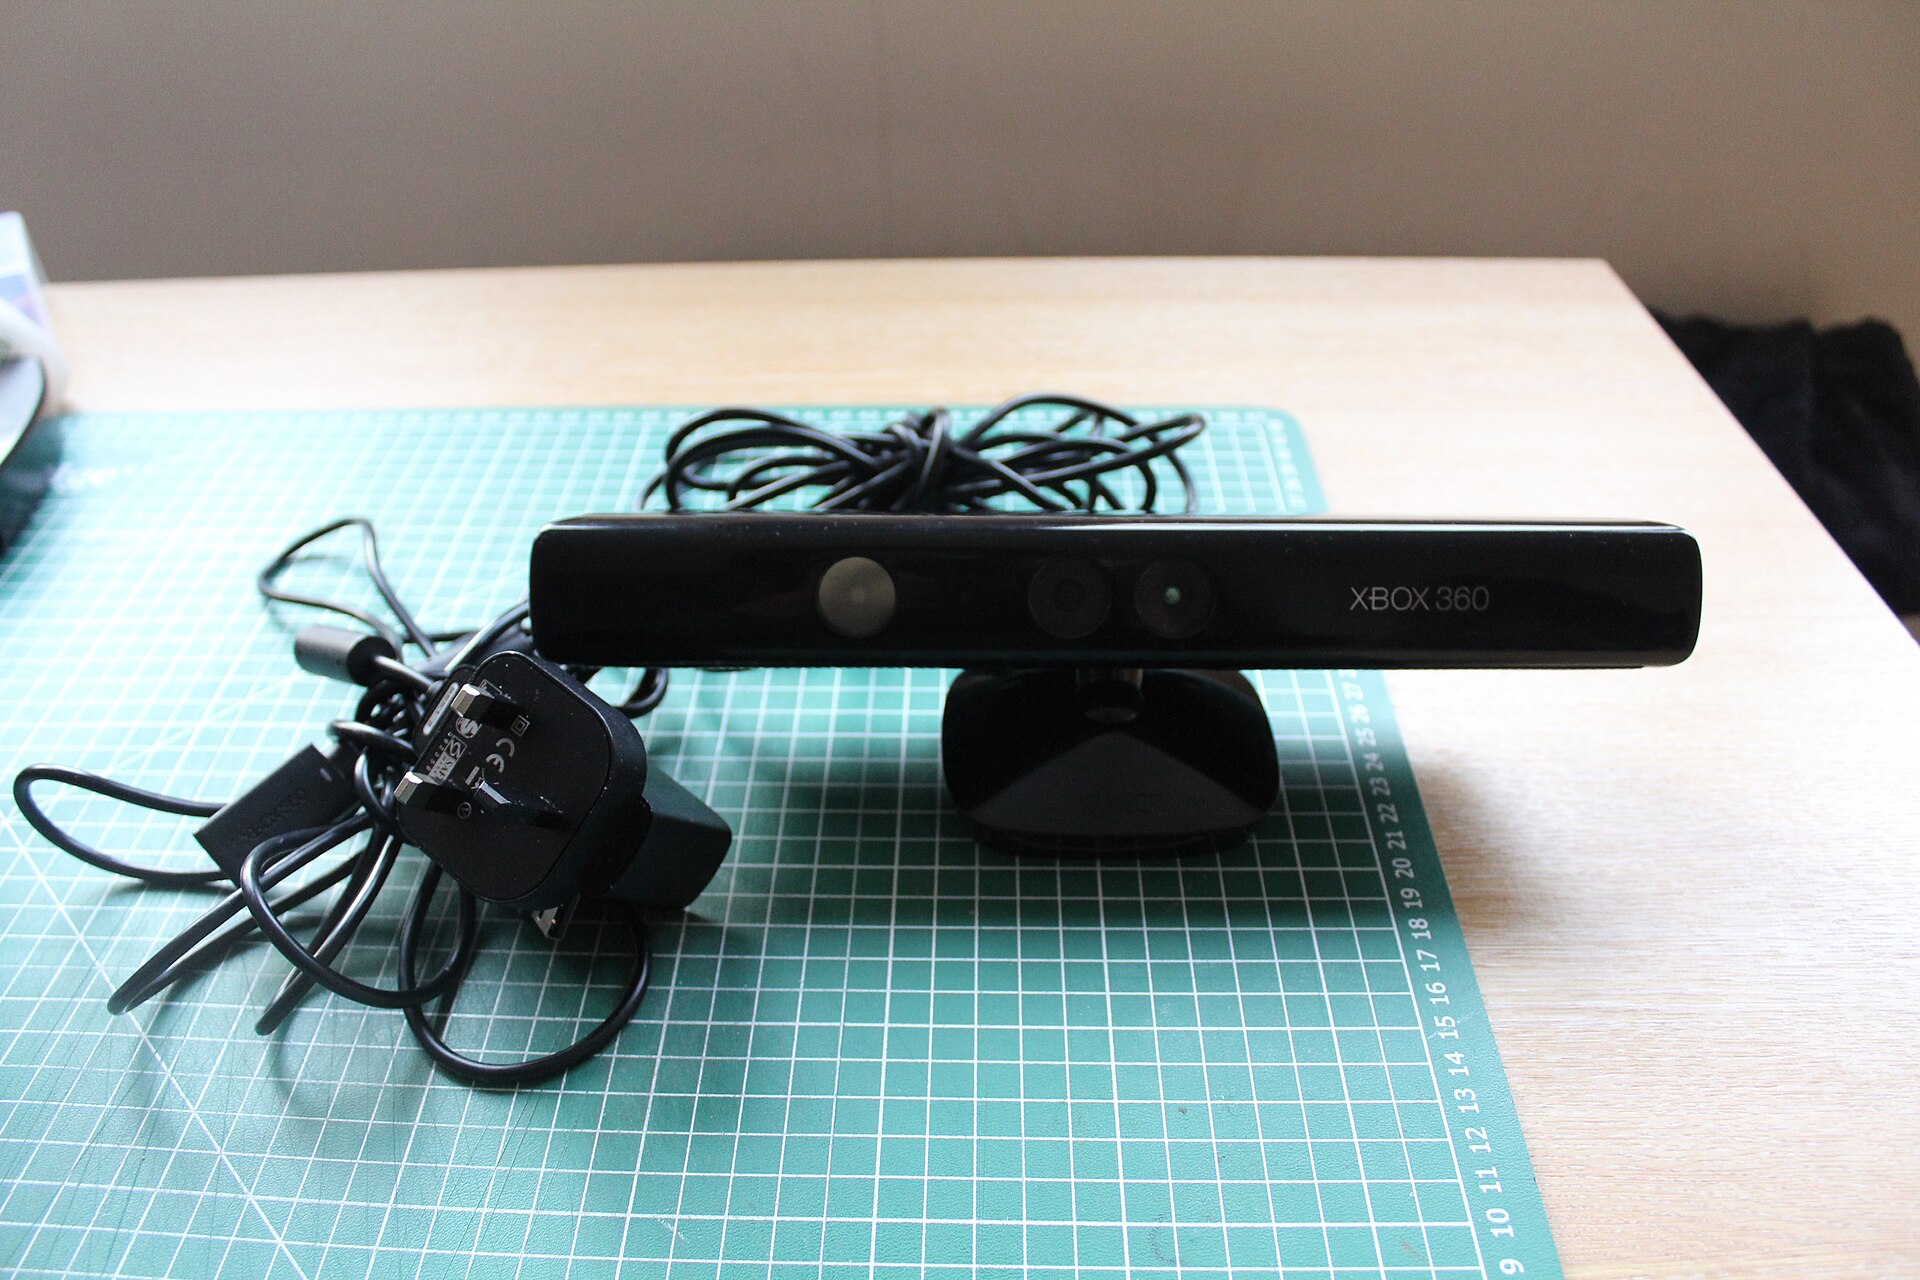
Trajectory optimizers need obstacle distances. Voxblox builds TSDFs faster than OctoMap builds its maps, then derives Euclidean signed distance fields (ESDFs) from them incrementally, more accurately than from occupancySource 25, and on GPUs nvblox reports up to 177x faster surface reconstruction and 31x faster distance-field computationSource 26.
Meshes, and then neural fields
A mesh adds connectivity, giving each face a normal and a renderable surface, but leaves holes where nothing was observed, and filling them invents geometrySource 2.
NeRF fits a neural radiance field to a static scene from posed RGB photographs, intrinsics and scene bounds. Its MLP predicts density from position and colour from position and viewing direction, and differentiable volume rendering lets image error drive optimizationSource 4.
Instant NGP cut optimization cost with a multiresolution hash encoding, smaller networks and fully fused CUDA kernels, and rendered one scene at 1080p in 5 seconds over 128 samples and a large 360-degree scene at 10 frames per second on one RTX 3090Source 5. 3D Gaussian splatting optimizes Gaussian positions, anisotropic covariances, opacities and spherical-harmonic appearance from calibrated photographs, then rasterizes by alpha-blending sorted splats. It reports real-time 1080p rendering, with results on an A6000 GPUSource 6.
DUSt3R predicts dense pointmaps from a pair of RGB images without intrinsics or poses, in the first image's frame and at unknown scale, trained with geometric supervision from pretrained CroCo weights. For an image collection, it then optimizes the alignment of pairwise pointmaps in 3DSource 7.
Feed-forward models now cover whole collections: VGGT infers cameras, point maps, depth maps and point tracks from one, a few or hundreds of views in under one secondSource 27.
A radiance field is geometry for rendering
The world-models taxonomy treats a splat reconstruction as a learned renderer: appearance is learned and physics is not. In the original 3DGS, learned opacity is an image-space alpha-compositing weight with no free, occupied or unknown label, and the stored primitive is a volumetric GaussianSource 6. The paper names mesh reconstruction as an open directionSource 6, and SuGaR then aligned Gaussians with surfaces and extracted meshes by Poisson reconstructionSource 28.
Simulators pair splats for appearance with separate physics: SplatSim renders with splats while PyBullet supplies physicsSource 16. Its authors report zero-shot real-world transfer of diffusion policies on four rigid-body tasks with a UR5 and Robotiq 2F-85 gripper, after manual robot segmentation and ICP alignmentSource 16. In RoboGSim's closed-loop evaluator, a policy acts on splat-rendered images while Isaac Sim handles inverse kinematics and physical interaction, from multi-view images, supplied MDH parameters and mesh assetsSource 17.
Other fields serve a planner directly. Dex-NeRF renders transparency-aware depth from learned density for a grasp planner, where a RealSense camera failed to compute depth for most transparent objects testedSource 15.
ParticleSplat, from Deepak Pathak (Carnegie Mellon) and colleagues (September 2026), encodes posed multi-view images into latent particles that decode to 3D Gaussians, trained with a novel-view synthesis objective. Object masks emerge without labels, moving a particle moves its object, and the representation improved downstream manipulationSource 35.
SLAM: the system that builds the map
Simultaneous localization and mapping (SLAM) builds such maps from sensor data while the robot moves without knowing its exact pose. Cadena and colleagues separate a sensor-dependent front end, which abstracts measurements and associates them with state variables, from a back end that performs inference and feeds information back for loop-closure detection and validationSource 8. State estimation covers the inference machinery.
Front ends are feature-based or direct. Monocular ORB-SLAM (2015) uses ORB features for tracking, local mapping, relocalization and loop closing, triangulating matched features and running local bundle adjustment. Its DBoW2 vocabulary proposes relocalization and loop candidates that need geometric validationSource 9.
ORB-SLAM3 supports stereo, RGB-D and visual-inertial modes with pinhole or fisheye cameras and MAP-based IMU initialization. It starts a new map after persistent tracking loss and merges maps only after geometric and covisibility checks, plus gravity-direction checks for mature visual-inertial maps. Low texture remains the main failure case, and slow motion can delay inertial initializationSource 10.
Direct Sparse Odometry skips the detector and optimizes photometric error over sampled pixels jointly with geometrySource 11. It can sample any region with intensity gradient, including near-featureless walls, and gains from calibrating exposure, vignetting and camera responseSource 11.
Learned systems keep classical machinery: DROID-SLAM iterates camera pose and per-pixel depth through a dense bundle-adjustment layerSource 29.
Revisiting mapped landmarks can reduce odometric drift and in some cases correct it, and visual-inertial methods drift less than wheel odometrySource 8. Monocular ORB-SLAM validates a loop closure geometrically, then spreads its error with similarity alignment and Essential Graph optimizationSource 9.
Loop closure
Recognising the start pulls the drifted map back into shape
1.5 degrees
Close the loop: every spring gives a little and the chain settles onto the planDrift 1.5 degrees a leg · the bar misses the start by 2.6 m
Illustrative course and drift; each joint's share is that chain's exact least-squares solution
How this was made
A robot that maps as it drives places each pose from the one before, so every small error in a measured turn bends the rest of the map and the drift grows with distance. Coming back to a place it has mapped and recognising it gives one more measurement: where that old place is from here. Once it is checked, it ties the end of the map to its start, and the back end spreads the loop's error along the whole chain instead of dumping it on the last pose, as monocular ORB-SLAM does with similarity alignment and Essential Graph optimization. This works because smoothing keeps the past poses in the graph, free to move. A revisit can reduce drift and in some cases correct it; it does not promise to remove all of it.
The drawing is a chain-map table. A printed floor plan shows a corridor round a block of rooms, with a ring at every place the robot truly stopped. On it lies a jointed chain, the robot's map of its lap: a steel link for every 2 m leg it drove, a pin on a glide puck for every pose it remembered, and a torsion spring at every pin, its legs on posts on the two links, holding the turn it measured. The first link is clamped to the start post. The last carries a small rover whose camera looks ahead at a ranging pole beside the start, and the lit bar on its front is that view, one leg straight ahead, ending in a square socket that fits the post's square spigot one way only. Closing the loop seats it, and every spring gives by its share.
Illustrative: a loop of 16 legs of 2 m round a block, and every measured turn short by between 0.2 and 1.8 times the drift set, more on the early legs, averaging it. Each joint's share is the smallest set of corrections, weighted alike, that puts the socket on the post facing the right way, solved by repeated linearisation as a pose-graph back end does. The springs are all alike, so they cannot tell which turns were worse, and a little error stays.
Cadena and colleagues (2016); Mur-Artal, Montiel and Tardós, ORB-SLAM (2015); Dellaert and Kaess (2006).
Place recognition asks whether the current image matches a stored place, and motion information can also inform that belief. Viewpoint, illumination and seasonal changes alter one place's appearance, and different places can look alike, which is perceptual aliasingSource 12.
Perceptual aliasing can create false-positive associations that corrupt back-end estimates, while false negatives discard useful measurements. Robust losses and loop-closure validation mitigate outliers, though failures remain that depend on initializationSource 8.
In the back end, Square Root SAM estimates the trajectory and landmark map jointly by MAP inference, which under Gaussian models with known data associations is sparse nonlinear least squares. It solves successive linearized systems by QR or Cholesky, and variable ordering controls fill-inSource 18. iSAM2 adds incremental reordering and relinearization on a Bayes tree. Thresholded updates trade some accuracy for speed, and a large loop closure can cost as much as a batch solveSource 19.
Smoothing suits loop closure because relinearizing the past requires the past to stay in the graph. Cadena and colleagues contrast sparse landmark maps with dense models suited to obstacle avoidance, and cite octrees and voxel hashing as efficient volumetric storage. Two rooms can look identical to a 2D laser yet differ to a camera. Severe illumination changes defeat bag-of-words methods, and active range cameras work in dark, untextured scenes but face range and external-light limitsSource 8.
The iMAP system learns a scene-specific MLP from scratch at room scale from a handheld RGB-D stream. It tracks at 10 Hz and maps at 2 Hz on a desktop CPU and GPU, retaining keyframes for replaySource 13. NICE-SLAM uses hierarchical feature grids with pretrained geometry decoders, reconstructs a multi-room apartment and performs no loop closureSource 14. Its 47 ms tracking and 130 ms mapping times use small pixel samples on an RTX 3090Source 14.
SplaTAM maps with 3D Gaussians from an RGB-D camera and uses a silhouette mask to determine whether areas were previously mappedSource 30.
The deployed answer: costmaps and two planners
A navigation stack plans over a costmap: occupancy from the map and live sensors, inflated by the robot's footprint. Lu, Hershberger and Smart's layered costmaps keep an ordered list of semantically separate layers and accumulate them into a master 2D costmap. Each update gathers the layers' bounds, then lets each layer write the master grid within them, and a configuration setting decides whether sensed obstacles overwrite static-map costsSource 20.
Navigation2, built on ROS 2, uses a layered costmap. Its global planner computes a shortest route to the goal, and a separate controller computes a local path and control signals, each a plugin in an asynchronous serverSource 21.
The layered costmap's track_unknown_space option defaults to false, which treats unknown space as free; keeping the unknown state requires enabling itSource 31. The planning algorithms are those of motion planning on a 2D grid.
A representation is a service contract
Perception locates objects in the current frameSource 33. Consumers issue different queries: localization needs stable landmarksSource 8, collision checking needs occupied volume and a conservative update ruleSource 24, grasping needs surface pose and identity, and rendering needs appearanceSource 8.
Hydra stacks rungs in one real-time system, building a local ESDF, extracting a topological map of places from it and segmenting places into roomsSource 32.
SceneLM, from Jitendra Malik (UC Berkeley), Marco Pavone and colleagues (September 2026), keeps the whole map as a structured text list of objects that one vision-language model edits after each image. On language-grounded retrieval and localization benchmarks it performed competitively with complete mapping pipelines, with a map 6 to 12 times more compact, and it ran online on an edge device aboard a quadrupedSource 36.
Ledger, from Shravan Chaudhari, Homanga Bharadhwaj and colleagues at Johns Hopkins (October 2026), keeps a persistent 3D object memory from a person's egocentric video: each object's resting locations, its moves and a short description, retained after it leaves view. A language model answering from these records as text, without the images, raised GPT-5.4's HD-EPIC accuracy from 29.7% to 42.6%, and on Ego4D the memory located objects with a median error of 0.99 m where it returned a predictionSource 37.
A deployed map publishes its frame, timestamp, resolution, unknown-state convention, update rate and invalidation rule. In MoveIt 2, the planning scene holds the robot's current state, its model and the world representation for collision checkingSource 34, and attached or removed objects must reach it before motion; the ROS 2 guide covers transforms and the planning scene. A scene representation answers what is present now, while a world model must answer how state changes under an action, as the simulator comparison sets out.
See also
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Sim-to-Real Transfer
Domain randomization, distillation, system identification and real-to-sim reconstruction.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
Linked from
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- State Estimation
Kalman filters, factor graphs, and pose estimation from noisy sensors.
- ROS 2 for Machine Learning Engineers
ROS 2 as the production boundary around a learned policy.
References
Hans P. Moravec, Alberto Elfes, ICRA 1985.
https://doi.org/10.1109/ROBOT.1985.1087316
Brian Curless, Marc Levoy, SIGGRAPH 1996.
https://doi.org/10.1145/237170.237269
Richard A. Newcombe, Shahram Izadi, Otmar Hilliges, David Molyneaux, David Kim, Andrew J. Davison, and 4 more, ISMAR 2011.
https://doi.org/10.1109/ISMAR.2011.6092378
Ben Mildenhall, Pratul P. Srinivasan, Matthew Tancik, Jonathan T. Barron, Ravi Ramamoorthi, Ren Ng, ECCV 2020.
https://arxiv.org/abs/2003.08934
Thomas Müller, Alex Evans, Christoph Schied, Alexander Keller, ACM Trans. Graph. (SIGGRAPH 2022).
https://arxiv.org/abs/2201.05989
Bernhard Kerbl, Georgios Kopanas, Thomas Leimkühler, George Drettakis, ACM Trans. Graph. 42(4), author manuscript (2023).
https://arxiv.org/abs/2308.04079
Shuzhe Wang, Vincent Leroy, Yohann Cabon, Boris Chidlovskii, Jerome Revaud, CVPR 2024.
https://arxiv.org/abs/2312.14132
Cesar Cadena, Luca Carlone, Henry Carrillo, Yasir Latif, Davide Scaramuzza, José Neira, and 2 more, IEEE Transactions on Robotics, 2016.
https://arxiv.org/abs/1606.05830
Raúl Mur-Artal, J. M. M. Montiel, Juan D. Tardós, IEEE Transactions on Robotics, 2015.
https://doi.org/10.1109/TRO.2015.2463671
Carlos Campos, Richard Elvira, Juan J. Gómez Rodríguez, José M. M. Montiel, Juan D. Tardós, IEEE Transactions on Robotics, 2021.
https://doi.org/10.1109/TRO.2021.3075644
Jakob Engel, Vladlen Koltun, Daniel Cremers, IEEE TPAMI, 2018.
https://doi.org/10.1109/TPAMI.2017.2658577
Stephanie Lowry, Niko Sünderhauf, Paul Newman, John J. Leonard, David Cox, Peter Corke, and 1 more, IEEE Trans. Robotics, 2016.
https://doi.org/10.1109/TRO.2015.2496823
Edgar Sucar, Shikun Liu, Joseph Ortiz, Andrew J. Davison, ICCV 2021.
https://arxiv.org/abs/2103.12352
Zihan Zhu, Songyou Peng, Viktor Larsson, Weiwei Xu, Hujun Bao, Zhaopeng Cui, and 2 more, CVPR 2022.
https://arxiv.org/abs/2112.12130
Jeffrey Ichnowski, Yahav Avigal, Justin Kerr, Ken Goldberg, CoRL 2021.
https://arxiv.org/abs/2110.14217
Mohammad Nomaan Qureshi, Sparsh Garg, Francisco Yandun, David Held, George Kantor, Abhisesh Silwal, 2024.
https://arxiv.org/abs/2409.10161
Xinhai Li, Jialin Li, Ziheng Zhang, Rui Zhang, Fan Jia, Tiancai Wang, and 3 more, 2024.
https://arxiv.org/abs/2411.11839
Frank Dellaert, Michael Kaess, Int. J. Robotics Research, 2006.
https://doi.org/10.1177/0278364906072768
Michael Kaess, Hordur Johannsson, Richard Roberts, Viorela Ila, John J. Leonard, Frank Dellaert, Int. J. Robotics Research, 2012.
https://doi.org/10.1177/0278364911430419
David V. Lu, Dave Hershberger, William D. Smart, IROS 2014.
https://doi.org/10.1109/IROS.2014.6942636
Charles R. Qi, Hao Su, Kaichun Mo, Leonidas J. Guibas, CVPR 2017.
https://arxiv.org/abs/1612.00593
Muhammad Zubair Irshad, Mauro Comi, Yen-Chen Lin, Nick Heppert, Abhinav Valada, Rares Ambrus, and 2 more, 2024.
https://arxiv.org/abs/2410.20220
Armin Hornung, Kai M. Wurm, Maren Bennewitz, Cyrill Stachniss, Wolfram Burgard, Autonomous Robots, 2013.
https://doi.org/10.1007/s10514-012-9321-0
Helen Oleynikova, Zachary Taylor, Marius Fehr, Juan Nieto, Roland Siegwart, arXiv preprint (IROS 2017), 2016.
https://arxiv.org/abs/1611.03631
Alexander Millane, Helen Oleynikova, Emilie Wirbel, Remo Steiner, Vikram Ramasamy, David Tingdahl, and 1 more, arXiv preprint (ICRA 2024), 2023.
https://arxiv.org/abs/2311.00626
Jianyuan Wang, Minghao Chen, Nikita Karaev, Andrea Vedaldi, Christian Rupprecht, David Novotny, arXiv preprint (CVPR 2025).
https://arxiv.org/abs/2503.11651
Antoine Guédon, Vincent Lepetit, 2023.
https://arxiv.org/abs/2311.12775
Zachary Teed, Jia Deng, 2021.
https://arxiv.org/abs/2108.10869
Nikhil Keetha, Jay Karhade, Krishna Murthy Jatavallabhula, Gengshan Yang, Sebastian Scherer, Deva Ramanan, and 1 more, arXiv preprint (CVPR 2024), 2023.
https://arxiv.org/abs/2312.02126
Nathan Hughes, Yun Chang, Luca Carlone, Robotics: Science and Systems (RSS) 2022.
https://arxiv.org/abs/2201.13360
Qiao Gu, Alihusein Kuwajerwala, Sacha Morin, Krishna Murthy Jatavallabhula, Bipasha Sen, Aditya Agarwal, and 10 more, 2023.
https://arxiv.org/abs/2309.16650
MoveIt Maintainers, MoveIt 2 Documentation, as of 2026-08-24.
https://moveit.picknik.ai/main/api/html/planning_scene_overview.html
Lyuxing He, Daniel Guo, Elizabeth Terveen, Deepak Pathak, David Held, Tal Daniel, 2026.
https://arxiv.org/abs/2609.19463
Adam Lilja, Fabio Hübel, Siming He, Junsheng Fu, Claire Tomlin, Lars Hammarstrand, and 3 more, 2026.
https://arxiv.org/abs/2609.21400
Shravan Chaudhari, William Paul, Suchi Saria, Rama Chellappa, Homanga Bharadhwaj, 2026.
https://arxiv.org/abs/2610.10538
Further reading
Vincent Leroy, Yohann Cabon, Jérôme Revaud, ECCV 2024.
https://arxiv.org/abs/2406.09756
Wenzhao Zheng, Weiliang Chen, Yuanhui Huang, Borui Zhang, Yueqi Duan, Jiwen Lu, 2023.
https://arxiv.org/abs/2311.16038
Qianqian Wang, Yifei Zhang, Aleksander Holynski, Alexei A. Efros, Angjoo Kanazawa, 2025.
https://arxiv.org/abs/2501.12387
Matthias Nießner, Michael Zollhöfer, Shahram Izadi, Marc Stamminger, ACM Transactions on Graphics, 2013.
https://doi.org/10.1145/2508363.2508374
Kai Zhang, Gernot Riegler, Noah Snavely, Vladlen Koltun, 2020.
https://arxiv.org/abs/2010.07492
Nikhil Keetha, Norman Müller, Johannes Schönberger, Lorenzo Porzi, Yuchen Zhang, Tobias Fischer, and 11 more, arXiv preprint (3DV 2026), 2025.
https://arxiv.org/abs/2509.13414
Yifan Wang, Jianjun Zhou, Haoyi Zhu, Wenzheng Chang, Yang Zhou, Zizun Li, and 4 more, 2025.
https://arxiv.org/abs/2507.13347
Haotong Lin, Sili Chen, Junhao Liew, Donny Y. Chen, Zhenyu Li, Guang Shi, and 2 more, 2025.
https://arxiv.org/abs/2511.10647
Binbin Huang, Zehao Yu, Anpei Chen, Andreas Geiger, Shenghua Gao, 2024.
https://arxiv.org/abs/2403.17888
Hanxiao Jiang, Hao-Yu Hsu, Kaifeng Zhang, Hsin-Ni Yu, Shenlong Wang, Yunzhu Li, 2025.
https://arxiv.org/abs/2503.17973
William Shen, Ge Yang, Alan Yu, Jansen Wong, Leslie Pack Kaelbling, Phillip Isola, arXiv preprint (CoRL 2023).
https://arxiv.org/abs/2308.07931
D. Galvez-López, J. D. Tardos, IEEE Transactions on Robotics, 2012.
https://doi.org/10.1109/TRO.2012.2197158
Nikhil Keetha, Avneesh Mishra, Jay Karhade, Krishna Murthy Jatavallabhula, Sebastian Scherer, Madhava Krishna, and 1 more, arXiv preprint (IEEE RA-L 2023).
https://arxiv.org/abs/2308.00688
Heng Yang, Pasquale Antonante, Vasileios Tzoumas, Luca Carlone, IEEE Robotics and Automation Letters, 2019.
https://arxiv.org/abs/1909.08605
Hidenobu Matsuki, Riku Murai, Paul H. J. Kelly, Andrew J. Davison, arXiv preprint (CVPR 2024), 2023.
https://arxiv.org/abs/2312.06741
Riku Murai, Eric Dexheimer, Andrew J. Davison, arXiv preprint (CVPR 2025), 2024.
https://arxiv.org/abs/2412.12392
Yuzheng Liu, Siyan Dong, Shuzhe Wang, Yingda Yin, Yanchao Yang, Qingnan Fan, and 1 more, arXiv preprint (CVPR 2025), 2024.
https://arxiv.org/abs/2412.09401
Dominic Maggio, Hyungtae Lim, Luca Carlone, 2025.
https://arxiv.org/abs/2505.12549
Wolfgang Hess, Damon Kohler, Holger Rapp, Daniel Andor, 2016 IEEE International Conference on Robotics and Automation (ICRA).
https://doi.org/10.1109/ICRA.2016.7487258
Steve Macenski, Matthew Booker, Joshua Wallace, Tobias Fischer, 2024.
https://arxiv.org/abs/2401.13078
Krishna Murthy Jatavallabhula, Alihusein Kuwajerwala, Qiao Gu, Mohd Omama, Tao Chen, Alaa Maalouf, and 11 more, Robotics: Science and Systems (RSS) 2023.
https://arxiv.org/abs/2302.07241
Balakumar Sundaralingam, Adithyavairavan Murali, Stan Birchfield, arXiv preprint, 2026.
https://arxiv.org/abs/2603.05493
Hengyi Wang, Lourdes Agapito, 2026.
https://arxiv.org/abs/2609.19518
Spot a factual error or missing qualification? Report a content correction.