Sim-to-Real Transfer
Domain randomization, distillation, system identification and real-to-sim reconstruction.
Sim-to-real transfer is getting a policy trained in simulation to work on the physical robot, through four families of methods: domain randomization, teacher-student distillation, system identification and real-to-sim reconstruction. Aljalbout and colleagues' survey covers all four, splitting methods that reduce the gap from those that overcome itSource 11.
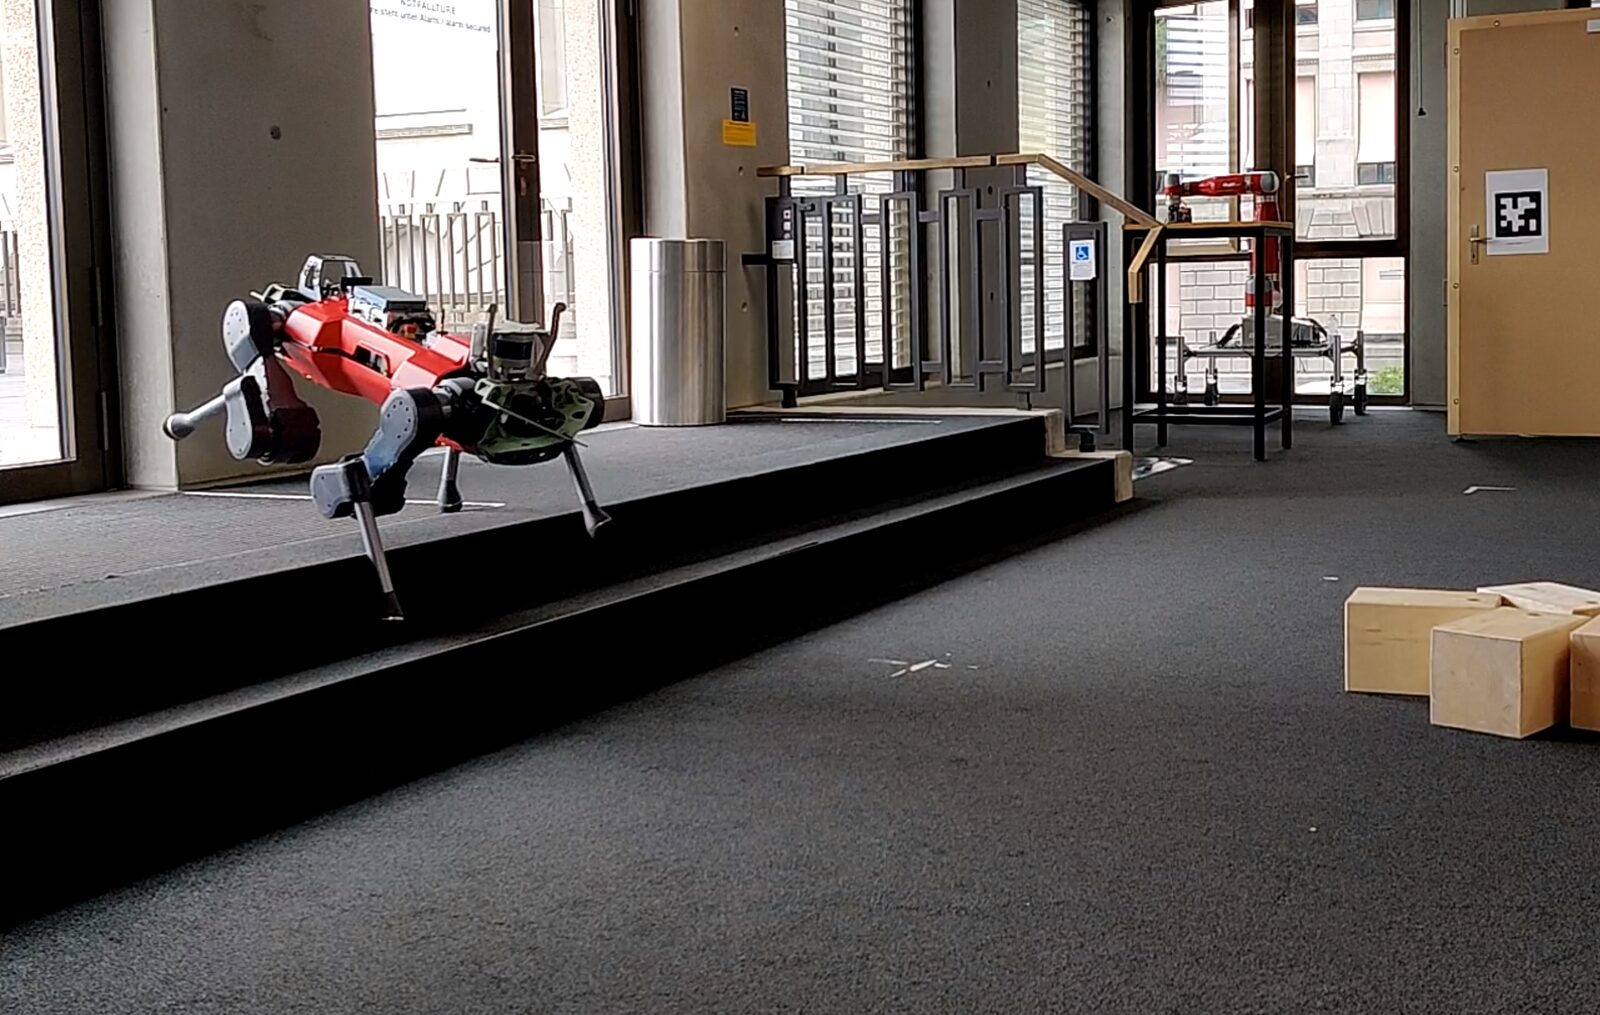
Domain randomization
One-floor robot wins on its floor; many-floor robot copes widely
Adjust more
one-floor robotmany-floor robot, practised on the shaded floors
Illustrative, not measured
How this was made
The task in this example is walking across the floor without falling, and the chart shows the share of tries that end without a fall. Friction is the ground friction coefficient, mu: low is slippery, high is grippy. The robot trained on one floor is a point policy trained at mu 0.80 only. The robot trained on many floors is a domain-randomized (DR) policy trained over uniform mu in [0.45, 1.15], a half-width of 0.35 either side of the practice floor; the shaded band is that assumed training range, not a confidence interval.
Real robot mu 0.80: point policy 97%, DR policy 74%, edge point +23 pts. The practice floors span friction 0.45 to 1.15, and the DR plateau is DR 74%; the point peak is 97%.
At friction 0.80 the point curve is higher. All curves are authored formulas, not trained policies or robot data, and not measured robot performance. All values and the falling DR peak are local assumptions: the plateau height is 0.93 minus 0.55 times the half-width, so it widens and falls together, 74% at half-width 0.35 and 57% at 0.65. These authored values do not come from Peng paper results, and domain randomization has no measured universal law of this shape.
Illustrative, not measured robot data. At selected friction 0.80, the point curve is 97% and the DR curve is 74%. The assumed DR half-width is 0.35 and its plateau is 74%. Its height follows 0.93 minus 0.55 times the half-width; the point Gaussian has center 0.80, peak 0.97 and width 0.09, and the DR tails have width 0.10. The shaded band marks an assumed range, not a confidence interval. The randomization band is marked ordinary at the selected half-width. Reset restores this panel to friction 0.80 and half-width 0.35. Selecting friction samples the formulas; no training or adaptation runs.
Sampled task success against ground friction
| mu | point policy | DR policy | playhead |
|---|---|---|---|
| 0.20 | 0% | 3% | off |
| 0.50 | 0% | 74% | off |
| 0.80 | 97% | 74% | playhead |
| 1.10 | 0% | 74% | off |
| 1.50 | 0% | 0% | off |
CPU API
DR parameter writes
Isaac Lab v1: mass and friction; runtime changes supported
< 1 s
RMA reported adaptation
A1: latent ~10 Hz; base policy 100 Hz
86.25%
SplatSim zero-shot (UR5)
vs 97.5% real-data; 4 tasks, 40 trials/task
delta action
ASAP correction
learned residual, sim to real to sim
Domain randomization: train on a distribution of simulators
Jakobi and colleagues found in 1995 that sim-to-real correspondence depended on how much noise the simulation usedSource 13. Tobin and colleagues randomized textures, lighting and camera pose for tabletop object localization; their best network localized objects to about 1.5 cm over 480 webcam images of eight geometric objects, though most runs used ImageNet initialization (random initialization nearly matched it given enough simulated data), and their abstract frames the real world as "just another variation" once the simulator varies enoughSource 1.
Peng and colleagues randomized link mass, joint damping, friction, controller gains, action timing and observation noise, maximizing expected return over that dynamics distribution. A recurrent policy trained only in simulation pushed a puck with a seven-DoF Fetch arm, with start and target positions randomized within a 30 cm squareSource 2.
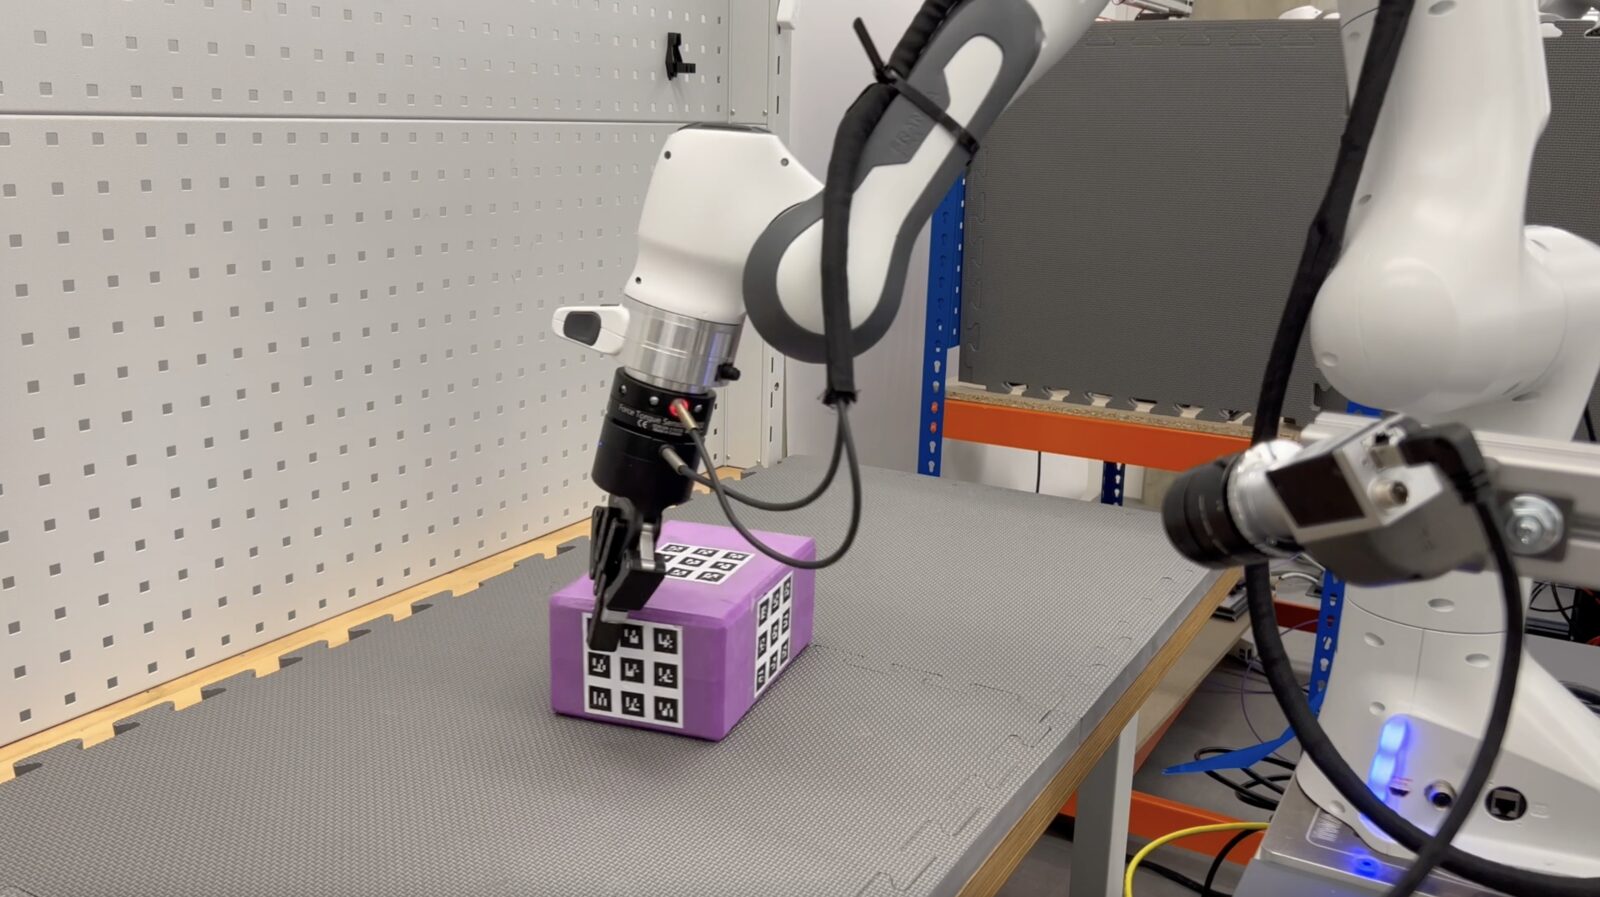
OpenAI's 2018 hand policy randomized friction coefficients and object appearance and transferred to the physical robotSource 14. Its Rubik's-cube successor added a curriculum version, automatic domain randomization, which widens ranges as the policy succeedsSource 3.
Isaac Lab, the GPU-parallel training framework, ships ADR as a configurable curriculum, but mass, friction, contact offsets and joint armature change through PhysX CPU APIs. Most parameters randomize at runtime, mesh scale and collider type only before simulation startsSource 4. SPI-Active notes that poorly tuned randomization "can lead to overly conservative policies"Source 15.
Teacher-student distillation: privilege in, proprioception out
Teacher-student training splits sensing from control: a teacher learns from privileged simulator state, then a student with deployable sensing imitates it. Learning by Cheating used this two-stage form for drivingSource 17, after asymmetric actor-critic had given only the critic full stateSource 18.
Lee and colleagues distilled a privileged RL teacher, which saw simulator-only terrain and contact information, into a temporal convolutional student via its actions and latent features. The student uses two seconds of proprioceptive history, plus the command and current state, and one controller per robot generation took ANYmal-B and ANYmal-C robots through mud, snow, rubble and vegetation without environment-specific tuningSource 5. Isaac Lab's DextrAH-RGB example distills a privileged KUKA and Allegro teacher into a stereo-RGB networkSource 4, and VIRAL's authors report that scaling to tens of GPUs, up to 64, made teacher and student training reliable for an RGB humanoid that ran up to 54 loco-manipulation cyclesSource 19.
RMA trains a base policy and an environment-factor encoder jointly with RL, then regresses an adaptation module on simulated state-action histories to predict the latent extrinsics. The module reads 50 state-action steps (0.5 seconds) and updates asynchronously at about 10 Hz on the A1, while the base policy runs at 100 Hz on the latest estimate, with no online gradient updates. The paper reports adaptation in fractions of a second without real-world fine-tuning, and failures after large perturbations or multiple leg obstructions; its latent encodes behavior-relevant conditions without guaranteeing each physical parameterSource 6. UP-OSI had earlier fed dynamics parameters predicted from recent history into a universal policySource 20.
Isaac Lab calls the failure mode an information gap due to input mismatch: the student must reconstruct unobserved states from partial observations such as images, hardest under heavy camera occlusionSource 4. The teacher-student panel illustrates this with authored terrain and noise, so its errors rise by construction.
Teacher-student training
A blind robot feels the ground through its legs
Sensor noise
Adjust more
real groundstudent’s guesswhat its legs feel
Illustrative, not measured
How this was made
Teacher-student training: a teacher policy learns in simulation with privileged information, here the terrain heightfield under the robot. A student policy then learns to act like the teacher from proprioception alone, the joint angles and motor efforts its legs report, and has to rebuild the ground from them. Proprioceptive degradation adds noise to those readings and drops channels; a dropped channel is a grey stub in the strip and a gap in the dashed guess.
Reconstruction error and action divergence rise by construction as degradation increases. The ground is chosen terrain, the leg readings are that terrain normalized plus seeded noise, and the guess is the terrain plus an authored error field; it is not inferred from the strip. Higher ground is drawn higher, with its height exaggerated. Darker cells are higher terrain: each of the 24 cells under the profile is shaded by its height, so the shade and the height agree.
Degradation 15%: reconstruction MAE 0.01 m, action divergence 0.02, occluded channels 3/24
At 15 percent proprioceptive degradation the student reconstruction of the teacher terrain sits at 0.01 m MAE with action divergence 0.02, and 3 of 24 input channels are already lost as gaps; the drawing puts the privileged ground profile, the proprioceptive strip and that dashed reconstruction on one side view.
Current teacher-student gap
- degradation
- 15%
- reconstruction MAE
- 0.01 m
- action divergence
- 0.02
- occluded channels
- 3/24
Chosen terrain, seeded noise and an authored error field; no recorded robot sensing or trained policies.
System identification: measure the gap instead
Randomization averages over model error, and system identification measures it. Hwangbo and colleagues fitted an actuator network for ANYmal's series-elastic actuators to real excitation data, predicting torque from joint-position errors and velocities now and 0.01 and 0.02 seconds earlier; policies trained with ideal or analytical actuator models failed to take a single step without fallingSource 7. Tan and colleagues paired an identified actuator model and simulated latency with randomizationSource 21. SPI-Active samples parameters in parallel with Fisher-information-driven excitation and beats baselines by 42 to 63% in locomotion tasksSource 15, and Miller and colleagues tune Spot simulation against hardware with CMA-ESSource 22.
ASAP pretrains phase-conditioned tracking policies in IsaacGym on retargeted human motions, runs them on a Unitree G1, and records trajectories with motion capture and onboard sensors. A second PPO policy learns a delta action added before the simulator step, the tracking policy is fine-tuned with the frozen delta model in simulation, and only the tracking policy is deployed. For the hardware study the delta covers only four ankle DoFs of the 23-DoF modelSource 8.
Evaluation separates IsaacGym-to-IsaacSim and IsaacGym-to-Genesis tests, with open-loop replay and closed-loop tracking over 43 motion sequences, and ASAP does not win every metric: in the easy IsaacSim closed-loop group its mean global joint-position error is 106 mm against SysID's 105 mm. On hardware, compared only with Vanilla, the error falls from 61.2 to 50.2 mm on kicking and from 159 to 112 mm on LeBron James's "Silencer"Source 8. ASAP reports better tracking on the held-out "Silencer" motion without establishing coverage of arbitrary unseen skills, and its stated hardware limits are motor overheating and damage, motion-capture dependence and the data needed for a full 23-DoF delta modelSource 8. Swift's champion-level drone racing likewise combined simulation RL with physical-world dataSource 23.
Real-to-sim: rebuild the scene, keep the physics
SplatSim replaces mesh rendering with Gaussian splats reconstructed from the deployment scene, while PyBullet supplies physics. Across four UR5 tasks with 40 trials each, diffusion policies trained on its simulated demonstrations reached 86.25% zero-shot real success, against 97.5% for real-data policies, with training augmentations includedSource 9.
The setup uses a Robotiq 2F-85 gripper and two RealSense D455 cameras, and splat preparation needs manual robot segmentation, CAD-derived link bounds and ICP alignment. The setup figure lists RGB plus end-effector pose as inputs, while the problem statement says the policy uses only RGB at test timeSource 9.
RoboGSim's August 2025 revision chains a Gaussian Reconstructor, Digital Twins Builder, Scene Composer and Interactive Engine, where mesh assets and measured layout connect it to Isaac Sim. Novel-pose rendering and trajectory replay are evaluated separately. Closed-loop policies act on splat renders while Isaac Sim handles kinematics and collisions. On UR5 ring-toss, ten trials with up to three grasps each, the real-data model placed 90% on the real robot but 30% in RoboGSim, so its scores cannot replace real-robot testsSource 10.
Newer twins go beyond static appearance: RialTo runs RL in digital twins built from small amounts of real data, raising imitation-policy robustness by over 67%Source 24, and PolaRiS turns short video scans into environments that track real generalist-policy performance better than existing benchmarksSource 25. SimFoundry's simulated evaluations correlated with real results at a mean Pearson coefficient of 0.911 across 7 tasks and 5 policy architecturesSource 31, and NVIDIA's Newton 1.0 post describes a tiled camera sensor that ray-traces both triangle meshes and Gaussian splatsSource 12.
A rebuilt twin can still mislead. Kadian and colleagues measured a sim-versus-real success correlation of 0.18 in a 3D-scanned lab because agents exploited collision dynamics, and tuning simulation parameters raised it to 0.844Source 26.
Kaiyuan Chen, Ken Goldberg and colleagues at UC Berkeley and NVIDIA (October 2026) built RoboSimStudio, which lets people and coding agents edit the solver, contact model and physical parameters of a Newton simulationSource 32. In a pilot, coding agents built a bimanual sponge-wiping simulation from a smartphone video in about an hour, and a policy improved there completed the wipe on the real robotSource 32. One real rollout then displaced a bar support that the simulation held fixed, and the authors judged sim and real agreement on this single task mainly by qualitative observationSource 32.
Real-to-sim evaluation
A scanned twin predicted the real robot only after tuning
The scanned lab's simulator
Correlations as reported
How this was made
Kadian and colleagues compared how agents scored in a simulated, 3D-scanned copy of a lab with how the same agents scored on the real robot. The correlation between the two was 0.18, because agents exploited the simulator's collision dynamics; tuning the simulation parameters raised it to 0.844.
The bar shows the correlation for the chosen simulator and the dashed line the other. A scanned scene copies how the lab looks; the figure's point is that its physics still has to be checked against the real robot.
In a 3D-scanned lab, success in simulation correlated with success on the real robot at 0.18, because agents exploited its collision dynamics, against 0.844 after the simulation parameters were tuned; a correlation of 1 would mean simulation predicts the real result exactly.
How well simulated success predicts real success
| simulator | correlation with real success | why |
|---|---|---|
| As scanned | 0.18 | because agents exploited its collision dynamics |
| Parameters tuned | 0.844 | after the simulation parameters were tuned |
Levers behind successful transfer
The survey says the action space "plays a crucial role in reducing the sim-to-real gap", citing joint-velocity control for manipulation, and that co-training with real-world data benefits robotic foundation models such as GR00T N1Source 11. Maddukuri and colleagues report that simulation data raises real-world performance by 38% on averageSource 27, and Lei and colleagues identify structured representation alignment as its primary effectSource 28.
Deployed systems lean on such levers: Haarnoja and colleagues' soccer humanoid transferred through high-frequency control, targeted dynamics randomization and training perturbationsSource 29. Actuator reality shaping makes physical actuators match the simulator's idealized dynamicsSource 30, and Boston Dynamics reports fewer fidelity issues because Atlas's model and hardware are extremely closeSource 16.
Where each family breaks
The two interactives construct their costs; measured costs come from the sources. ASAP's broader skill coverage and affordable real-robot data collection remain openSource 8.
Self-check
Read the reasoning
- Domain randomization over a very wide friction rangeA wide training distribution gives no observation of current terrain friction. Peng and colleagues use recurrent memory to infer dynamics from past states and actions; the friction chart here contains no such adaptation process.
- A separately trained adaptation moduleRMA trains the adaptation module in simulation to estimate latent extrinsics from 50 state-action steps. On its A1 setup, that module runs at about 10 Hz and the base policy at 100 Hz, asynchronously using the latest estimate. Sub-second adaptation describes the estimate, with no online gradient update or claim that the latent recovers exact ground-truth friction.
- Give the deployed policy the friction coefficient as an inputThe teacher sees this privileged input. The deployed robot has no friction sensor; handing its student policy a value nobody can measure at runtime would recreate the input mismatch the teacher-student pattern addresses.
RMA trains a latent predictor in simulation, then performs asynchronous latent inference during deployment. Its base policy uses the latest estimate; neither an exact friction estimate nor adaptation at every control step is promised.
See also
- Robot Calibration
The measurements that make sensor coordinates agree with motion.
- State Estimation
Kalman filters, factor graphs, and pose estimation from noisy sensors.
- Dexterity
Contact-rich manipulation, touch sensing, in-hand reorientation and deformables.
Linked from
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Why RL Won Locomotion but Not Manipulation
Walking is cheap to simulate; contact-rich manipulation is not.
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Humanoid Whole-Body Control
How humanoids track retargeted human motion.
- Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
- Robot Calibration
The measurements that make sensor coordinates agree with motion.
- The Bear Case
Why this could be another robotics winter.
- Drones and Aerial Robotics
Autonomous flight, from state estimation to champion-level racing.
References
Josh Tobin, Rachel Fong, Alex Ray, Jonas Schneider, Wojciech Zaremba, Pieter Abbeel, IROS 2017.
https://arxiv.org/abs/1703.06907
Xue Bin Peng, Marcin Andrychowicz, Wojciech Zaremba, Pieter Abbeel, ICRA 2018.
https://arxiv.org/abs/1710.06537
OpenAI, Ilge Akkaya, Marcin Andrychowicz, Maciek Chociej, Mateusz Litwin, Bob McGrew, and 13 more, 2019.
https://arxiv.org/abs/1910.07113
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
Joonho Lee, Jemin Hwangbo, Lorenz Wellhausen, Vladlen Koltun, Marco Hutter, Science Robotics 5(47), 2020.
https://arxiv.org/abs/2010.11251
Ashish Kumar, Zipeng Fu, Deepak Pathak, Jitendra Malik, RSS 2021.
https://arxiv.org/abs/2107.04034
Jemin Hwangbo, Joonho Lee, Alexey Dosovitskiy, Dario Bellicoso, Vassilios Tsounis, Vladlen Koltun, and 1 more, Science Robotics 4(26), 2019.
https://arxiv.org/abs/1901.08652
Tairan He, Jiawei Gao, Wenli Xiao, Yuanhang Zhang, Zi Wang, Jiashun Wang, and 12 more, RSS 2025.
https://arxiv.org/abs/2502.01143
Mohammad Nomaan Qureshi, Sparsh Garg, Francisco Yandun, David Held, George Kantor, Abhisesh Silwal, 2024.
https://arxiv.org/abs/2409.10161
Xinhai Li, Jialin Li, Ziheng Zhang, Rui Zhang, Fan Jia, Tiancai Wang, and 3 more, 2024.
https://arxiv.org/abs/2411.11839
Elie Aljalbout, Jiaxu Xing, Angel Romero, Iretiayo Akinola, Caelan Reed Garrett, Eric Heiden, and 6 more, Annual Review of Control, Robotics, and Autonomous Systems 2026 (accepted), 2025.
https://arxiv.org/abs/2510.20808
Philipp Reist, Miguel Zamora Mora, JC Chang, Rishabh Chadha, Mohammad Mohajerani, 2026.
https://developer.nvidia.com/blog/newton-adds-contact-rich-manipulation-and-locomotion-capabilities-for-industrial-robotics
Nick Jakobi, Phil Husbands, Inman Harvey, Advances in Artificial Life (ECAL 1995), Lecture Notes in Computer Science, pp. 704-720.
https://doi.org/10.1007/3-540-59496-5_337
OpenAI, Marcin Andrychowicz, Bowen Baker, Maciek Chociej, Rafal Jozefowicz, Bob McGrew, and 11 more, 2018.
https://arxiv.org/abs/1808.00177
Nikhil Sobanbabu, Guanqi He, Tairan He, Yuxiang Yang, Guanya Shi, 2025.
https://arxiv.org/abs/2505.14266
Alberto Rodriguez, Shane Rozen-Levy, Vinay Kamidi, Boston Dynamics blog, 2026.
https://bostondynamics.com/blog/training-a-humanoid-robot-for-hard-work/
Dian Chen, Brady Zhou, Vladlen Koltun, Philipp Krähenbühl, CoRL 2019.
https://arxiv.org/abs/1912.12294
Lerrel Pinto, Marcin Andrychowicz, Peter Welinder, Wojciech Zaremba, Pieter Abbeel, arXiv preprint, 2017.
https://arxiv.org/abs/1710.06542
Wenhao Yu, Jie Tan, C. Karen Liu, Greg Turk, RSS 2017.
https://arxiv.org/abs/1702.02453
Jie Tan, Tingnan Zhang, Erwin Coumans, Atil Iscen, Yunfei Bai, Danijar Hafner, and 2 more, arXiv preprint, 2018.
https://arxiv.org/abs/1804.10332
AJ Miller, Fangzhou Yu, Michael Brauckmann, Farbod Farshidian, arXiv preprint, 2025.
https://arxiv.org/abs/2504.17857
Elia Kaufmann, Leonard Bauersfeld, Antonio Loquercio, Matthias Müller, Vladlen Koltun, Davide Scaramuzza, Nature 620, 982-987, 2023.
https://www.nature.com/articles/s41586-023-06419-4
Marcel Torne, Anthony Simeonov, Zechu Li, April Chan, Tao Chen, Abhishek Gupta, and 1 more, 2024.
https://arxiv.org/abs/2403.03949
Arhan Jain, Mingtong Zhang, Kanav Arora, William Chen, Marcel Torne, Muhammad Zubair Irshad, and 8 more, 2025.
https://arxiv.org/abs/2512.16881
Abhishek Kadian, Joanne Truong, Aaron Gokaslan, Alexander Clegg, Erik Wijmans, Stefan Lee, and 3 more, IEEE Robotics and Automation Letters 2020, 2019.
https://arxiv.org/abs/1912.06321
Abhiram Maddukuri, Zhenyu Jiang, Lawrence Yunliang Chen, Soroush Nasiriany, Yuqi Xie, Yu Fang, and 9 more, 2025.
https://arxiv.org/abs/2503.24361
Yu Lei, Minghuan Liu, Abhiram Maddukuri, Zhenyu Jiang, Yuke Zhu, arXiv preprint, 2026.
https://arxiv.org/abs/2604.13645
Tuomas Haarnoja, Ben Moran, Guy Lever, Sandy H. Huang, Dhruva Tirumala, Jan Humplik, and 22 more, arXiv preprint (Science Robotics 2024), 2023.
https://arxiv.org/abs/2304.13653
Satoshi Yamamori, Koji Ishihara, Kenjiro Minamikawa, Ryosei Ohmori, Taiyo Yasaki, Norikazu Sugimoto, and 1 more, arXiv preprint, 2026.
https://arxiv.org/abs/2607.02205
Nadun Ranawaka, Josiah Wong, Wei-Lin Pai, Wei-Teng Chu, Tianyuan Dai, Masoud Moghani, and 12 more, 2026.
https://arxiv.org/abs/2606.28276
- RoboSimStudio: An Interactive Toolkit for Human and Agent Rapid Real2Sim of Robot Manipulation Tasks
Kaiyuan Chen, Shuangyu Xie, Uksang Yoo, Xinyue Zhu, Cael Magner, Alvin Zhu, and 6 more, 2026.
https://arxiv.org/abs/2610.18835
Further reading
Xiaoyu Chen, Jiachen Hu, Chi Jin, Lihong Li, Liwei Wang, arXiv preprint, 2021.
https://arxiv.org/abs/2110.03239
Ananye Agarwal, Ashish Kumar, Jitendra Malik, Deepak Pathak, CoRL 2022.
https://arxiv.org/abs/2211.07638
Xingyi Wang, Chenyun Zhang, Weiji Xie, Chao Yu, Wei Song, Chenjia Bai, and 1 more, 2026.
https://arxiv.org/abs/2603.15084
Kaifeng Zhang, Shuo Sha, Hanxiao Jiang, Matthew Loper, Hyunjong Song, Guangyan Cai, and 4 more, arXiv preprint, 2025.
https://arxiv.org/abs/2511.04665
Bingjie Tang, Michael A. Lin, Iretiayo Akinola, Ankur Handa, Gaurav S. Sukhatme, Fabio Ramos, and 2 more, RSS 2023.
https://arxiv.org/abs/2305.17110
Tao Sun, Beining Han, Patrick Yin, Rui Xu, Harry He, Abhishek Gupta, and 2 more, 2026.
https://arxiv.org/abs/2609.20477
Tim Engelbracht, René Zurbrügg, Mayank Mittal, Marco Hutter, Marc Pollefeys, Hermann Blum, and 1 more, 2026.
https://arxiv.org/abs/2609.21751
Jean Pierre Sleiman, He Li, Alphonsus Adu-Bredu, Robin Deits, Arun Kumar, Kevin Bergamin, and 22 more, 2026.
https://arxiv.org/abs/2602.00401
Tianyi Xie, Haotian Zhang, Jinhyung Park, Zi Wang, Bowen Wen, Jiefeng Li, and 14 more, 2026.
https://arxiv.org/abs/2606.05160
Huang Huang, Wensi Ai, Ziyu Chen, Youhui Wang, Zijian Du, Yang Liu, and 3 more, 2026.
https://arxiv.org/abs/2610.09254
Spot a factual error or missing qualification? Report a content correction.