The Evaluation Crisis
What a success rate hides, from trial count to scorer.
The evaluation crisis is the gap between the success rates robot learning papers report and what those rates can establish. A success rate folds trial count, task length, scene setup and scorer into one number, and papers often report it with little or no information on the number of runs, initial conditions or success criteriaSource 11.
10 or 50
trial-count examples
small feasible samples, Snyder et al.; not a census
1,800
real rollouts
TRI LBM evaluation, blind A/B
612
pairwise comparisons
RoboArena v2, seven universities; distinct from 4,284 oracle rollouts
<30%
benchmark collapse
LIBERO-Plus, from 95% under modest shifts
What the success rate hides: the horizon
In an illustrative model, every decision succeeds with the same probability conditional on all earlier decisions succeeding, so a task of decisions completes with probability Source 1. At , 30 decisions give 21.5% and 100 give 0.6%. Drag "How many steps the job has" to compare these examples.
Guess first
At 95.0% per step over 14 steps, 48.8% of jobs go right. Drag "How many steps the job has" and watch it fall.
Compounding error
At 95% per step, half of 14-step jobs fail
How often each step goes right
Adjust more
White trapdoors: the steps · blue marbles: jobs that finish95.0% per step · 14 steps · 48.8% of jobs finish
Illustrative: a simple model, not a measured robot.
How this was made
This is an illustrative probability model, computed rather than measured on a robot. A job (an episode) is a chain of steps (decisions), and it finishes only if every step goes right. If each step succeeds with the same probability p, independently of the others, a job of n steps finishes with probability p^n. At the current setting that is (0.950)^14 = 48.8%. Real failures are rarely independent, so treat the curve as a teaching model, not a forecast.
The drawing is a marble run of 100 trapdoor gates, ten to a rail; the first 14 are armed as the job’s steps and the rest are pinned shut. A hundred marbles, one job each, roll from the hopper. Each armed gate passes the share p of the marbles that reach it, rounded to whole marbles, so after k gates round(100 p^k) are still rolling, and the finish tray holds the readout’s share as whole jobs out of 100 (now 49). Which marble drops at which gate is a fixed shuffle of the release order; the counts do not depend on it. A run plays in about ten seconds, not to scale. Working backwards, a job that must finish with probability q over n steps needs each step to succeed with probability q^(1/n).
The evaluation calculator at 95.0 percent per-step success reports 48.8% episode success after 14 decisions and 0.6% at the 100-step end of the range, crossing half only around step 14. In the drawing, 49 of 100 marbles reach the finish tray.
Sampled episode success by episode length
| episode length | episode success |
|---|---|
| 0 steps | 100.0% |
| 10 steps | 59.9% |
| 25 steps | 27.7% |
| 50 steps | 7.7% |
| 75 steps | 2.1% |
| 100 steps | 0.6% |
Read the reasoning
- About 200 decisions, because errors average out over an episodeThis encodes the belief that independent mistakes cancel like noise around a mean. A successful episode needs every decision right, so errors compound toward zero, and a longer episode can only be worse.
- About 50 decisions, since 95% leaves little room for errorThis reads the per-step number as if it carried over linearly to the task. The loss is multiplicative: by 50 decisions the product is 7.7%, far past a coin flip and heading for the floor.
- About 14 decisions, because the loss compounds at every stepThe product crosses one half between the 13th and 14th decision: 0.95 to the 14th is 48.8%, and the module's own horizon arithmetic already lands 30 steps at 21.5%. Episode success halves roughly every 14 decisions; the coin flip arrives early.horizon arithmetic
At 95% per step, the task is a coin flip after 14 decisions and down to 21.5% after 30: the per-step number cannot be read off the task-level number.
Solving gives , so an episode target of needs 95.6% per step at and 99.3% at . Behavior cloning compounds errors the same way: a policy with error rate on the expert's states can make as many as mistakes over steps of its ownSource 12.
Benchmarks now measure long horizons directly. CALVIN scores 1,000 chains of five sequential tasksSource 13, and the 2026 BEHAVIOR Challenge ranks 100 full-length household tasks by average success with partial credit, with 20,000 teleoperated demonstrations totaling 1,950 hoursSource 14.
Small samples limit comparison
Toyota Research Institute's Large Behavior Models extend the Diffusion Policy recipe to multitask models trained on about 1,700 demonstration hours. The mixture holds 468 hours of real bimanual teleoperation, 45 simulation hours, 32 UMI hours and about 1,150 hours from a subset of Open X-EmbodimentSource 3 Source 2. TRI reports 1,800 real-world rollouts and over 47,000 simulation rollouts, with 50 real attempts per task per policy per condition, a target of 200 in simulation and missing simulation data for some combinations. Hardware comparisons were blind, with policy order randomized within bundles sharing an initial conditionSource 2.
Simulation used automated predicates for scoring. TRI draws Bayesian posteriors over each policy's success probability under a uniform prior as violin plots, which avoid reading significance from overlapping confidence intervals; the posteriors describe single checkpoints and exclude variation from stochastic training. TRI also warns of a significant risk that many robotics papers measure statistical noise for lack of powerSource 2. Snyder et al. give 10 or 50 trials as examples of small feasible samples, and a test that finds no significant difference does not show two policies are equivalentSource 4.
Deep reinforcement learning met the same problem: without significance tests and standard reporting, claimed improvements are hard to judgeSource 15, so interval estimates and performance profiles are advocated over point estimatesSource 16.
STEP, a sequential test from Snyder et al., stops comparing two policies once enough evidence accumulates. It reports up to 32% fewer trials than the Lai and SAVI sequential baselines, assumes i.i.d. binary outcomes and uses a uniform risk-accumulation schedule in its experimentsSource 4. TRI uses the Lai test for binary comparisons, while STEP is a separate method, and Welch's t-test for task progressSource 2. A 2026 follow-up from Snyder and colleagues extends anytime-valid testing to partial credit and continuous metrics and reports up to 70% less evaluation effort than batch methodsSource 17.
Clean benchmarks overstate
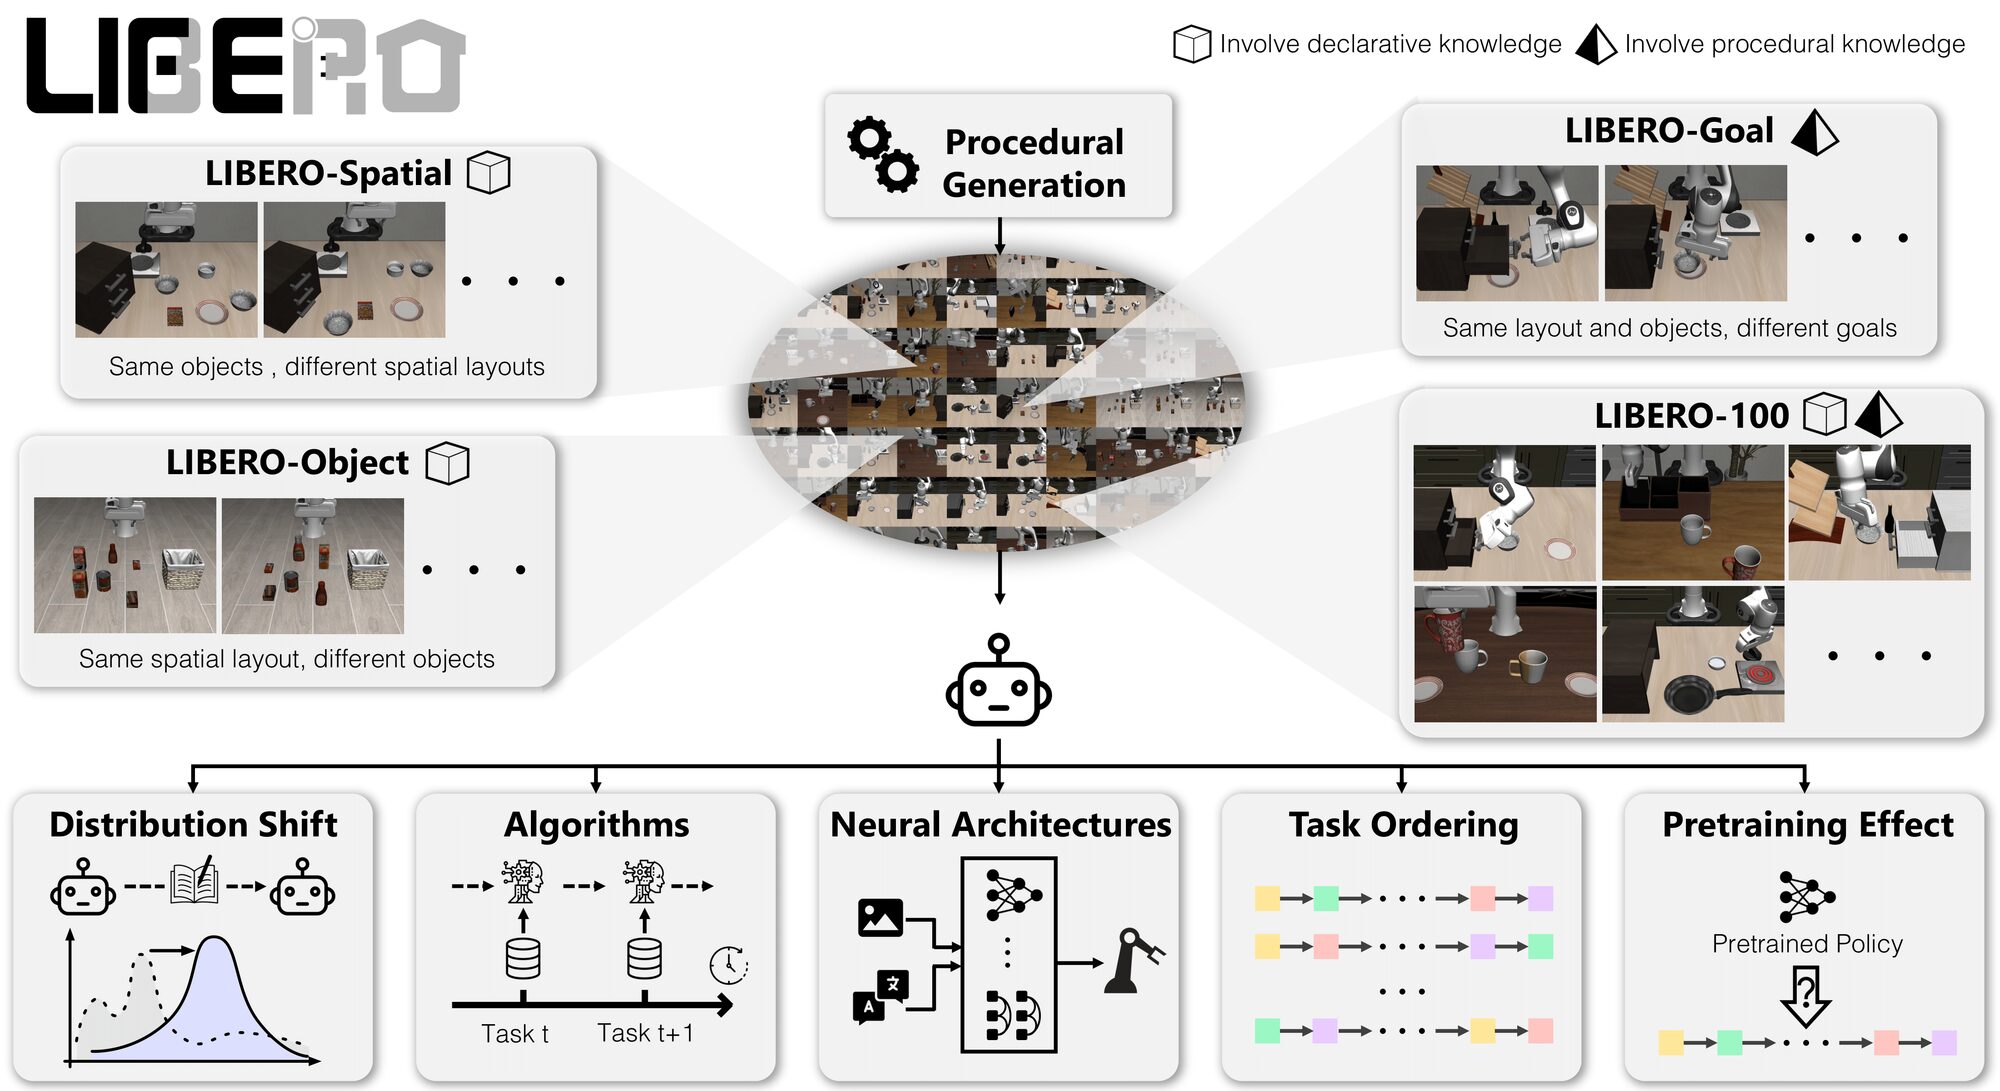
LIBERO reports 130 tasks: ten each in LIBERO-Spatial, LIBERO-Object and LIBERO-Goal, plus LIBERO-100: 90 short-horizon pretraining tasks and ten long-horizon downstream tasks. Each task has 50 human-expert demonstrations collected by Spacemouse teleoperationSource 5. LIBERO-Plus perturbs the benchmark along seven dimensions: object layout, camera viewpoint, robot initial state, language instruction, lighting, background texture and sensor noise. Models that score 95% on the clean benchmark fall below 30% under modest camera or initial-state shifts, and shuffling or removing the instruction barely moves performance, suggesting the models largely ignore the languageSource 6.
LIBERO-PRO reports that models above 90% on standard LIBERO collapse to 0.0% in its generalized settingSource 18, and THE COLOSSEUM measured 30 to 50% degradation per perturbation factor and at least 75% when perturbations combineSource 19. On RoboDojo's 42 simulated and 18 real tasks, the best of 30 policies in the standard setting scored 21.98 and fell to 1.57 under randomization, a 92.9% relative dropSource 20. On RoboCasa365's household tasks, the best multi-task baseline, GR00T N1.5, averaged 20.0% successSource 21.
Newer benchmarks build the variation in. RoboTwin 2.0 randomizes clutter, lighting, background, tabletop height and languageSource 22, and RoboLab's 120 tasks address the overlap between training and evaluation that trivializes success rates on existing benchmarksSource 23.
Simulation as an evaluation proxy
SIMPLER tests whether simulated performance predicts real performanceSource 7. It narrows the visual gap with real-image backgrounds and matched textures, and the control gap by fitting controller stiffness and damping through offline system identification. The project site reports about 1,500 evaluation episodes each from real and simulated Google Robot and WidowX setupsSource 24.
Agreement is scored with Pearson correlation, which can be unstable when policies perform similarly, and Mean Maximum Rank Violation, which weights wrong orderings by real performance margins. It varies by task: the WidowX carrot-placement comparison contains a ranking error. The experiments focus on rigid objects, and green-screening assumes fixed cameras and misses shadowsSource 7. Across 7 tasks and 5 policy architectures, SimFoundry's simulated evaluations reached a mean Pearson correlation of 0.911 with real results and a mean maximum rank violation of 0.018Source 25.
Generative world models now act as evaluators (world-model evaluation). Google DeepMind validated a Veo world simulator against 1,600+ real-world evaluations of eight Gemini Robotics checkpointsSource 26, WorldEval reports a strong correlation with real-world performanceSource 27, and Ctrl-World, trained on DROID, ranks policies without real rolloutsSource 28. SureSim corrects simulator bias with a few paired real and simulated trials and saves over 20 to 25% of hardware evaluation effort for similar boundsSource 29. Sim-to-Real Transfer covers simulation for training.
WorldOracle, from Haoyi Duan, Yuke Zhu and colleagues at AgiBot, NVIDIA and three universities (October 2026), feeds recorded actions from real robot episodes to seven action-conditioned world models and scores whether each predicted video matches what happenedSource 34. On 100 two-minute AgiBot G2 episodes, DreamDojo's single-view score out of 100 fell from 50.56 over the first 30 seconds to 27.08 over the full episode, and Cosmos 3 Nano's from 53.99 to 26.60Source 34. AgiBot's own GE-Sim 2.0, which shares four authors with the benchmark, fell from 73.86 to 63.33Source 34 Source 35.
Blind, distributed, pairwise
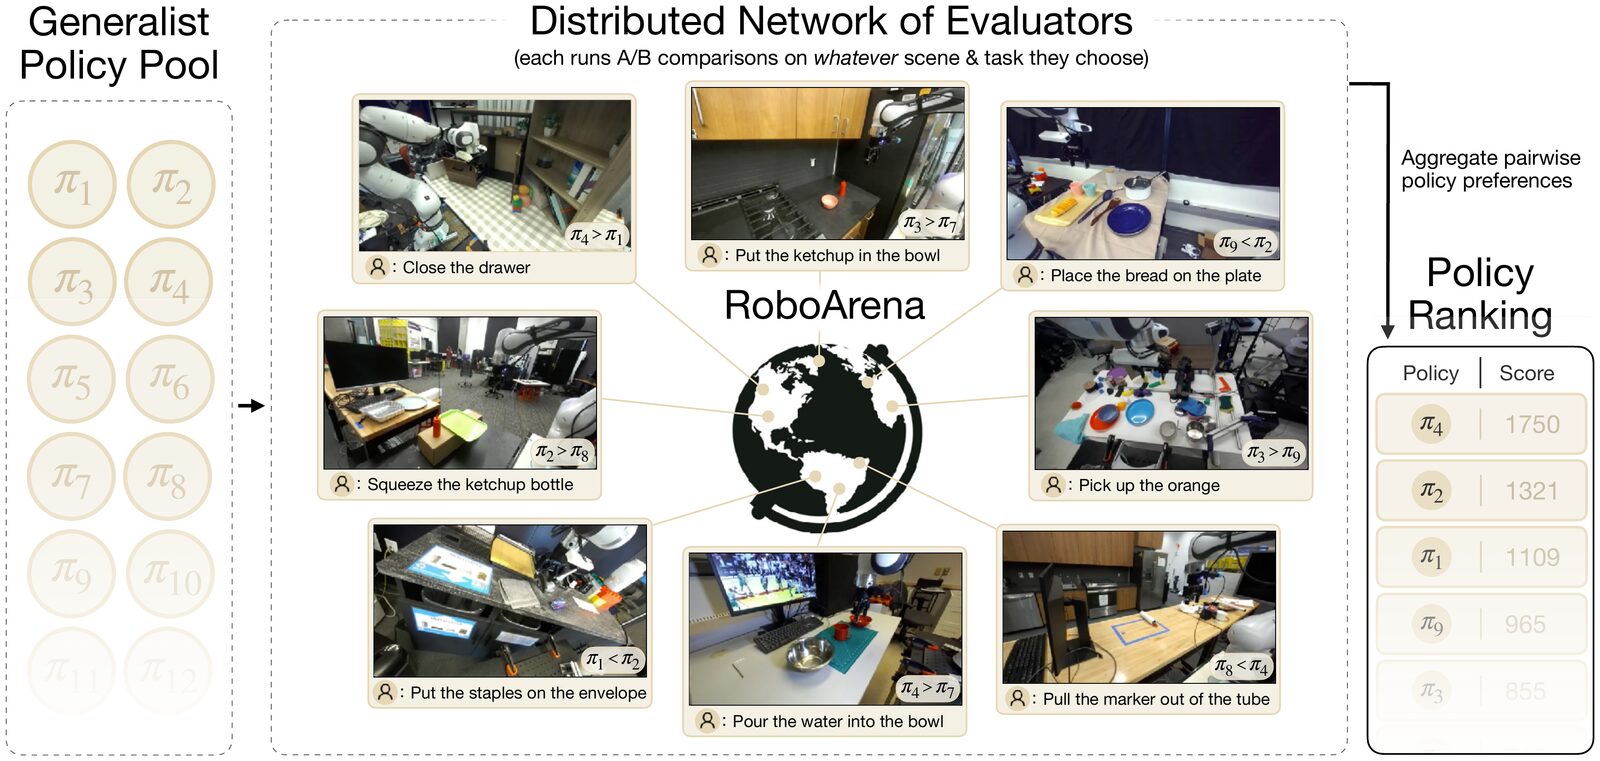
RoboArena distributes evaluation across seven universities on the DROID Franka Panda platformSource 10 Source 8. Evaluators receive anonymous policy endpoints, choose tasks and scenes, and run each pair double-blind and back-to-back from closely matched initial conditions, recording progress scores, preferences and explanations. Its study reports 612 pairwise comparisons across seven DROID-trained policies, and against a 4,284-rollout oracle its rankings agreed better than a conventional evaluation of 17 tasks and 44 episodes per policySource 8. Chatbot Arena ranks language models the same pairwise, crowdsourced way, from over 240K votesSource 30.
RoboChallenge hosts robots at its own site and exposes asynchronous observation and action APIs; model inference stays with the submitting user. Its first benchmark, Table30, holds tabletop tasks; held-out demonstration frames guide scene resets, but lighting and camera drift remain, and the system cannot verify the remote model matches its submitted nameSource 9.
OpenVLA's evaluation needed over 2,500 rollouts and over 100 hours of human labour, and AutoEval's automatic resets and success detection let evaluation run around the clockSource 31. XPolicyLab cuts the integrations needed to connect policies to environments from to Source 32.
Reading a result table
- How many rollouts produced the number, and is its uncertainty reportedSource 2?
- How long is the task?
- What survives perturbationSource 6?
- Who scored the rollouts, with what agreement against the tested populationSource 8?
- What correlation backs a simulation numberSource 7?
StopWatch, from Xinhao Liu, Pieter Abbeel, Guanya Shi and colleagues at Amazon FAR, NYU, UC Berkeley and Carnegie Mellon (October 2026), checked the labels that score HM3D-OVON, an object-goal navigation benchmark. A stop counts only when the object's annotated name matches the goal word, so a robot that stops at a couch annotated as sofa fails when asked for a couch, and a manual audit dropped 23% of the unseen-category validation episodes for missing or wrong labels. The frontier-exploration expert that generated the training demonstrations succeeds in 72% of episodes under the official scoring and 96% under the authors' corrected scoring of the remaining episodes, and their system's lead over the strongest baseline, LightNav-0, grows from 6.4 to 8.8 pointsSource 36.
Eval-Actions argues binary success rates hide process-level differences and provides 13K+ real-robot episodes over 150+ tasksSource 33, and fine-grained task progress separates policies with fewer trials than binary successSource 17. The reliability gap follows the same arithmetic into deployment.
Self-check
Read the reasoning
- Neither policy is established as better; inspect the uncertainty and comparison protocolA reported rate is not a policy comparison. TRI uses posterior distributions to characterize uncertainty and hypothesis tests to compare policies. Snyder et al. explain that an inconclusive test does not establish equivalence. Fifty trials is TRI's protocol choice; there is no universal threshold for an interpretable result.
- The identical reported success rates establish equivalent performanceThe same empirical rate does not establish equal underlying success probabilities. A failure to detect a difference can reflect insufficient power without establishing equivalence.
- Policy B is better because it used the more rigorous protocolMore information about how a policy was evaluated does not establish that its success probability is higher. Compare the policies under a suitable statistical procedure instead of ranking them by trial count.
Trial count and uncertainty matter, but neither equal reported rates nor an inconclusive test establish policy equivalence.
See also
- World Model Evaluation for Robotics
Testing a world model on what a robot needs.
- The Reliability Gap
80% task success is a demo; 99.9% is a product.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
Linked from
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Comparison Matrix
Every major policy compared on eight architectural axes.
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Offline Reinforcement Learning for Robotics
CQL and TD3+BC, and when behavior cloning is the stronger baseline.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- Industrial Deployment
The jam-rate arithmetic that decides whether a 99 percent cell ships.
- The Robot Learning Stack
From data capture to robot integration as one reproducible system.
- The Reliability Gap
80% task success is a demo; 99.9% is a product.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
- Competing Theses
Six bets on how robot intelligence gets built.
- The Bear Case
Why this could be another robotics winter.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
- Space Robotics
Robots where repair is impossible, from Mars to orbit.
References
Elliot Meyerson, Giuseppe Paolo, Roberto Dailey, Hormoz Shahrzad, Olivier Francon, Conor F. Hayes, and 3 more, 2025.
https://arxiv.org/abs/2511.09030
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
David Snyder, Asher James Hancock, Apurva Badithela, Emma Dixon, Patrick Miller, Rares Andrei Ambrus, and 3 more, RSS 2025.
https://arxiv.org/abs/2503.10966
Bo Liu, Yifeng Zhu, Chongkai Gao, Yihao Feng, Qiang Liu, Yuke Zhu, and 1 more, 2023.
https://arxiv.org/abs/2306.03310
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Xuanlin Li, Kyle Hsu, Jiayuan Gu, Karl Pertsch, Oier Mees, Homer Rich Walke, and 10 more, 2024.
https://arxiv.org/abs/2405.05941
Pranav Atreya, Karl Pertsch, Tony Lee, Moo Jin Kim, Arhan Jain, Artur Kuramshin, and 26 more, 2025.
https://arxiv.org/abs/2506.18123
Adina Yakefu, Bin Xie, Chongyang Xu, Enwen Zhang, Erjin Zhou, Fan Jia, and 31 more, 2025.
https://arxiv.org/abs/2510.17950
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
Hadas Kress-Gazit, Kunimatsu Hashimoto, Naveen Kuppuswamy, Paarth Shah, Phoebe Horgan, Gordon Richardson, and 2 more, 2024.
https://arxiv.org/abs/2409.09491
Stéphane Ross, Geoffrey J. Gordon, J. Andrew Bagnell, AISTATS 2011.
https://arxiv.org/abs/1011.0686
Oier Mees, Lukas Hermann, Erick Rosete-Beas, Wolfram Burgard, 2021.
https://arxiv.org/abs/2112.03227
Stanford Vision and Learning Lab, BEHAVIOR project site, 2026.
https://behavior.stanford.edu/challenge/index.html
Peter Henderson, Riashat Islam, Philip Bachman, Joelle Pineau, Doina Precup, David Meger, AAAI 2018.
https://arxiv.org/abs/1709.06560
Rishabh Agarwal, Max Schwarzer, Pablo Samuel Castro, Aaron Courville, Marc G. Bellemare, NeurIPS 2021.
https://arxiv.org/abs/2108.13264
David Snyder, Apurva Badithela, Nikolai Matni, George Pappas, Anirudha Majumdar, Masha Itkina, and 1 more, 2026.
https://arxiv.org/abs/2603.13616
Xueyang Zhou, Yangming Xu, Guiyao Tie, Yongchao Chen, Guowen Zhang, Duanfeng Chu, and 2 more, 2025.
https://arxiv.org/abs/2510.03827
Wilbert Pumacay, Ishika Singh, Jiafei Duan, Ranjay Krishna, Jesse Thomason, Dieter Fox, RSS 2024.
https://arxiv.org/abs/2402.08191
Tianxing Chen, Yue Chen, Zixuan Li, Junyuan Tang, Kailun Su, Haoran Lu, and 38 more, 2026.
https://arxiv.org/abs/2607.04434
Soroush Nasiriany, Sepehr Nasiriany, Abhiram Maddukuri, Yuke Zhu, ICLR 2026.
https://robocasa.ai/assets/robocasa365_iclr26.pdf
Tianxing Chen, Zanxin Chen, Baijun Chen, Zijian Cai, Yibin Liu, Zixuan Li, and 20 more, 2025.
https://arxiv.org/abs/2506.18088
Jenai Xuning Yang, Rishit Dagli, Alex Zook, Hugo Hadfield, Ankit Goyal, Stan Birchfield, and 2 more, Robotics: Science and Systems XXII (2026).
https://arxiv.org/abs/2604.09860
Xuanlin Li, Kyle Hsu, Jiayuan Gu, Karl Pertsch, Oier Mees, Homer Rich Walke, and 10 more, simpler-env.github.io, n.d.; accessed 2026-10-13.
https://simpler-env.github.io/
Nadun Ranawaka, Josiah Wong, Wei-Lin Pai, Wei-Teng Chu, Tianyuan Dai, Masoud Moghani, and 12 more, 2026.
https://arxiv.org/abs/2606.28276
Gemini Robotics Team, Krzysztof Choromanski, Coline Devin, Yilun Du, Debidatta Dwibedi, Ruiqi Gao, and 17 more, 2025.
https://arxiv.org/abs/2512.10675
Yaxuan Li, Yichen Zhu, Junjie Wen, Chaomin Shen, Yi Xu, 2025.
https://arxiv.org/abs/2505.19017
Yanjiang Guo, Lucy Xiaoyang Shi, Jianyu Chen, Chelsea Finn, 2025.
https://arxiv.org/abs/2510.10125
Apurva Badithela, David Snyder, Lihan Zha, Joseph Mikhail, Matthew O'Kelly, Anushri Dixit, and 1 more, 2025.
https://arxiv.org/abs/2510.04354
Wei-Lin Chiang, Lianmin Zheng, Ying Sheng, Anastasios Nikolas Angelopoulos, Tianle Li, Dacheng Li, and 5 more, 2024.
https://arxiv.org/abs/2403.04132
Zhiyuan Zhou, Pranav Atreya, You Liang Tan, Karl Pertsch, Sergey Levine, 2025.
https://arxiv.org/abs/2503.24278
XPolicyLab Community, Tianxing Chen, Yue Chen, Tian Nian, Zijian Cai, Guangyu Chen, and 64 more, 2026.
https://arxiv.org/abs/2608.09892
Mengyuan Liu, Juyi Sheng, Peiming Li, Ziyi Wang, Tianming Xu, Tiantian Xu, and 1 more, 2026.
https://arxiv.org/abs/2601.18723
Haoyi Duan, Liliang Chen, Nan Wang, Yang Zhang, Yuhang Lu, Xiaotong Chen, and 10 more, 2026.
https://arxiv.org/abs/2610.18826
Boxiang Qiu, Liliang Chen, Yue Liao, Nan Wang, Lintao Wang, Jiayi Luo, and 9 more, 2026.
https://arxiv.org/abs/2605.27491
Xinhao Liu, Yunsheng Tian, Yuheng Qiu, Pieter Abbeel, Xi Chen, Guanya Shi, and 1 more, 2026.
https://arxiv.org/abs/2610.23841
Spot a factual error or missing qualification? Report a content correction.