Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
Generative video world models are video predictors that generate future pixels from the current frame and an action or text prompt, standing in for the environment to supply training data, policy evaluation, RL post-training and interactive worlds. UniSim trained policies purely inside such a simulator and deployed them zero-shot in the real worldSource 16.
Switch "Video model" from "Listens to the action" to "Ignores the action", and the two futures from one start frame collapse onto the same picture. The action-sensitivity score falls to near zero while the visual-realism score stays put. Video generators show this split: "visual realism does not imply physical understanding"Source 17.
The action test
A good video model shows different futures for different actions
Video model
Adjust more
First command
Second command
Left screen: push left; right screen: lift gripper. Two commands, two different futures: the model is listeningaction sensitivity 0.419 · realism 0.91
Illustrative: a toy model, not a trained video model.
How this was made
The photo standing on top of the console is the shared start: a block on a table, a gripper above it and a goal zone on the left. Each screen plays what a video model imagines after one command, with the 4 imagined frames drawn on top of each other, earlier ones faint. The command comes from the lever on the desk in front of the screen: left for push left, right for push right, back for lift.
A model that listens is the console with both plugs seated, so it slides the block for a push and raises the gripper for a lift. A model that ignores the action is the console with the plugs pulled: it imagines the block drifting toward the goal for every command, because that is what most successful task videos show.
What tells the two models apart is action sensitivity, the upper meter between the screens: the average distance between the two imagined futures, frame by frame, with block position and gripper height each measured from 0 to 1. Above 0.30, the long mark at the top of its scale, the futures genuinely differ. For the current pair it is 0.419. Visual realism, the lower meter, is held at 0.91 for both models on purpose: both draw equally sharp video, so realism alone cannot show whether a model follows the action.
The futures are hand-set for this toy, not produced by a trained video model, and the plug stands for how strongly a model uses the action, not for a real connector.
With a model that listens to the action, push left and lift gripper lead to different futures across 4 imagined frames: action sensitivity is 0.419, above the 0.30 threshold, while visual realism stays 0.91 for both models.
Current pair of imagined futures
- video model
- Listens to the action
- first command
- Push left
- second command
- Lift gripper
- action sensitivity
- 0.419
- visual realism
- 0.91
16B
Cosmos 3 Nano
dense 8B basis; dual-tower MoT
24 fps
Genie 3
DeepMind-reported: 720p, a few minutes
>10 min
IWS video rollout
reported; up to 15 FPS, one RTX 4090
0.989
RoboWorld Pearson r
8 policy aggregates; GPT-4o vs RoboArena
Cosmos 3 replaces a stack of separate models with one omni-model
NVIDIA's Cosmos 3 report calls a home robot built from a separate VLM planner, VLA or WAM, and forward-dynamics model "fragmented" and "computationally wasteful"Source 1. Cosmos 3, launched at GTC Taipei on 31 May 2026, unifies those capabilities in one omni-modelSource 2.
Its Mixture-of-Transformers backbone routes language and ViT-encoded vision to a causal autoregressive reasoner and VAE-encoded vision, audio and actions to a diffusion generator; diffusion tokens attend to both streams, while reasoner tokens never read diffusion tokensSource 1. It supports VLM understanding, video generation and three action modes: forward dynamics (video from clean actions), inverse dynamics (actions from clean video) and policy (both). Specialized results come from separate post-training, such as a DROID policy started from mid-trained Cosmos3-Nano with fresh action modules. Nano has 16B parameters on a dense 8B transformer and Super 64B on a dense 32B oneSource 1.
Genie 3 renders worlds at 24 fps that hold for a few minutes
The original Genie learned latent actions and generated 2D worlds at about one frame per secondSource 3. Genie 2 (December 2024) moved to 3D, with consistent worlds for up to a minute and most examples lasting 10 to 20 secondsSource 4.
In its August 5, 2025 announcement, DeepMind describes Genie 3 as a limited research preview: text-prompted worlds navigable in real time at 24 fps and 720p, largely consistent for a few minutes. A SIMA agent sent navigation actions to Genie 3, and the world model simulated the future without knowing the agent's goal; the test involved no robot manipulation. It lists five limits: a constrained direct action space, multi-agent interaction, geographic accuracy, legible text only when supplied, and a few minutes of continuous interactionSource 5.
Project Genie, released in January 2026 for AI Ultra subscribers, caps sessions at 60 seconds per worldSource 6 Source 18.
GR-1 and GR-2 built on video pre-training; GR-3 switched to a VLA
GR-1 applied large-scale video generative pre-training to multi-task manipulation, predicting future images and actions end to end. On CALVIN it moved success from 88.9% to 94.9%, and in zero-shot unseen scenes from 53.3% to 85.4%Source 7. GR-2 pre-trained on 38 million internet clips and over 50 billion tokens, reporting 97.7% average success across more than 100 tasksSource 8. GR-3 then switched to a 4B-parameter VLASource 19.
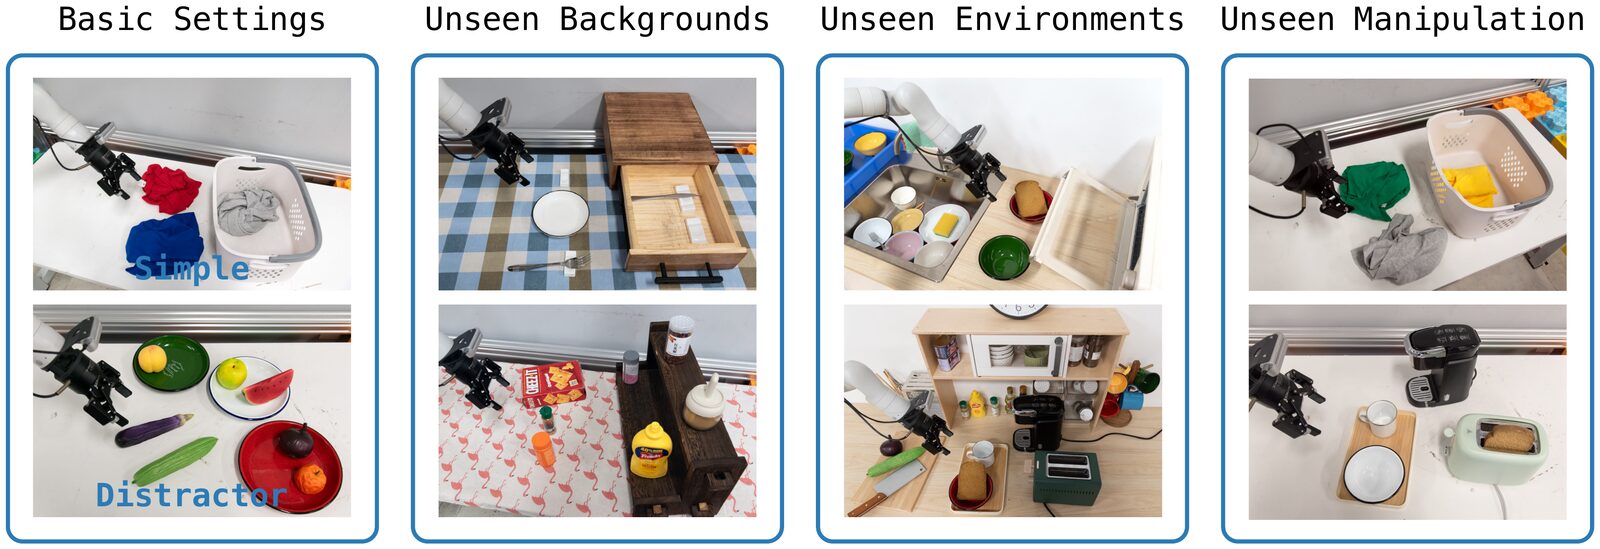
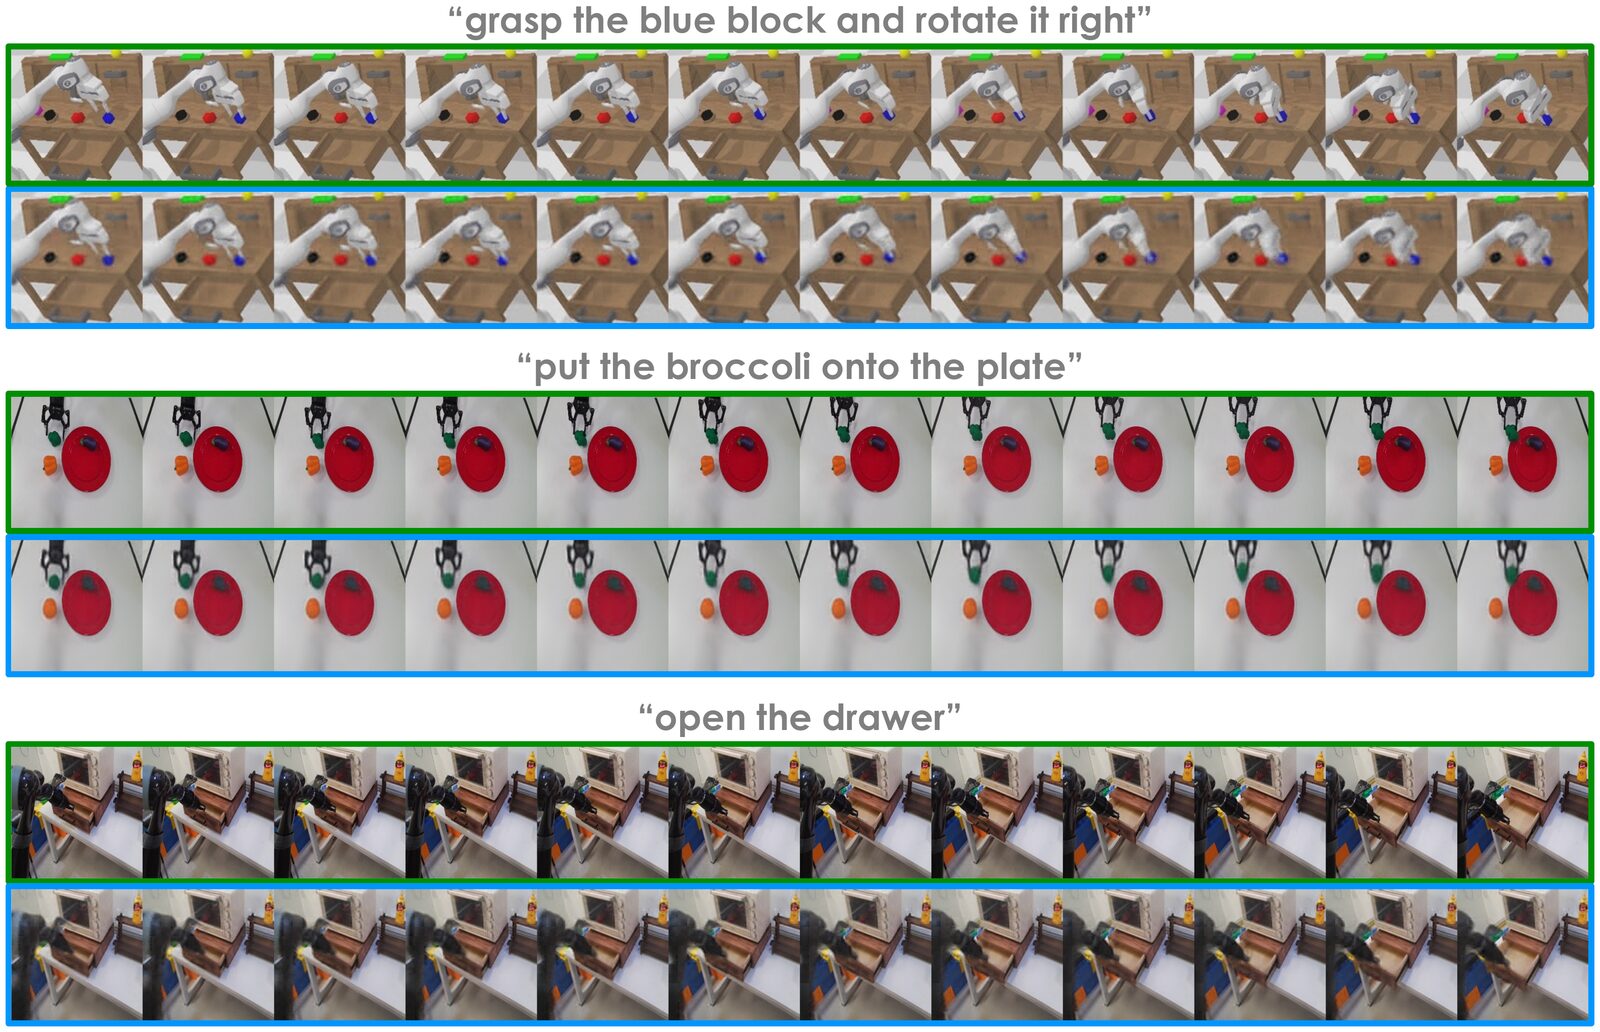
World-action models now run as closed-loop robot policies
A world-action model (WAM) predicts future video and actions together. NVIDIA reports that DreamZero runs a 14B autoregressive video-diffusion model as a 7 Hz closed-loop policy and more than doubles the generalization of state-of-the-art VLAs on real robotsSource 20. Cosmos Policy post-trains Cosmos-Predict2 with no architectural modifications and reaches 98.5% on LIBERO and 67.1% on RoboCasaSource 21.
Under perturbation, Cosmos-Policy reached 82.2% on LIBERO-Plus and LingBot-VA 74.2% on RoboTwin 2.0-Plus, while VLAs such as π0.5 matched them on some tasks only with extensive, diverse trainingSource 22. Fast-WAM stays competitive without test-time video generation, while removing video co-training costs far moreSource 23.
OpenWAM (October 2026), from Heng Yu, Li Fei-Fei, Jiajun Wu, Ehsan Adeli and colleagues at Stanford, pretrains the Wan2.2-5B video model causally on more than 10,000 hours of robot video. That training raised video-then-action success on LIBERO-Long from 68.4% to 97.8% over the original Wan2.2-5B. Its action expert can generate jointly, video first, action first or decoupledSource 31.
Long-WAM (October 2026), from Wei Huang, Linxi Fan, Song Han, Yukang Chen and colleagues at NVIDIA, MIT and HKU, found that longer visual history pays off when the video model was pretrained autoregressively. On RoboCasa GR-1, extending context from 0 to 19.2 seconds raised success from 63.3% to 78.7%, while a bidirectionally pretrained start showed no net gain. On real robots it stacked moving cups in 95% of trials, a task where π0.5 and Fast-WAM succeeded in none of 20Source 32.
DreamCan (October 2026), from Chongkai Gao, Jiajun Wu, Li Fei-Fei and colleagues at Stanford, NUS, Harvard and Northwestern, plans with a few generated subgoal images instead of dense video. Its training subgoals are chosen to balance whether a low-level policy can reach each one against how far each moves the task. With a 0.1-billion-parameter policy that was not pretrained, it reached 91.2% on LIBERO-Long against 82.4% for evenly spaced subgoals. π0.5 and Lingbot-VA, whose scores the authors took from the original papers, reached 92.4% and 98.5%Source 34.
1X still fails dexterous tasks, while Odyssey streams worlds live
1X reports that its NEO policy builds on a 14B video model, mid-trained on 900 hours of egocentric human video and fine-tuned on 70 hours of robot data, with an inverse-dynamics model (IDM) extracting actions. Over 30 runs per task it scored 0% on drawing a smiley and pouring cereal. The backbone takes 11 seconds per 5 seconds of video, plus 1 second for the IDMSource 24. In June 2026, 1X launched a World Model Lab led by Sam Sinha, previously a founding research scientist at Luma AISource 9.
Odyssey-2 (October 2025) generates each frame causally from prior frames and user input, streaming a new frame every 50 ms (about 20 fps), steerable by textSource 10.
Weak action conditioning is the field's main bottleneck
The 2026 survey lists causal conditioning gaps first among its open challenges and calls weak action conditioning the technical bottleneck. Models trained mostly from observation history and task intent produce futures "semantically plausible or intention-consistent, but not necessarily faithful to the physical consequences of the candidate action"Source 13. In closed-loop tests, controllability mattered more than visual quality, and post-training on action-observation data beat upgrading the base generatorSource 25.
Samuel Bateman, Benjamin Eysenbach, Dhruv Shah and colleagues at Princeton and Columbia (October 2026) trace the weakness to the data. They prove that how much a dataset's actions influence its next states caps the action influence any model trained on it can express, so expert demonstrations, whose next states can be predicted without the action, set a low ceilingSource 35. In a simulated pixel-based Push-T task, 500 episodes collected by their AIM method and added to 3,000 demonstrations matched a model trained on 300,000 expert episodes on end-effector controllability, an 85-fold cut in dataSource 35.
In IWS tests, generated demonstrations rivalled real ones for two policies
The Interactive World Simulator is built on an action-conditioned latent dynamics model. It reports more than 10 minutes of stable generated-video interaction at up to 15 FPS on a single RTX 4090, at a default 128×128 resolution; quantitative video comparisons use 192 steps (19.2 seconds)Source 11.
In 100-episode mixtures, generated-only versus real-only policy data scored 87.9% versus 90.3% for DP and 76.2% versus 73.6% for ACT. With more real data, π0.5 rose from 73.1% to 88.8%. Points used 100 MuJoCo or 10 physical evaluations, and the simulator was trained on interaction data including real play. A four-task test from 20 initial configurations gave positively biased simulator scores except for T pushingSource 11.
Some video simulators rank policies in real-world order, others do not
RoboWorld pairs an autoregressive video world model with a GPT-4o scorer that rates task progress from 0 to 5 from fixed external views. In its fourth revision, 4,186 generated 30-second rollouts gave eight policy-level scores matching the 26 February 2026 RoboArena leaderboard at Pearson r = 0.989 and Spearman rho = 0.970 (p < 0.001); the eight aggregates are the correlation points. The paper reports contact-induced object artifacts and VLM scores about one point above human scores over roughly 100 rolloutsSource 12.
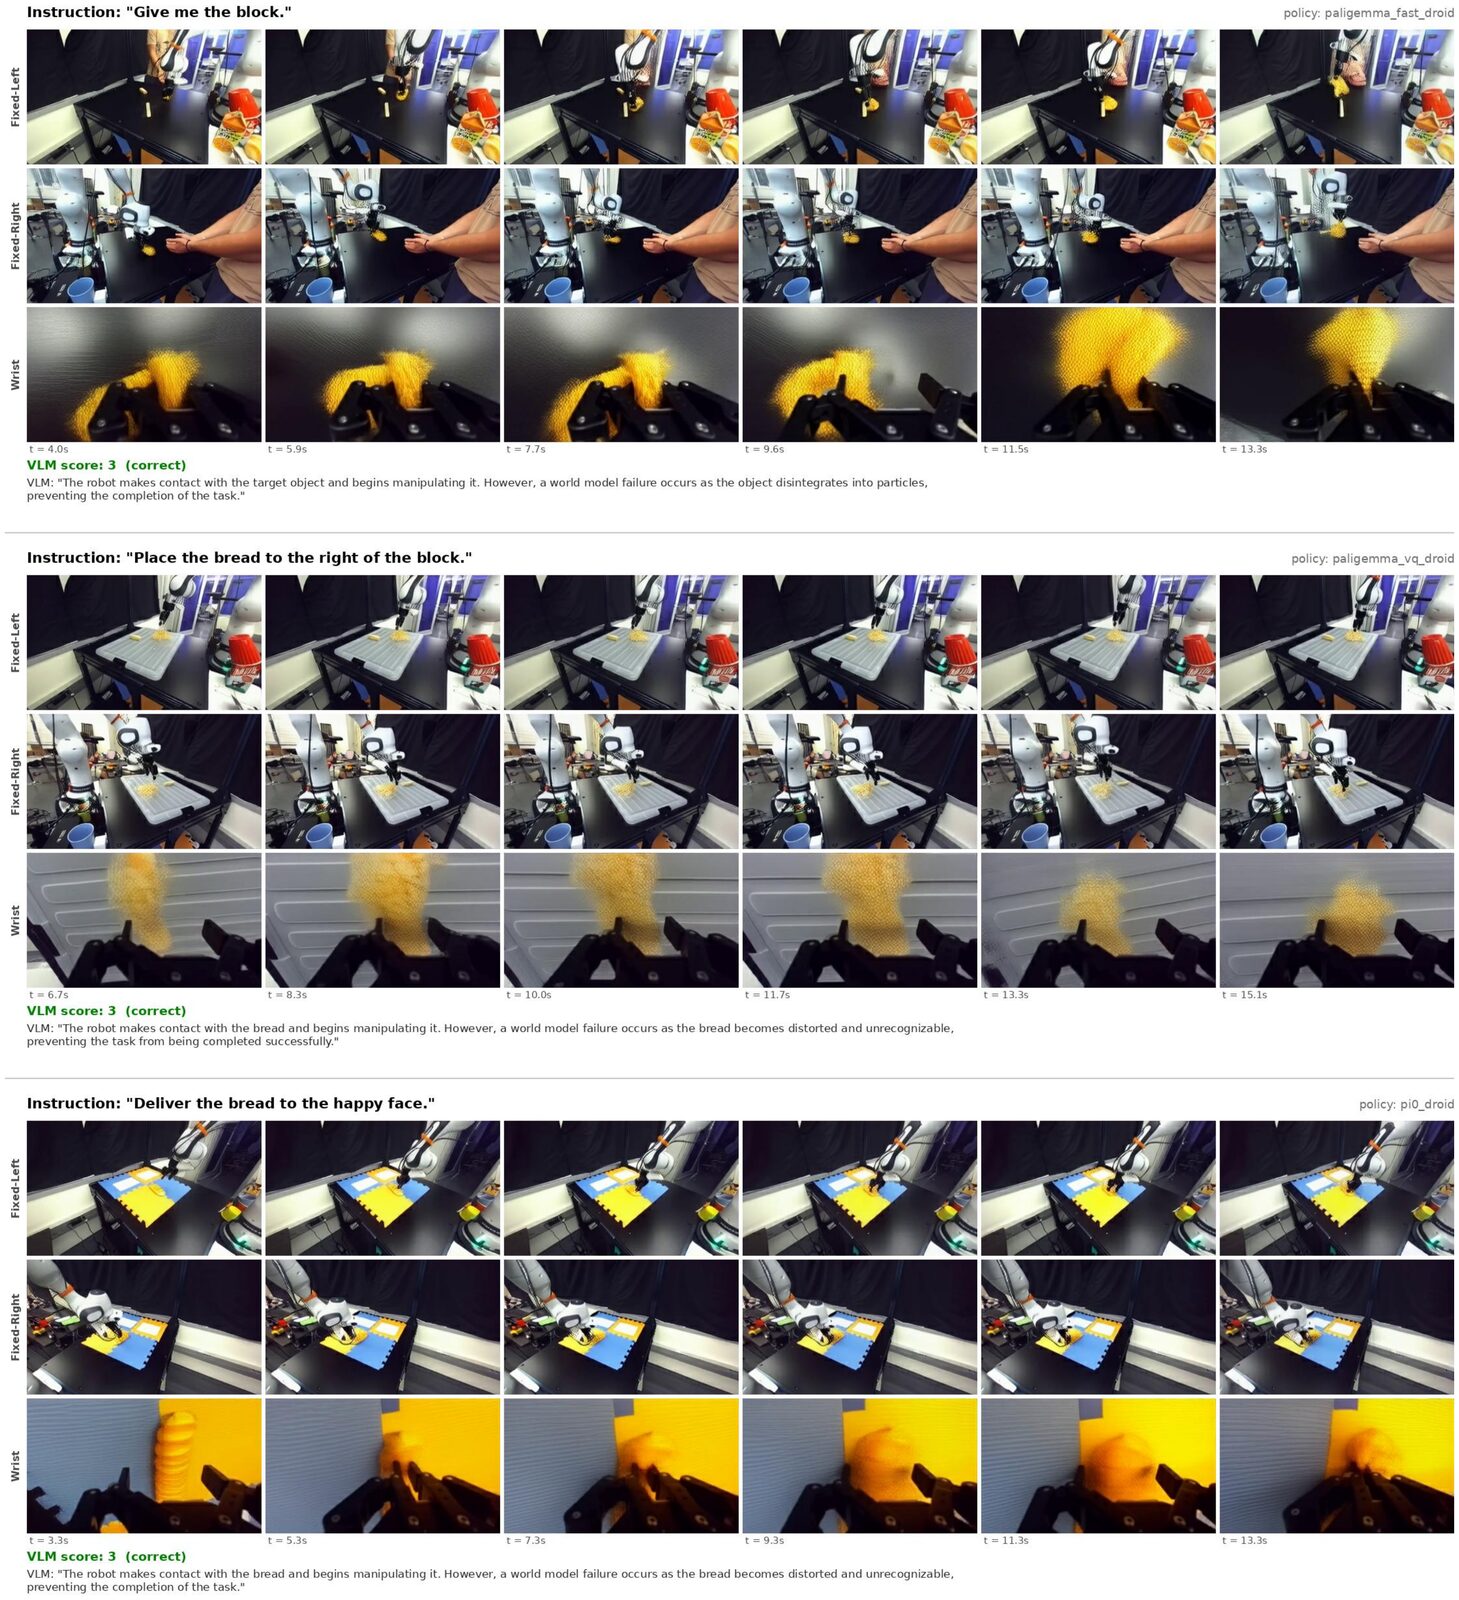
DeepMind reports its Veo-based simulator predicted relative policy performance in nominal and out-of-distribution conditions, checked against more than 1,600 real evaluations. Its episodes last 8 seconds, and its authors call contact-rich, small-object interaction an open challengeSource 26. PolaRiS found that the open Ctrl-World hallucinated during object interaction in diverse scenes and mis-ranked policies at MMRV 0.22Source 27.
In February 2026 Runway reported a similar ranking test for its GWM-Robotics world model. Across eight vision-language-action policies from RoboArena, with 1,450 simulated rollouts scored by human graders, the policies' simulated and real progress scores had a Pearson correlation of 0.95Source 14. Runway says the study tests policy ranking only and does not predict absolute success ratesSource 14. In September 2026 it announced Praxis-1, a world action model it is testing with partners before an open-weight releaseSource 15.
Generated experience trains real policies, but contact-rich tasks stay open
RISE ran RL inside a compositional world model and gained 35 to 45 absolute points on three real tasks, including dynamic brick sortingSource 28. GRAIL used 3D assets and video-model priors to generate over 20,000 humanoid sequences. Visual policies trained only on them reached 84% success on object pick-up and 90% on stair-climbing on a real Unitree G1Source 30.
Yinlong Dai, Homanga Bharadhwaj and Dylan P. Losey at Virginia Tech and Johns Hopkins (October 2026) seed CASTER with generated videos of a person doing the task, then optimize a feasible robot motion in a digital twinSource 33. Over 12 real tasks on a Franka arm with 21 trials each, it succeeded zero-shot 76.6% of the time, against 42.5% for a twin baseline that tracks each video's object path exactlySource 33. The authors trace kettle pouring and bucket covering failures to physics the twin did not modelSource 33.
The survey calls visual plausibility "only a weak proxy for control utility" and says vision and proprioception miss friction, stiffness and contact stability, making tactile integration indispensable. World-model policies also cost far more compute than VLAs in training and inference, and iterative diffusion denoising adds latencySource 13.
Test action response before trusting a video model's rankings
Start with paired interventions that change only the action from identical frames, checking direction, contact onset and object identity before image quality, then lengthen the horizon on held-out transitions. Only then rank policies against blinded real trials. By 1X's estimate, with a 15% real gap between two policies, a world model with 70% accuracy picks the better one 90% of the timeSource 29. The evaluation guide gives the full protocol; see also the evaluation crisis, world models versus simulators and the non-generative JEPA.
See also
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
Linked from
- Diffusion Policy
Visuomotor control as conditional denoising over action sequences, with receding-horizon execution.
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
- Competing Theses
Six bets on how robot intelligence gets built.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
References
NVIDIA, Aditi, Niket Agarwal, Arslan Ali, Jon Allen, Martin Antolini, and 289 more, 2026.
https://research.nvidia.com/labs/cosmos-lab/cosmos3/technical-report.pdf
NVIDIA, NVIDIA Newsroom, 2026.
https://nvidianews.nvidia.com/news/nvidia-launches-cosmos-3-the-open-frontier-foundation-model-for-physical-ai
Jake Bruce, Michael Dennis, Ashley Edwards, Jack Parker-Holder, Yuge Shi, Edward Hughes, and 19 more, 2024.
https://arxiv.org/abs/2402.15391
Jack Parker-Holder, Philip Ball, Jake Bruce, Vibhavari Dasagi, Kristian Holsheimer, Christos Kaplanis, and 26 more, Google DeepMind, 2024.
https://deepmind.google/blog/genie-2-a-large-scale-foundation-world-model/
Jack Parker-Holder, Shlomi Fruchter, Google DeepMind, 2025.
https://deepmind.google/blog/genie-3-a-new-frontier-for-world-models/
Ryan Whitwam, Ars Technica, 2026.
https://arstechnica.com/google/2026/01/google-project-genie-lets-you-create-interactive-worlds-from-a-photo-or-prompt/
Hongtao Wu, Ya Jing, Chilam Cheang, Guangzeng Chen, Jiafeng Xu, Xinghang Li, and 3 more, 2023.
https://arxiv.org/abs/2312.13139
Chi-Lam Cheang, Guangzeng Chen, Ya Jing, Tao Kong, Hang Li, Yifeng Li, and 6 more, 2024.
https://arxiv.org/abs/2410.06158
1X, 2026.
https://www.1x.tech/discover/1x-world-model-lab
Oliver Cameron, Odyssey, 2025.
https://odyssey.ml/introducing-odyssey-2
Yixuan Wang, Rhythm Syed, Fangyu Wu, Mengchao Zhang, Aykut Onol, Jose Barreiros, and 4 more, 2026.
https://arxiv.org/abs/2603.08546
Byeongguk Jeon, Seonghyeon Ye, JaeHyeok Doo, Sungdong Kim, Minjoon Seo, Hyungmok Son, and 1 more, 2026.
https://arxiv.org/abs/2607.01060
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Andy Chen, Lucas Eager Leavitt, Rik Heijdens, Robin Kahlow, Runway Research, 2026.
https://runway.com/research/accelerating-robot-policy-evaluation
Sherry Yang, Yilun Du, Kamyar Ghasemipour, Jonathan Tompson, Leslie Kaelbling, Dale Schuurmans, and 1 more, 2023.
https://arxiv.org/abs/2310.06114
Saman Motamed, Laura Culp, Kevin Swersky, Priyank Jaini, Robert Geirhos, 2025.
https://arxiv.org/abs/2501.09038
Google, Google (The Keyword), 2026.
https://blog.google/innovation-and-ai/models-and-research/google-deepmind/project-genie/
Chilam Cheang, Sijin Chen, Zhongren Cui, Yingdong Hu, Liqun Huang, Tao Kong, and 15 more, 2025.
https://arxiv.org/abs/2507.15493
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
Moo Jin Kim, Yihuai Gao, Tsung-Yi Lin, Yen-Chen Lin, Yunhao Ge, Grace Lam, and 5 more, 2026.
https://arxiv.org/abs/2601.16163
Zhanguang Zhang, Zhiyuan Li, Behnam Rahmati, Rui Heng Yang, Yintao Ma, Amir Rasouli, and 8 more, 2026.
https://arxiv.org/abs/2603.22078
Tianyuan Yuan, Zibin Dong, Yicheng Liu, Hang Zhao, 2026.
https://arxiv.org/abs/2603.16666
1X AI Team, 1X Technologies, 2026.
https://www.1x.tech/discover/world-model-self-learning
Jiahan Zhang, Muqing Jiang, Nanru Dai, Taiming Lu, Arda Uzunoglu, Shunchi Zhang, and 11 more, ICLR 2026 (Oral), 2025.
https://arxiv.org/abs/2510.18135
Gemini Robotics Team, Krzysztof Choromanski, Coline Devin, Yilun Du, Debidatta Dwibedi, Ruiqi Gao, and 17 more, 2025.
https://arxiv.org/abs/2512.10675
Arhan Jain, Mingtong Zhang, Kanav Arora, William Chen, Marcel Torne, Muhammad Zubair Irshad, and 8 more, 2025.
https://arxiv.org/abs/2512.16881
Jiazhi Yang, Kunyang Lin, Jinwei Li, Wencong Zhang, Tianwei Lin, Longyan Wu, and 7 more, RSS 2026.
https://arxiv.org/abs/2602.11075
Tianyi Xie, Haotian Zhang, Jinhyung Park, Zi Wang, Bowen Wen, Jiefeng Li, and 14 more, 2026.
https://arxiv.org/abs/2606.05160
Heng Yu, David D. Yuan, Juze Zhang, Changan Chen, Yao Feng, Michelle Baldonado, and 4 more, 2026.
https://arxiv.org/abs/2610.07922
Wei Huang, Bohan Zhang, Chenzhi Liu, Isabella Liu, Shuai Yang, Weian Mao, and 10 more, 2026.
https://arxiv.org/abs/2610.10528
Yinlong Dai, Homanga Bharadhwaj, Dylan P. Losey, 2026.
https://arxiv.org/abs/2610.12567
Chongkai Gao, Wenlong Huang, Haonan Chen, Lin Shao, Yilun Du, Jiajun Wu, and 2 more, 2026.
https://arxiv.org/abs/2610.24981
Samuel M. Bateman, Tenny Yin, Chongyi Zheng, Lei Huang, Brian Wang, Benjamin Eysenbach, and 2 more, 2026.
https://arxiv.org/abs/2610.27387
Further reading
Oliver Cameron, Odyssey, 2026.
https://odyssey.systems/introducing-starchild-1
Oliver Cameron, Odyssey, 2026.
https://odyssey.systems/introducing-agora-1
Waymo, Waymo Blog, 2026.
https://waymo.com/blog/2026/02/the-waymo-world-model-a-new-frontier-for-autonomous-driving-simulation/
Lin Li, Qihang Zhang, Yiming Luo, Shuai Yang, Ruilin Wang, Fei Han, and 6 more, 2026.
https://arxiv.org/abs/2601.21998
Shenyuan Gao, William Liang, Kaiyuan Zheng, Ayaan Malik, Seonghyeon Ye, Sihyun Yu, and 24 more, 2026.
https://arxiv.org/abs/2602.06949
Spot a factual error or missing qualification? Report a content correction.