Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
Model-based robot learning is the family of methods that learn how the world responds to actions and use that model to plan, to train a policy in imagination, or both. Its two steps are learning a dynamics model and integrating planning with learningSource 10.
The loop predicts futures under candidate actions, scores them, acts, observes the real transition and updates the model. Sutton proposed integrated architectures for learning, planning and reacting in 1990Source 11.
Self-check
Read the reasoning
- The model is useful for planning because its videos look photorealisticVisual fidelity cannot select among actions when the rollout ignores the candidate action. The model may be a good generator and a poor control model.
- The model has action-conditioning collapse and cannot support planningPlanning requires counterfactual separation: different actions must produce meaningfully different predicted consequences. Without it, every candidate receives nearly the same evidence.
- The planner needs a longer prediction horizonA longer rollout compounds the same missing action dependence. Horizon cannot recover information the one-step transition failed to encode.
A control model earns its name by changing its prediction when the candidate action changes.
Model-based means predicting the effect of an action
A 2026 survey defines a world model as "an action-conditioned predictive system"Source 13. Classical model-predictive control (MPC) uses explicit dynamics, such as MuJoCo's rigid-body and contact modelSource 6; model-based learning fits some or all of that transition to data.
A world model need not predict pixels: value-equivalent models predict only what planning needs, "without compromising performance"Source 14.
A model can plan each step or train a policy in imagination
A planner rolls sampled action sequences through the model, executes the best first action and replans, so a new goal or cost needs no retraining, at the price of many rollouts per real step (reward design and MPC). In 2016 Finn and Levine combined action-conditioned video prediction with MPC so a real robot could push novel objectsSource 15. TD-MPC2 trained one 317M-parameter agent on 80 tasksSource 4, and PointWorld, trained on about 2 million trajectories, plans with MPC at 0.1 s per inference on a real Franka without demonstrationsSource 30.
Dreamer instead trains a policy on trajectories imagined in a learned latent spaceSource 1, and DreamerV3 covers more than 150 tasks with one configurationSource 2. Dreamer 4 learns purely offline, a setting its authors tie to robotics, where interaction "can be unsafe and slow"Source 16. Latent dynamics covers these agents.
Uncertainty estimates keep policies from exploiting model errors
A policy trained on a model "tends to exploit regions where insufficient data is available", which ME-TRPO counters with an ensembleSource 17. PETS, a probabilistic ensemble, matches model-free asymptotic performance with 8 and 125 times fewer samples than SAC and PPO on half-cheetahSource 18. MBPO keeps rollouts short and "branched from real data"Source 19. In offline RL, MOPO penalizes reward by model uncertaintySource 20.
Robots see only part of the state, yet learn useful models in minutes to hours
A robot observation is partial: cameras miss forces, friction and compliance, and RGBD gave an 80% improvement in fabric-folding success over RGBSource 21. Data is narrow too: Hansen and Wang call world-model hallucination "inherently a data coverage issue" and adapt a model to unseen simulated environments with 50 trajectoriesSource 22.
Chenyuan Zhou, Yining Hong, Jiajun Wu and colleagues at Stanford and elsewhere (October 2026) condition a video world model on a 32-dimensional latent for hidden factors such as friction or mass, fitted at test time from one or two interactions while the model stays frozenSource 31. Averaged over four real-robot tasks, the adapted model's mean tracking error fell from 19.30 to 10.85 pixels against the same model without a latentSource 31. Actions it picked succeeded 70.80% of the time against 26.47% for the model without a latent, though the paper does not state trial countsSource 31.
PDDM learned contact-rich manipulation on a 24-DoF hand from 4 real hoursSource 23. DayDreamer ran Dreamer online on 4 robots without simulators; a quadruped learned to stand up and walk in 1 hourSource 3. SSRL adds a learned force ensemble to known Lagrangian dynamics and learned Go1 gaits from a few minutes of dataSource 24.
In September 2026, Claudio Canales, Marco Hutter and colleagues learned a probabilistic dynamics ensemble from scratch on an 11.5-ton hydraulic excavator. After 20 minutes, their sampling-based MPC tracked comparably to learned controllers trained on 100 to 150 minutes; after 40 it held sub-centimeter mean path error at high speedSource 8. Hansen, Fox and colleagues trained one TD-MPC2 model in simulation on up to 90 insertion tasks, with 56% zero-shot success on unseen objects against 7% model-freeSource 9.
Learning on the machine
An excavator learned its own arm in 20 minutes
Minutes of practice on the machine
Faint: the five models' guesses. Blue: where the shovel went20 minutes · matches earlier controllers
Checkpoints from the paper; the path and the guesses' spread are illustrative
How this was made
Canales, Nan, Hutter and Ruiz-del-Solar learned a model of an 11.5-ton Menzi Muck M445 walking excavator's arm from scratch on the machine itself, with no demonstrations and no simulator. Its sensors measure the joints but not the oil pressures or the valves' inner state, so the model reads a short history of joint positions and valve commands. The model is an ensemble of five networks, refitted after every ten trajectories; a sampling-based planner tries thousands of command sequences through it every control cycle and sends the first command of the best one.
The drawing is that loop on a practice yard. A stylus on the shovel inks where the shovel really went (blue) against the path engraved on the board, and five faint lines ahead of it are the five models' guesses of where it goes next. The trainer's dial counts minutes of practice; its band marks the 100 to 150 minutes of machine data the earlier learned controllers were given. The paper's snapshots show large misses after 3 minutes, the path followed more closely after 10 and consistent tracking after 20. After 20 minutes the shovel tracked its timed path 2.7 cm off on average, against 2.8 and 4.5 cm for the earlier controllers; after 40 minutes every objective kept it under a centimetre off the path on average.
Illustrative: the path, the misses drawn at 3 and 10 minutes (shaped like the paper's snapshots, not measured) and how far the guesses fan out. At 20 and 40 minutes the misses are drawn at the paper's mean errors, too small to see at this scale. The machine is drawn with its arm in one plane, the telescopic extension sliding out as it reaches further.
Canales, Nan, Hutter and Ruiz-del-Solar (2026), Fig. 5 and Table II.
Model error is task-weighted
A two-millimeter error is irrelevant in free space and decisive at a tight connector. One-step prediction likelihood "is not always correlated with control performance", and task-effective models "do not necessarily need to be globally accurate"Source 12. The 2026 robot world-model survey stresses action-conditioned consistency and functional-utility evaluationSource 7; the evaluation guide gives a protocol.
Neural and hybrid simulators now train real-robot policies
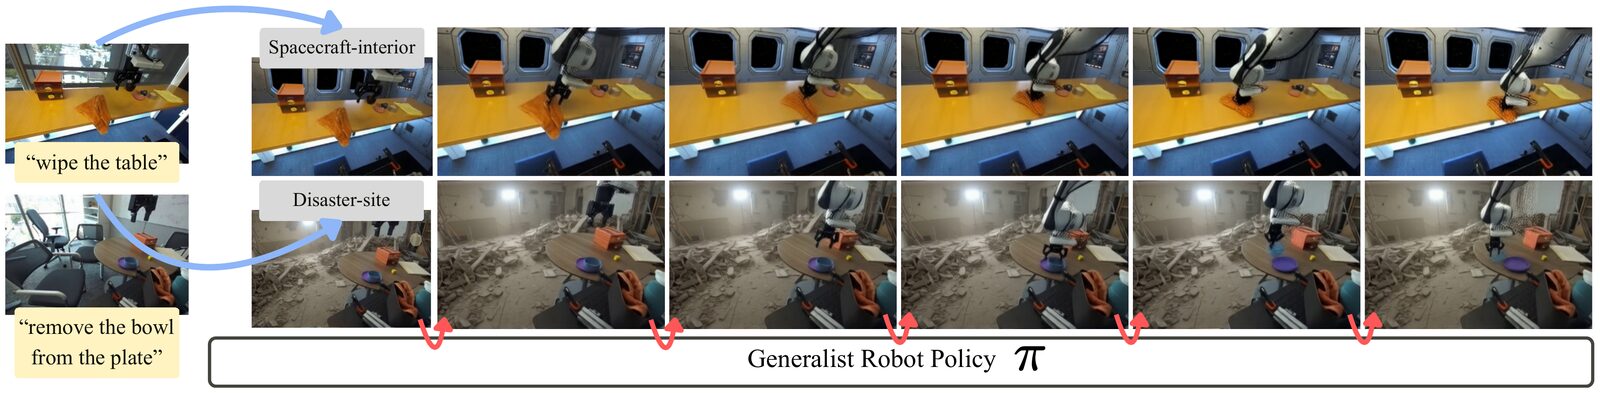
Robotic World Model trains a neural-network simulator for policy optimizationSource 5, and RWM-U adds epistemic uncertainty to train real quadruped and humanoid policies entirely offlineSource 25. RISE improves a VLA inside a video world model scored by a progress-value model, gaining 35 to 45 points on three real tasksSource 26.
Hybrids keep known physics and learn what it misses: TossingBot learns residuals on a physics-based throw and reached 500+ mean picks per hourSource 27, and ASAP fits a delta action model to real Unitree G1 dataSource 28. World models versus physics simulators compares the options.
Model-based learning pays off when real interaction is expensive
It fits when interaction is expensive, goals change faster than dynamics and planning fits the latency budget; it fits less well when observations omit contact state or resets are cheap. Plan only once predicted action rankings track real ones: in a 2026 agile-driving study, SAC won in simulation, yet "only TD-MPC2 consistently outperforms the MPPI baseline on the physical platform"Source 29.
Adrian Remonda, Nicklas Hansen, Xiaolong Wang and colleagues at Toyota Research Institute and UC San Diego (October 2026) pretrain a racing world model in simulation and correct its mismatch on the real carSource 32. On one track, with 44 minutes of real-car data, 1.13% of its buffer, all 8 runs succeeded, with a best sector time of 49.55 s against 52.47 s for an MPC reference; without the simulation priors, a real-data-only run was stopped for safetySource 32.
See also
- Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
- Offline Reinforcement Learning for Robotics
CQL and TD3+BC, and when behavior cloning is the stronger baseline.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
Linked from
- Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
- Offline Reinforcement Learning for Robotics
CQL and TD3+BC, and when behavior cloning is the stronger baseline.
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
- JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
References
Danijar Hafner, Timothy Lillicrap, Jimmy Ba, Mohammad Norouzi, ICLR 2020, 2019.
https://arxiv.org/abs/1912.01603
Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap, 2023.
https://arxiv.org/abs/2301.04104
Philipp Wu, Alejandro Escontrela, Danijar Hafner, Ken Goldberg, Pieter Abbeel, CoRL 2022.
https://arxiv.org/abs/2206.14176
Nicklas Hansen, Hao Su, Xiaolong Wang, ICLR 2024, 2023.
https://arxiv.org/abs/2310.16828
Chenhao Li, Andreas Krause, Marco Hutter, 2025.
https://arxiv.org/abs/2501.10100
Emanuel Todorov, Tom Erez, Yuval Tassa, IROS 2012.
https://doi.org/10.1109/IROS.2012.6386109
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Claudio Canales, Fang Nan, Marco Hutter, Javier Ruiz-del-Solar, 2026.
https://arxiv.org/abs/2609.31025
Nicklas Hansen, Iretiayo Akinola, Yijie Guo, Jie Xu, Bingjie Tang, Hao Su, and 4 more, IROS 2026.
https://arxiv.org/abs/2609.28258
Thomas M. Moerland, Joost Broekens, Aske Plaat, Catholijn M. Jonker, 2020.
https://arxiv.org/abs/2006.16712
Richard S. Sutton, Machine Learning Proceedings 1990.
https://doi.org/10.1016/B978-1-55860-141-3.50030-4
Nathan Lambert, Brandon Amos, Omry Yadan, Roberto Calandra, L4DC 2020.
https://arxiv.org/abs/2002.04523
Fangyuan Wang, Ziyuan Wang, Guorui Pei, Mengshi Zhang, Canxi Liang, Jun Hu, and 12 more, 2026.
https://arxiv.org/abs/2606.00113
Christopher Grimm, André Barreto, Satinder Singh, David Silver, NeurIPS 2020.
https://arxiv.org/abs/2011.03506
Chelsea Finn, Sergey Levine, ICRA 2017, 2016.
https://arxiv.org/abs/1610.00696
Danijar Hafner, Wilson Yan, Timothy Lillicrap, 2025.
https://arxiv.org/abs/2509.24527
Thanard Kurutach, Ignasi Clavera, Yan Duan, Aviv Tamar, Pieter Abbeel, 2018.
https://arxiv.org/abs/1802.10592
Kurtland Chua, Roberto Calandra, Rowan McAllister, Sergey Levine, NeurIPS 2018.
https://arxiv.org/abs/1805.12114
Michael Janner, Justin Fu, Marvin Zhang, Sergey Levine, NeurIPS 2019.
https://arxiv.org/abs/1906.08253
Tianhe Yu, Garrett Thomas, Lantao Yu, Stefano Ermon, James Zou, Sergey Levine, and 2 more, NeurIPS 2020.
https://arxiv.org/abs/2005.13239
Ryan Hoque, Daniel Seita, Ashwin Balakrishna, Aditya Ganapathi, Ajay Kumar Tanwani, Nawid Jamali, and 3 more, RSS 2020.
https://arxiv.org/abs/2003.09044
Nicklas Hansen, Xiaolong Wang, 2026.
https://arxiv.org/abs/2606.27326
Anusha Nagabandi, Kurt Konoglie, Sergey Levine, Vikash Kumar, 2019.
https://arxiv.org/abs/1909.11652
Jacob Levy, Tyler Westenbroek, David Fridovich-Keil, 2024.
https://arxiv.org/abs/2410.09163
Chenhao Li, Andreas Krause, Marco Hutter, 2025.
https://arxiv.org/abs/2504.16680
Jiazhi Yang, Kunyang Lin, Jinwei Li, Wencong Zhang, Tianwei Lin, Longyan Wu, and 7 more, RSS 2026.
https://arxiv.org/abs/2602.11075
Andy Zeng, Shuran Song, Johnny Lee, Alberto Rodriguez, Thomas Funkhouser, 2019.
https://arxiv.org/abs/1903.11239
Tairan He, Jiawei Gao, Wenli Xiao, Yuanhang Zhang, Zi Wang, Jiashun Wang, and 12 more, RSS 2025.
https://arxiv.org/abs/2502.01143
Kohei Honda, Hirotaka Hosogaya, 2026.
https://arxiv.org/abs/2604.07672v1
Wenlong Huang, Yu-Wei Chao, Arsalan Mousavian, Ming-Yu Liu, Dieter Fox, Kaichun Mo, and 1 more, 2026.
https://arxiv.org/abs/2601.03782
Chenyuan Zhou, Yining Hong, Huang Huang, Yunfan Jiang, Wenlong Huang, David Held, and 6 more, 2026.
https://arxiv.org/abs/2610.22364
Adrian Remonda, Jiajun Xi, Nicklas Hansen, Marcus Greiff, Thomas Lew, John Talbot, and 2 more, 2026.
https://arxiv.org/abs/2610.26757
Further reading
Nicklas Hansen, Xiaolong Wang, Hao Su, ICML 2022.
https://arxiv.org/abs/2203.04955
Nicklas Hansen, Hao Su, Xiaolong Wang, 2025.
https://arxiv.org/abs/2511.19584
Rahul Kidambi, Aravind Rajeswaran, Praneeth Netrapalli, Thorsten Joachims, NeurIPS 2020.
https://arxiv.org/abs/2005.05951
Marc Peter Deisenroth, Dieter Fox, Carl Edward Rasmussen, IEEE TPAMI 37(2), 2015.
https://arxiv.org/abs/1502.02860
Jacob Levy, Tyler Westenbroek, Kevin Huang, Fernando Palafox, Patrick Yin, Shayegan Omidshafiei, and 3 more, RSS 2026.
https://arxiv.org/abs/2603.15759
Spot a factual error or missing qualification? Report a content correction.