JEPA and the Non-Generative Counterargument
V-JEPA 2 and 2.1 predict in representation space, with no pixel decoder.
The Joint-Embedding Predictive Architecture (JEPA) is a world-model design that predicts the representation of the future instead of its pixels: an encoder and predictor learn to match the embedding a target encoder gives the true futureSource 2. It is the main non-generative alternative to generative world models.
Drag "Options tried each step" in the figure and the fan of tried moves follows it. "Plan next move" takes one more step. Planning in a frozen feature space works without reconstruction: DINO-WM solved six environments zero-shot without demonstrations, reward models or inverse modelsSource 11.
Planning by comparing summaries
Robot plans by steering its mental summary toward the goal
Adjust more
Goal picture
Each step: try 24 possible moves, keep the one closest to the goalmove 2 · 55% of the distance left · 24 tried
Illustrative: a toy model, not learned robot features.
How this was made
JEPA, short for joint-embedding predictive architecture, does not predict the next picture pixel by pixel. It turns each camera picture into a compact summary, a short list of numbers called a latent or embedding, and learns to predict how that summary changes when the robot acts. V-JEPA 2-AC plans this way: it compares the summary of what the camera sees now with the summary of a goal picture and picks the actions that shrink the difference.
No pixel decoder is used to select V-JEPA 2-AC control actions; this toy plans over synthetic two-dimensional points and loads no trained encoder or predictor. Each goal is a fixed point standing in for an encoded goal picture, and the table is the plane turned so the start-to-pick direction runs along it, which changes no distance.
On the planning table, the ring at the left is the summary of the picture the camera sees now and the target at the right is the summary of the goal picture; both pictures stand on the easels in front. The table is the toy plane at one uniform scale, so every distance on it keeps its proportion.
The probe head stands on the current summary and sets out one feeler for each move it tries, each ending on a pin. The lit pin sits exactly where the model predicts the kept move lands, closest to the target, and “Plan next move” carries the head along its feeler. Prick marks show where the head really ended up, and the dial on the controller reads the distance left.
The model’s other moves bunch into narrow wings, so for display their pins are spread evenly from 20 degrees past the kept move to 100 degrees either side of the goal direction. Each pin keeps its side, the common reach and its order, so the spread changes no pin’s rank and the lit one stays the closest.
Each planning step tries 24 moves, scores each by the straight-line distance from where it is predicted to land to the goal, d = √((x − xgoal)² + (y − ygoal)²), keeps the closest and carries it out. The real move lands slightly off the predicted one, by a fixed 5% of the distance left, so the robot plans again from where it actually is. The distance is now 0.443 after 2 planning steps, against 0.813 at the start.
With few options even the best one points well away from the goal, so the path zig-zags; with many it heads almost straight there. The toy prescribes this by construction, so it measures nothing about a real robot. The paper scores moves by the L1 distance between predicted and goal feature maps and searches with the Cross-Entropy Method, using 800 samples and ten refinement iterations a step (arXiv:2506.09985, Section 3.2).
With 24 options tried each step, the current latent sits 0.443 from the pick goal after 2 planning steps, 55% of the starting distance of 0.813; the plane shows the walked path and the fan of 24 tried moves, and the distance strip falls from 100% to 55%.
Current plan toward the goal
- options tried each step
- 24
- goal
- cup in hand
- moves made
- 2
- distance left
- 0.443 (55% of the start)
>1M
pretrain video
video hours; action-free
<62
robot video
Droid hours; state signals used
77.3%
SSv2 top-1
frozen encoder, motion benchmark
$1.03B
AMI raise
March 2026
Predicting embeddings skips detail that control does not need
A generative objective spends capacity on leaf texture and sensor noise that control does not need. In deep linear models, JEPA objectives are "biased to learn high-influence features"Source 12. In violation-of-expectation tests, predictors trained in a learned representation space showed object permanence and shape consistency, while pixel-space predictors and multimodal LLMs scored near chanceSource 13.
I-JEPA introduced the architecture as "a non-generative approach" that predicts the representations of target image blocks from a context blockSource 14. V-JEPA extended it to masked video, with no pixel reconstruction, negative examples, text or pretrained image encoderSource 1.
V-JEPA 2 adds robot control with under 62 hours of robot video
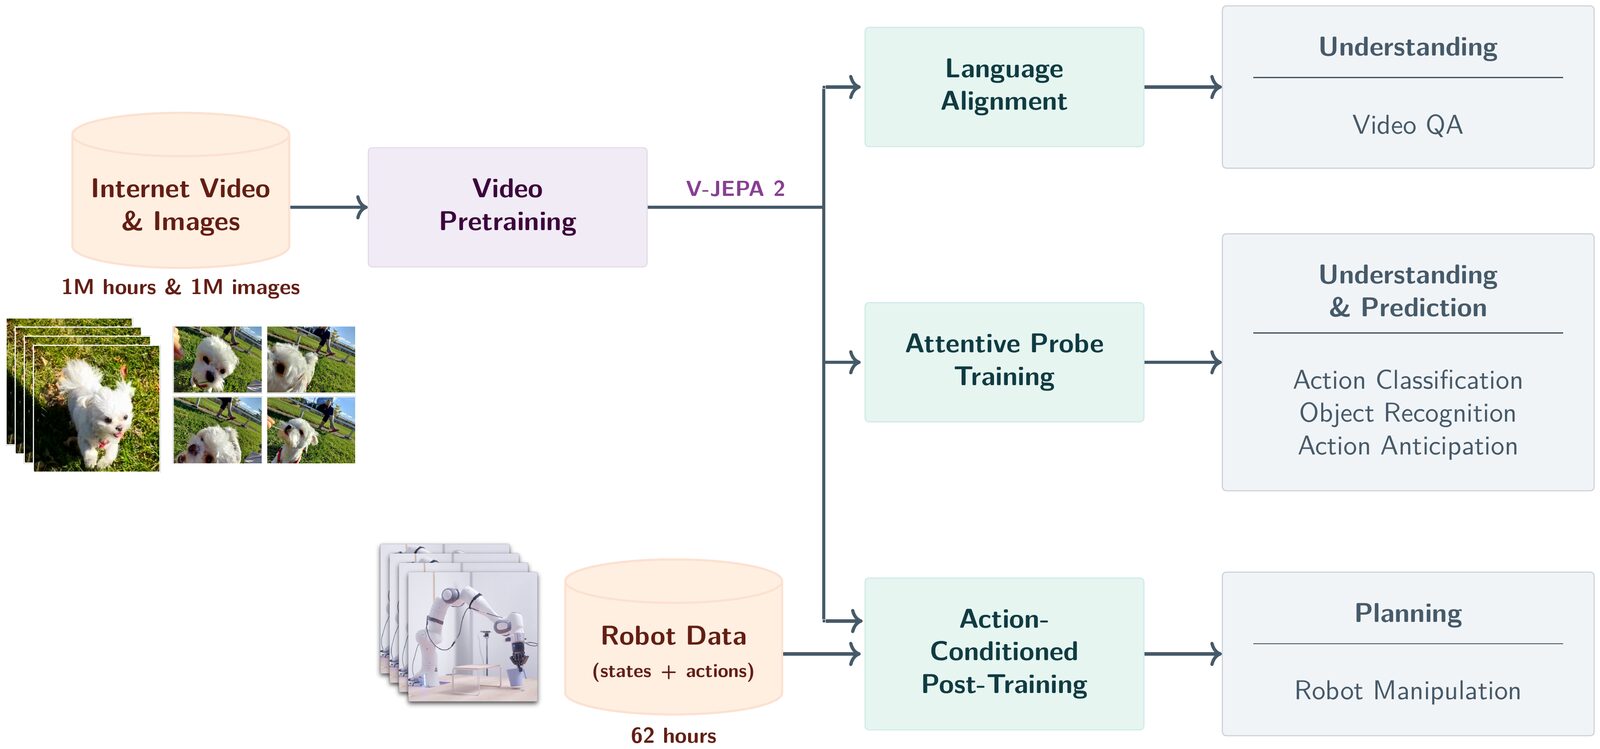
V-JEPA 2 first learns action-free representations by masked prediction on over 1 million hours of internet video plus images, with a 1B-parameter ViT-g encoder and a 22M pretraining predictor. A frozen ViT-g384 with a four-layer attentive probe reaches 77.3% top-1 accuracy on Something-Something-v2, using 64 frames, two temporal and three spatial crops and the best of 20 headsSource 2.
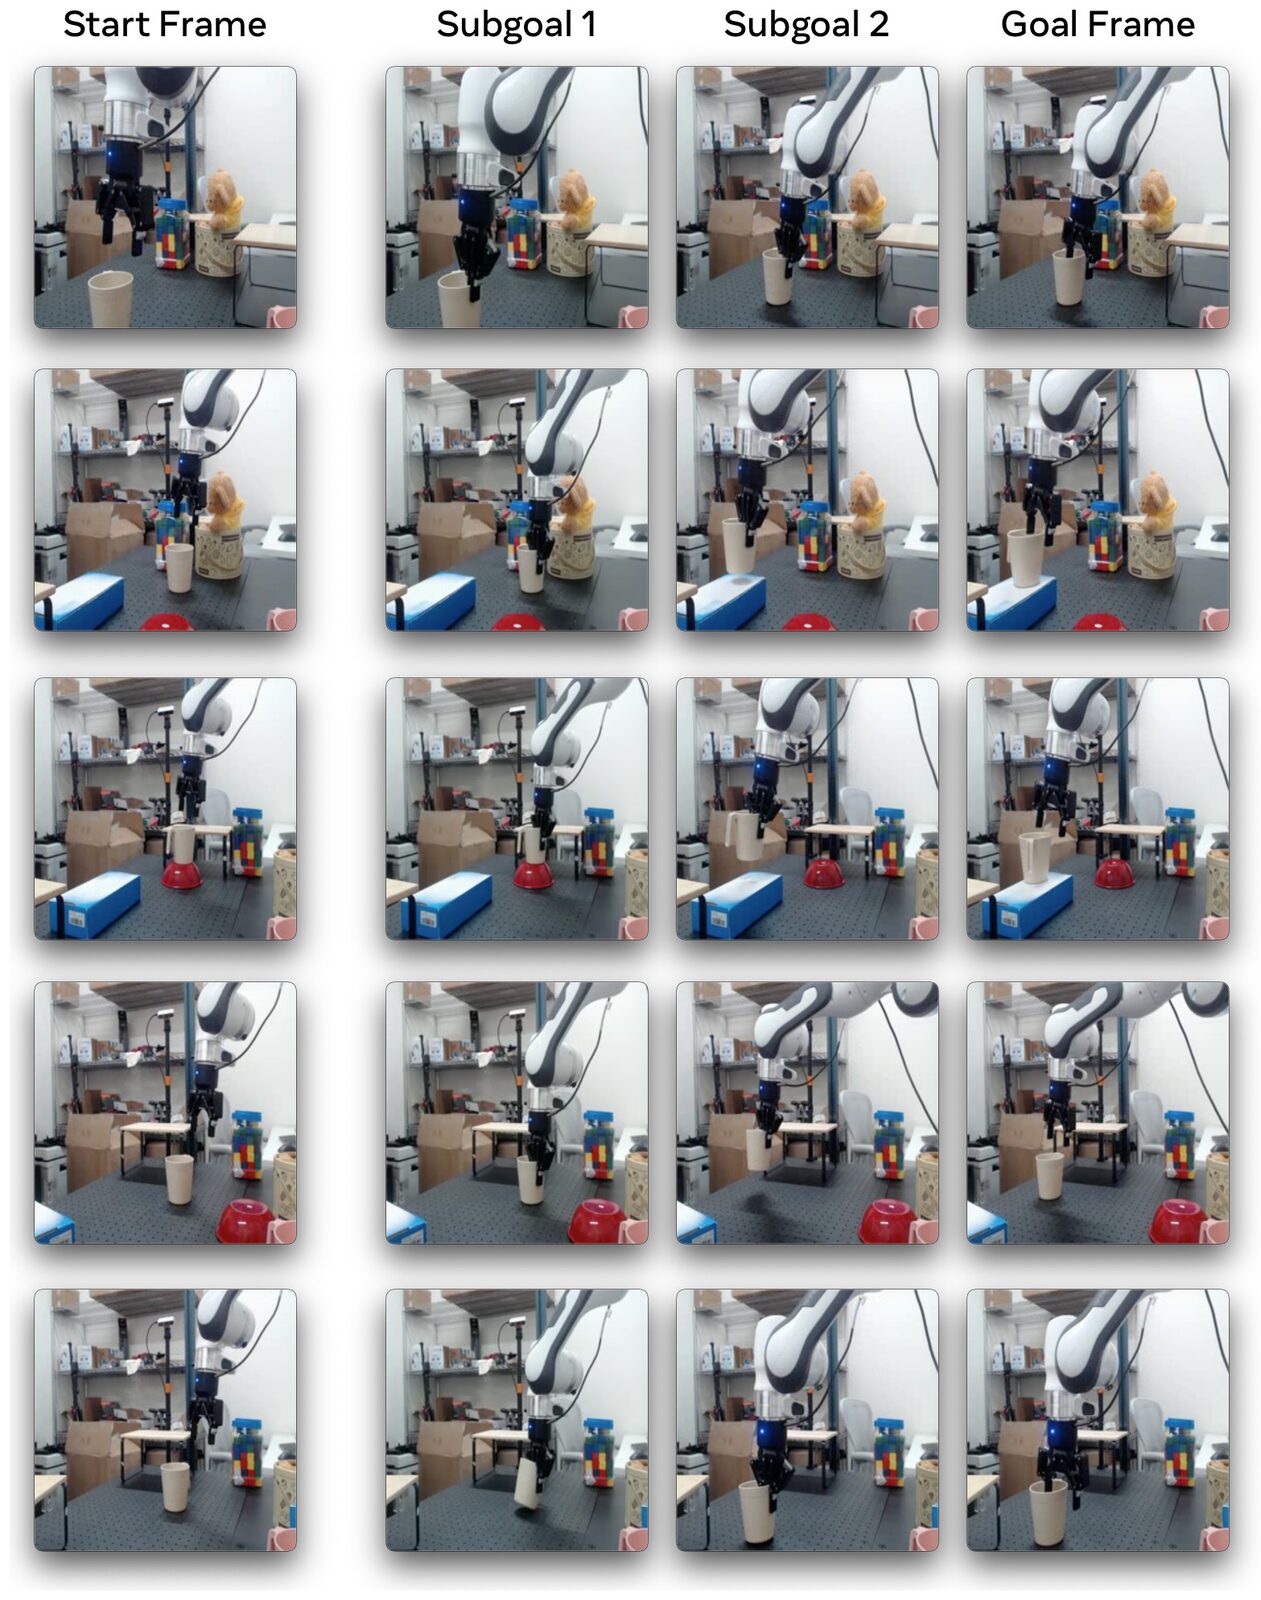
V-JEPA 2-AC then freezes the encoder and trains a roughly 300M-parameter action-conditioned predictor on less than 62 hours of Droid robot video. "Unlabeled" means no reward, task or success labels; actions are changes in end-effector position, orientation and gripper state. It ran zero-shot on Franka Emika Panda arms in two labs absent from Droid, though Droid itself is Franka teleoperation and the authors hand-picked camera positions. Its four tabletop tasks used image goals, with two subgoal images for pick-and-place, at ten trials per settingSource 2.
Latent planning works on tabletop picks, and successors improve it
Control is energy minimization in latent space. The Cross-Entropy Method searches 800 candidates over ten iterations at horizon one for actions whose predicted feature map is closest in L1 to the goal's, executes the first action and replans. This goal distance has no demonstrated calibration to a value function, and the pixel decoder trained for visualization plays no part in controlSource 2. Meta reports a 1.2B-parameter model with 65% to 80% pick-and-place success on new objects in unseen environments, given visual subgoalsSource 16.
V-JEPA 2.1 adds dense predictive losses and reports "a 20-point improvement in real-robot grasping success rate over V-JEPA-2 AC"Source 17. A Meta FAIR design study produced a JEPA world model that beats DINO-WM and V-JEPA-2-AC in navigation and manipulationSource 18.
LeCun's AMI Labs raised over a billion dollars for world models
LeCun left Meta and co-founded AMI Labs (Advanced Machine Intelligence), which raised $1.03 billion at a $3.5 billion pre-money valuation in March 2026 to build world modelsSource 3. LeCun is executive chairman and Alex LeBrun is CEOSource 20. LeBrun told TechCrunch that "'world models' will be the next buzzword": "In six months, every company will call itself a world model to raise funding."Source 3.
JEPA has no steerable simulator, and its latents are hard to validate
- Every currently usable interactive simulator is generative. Genie 3, Cosmos 3, Odyssey-2 and the Interactive World Simulator render pixels a user can inspect and steerSource 5 Source 6 Source 7 Source 8. No interactive, action-controllable JEPA environment has shipped.
- Latent-only objectives are hard to validate: without a decoder, a reader cannot see what the model believes. V-JEPA prevents collapse with an exponential-moving-average target encoder and stop-gradient, a design inherited from BYOLSource 15, and its authors state their adaptation of BYOL's justification as a hypothesisSource 1. LeJEPA removes those heuristics with "no stop-gradient, no teacher-student"Source 21, and Klindt and colleagues prove that it linearly recovers a world's latent variables under stated assumptionsSource 22. In complex scenes, most models still score at chance on IntPhys 2 while humans are near perfectSource 23.
Robot results do not yet separate the two camps
- V-JEPA 2-AC's reported robot tests are bounded tabletop skills. Reaching, grasping, reach-with-object and pick-and-place with supplied goals and subgoals do not establish contact-rich assembly, deformable manipulation or whole-body controlSource 2. SkyJEPA, a June 2026 preprint from Pratyaksh Rao, Yann LeCun, Giuseppe Loianno and colleagues, runs a JEPA-style latent dynamics model with sampling-based optimal control on a quadrotor's embedded hardware. It reports outdoor closed-loop flight with zero-shot sim-to-real transferSource 30.
- The camps post similar numbers. On LIBERO, latent world-model VLAs (VLA-JEPA 97.2, JEPA-VLA 96.4) sit beside video-based ones (Cosmos Policy and LingBot-VA 98.5, Say-Dream-ACT 98.1)Source 4. VLA-JEPA argues that pixel-anchored latent actions learn nuisance motionSource 24, and JEPA-VLA that V-JEPA 2 embeddings discard unpredictable factorsSource 25. On the harder LIBERO-Plus, Cosmos-Policy reaches 82.2%Source 26 and JEPA-WAM 79.2% without large-scale robot pretraining, or 86.3% as a π0.5 instantiationSource 27.
- Fast-WAM separates video co-training from test-time generation. It keeps a future-video training objective but at inference only encodes the current frame and runs action denoising on a chunk. On LIBERO and RoboTwin 2.0, removing video co-training hurt success more than removing explicit future generation. That leaves a general JEPA advantage unproven.Source 9
An interactive JEPA world or a contact-rich win would settle it
Either of two results would break the stalemate: a JEPA environment a user can steer the way Genie 3 is steered todaySource 5, or a JEPA advantage on contact-rich tasks, where both camps' evidence runs out. Until then the JEPA line has the cheapest demonstrated path from observation to zero-shot planningSource 19, and the generative video line has the only usable simulators.
In September 2026, Haoran Zhu, Wancong Zhang, Yann LeCun and Anna Choromanska tested JEPA world models as driving planners with no driving policy trained, using ground-truth future observations as goals. They report that earlier JEPA models were either accurate but slow or fast but too weak to plan. Their AD-E2E-JEPA projector gives a 100-fold inference speedup while keeping planning performance, rolling out 256 candidate trajectories over 8 frames in 0.8 secondsSource 10.
H-JEPA, from Yann LeCun (AMI Labs and NYU) and colleagues (October 2026), stacks action-conditioned JEPAs that each predict farther ahead and hand subgoals to the level below. On Visual AntMaze a three-level hierarchy raised success from 18% to 73% with less planner computeSource 29.
Leonardo Toso, Yann LeCun, James Anderson and Oumayma Bounou of Columbia, NYU and AMI Labs showed in October 2026 that next-step prediction with anti-collapse regularization can reach its minimum loss while discarding a system's controllable unstable modes. The learned state is then impossible to stabilize. They add an inverse-dynamics loss that reconstructs actions and prove, for linear systems, that exact reconstruction keeps every state direction reachable within the horizon. Experiments on CartPole, Walker2D and PointMaze from pixels extend the finding to nonlinear tasksSource 31.
Romina Yalovetzky, Randall Balestriero and Yann LeCun of NYU, Brown University and AMI Labs (October 2026) replace the JEPA predictor with an action-conditioned Hamiltonian flow whose leapfrog step preserves latent volume at every rollout stepSource 32. On a simulated pendulum seen only in pixels, LeHami has 2.8 times lower angular velocity error than LeWorldModel over the first ten rollout stepsSource 32. When a torque-driven pendulum must reach a goal angle and velocity, the best LeWorldModel variant still succeeds more often, 0.636 against 0.304 over three model seedsSource 32.
Use JEPA when reconstructing pixels adds no evidence
Use a JEPA-style model when the decision depends on task-relevant change and reconstructing pixels adds no evidence, as in goal-conditioned planning. Decoder-free latent planning already scales, with one 317M-parameter TD-MPC2 agent performing 80 tasksSource 28. Synthetic video, visual debugging and simulator replacement fit poorly, because the decoder-free state hides what it omitted. Test whether nearby embeddings mean equivalent outcomes and whether action rankings match hardware, and add out-of-distribution detectors or planner fallbacks, since embedding distance is uncalibrated confidence (see the model-based and evaluation guides).
See also
- Drones and Aerial Robotics
Autonomous flight, from state estimation to champion-level racing.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Perception for Manipulation
How camera images become an object's position and orientation.
Linked from
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
References
Adrien Bardes, Quentin Garrido, Jean Ponce, Xinlei Chen, Michael Rabbat, Yann LeCun, and 2 more, 2024.
https://arxiv.org/abs/2404.08471
Mahmoud Assran, Adrien Bardes, David Fan, Quentin Garrido, Russell Howes, Mojtaba Komeili, and 23 more, 2025.
https://arxiv.org/abs/2506.09985
Anna Heim, TechCrunch, 2026.
https://techcrunch.com/2026/03/09/yann-lecuns-ami-labs-raises-1-03-billion-to-build-world-models/
Bohan Hou, Gen Li, Jindou Jia, Tuo An, Xinying Guo, Sicong Leng, and 12 more, 2026.
https://arxiv.org/abs/2605.00080
Jack Parker-Holder, Shlomi Fruchter, Google DeepMind, 2025.
https://deepmind.google/blog/genie-3-a-new-frontier-for-world-models/
NVIDIA, Aditi, Niket Agarwal, Arslan Ali, Jon Allen, Martin Antolini, and 289 more, 2026.
https://research.nvidia.com/labs/cosmos-lab/cosmos3/technical-report.pdf
Oliver Cameron, Odyssey, 2025.
https://odyssey.ml/introducing-odyssey-2
Yixuan Wang, Rhythm Syed, Fangyu Wu, Mengchao Zhang, Aykut Onol, Jose Barreiros, and 4 more, 2026.
https://arxiv.org/abs/2603.08546
Tianyuan Yuan, Zibin Dong, Yicheng Liu, Hang Zhao, 2026.
https://arxiv.org/abs/2603.16666
Haoran Zhu, Wancong Zhang, Yann LeCun, Anna Choromanska, 2026.
https://arxiv.org/abs/2609.34085
Gaoyue Zhou, Hengkai Pan, Yann LeCun, Lerrel Pinto, 2024.
https://arxiv.org/abs/2411.04983
Etai Littwin, Omid Saremi, Madhu Advani, Vimal Thilak, Preetum Nakkiran, Chen Huang, and 1 more, 2024.
https://arxiv.org/abs/2407.03475
Quentin Garrido, Nicolas Ballas, Mahmoud Assran, Adrien Bardes, Laurent Najman, Michael Rabbat, and 2 more, 2025.
https://arxiv.org/abs/2502.11831
Mahmoud Assran, Quentin Duval, Ishan Misra, Piotr Bojanowski, Pascal Vincent, Michael Rabbat, and 2 more, ICCV 2023.
https://arxiv.org/abs/2301.08243
Jean-Bastien Grill, Florian Strub, Florent Altché, Corentin Tallec, Pierre H. Richemond, Elena Buchatskaya, and 8 more, 2020.
https://arxiv.org/abs/2006.07733
Meta AI, Meta AI Blog, 2025.
https://ai.meta.com/blog/v-jepa-2-world-model-benchmarks/
Lorenzo Mur-Labadia, Matthew Muckley, Amir Bar, Mido Assran, Koustuv Sinha, Mike Rabbat, and 3 more, 2026.
https://arxiv.org/abs/2603.14482
Basile Terver, Tsung-Yen Yang, Jean Ponce, Adrien Bardes, Yann LeCun, 2025.
https://arxiv.org/abs/2512.24497
Lucas Maes, Quentin Le Lidec, Damien Scieur, Yann LeCun, Randall Balestriero, 2026.
https://arxiv.org/abs/2603.19312
Julie Bort, TechCrunch, 2025.
https://techcrunch.com/2025/12/19/yann-lecun-confirms-his-new-world-model-startup-reportedly-seeks-5b-valuation/
Randall Balestriero, Yann LeCun, 2025.
https://arxiv.org/abs/2511.08544
David Klindt, Yann LeCun, Randall Balestriero, 2026.
https://arxiv.org/abs/2605.26379
Florian Bordes, Quentin Garrido, Justine T Kao, Adina Williams, Michael Rabbat, Emmanuel Dupoux, 2025.
https://arxiv.org/abs/2506.09849
Jingwen Sun, Wenyao Zhang, Zekun Qi, Shaojie Ren, Zezhi Liu, Hanxin Zhu, and 3 more, 2026.
https://arxiv.org/abs/2602.10098
Shangchen Miao, Ningya Feng, Jialong Wu, Ye Lin, Xu He, Dong Li, and 1 more, 2026.
https://arxiv.org/abs/2602.11832
Zhanguang Zhang, Zhiyuan Li, Behnam Rahmati, Rui Heng Yang, Yintao Ma, Amir Rasouli, and 8 more, 2026.
https://arxiv.org/abs/2603.22078
Yihan Lin, Jiawei He, Shifeng Bao, Chen Zhao, Yang Li, Xiaobo Wang, and 3 more, 2026.
https://arxiv.org/abs/2608.09381
Nicklas Hansen, Hao Su, Xiaolong Wang, ICLR 2024, 2023.
https://arxiv.org/abs/2310.16828
Wancong Zhang, Basile Terver, Michael Rabbat, Yann LeCun, Randall Balestriero, 2026.
https://arxiv.org/abs/2610.06805
Pratyaksh Rao, Wancong Zhang, Randall Balestriero, Yann LeCun, Giuseppe Loianno, 2026.
https://arxiv.org/abs/2606.23444
Leonardo F. Toso, Yann LeCun, James Anderson, Oumayma Bounou, 2026.
https://arxiv.org/abs/2610.07540
Romina Yalovetzky, Randall Balestriero, Yann LeCun, 2026.
https://arxiv.org/abs/2610.15267
Further reading
Julian Schrittwieser, Ioannis Antonoglou, Thomas Hubert, Karen Simonyan, Laurent Sifre, Simon Schmitt, and 6 more, 2019.
https://arxiv.org/abs/1911.08265
Advanced Machine Intelligence (AMI Labs), AMI Labs, 2026.
https://amilabs.xyz/updates
Shenyuan Gao, William Liang, Kaiyuan Zheng, Ayaan Malik, Seonghyeon Ye, Sihyun Yu, and 24 more, 2026.
https://arxiv.org/abs/2602.06949
Danijar Hafner, Wilson Yan, Timothy Lillicrap, 2025.
https://arxiv.org/abs/2509.24527
Lukas Kuhn, Lucas Maes, Giuseppe Serra, Quentin Le Lidec, Yann LeCun, Randall Balestriero, and 1 more, 2026.
https://arxiv.org/abs/2608.27395
Spot a factual error or missing qualification? Report a content correction.