Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
Latent dynamics is the world-model paradigm that learns a compact recurrent state, predicts how it and the reward evolve under actions, and trains or plans inside that imaginationSource 1. It is the oldest of the six paradigms in the taxonomy: Embed to Control learned locally linear latent dynamics from raw images in 2015Source 9.
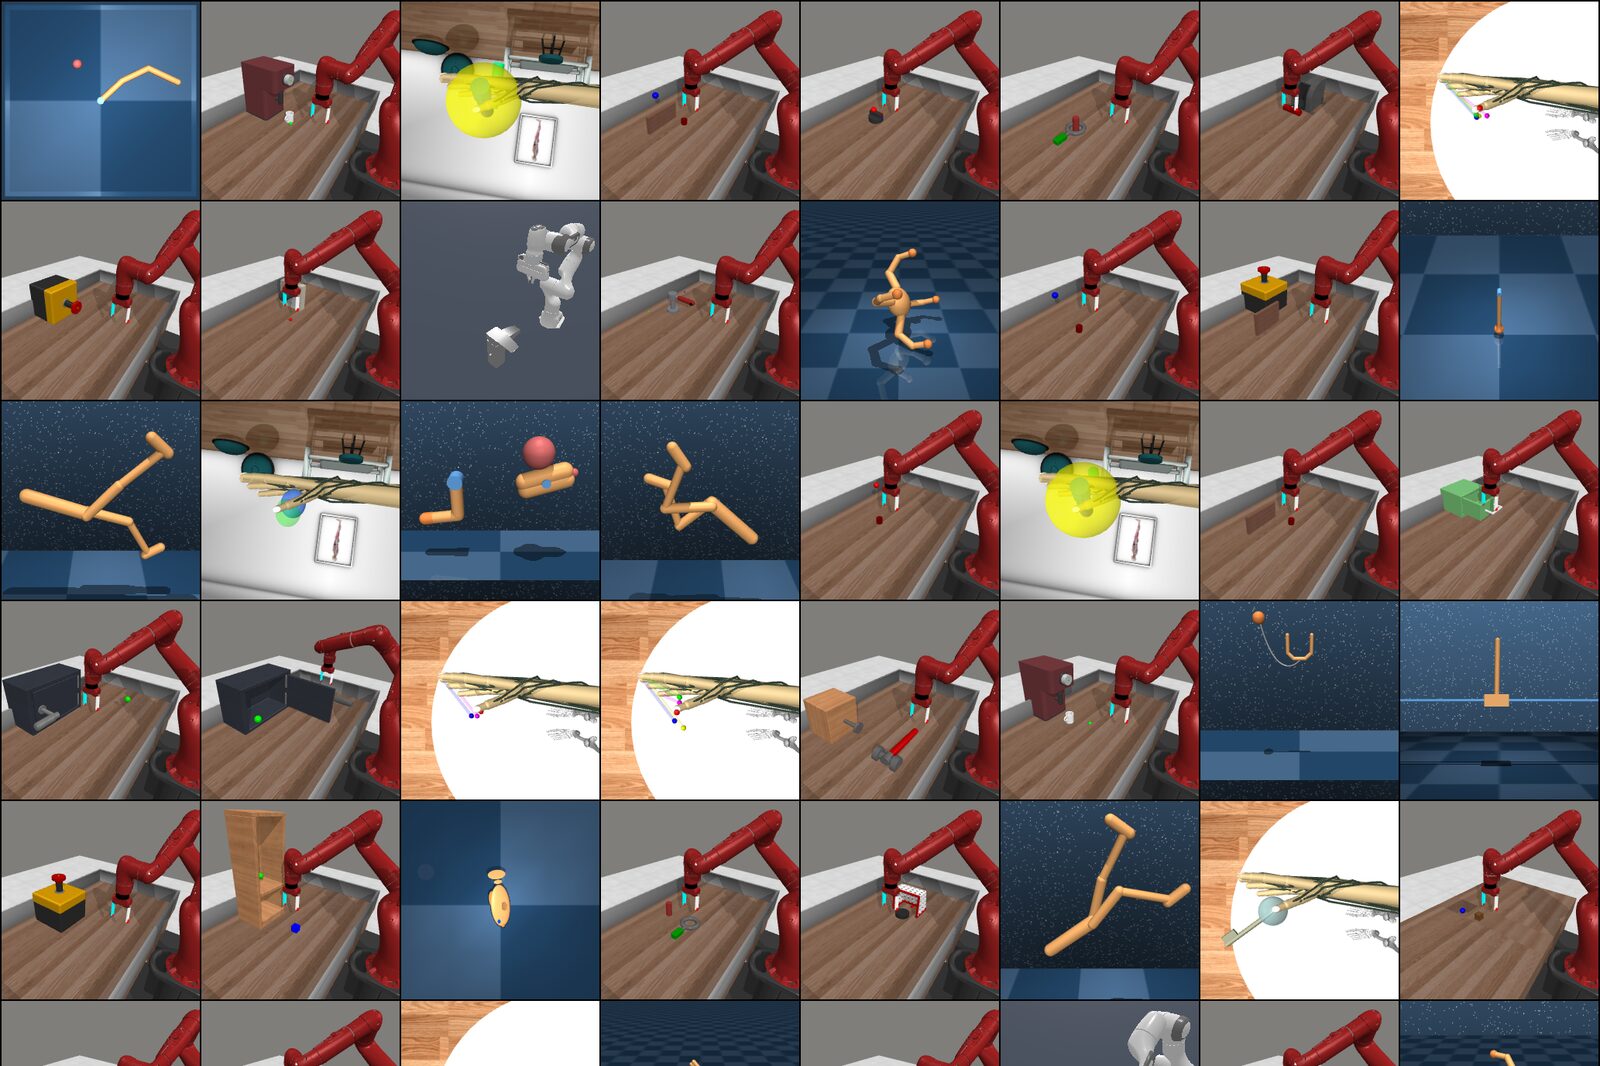
Drag "How far ahead to imagine" in the figure and the imagined throw peels away from the real one. In measured models, compounding error is shaped most by the system's own dynamicsSource 10.
Planning in imagination
Imagine further ahead and small mistakes snowball
Adjust more
Which model?
15 steps ahead: already this far off15 steps ahead · 0.301 off the route
Illustrative: a toy model, not measured on a real robot.
How this was made
The robot plans by imagining its future one step at a time, and each imagined step starts from the last imagined one, not from the real state. On the bench each imagined step is one section of track, bolted to the end of the section before it, and the curved steel template with a station post every five steps is the real route. A small error at one joint is carried into every later section and grows. The bench lays as many sections as the first slider says; the knob on the controller turns with the second.
The drift is a toy recurrence, not a measured model: each step adds the one-step error, scaled up by how far the imagined state has already drifted, d(t) = d(t − 1) + e × (1 + 0.02 × d(t − 1)). At 2.0% error per step and 15 steps it reaches 0.301 units of toy latent deviation. The bench draws each unit as the same inward step off the template, read on the radius arm, and stops the track at the hub’s flange; the number keeps growing.
Dreamer learns with a decoder that turns imagined states back into pictures, drawn here as picture cards on flags along the track. TD-MPC2 has no decoder: it never draws a picture, and its drift shows up as error in the reward it predicts (“Adjust more” switches between the two). TD-MPC and TD-MPC2 are also trained to keep imagined and encoded states consistent, so a single toy number is not a complete account of either training loss.
In the chart below, the shaded band from 3 to 15 steps is a teaching choice, not a published range, a confidence interval or a reliability bound; the article discusses the horizons the papers use.
In this deterministic toy, latent deviation grows from 0 at step 0 to 0.301 units at the current 15-step horizon under the 2.0% one-step-error input. The shaded band is illustrative, from 3 to 15 steps; it is not a published range, confidence interval, or reliability bound.
Sampled latent deviation by imagination step
| step | deviation | range | playhead |
|---|---|---|---|
| 0 | 0.000 | before illustrative band | off |
| 10 | 0.200 | inside illustrative band | off |
| 15 | 0.301 | inside illustrative band | playhead |
| 20 | 0.402 | past illustrative band | off |
| 30 | 0.603 | past illustrative band | off |
| 40 | 0.806 | past illustrative band | off |
| 50 | 1.01 | past illustrative band | off |
In this toy, the head of the track the robot imagines 15 steps ahead, at 2.0% off per step, is 0.301 units of toy deviation off the real route; each imagined section is bolted to the last imagined one, so the gap grows with every step of the 50-step range.
Current imagined track
- how far ahead
- 15 steps
- error per step
- 2.0%
- how far off
- 0.301
- model
- Dreamer (draws pictures)
150+
DreamerV3 tasks
one fixed hyperparameter set
317M
TD-MPC2 agent
one offline agent, 80 tasks
~1 h
DayDreamer A1
one real-world training run
15-16
DreamerV3 horizon
imagined steps ahead
Agents trained inside a recurrent latent model reached human-level Atari
Ha and Schmidhuber trained an agent "entirely inside of its own hallucinated dream" and transferred it back to the real environmentSource 11. PlaNet planned from pixels with deterministic and stochastic latent transitionsSource 12. DreamerV3's Recurrent State-Space Model (RSSM) pairs a recurrent state that carries memory with a stochastic categorical representation, and learns to reconstruct inputs and predict reward and continuationSource 2.
Dreamer's actor and critic are trained purely on imagined latent rollouts from real encoded states, backpropagating value gradients through the modelSource 1. DreamerV2, which added discrete latents, was the first agent to reach human-level performance on the 55-task Atari benchmark by learning inside a separately trained world modelSource 13.
DreamerV3: one recipe across 150 tasks
DreamerV3 was evaluated on more than 150 tasks across eight domains with fixed hyperparameters. It uses symlog transforms for vector observations, free bits with KL balancing and percentile-based return normalizationSource 2. In the 2025 Nature article its authors call it, to their knowledge, the first algorithm to collect diamonds in Minecraft from scratch without human data or adaptive curriculaSource 14. Its MineRL-based task used abstract crafting actions, accelerated block breaking and sparse intermediate rewards for 12 milestones from log to diamondSource 2.
DreamerV3 learned online; in 2025 Dreamer 4 became "the first agent to obtain diamonds in Minecraft purely from offline data", with a world model that runs in real time on a single GPUSource 15.
TD-MPC2 drops the decoder and plans at every step
MuZero planned with a model predicting only "the reward, the action-selection policy, and the value function"Source 16, and value-equivalence theory holds that capacity is "better used to build models that are directly useful for value-based planning"Source 17. TD-MPC trains reward, TD value and latent-state consistency predictions without reconstructing observations, and at each step runs short-horizon MPPI with a learned terminal valueSource 3. TD-MPC2 keeps this planner, adds candidate sequences from a policy prior and warm-starts from the previous solution.Source 4
The multitask experiment trained one 317M-parameter agent on 545M transitions from 240 single-task agents. This offline 80-task experiment is separate from the 104-task online benchmark, and aggregate normalized scores rose across five model sizesSource 4. MuDreamer replaced Dreamer's reconstruction with value and action predictionSource 18.
DayDreamer taught a real quadruped to walk in about an hour
DayDreamer builds on DreamerV2 and learns online without a simulator on four robots with shared hyperparameters. After about one hour of real training, a Unitree A1 learned to roll off its back, stand and walk, with manual repositioning at the area boundary that left its joints and orientation unchanged. SAC learned to roll over but neither stood nor walked within that budgetSource 5.
Latent models imagine only 3 to 16 steps ahead
The 2023 DreamerV3 preprint lists imagination horizon H = 15 in a table and prediction horizon T = 16 in its actor-critic section, the 2024 revision keeps both labels, and the 2025 Nature article uses T = 16Source 2 Source 14. TD-MPC2 plans with H = 3 and bootstraps beyond it with a terminal valueSource 4. DayDreamer states H = 16 in its methods and H = 15 in its appendixSource 5.
MBPO keeps model rollouts short and "branched from real data"Source 19, and STEVE varies the horizon per example to limit model errorSource 20. HWM, with world models at several time scales in one latent space, lifted real Franka pick-and-place from 0% to 70%Source 21. A 350M-parameter model trained on 427 hours across 210 tasks still showed perceptual, action-marginalized and scene-diverging hallucinationsSource 22.
Simulation-trained world models now transfer to real legged robots
Robotic World Model (RWM) predicts observations over long horizons under partial observability with a GRU that feeds its predictions back in. Policies trained with MBPO-PPO in simulation showed zero-shot transfer to ANYmal D and Unitree G1, including under external disturbances; safe online hardware learning remains openSource 6. RWM-U adds uncertainty and trains policies "entirely from offline datasets" for a real quadruped and humanoidSource 23. SimDist pretrains in simulation and on hardware updates only the latent dynamics; on contact-rich manipulation and quadruped locomotion it kept improving where prior adaptation methods stalled or degradedSource 29.
Refinements to latent planning bring uneven gains
Dream-MPC refines policy-proposed action sequences by gradient ascent on predicted return, with an uncertainty penalty. Used in place of MPPI in pretrained TD-MPC2 and BMPC on 24 simulated tasks, over three seeds and ten episodes, the BMPC variant raises interquartile mean by 26.7% and mean by 20.5%. The TD-MPC2 variant beats its policy alone but does not consistently match MPPISource 7. BMPC learns its policy by imitating the MPC plannerSource 24, and HumanoidBench, one of the three task suites, poses whole-body humanoid tasksSource 25.
TD-M(PC)² found that planner-generated data causes "persistent value overestimation" and fixed it with a policy constraint, gaining most on 61-DoF humanoidsSource 26. Fast-WAM, a video world-action model, keeps video co-training but encodes the current frame once and runs action denoising on a chunk, with success similar to its imagine-then-execute variants on LIBERO and RoboTwin 2.0. On Galaxea R1 Lite towel folding it reports 190 ms inference latency against 810 ms for Fast-WAM-IDM on one RTX 5090D V2 32GB GPUSource 8.
TD-MPC2's authors expect broad generalization to need far more tasks
TD-MPC2's authors expect broad generalization, such as transfer to new embodiments, "will likely require several orders of magnitude more tasks"Source 4. In November 2025 the same group's Newt trained one language-conditioned world model jointly across 200 tasksSource 27. In simulation, one world model trained on up to 90 insertion tasks reached 56% zero-shot success on unseen parts, against 7% for a model-free baselineSource 30. DayDreamer's authors report that long hardware training causes wear needing human intervention or repairSource 5.
Imagination tolerates slow models; online planning needs predictable latency
Imagination-only training, as in Dreamer, tolerates slow generation but can bias the policy silently. Online planning, as in TD-MPC2, needs predictable latency and a fallback, and a planner that never changes its policy prior's proposal pays model cost for nothing. A latent model can also supply a representation: a simulation-trained world model predicted real legged-locomotion trajectories well enough to inform a separate controllerSource 28. See the model-based and evaluation guides.
See also
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
Linked from
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- State Estimation
Kalman filters, factor graphs, and pose estimation from noisy sensors.
References
Danijar Hafner, Timothy Lillicrap, Jimmy Ba, Mohammad Norouzi, ICLR 2020, 2019.
https://arxiv.org/abs/1912.01603
Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap, 2023.
https://arxiv.org/abs/2301.04104
Nicklas Hansen, Xiaolong Wang, Hao Su, ICML 2022.
https://arxiv.org/abs/2203.04955
Nicklas Hansen, Hao Su, Xiaolong Wang, ICLR 2024, 2023.
https://arxiv.org/abs/2310.16828
Philipp Wu, Alejandro Escontrela, Danijar Hafner, Ken Goldberg, Pieter Abbeel, CoRL 2022.
https://arxiv.org/abs/2206.14176
Chenhao Li, Andreas Krause, Marco Hutter, 2025.
https://arxiv.org/abs/2501.10100
Jonathan Spieler, Sven Behnke, ICML 2026.
https://arxiv.org/abs/2605.04568
Tianyuan Yuan, Zibin Dong, Yicheng Liu, Hang Zhao, 2026.
https://arxiv.org/abs/2603.16666
Manuel Watter, Jost Tobias Springenberg, Joschka Boedecker, Martin Riedmiller, NIPS 2015.
https://arxiv.org/abs/1506.07365
Nathan Lambert, Kristofer Pister, Roberto Calandra, 2022.
https://arxiv.org/abs/2203.09637
Danijar Hafner, Timothy Lillicrap, Ian Fischer, Ruben Villegas, David Ha, Honglak Lee, and 1 more, 2018.
https://arxiv.org/abs/1811.04551
Danijar Hafner, Timothy Lillicrap, Mohammad Norouzi, Jimmy Ba, ICLR 2021, 2020.
https://arxiv.org/abs/2010.02193
Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap, Nature 640, 647-653, 2025.
https://doi.org/10.1038/s41586-025-08744-2
Danijar Hafner, Wilson Yan, Timothy Lillicrap, 2025.
https://arxiv.org/abs/2509.24527
Julian Schrittwieser, Ioannis Antonoglou, Thomas Hubert, Karen Simonyan, Laurent Sifre, Simon Schmitt, and 6 more, 2019.
https://arxiv.org/abs/1911.08265
Christopher Grimm, André Barreto, Satinder Singh, David Silver, NeurIPS 2020.
https://arxiv.org/abs/2011.03506
Maxime Burchi, Radu Timofte, 2024.
https://arxiv.org/abs/2405.15083
Michael Janner, Justin Fu, Marvin Zhang, Sergey Levine, NeurIPS 2019.
https://arxiv.org/abs/1906.08253
Jacob Buckman, Danijar Hafner, George Tucker, Eugene Brevdo, Honglak Lee, 2018.
https://arxiv.org/abs/1807.01675
Wancong Zhang, Basile Terver, Artem Zholus, Soham Chitnis, Harsh Sutaria, Mido Assran, and 5 more, 2026.
https://arxiv.org/abs/2604.03208
Nicklas Hansen, Xiaolong Wang, 2026.
https://arxiv.org/abs/2606.27326
Chenhao Li, Andreas Krause, Marco Hutter, 2025.
https://arxiv.org/abs/2504.16680
Yuhang Wang, Hanwei Guo, Sizhe Wang, Long Qian, Xuguang Lan, ICLR 2025.
https://arxiv.org/abs/2503.18871
Carmelo Sferrazza, Dun-Ming Huang, Xingyu Lin, Youngwoon Lee, Pieter Abbeel, 2024.
https://arxiv.org/abs/2403.10506
Haotian Lin, Pengcheng Wang, Jeff Schneider, Guanya Shi, 2025.
https://arxiv.org/abs/2502.03550
Nicklas Hansen, Hao Su, Xiaolong Wang, 2025.
https://arxiv.org/abs/2511.19584
Hang Lai, Jiahang Cao, Jiafeng Xu, Hongtao Wu, Yunfeng Lin, Tao Kong, and 2 more, 2024.
https://arxiv.org/abs/2409.16784
Jacob Levy, Tyler Westenbroek, Kevin Huang, Fernando Palafox, Patrick Yin, Shayegan Omidshafiei, and 3 more, RSS 2026.
https://arxiv.org/abs/2603.15759
Nicklas Hansen, Iretiayo Akinola, Yijie Guo, Jie Xu, Bingjie Tang, Hao Su, and 4 more, IROS 2026.
https://arxiv.org/abs/2609.28258
Further reading
Younggyo Seo, Danijar Hafner, Hao Liu, Fangchen Liu, Stephen James, Kimin Lee, and 1 more, CoRL 2022.
https://arxiv.org/abs/2206.14244
Kohei Honda, Hirotaka Hosogaya, 2026.
https://arxiv.org/abs/2604.07672v1
Nicklas Hansen, Jyothir S V, Vlad Sobal, Yann LeCun, Xiaolong Wang, Hao Su, 2024.
https://arxiv.org/abs/2405.18418
Spot a factual error or missing qualification? Report a content correction.