State Estimation
Kalman filters, factor graphs, and pose estimation from noisy sensors.
State estimation computes a robot's state, such as its configuration or velocity over ground, from noisy, biased and intermittent sensor readings, and planning and control assume that state is known. Probabilistic estimators report a belief, so each estimate carries its uncertaintySource 3.
Kalman filter
Blend a guess and a noisy reading: sharper than either
Adjust more
the cart’s guessthe sensor’s readingthe blendits share of the way to the reading
beat 5 / 5 Jaws either side: guess 1.27 · reading 1.00 · blend 0.79
Illustrative: one step of a simulated robot, drawn to scale.
A robot never knows exactly where it is, so it keeps mixing its own prediction with each new sensor reading.
How this was made
In symbols, the update is : the new estimate (the posterior) is the predicted estimate plus the gain K times the gap between the reading z and the predicted position.
Here the gain is 0.62, the reading is 0.82, the predicted position 0.03 and the blend 0.52, so 0.52 = 0.03 + 0.62 × (0.82 − 0.03). The spread of the position estimate (one standard deviation) goes from 0.94 to 1.27 in the predict step and to 0.79 after the update; the reading’s spread is 1.00.
The drawing is an estimating rail. The cart tows the guess’s caliper while its odometer counts the roll, a rangefinder drives the reading’s caliper, and the blend’s caliper runs along a share rule from the guess to the reading. Each caliper’s jaws stand one spread either side of its estimate, so closer jaws mean surer. The numbers are step 41 of the seeded constant-velocity filter (seed 1, process noise 0.20, reading noise 1.00, beliefs matched to the world), drawn to scale. The drawing shows position only; the filter also tracks velocity. The rail is an illustration.
The steps, in order:
- Guess: from where it was and how fast it was going, the robot predicts where it is now, and the guess spreads out.
- Measure: a sensor also reports the position, but it is noisy, so the reading could be off in either direction.
- Blend: the robot mixes guess and reading, trusting the less spread-out one more, and the blend is narrower than either.
- The same step in numbers, then in symbols: the blend is the guess plus a share K of the gap to the reading z.
- A robot never knows exactly where it is, so it keeps mixing its own prediction with each new sensor reading.
Kalman filter: guess, measure, blend. A five-beat scene: a cart on a track and three calipers whose jaws stand one spread either side of where the cart might be. Beat 1: Guess: from where it was and how fast it was going, the robot predicts where it is now, and the guess spreads out. Beat 2: Measure: a sensor also reports the position, but it is noisy, so the reading could be off in either direction. Beat 3: Blend: the robot mixes guess and reading, trusting the less spread-out one more, and the blend is narrower than either. Beat 4: The same step in numbers, then in symbols: the blend is the guess plus a share K of the gap to the reading z. Beat 5: A robot never knows exactly where it is, so it keeps mixing its own prediction with each new sensor reading. In filter terms, the posterior position equals the predicted position plus gain K (0.62) times the gap between reading z (0.82) and the predicted position (0.03). The spread of the position estimate goes from 0.94 to 1.27 in the predict step and to 0.79 after the update.
1960
Kalman filter
Kalman's recursive linear estimator
1960s
EKF
Ames nonlinear navigation studies
2001
factor graphs
Kschischang, Frey, Loeliger unify the algebra
2012
iSAM2
incremental smoothing on the Bayes tree
The Bayes filter
A belief is a probability distribution over the state, kept current by two alternating steps. The predict step pushes the belief through the process model, given the control Source 3:
The update step folds in the measurement through the sensor model and sharpens the belief where the measurement pointsSource 3:
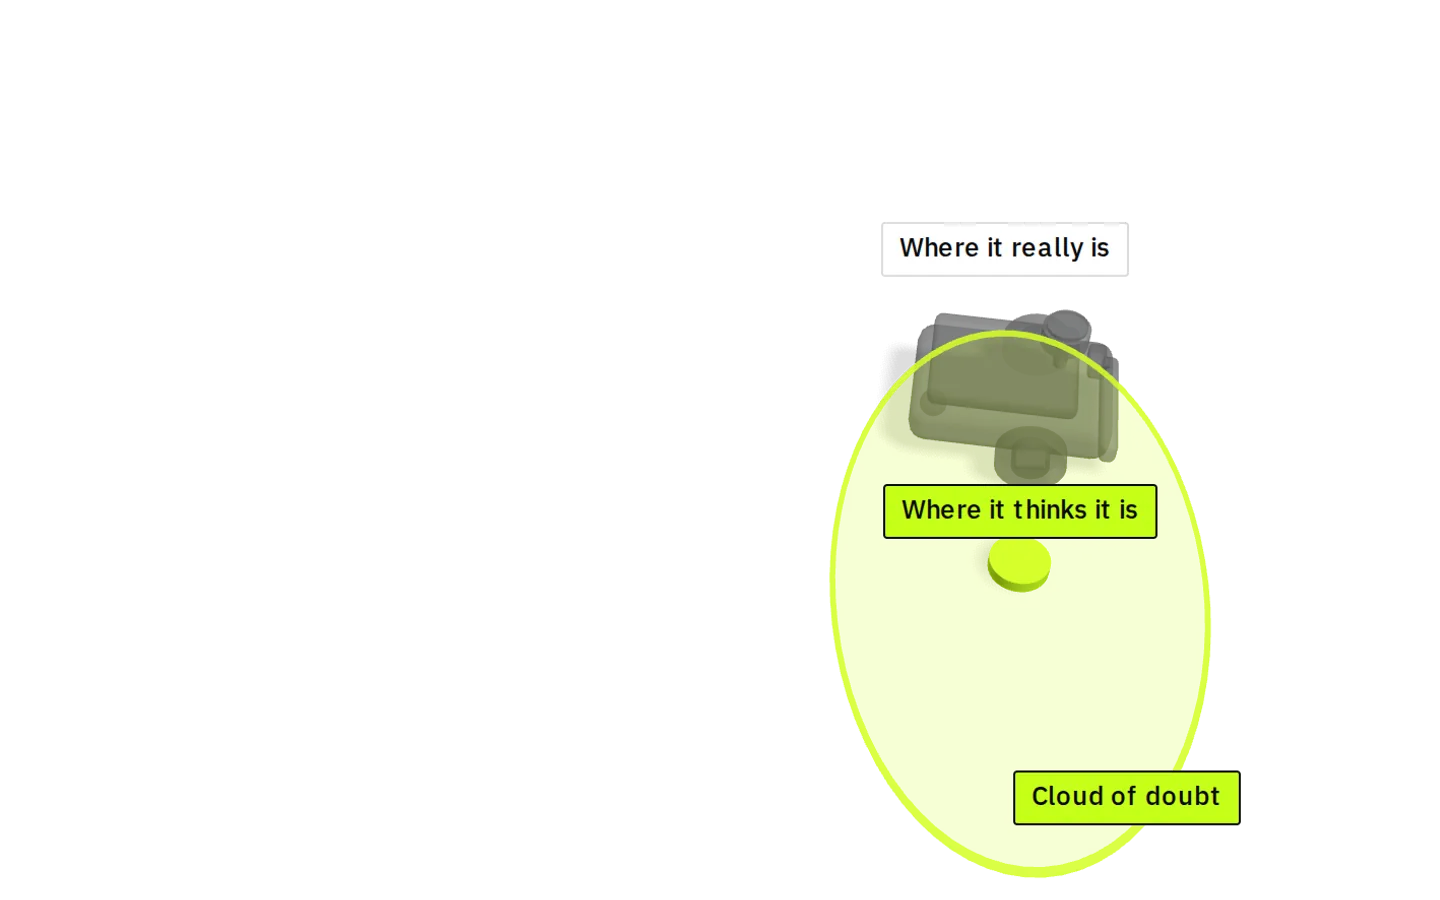
with normalizer . This recursion is the Bayes filter, which Thrun, Burgard and Fox call the basis of virtually every technique in their book, and each tractable filter adds assumptions or approximations that make the integral computableSource 3. The bootstrap filter of Gordon, Salmond and Smith drops the linearity and Gaussian-noise assumptions and applies to any state transition or measurement modelSource 13. Drive the robot in the figure below: its cloud of doubt grows as it moves and shrinks when it spots a landmark.
Does a robot know where it is?
Loading…
It drives by counting wheel turns. Each turn adds a little error, so its guess slips further off and its cloud of doubt grows.
A robot never knows exactly where it is: moving makes it less sure and each landmark it sees makes it surer.
How this was made
The steps in words
- It drives by counting wheel turns. Each turn adds a little error, so its guess slips further off and its cloud of doubt grows.
- Now its camera spots a landmark: a sign it already knows, at a known place on its map.
- A poorer camera shrinks the cloud less. The robot blends its own guess with the landmark's, trusting whichever has less doubt.
- This blending is a Kalman filter. Spacecraft, drones and many robots use one to keep track of where they are.
The Kalman filter
The 1960 Kalman filter reduces the recursion to matrix algebra by assuming linear process and measurement models and Gaussian noiseSource 1:
with and ; Probabilistic Robotics swaps the two symbols. A Gaussian belief then stays Gaussian, so the recursion tracks only a mean and covariance. PredictSource 3:
Update, through the Kalman gain Source 3:
The gain is prior uncertainty over prior-plus-sensor uncertainty: a filter that trusts its model gets a small gain and mostly ignores the sensor, and one that trusts its sensor gets a gain near one. Under linear-Gaussian assumptions the recursion is the minimum-variance estimator, and Kalman's projection-based derivation makes it the best linear estimator with white noise even without Gaussian noiseSource 1.
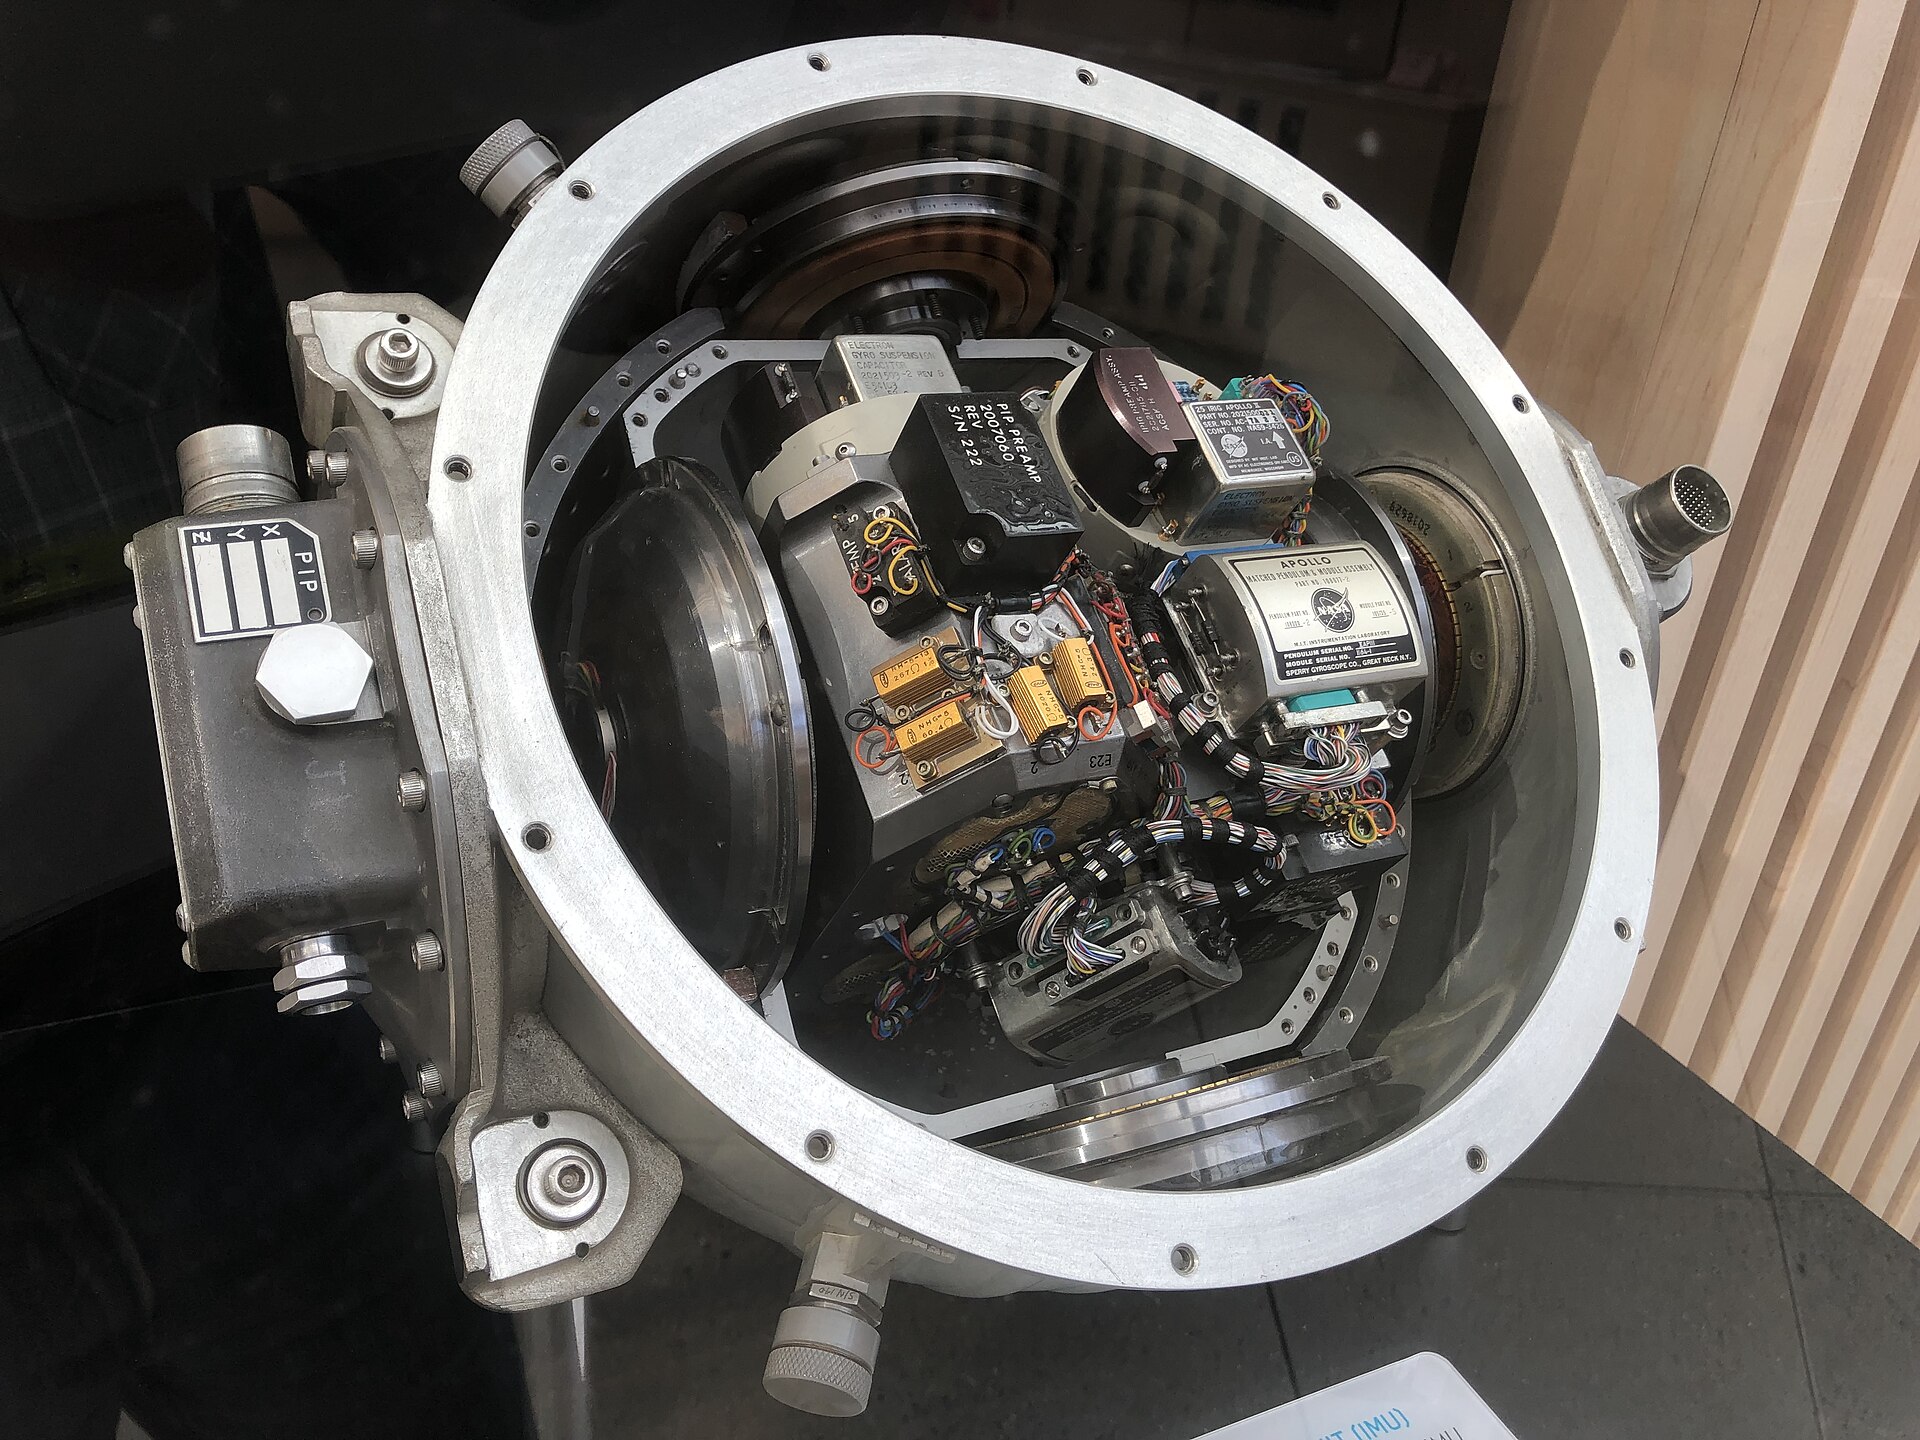
McGee and Schmidt's 1985 NASA history credits Schmidt's Ames group with adapting the filter to nonlinear circumlunar navigation in the early 1960s. By early 1961 simulations supported the approach, though operation on available flight computers was unverified. The report separates this work from Battin's Apollo studies at MIT and Potter's square-root implementation used in Apollo. Primary Apollo navigation used ground radar, with an onboard backupSource 2.
Kalman filter, a whole run
The filter keeps tracking, but grows less sure without readings
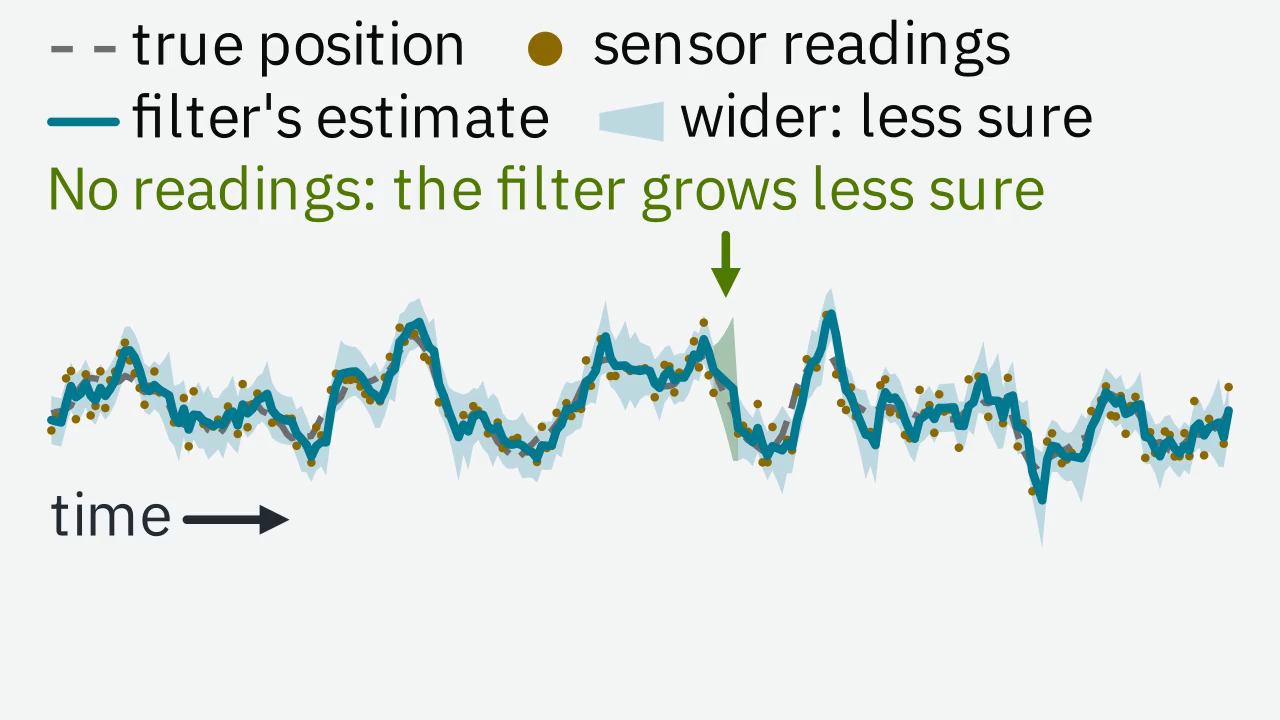
Through noisy and missing readings the filter stays close to the object, and its band shows when a robot should trust it less.
How this was made
A seeded toy simulation (seed 1): an object drifts along a line, and a position sensor reads it with random noise and misses about one step in five. The clip shows 240 steps of that run, steps 300 to 540, with time running left to right and position up and down.
Each step has two halves, which Kalman filters call predict and update: predicting where the object moved widens the band, and a reading, when one arrives, narrows it.
The band spans two standard deviations either side of the filter's estimate, about 95% of its belief. The filter's noise settings match the simulation: process noise 0.20, reading noise 1.00.
The note and its arrow mark steps 436 to 439, the longest run of missing readings in the simulation: four in a row, with that stretch of the band tinted in the note's colour. By the fourth missing step the band is three times as wide as at the last reading before the gap, and it narrows when the next reading arrives.
The clip is rendered offline from the same filter code as the scene above. It is silent; its captions and the transcript carry the words.
Illustrative: a simulated run, not measured on hardware.
Illustrative cinematic clip, 16 seconds: one Kalman filter over a whole run of 240 steps, with time running left to right and position up and down. Labels name each mark. An object moves back and forth; a dashed line marks its true position. A noisy sensor reports the object's position as scattered dots, and about one time in five it reports nothing. The filter's estimate, a solid line, stays close to the true position, and a shaded band around it shows how unsure the filter is: a wider band means less sure. A note reads: no readings, the filter grows less sure. Its arrow points at the band's widest stretch, tinted in the note's colour, where four readings in a row are missing and the band grows to three times its width; the next reading narrows it again. In filter terms, each predict step widens the band and each update with a reading narrows it. Simulated run, not measured on hardware.
The extended Kalman filter
Real robots are nonlinear: joint angles enter through sines and cosines, so the models become and . The extended Kalman filter keeps the Gaussian belief, linearizes both models about the current estimate with their Jacobians and , and propagates the covariance through the tangent systemSource 3:
The mean moves through the true maps and ; only the covariance takes the linearized routeSource 3. The Ames group moved from linearizing about a nominal reference trajectory to relinearizing about the current estimated state, which they hoped would bring "substantial advantages". An accidentally off-nominal simulation converged after initial overshoots, and the report names this modification the extended Kalman filter. It also discusses instability from round-off, inadequate statistical models and nonlinearitiesSource 2.
Linearization holds near the estimate, which is itself uncertain, so where the nonlinearity is strong over the region the covariance covers, stops describing the true error, and the filter grows overconfident and can divergeSource 2 Source 6. Julier and Uhlmann summarize 35 years of experience: the EKF is difficult to implement and tune, and reliable only for systems almost linear on the time scale of the updatesSource 14. Li and Mourikis proved that standard EKF visual-inertial odometry is inconsistent because of how its Jacobians are computed, so it underestimates its uncertaintySource 15.
Linearization
A straight line fits the curve only near the guess
30 degrees
The dial on the cursor reads the miss: the lit plunger’s lengthSpread 30 degrees · 6.8 cm off at the edge
Illustrative arm and spread; the miss is that arm's exact geometry
How this was made
Joint angles enter a robot's models through sines and cosines, so where a one-joint arm puts its hand is a curve. The extended Kalman filter keeps a Gaussian belief and moves its spread through the models' tangents at the current estimate, the Jacobians. Near the estimate the tangent and the curve agree; away from it they part, and the farther the belief spreads, the more the straight line misses: about four times as much for twice the spread. Where the curve bends strongly over the spread the filter's covariance stops describing its real error, and it can grow overconfident and diverge.
The drawing is a tangent-rule stand. A one-joint arm swings over an upright protractor, its stylus riding in a groove engraved in the face: the hand's true path. A steel rule across the top touches the groove at the guess: the straight line the filter uses in its place. A cursor on the rule goes where the straight line puts the hand for the arm's angle, the same arc length along the rule as the stylus goes along the groove. The dial gauge on the cursor reaches its lit plunger down to the arm's tip, so the plunger's length is the miss; its dial turns once for 15 cm, and the plunger is marked every centimetre. Groove and rule carry the same graduations, five degrees of arc apart. Two pairs of stops, on the rim and on the rule, mark the spread either side of the guess.
Illustrative: a 50 cm arm and spreads from 5 to 40 degrees. The miss is that arm's exact geometry, the distance between the hand and the tangent's point for the same angle.
Thrun, Burgard and Fox, Probabilistic Robotics (2005); McGee and Schmidt (1985); Dellaert and Kaess (2006).
The unscented Kalman filter of Julier and Uhlmann keeps the Gaussian and pushes deterministically chosen sample points through the true nonlinearitySource 4. Particle filters drop the Gaussian assumption and carry the belief as a set of particlesSource 3.
Invariant filters on Lie groups remove the dependence on the estimate: in the contact-aided invariant EKF, neither the linearized error dynamics nor the linearized observation model depends on the current state estimateSource 16.
Factor graphs: keep the whole trajectory
Rauch, Tung and Striebel related filtered and smoothed estimates in 1965 and showed numerically that smoothing reduces errorsSource 18. In EKF-based SLAM, marginalizing old poses commits their linearized information to a Gaussian approximation that cannot be relinearized later. Full smoothing keeps the trajectory and can relinearize, though nonlinear optimization is not guaranteed to reach the global minimumSource 6 Source 9. The posterior over the trajectory is a product of factors, one per measurement or motion constraintSource 6:
Drawn as a bipartite graph of variable and factor nodes, this is a factor graph. Kschischang, Frey, and Loeliger's 2001 paper unified inference on such graphs under the sum-product algorithmSource 5. With Gaussian factors, the most probable trajectory solves one sparse nonlinear least-squares problemSource 6:
Dellaert and Kaess's 2006 Square Root SAM jointly estimates the SLAM trajectory and landmark map, assuming known data associations, Gaussian models, a uniform landmark prior and a fixed initial frame. It solves successive linearized systems, by QR on the measurement Jacobian or Cholesky on the information matrix, and variable ordering sets fill-in and costSource 6. The iSAM method updates only the part of the factorization a new measurement touchesSource 7.
iSAM2 adds a Bayes tree with incremental reordering and relinearization: an update re-eliminates the affected cliques and their ancestors, then reattaches unaffected subtrees. Thresholds trade accuracy for computation, and a large loop closure can cost as much as a batch solveSource 8.
GTSAM is a BSD-licensed C++ library that implements sensor fusion for robotics and computer vision using factor graphsSource 11. Version 4.3 moved to C++17 and added experimental CUDA nonlinear optimization and several legged-state-estimation implementationsSource 17. Building on Lupton and Sukkarieh's preintegration, Forster and colleagues' on-manifold version collapses anywhere from a few to hundreds of IMU readings between two keyframes into one factorSource 10.
Cadena and colleagues describe a classical SLAM period from 1986 to 2004, with EKF, Rao-Blackwellised particle-filter and maximum-likelihood approaches, and an algorithmic-analysis period from 2004 to 2015Source 9. In Rao-Blackwellized grid mapping, each particle carries its own mapSource 19.
The survey treats MAP estimation, often over factor graphs, as the de facto standard but notes EKF systems with state-of-the-art performance. The gap shrinks when EKF linearization is accurate, sliding windows are used and inconsistency is addressed, and graphs still face unbounded growth and information loss under sparsificationSource 9. The MSCKF sliding-window filter keeps 3D feature positions out of the state and is optimal up to linearization errorsSource 20, while OKVIS argues that nonlinear optimization offers superior accuracy and stays tractable through sparsitySource 21. Scene representation and mapping covers what a robot keeps from the estimate.
Where this meets the learned stack
Learned components mostly enter classical estimators as measurements with uncertainty. TLIO regresses 3D displacement and its uncertainty from IMU data and fuses both into a stochastic cloning EKFSource 22, and MAC-VO learns a metrics-aware keypoint covariance and uses it to weight pose graph optimizationSource 23.
A September 2026 paper from Linus Kramer, William Talbot, Olga Vysotska and Marco Hutter is an example. For robots on construction sites, they replace the observation model of a Monte Carlo localization particle filter with a network that matches LiDAR scans against the building mesh, trained only on scans simulated inside that mesh. On real-world datasets it outperformed diffusion-based and ScanContext++ baselines at 18 ms per callSource 12.
GAIT estimates legged-robot state without an explicit contact estimator and outperforms contact-aided model-based methods on a Unitree Go1Source 24.
Yuheng Qiu, Pieter Abbeel, Guanya Shi and colleagues at Amazon FAR, Carnegie Mellon and three other universities (October 2026) train inertial odometry from scratch without velocity or position labels: a teacher integrates the IMU over each short window, and a pose graph over many windows refines the targetsSource 32. On six datasets from pedestrians, drones, quadrupeds and a humanoid, average velocity error came within 0.07 m/s of a supervised network of the same architecture, though its trajectory error on the EuRoC drone flights was 10.23 m against the supervised network's 3.72 mSource 32. The teacher used a reference attitude to remove gravity, and the IMU bias must be calibratedSource 32.
Jiaxi Jiang, Marco Hutter, Christian Holz and colleagues at ETH Zurich (October 2026) estimate a humanoid's joint angles and world-space motion from ordinary video, training the pose decoder only on 128,000 synthetic images of sixteen humanoidsSource 33. With no real pose labels, joint-angle error on three real humanoids was 18 to 32% below the best baseline on eachSource 33.
Latent-dynamics world models act as learned belief states. PlaNet's latent dynamics model has deterministic and stochastic transition components trained with variational inferenceSource 25. DreamerV3 learns a model of the environment and improves its behaviour by imagining future scenariosSource 26.
Timing is part of the state
Fusing visual and inertial measurements requires each measurement's precise sampling timeSource 27, and most consumer cameras use rolling shutters that capture each pixel row at a slightly different timeSource 28. The camera-IMU offset can be a state variable, locally identifiable except in a few degenerate motionsSource 27; OpenVINS calibrates it in its sliding-window filterSource 29, and Kalibr estimates time offsets to a fraction of the smallest measurement periodSource 30.
Persistent directional residuals in per-sensor innovations point to calibration or timing bias instead of random noise. GrandTour, which its authors call the largest open-access legged-robotics dataset, supplies RTK-GNSS and total-station ground truthSource 31. The calibration guide covers temporal residuals, and the ROS 2 guide covers timestamped interfaces.
See also
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
Linked from
- Robot Learning Curriculum for ML Engineers
A dependency-ordered route from supervised learning to real robot policies.
- Sim-to-Real Transfer
Domain randomization, distillation, system identification and real-to-sim reconstruction.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
- Space Robotics
Robots where repair is impossible, from Mars to orbit.
References
R. E. Kalman, J. Basic Engineering, 1960.
https://doi.org/10.1115/1.3662552
Leonard A. McGee, Stanley F. Schmidt, NASA TM-86847, 1985.
https://ntrs.nasa.gov/citations/19860003843
Sebastian Thrun, Wolfram Burgard, Dieter Fox, MIT Press, 2005.
https://mitpress.mit.edu/9780262201629/probabilistic-robotics/
Simon J. Julier, Jeffrey K. Uhlmann, Proc. SPIE 3068, 1997.
https://doi.org/10.1117/12.280797
Frank R. Kschischang, Brendan J. Frey, Hans-Andrea Loeliger, IEEE Trans. Information Theory, 2001.
https://doi.org/10.1109/18.910572
Frank Dellaert, Michael Kaess, Int. J. Robotics Research, 2006.
https://doi.org/10.1177/0278364906072768
Michael Kaess, Ananth Ranganathan, Frank Dellaert, IEEE Trans. Robotics, 2008.
https://doi.org/10.1109/TRO.2008.2006706
Michael Kaess, Hordur Johannsson, Richard Roberts, Viorela Ila, John J. Leonard, Frank Dellaert, Int. J. Robotics Research, 2012.
https://doi.org/10.1177/0278364911430419
Cesar Cadena, Luca Carlone, Henry Carrillo, Yasir Latif, Davide Scaramuzza, José Neira, and 2 more, IEEE Transactions on Robotics, 2016.
https://arxiv.org/abs/1606.05830
Christian Forster, Luca Carlone, Frank Dellaert, Davide Scaramuzza, IEEE Trans. Robotics, 2017.
https://arxiv.org/abs/1512.02363
Frank Dellaert, GTSAM Contributors, 2026.
https://gtsam.org/
Linus Kramer, William Talbot, Olga Vysotska, Marco Hutter, 2026.
https://arxiv.org/abs/2609.31357
N. J. Gordon, D. J. Salmond, A. F. M. Smith, IEE Proceedings F (Radar and Signal Processing), 1993.
https://doi.org/10.1049/ip-f-2.1993.0015
S. J. Julier, J. K. Uhlmann, Proceedings of the IEEE, 2004.
https://doi.org/10.1109/JPROC.2003.823141
Mingyang Li, Anastasios I. Mourikis, Int. J. Robotics Research, 2013.
https://doi.org/10.1177/0278364913481251
Ross Hartley, Maani Ghaffari, Ryan M. Eustice, Jessy W. Grizzle, arXiv preprint (Int. J. Robotics Research 2020), 2019.
https://arxiv.org/abs/1904.09251
Frank Dellaert, GTSAM Contributors, borglab/gtsam GitHub release, 2026-09-18.
https://github.com/borglab/gtsam/releases/tag/4.3.0
H. E. Rauch, F. Tung, C. T. Striebel, AIAA Journal, 1965.
https://doi.org/10.2514/3.3166
Giorgio Grisetti, Cyrill Stachniss, Wolfram Burgard, IEEE Trans. Robotics, 2007.
https://doi.org/10.1109/TRO.2006.889486
Anastasios I. Mourikis, Stergios I. Roumeliotis, ICRA 2007.
https://doi.org/10.1109/ROBOT.2007.364024
Stefan Leutenegger, Simon Lynen, Michael Bosse, Roland Siegwart, Paul Furgale, Int. J. Robotics Research, 2014.
https://doi.org/10.1177/0278364914554813
Wenxin Liu, David Caruso, Eddy Ilg, Jing Dong, Anastasios I. Mourikis, Kostas Daniilidis, and 2 more, IEEE Robotics and Automation Letters, 2020.
https://arxiv.org/abs/2007.01867
Yuheng Qiu, Yutian Chen, Zihao Zhang, Wenshan Wang, Sebastian Scherer, arXiv preprint (ICRA 2025), 2024.
https://arxiv.org/abs/2409.09479
Young-Rang Seo, Hajun Kim, Sangmin Kim, Dongyun Kang, Hae-Won Park, arXiv preprint, 2026.
https://arxiv.org/abs/2606.14160
Danijar Hafner, Timothy Lillicrap, Ian Fischer, Ruben Villegas, David Ha, Honglak Lee, and 1 more, 2018.
https://arxiv.org/abs/1811.04551
Danijar Hafner, Jurgis Pasukonis, Jimmy Ba, Timothy Lillicrap, Nature 640, 647-653, 2025.
https://doi.org/10.1038/s41586-025-08744-2
Mingyang Li, Anastasios I. Mourikis, Int. J. Robotics Research, 2014.
https://doi.org/10.1177/0278364913515286
Mingyang Li, Byung Hyung Kim, Anastasios I. Mourikis, ICRA 2013.
https://doi.org/10.1109/ICRA.2013.6631248
Patrick Geneva, Kevin Eckenhoff, Woosik Lee, Yulin Yang, Guoquan Huang, ICRA 2020.
https://doi.org/10.1109/ICRA40945.2020.9196524
Paul Furgale, Joern Rehder, Roland Siegwart, 2013 IEEE/RSJ International Conference on Intelligent Robots and Systems.
https://doi.org/10.1109/IROS.2013.6696514
Turcan Tuna, Jonas Frey, Frank Fu, Katharine Patterson, Tianao Xu, Maurice Fallon, and 2 more, arXiv preprint, 2026.
https://arxiv.org/abs/2602.18164
Yuheng Qiu, Yutian Chen, Carlton Cort, Weison Huang, Shibo Zhao, Pieter Abbeel, and 7 more, 2026.
https://arxiv.org/abs/2610.25988
Jiaxi Jiang, Matthias Heyrman, René Zurbrügg, Marco Hutter, Christian Holz, 2026.
https://arxiv.org/abs/2610.25288
Further reading
Randall C. Smith, Matthew Self, Peter Cheeseman, Autonomous Robot Vehicles, 1990.
https://doi.org/10.1007/978-1-4613-8997-2_14
F. Dellaert, D. Fox, W. Burgard, S. Thrun, ICRA 1999.
https://doi.org/10.1109/ROBOT.1999.772544
R. E. Kalman, R. S. Bucy, J. Basic Engineering, 1961.
https://doi.org/10.1115/1.3658902
Pieter van Goor, Robert Mahony, IEEE Trans. Robotics, 2022.
https://arxiv.org/abs/2205.01980
Tuomas Haarnoja, Anurag Ajay, Sergey Levine, Pieter Abbeel, NIPS 2016.
https://arxiv.org/abs/1605.07148
Yuheng Qiu, Can Xu, Yutian Chen, Shibo Zhao, Junyi Geng, Sebastian Scherer, arXiv preprint, 2025.
https://arxiv.org/abs/2501.15659
Shibo Zhao, Sifan Zhou, Raphael Blanchard, Yuheng Qiu, Wenshan Wang, Sebastian Scherer, CVPR 2025.
https://openaccess.thecvf.com/content/CVPR2025/papers/Zhao_Tartan_IMU_A_Light_Foundation_Model_for_Inertial_Positioning_in_CVPR_2025_paper.pdf
Riku Murai, Eric Dexheimer, Andrew J. Davison, arXiv preprint (CVPR 2025), 2024.
https://arxiv.org/abs/2412.12392
Spot a factual error or missing qualification? Report a content correction.