Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
Control uses feedback to make a robot follow a reference, such as a motion plan, despite model error and disturbances: measure the state, compare it with the reference, correctSource 19. Feedback loops run beneath any learned policy, from motor drivers to whole-body torque control.
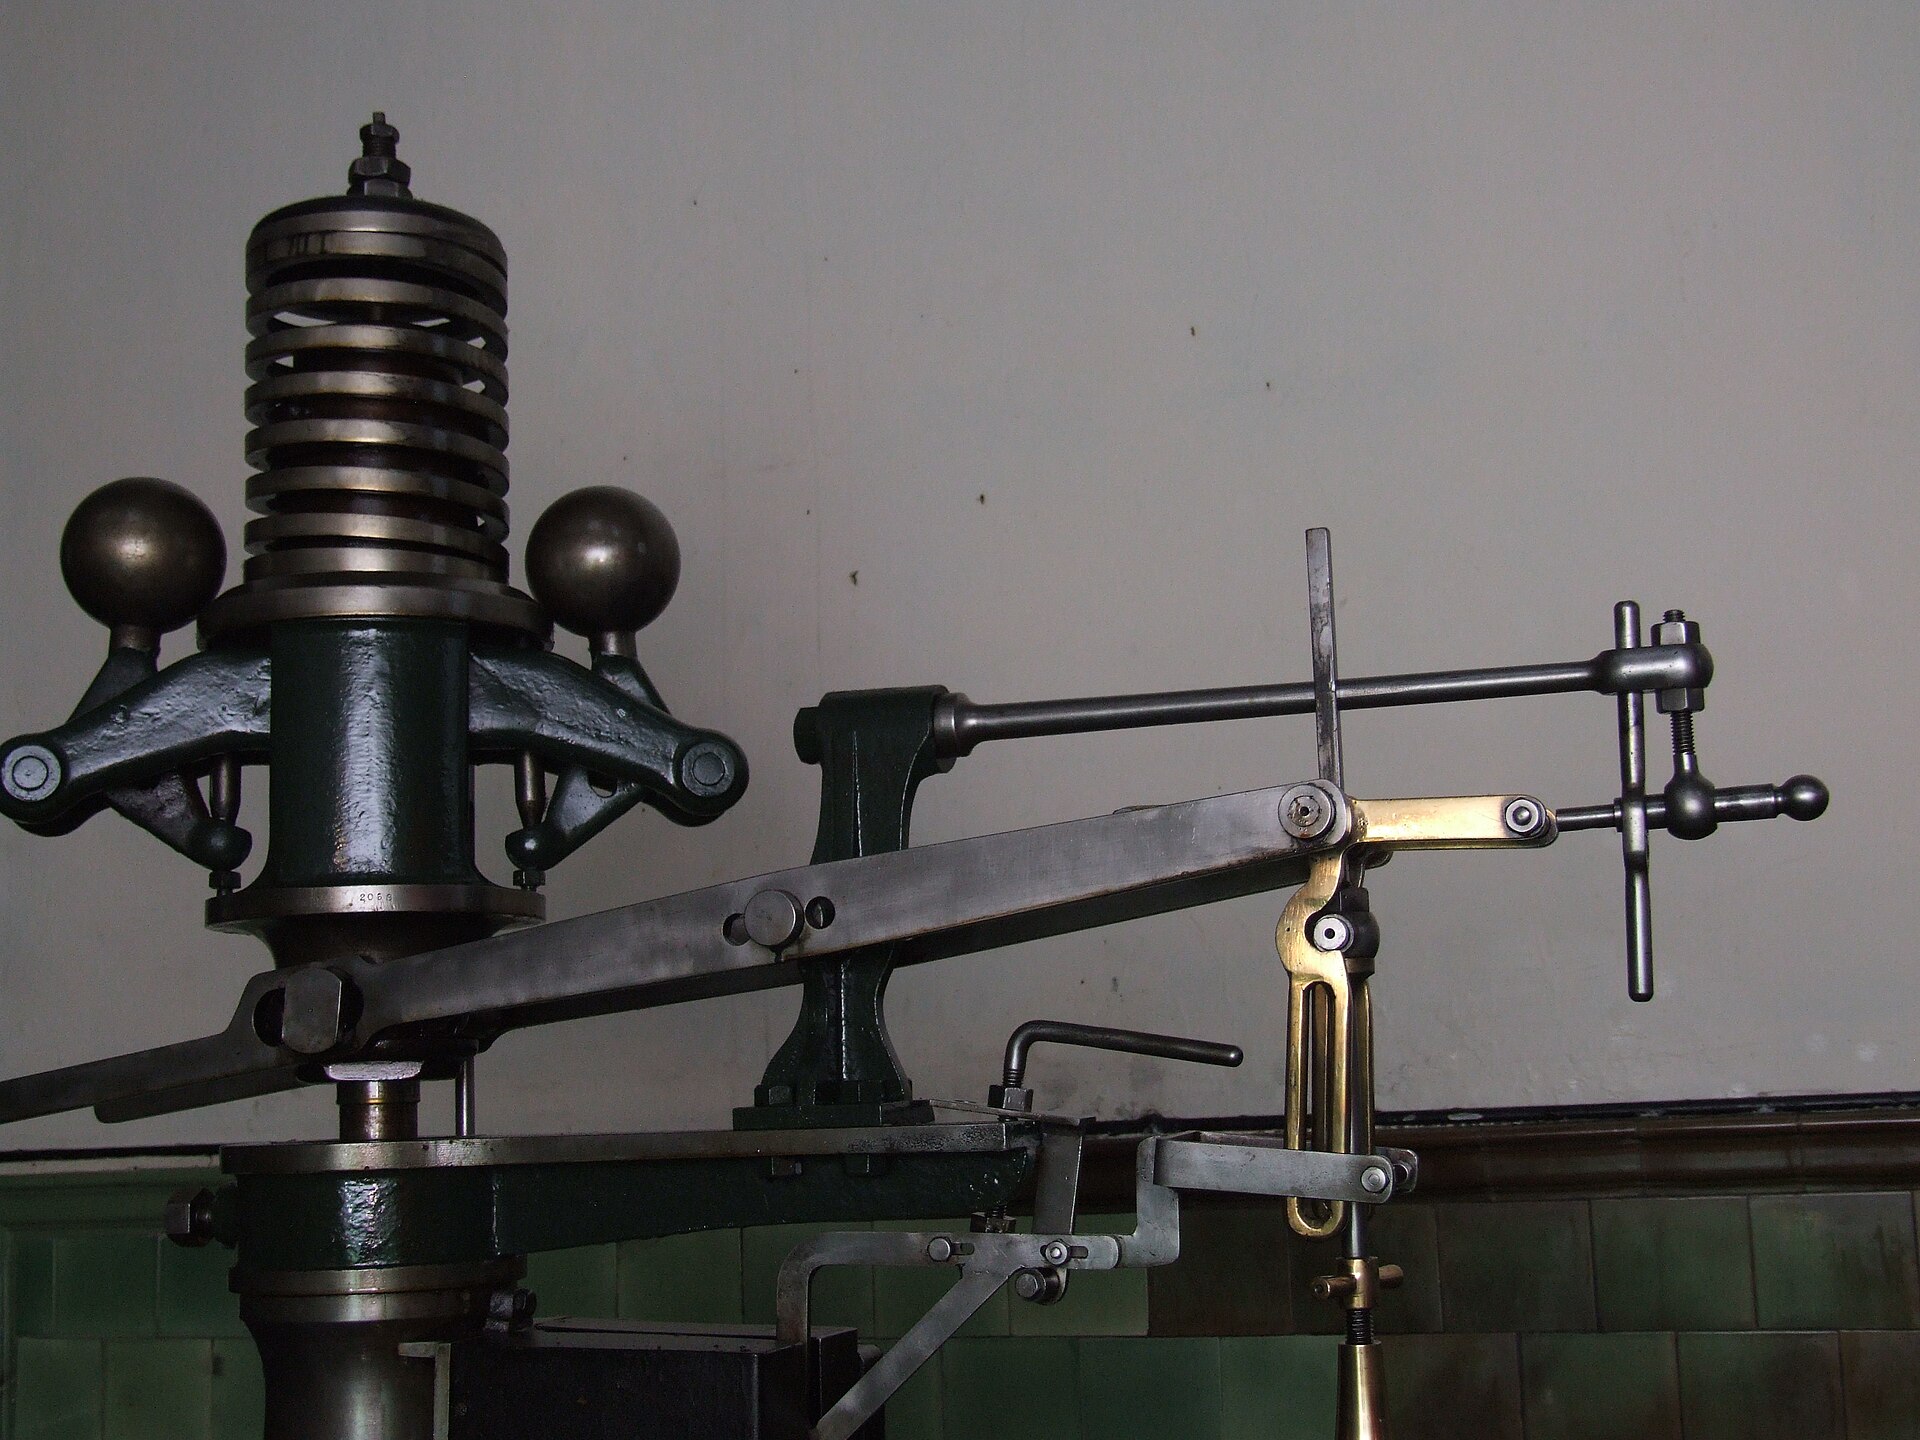
Guess first
The lab starts half a unit under the threshold: press Too gentle to release the pole and it sags to a steep lean. Press Strong enough and it holds near upright.
PID control
Push back harder than gravity to keep the pole upright
How hard the motor pushes back
Adjust more
angle +12.0°rate +0.0°/sintegral 0.00torque -2.0 N·mstatus holding at release
Pole: 1 kg weight, 1 m rodLong needle: the motor's pushShort needle: gravity's pullReleased 12 degrees off upright
Illustrative simulation
How this was made
A deterministic simulation: a 1 kg point mass on a massless 1 m rod, released 12 degrees off upright, with the motor's torque applied at the pivot and capped at 40 N·m. A small off-centre load adds a constant 0.8 N·m that tips the pole right. The motor pushes back with u = −(Kp·θ + Ki·∫θ + Kd·θ̇): P reacts to the lean, I removes the steady lean the load leaves, and D damps the swing. Linearised about upright, the pole can only be held upright when Kp exceeds m·g·l = 9.81 N·m per radian, so below it no I or D setting helps. Too gentle sets Kp to 9.5: the pole sags until the motor's push matches gravity's pull, about 50 degrees off upright. Strong enough sets the stock 25. On the gauge both needles sweep 18 degrees per N·m from one zero: the long one is the motor's torque, the short one gravity's pull on the leaning pole plus the load's 0.8 N·m, so the pole can only come back while the long needle is past the short one. On the dial plate a printed band marks upright within 10 degrees and another marks past 60 degrees, where the lab calls the pole fallen; the faint ink is the weight's path over the last two seconds. The balance problem follows Tedrake's Underactuated Robotics, chapters 2 and 3; the PID structure follows Åström and Murray's Feedback Systems.
The prediction-step pole starts at Kp 9.5, under the 9.81 mgl hold threshold, still +12.0 degrees off upright and holding at release so the prompt can be answered before playback.
Current pendulum gains and regime
- Kp
- 9.5
- Ki
- 0.0
- Kd
- 3.0
- angle
- +12.0°
- status
- holding at release
Read the reasoning
- Kp must clear the weight threshold, about 9.8 here; below it the pole cannot stay upright, even at high dampingLinearized about upright, the loop is stable only when Kp exceeds m g l, 9.81 in the slider’s units. The derivative term can shape the recovery but cannot create a restoring torque the proportional term does not supply, so below the threshold nothing holds the pole upright.Tedrake 2024
- Any positive Kp holds the pole in the usual case; a small gain only corrects more slowly and the lean settles outThis is the expectation the lab exists to break. Proportional action generates corrective torque from error, and under the threshold that torque loses to gravity near upright: the mounted figure sits half a unit under it, and once released the pole sags to about 50 degrees and stays there.
- A Kp below the threshold can still work, provided Kd is raised enough for the damping to hold the pole upDamping opposes rate. With the pole leaning and accelerating away, a high Kd slows the fall, but it adds no push once the pole stops moving: drag Kd to its ceiling in the figure and the pole sags to the same lean, only more slowly.
The restoring torque must outweigh gravity before anything else matters: past that floor the loop is unstable, and damping alone cannot buy it back.
3 actions
PID
proportional, reset, pre-act
Q / R
LQR cost
state error / control effort
<1 ms
Cheetah 3 MPC
per convex QP, at 20-30 Hz
1 kHz
whole-body layer
Di Carlo's estimation and leg loops
PID: three ways to use an error
For an error between reference and measured output, a PID controller commandsSource 19
Ziegler and Nichols called the three actions proportional response, automatic reset and pre-act. Their 1942 tuning rules drive the loop into oscillation with proportional gain alone, then back off from the critical gain and period by fixed fractionsSource 1.
Integral action removes the steady-state offset that a constant disturbance leaves under proportional control, and it needs anti-windup when the actuator saturates. Åström and Murray quote a survey in which 97% of over eleven thousand regulatory controllers in refining, chemicals and pulp and paper used PIDSource 19.
A torque-driven inverted pendulum, the canonical underactuated plant, obeysSource 2
with measured from upright and a constant torque from an off-center payload. Linearized about upright, the loop is stable only when Source 2.
State space and LQR
For a linear plant under state feedback , the linear quadratic regulator (LQR) picks the gain that minimizes a quadratic cost trading state error against control effortSource 2:
The optimal gain is , where solves the algebraic Riccati equationSource 2:
A heavier angle penalty in stiffens the controller and a heavier torque penalty in softens it; for the linearized pendulum, the LQR gain is a PD controller. The guarantee is local: swinging the pole up from hanging takes an energy-shaping controller, with LQR catching it at the topSource 2.
MPC: re-solve the plan at every step
Model-predictive control solves a short-horizon optimal control problem at every control step, from the measured state and subject to the constraintsSource 4:
Only the first input is applied before the next solve, so feedback from the measured state absorbs part of the model errorSource 2 Source 6, and limits on states and inputs, from torque bounds to friction cones, enter the optimization directlySource 6 Source 21.
MPC grew out of 1970s and 1980s power-plant and refinery practice, where slow, constrained, multivariable plants defeated PIDSource 3 Source 5. On the MIT Cheetah 3, Di Carlo and colleagues' convex MPC solved each QP in under a millisecond at 20 to 30 Hz, and one gain set served every gait from standing to gallopSource 6.
On legged hardware, DIAL-MPC optimizes full-order quadruped dynamics in real time without training and beats RL policies by 50% on climbing tasksSource 22. Reward design and the MPC debate compares these controllers with learned policies.
Whole-body QP: the bottom of the stack
A legged or humanoid robot's whole-body controller turns desired accelerations and contact forces into joint torques. Khatib's 1987 operational-space formulation writes the dynamics in task spaceSource 8:
with the task-space inertia and , the Coriolis and gravity terms, mapped to joints through the kinematic Jacobian. Sentis and Khatib extended it to a task hierarchy, with contact and joint-limit constraints first and posture in the remaining degrees of freedomSource 9, and hierarchical QP solves such priorities at control rateSource 23. Weighted controllers instead solve one quadratic program per tick:
Its variables are joint accelerations, torques and contact forces; the rigid-body dynamics are the equality constraint, holds the friction cones, and each task is one weighted row of the objectiveSource 24.
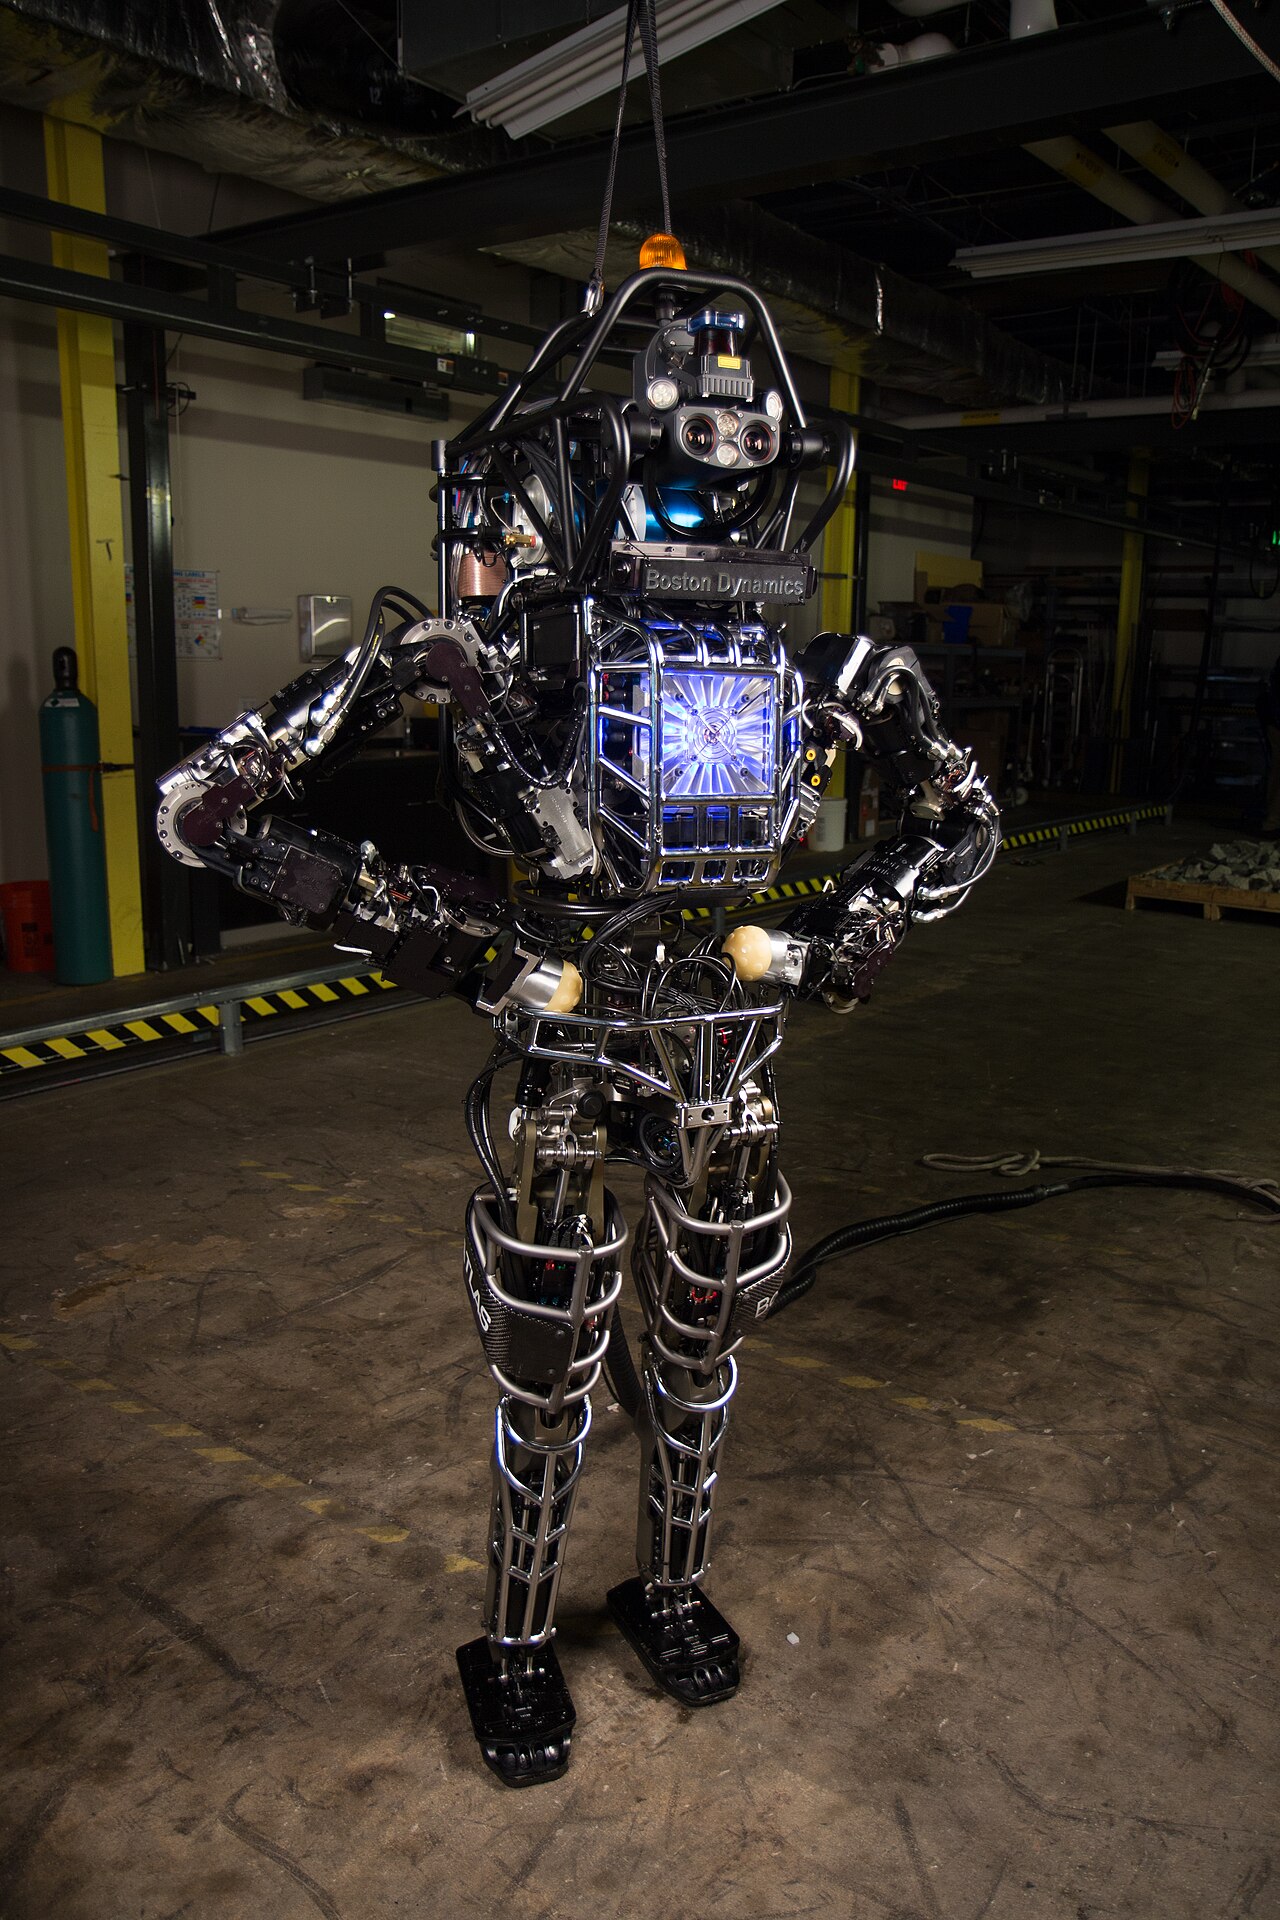
Learned and model-based whole-body control both ship. Figure reports that Helix 02's System 0 runs at 1 kHz and handles balance, contact and coordination across the whole bodySource 25, while Boston Dynamics reports that the teleoperation system behind Atlas's large behavior models pairs Atlas's model-predictive controller with a VR interfaceSource 26. Humanoid whole-body control covers how learned policies relate to the QP.
Impedance control: making contact a design variable
A stiff position-controlled arm driven into a surface 2 mm nearer than modeled turns that error into stored collision energy. Hogan's 1985 impedance control instead commands the relationship between force and motion, so the arm presents a programmable mass-spring-damper: at a contact, a controller commands force or velocity, and the environment fixes the otherSource 11.
Admittance control is the dual: measure force with a wrist sensor and command motion. A backdrivable direct-drive arm realizes an impedance directly, while a stiff geared arm with a force-torque sensor runs admittance in software.
Mason's and Raibert and Craig's hybrid force/position control builds a task frame from the contact geometry and controls force along the constrained axes and position along the free ones, never both on one axisSource 13 Source 12. Polishing, for instance, controls force normal to the surface and position along it, which needs the contact geometry in advance.
Learned policies now set impedance: Adaptive Compliance Policy learns spatially and temporally varying compliance from human demonstrations and reports over 50% improvement over state-of-the-art visuomotor policiesSource 27. A diffusion-based impedance learner co-authored by Hogan adapts stiffness and damping online on a torque-controlled KUKA LBR iiwaSource 28. Intrinsic, which ran the 2026 AI for Industry Challenge, reports that 90% of the top teams in its real-workcell phase inserted the connector with rules-based routines, such as spiral searches, and force-torque feedbackSource 37.
ForceTwin, from Marco Hutter (ETH Zurich) and colleagues (September 2026), fits an articulated object's inertia, friction, damping and spring or door-closer forces from a person probing it with a handheld force-sensing gripper. As the feedforward model for impedance control on a Spot and a Franka FR3, it completed 87% of goals across nine object-robot pairs, against 60% with vision-language-model priors and 57% with kinematics-only twinsSource 36.
A non-backdrivable, position-controlled geared arm without a force sensor has no force channel: position error, gear ratio and the surface set the contact force, so a joint-position policy on it cannot regulate force in the contact-rich tasks of dexterity. Series elastic actuation adds a deliberate spring for shock tolerance and more accurate, stable force controlSource 14.
Franka's interface exposes a 1 kHz torque-level layer with Cartesian impedance controllersSource 15, while Universal Robots' URScript force mode takes a task frame, compliant axes, target forces and position-deviation limitsSource 16. Backdrivability is an actuator decision that fixes which of these schemes the hardware can attempt.
The contact lab's transient force limit comes from published biomechanical measurementsSource 18. ISO/TS 15066:2016 holds the original collaborative-robot tablesSource 17. ISO republished ISO 10218-1 and ISO 10218-2 in February 2025, withdrawing the 2011 editionsSource 29 Source 30, and a 2026 comparison describes the 2025 series as fully absorbing ISO/TS 15066Source 31.
Impedance control
A softer arm touches gently enough not to crush
Adjust more
softness 800 N/msettles at 1.6 Npeak 23.7 Noutcome object intact
The pointer stays at the first bump; past the shaded arc the glass cracksFirst bump 23.7 newtons · just under the crushing force
Illustrative model, not measured
How this was made
An illustrative model, not measured: a 4 kg fingertip mass starts 0.5 mm above the object and is commanded 2.0 mm into it. The object is a stiff 400 kN/m contact spring that crushes at 25 N, at the first bump or once settled. The arm that controls its own push runs an impedance law with stiffness K (Softness, 800 N/m) and damping D (Calm the bounce, 40 N·s/m). The arm with a built-in spring adds an 800 N/m spring in series with the contact. The stiff arm, a geared arm under position control, only follows its commanded position, so the force is whatever the position error makes it. The press is drawn as a test stand: the gauge reads to 50 N and a bigger push rests on its stop pin; the head's travel and the spring's squeeze are drawn larger than they are, and each press plays the 0.6 s contact slowed 6 times. For scale, the human pain limit is about 10 times the crush force: contact-force limit 255 N (thigh, transient contact; research basis: 75th-percentile force pain threshold, Han 2024), measured with a wedge-shaped impactor Source 18, used in place of the paywalled ISO/TS 15066 table.
On the arm that controls its own push at press depth 2.0 mm, stiffness 800 N/m and damping 40 N·s/m, the contact peaks at 23.7 N, under the 25 N crush force, and settles at 1.6 N; the 255 N research-basis transient limit is not reached: object intact.
Current contact lab settings and outcome
- depth
- 2.0 mm
- K
- 800 N/m
- D
- 40 N·s/m
- peak
- 23.7 N
- outcome
- object intact
The policy-to-controller contract
A learned action reaches the motors through a lower controller, so request type, rate, horizon, frame and saturation behavior belong to the interface. Peng and van de Panne showed that the action parameterization, from torques to target joint angles, affects learning, robustness and motion qualitySource 32, and the same Cartesian delta behaves differently in contact under a position controller and under an impedance controller.
Deployed stacks are multi-rate: Berkeley Humanoid runs its RL policy at 50 Hz, its state estimator at 1 kHz and its PD controller at 25 kHzSource 20.
Model latency is part of the loop: a 3-billion-parameter VLA spends 46 ms on KV-cache prefill alone on an RTX 4090Source 33. Deadline handling and hard bounds therefore sit outside the model, holding or stopping the robot when inference is late or an action is out of bounds. Data-driven controllers often lack well-understood guarantees, which motivates separate safety filtersSource 34. The action-space guide covers interface choice.
Where this meets the learned stack
MPC keeps a sim-to-real gap even when it re-solves against the measured stateSource 7. That gap and the computational burden still limit whole-body MPC on real humanoids, and Ishihara and colleagues patch the model with a learned residual networkSource 35. Boston Dynamics added reinforcement learning to Spot's existing MPC stackSource 10.
Self-check
Read the reasoning
- The integral term of the joint-level controllerProportional action alone always leaves a steady-state error, because a nonzero error is what generates the corrective torque. The integral term accumulates that residual error and erases a constant offset, which is why the current loop inside every actuator of a learned-policy demo is usually PI.
- Retrain the walking policy with the payload presentThis treats a constant disturbance as a training problem. Automatic reset, the integral action in the joint-level loop, instead accumulates the residual error and removes a constant offset at runtime without changing the walking policy.
- A higher MPC re-solve rate at the whole-body layerRe-solving faster does not remove a bias the model omits: MPC re-solves against the measured state every step, so tracking improves, but a constant unmodeled offset survives each re-solve exactly as it survived the last one. Speed pays for constraints and horizon, not for erasing offsets.
A constant disturbance is the textbook case for integral action: the loop removes it at runtime, whatever learned policy sits above it.
See also
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
- Industrial Deployment
The jam-rate arithmetic that decides whether a 99 percent cell ships.
Linked from
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- Motion Planning
Configuration space, RRT and its variants, and trajectory optimization.
- State Estimation
Kalman filters, factor graphs, and pose estimation from noisy sensors.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Dexterity
Contact-rich manipulation, touch sensing, in-hand reorientation and deformables.
- Safety and Assurance
What ships is a verifiable safety layer around the learned policy.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
References
J. G. Ziegler, N. B. Nichols, Trans. ASME, 1942.
https://doi.org/10.1115/1.2899060
Carlos E. Garcia, David M. Prett, Manfred Morari, Automatica, 1989.
https://doi.org/10.1016/0005-1098(89)90002-2
D. Q. Mayne, James B. Rawlings, Christopher V. Rao, P. O. M. Scokaert, Automatica, 2000.
https://doi.org/10.1016/S0005-1098(99)00214-9
S. Joe Qin, Thomas A. Badgwell, Control Engineering Practice, 2003.
https://doi.org/10.1016/S0967-0661(02)00186-7
Jared Di Carlo, Patrick M. Wensing, Benjamin Katz, Gerardo Bledt, Sangbae Kim, IEEE/RSJ IROS, 2018.
https://doi.org/10.1109/IROS.2018.8594448
John Z. Zhang, Taylor A. Howell, Zeji Yi, Chaoyi Pan, Guanya Shi, Guannan Qu, and 3 more, ICRA 2026.
https://arxiv.org/abs/2503.04613
Oussama Khatib, IEEE J. Robotics and Automation, 1987.
https://doi.org/10.1109/JRA.1987.1087068
Luis Sentis, Oussama Khatib, Int. J. Humanoid Robotics, 2005.
https://doi.org/10.1142/S0219843605000594
Boston Dynamics, 2024.
https://bostondynamics.com/blog/starting-on-the-right-foot-with-reinforcement-learning/
Neville Hogan, ASME J. Dynamic Systems, Measurement, and Control, 1985.
https://doi.org/10.1115/1.3140702
M. H. Raibert, J. J. Craig, ASME J. Dynamic Systems, Measurement, and Control, 1981.
https://doi.org/10.1115/1.3139652
Matthew Mason, IEEE Trans. Systems, Man, and Cybernetics, 1981.
https://doi.org/10.1109/TSMC.1981.4308708
Gill Pratt, Matthew Williamson, IEEE/RSJ Int. Conf. Intelligent Robots and Systems, 1995.
https://doi.org/10.1109/IROS.1995.525827
Franka Robotics, Franka Robotics, as of 2026-08-20.
https://frankarobotics.github.io/docs/
Universal Robots, Universal Robots, as of 2026-08-20.
https://www.universal-robots.com/articles/ur/programming/urscript-dynamic-force-control/
ISO, ISO Technical Specification (public catalogue entry), 2016.
https://www.iso.org/standard/62996.html
D. Han, M. Y. Park, J. Choi, H. Shin, R. Behrens, S. Rhim, Frontiers in Robotics and AI, 2024.
https://doi.org/10.3389/frobt.2024.1374999
Karl Johan Åström, Richard M. Murray, Princeton University Press (electronic edition v3.1.5), 2020.
https://fbswiki.org/wiki/index.php/Main_Page
Qiayuan Liao, Bike Zhang, Xuanyu Huang, Xiaoyu Huang, Zhongyu Li, Koushil Sreenath, arXiv preprint, 2024.
https://arxiv.org/abs/2407.21781
Michael Neunert, Markus Stauble, Markus Giftthaler, Carmine D. Bellicoso, Jan Carius, Christian Gehring, and 2 more, IEEE Robotics and Automation Letters, 2018.
https://doi.org/10.1109/LRA.2018.2800124
Haoru Xue, Chaoyi Pan, Zeji Yi, Guannan Qu, Guanya Shi, arXiv preprint (ICRA 2025), 2024.
https://arxiv.org/abs/2409.15610
Adrien Escande, Nicolas Mansard, Pierre-Brice Wieber, Int. J. Robotics Research, 2014.
https://doi.org/10.1177/0278364914521306
Scott Kuindersma, Robin Deits, Maurice Fallon, Andrés Valenzuela, Hongkai Dai, Frank Permenter, and 3 more, Autonomous Robots, 2015.
https://doi.org/10.1007/s10514-015-9479-3
Eric Cousineau, Scott Kuindersma, Lucas Manuelli, Pat Marion, 2025.
https://bostondynamics.com/blog/large-behavior-models-atlas-find-new-footing/
Yifan Hou, Zeyi Liu, Cheng Chi, Eric Cousineau, Naveen Kuppuswamy, Siyuan Feng, and 2 more, arXiv preprint (ICRA 2025), 2024.
https://arxiv.org/abs/2410.09309
Noah Geiger, Tamim Asfour, Neville Hogan, Johannes Lachner, arXiv preprint, 2025.
https://arxiv.org/abs/2509.19696
ISO, ISO International Standard (public catalogue entry), 2025.
https://www.iso.org/standard/73933.html
ISO, ISO International Standard (public catalogue entry), 2025.
https://www.iso.org/standard/73934.html
Daniel Hartmann, Kristýna Hamříková, Aleš Vysocký, Vendula Laciok, Aleš Bernatík, Results in Engineering, 2026.
https://doi.org/10.1016/j.rineng.2026.110486
Xue Bin Peng, Michiel van de Panne, arXiv preprint (SCA 2017), 2016.
https://arxiv.org/abs/1611.01055
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://arxiv.org/abs/2506.07339
Kai-Chieh Hsu, Haimin Hu, Jaime Fernández Fisac, Annual Review of Control, Robotics, and Autonomous Systems, 2023.
https://arxiv.org/abs/2309.05837
Koji Ishihara, Hiroaki Gomi, Jun Morimoto, arXiv preprint, 2024.
https://arxiv.org/abs/2409.08488
Tim Engelbracht, René Zurbrügg, Mayank Mittal, Marco Hutter, Marc Pollefeys, Hermann Blum, and 1 more, 2026.
https://arxiv.org/abs/2609.21751
Intrinsic, 2026.
https://www.intrinsic.ai/blog/posts/ai-for-industry-challenge
Further reading
J. Salisbury, 19th IEEE Conf. Decision and Control, 1980.
https://doi.org/10.1109/CDC.1980.272026
Christian Ott, Alin Albu-Schäffer, Andreas Kugi, Gerd Hirzinger, IEEE Int. Conf. Robotics and Automation, 2003.
https://doi.org/10.1109/ROBOT.2003.1242067
Christian Ott, Ranjan Mukherjee, Yoshihiko Nakamura, IEEE Int. Conf. Robotics and Automation, 2010.
https://doi.org/10.1109/ROBOT.2010.5509861
J. Koenemann, A. Del Prete, Y. Tassa, E. Todorov, O. Stasse, M. Bennewitz, and 1 more, IROS 2015.
https://doi.org/10.1109/IROS.2015.7353843
Kevin Zakka, Baruch Tabanpour, Qiayuan Liao, Mustafa Haiderbhai, Samuel Holt, Jing Yuan Luo, and 7 more, 2025.
https://arxiv.org/abs/2502.08844
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Magnus Dierking, Joao Carvalho, An Thai Le, Georgia Chalvatzaki, Jan Peters, ICRA 2026 Workshop on Frontiers of Optimization for Robotics.
https://arxiv.org/abs/2606.20712
Spot a factual error or missing qualification? Report a content correction.