Action Spaces for Robot Learning
What each action representation gives the learner and asks of the controller.
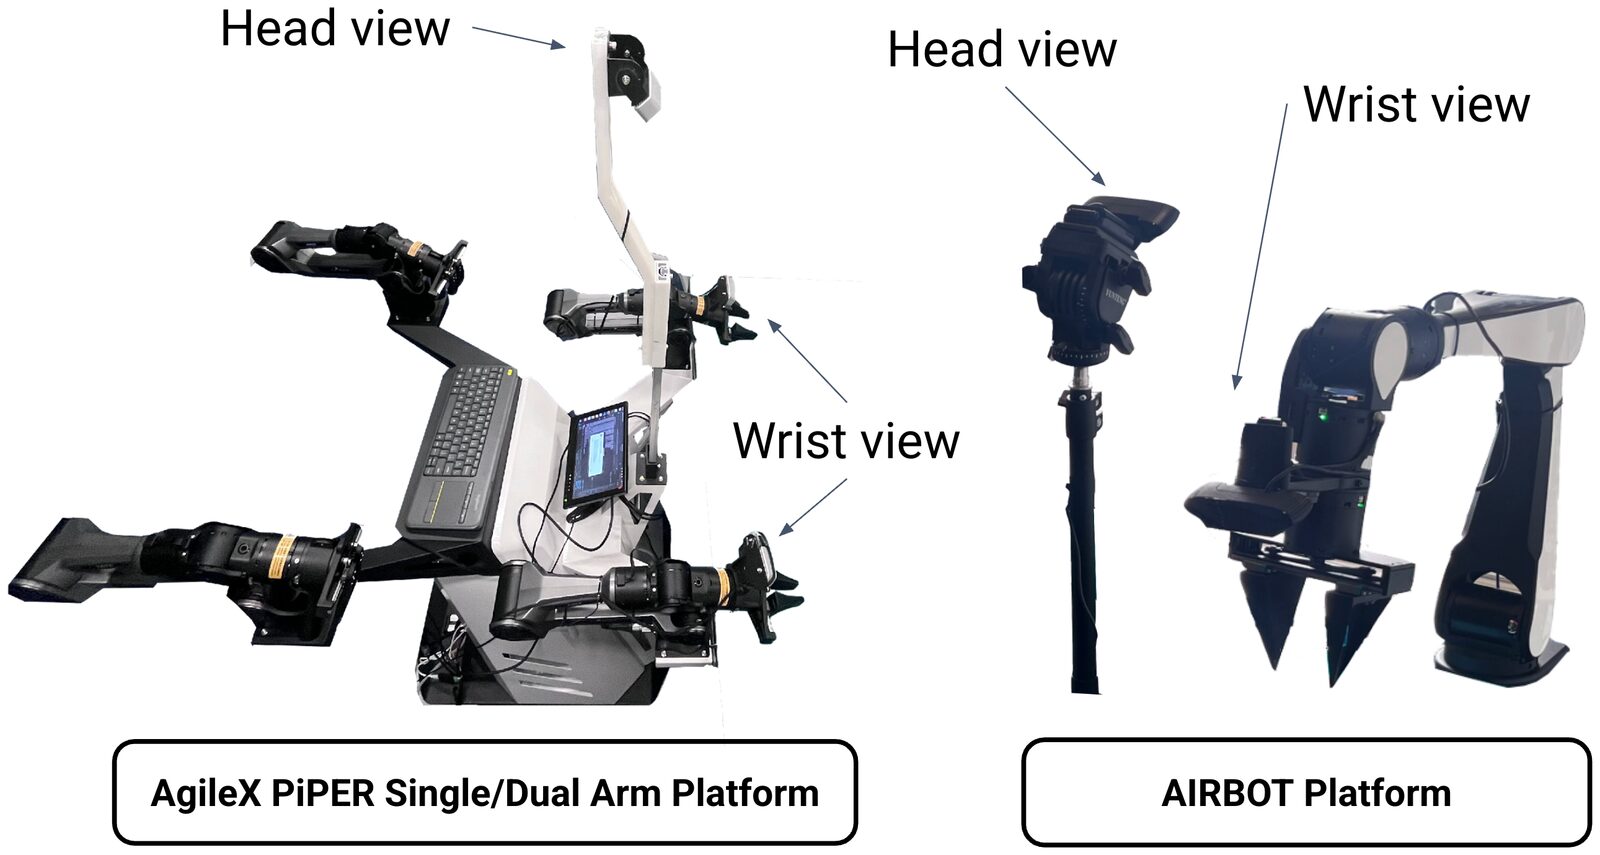
An action space is the interface between a policy and the rest of the robot: what the network predicts, which errors the controller absorbs, how often inference runs and whether embodiments share labels. In Open X-Embodiment, the same seven numbers can mean absolute or relative positions or velocitiesSource 10.
Try the check below.
Self-check
Read the reasoning
- Absolute joint positions for each robotThe same joint vector places different robots in different physical poses. This is easy to replay on one embodiment and a poor shared task-space label across different kinematic chains.
- Relative Cartesian end-effector deltas plus gripper stateThis expresses motion where the task happens and delegates embodiment-specific inverse kinematics and tracking to each robot controller. The frame and rotation convention still have to be identical.
- Raw motor torques at the policy inference rateTorque can express contact behavior, but it is tightly coupled to dynamics, actuator limits and a high-rate safety loop. It is the least portable starting point for these two arms.
Task-space labels can offer a shared interface across these hypothetical arms when each robot implements compatible kinematic conversion.
The contract has four parts
A contract names coordinates (joint, Cartesian, object-relative or another frame), semantics (absolute target, delta, velocity, force, torque or controller parameter), timing (rate, horizon and stale-prediction handling) and execution (interpolation, clipping, inverse kinematics, feedback and safety limits). DROID records equivalent commands in several action spacesSource 11, and robosuite's controllers span joint and Cartesian spacesSource 12.
Joint-space actions
Joint position targets are a common imitation baseline; ACT predicts chunks of absolute joint-and-gripper targets for two ViperX armsSource 2. The controller interpolates and enforces limits, but one shoulder angle moves different arms differently.
Joint velocity targets drift when integrated; the kinematics module derives the forward map and Jacobian both needSource 1. In locomotion RL, target joint angles with local feedback beat raw torques for learning speed, robustness and motion qualitySource 13.
Cartesian actions
Cartesian actions say what the tool should do. Once range and frame are fixed, relative deltas from the current pose label arms with different joint counts and link lengths alike, provided each robot supplies inverse kinematics or an operational-space controller; Khatib's 1987 operational space formulation unifies motion and force controlSource 7. Euler angles and quaternions are discontinuous as network outputs, while 6D representations are continuousSource 14.
GR00T N1.6's notes find relative actions smoother and more accurate than absolute ones but prone to error accumulation on small datasetsSource 15, and in matched VLA pretraining ablations a unified end-effector-relative representation was critical for cross-embodiment transferSource 16. X-VLA instead learns a separate set of soft-prompt embeddings for each data source as embodiment-specific promptsSource 27.
Torque and impedance actions
Torque actions expose dynamics and contact; Levine et al. mapped raw images to motor torquesSource 17. They need a high rate and a safety layer that holds when the output is wrong: libfranka sends 1 kHz commands in five modes, including gravity- and friction-compensated joint torqueSource 9, while Rudin et al.'s locomotion pipeline sends joint-position targets to a PD controllerSource 18.
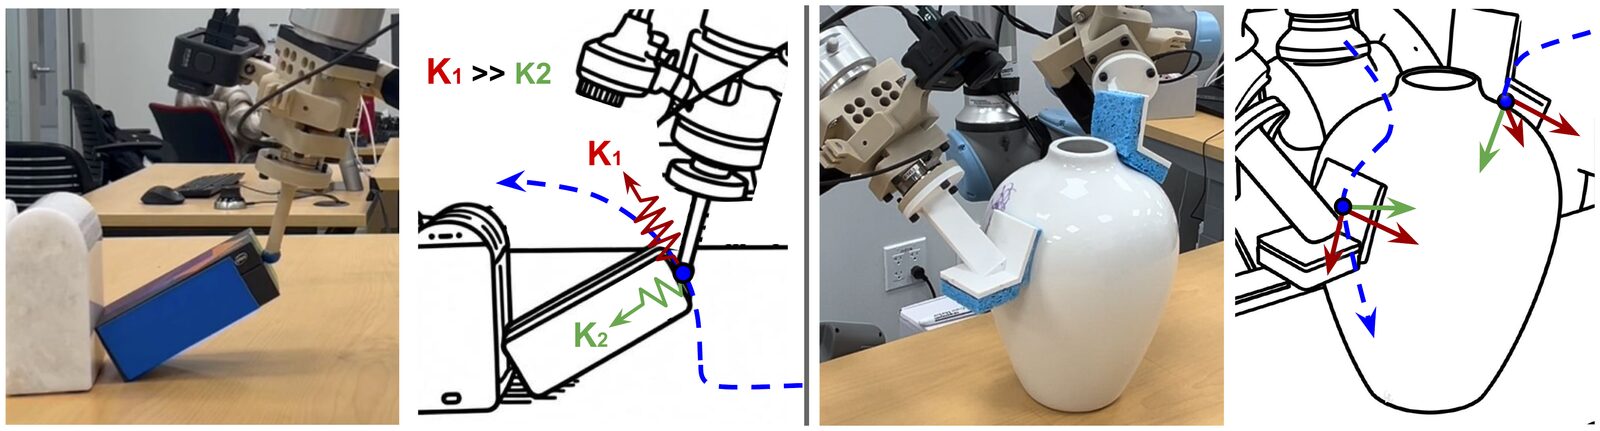
Impedance actions sit between: the policy picks a pose target plus stiffness and damping, and a controller turns error into force. Hogan judged position or force control alone inadequate for manipulationSource 19. Task-space impedance references needed the fewest samples against torque, joint PD and inverse dynamicsSource 20, and Adaptive Compliance Policy's predicted compliance beats position-only visuomotor policies by over 50%Source 21.
Impedance action
The same target pushes harder through a stiffer spring
Spring the policy sets
2 marks past
The lit spring takes up the gap between the target and the toolMedium · 2 marks past · push 4
Illustrative springs: 1, 2 and 4 marks of push per mark of gap
How this was made
An impedance action is a target pose plus a stiffness and a damping, and a controller under the policy turns the gap between the target and the tool into a push. Hogan's impedance law says exactly that: at rest the push is the stiffness times the gap, and the damping only acts while the tool moves.
The press is that law made of parts. The crosshead and its depth rod carry the target; the rod's tip, read on the column's ruler, is where the policy asked the tool to be. The tool hangs from the arm on a spring. In free space nothing stops the tool, so it rides on the target and the scale reads nothing. Once the target passes the pan, the pan stops the tool, the arm keeps going, the nut lifts off the arm, and the spring is squeezed by the gap. The dial reads the push: the spring's rate times the gap. The same target pushes four times as hard through the stiff spring as through the soft one.
Illustrative: the three springs push 1, 2 and 4 dial marks per ruler mark of gap, and no force in newtons is claimed. On a robot the spring is in the controller, and the policy can change it at every step.
Impedance law from Hogan (1985).
Chunks change the time axis
An action chunk predicts several steps per inference, which helped ACT and two retrofitted baselines (action chunking)Source 2; Diffusion Policy executes the first part of a predicted horizon, then replansSource 3. Open-loop chunks go stale when contact changes the scene, which receding horizons, temporal ensembling and real-time chunk replacement each addressSource 4 (real-time execution).
Rates differ by layer: GEN-1.5 produces 100 Hz action trajectoriesSource 28, and Helix 02's S0 sends joint-level actuator commands at 1 kHz beneath S1's 200 Hz joint targetsSource 29. Report predicted and executed horizons separately.
Tokens change the output geometry
RT-2Source 5 and OpenVLA map continuous actions to vocabulary tokens to reuse language-model training, OpenVLA binning seven dimensions into 256 valuesSource 6. Binning allows cross-entropy but limits resolution and adds autoregressive decoding to latency. FAST compresses a chunk's frequency coefficients with byte-pair encoding, far better than per-dimension binning, and its universal FAST+ tokenizer was trained on 1M real robot action trajectoriesSource 8. VQ-BeT's vector-quantized actions infer 5 times faster than Diffusion PolicySource 22, and LAP writes end-effector motions as short natural-language phrases, with LAP-3B averaging over 50% zero-shot success on three unseen robotsSource 30.
Continuous heads skip tokens: OpenVLA-OFT's continuous actions, parallel decoding and L1 objective lifted LIBERO success from 76.5% to 97.1%Source 23, and Figure says Helix outputs continuous control to avoid tokenizationSource 24. Naively adding a continuous expert to a VLM harms training speed and knowledge transfer, which knowledge insulation addressesSource 25.
Zeji Yi, Max Simchowitz, Guanya Shi and colleagues at Carnegie Mellon and Amazon FAR (October 2026) gave one PaliGemma VLA four action heads: continuous or binned into 512 values, each predicted in one pass or by iterative flow. On simulated RoboCasa, over five seeds of 500 episodes, binned flow reached 53.9% success, continuous flow 52.7% and one-pass continuous regression 38.8%. One-pass binned prediction reached 27.1%, which the authors trace to tokens chosen independently across time steps and action dimensions; guidance raised it to 49.2%Source 31.
A selection rule
Choose the lowest-level action the task requires and the platform supports safely. Across 13,000+ real rollouts and 500+ models, predicting delta actions consistently helped, with joint space favoring control stability and task space favoring generalizationSource 26. Hold controller, rate, horizon and observation history fixed when comparing architectures, or the comparison measures interface changes.
| Requirement | Practical starting point | Main burden below the policy |
|---|---|---|
| Single-arm imitation on fixed hardware | Joint positions or velocities | Tracking and joint limits |
| Transfer across different arms | Relative Cartesian deltas | IK, frames and singularities |
| Contact compliance | Cartesian impedance targets | Fast force or torque controller |
| Dynamic locomotion or dexterity | Torque or residual torque | Dynamics, rate and safety |
| Slow semantic manipulation | Chunked Cartesian actions | Replanning and stale chunks |
| Language-model output head | Tokenized chunks | Quantization and decode latency |
See also
- Knowledge Insulation
Discrete tokens train the backbone while the action expert trains behind a stop-gradient.
- Dexterity
Contact-rich manipulation, touch sensing, in-hand reorientation and deformables.
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
Linked from
- Behavior Cloning Foundations
Covariate shift makes naive imitation drift, and DAgger is the standard fix.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Comparison Matrix
Every major policy compared on eight architectural axes.
- Knowledge Insulation
Discrete tokens train the backbone while the action expert trains behind a stop-gradient.
- Robot Learning Curriculum for ML Engineers
A dependency-ordered route from supervised learning to real robot policies.
- The Robot Learning Stack
From data capture to robot integration as one reproducible system.
- Kinematics
How joint angles place a robot's hand, and the reverse.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
- Robot Calibration
The measurements that make sensor coordinates agree with motion.
References
Kevin M. Lynch, Frank C. Park, Cambridge University Press, 2017.
https://hades.mech.northwestern.edu/index.php/Modern_Robotics
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://arxiv.org/abs/2506.07339
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, and 48 more, 2023.
https://arxiv.org/abs/2307.15818
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
Oussama Khatib, IEEE J. Robotics and Automation, 1987.
https://doi.org/10.1109/JRA.1987.1087068
Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, and 3 more, 2025.
https://arxiv.org/abs/2501.09747
Franka Robotics, Franka Robotics, as of 2026-08-20.
https://frankarobotics.github.io/docs/
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
Yuke Zhu, Josiah Wong, Ajay Mandlekar, Roberto Martín-Martín, Abhishek Joshi, Kevin Lin, and 3 more, 2020.
https://arxiv.org/abs/2009.12293
Xue Bin Peng, Michiel van de Panne, arXiv preprint (SCA 2017), 2016.
https://arxiv.org/abs/1611.01055
Yi Zhou, Connelly Barnes, Jingwan Lu, Jimei Yang, Hao Li, 2018.
https://arxiv.org/abs/1812.07035
GEAR Team, Allison Azzolini, Johan Bjorck, Valts Blukis, Fernando Castañeda, Rahul Chand, and 53 more, 2025.
https://research.nvidia.com/labs/gear/gr00t-n1_6/
Ye Wang, Sipeng Zheng, Hao Luo, Wanpeng Zhang, Haoqi Yuan, Chaoyi Xu, and 6 more, 2026.
https://arxiv.org/abs/2602.09722
Sergey Levine, Chelsea Finn, Trevor Darrell, Pieter Abbeel, 2015.
https://arxiv.org/abs/1504.00702
Nikita Rudin, David Hoeller, Philipp Reist, Marco Hutter, CoRL 2021.
https://arxiv.org/abs/2109.11978
Neville Hogan, ASME J. Dynamic Systems, Measurement, and Control, 1985.
https://doi.org/10.1115/1.3140702
Patrick Varin, Lev Grossman, Scott Kuindersma, 2019.
https://arxiv.org/abs/1908.08659
Yifan Hou, Zeyi Liu, Cheng Chi, Eric Cousineau, Naveen Kuppuswamy, Siyuan Feng, and 2 more, arXiv preprint (ICRA 2025), 2024.
https://arxiv.org/abs/2410.09309
Seungjae Lee, Yibin Wang, Haritheja Etukuru, H. Jin Kim, Nur Muhammad Mahi Shafiullah, Lerrel Pinto, 2024.
https://arxiv.org/abs/2403.03181
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Figure AI, 2025.
https://www.figure.ai/news/helix
Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, and 5 more, 2025.
https://arxiv.org/abs/2505.23705
Yuchun Feng, Jinliang Zheng, Zhihao Wang, Dongxiu Liu, Jianxiong Li, Jiangmiao Pang, and 2 more, 2026.
https://arxiv.org/abs/2602.23408
Jinliang Zheng, Jianxiong Li, Zhihao Wang, Dongxiu Liu, Xirui Kang, Yuchun Feng, and 9 more, 2025.
https://arxiv.org/abs/2510.10274
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1.5
Lihan Zha, Asher J. Hancock, Mingtong Zhang, Tenny Yin, Yixuan Huang, Dhruv Shah, and 2 more, 2026.
https://arxiv.org/abs/2602.10556
Zeji Yi, Soham Dasgupta, Xinyang Zhang, Koushil Sreenath, Guannan Qu, Xi Chen, and 2 more, 2026.
https://arxiv.org/abs/2610.20429
Further reading
Roberto Martin-Martin, Michelle A. Lee, Rachel Gardner, Silvio Savarese, Jeannette Bohg, Animesh Garg, IEEE/RSJ Int. Conf. Intelligent Robots and Systems, 2019.
https://doi.org/10.1109/IROS40897.2019.8968201
Cheng Chi, Zhenjia Xu, Chuer Pan, Eric Cousineau, Benjamin Burchfiel, Siyuan Feng, and 2 more, 2024.
https://arxiv.org/abs/2402.10329
Hongyi Zhou, Weiran Liao, Xi Huang, Yucheng Tang, Fabian Otto, Xiaogang Jia, and 8 more, 2025.
https://arxiv.org/abs/2506.06072
Steven Oh, Jason Jingzhou Liu, Tony Tao, Philip Han, Kenneth Shaw, Satoshi Funabashi, and 2 more, 2026.
https://arxiv.org/abs/2606.12406
Dantong Niu, Zhuoyang Liu, Zekai Wang, Boning Shao, Zhao-Heng Yin, Anirudh Pai, and 28 more, 2026.
https://arxiv.org/abs/2606.17055
Zibin Dong, Yicheng Liu, Shiduo Zhang, Baijun Ye, Yifu Yuan, Fei Ni, and 5 more, 2026.
https://arxiv.org/abs/2602.15397
Spot a factual error or missing qualification? Report a content correction.