Comparison Matrix
Every major policy compared on eight architectural axes.
The comparison matrix is a table of major robot policies, from RT-1 (2022) to π0.7 (2026), compared on eight architectural axes: action representation, horizon, control frequency, backbone, conditioning, cross-embodiment, hierarchy and weightsSource 1 Source 11. Each cell records what its named source discloses.
Set the weights filter to Downloadable.
Policy comparison
Most 2026 robot brains don't disclose how they move
Adjust more
Weights
Action representation
| Backbone | Conditioning | Sources | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| RT-1 | 2022 | discrete tokens | 1 / 1 | 3 HzEveryday Robots commanded control; six input images are observation history, not action horizon | FiLM-EfficientNet + TokenLearner + 19M transformer; separate SayCan planner in the long-horizon kitchen runs | language, 6-frame image history | limited | external | not disclosedPretrained weights not disclosed in the checked RT-1 paper; its code-release statement is not a weight release | |
| ACT | 2023 | continuous | 100 / 1k=100 ablation reference; temporal ensembling queries the policy every timestep | 50 HzALOHA teleoperation/data-recording setting; task-specific models | ResNet-18 x4 + transformer encoder-decoder, ~80M | 4 RGB cameras, joint positions | not disclosed | none | not disclosedThe checked ACT paper announces software/hardware and per-task training, not downloadable pretrained checkpoints | |
| Diffusion Policy | 2023 | diffusion | 16 / 8CNN Push-T reference: observation horizon 2; not universal settings | 10 HzReal-world UR5 Push-T: 10 Hz predictions interpolated to 125 Hz commands; separate from the reference horizon | ResNet-18 + CNN U-Net or time-series diffusion transformer | 2 observation frames | not disclosed | none | not disclosedThe inspected paper announces code, data and training details; it does not establish downloadable pretrained checkpoints | |
| RT-2 | 2023 | discrete tokens | 1 / 1 | not disclosedMulti-TPU cloud serving: PaLI-X-55B 1-3 Hz; 5B model around 5 Hz. No universal scalar. | PaLI-X / PaLM-E, up to 55B | language, image | no | none | not disclosedModel-specific weight-release terms are not established by the checked RT-2 paper; not a closed-license claim | |
| Octo | 2024 | diffusion | 64 / 12ALOHA finetuning only; not a universal Octo horizon | not disclosedNo universal rate disclosed; separate setups: Franka prediction 15 Hz, coffee controller 10 Hz, ViperX control 5 Hz | Octo transformer checkpoints: 27M or 93M; pretrained t5-base (111M) language encoder | language or goal image | yes | none | downloadable | |
| OpenVLA | 2024 | discrete tokens | 1 / 1 | not disclosedApproximately 6 Hz inference on RTX 4090 in bfloat16 without speed-up tricks; Franka-Tabletop/DROID controllers are separately 5/15 Hz | Prismatic-7B (LLaMA-2 + DINOv2 + SigLIP) | language, single image | yes | none | downloadableThe paper explicitly releases model checkpoints and describes downloadable models; availability is not a blanket license classification | |
| π0 | 2024 | flow matching | 50 / 16UR5e/Franka reference; other robots execute 25 of 50 | 20 HzUR5e/Franka; other evaluated robots 50 Hz (paper: up to 50 Hz) | PaliGemma (Gemma 2B language model) + ~300M action expert; separate high-level VLM for several evaluated tasks | 2-3 RGB cameras, language, proprioception | yes | external | downloadableThe pinned openpi README lists pi0 base checkpoints; this is download availability, not license openness | |
| OpenVLA-OFT | 2025 | continuous; Parallel bidirectional decoding with an L1-trained four-layer MLP; OFT+ adds FiLM for the ALOHA experiments | 25 / 25OFT+ ALOHA reference: execute the full chunk before replanning. LIBERO separately predicts and executes 8; adaptation is task-specific, not one shared multi-robot checkpoint | 25 HzOFT+ ALOHA controller, reduced from the original 50 Hz. A100 action-generation throughput is separate: 77.9 actions/s with three images and robot state | Prismatic-derived OpenVLA: Llama-2 7B + DINOv2/SigLIP + four-layer L1 MLP | language, 3 ALOHA camera images, robot proprioceptive state | limited | none | downloadableThe OFT v2 paper announces code and pretrained checkpoints. Download availability is source-reported; checkpoint files and their license terms were not inspected. The paper license is not a weights license | |
| π0-FAST | 2025 | discrete tokens; Autoregressive FAST action tokens, decoded back into continuous action chunks | 15 / {8, 15}DROID setup in the FAST v1 paper: predicts 15, executes either 8 or 15; other tasks use one-second chunks at their own rates | 15 HzDROID setup; other evaluated tasks use 20 or 50 Hz. Not inference throughput: the paper reports approximately 750 ms per one-second chunk on NVIDIA 4090 | PaliGemma 3B + FAST DCT/BPE tokenizer | 2-3 RGB cameras, language, proprioception | yes | none | downloadablePinned openpi README lists pi0_fast_base and pi0_fast_droid downloads; availability is not a license classification | |
| π0.5 | 2025 | flow matching | 50 / n.d.50 predictions (inclusive H=49); executed count not disclosed in the v1 paper | 50 Hzv1 paper mobile-manipulation targets; not inference throughput | PaliGemma-initialized VLM co-trained with web data + 300M expert (v1 technical appendix labels the VLM 2B) | language, images, proprioceptive state, predicted subtask | yes | internal | downloadableopenpi snapshot lists the base π0.5 checkpoint; download availability does not establish license terms | |
| π0.6 | 2025 | flow matching; continuous actions; FAST backbone supervision during training | not disclosedPredicted and executed counts not disclosed in the November 17, 2025 model card | not disclosedRobot-control Hz not disclosed in the model card; 63 ms chunk inference uses five denoising steps, three cameras and one H100 | SigLIP 400M + Gemma3 4B + approximately 860M expert; no total stated in the card | language, up to 4 images, proprioceptive state, metadata | yes | internal | not disclosedModel-specific weight-release and licensing terms not disclosed in the checked pi0.6 model card | |
| Gemini Robotics 1.5 | 2025 | continuous; The v3 model card states continuous numerical robot actions and text when thinking is enabled; it does not identify a regression, diffusion, or flow-matching action head | not disclosedPredicted and executed action-chunk lengths are not disclosed in the inspected v3 report | not disclosedRobot-command frequency is not disclosed in the inspected v3 report. Its 5 Hz success-detection evaluation concerns GR-ER, not the VLA control loop | Gemini-derived VLA; separate GR-ER 1.5 orchestrator | language, images, natural-language thinking traces when enabled | yes | internal | not disclosedModel-specific weight-download and licensing terms are not disclosed in the inspected v3 technical report; this is not a closed-license finding | |
| π0.7 | 2026 | flow matching; continuous actions; FAST backbone supervision during training | 50 / {15, 25}Five denoising steps; executes either 15 or 25; paper does not map these choices to robots | 20 HzUR5e reference; other tested robots 50 Hz | Gemma3 4B + 860M expert, ~5B | language, subtask, metadata, control mode, up to 4 camera images, subgoal images, memory, proprioceptive state | yes | internal | not disclosedModel-specific weight-release and licensing terms not disclosed in the checked pi0.7 paper | |
| Gemini Robotics 2 | 2026 | not disclosed | not disclosedPredicted and executed chunk lengths are not disclosed in the inspected announcement | not disclosedRobot-command rate and parameter count are not disclosed in the inspected announcement; multi-minute ER tasks are not a control frequency | not disclosed | vision, language | yes | external | not disclosedAnnouncement scope: separate ER 2 coordinates the VLA. One checkpoint covers Apollo 2 with SharpaWave, Apollo 2 with Inspire, and Franka Duo with Robotiq. ER access is via AI Studio/private preview; VLA and On-Device access is for early-access partners. Weight downloads and licensing terms are not disclosed | |
| GR00T N1.7 | 2026 | flow matching | 40 / n.d.N1.7 README model horizon; executed count is rollout-dependent, not disclosed as one value | not disclosedNo universal robot-control Hz disclosed in the checked N1.7 README; inference throughput is not control frequency | Cosmos-Reason2-2B (Qwen3-VL), 3B total | language, images, state (dim 132) | yes | external | downloadableGA README lists downloadable weights; License section: code Apache 2.0, weights NVIDIA Open Model License | |
| Helix 02 | 2026 | not disclosed | not disclosedChunk length not disclosed in the January 27, 2026 announcement; not inapplicable | 200 HzFigure announcement: S1 full-body joint targets at 200 Hz; S0 actuator commands at 1 kHz | S2 semantic layer + S1 visuomotor transformer + S0 10M | head and palm cameras, fingertip tactile, full-body proprioception | not disclosed | internal | not disclosedWeight-release and licensing terms not disclosed in this announcement | |
| AgiBot GO-2 | 2026 | not disclosed | not disclosedPredicted and executed action-chunk lengths are not disclosed in the announcement text | not disclosedSystem 2 semantic planning is lower frequency; System 1 action following is higher frequency. Neither numerical inference rates nor a robot-control Hz value are disclosed | not disclosed | instructions, real-time observations | not disclosed | internal | not disclosedTrained GO-2 weight-release and licensing terms are not established by the inspected announcement; this is not a closed-license finding | |
| Skild | 2026 | not disclosed | not disclosedPredicted and executed chunk lengths are not disclosed in the inspected announcement | not disclosedControl frequency and parameter count are not disclosed in the inspected announcement | not disclosed | not disclosed | not disclosed | not disclosed | not disclosed2026 is the Series C announcement year, not an established model-release year. Architecture, runtime inputs, hierarchy, weight downloads and licensing terms are not disclosed in that source. Omni-bodied generalization is a company assertion, not a demonstrated transfer protocol |
Each dot is one robot brain, placed by year and by how it outputs motion.
Figures as each source reports them, often for one test setup.
- RT-12022
- Output
- word-like codes
- Plans ahead
- 1 move
- Speed
- 3 commands a second
- Download
- not disclosed
- ACT2023
- Output
- plain numbers
- Plans ahead
- 100 moves
- Speed
- 50 commands a second
- Download
- not disclosed
- Diffusion Policy2023
- Output
- refined from noise
- Plans ahead
- 16 moves
- Speed
- 10 commands a second
- Download
- not disclosed
- RT-22023
- Output
- word-like codes
- Plans ahead
- 1 move
- Speed
- not disclosed
- Download
- not disclosed
- Octo2024
- Output
- refined from noise
- Plans ahead
- 64 moves
- Speed
- not disclosed
- Download
- yes
- OpenVLA2024
- Output
- word-like codes
- Plans ahead
- 1 move
- Speed
- not disclosed
- Download
- yes
- π02024
- Output
- refined from noise
- Plans ahead
- 50 moves
- Speed
- 20 commands a second
- Download
- yes
- OpenVLA-OFT2025
- Output
- plain numbers
- Plans ahead
- 25 moves
- Speed
- 25 commands a second
- Download
- yes
- π0-FAST2025
- Output
- word-like codes
- Plans ahead
- 15 moves
- Speed
- 15 commands a second
- Download
- yes
- π0.52025
- Output
- refined from noise
- Plans ahead
- 50 moves
- Speed
- 50 commands a second
- Download
- yes
- π0.62025
- Output
- refined from noise
- Plans ahead
- not disclosed
- Speed
- not disclosed
- Download
- not disclosed
- Gemini Robotics 1.52025
- Output
- plain numbers
- Plans ahead
- not disclosed
- Speed
- not disclosed
- Download
- not disclosed
- π0.72026
- Output
- refined from noise
- Plans ahead
- 50 moves
- Speed
- 20 commands a second
- Download
- not disclosed
- Gemini Robotics 22026
- Output
- not disclosed
- Plans ahead
- not disclosed
- Speed
- not disclosed
- Download
- not disclosed
- GR00T N1.72026
- Output
- refined from noise
- Plans ahead
- 40 moves
- Speed
- not disclosed
- Download
- yes
- Helix 022026
- Output
- not disclosed
- Plans ahead
- not disclosed
- Speed
- 200 commands a second
- Download
- not disclosed
- AgiBot GO-22026
- Output
- not disclosed
- Plans ahead
- not disclosed
- Speed
- not disclosed
- Download
- not disclosed
- Skild2026
- Output
- not disclosed
- Plans ahead
- not disclosed
- Speed
- not disclosed
- Download
- not disclosed
18 of 18 methods
How this was made
Compiled from the primary sources linked in each row of the full matrix under “Adjust more”. The cards and dots group the action representations into plain words: discrete tokens are “word-like codes”, continuous outputs are “plain numbers”, and diffusion and flow matching, which both refine random noise into a move, are “refined from noise”.
“Plans ahead” is the planned action horizon and “speed” the reported control frequency, each for the setting the source names; the matrix keeps the executed steps and the setting notes. “Download” describes download availability, not licence openness. Cells the vendor has not published read not disclosed and sort last in both directions.
Compiled from the primary sources linked in each row's Sources column.
Use the matrix as a constraint solver
Remove models whose weights or training data the project cannot use (Gemini Robotics On-Device, for example, is reached through a trusted-tester SDKSource 19), then models whose action representation, latency, observations or adaptation-data needs do not fit the robot, and only then compare benchmark performance.
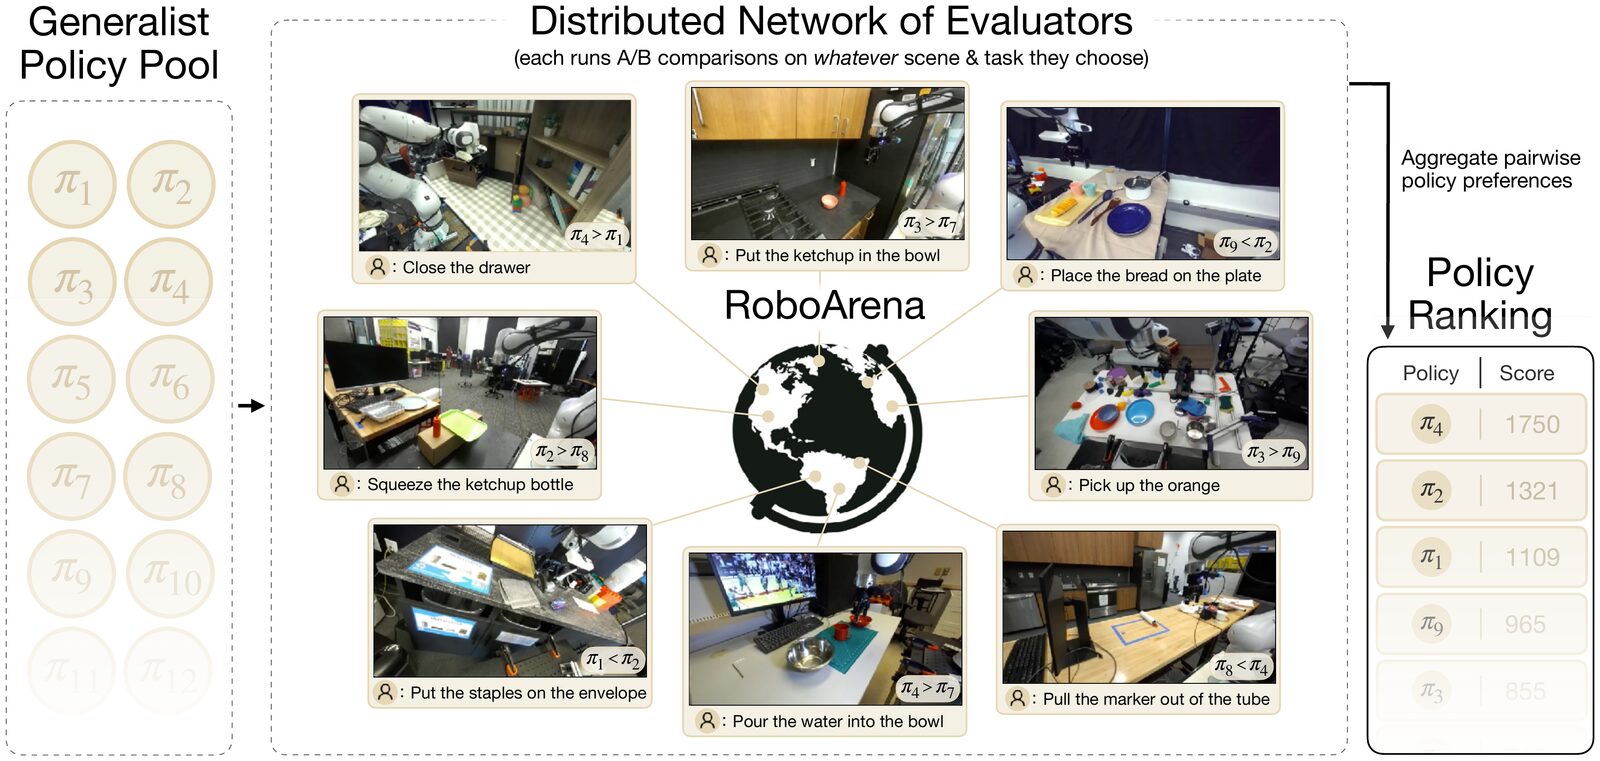
Compare the survivors under one trial protocol with the same cameras, action horizon and resets, and keep a behavior-cloning or action-chunking baseline. TRI's Large Behavior Model study used blind, randomized trialsSource 20, and RoboArena ranked seven generalist policies more accurately than centralized evaluation through over 600 double-blind pairwise real-robot episodesSource 21. The foundation-model guide explains what prior each family contributes, the action-space guide whether its output fits, and the evaluation crisis why protocols resist a shared leaderboard.
The eight axes
Action representation is the output mechanism: continuous regression, discrete action tokens, or a generative head such as diffusion or flow matching. Supervision and runtime generation can differ: π0.5 trains with FAST tokens but generates continuous actions with flow matchingSource 8.
Horizon separates the planned chunk length , the predicted horizon, from the steps executed before re-planning, the committed horizon. Diffusion Policy's simulated CNN Push-T reference uses observation, prediction and execution horizons of 2, 16 and 8Source 3; ACT's 100-step entry is its k=100 chunk-ablation referenceSource 2; OFT+ predicts and executes 25 actions at 25 Hz on ALOHASource 6; and π0.7 predicts 50 with five denoising steps and executes 15 or 25Source 11. Real-time chunking generates the next chunk while the current one executesSource 18.
Control frequency needs a named measurement setting. ACT's ALOHA setup runs at 50 Hz with temporal ensemblingSource 2, RT-1 commands the Everyday Robots platform at 3 HzSource 1, and RT-2's multi-TPU cloud service runs PaLI-X-55B at 1 to 3 HzSource 4. OpenVLA reaches about 6 Hz on one RTX 4090, and its Franka fine-tuning setups use 5 Hz and 15 Hz controllersSource 5.
Gemini Robotics turns about 250 ms of end-to-end latency into a 50 Hz effective control frequency with multi-action chunksSource 22, GR00T N1 samples a 16-action chunk in 63.9 ms on an L40Source 23, the π0.6 card reports 63 ms per chunk on one H100Source 10, and Generalist says GEN-1.5 produces 100 Hz action trajectoriesSource 24.
Action chunks
Each answer carries enough actions to last until the next
16 actions
The deck on its way is the next answer; the lit deck is being played16 per chunk · the arm never waits
250 ms and 50 Hz from Gemini Robotics; chunk sizes illustrative; slowed twenty times
How this was made
Gemini Robotics runs about 250 ms from camera to action, yet reaches a 50 Hz effective control frequency because each answer is a chunk of several actions. At 50 Hz the controller needs an action every 20 ms, so one 250 ms wait spans 12.5 ticks: a chunk of 13 or more lasts until the next answer lands.
The feeder is that arithmetic made of parts. Each answer is a deck of cards, one card per action, and the deck on its way slides down the channel for the whole 250 ms. When it lands it shoves out what is left of the deck before, because the fresher plan wins. The Geneva wheel indexes once every 20 ms; the belt moves one slot, and the bottom card of the deck slides onto it. A deck that runs out early leaves slots empty, and each empty slot is a tick the arm waits. The line on the ruler beside the deck marks 12.5 cards.
Assumed: one request at a time, the next sent when an answer lands. Gemini Robotics does not publish its chunk length, so the deck size is the reader's; 16 is the chunk GR00T N1 samples. Robot time is slowed twenty times.
Latency and control rate from the Gemini Robotics report (2025).
Backbone, conditioning and cross-embodiment describe model components, inputs and the scope of robot-body transfer. Mixed-embodiment training, one checkpoint on several bodies and fine-tuning on a new body are different evidence; CrossFormer shows the strongest kind, with the same weights controlling very different robots after training on 900K trajectories from 20 embodimentsSource 25. Skild says S1 executes a task shown in one videoSource 26, which adds demonstration video as a conditioning input.
Hierarchy distinguishes an internal high-level stage from a separately paired system. π0.5 predicts a semantic subtask before low-level actionsSource 8, while in the N1.7 SONIC workflow a separate whole-body controller decodes the VLA's latent action tokens into joint commandsSource 14. A separate high-level VLM gives π0 subtasksSource 7.
Weights records download availability, separately from license. openpi lists π0, π0-FAST and π0.5 checkpointsSource 9; the N1.7 README separates Apache 2.0 code from weights under the NVIDIA Open Model LicenseSource 14; and SmolVLA releases code, pretrained models and training dataSource 27.
Row notes
RT-1's "limited" cross-embodiment label means Kuka IIWA data mixed with Everyday Robots data and evaluated on Everyday RobotsSource 1. ACT trains a roughly 80M-parameter model from scratch for each taskSource 2, and RT-2's action-only entry excludes its chain-of-thought variantSource 4.
OpenVLA's 7B label names the language model, beside a 600M visual encoderSource 5. OFT's "limited" label means adapting the pretrained model to separate tasks and robot setupsSource 6, and GR00T N1.6 predicts state-relative action chunks for most embodimentsSource 28. π*0.6 adds Recap post-training, which more than doubles throughput on some of the hardest tasksSource 29.
Gemini Robotics 1.5's model card discloses continuous numerical action outputs but no action-head family, chunk length, command rate or parameter count; one checkpoint runs across ALOHA, bi-arm Franka and Apollo, and a separate GR-ER 1.5 orchestrator can pair with itSource 12. DeepMind's July 30, 2026 Gemini Robotics 2 announcement covers Apollo 2 and Franka Duo with one checkpoint but gives no backbone, output parameterization, chunk length, control frequency or parameter countSource 13. Skild's row rests on its January 14, 2026 Series C announcement, with no reproducible cross-embodiment evaluation or runtime detailsSource 17.
What the matrix can establish
ACT fixes its CVAE latent to the prior mean, zero, to decode deterministicallySource 2, while π0 generates continuous action chunks with a flow-matching action expertSource 7. Generalist says GEN-1's base model trains on wearable human data without robot data and reaches 99% average success where earlier models reached 64%, with 1 hour of robot data per taskSource 30. On March 16, 2026, NVIDIA previewed GR00T N2, based on DreamZero researchSource 31.
Helix 02 and GO-2 disclosure limits
Figure's Helix 02 announcement gives S1 joint targets at 200 Hz and S0 actuator commands at 1 kHz, but no output-head training loss, chunk horizon or weight-release termsSource 15. The first Helix post disclosed a 7 to 9 Hz onboard VLM and an 80M-parameter S1 at 200 Hz, trained end-to-end with a standard regression lossSource 32, and Figure reports that Index human-video pretraining raised Helix 2.5's zero-shot success in 30 unseen homes from 9% to 56%Source 33. AgiBot describes lower-frequency System 2 planning and higher-frequency System 1 action following, with no numerical rate, backbone, output encoding, chunk length or weight termsSource 16; its predecessor GO-1 uses latent action representations trained on AgiBot World's more than 1 million trajectories across 217 tasksSource 34.
See also
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
- Action Spaces for Robot Learning
What each action representation gives the learner and asks of the controller.
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
Linked from
- Knowledge Insulation
Discrete tokens train the backbone while the action expert trains behind a stop-gradient.
References
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Joseph Dabis, Chelsea Finn, and 45 more, 2022.
https://arxiv.org/html/2212.06817v2
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, and 48 more, 2023.
https://arxiv.org/abs/2307.15818
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Physical Intelligence, 2026.
https://github.com/Physical-Intelligence/openpi/blob/215abfb217dbac7d5f1273282331b9b1866c0479/README.md
Physical Intelligence, 2025.
https://website.pi-asset.com/pi06star/PI06_model_card.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Gemini Robotics Team, Abbas Abdolmaleki, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, and 167 more, 2025.
https://arxiv.org/abs/2510.03342
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
AgiBot, 2026.
https://www.agibot.com/article/231/detail/56.html
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://arxiv.org/abs/2506.07339
Carolina Parada, Google DeepMind blog, 2025.
https://deepmind.google/blog/gemini-robotics-on-device-brings-ai-to-local-robotic-devices/
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Pranav Atreya, Karl Pertsch, Tony Lee, Moo Jin Kim, Arhan Jain, Artur Kuramshin, and 26 more, 2025.
https://arxiv.org/abs/2506.18123
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1.5
Ria Doshi, Homer Walke, Oier Mees, Sudeep Dasari, Sergey Levine, 2024.
https://arxiv.org/abs/2408.11812
Skild AI Team, Skild AI blog, 2026.
https://www.skild.ai/blogs/s1
Mustafa Shukor, Dana Aubakirova, Francesco Capuano, Pepijn Kooijmans, Steven Palma, Adil Zouitine, and 8 more, 2025.
https://arxiv.org/abs/2506.01844
GEAR Team, Allison Azzolini, Johan Bjorck, Valts Blukis, Fernando Castañeda, Rahul Chand, and 53 more, 2025.
https://research.nvidia.com/labs/gear/gr00t-n1_6/
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/download/pistar06.pdf
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
NVIDIA, NVIDIA Newsroom, 2026.
https://nvidianews.nvidia.com/news/nvidia-and-global-robotics-leaders-take-physical-ai-to-the-real-world
Figure AI, 2025.
https://www.figure.ai/news/helix
Figure AI, Figure news, 2026.
https://www.figure.ai/news/helix-2-5-zero-shot-30-home-generalization
AgiBot-World-Contributors, Qingwen Bu, Jisong Cai, Li Chen, Xiuqi Cui, Yan Ding, and 46 more, 2025.
https://arxiv.org/abs/2503.06669
Further reading
Octo Model Team, Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, and 14 more, 2024.
https://arxiv.org/html/2405.12213v2
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, and 3 more, 2025.
https://arxiv.org/abs/2501.09747
Spot a factual error or missing qualification? Report a content correction.