Foundation Models for Robotics
What foundation means in robotics, and what adaptation still costs.
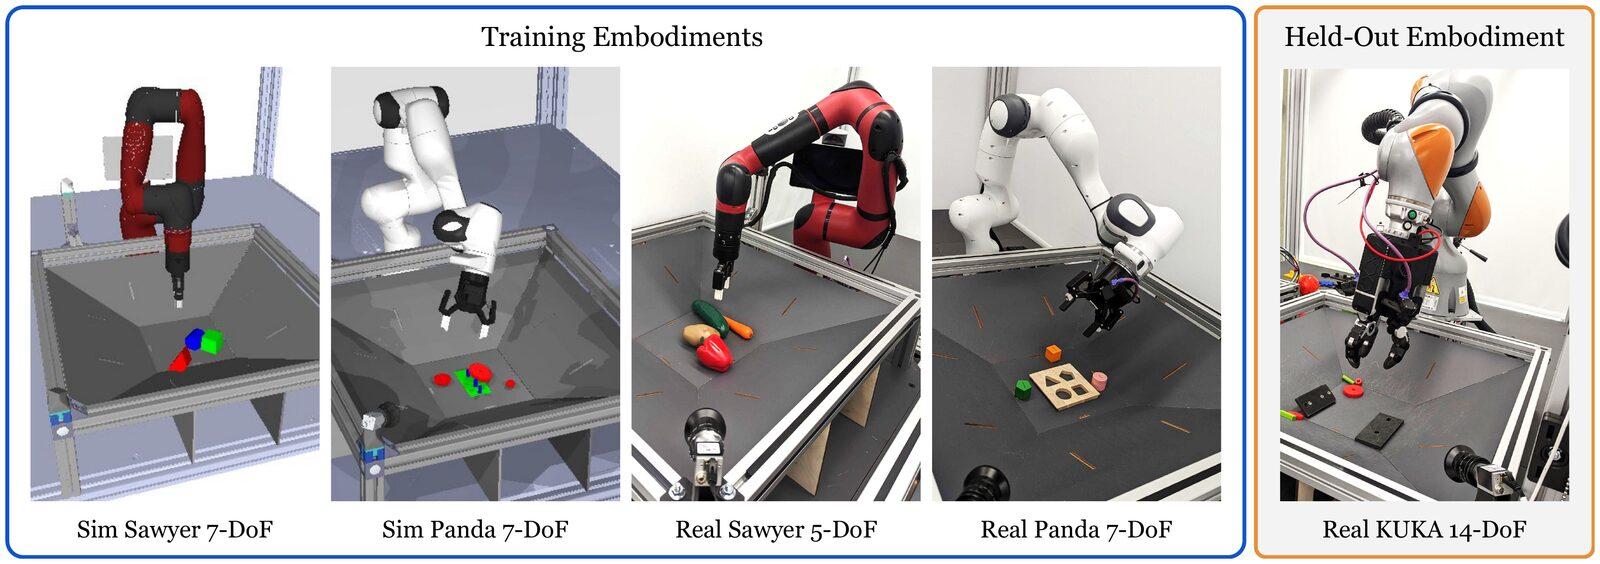
A foundation model is a network trained on broad data at scale and adaptable to many downstream tasksSource 10. In robotics three families carry the label (vision-language-action models, predictive world models and multimodal backbones adapted into either), and the test is whether one checkpoint transfers to new tasks, environments or embodiments after bounded adaptation.
Try the check below.
Self-check
Read the reasoning
- The checkpoint has a large parameter countScale may increase capacity, but it says nothing by itself about reuse or adaptation. A seven-billion-parameter specialist remains a specialist.
- The model performs well on many training task labelsTraining breadth is relevant, but success on the training distribution does not demonstrate transfer. The claim needs a downstream setting that was not simply another row in the training set.
- One checkpoint adapts with limited data to new tasks and embodimentsThis is the operational evidence. A shared pretrained representation is useful if it reduces the data or optimization needed across genuinely different downstream settings.
Judge foundation models by the breadth and cost of downstream reuse; parameter count and branding are weak selectors.
What must be specified
A claim names its pretraining data, objective, interface and adaptation budget. Data spans web text and images, human video, robot trajectories and simulation; Open X-Embodiment pools 22 robots from 21 institutionsSource 11. Objectives include next-token prediction, contrastive learning, video prediction and action denoising.
Budgets run from zero-shot prompting through parameter-efficient and full fine-tuning to new robot data at scale. RoboCat adapts to new tasks and robots from 100 to 1,000 examplesSource 12, Octo fine-tunes to new sensors and action spaces in hours on consumer GPUsSource 13, and π*0.6's RL from experience more than doubles throughput on some of the hardest tasksSource 14. The newest rung is in-context learning: Generalist reports GEN-1.5 learning a task from one 3 to 12 second demonstration with no trainingSource 15.
Robota-Embed, from Yunze Liu, Linxi Fan, Han Cai and colleagues at NVIDIA, MIT, UC Berkeley, Oxford and CMU (October 2026), encodes vision, language and action in one vector, so a robot can retrieve recorded experience as context. Seeding a frozen DreamZero policy with a retrieved video, chosen by a reranking agent, raised its average success on three simulated DROID-Sim tasks from 47.0% to 56.3% over 100 trials per task, while random reference videos lowered it to 36.0%. Without the reranker, its top-1 retrievals reached 50.3% against 43.3% for Omni-Embed-Nemotron-3BSource 32.
VLA foundations
RT-1 argued for task-agnostic training of high-capacity models on diverse robot dataSource 16. RT-2 co-fine-tunes a vision-language model on robot trajectories and internet-scale vision-language tasks, writing actions as reserved tokensSource 1, and OpenVLA made a comparable recipe public on Open X-EmbodimentSource 2. VLAs still struggle with novel robot setups until fine-tuned: OpenVLA-OFT's recipe lifted OpenVLA's average success across four task suites from 76.5% to 97.1%Source 17.
π0 pairs a pretrained VLM with a separate flow-matching expert for continuous action chunksSource 3. π0.5 credits its generalization to co-training on heterogeneous tasksSource 18, and π0.7's authors call their 2026 model a steerable generalist robotic foundation modelSource 4.
Test-time training stores past observations in fast weights that gradient descent updates while the policy runs. RoboTTT (July 2026) extends visuomotor context to 8K timesteps without growing inference latency and averaged a 79% task completion score on long-horizon real-robot tasks, against 42% for the single-step-context GR00T N1.7 baselineSource 9. ECoMEM (Stanford, September 2026) keeps an explicit record of task facts that a learned reader turns into memory tokens for the VLA, reaching 86.1% success on two new real-robot tasks against 8.6% without memorySource 28.
IMPRINT, from Yilin Wu, Homanga Bharadhwaj, Guanya Shi and colleagues at Amazon FAR and Carnegie Mellon (October 2026), trains a latent memory of past camera frames, actions and joint states with the policy, so no rule has to pick which frames to keep. On the nine memory-dependent RMBench simulation tasks, with 100 trials per task, it raised π0.5 from 25.4% to 72.8% average success; EventVLA, the strongest of six memory baselines, reports 67.8%. The recurrent version took 122.8 ms per 50-step action chunk on an L40S GPU, against 91.0 ms for π0.5 without memory and 960 ms for EventVLASource 33.
Humanoid foundations
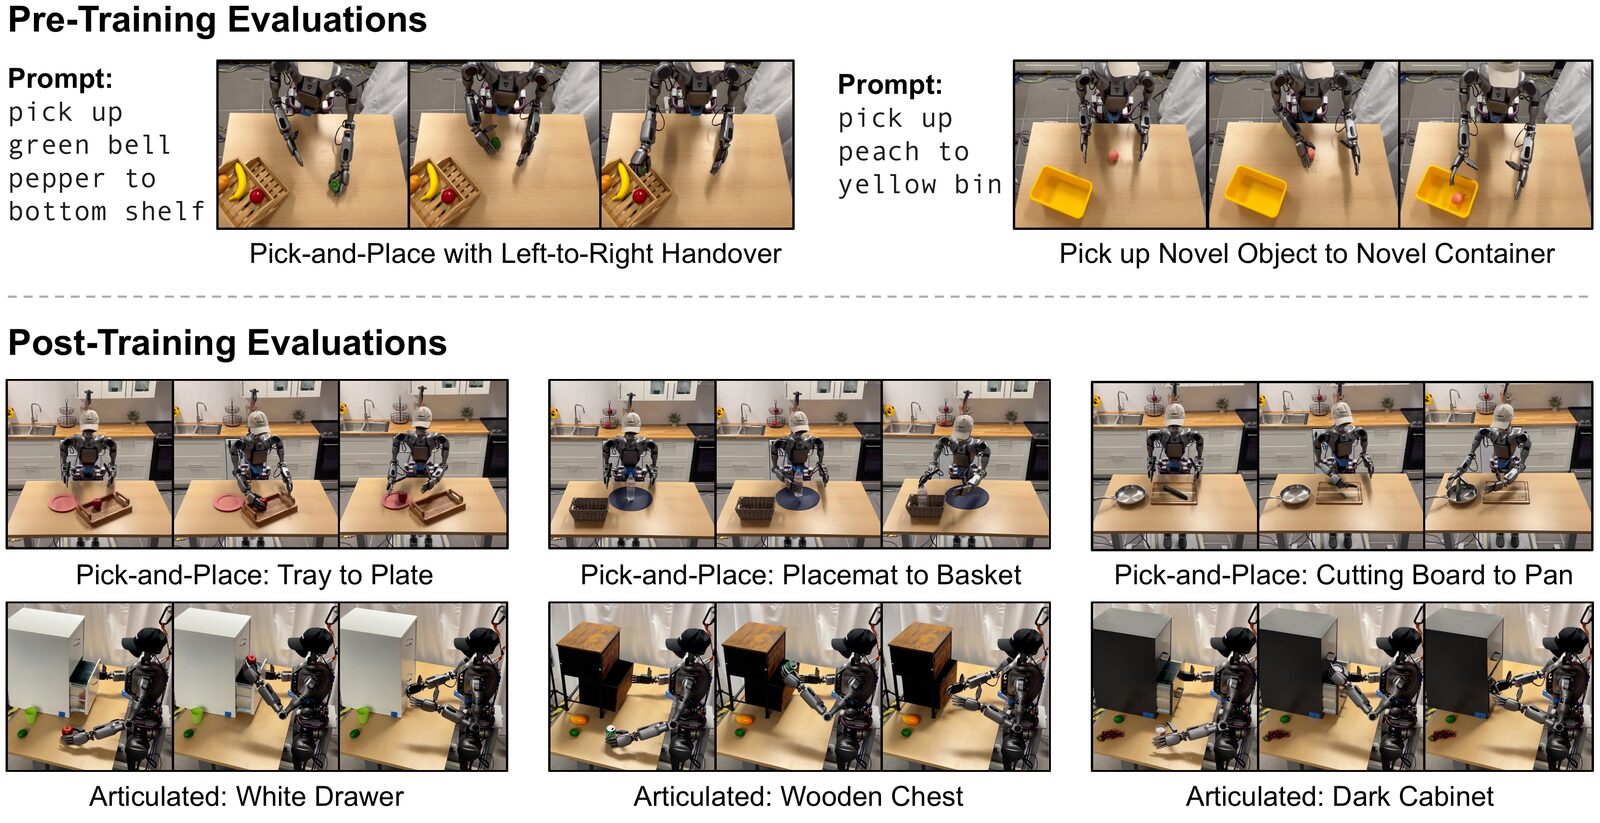
GR00T N1 combines a vision-language module with a diffusion transformer, trained on real-robot trajectories, human videos and synthetic datasetsSource 5. For a humanoid, morphology, whole-body balance and shared action coordinates set the reuse boundary. Figure pretrained Helix 2.5 from random initialization entirely on Index, its dataset of human behavior; with identical task data, it succeeded on 56% of zero-shot trials in 30 unseen homes, against 9% for a policy trained from scratchSource 29.
Predictive foundations
V-JEPA 2 learns representations from over 1M hours of internet video, then trains an action-conditioned stage on fewer than 62 hours of unlabeled DROID videoSource 6. R3M's embedding, pretrained on Ego4D human video, beats from-scratch training by over 20%Source 19.
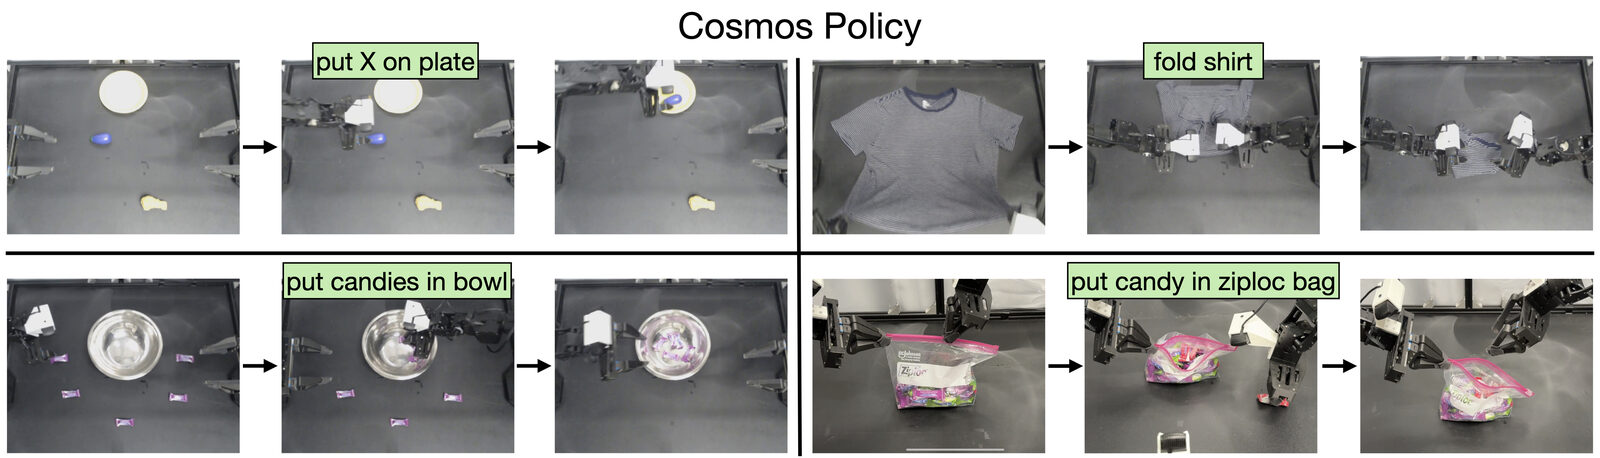
Cosmos frames a world foundation model as a general-purpose model fine-tuned into custom onesSource 20. Cosmos 3 unifies understanding, generation, forward and inverse dynamics and policy outputs in one omnimodal modelSource 7, and Cosmos Policy turns Cosmos-Predict2 into a policy in one post-training stage, reaching 98.5% on LIBEROSource 21. Each output needs its own test: Ctrl-World ranks policies without real rolloutsSource 22.
DreamZero (February 2026) is a world action model on a pretrained video diffusion backbone that predicts video and actions together; in real-robot tests it more than doubled average task progress on new tasks and environments over state-of-the-art VLAs, and its 14-billion-parameter model ran closed-loop at 7 HzSource 8.
What pretraining does not erase
In TRI's blind, randomized trials, multitask pretraining matched from-scratch policies with 3 to 5 times less dataSource 23. VC-1 found no pretrained visual representation universally dominantSource 24, and Toyota Research Institute's 89-policy study found that robot-only training degrades the backbone's visiolinguistic understandingSource 31. Generalist reports that GEN-1's base model, pretrained on over half a million hours of wearable human data and no robot data, averaged 99% on three tasks with about one hour of robot data per task, against 19% from scratchSource 30.
Pretraining leaves calibration and control integration, closed-loop evaluation under perturbation, latency limits and safety cases to the builder. RoboPAIR jailbroke LLM-controlled robots, including a deployed Unitree Go2, often at 100% attack successSource 25, and a downloadable checkpoint can hide its training mixture, adaptation data or benchmark protocol.
A comparison framework
| Family | Pretrained capability | Typical downstream output | Strongest transfer claim | Main unresolved cost |
|---|---|---|---|---|
| VLA | Vision-language semantics | Action tokens or continuous chunks | New tasks, objects and instructions | Robot data and control integration |
| Generalist humanoid | Multimodal behavior across a morphology family | Embodiment-specific action targets or chunks | Tasks and related humanoid embodiments | Balance, contact and hardware variation |
| Latent or JEPA world model | Predictive state representation | Latent future, value or plan | New tasks with shared dynamics structure | Planning objective and action grounding |
| Generative world model | Visual and temporal generation | Future video or synthetic experience | Data generation and policy evaluation | Physical fidelity and inference cost |
Evaluating a foundation claim
Look for a matrix: rows vary tasks and environments, columns vary embodiment, adaptation data and evaluation shift. Report the checkpoint, every tuned component, the new robot data and a same-budget from-scratch baseline. VLAs near 95% on LIBERO drop below 30% under modest camera or initial-state perturbationsSource 26, and models above 90% fall to 0.0% under LIBERO-PRO's generalized settingSource 27.
See also
- What Is a World Model?
Six example groups compared, from DreamerV3 to V-JEPA 2.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
Linked from
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Comparison Matrix
Every major policy compared on eight architectural axes.
- Knowledge Insulation
Discrete tokens train the backbone while the action expert trains behind a stop-gradient.
- Robot Learning Curriculum for ML Engineers
A dependency-ordered route from supervised learning to real robot policies.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
References
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, and 48 more, 2023.
https://arxiv.org/abs/2307.15818
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Mahmoud Assran, Adrien Bardes, David Fan, Quentin Garrido, Russell Howes, Mojtaba Komeili, and 23 more, 2025.
https://arxiv.org/abs/2506.09985
NVIDIA, Aditi, Niket Agarwal, Arslan Ali, Jon Allen, Martin Antolini, and 289 more, 2026.
https://research.nvidia.com/labs/cosmos-lab/cosmos3/technical-report.pdf
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
Yunfan Jiang, Yevgen Chebotar, Ruijie Zheng, Fengyuan Hu, Yunhao Ge, Jimmy Wu, and 5 more, 2026.
https://arxiv.org/abs/2607.15275
Rishi Bommasani, Drew A. Hudson, Ehsan Adeli, Russ Altman, Simran Arora, Sydney von Arx, and 108 more, 2021.
https://arxiv.org/abs/2108.07258
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Konstantinos Bousmalis, Giulia Vezzani, Dushyant Rao, Coline Devin, Alex X. Lee, Maria Bauza, and 33 more, TMLR, 2023.
https://arxiv.org/abs/2306.11706
Octo Model Team, Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, and 14 more, 2024.
https://arxiv.org/html/2405.12213v2
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/download/pistar06.pdf
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1.5
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Joseph Dabis, Chelsea Finn, and 45 more, 2022.
https://arxiv.org/html/2212.06817v2
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Suraj Nair, Aravind Rajeswaran, Vikash Kumar, Chelsea Finn, Abhinav Gupta, CoRL 2022.
https://arxiv.org/abs/2203.12601
Moo Jin Kim, Yihuai Gao, Tsung-Yi Lin, Yen-Chen Lin, Yunhao Ge, Grace Lam, and 5 more, 2026.
https://arxiv.org/abs/2601.16163
Yanjiang Guo, Lucy Xiaoyang Shi, Jianyu Chen, Chelsea Finn, 2025.
https://arxiv.org/abs/2510.10125
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Arjun Majumdar, Karmesh Yadav, Sergio Arnaud, Yecheng Jason Ma, Claire Chen, Sneha Silwal, and 9 more, 2023.
https://arxiv.org/abs/2303.18240
Alexander Robey, Zachary Ravichandran, Vijay Kumar, Hamed Hassani, George J. Pappas, 2024.
https://arxiv.org/abs/2410.13691
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Xueyang Zhou, Yangming Xu, Guiyao Tie, Yongchao Chen, Guowen Zhang, Duanfeng Chu, and 2 more, 2025.
https://arxiv.org/abs/2510.03827
Yize Liu, Ke Wang, Mac Schwager, Yiqing Xu, Jiajun Wu, 2026.
https://arxiv.org/abs/2610.00801
Figure AI, Figure news, 2026.
https://www.figure.ai/news/helix-2-5-zero-shot-30-home-generalization
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
Fanqi Lin, Kushal Arora, Jean Mercat, Haruki Nishimura, Paarth Shah, Chen Xu, and 6 more, 2026.
https://arxiv.org/abs/2602.01067
Yunze Liu, Jing Wang, Shenrui Wu, Wenkun He, Guanqi Zhan, Xianzheng Ma, and 13 more, 2026.
https://arxiv.org/abs/2610.19495
Yilin Wu, Rutav Shah, Shuaiyi Huang, Sumedh A. Sontakke, Andrea Bajcsy, Max Simchowitz, and 2 more, 2026.
https://arxiv.org/abs/2610.14406
Further reading
Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, and 5 more, 2025.
https://arxiv.org/abs/2505.23705
Yize Liu, Huang Huang, Yining Hong, Zijian Du, Zhi Cao, Li Fei-Fei, and 1 more, 2026.
https://arxiv.org/abs/2609.36720
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Skild AI Team, Skild AI blog, 2026.
https://www.skild.ai/blogs/s1
Danijar Hafner, Wilson Yan, Timothy Lillicrap, 2025.
https://arxiv.org/abs/2509.24527
NVIDIA, NVIDIA Newsroom, 2026.
https://nvidianews.nvidia.com/news/nvidia-and-global-robotics-leaders-take-physical-ai-to-the-real-world
Spot a factual error or missing qualification? Report a content correction.