Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
Generalization is a robot policy's ability to work in settings it was not trained in, closing the distribution shift of new geometry, objects and clutter without per-site data. Even the most general policies are "mostly trained on data collected in a small number of environments"Source 12, and in a new home a one-centimeter grasp error drops the object.
EgoScale's scaling law is the strongest argument that the gap closes with dataSource 4. Try a larger amount under "How much video?" and the dashed line continues past the measurements.
Guess first
The chart is set to 250k hours, the largest preset: a straight line would score 1.00 there, which is impossible. Pick a smaller amount and the line stays under the top.
EgoScale scaling law
Robots improve with more video; beyond 20,000 hours is guesswork
How much video?
Adjust more
At 250k hours a straight line would pass 100% (a score of 1.00), which is impossible.
How this was made
EgoScale (Zheng et al. 2026) pretrained one robot model on 1k, 2k, 4k, 10k and 20k hours of first-person (egocentric) human video, then post-trained each on robot tasks with a 22-DoF dexterous hand. Average task completion rose from 0.30 at 1k hours to 0.71 at 20k; the dots are those five reported scores. The paper states that it does not extrapolate beyond the measured range.
The line is a least-squares log-linear fit through the five scores, an editorial completion fit (Robot Wiki, R² = 0.96), not the paper’s law. It reads 0.89 at 100k hours, crosses the 0.90 solved bar near 111k hours and passes 100% near 250k hours, which is impossible. The hours axis is logarithmic. The solved bar is this article’s criterion: one policy above 90% success across many unseen homes with no per-site data.
The paper’s published law is about validation loss (MSE on held-out human video): L = 0.024 − 0.003 ln D, D in thousands of hours, R² = 0.9983, over the five scales. “Show the paper’s error measure” in “Adjust more” draws it above the completion panel. Past 20k hours both panels then show a scenario band, a scenario bracket between the law holding and a plateau at the last measured value, not a confidence interval.
At the current setting (250k h): loss 0.0074 holds / 0.0150 plateau; completion fit 1.00 holds / 0.71 plateau, past 100%, which is impossible; the curve must bend before then.
EgoScale (2026) fits the law to held-out human-video validation loss, a proxy that correlates with downstream robot performance without establishing real-world success rate across unseen environments.
The generalization prediction-step law panel is seeded past the 100 percent crossing: validation loss still falls from 0.0240 at 1k hours to 0.0150 at 20k hours, but the completion fit is already flagged as impossible at the 250k h horizon rather than drawn through 100 percent.
Sampled loss and completion by pretraining hours
| pretraining hours | loss (MSE) | reported completion | completion fit | region |
|---|---|---|---|---|
| 1k h | 0.0240 | 0.30 | 0.32 | measured |
| 4k h | 0.0198 | 0.48 | 0.49 | measured |
| 10k h | 0.0171 | 0.57 | 0.60 | measured |
| 20k h | 0.0150 | 0.71 | 0.69 | measured range ends |
| 100k h | 0.0102 holds / 0.0150 plateau | n/a | 0.89 holds / 0.71 plateau | extrapolated, dashed |
| 1M h | 0.0033 holds / 0.0150 plateau | n/a | 1.17 holds / 0.71 plateau | extrapolated, dashed, fit past 100 percent, impossible |
Measured points: EgoScale (Zheng et al. 2026), Figure 5.
Read the reasoning
- Around 100,000 hours, the first slider stop past the measured range where the line typically bendsAt 100k hours the fit still reads 0.89, high but not impossible. The line-crossing reading is exactly what the dashed styling is there to slow down: everything right of 20k is inference, and the paper’s authors say so explicitly.
- Near 250,000 hours, roughly twelve times past the end of the measured rangePush the fit out and it crosses 100% near 250k hours, which is impossible: success cannot exceed certainty, so the curve must bend somewhere before then. The chart flags the crossing instead of drawing through it, because the paper measures nothing past 20k hours.Zheng et al. 2026
- Only near 1,000,000 hours, the slider’s ceiling, since log-linear laws usually hold to the edge of their rangeHeld-to-the-ceiling is the happy extrapolation the band exists to bracket. The fit passes 100% a full decade before 1M hours, and the impossible flag at the top of the slider is the chart telling you the straight line ran out of physics long before the slider did.
A straight line in log data crosses 100% near 250k hours, which success cannot do: the crossing is the chart telling you the law must bend before the extrapolation does.
20,854
human video
hours, EgoScale pretraining
R²=0.9983
scaling law
log-linear, validation loss
0.71
best measured
task completion at 20k hours
>90%
solved bar
on N unseen homes; unmet
π0.5 cleaned three unseen homes, trained mostly on other data
Physical Intelligence's π0.5 (April 2025) is one end-to-end vision-language-action model, tested cleaning kitchens and bedrooms in homes absent from its training dataSource 1.
Only about 400 hours of the mixture is mobile-manipulator data from real homes; 97.6% of the training examples in the first training phase come from somewhere else, including other robots, laboratory tasks and web data. Removing the other robots' data degrades performance sharply, while removing web data mainly hurts unseen objects. A model trained on data from the test homes scored about the same as the 104-location model that never saw themSource 1.
Web-scale vision-language pretraining supplies semantic generalization, knowing what "the spatula" is in a new kitchen, as RT-2 showed for novel objectsSource 13. Motor generalization, grasping that spatula with this gripper, needs more, and the semantic half survives only if action training preserves it. Naively adding an action expert "significantly harms both training speed and knowledge transfer"Source 14. Action finetuning "can erode the original VLM's generalist reasoning abilities"Source 15, and open VLAs "often struggle with semantic generalization"Source 16.
π0.7 recombines trained skills and transfers them to new robots
π0.7 (April 2026; see The Pi Line) adds compositional generalization, recombining trained skills into untrained tasks. Asked to load a sweet potato into an air fryer without robot demonstrations, the model "makes a reasonable attempt, performing part of the task after a few false starts, but not finishing it fully"Source 3. With step-by-step language coaching the robot completes it, and the coaching transcripts train a high-level policy that runs the task with no additional teleoperationSource 2. Generalist reports a competing route: GEN-1.5 learns a new task in context from 3 to 12 seconds of one demonstration, with no trainingSource 17.
Physical Intelligence also reports cross-embodiment transfer: π0.7 folds laundry on a bimanual UR5e that never had laundry data at 85.6% task progress and 80% success. Expert teleoperators averaging 375 hours reached 90.9% and 80.6% on their first try with that robotSource 2. Google DeepMind reports that Gemini Robotics On-Device 2 adapts to new bi-arm embodiments in a few hours, "typically with less than 200 examples"Source 6.
None of these results shows reliable, unaided success in unseen homes
First, the air fryer attempt does not finish the task without coaching, and the authors claim only "early signs of compositional task generalization"Source 3 Source 2.
Second, reliability is unshown: π0.5's headline evaluation is three homes and ten trials per taskSource 1 (The Reliability Gap, The Evaluation Crisis). No published result shows a generalist policy sustaining better than 95% success across a broad task distribution in unseen environments. Generalist's reported 99% average for GEN-1 covers only tasks it was fine-tuned onSource 18.
Benchmark scores hide brittleness: modest perturbations cut LIBERO-Plus success "from 95% to below 30%"Source 19 and Colosseum's by 30 to 50%Source 20. On LIBERO-PRO, over-90% performance "collapses to 0.0%"Source 21.
Third, the evaluations lean semantic, while new object physics bring in touch and contact (Dexterity). DreamZero's authors write that VLAs "struggle to generalize to unseen physical motions in novel environments", and report over 2x better generalization from a video world action modelSource 22. In March 2026 NVIDIA previewed GR00T N2, built on DreamZero research, and says it succeeds at new tasks more than twice as often as leading VLAsSource 31.
Fourth, transfer works best when source and target share task structure. In π0.7's ablations, performance degrades as the embodiment gap widens before the latest model recovers itSource 2. Across morphologies, the closest evidence is EgoScale's transfer from a 22-DoF hand to lower-DoF handsSource 4.
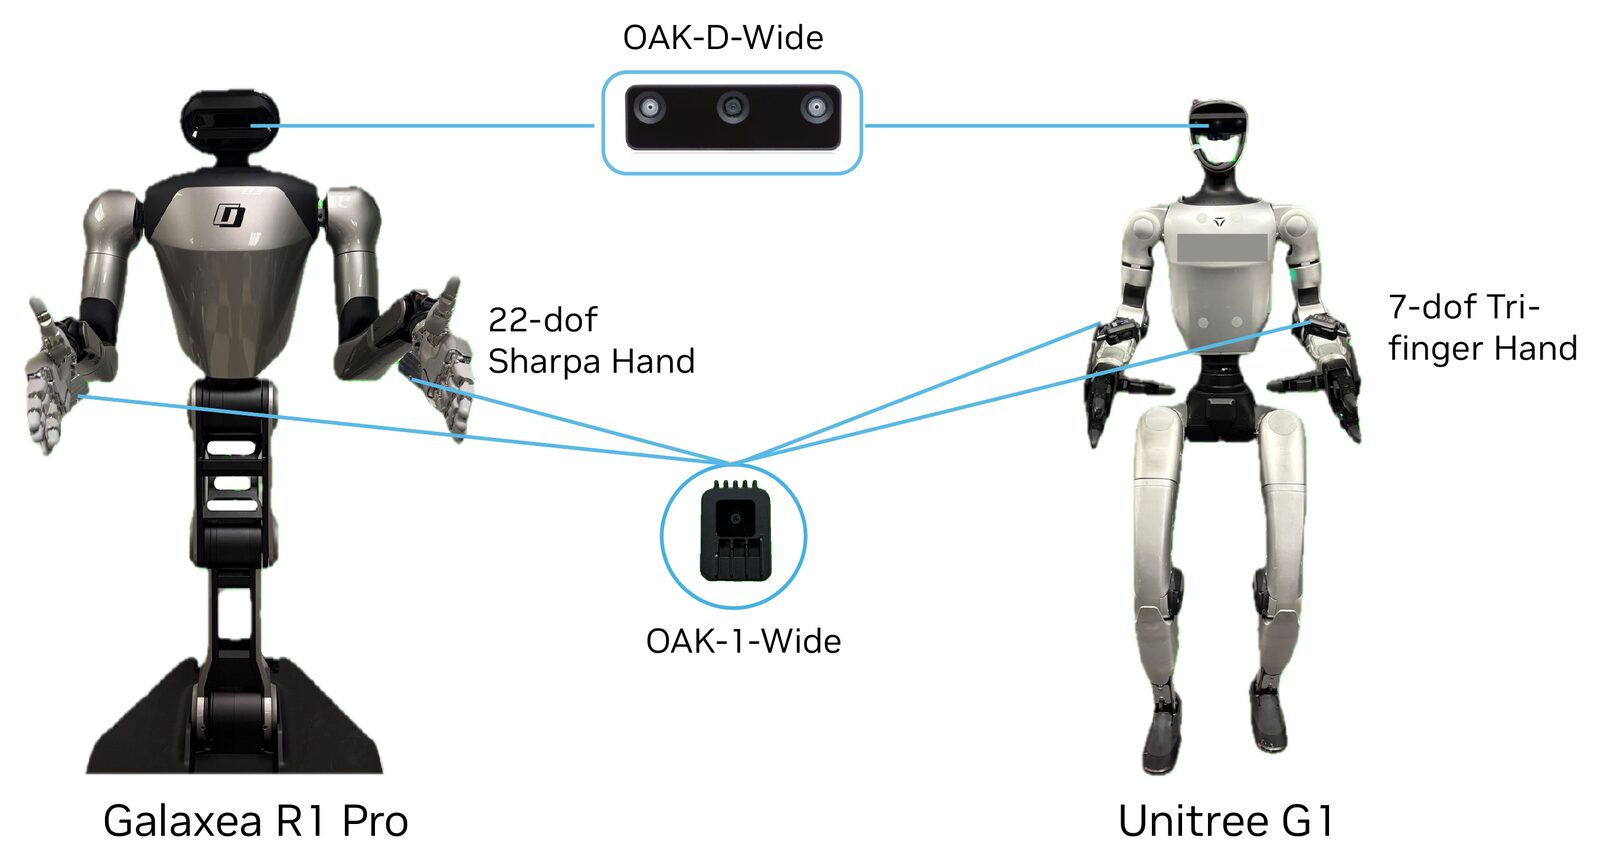
EgoScale's law holds from 1k to 20k hours of human video
NVIDIA's EgoScale trained a VLA on 20,854 hours of action-labeled egocentric human video, more than twenty times prior efforts. Held-out validation loss follows with in thousands of hours, fit over five scales from 1k to 20k hours at . After post-training, average task completion rises from 0.30 at 1k hours to 0.71 at 20k, and the recipe lifts success by 54% over no pretraining on a 22-DoF handSource 4.
NVIDIA's GR00T N1 mixed "real-robot trajectories, human videos, and synthetically generated datasets"Source 23. N1.7 adds 20K hours of EgoScale video through an end-effector space shared by robots and humans (Cross-Embodiment Transfer)Source 5.
The chart extends the fit past 20k hours, although the authors "do not extrapolate beyond the measured range", and its completion fit crosses an impossible 100% near 250k hoursSource 4. The law is fit to validation loss, a proxy that correlates with real-robot performance without being a success rate across unseen environments. Lin et al. come closest to a law for that metric: single-task performance in unseen environments "follows a roughly power-law relationship with the number of environments and objects"Source 7.
No published law yet predicts real-world success in unseen settings
Generalist fits a power law to GEN-0's 270,000 hours of real-world manipulation data, with "next-action prediction error" as its targetSource 24. Figure's human-to-humanoid transfer law is also fit to robot-action predictionSource 25. TRI's blind, randomized trials found that performance "predictably increases as pretraining scale and diversity grows", without fitting a lawSource 26.
The scaling camp cites EgoScale's "no signs of saturation in the explored regime"Source 4, AgiBot World's "predictable performance scaling with increased data volume"Source 27 and π0.7's compositional resultsSource 2. Investor analysis from Bessemer, arguing that scaling laws are beginning to show up in robotics data, says of robotics' ChatGPT moment: "We don't think that moment is years away. But it's not here yet."Source 11.
Generalist reports over half a million hours for GEN-1Source 18. Xiaomi trained on over 100k hours from UMI handheld grippersSource 28, with stronger pretraining giving better out-of-the-box results in unseen environmentsSource 29.
Ken Goldberg frames the shortfall as a 100,000-year data gap. He expects end-to-end learning to win eventually, but argues that pairing good old-fashioned engineering with learning gets robots deployed and collecting data soonerSource 8. Rodney Brooks argues the missing ingredients are touch and engineered priorsSource 9. Karcini and co-authors argue that policy scaling lacks mechanisms that turn unstructured behavior into grounded robot supervisionSource 10.
The settling test is whether a 10x or 100x data increase, with no architectural change, yields proportional real-world gains in unseen environments. Shi et al. find task diversity "more critical than per-task demonstration quantity"Source 30.
No system yet meets the solved bar of 90% across dozens of unseen homes
Generalization is solved when a single policy achieves better than 90% success across many unseen homes, dozens of them, with no per-site data collection or fine-tuning, in a published, reproducible evaluation spanning many tasks and objects. No current system has been evaluated this way. Figure reports that Helix 2.5 reached 56% zero-shot success, against 9% without Index pretraining, on three whole-body tasks in 30 unseen Bay Area homes, graded blind with no published trial countsSource 25.
Zero-shot success in 30 homes
Helix 2.5 reached 56% in unseen homes, short of 90%
How this was made
Figure trained two policies on the same task data, one from random weights and one from the Index-pretrained Helix 2.5 model, and ran both in 30 Bay Area homes where it had collected no data. Figure reports one success rate for the three tasks together (tidying a living room, folding towels, making a bed) and publishes no trial counts and no per-task rates. The 90 percent line is the bar for solved that this article sets.
Zero-shot success on three whole-body tasks in 30 unseen homes, as Figure reports it: 9% for a policy trained from scratch and 56% for Helix 2.5, pretrained on Figure's Index human data, both trained on the same task data. Helix 2.5 sits 34 points below the 90% bar this article sets for solved. Figure published no trial counts.
Zero-shot success, with and without pretraining
| policy | zero-shot success (percent) |
|---|---|
| Trained from scratch | 9 |
| Helix 2.5, pretrained on Index | 56 |
| Bar for solved, this article | 90 |
The solved bar sits at 0.90 on the EgoScale chart's completion axis, and the best measured point is 0.71, on a friendlier metric, after post-training, on tasks the evaluators choseSource 4. The extrapolation crosses the bar only near 111k hours of human video, five times past the measured range.
See also
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- Foundation Models for Robotics
What foundation means in robotics, and what adaptation still costs.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
Linked from
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
- Competing Theses
Six bets on how robot intelligence gets built.
- The Bear Case
Why this could be another robotics winter.
References
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/blog/pi07
Ruijie Zheng, Dantong Niu, Yuqi Xie, Jing Wang, Mengda Xu, Yunfan Jiang, and 9 more, 2026.
https://arxiv.org/abs/2602.16710
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Fanqi Lin, Yingdong Hu, Pingyue Sheng, Chuan Wen, Jiacheng You, Yang Gao, ICLR 2025, 2024.
https://arxiv.org/abs/2410.18647
Ken Goldberg, Science Robotics, 2025.
https://doi.org/10.1126/scirobotics.aea7390
Rodney Brooks, 2025.
https://rodneybrooks.com/why-todays-humanoids-wont-learn-dexterity/
Elis Karcini, Faisal Mehrban, Quang Nguyen, Mac Schwager, Arash Ajoudani, Cesar Cadena, and 3 more, 2026.
https://arxiv.org/abs/2606.06556
Jeremy Levine, Talia Goldberg, Janelle Teng Wade, Alexandra Sukin, Bhavik Nagda, Jason Scheller, and 1 more, 2026.
https://www.bvp.com/atlas/bessemer-predicts-robotics-and-physical-ai
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, and 48 more, 2023.
https://arxiv.org/abs/2307.15818
Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, and 5 more, 2025.
https://arxiv.org/abs/2505.23705
Irving Fang, Juexiao Zhang, Shengbang Tong, Chen Feng, 2025.
https://arxiv.org/abs/2506.09930
Jensen Gao, Suneel Belkhale, Sudeep Dasari, Ashwin Balakrishna, Dhruv Shah, Dorsa Sadigh, IEEE Robotics and Automation Letters, 2025.
https://arxiv.org/abs/2503.01238
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1.5
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Wilbert Pumacay, Ishika Singh, Jiafei Duan, Ranjay Krishna, Jesse Thomason, Dieter Fox, RSS 2024.
https://arxiv.org/abs/2402.08191
Xueyang Zhou, Yangming Xu, Guiyao Tie, Yongchao Chen, Guowen Zhang, Duanfeng Chu, and 2 more, 2025.
https://arxiv.org/abs/2510.03827
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Generalist Team, Generalist AI blog, 2025.
https://generalistai.com/blog/gen-0
Figure AI, Figure news, 2026.
https://www.figure.ai/news/helix-2-5-zero-shot-30-home-generalization
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
AgiBot-World-Contributors, Qingwen Bu, Jisong Cai, Li Chen, Xiuqi Cui, Yan Ding, and 46 more, 2025.
https://arxiv.org/abs/2503.06669
Cheng Chi, Zhenjia Xu, Chuer Pan, Eric Cousineau, Benjamin Burchfiel, Siyuan Feng, and 2 more, 2024.
https://arxiv.org/abs/2402.10329
Xiaomi Robotics Team, Jun Guo, Piaopiao Jin, Jason Li, Peiyan Li, Yingyan Li, and 28 more, 2026.
https://arxiv.org/abs/2607.15330
Modi Shi, Li Chen, Jin Chen, Yuxiang Lu, Chiming Liu, Guanghui Ren, and 4 more, 2025.
https://arxiv.org/abs/2507.06219
NVIDIA, NVIDIA Newsroom, 2026.
https://nvidianews.nvidia.com/news/nvidia-and-global-robotics-leaders-take-physical-ai-to-the-real-world
Further reading
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Spot a factual error or missing qualification? Report a content correction.