The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
The pi line is Physical Intelligence's series of vision-language-action models, from π0 (October 2024) to π0.7 (April 2026)Source 14 Source 10.
π0 kept a pretrained vision-language backbone and replaced discrete action tokens with a flow-matching action expertSource 1. Later models changed tokenization, training data, memory and prompting. Drag the integration steps slider from 1 upward to watch the cloud reach the action modes.
Flow matching: refining steps
Five small steps land where one big jump misses
Refining steps per move
Adjust more
10 small steps land on the good move. Run the stylus.10 steps · on average lands 0.05 from a good move · one big jump misses by 0.51
Illustrative model, not measured.
How this was made
Flow matching turns a random guess into a move by following a learned field for a set number of Euler integration steps. Each step samples the field once and goes straight, so with one or two steps the path cuts the corner and lands short of the good move; with five to ten it lands on it. On the field table a vane beside the stylus turns to the field before every hop and the hop runs straight along it; the groove is the path the field itself would trace, and each pocket is two spreads of the good moves wide. The vanes in “Adjust more” show the learned field at τ = 0.5, halfway through the trip. Every step costs one forward pass through the action expert, one bead on the counter, which is why more steps are not free at a 50 Hz control rate.
Illustrative model, not a reimplementation: 48 seeded noise samples in 2 of the chunk's dimensions (action dimension 1 and action dimension 2) are carried to two action modes along slightly bent, near-straight paths. The stage draws 12 of them. The mean endpoint error is k = 10 Euler steps: 0.05, on the modes; one step gives 0.51, ten give 0.05 and 50 give 0.01. π0 ran 10 integration steps; π0.6 and π0.7 run 5.
With 10 Euler steps the 48 samples travel near-straight from Gaussian noise toward the two action modes and finish at mean endpoint error 0.05; one step would cut the corner, 50 steps is more compute than a 50 Hz loop can spend.
Current flow-matching transport
- Euler steps
- 10
- samples
- 48
- endpoint error
- 0.05
- regime
- on the modes
Illustrative model; step counts from the π0, π0.6 and π0.7 papers.
π0: the action expert
π0 grafts a second transformer, the action expert of about 300M parameters, onto a pretrained vision-language model initialized from PaliGemma; the backbone handles image and text tokens, and the expert's 50 action tokens attend into it at every layer through shared self-attention. Inputs are 2 or 3 RGB images, language and proprioceptive state, and the model predicts H = 50 actions, executing 16 per inference at 20 Hz on UR5e and Franka or 25 at 50 Hz on the other robotsSource 1.
Where Diffusion Policy denoises with a DDPM, π0 trains the expert with conditional flow matching on a straight path. Training samples noise , forms , and regresses onto . Inference integrates from to in 10 forward-Euler steps, with the image-text-state prefix KV-cached once so each step recomputes only the action suffixSource 1. Lipman et al. found optimal-transport paths more efficient than diffusion paths for training and samplingSource 15.
~300M
action expert
PaliGemma-initialized VLM; no total asserted here
H = 50
predicted chunk
Executes 16 at 20 Hz or 25 at 50 Hz, by setup
10
Euler steps
KV-cached prefix
~10k h
demonstrations
7 robot configurations, 68 tasks; plus OXE data
Cross-embodiment pre-training combines single-arm, dual-arm and mobile manipulators across 7 robot configurations. The base model reaches what the authors call "rudimentary proficiency", and complex tasks such as laundry folding use curated post-training dataSource 1. PI says π0, π0-FAST and π0.5 executed chunks synchronously, waiting for inference after each oneSource 17, which the RTC paper later compared with asynchronous execution on π0.5Source 13.
Why ten steps is enough
A DDPM path curves through noise space, while rectified flow straightens paths so that coarse time steps simulate them accuratelySource 18. Each Euler step costs a forward pass through the expert: π0 uses 10 stepsSource 1, π0.6 uses fiveSource 6, and π0.7 also uses fiveSource 10. Consistency and one-step distillation, covered in Diffusion Policy, pursue the same saving.
π0-FAST: compressed action tokens
FAST traces the failure of per-dimension, per-timestep binning to highly correlated tokens, which make next-token prediction trivial; policies with this naive tokenization make no progress on table bussing at 20 Hz or T-shirt folding at 50 HzSource 2. FAST instead applies a discrete cosine transform along time, rounds the coefficients and byte-pair-encodes the result, and its universal FAST+ tokenizer is trained on about one million one-second action chunks across embodimentsSource 2, or "1M real robot action sequences" in PI's postSource 19.
Trained on a 10k-hour cross-embodied mixture, π0-FAST matches π0's generalist performance with up to five times fewer GPU hours. Inference costs more: about 750 ms per one-second chunk on an NVIDIA 4090, against within 100 ms for diffusion π0, since decoding needs 30 to 60 tokens instead of ten stepsSource 2. The Knowledge Insulation note reports that π0-FAST took twice as long to finish single-embodiment table bussingSource 5.
π0.5 and Knowledge Insulation
π0.5 targets open-world generalizationSource 3. It keeps the π0 skeleton, adds training examples that interleave images, language commands, object detections, subtask predictions and low-level actions, and at inference first predicts a language subtask ("pick up the plate"), then conditions the action expert on it. In long-horizon mobile manipulation in new homes, removing either cross-embodiment data source significantly hurts home-task scores, while removing web data leaves those scores nearly unchanged but strongly hurts language following and subtask inferenceSource 3.
The Knowledge Insulation paper turns the two-stage π0.5 approach into one stage: the expert trains with flow matching for continuous inference, and the backbone trains on discrete FAST tokens, vision-language data and planning data, with expert gradients stopped at the backbone keys and valuesSource 4. With a frozen backbone, shirt folding drops to 0%; on generalist table bussing, π0 needs 7.5 times as many training steps to match; and vision-language co-training also gives the joint-training baseline good language following without stop-gradientSource 4. The openpi π0.5 checkpoints were trained with KI, but the repository supports only the flow-matching headSource 12, so outside groups reimplement the FAST loss and KISource 20.
π0.6 and π*0.6: scaling and experience
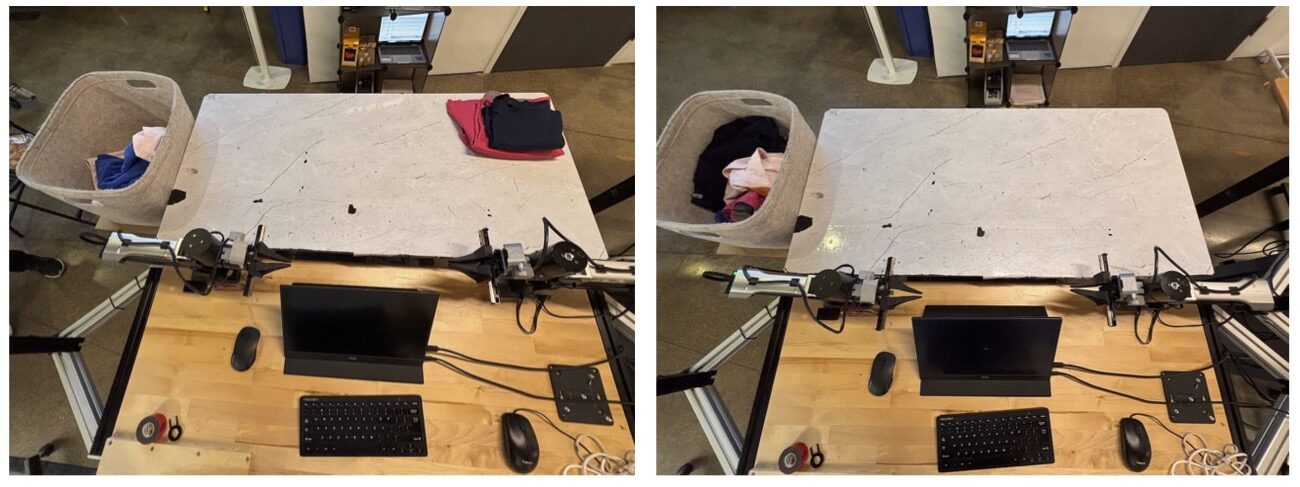
The π0.6 model card, dated November 17, 2025, initializes the backbone from Gemma3 4B, gives the action expert about 860M parameters and keeps expert gradients out of the backbone. Without task-specific fine-tuning, π0.6 folds laundry reliably and fully assembles the box 20% of the time, tasks that previously needed fine-tuning to succeed at allSource 6. In PI's Robot Olympics, fine-tuned π0.6 averaged 52% success and 72% task progress, while a fine-tuned standard VLM without π0.6's robot pre-training had no successes and 9% progressSource 21.
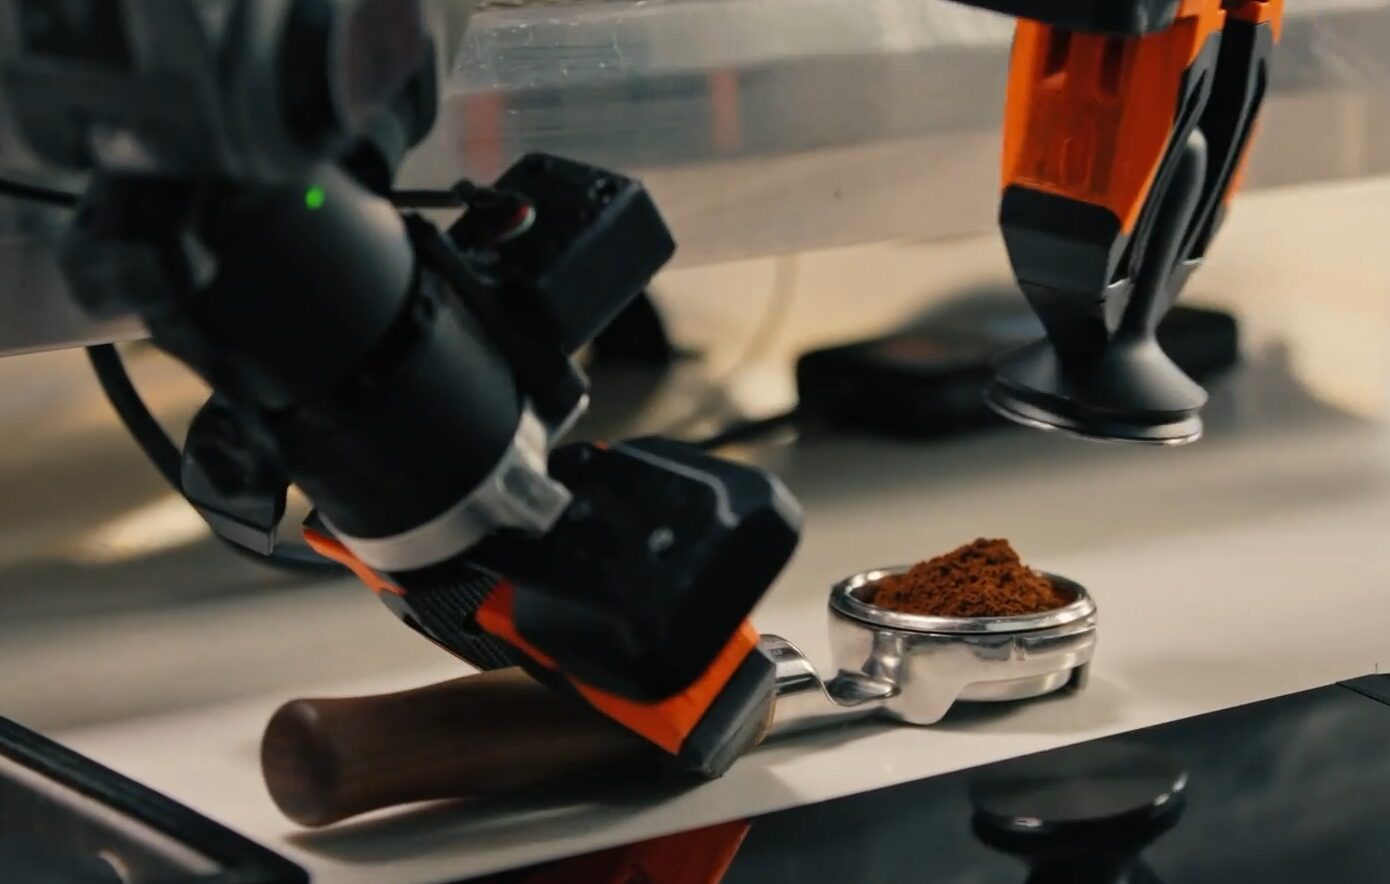
π*0.6 uses Recap to learn from demonstrations, expert teleoperation corrections and autonomous experience, with a language-conditioned value function whose advantage, against a task-dependent threshold, gives each action a binary improvement indicator; human corrections are forced positive, and evaluation samples with the positive indicatorSource 7. The report places this formulation closest to CFGRLSource 22, while outside groups find RL on flow-based π0 and π0.5 hard because flow matching makes action log-likelihoods intractableSource 23. The companion blog's example is a bad portafilter grasp that causes a later insertion failureSource 8.
On a rig with two 6-DoF arms and 50 Hz joint-position control, on-robot experience more than doubles successful completions per hour for double-shot espresso and diverse laundry, tested on a button-up shirt, against offline RL plus demonstration fine-tuning. Failures fall by "about a factor of two" ("more than 2×" in the figure), the "90%+" summary excludes diverse laundry, and the box task reports stages separately, with remaining failures mostly in final placementSource 7.
PI published MEM on March 3, 2026Source 24. π0.6-MEM pairs a video encoder with a high-level policy that predicts updated natural-language summaries of earlier events, and handles tasks needing up to fifteen minutes of memory, such as recipe setup and kitchen cleanup. Its adaptation experiments train memory and memoryless policies on the same corrections, such as which way to open a refrigeratorSource 9.
RL tokens
On March 19, 2026, PI described RL tokens: small actor and critic networks train online on a compressed, frozen token from π0.6, speeding up the most precise stages of four tasks by up to 3×; Ethernet insertion took two hours of training with 15 minutes of robot dataSource 25. RL fine-tuning covers the wider method family.
π0.7: generalization as a prompting problem
π0.7 treats underspecified prompts as the generalization bottleneck. It is π0.6 plus MEM at about 5B parameters, and training simulates real-time chunking delays of 0 to 12 timesteps, up to 240 ms on a 50 Hz robotSource 10, the training-time RTC method that on π0.6 matched inference-time RTC at lower computeSource 26.
The context holds task and subtask language, with the subtask from a learned high-level policy or a human, and episode metadata on quality, speed and mistakes; training uses different subsets of this context but always keeps the joint or end-effector control-mode label. Multi-view subgoal images come from a BAGEL-initialized world model, and subgoal and subtask generation run in separate threadsSource 10. BAGEL is a unified decoder-only model pretrained on trillions of interleaved tokensSource 27.
π0.7 folds laundry on a bimanual UR5e with no laundry data for that robot, matching the task progress of experienced teleoperators trying it there for the first timeSource 10. In the air-fryer example, language coaching fine-tunes a high-level policy that generates the subtasks without new teleoperation, which the authors call "early signs of compositional task generalization"Source 11. Human video joins the line through π0.5 co-fine-tuning, which roughly doubles performance on scenarios seen only in human dataSource 28.
Which checkpoints are listed
PI released π0's code and weights in openpi on February 4, 2025, saying 1 to 20 hours of data sufficed to fine-tune a variety of tasksSource 16. The openpi README at the pinned commit of August 24, 2026 lists base checkpoints for π0, π0-FAST and π0.5, plus π0-FAST, π0 and π0.5 models fine-tuned on DROID and a π0.5 LIBERO modelSource 12. DROID holds 76k trajectories from 564 scenesSource 29, and LIBERO has 130 tasks in four suitesSource 30.
Physical Intelligence's models
A new robot model every few months; first three downloadable
Adjust more
Month not known:
π0Oct 2024weights downloadable
The first model in the family: it adds a part that turns what a picture-and-language model understands into smooth arm motion.
How this was made
Each name sits above the month its source was published, which is not always the month a checkpoint was released. The π0.6-MEM report does not establish its month, so it is listed beside the timeline and not plotted. Shaded bands mark calendar years and change at January.
“Downloadable” means listed in the openpi checkpoint catalogue as pinned at commit 215abfb; it says nothing about the licence. The pinned catalogue ends at π0.5.
4 model entries not in the pinned catalogue have unverified weight availability: missing from that list is not evidence of closed weights.
| Model | Source month | Weights | Architecture | Contribution | Source |
|---|---|---|---|---|---|
| π0 | Oct 2024 | downloadable | PaliGemma 3B + 300M action expert | Flow-matching action expert grafted onto a pretrained VLM; 50-step action chunks, at up to 50 Hz. | Black et al. 2024 |
| π0-FAST | Jan 2025 | downloadable | PaliGemma 3B, autoregressive | DCT + BPE action tokenization (FAST); autoregressive VLAs become viable at 50 Hz. | Pertsch et al. 2025 |
| π0.5 | Apr 2025 | downloadable | PaliGemma-class 3B + 300M expert | Heterogeneous co-training buys open-world generalization in never-before-seen homes. | Physical Intelligence et al. 2025 |
| π0.6 | Nov 2025 | unverified | Gemma3 4B + SigLIP 400M + 860M expert | Knowledge Insulation at scale; laundry folding and box assembly without task-specific fine-tuning. | Physical Intelligence 2025 |
| π*0.6 | Nov 2025 | unverified | π0.6 + advantage-conditioned Recap | RL from demonstrations, coaching, and practice; espresso throughput more than doubled. | Amin et al. 2025 |
| π0.6-MEM | Date unverified | unverified | π0.6 + two-scale memory | Short-term video history plus long-term model-authored notes; 15-minute tasks. | Torne et al. 2026 |
| π0.7 | Apr 2026 | unverified | Gemma3 4B + 860M expert | Diverse multimodal prompting (metadata, control mode, generated subgoals); early signs of compositional generalization. | Ai et al. 2026 |
The π line contains 7 generations, with established source months from Oct 2024 to Apr 2026. MEM has no established month and is not plotted. The downloadable bracket ends at π0.5 and marks the pinned checkpoint catalogue, not licensing; selected now is π0 (PaliGemma 3B + 300M action expert, weights downloadable) and 4 other entries have unverified availability.
Current π generation
- selected
- π0
- source month
- Oct 2024
- weights
- downloadable
- generations
- 7
- not in pinned catalogue
- 4
Source for π0: Black et al. 2024; download status from the openpi checkpoint catalogue.
In two outside comparisons, Google DeepMind's re-implementation trained on its own mixture beat the public π0 checkpointSource 31, and OpenVLA with the OFT recipe outperformed π0 fine-tuned with its default recipeSource 32.
See also
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
- Cross-Embodiment Transfer
How one policy learns from many robot bodies and from humans.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
Linked from
- Action Chunking (ACT and ALOHA)
ACT predicts short action sequences and smooths them with temporal ensembling.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
- Offline Reinforcement Learning for Robotics
CQL and TD3+BC, and when behavior cloning is the stronger baseline.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
References
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, and 3 more, 2025.
https://arxiv.org/abs/2501.09747
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, and 5 more, 2025.
https://arxiv.org/abs/2505.23705
Danny Driess, Jost Tobias Springenberg, Brian Ichter, Lili Yu, Adrian Li-Bell, Karl Pertsch, and 5 more, 2025.
https://www.pi.website/research/knowledge_insulation
Physical Intelligence, 2025.
https://website.pi-asset.com/pi06star/PI06_model_card.pdf
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/download/pistar06.pdf
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/blog/pistar06
Marcel Torne, Karl Pertsch, Homer Walke, Kyle Vedder, Suraj Nair, Brian Ichter, and 11 more, 2026.
https://www.pi.website/download/Mem.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/blog/pi07
Physical Intelligence, 2026.
https://github.com/Physical-Intelligence/openpi/blob/215abfb217dbac7d5f1273282331b9b1866c0479/README.md
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://arxiv.org/abs/2506.07339
Kevin Black, Noah Brown, Danny Driess, Michael Equi, Adnan Esmail, Chelsea Finn, and 18 more, Physical Intelligence, 2024.
https://www.pi.website/blog/pi0
Yaron Lipman, Ricky T. Q. Chen, Heli Ben-Hamu, Maximilian Nickel, Matt Le, 2022.
https://arxiv.org/abs/2210.02747
Physical Intelligence, Physical Intelligence, 2025.
https://www.pi.website/blog/openpi
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://www.pi.website/research/real_time_chunking
Xingchao Liu, Chengyue Gong, Qiang Liu, 2022.
https://arxiv.org/abs/2209.03003
Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, and 3 more, Physical Intelligence, 2025.
https://www.pi.website/research/fast
Prachi Garg, Steve Xing, Prahit Yaugand, Saurabh Gupta, Derek Hoiem, 2026.
https://arxiv.org/abs/2608.19490
Physical Intelligence, 2025.
https://www.pi.website/blog/olympics
Kevin Frans, Seohong Park, Pieter Abbeel, Sergey Levine, 2025.
https://arxiv.org/abs/2505.23458
Kang Chen, Zhihao Liu, Tonghe Zhang, Zhen Guo, Si Xu, Hao Lin, and 10 more, 2026.
https://arxiv.org/abs/2510.25889
Marcel Torne, Karl Pertsch, Homer Walke, Kyle Vedder, Suraj Nair, Brian Ichter, and 11 more, Physical Intelligence, 2026.
https://www.pi.website/research/memory
Charles Xu, Jost Tobias Springenberg, Michael Equi, Ali Amin, Adnan Esmail, Sergey Levine, and 1 more, Physical Intelligence, 2026.
https://www.pi.website/research/rlt
Kevin Black, Allen Z. Ren, Michael Equi, Sergey Levine, 2025.
https://arxiv.org/abs/2512.05964
Chaorui Deng, Deyao Zhu, Kunchang Li, Chenhui Gou, Feng Li, Zeyu Wang, and 6 more, 2025.
https://arxiv.org/abs/2505.14683
Simar Kareer, Karl Pertsch, James Darpinian, Judy Hoffman, Danfei Xu, Sergey Levine, and 2 more, 2025.
https://www.pi.website/research/human_to_robot
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
Bo Liu, Yifeng Zhu, Chongkai Gao, Yihao Feng, Qiang Liu, Yuke Zhu, and 1 more, 2023.
https://arxiv.org/abs/2306.03310
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Further reading
Lucas Beyer, Andreas Steiner, André Susano Pinto, Alexander Kolesnikov, Xiao Wang, Daniel Salz, and 29 more, 2024.
https://arxiv.org/abs/2407.07726
Aditya Sahu, Anqi Liu, official tutorial, n.d.; accessed 2026-10-04.
https://www.jetson-ai-lab.com/tutorials/openpi_on_thor/
Lucy Shi, Brian Ichter, Michael Equi, Liyiming Ke, Karl Pertsch, Quan Vuong, and 9 more, Physical Intelligence, 2025.
https://www.pi.website/research/hirobot
Gemma Team, Aishwarya Kamath, Johan Ferret, Shreya Pathak, Nino Vieillard, Ramona Merhej, and 210 more, 2025.
https://arxiv.org/abs/2503.19786
Physical Intelligence, Physical Intelligence, 2026.
https://www.pi.website/blog/partner
Spot a factual error or missing qualification? Report a content correction.