RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
RL fine-tuning is the use of reinforcement learning to improve a pretrained robot policy from its own successes and failures. Imitation learning is brittle off the demonstration distribution because errors compoundSource 1, and Physical Intelligence finds reliable success much harder than occasional successSource 6.
Switch to “What it learns”.
Advantage tags
The robot learns its real mistake came 20 seconds earlier
Show
Adjust more
Current step: Outcome: low advantage (-2.0)
How this was made
Advantage is the change in the value score across a step: the score at its end minus the score at its start. A step whose score rises is tagged high advantage (“helped”); one whose score falls is tagged low advantage (“hurt”). The value score is drawn as the chance the attempt ends well; this toy starts it at V = 30 on an arbitrary scale.
- Reach (0-8 s, score change +8.0, high advantage): The arm approaches the portafilter and pre-shapes the hand.
- Grasp (8-16 s, score change -12.0, low advantage): In this toy, the portafilter is grasped at a bad angle and the arbitrary score falls. This is not evidence that a value function is the only possible signal.
- Dose and tamp (16-26 s, score change +7.0, high advantage): Grounds are dosed and tamped. Locally competent, but the grasp angle has not been corrected.
- Insert and lock (26-36 s, score change -21.0, low advantage): The misaligned portafilter will not seat. The failure is observed here, 20 s after the grasp that caused it.
- Outcome (36-40 s, score change -2.0, low advantage): No extraction. The episode ends in failure and every transition keeps its advantage tag.
The episode follows the portafilter example in the Recap companion blog. The step scores, the forty-second length and the twenty-second gap are illustrative, not a recorded episode. Recap's own estimator also counts rewards, applies a task-dependent threshold, forces human corrections positive and sometimes drops the indicator during training. A value score is not the only possible signal for finding the cause.
At t = 40.0 s this teaching toy shows an arbitrary value score of 10.0 in the Outcome segment, tagged low advantage because its score changes by -2.0. The dashed arc links a fictional insertion failure at 32 s to a grasp 20 s earlier. The tinted stage blocks are the steps tagged low advantage. Its timings, values and stage-difference tags are illustrative, not a measured Recap episode or its reward-inclusive, task-thresholded advantage estimator.
Toy value along the fictional espresso episode
| time (s) | value | segment | playhead |
|---|---|---|---|
| 0 | 30.0 | Reach | off |
| 8 | 38.0 | Grasp | off |
| 16 | 26.0 | Dose and tamp | off |
| 26 | 33.0 | Insert and lock | off |
| 32 | 18.0 | Insert and lock | off |
| 40 | 10.0 | Outcome | playhead |
Teaching toy after the Recap portafilter example; timings, scores and tags are illustrative.
>2x
espresso throughput
Double espresso: on-robot RL vs offline RL + SFT; lab-reported
1-2.5 h
reported RL training
Nearly all HIL-SERL tasks; timing-belt assembly: 6 h
15-90 min
online fine-tune
ConRFT lab report: 96.3% mean over 8 tasks, 20 trials each; listed online times 15-90 min, abstract and prose 45-90
2026
pi_RL revision
January 29 revision; path/transition likelihoods
The flow-matching log-likelihood problem
PPO runs several epochs of minibatch updates on a clipped surrogate objectiveSource 18, which needs the likelihood of each action taken. Flow matching trains by regressing vector fields along fixed conditional probability pathsSource 19, so the executed action's log-likelihood is intractableSource 4. Online RL applied directly to large VLAs is also unstable and needs compute beyond most local machinesSource 20.
DPPO (Ren et al., 2024) follows DDPO, which posed diffusion denoising as a multi-step decision problemSource 21. DPPO embeds denoising inside the environment MDP: each denoising transition has an analytic Gaussian likelihood, and the environment advances and pays reward only after the final step. Only the last selected denoising steps are fine-tuned, with a frozen copy of the network for earlier onesSource 2.
DPPO is the strongest of the compared diffusion-based RL methods on state-input Robomimic tasks, though off-policy methods are more sample-efficient on HalfCheetah and a Gaussian policy slightly beats it on the low-randomness Lamp task. A simulation-trained One-leg assembly policy transferred zero-shot to a Franka Emika Panda and succeeded in 16 of 20 trials at 10 HzSource 2.
ReinFlow injects learnable noise into a flow policy's path for exact per-step likelihoods, saving 82.63% of wall time against DPPO on legged locomotionSource 22, and FPO instead builds a PPO-clip ratio from the conditional flow-matching lossSource 23. QF3 (UC Berkeley and Amazon FAR, October 2026), an off-policy method that adds the critic's action gradient to the flow-matching loss, is reported as the first off-policy flow RL method to train humanoid locomotion from scratch and transfer it zero-shot to hardware, with a 10× wall-clock speedup over the on-policy FPO++Source 37.
ConRFT (Chen et al., 2025) fine-tunes a consistency-policy action head, a sampler distilled from a diffusion policySource 24, while freezing the visual encoders and transformer backbone of Octo-small on a 7-DoF Franka. Offline Cal-ConRFT pairs a consistency-based behavior cloning loss with a Cal-QL critic, from 20 to 30 demonstrations per task, and online HIL-ConRFT adds human takeovers to the demonstration bufferSource 3.
ConRFT reports 96.3% mean success rate across eight tasks, 20 trials each, after 15 to 90 minutes of listed online training. ConRFT's headline 144% is a rounded relative gain over offline Cal-ConRFT's 39.4% mean, which the SFT baseline also scores. Online learning curves can include successes produced by human takeovers, and the paper warns of reward-classifier hacking and limited generalizationSource 3. ConRFT says every compared method used interventions, but PA-RL reports fine-tuning OpenVLA autonomously with Cal-QL, from 40% to 70% in 40 real-world minutesSource 25.
pi_RL (Chen et al., 2026) fine-tunes flow-based policies with online PPO. Flow-Noise learns Gaussian noise for denoising transitions jointly with the velocity network and uses the joint likelihood of the denoising path in place of the executed action's marginal likelihood. Flow-SDE uses Gaussian transition likelihoods in a two-layer denoising and environment MDP, with one randomly chosen denoising step stochastic and the rest deterministicSource 4.
Main experiments fine-tune π0 and π0.5 in simulation on LIBERO, ManiSkill, MetaWorld and CALVIN, and gains under distribution shift do not consistently reach the five unseen MetaWorld ML45 tasks. A Real2Sim2Real case transfers zero-shot to a Franka Panda, reporting 40% success without a trial countSource 4.
Recap: advantage-conditioned policy learning
Recap, the method behind π*0.6, combines demonstrations, expert teleoperation corrections during rollouts and autonomous experience, in rounds of collection and retraining. A language-conditioned distributional value function predicts negative remaining steps for successes and a large negative value for failures. In post-training the advantage uses rewards over the next N = 50 steps plus the later value minus the current value, and a task-dependent threshold turns it into a binary indicator, with human corrections assigned the positive oneSource 5.
The text "Advantage: positive" or "Advantage: negative" precedes the actions, so good and bad data both train the policy, and evaluation uses the positive-conditioned policy; indicator dropout permits classifier-free guidanceSource 5, which combines jointly trained conditional and unconditional estimatesSource 26. The KL-regularized objective has the exponential solution:
Advantage-weighted regression fits that target with two supervised stepsSource 27. Recap's binary conditioning instead writes the improved policy as
At this reduces to the indicator-conditioned policy. Recap thereby avoids a PPO-style objective: training combines next-token prediction with the flow-matching loss, and Knowledge Insulation stops the action expert's gradient at the backbone interfaceSource 5 Source 7.
On-robot experience more than doubles successful completions per hour for double-shot espresso and diverse laundry, against offline RL plus demonstration fine-tuning, on a static bimanual setup with a button-up-shirt test in place of the 11-item laundry set. Failures fall by "about a factor of two" ("more than 2×" elsewhere in the report); the "90%+" summary excludes diverse laundry, and the box chart reports stages separatelySource 5. The pi line lists the hardware and time limits.
The companion blog's video caption gives 5:30am to 11:30pm of espresso making, while the report says "13 hours straight"Source 6 Source 5. The results are Physical Intelligence's own, with human reward labeling, interventions, resets and batch offline updatesSource 5. In March 2026 Physical Intelligence added RL tokens: small actor and critic networks train online on a compact token from π0.6, speeding the most precise stage of four tasks by up to 3×Source 28.
HIL-SERL: a human in the loop, RL on the robot
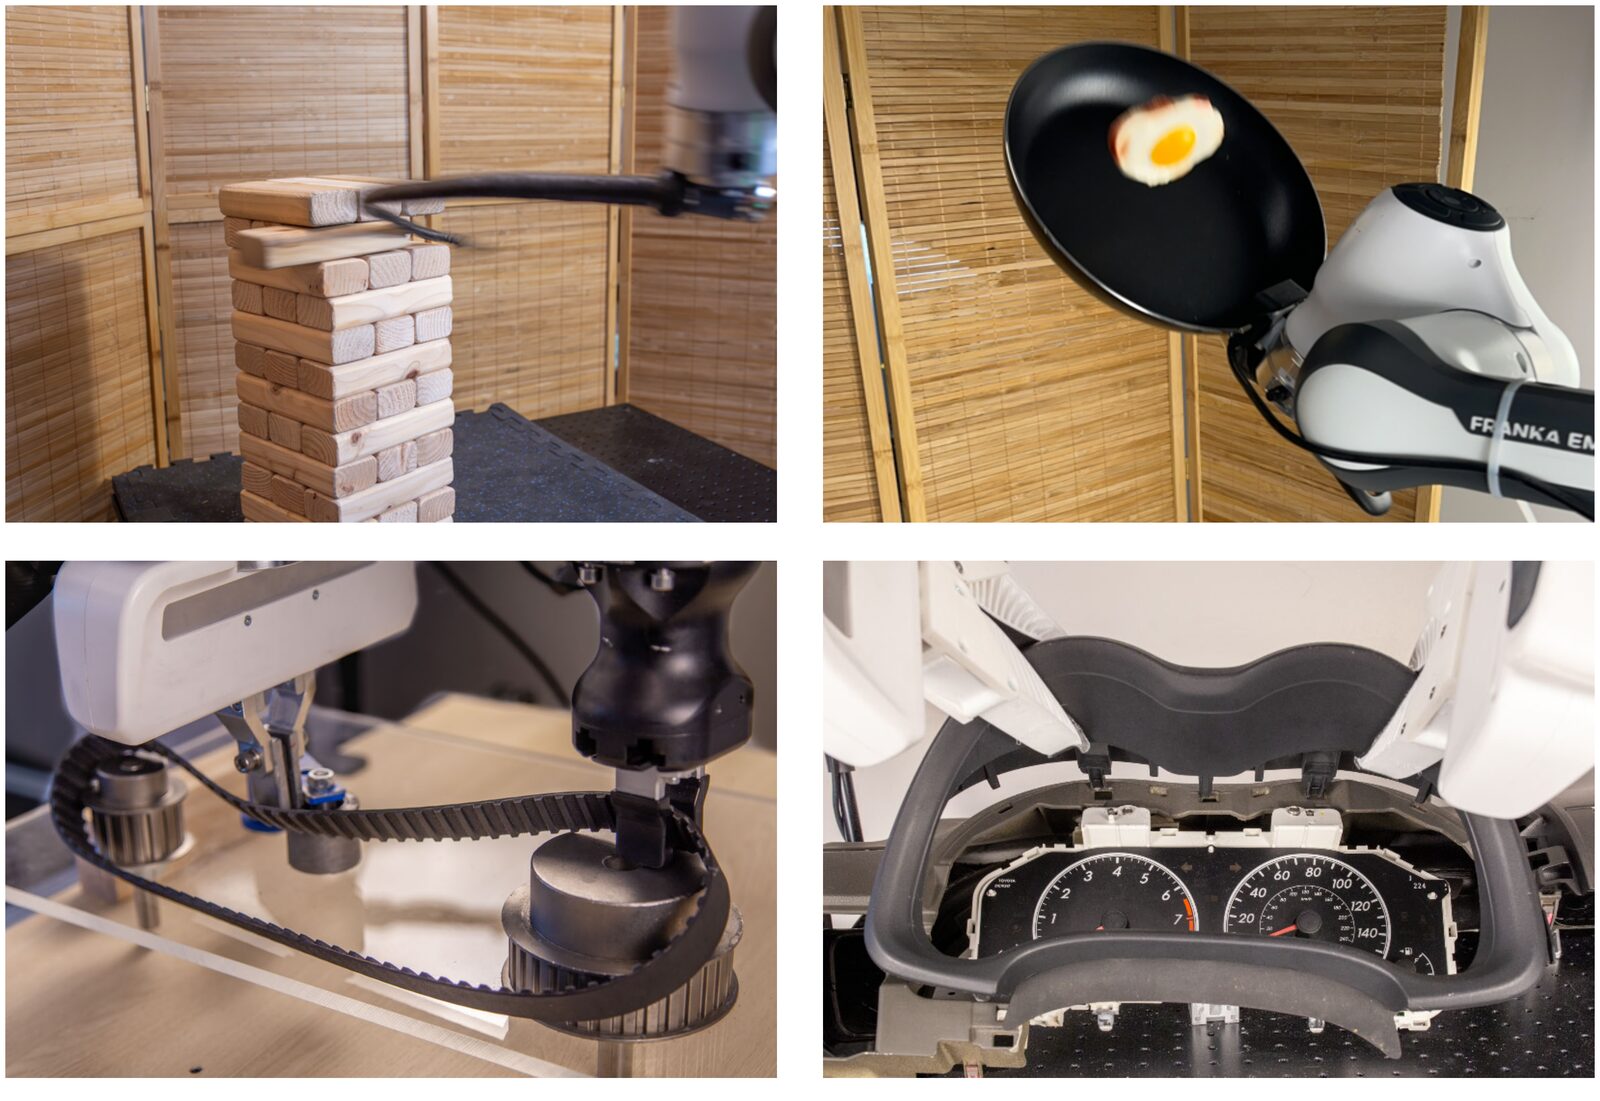
HIL-SERL (Luo et al., Science Robotics 2025) follows SERL, which learned PCB assembly, cable routing and object relocation in 25 to 50 minutes per policySource 29, and uses RLPD, off-policy RL with offline data mixed inSource 30. Intervention transitions enter both the demonstration and RL buffers, autonomous ones only the RL buffer, and training typically starts from 20 to 30 demonstrations; Jenga whipping starts from 30 with no real-time takeoversSource 8.
HIL-SERL completes 100% of observed evaluation trials, 100 per task, except IKEA whole assembly with 10 trials and at most two attempts per sub-policy. Training takes 1 to 2.5 hours for nearly all tasks and 6 for timing-belt assembly, including scripted motion, rollouts, intended stops and computation. Against HG-DAgger with matched episodes and interventions, average success is 49.7% versus 100% and cycle time 9.6 versus 5.4 secondsSource 8.
Online learning curves can include human-assisted successes, the paper reports DP's dashboard-assembly success as both 18% and 28%, and Luo and colleagues did not test unstructured environments or extensive randomizationSource 8. The RL for Robotics module covers the off-policy context, and parallel simulation RL the simulation route.
Mulligan (Stanford, October 2026) starts each round of supervised collection at the initial states where the policy failed or has not been tried; with value-based action selection, it raised final-round success on three real tasks by 10 to 34 percentage points over HG-DAgger, scored on 2,550 held-out, blinded episodesSource 38.
Residual RL and distillation back into the generalist
Residual RL adds a learned correction to a fixed controllerSource 31. PLD (Probe, Learn, Distill; Xiao et al., 2025) freezes a VLA, trains task-specific residual actors with off-policy RL, lets them recover from the states the base policy reaches, and distills the trajectories back into the generalist through SFT. Residual exploration carries no safety guaranteeSource 9.
On LIBERO, averages are 99.2% for the model labelled OpenVLA against 91.8% for its baseline, and 97.2% against 93.4% for π0. On a four-task SimplerEnv suite, Octo-SFT rises from 71.8% to 96.6% and the WidowX carrot task from 43.3% to 93.9%; the printed average delta is +24.9, though the means differ by 24.8Source 9.
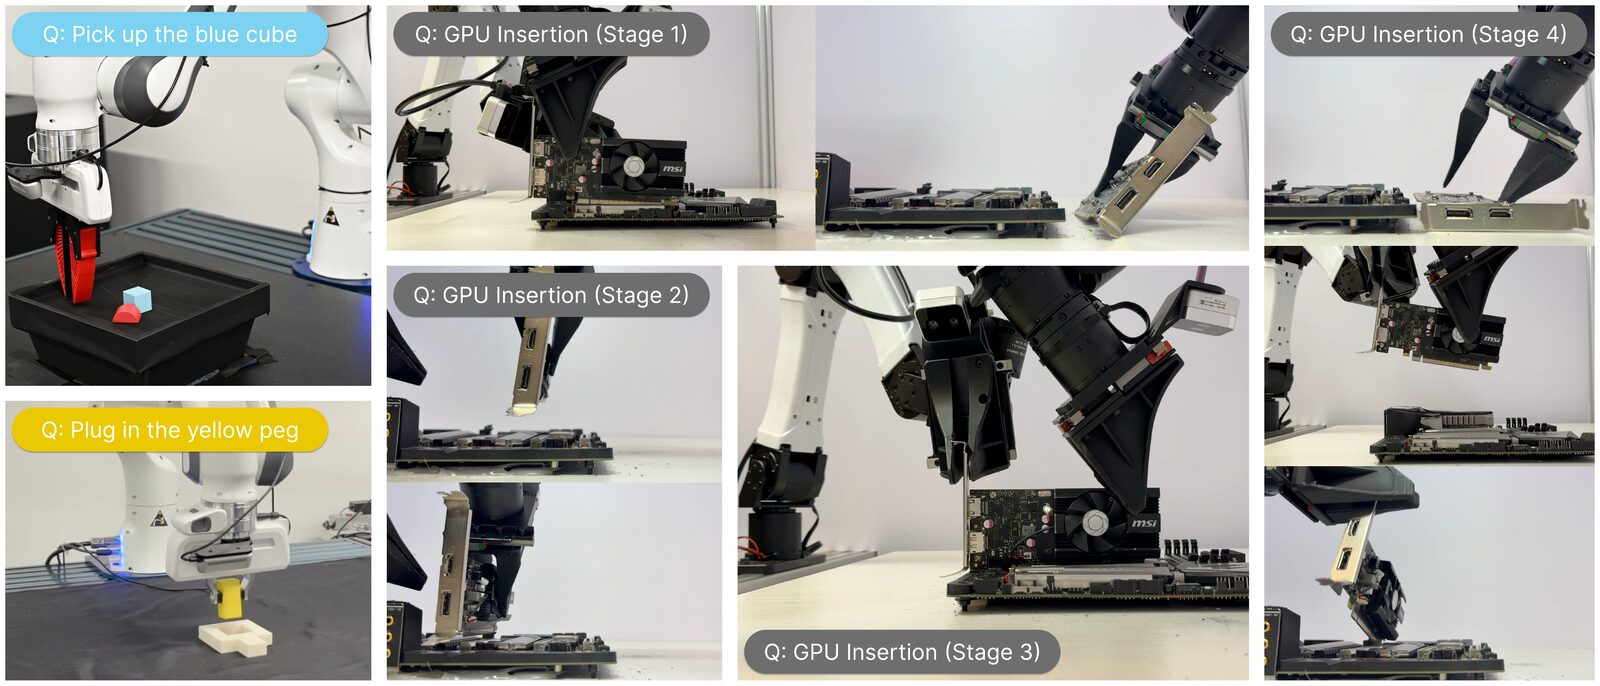
On a Franka, PLD records 30/30 randomized trials for cube pick-up and peg insertion, but 28/30 for a blue cube and 20/30 for a red one under changed clutter. On YAM, four GPU insertion and removal stages distill into one BC policy that runs at least an hour continuously with recovery, though per-stage one-shot success stays below 100%Source 9.
RLDG (Xu et al., 2024) uses HIL-SERL specialists to generate data for fine-tuning OpenVLA and Octo, so the generalist never receives RL updates. In FMB single-object assembly, RL supplies insertion data while humans supply grasping and transport, and OpenVLA succeeds in 20/20 trials against 12/20 with human demonstrationsSource 10. Relabeling suggests action quality, more than state distribution, drives the benefit; the method needs task rewards, speed-optimized RL data can cause premature object drops, and OpenVLA commands actions at 4 Hz while RL runs at 10 HzSource 10.
EXPO-FT: value-guided edits on a frontier VLA
EXPO (Perry Dong, Qiyang Li, Dorsa Sadigh and Chelsea Finn; ICLR 2026) trains a large flow or diffusion base policy with a stable imitation objective plus a lightweight Gaussian edit policy that nudges sampled actions toward higher value, avoiding gradients through the denoising chain, and reports up to 2 to 3× better sample efficiency on averageSource 14.
EXPO-FT, from Dong, Kuo-Han Hung, Tian Gao, Sadigh and Finn, extends EXPO to VLA action chunks and human teleoperation corrections on π0.5. Tasks the base cannot do zero-shot get imitation fine-tuning to around 40% success or above before online RL, and sparse binary rewards come from rule-based detectors over 95% accurate. It reports 30/30 on every evaluated task within an average of 19.1 minutes of online robot data across eight task variantsSource 13.
EXPO-FT vs four other methods
One method succeeded every time on all four tasks
How this was made
Each bar counts successful trials out of 30 on one task, from the comparison table in the EXPO-FT paper (Dong et al., 2026). No value is derived or interpolated.
- SFT on π0.5: supervised finetuning, which copies demonstrations; it is the starting checkpoint EXPO-FT itself begins from.
- HG-DAgger: a person takes over when the robot goes wrong, and the robot learns to copy those corrections.
- DSRL: keeps the base policy frozen and runs reinforcement learning over the noise it starts from.
- HIL-SERL: reinforcement learning on the robot from demonstrations, its own tries and human corrections.
- EXPO-FT: reinforcement learning on π0.5 action chunks, where a small edit policy nudges sampled actions toward higher value, with human teleoperation corrections during online training.
On the four shared comparison tasks EXPO-FT completes 30 of 30 trials on every task, against average successes of 18.8 for supervised finetuning, 20.5 for HG-DAgger, 19 for DSRL and 5.5 for HIL-SERL; the same paper notes HIL-SERL is highly reliable in its original evaluations and that this suite randomizes a substantially larger initial-state space, and with extra training samples HIL-SERL reaches 27 of 30 on Cube Pick and 13 of 30 on Pool Shot.
Per-task successes out of 30
| task | SFT on π0.5 | HG-DAgger | DSRL | HIL-SERL | EXPO-FT |
|---|---|---|---|---|---|
| Egg Flip | 16/30 | 18/30 | 15/30 | 13/30 | 30/30 |
| Cube Pick | 22/30 | 26/30 | 24/30 | 0/30 | 30/30 |
| Pool Shot | 23/30 | 14/30 | 25/30 | 1/30 | 30/30 |
| Flower Insertion | 14/30 | 24/30 | 12/30 | 8/30 | 30/30 |
Counts from the EXPO-FT paper's four-task comparison (Dong 2026).
The paper calls HIL-SERL highly reliable in its original evaluations; this suite randomizes a much larger initial-state space, and the standard budget was too small for learning to start on Cube Pick and Pool Shot. With extra samples, HIL-SERL reaches 27/30 and 13/30 thereSource 13 Source 8.
DSRL keeps the base policy frozen and runs RL over its latent-noise spaceSource 15. Dong and Finn argue it has a ceiling: "If the skill a robot needs isn't already somewhere in what the base model learned during pretraining, no amount of noise-searching will produce the action ...". DSRL averages 19/30 in their comparisonSource 17 Source 13.
Frozen base policy
Steering the noise finds only actions the policy already makes
What RL may change
Dark strip: every place the frozen cam can put the pegSteered noise only · peg lands short
Schematic: an illustrative cam, hole and edit; nothing is measured
How this was made
A diffusion or flow policy turns a noise sample into an action. DSRL keeps the pretrained policy frozen and runs RL over that noise. Dong and Finn give the cost: whatever noise is chosen, the result is still an action the model already knows how to produce, so a skill the model never learned cannot be found that way. EXPO instead pairs the base policy with a lightweight edit policy that shifts actions toward higher value, keeping each edit small, and the base keeps training on the edited actions that worked.
The drawing is that difference on a cam bench. The frozen cam is the base policy and the dial on the stand at the front, belted to the camshaft, is its noise. The follower rides the cam and pushes the slide, so the follower's place is the action: whatever the dial reads, the lit peg lands on the darker strip in the fixture plate, between the cam's lowest and highest lift. The hole the task needs is just past the strip. With the micrometer locked (noise only), the best the search can do is turn the cam's nose to the follower, and the peg still drops short. With the edit free, the same setting plus a small turn of the micrometer moves the peg past the strip and into the hole.
Schematic: one action, an illustrative cam, hole and edit, and no number is measured. In Dong and colleagues' comparison on six real tasks, EXPO-FT reached 30 of 30 trials on average, where DSRL averaged 19 of 30.
Wagenmaker and colleagues, DSRL (2025); Dong and colleagues, EXPO (2025) and EXPO-FT (2026); Dong and Finn (2026).
Dong and Finn's September 2026 blog post says: "RL shows incredible promise in training frontier robotics models, but it is not yet a recipe. It's a craft." EXPO-FT still needs a human to define success, reset the scene and intervene, longer horizons strain the value function, and "Nineteen minutes of robot interaction is not nineteen minutes of post-training," because gradient updates dominate wall-clock timeSource 17. Real-Time EXPO-FT lets a lightweight edit policy react to the latest observation while a slow VLA proposes chunks, and on four dynamic real tasks average performance rises from 42% to 97%Source 16; real-time execution covers the latency budgets.
The methods side by side
| Mechanism | Headline result | Openness | |||
|---|---|---|---|---|---|
| DPPO | 2024 | PPO over Gaussian denoising transitions in a two-layer MDP; separate environment and denoising discounts; selected final denoising steps can be fine-tuned | Paper-specific Robomimic comparisons; zero-shot One-leg hardware transfer: 16/20 trials at 10 Hz. Not a universal sample-efficiency or wall-clock winner | preprint | codeDPPO v3 announces a website with code; repository contents, weights and license terms were not inspected. |
| HIL-SERL | 2024 | RLPD with demonstration and online buffers plus human corrections; Jenga whipping uses demonstrations without online corrections | Table 1a: 100% observed success (100 trials/task; IKEA whole assembly 10 trials); 1-2.5 h for nearly all tasks, 6 h for timing belt. Imitation comparison: 49.7% vs 100%, 9.6 s vs 5.4 s | preprint | codeThe retained HIL-SERL body points to accompanying videos and code; its body revision, repository contents, weights and license terms are not independently established here. |
| ConRFT | 2025 | Frozen Octo-small encoders/backbone; consistency action head with BC and Q objectives offline and online, plus human takeovers | Table I: 96.3% mean on 8 Franka tasks, 20 trials/task; 15-90 min online (prose says 45-90); rounded 144% relative gain over offline Cal-ConRFT | preprint | codeConRFT v2 states that videos and code are available on its project site; weights and license terms are not established by the inspected paper. |
| Recap (pi*0.6) | 2025 | Negative remaining-step values with a failure penalty; reward-inclusive advantage is thresholded into a conditioning token. Supervised-style extraction still trains the action expert | Double-espresso throughput >2x versus offline RL + SFT; the paper’s 90%+ summary excludes diverse laundry, and its box chart reports subtask success | vendor-reported | not disclosedInspected Physical Intelligence report, companion blog and model card: checkpoint availability and model-specific license terms are not established. This is not a claim that the model is closed. |
| Residual RL (PLD) | 2025 | Frozen VLA prior, off-policy residual specialists, hybrid recovery-data collection, then SFT of the generalist | OpenVLA-labelled model: 99.2% across 3 LIBERO suites, 50 trials/task; Octo: 96.6% across 4 Simpler tasks; Franka: 30/30 on each of 2 tasks; YAM: at least 1 h with recovery, not 100% one-shot success | preprint | not disclosedThe inspected PLD v1 preprint does not establish a PLD code or weight release; mentions of open-source code refer to baseline models, not PLD release terms. |
| DSRL | 2025 | RL over a frozen diffusion policy's latent-noise space with black-box access to the base policy; base weights stay fixed | 19/30 average on EXPO-FT's four-task comparison; its own evaluation demonstrates real-world autonomous improvement of diffusion policies and pretrained generalists | preprint | not disclosedThe inspected DSRL abstract does not state a code or weight release. |
| pi_RL | 2026 | Online PPO: Flow-Noise uses learned Gaussian transition noise and joint denoising-path likelihood; Flow-SDE uses transition likelihoods in a two-layer MDP | ID gains for pi0/pi0.5 across four simulation benchmarks; OOD gains do not consistently extend to unseen MetaWorld tasks. Separate Franka transfer test; paper-reported code release, not a weight/license claim | preprint | codeThe printed pi_RL v3 paper states a code release; a particular downloadable weight checkpoint and its license are not established. |
| EXPO-FT | 2026 | On-the-fly selection of the value-maximizing candidate between π0.5 action chunks and lightweight Gaussian edits, with human teleoperation corrections during online training | 30/30 successes on every evaluated task, average 19.1 minutes of online robot data (eight task variants); on the four-task comparison, baselines average 5.5-20.5/30 | preprint | codeThe EXPO-FT paper states an open-source codebase release; repository contents, weights and license terms were not inspected. |
The protocols differ too much for a cross-paper ranking. DPPO, ConRFT, EXPO-FT, HIL-SERL and pi_RL state that code is available. The inspected PLD, DSRL and Recap sources establish no code, weight or license releaseSource 2 Source 3 Source 8 Source 4 Source 5 Source 6 Source 7 Source 9 Source 13 Source 15.
Real-world and fleet-scale results
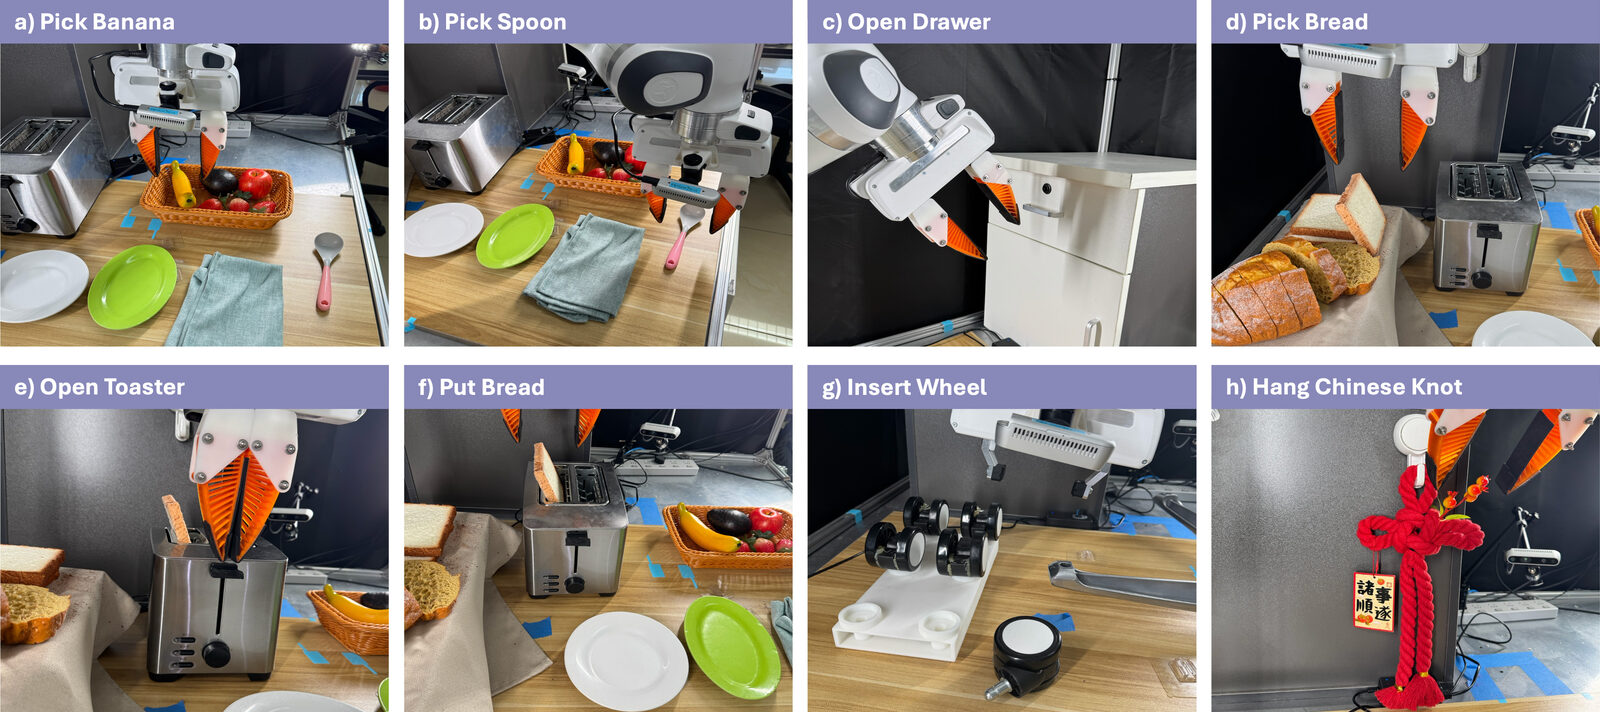
RL-100, published in Science Robotics in July 2026, applies one clipped-PPO objective within the denoising process across offline and online stages and reports 1000 of 1000 successful episodes on eight real tasksSource 32. LWD runs offline-to-online RL on a fleet of 16 dual-arm robots, where one generalist policy reaches 95% average success across eight real tasksSource 33.
What RL buys, with caveats
Liu et al.'s NeurIPS 2025 study finds PPO beats the tested DPO/TPO and GRPO implementations for OpenVLA pick-and-place with sparse task rewards, with stronger semantic and execution generalization than supervised fine-tuning and comparable visual robustness. A September 2025 revision adds appendix tests, and SFT wins the articulated task's visual average and rephrased instructions, and the action-chunking multi-receptacle test; the main-text limitations still say all experiments are simulated pick-and-placeSource 11.
PAIR-VLA adds paired-view invariance and sensitivity objectives to PPO in simulated ManiSkill3 pick-and-place and reports better OOD success than PPO under the tested shifts. The sensitivity-only ablation loses to PPO on target-pose success, the camera-view variant trails PPO slightly in-distribution, the task-preserving views rely on simulator object masks, and real-world transfer is untestedSource 12.
SimpleVLA-RL lifts OpenVLA-OFT's LIBERO average from 91% to 99%Source 34. Reward specification remains open: a benchmark of open and proprietary VLMs as robot reward models finds that no model excels across tasksSource 35. Physical Intelligence says π0.7 runs an espresso machine out of the box at a level matching much more specialized RL-finetuned modelsSource 36.
See also
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
- Massively Parallel Sim RL
GPU-parallel simulation with Isaac Lab, Newton, MJX and Brax.
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
Linked from
- Action Chunking (ACT and ALOHA)
ACT predicts short action sequences and smooths them with temporal ensembling.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Why RL Won Locomotion but Not Manipulation
Walking is cheap to simulate; contact-rich manipulation is not.
- Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
- Offline Reinforcement Learning for Robotics
CQL and TD3+BC, and when behavior cloning is the stronger baseline.
- Competing Theses
Six bets on how robot intelligence gets built.
References
Stéphane Ross, Geoffrey J. Gordon, J. Andrew Bagnell, AISTATS 2011.
https://arxiv.org/abs/1011.0686
Allen Z. Ren, Justin Lidard, Lars L. Ankile, Anthony Simeonov, Pulkit Agrawal, Anirudha Majumdar, and 3 more, 2024.
https://arxiv.org/abs/2409.00588
Yuhui Chen, Shuai Tian, Shugao Liu, Yingting Zhou, Haoran Li, Dongbin Zhao, 2025.
https://arxiv.org/abs/2502.05450
Kang Chen, Zhihao Liu, Tonghe Zhang, Zhen Guo, Si Xu, Hao Lin, and 10 more, 2026.
https://arxiv.org/abs/2510.25889
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/download/pistar06.pdf
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/blog/pistar06
Physical Intelligence, 2025.
https://website.pi-asset.com/pi06star/PI06_model_card.pdf
Jianlan Luo, Charles Xu, Jeffrey Wu, Sergey Levine, 2024.
https://arxiv.org/abs/2410.21845
Wenli Xiao, Haotian Lin, Andy Peng, Haoru Xue, Tairan He, Yuqi Xie, and 6 more, 2025.
https://arxiv.org/abs/2511.00091
Charles Xu, Qiyang Li, Jianlan Luo, Sergey Levine, 2024.
https://arxiv.org/abs/2412.09858
Jijia Liu, Feng Gao, Bingwen Wei, Xinlei Chen, Qingmin Liao, Yi Wu, and 2 more, NeurIPS 2025.
https://arxiv.org/abs/2505.19789
Yuanfang Peng, Jingjing Fu, Chuheng Zhang, Li Zhao, Jiang Bian, Mingyu Liu, and 3 more, 2026.
https://arxiv.org/abs/2605.13105
Perry Dong, Kuo-Han Hung, Tian Gao, Dorsa Sadigh, Chelsea Finn, 2026.
https://arxiv.org/abs/2605.25477
Perry Dong, Qiyang Li, Dorsa Sadigh, Chelsea Finn, 2025.
https://arxiv.org/abs/2507.07986
Andrew Wagenmaker, Mitsuhiko Nakamoto, Yunchu Zhang, Seohong Park, Waleed Yagoub, Anusha Nagabandi, and 2 more, 2025.
https://arxiv.org/abs/2506.15799
Perry Dong, Kuo-Han Hung, Dorsa Sadigh, Chelsea Finn, 2026.
https://arxiv.org/abs/2609.18207
Perry Dong, Chelsea Finn, 2026.
https://pd-perry.github.io/posts/post-training.html
John Schulman, Filip Wolski, Prafulla Dhariwal, Alec Radford, Oleg Klimov, 2017.
https://arxiv.org/abs/1707.06347
Yaron Lipman, Ricky T. Q. Chen, Heli Ben-Hamu, Maximilian Nickel, Matt Le, 2022.
https://arxiv.org/abs/2210.02747
Yanjiang Guo, Jianke Zhang, Xiaoyu Chen, Xiang Ji, Yen-Jen Wang, Yucheng Hu, and 1 more, ICRA 2025.
https://arxiv.org/abs/2501.16664
Kevin Black, Michael Janner, Yilun Du, Ilya Kostrikov, Sergey Levine, 2023.
https://arxiv.org/abs/2305.13301
Tonghe Zhang, Chao Yu, Sichang Su, Yu Wang, 2025.
https://arxiv.org/abs/2505.22094
David McAllister, Songwei Ge, Brent Yi, Chung Min Kim, Ethan Weber, Hongsuk Choi, and 2 more, 2025.
https://arxiv.org/abs/2507.21053
Aaditya Prasad, Kevin Lin, Jimmy Wu, Linqi Zhou, Jeannette Bohg, 2024.
https://arxiv.org/abs/2405.07503
Max Sobol Mark, Tian Gao, Georgia Gabriela Sampaio, Mohan Kumar Srirama, Archit Sharma, Chelsea Finn, and 1 more, 2024.
https://arxiv.org/abs/2412.06685
Xue Bin Peng, Aviral Kumar, Grace Zhang, Sergey Levine, 2019.
https://arxiv.org/abs/1910.00177
Charles Xu, Jost Tobias Springenberg, Michael Equi, Ali Amin, Adnan Esmail, Sergey Levine, and 1 more, Physical Intelligence, 2026.
https://www.pi.website/research/rlt
Jianlan Luo, Zheyuan Hu, Charles Xu, You Liang Tan, Jacob Berg, Archit Sharma, and 4 more, ICRA 2024.
https://arxiv.org/abs/2401.16013
Philip J. Ball, Laura Smith, Ilya Kostrikov, Sergey Levine, ICML 2023.
https://arxiv.org/abs/2302.02948
Tobias Johannink, Shikhar Bahl, Ashvin Nair, Jianlan Luo, Avinash Kumar, Matthias Loskyll, and 3 more, 2018.
https://arxiv.org/abs/1812.03201
Kun Lei, Huanyu Li, Dongjie Yu, Zhenyu Wei, Lingxiao Guo, Zhennan Jiang, and 3 more, 2025.
https://arxiv.org/abs/2510.14830
Yi Wang, Xinchen Li, Pengwei Xie, Pu Yang, Buqing Nie, Yunuo Cai, and 10 more, 2026.
https://arxiv.org/abs/2605.00416
Haozhan Li, Yuxin Zuo, Jiale Yu, Yuhao Zhang, Zhaohui Yang, Kaiyan Zhang, and 15 more, 2025.
https://arxiv.org/abs/2509.09674
Tony Lee, Andrew Wagenmaker, Karl Pertsch, Percy Liang, Sergey Levine, Chelsea Finn, 2026.
https://arxiv.org/abs/2601.00675
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Chung Min Kim, Brent Yi, David McAllister, Hongsuk Choi, Himanshu Gaurav Singh, Jinkun Cao, and 4 more, 2026.
https://arxiv.org/abs/2610.08789
Lars Ankile, Perry Dong, Rohan Bhowmik, Aneesh Muppidi, David D. Yuan, Shuran Song, and 1 more, 2026.
https://arxiv.org/abs/2610.05882
Further reading
Seungeun Rho, Wontaek Kim, Danfei Xu, Sehoon Ha, 2026.
https://arxiv.org/abs/2609.40165
Zhihong Shao, Peiyi Wang, Qihao Zhu, Runxin Xu, Junxiao Song, Xiao Bi, and 5 more, 2024.
https://arxiv.org/abs/2402.03300
Mingjie Pan, Siyuan Feng, Qinglin Zhang, Xinchen Li, Jianheng Song, Chendi Qu, and 6 more, 2026.
https://arxiv.org/abs/2601.03044
Saksham Singh, Zheyuan Hu, Max Sobol Mark, Jeffrey Yu, Zackory Erickson, Aviral Kumar, 2026.
https://arxiv.org/abs/2609.22085
Wenli Xiao, Jia Xie, Tonghe Zhang, Haotian Lin, Letian Fu, Haoru Xue, and 11 more, 2026.
https://arxiv.org/abs/2606.19980
Spot a factual error or missing qualification? Report a content correction.