Why RL Won Locomotion but Not Manipulation
Walking is cheap to simulate; contact-rich manipulation is not.
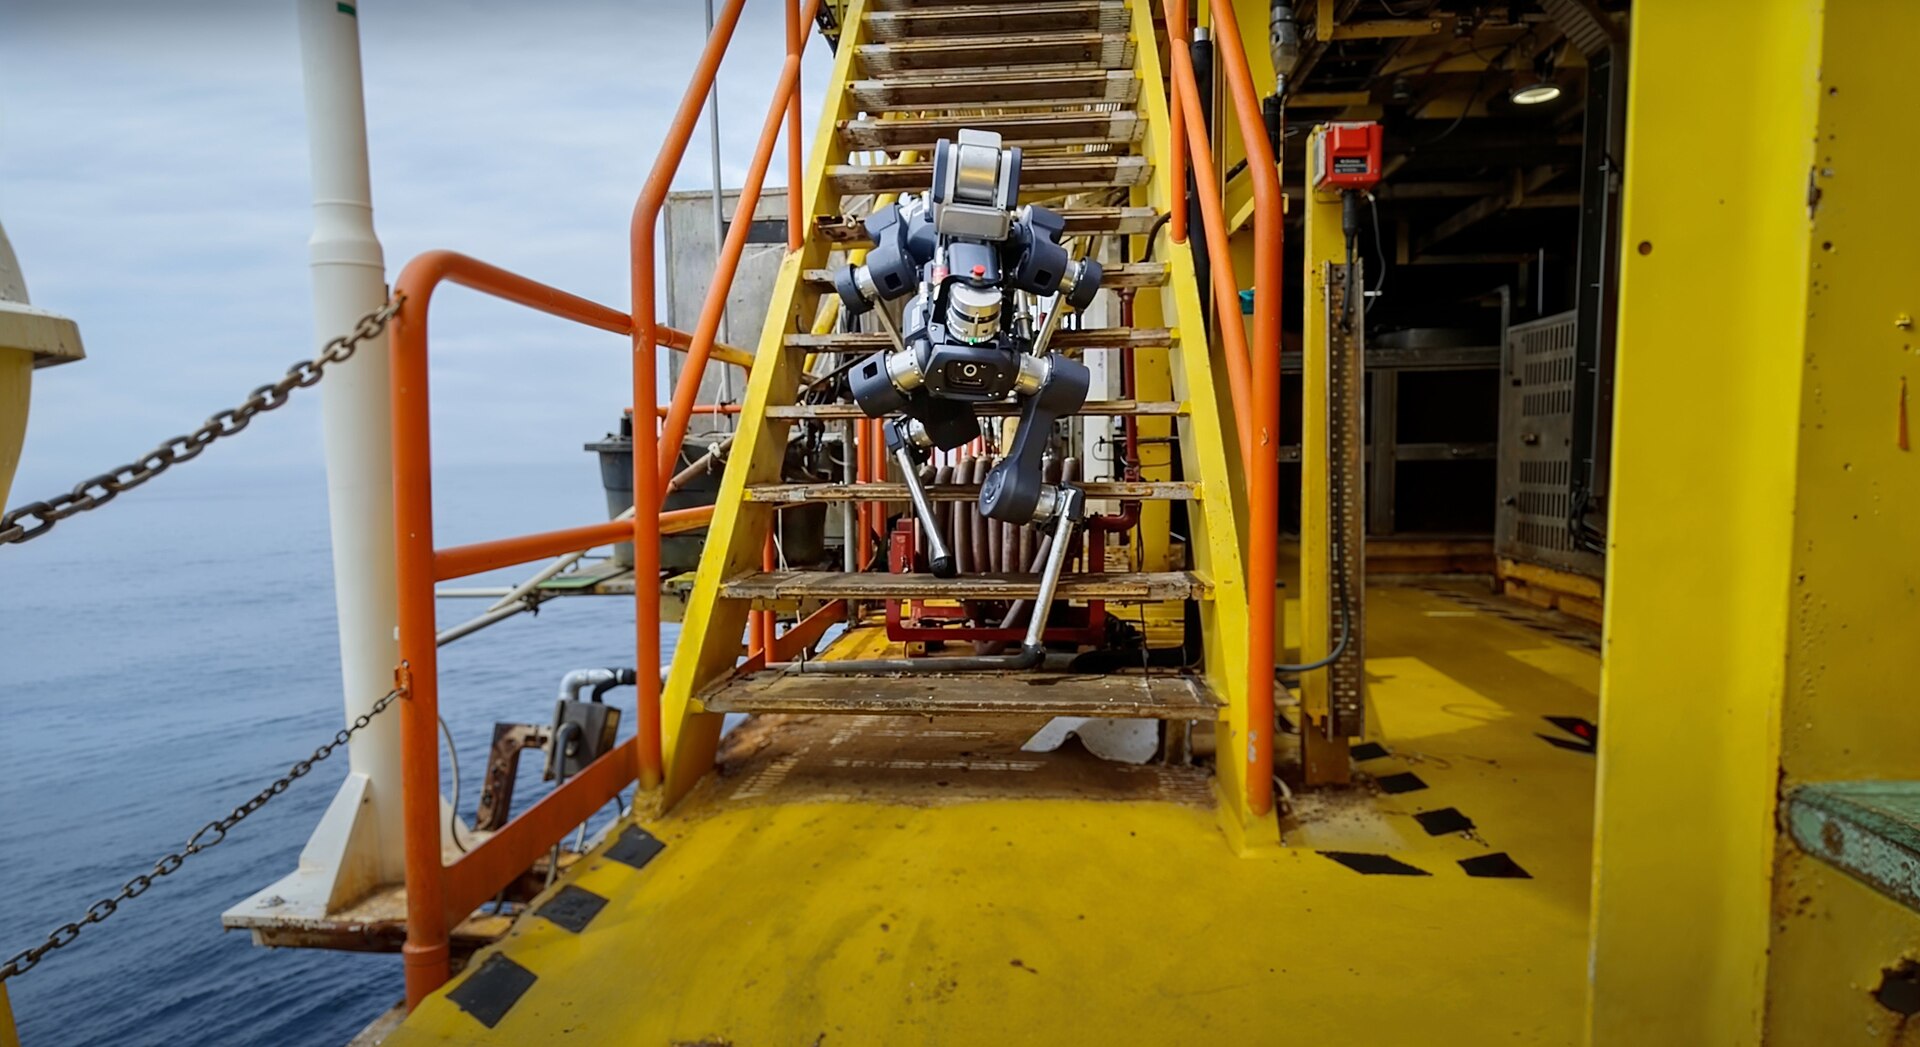
Simulation-trained reinforcement learning (RL) made legged locomotion robust well before general manipulation, because walking is cheap to simulate and contact-rich manipulation is not. In 2021 an ANYmal quadruped learned to walk on flat ground in under four minutes, and on uneven terrain in twenty, on one workstation GPUSource 1.
Contact in simulation
Legs forgive tiny surface errors; precise hand work does not
How wrong the simulator’s surface is
Adjust more
Same 2 mm error: the dog keeps walking, the peg misses the holeOne 2.0 mm error · legs reach · peg jams
Illustrative, not measured; gaps drawn larger than real
How this was made
Both fixtures take the same contact-model error, epsilon: how far the simulator’s idea of a surface is from the real one. The drawing is a test bench. One knob at its front sets the error: its shaft runs along the bench to a gearbox at each fixture, so the same turn lowers the floor and moves the hole. At the left a four-legged robot stands with its hind feet on a deck, where the simulator puts the floor, and steps its front feet down to a lift plate, the real floor, which a screw jack lowers by the error; the legs reach it until the drop passes the 20 mm a gait absorbs, and past that the robot pitches forward onto the plate. At the right a gripper lowers the lit peg where the simulator puts the hole, and a cross-slide moves the real hole by the same error. A ruler at each station reads its gap, the tolerance marked by the longest tick. Gaps are drawn larger than real so a couple of millimetres shows at all: the floor at 0.55 drawing units a millimetre, the hole at 6, whose shift stops growing at four clearances. The slider under “Adjust more” sets any error from 0 to 30 mm, and each change runs the test again.
Exact error: 2.0 mm
- Locomotion: stable: all 4 feet loaded; 4 contacts, patch r ≤ 5 mm, near-point, tolerance ±20 mm. Quadruped stance: four near-point foot-ground contacts on a rigid substrate.
- Manipulation: jammed: peg binds against the wall; 14 contacts, patch r ≤ 0.2 mm, distributed, tolerance ±0.5 mm. Peg insertion: 14 simultaneous contacts across walls, rim, chamfer, and grip pads.
The contact counts and patch radii are illustrative, not one simulator’s solver output; the 20 mm walking tolerance and the 0.5 mm insertion clearance are representative physical scales.
Locomotion at 2.0 mm of contact-model error stays stable: all 4 paws stay loaded as the front pair steps down to the real floor, inside the 20 mm a gait absorbs, with 18.0 mm of margin left. The peg at the same error jams on the edge of the real hole, past its 0.5 mm clearance, so its 14 distributed contacts cannot absorb millimetres the way a gait can.
Current contact-model error
- error
- 2.0 mm
- walking
- stable: all 4 feet loaded
- walking tolerance
- 20 mm
- peg insertion
- jammed: peg binds against the wall
- insertion clearance
- 0.5 mm
Illustrative contact counts and patch radii, not one simulator's solver output; tolerances are representative physical scales.
< 4 min
Flat-terrain walk
sim RL training, one workstation GPU
20 min
Uneven terrain
ANYmal, game-inspired curriculum
32-92%
GR2 multi-finger tasks
success spread, Gemini Robotics 2
60%
Sim-to-real insertion
Play2Perfect, 0.5 mm clearance (CoRL 2026)
The asymmetry is in the MDP
Legged RL left simulation in 2019, when Hwangbo and colleagues transferred trained policies to ANYmalSource 8. Lee and colleagues' proprioceptive controller then held up in natural environmentsSource 9, RMA ran on an A1 without fine-tuningSource 10, and an off-policy recipe now trains humanoid locomotion in 15 minutes on one RTX 4090Source 11.
Boston Dynamics says RL helps where conditions are easy to simulate but good strategies are hard to describeSource 12. Rudin and colleagues' policy observes proprioception and 108 terrain-height samples, and a learned network models ANYmal's series-elastic actuators, which are hard to simulateSource 1. Contact-rich manipulation is harder: the 2026 reality-gap survey notes that most simulators assume rigid bodies while real objects deform, that perfect fidelity is computationally infeasible, and that simplified contact models are particularly problematic in contact-rich tasksSource 2. Tang and colleagues blame the cost of physical interaction for RL's difficulty in roboticsSource 13.
Locomotion papers combine PPO, domain randomization and a curriculum. Manipulation papers more often learn from real demonstrations, which need no contact model: Diffusion Policy beat prior methods by 46.9% on average across 12 tasksSource 14, and ACT learned to slot a battery at 80 to 90% success from 10 minutes of demonstrationsSource 15.
Two training recipes
Real demonstrations need no contact model
Train the policy from
Schematic; examples cited
How this was made
Locomotion papers read PPO, domain randomization and curriculum: the policy learns by trial and error in a simulator, against the simulator's model of contact. The 2026 reality-gap survey calls mismatches from simplified contact models particularly problematic in contact-rich tasks. Many manipulation papers learn instead from real demonstrations, which need no contact model.
The pipeline is a schematic. The examples are the article's: Rudin and colleagues' ANYmal walked on flat ground after under four minutes of simulated training, and ACT slotted a battery at 80 to 90% success from 10 minutes of demonstrations.
Trained by reinforcement learning in a simulator, the policy learns against an approximate contact model whose errors reach the real robot, as when ANYmal learned to walk on flat ground in under 4 minutes of simulated training; copied from real demonstrations, it needs no contact model, as when ACT slotted a battery 80 to 90% of the time after 10 minutes of demonstrations.
What each recipe needs from a contact model
| train the policy from | needs a contact model | example |
|---|---|---|
| Simulation, with RL | yes | ANYmal walked on flat ground after under 4 minutes of training |
| Real demonstrations | no | ACT slotted a battery 80 to 90% of the time after 10 minutes of demonstrations |
Six properties of the two MDPs
| MDP property | Locomotion | Manipulation |
|---|---|---|
| Observation sufficiency | Proprioception (joint positions and velocities, IMU) plus an optional terrain heightscan is nearly sufficient; body state is directly measured. | Object pose, geometry, mass, friction, and deformability are not measured; they must be inferred from pixels. |
| Contact structure | A small number of near-point foot-ground contacts, mostly against a rigid, high-friction substrate. | Many simultaneous, geometrically intricate contacts between non-convex parts at tight tolerance. |
| Sensitivity to contact-model error | High-bandwidth feedback (50-1000 Hz) and a stable gait attractor absorb modeling error. | Insertion and assembly failures are irreversible on a millimeter scale; the policy cannot recover into an attractor. |
| Reward density | Dense: track a commanded body velocity. | Sparse: did the connector seat? |
| Environment authoring cost | Terrain is procedurally generated heightfields, essentially free. | Every task needs new assets with correct physics parameters; "SimReady asset" pipelines exist as a commercial category for this reason. |
| Episode reset | Free in simulation, cheap on hardware. | Real resets need a human or a second robot. |
Boston Dynamics builds Atlas from rotary actuators that are "much easier to represent well in simulation"Source 16, and NVIDIA's SimReady asset standard specifies mass, friction, inertia, collision and articulation limitsSource 17. Isaac Lab calls multi-fingered manipulation harder than parallel-jaw graspingSource 3, and Lin and colleagues find sim-to-real dexterous RL still largely limited to single-hand or state-based setupsSource 4.
Contact geometry is where the gap lives
A gait recovers from a wrong contact force on the next step; a jammed peg cannot. Acosta and colleagues call dynamic contact the computational bottleneck for most simulations, and three simulators they tested missed elastic impactsSource 18. Rigid-body contact models have a task-specific accuracy ceilingSource 19, and Factory, which simulates 1000 nut-and-bolt interactions at once, still calls assembly contact a longstanding challengeSource 20.
Exceptions in manipulation
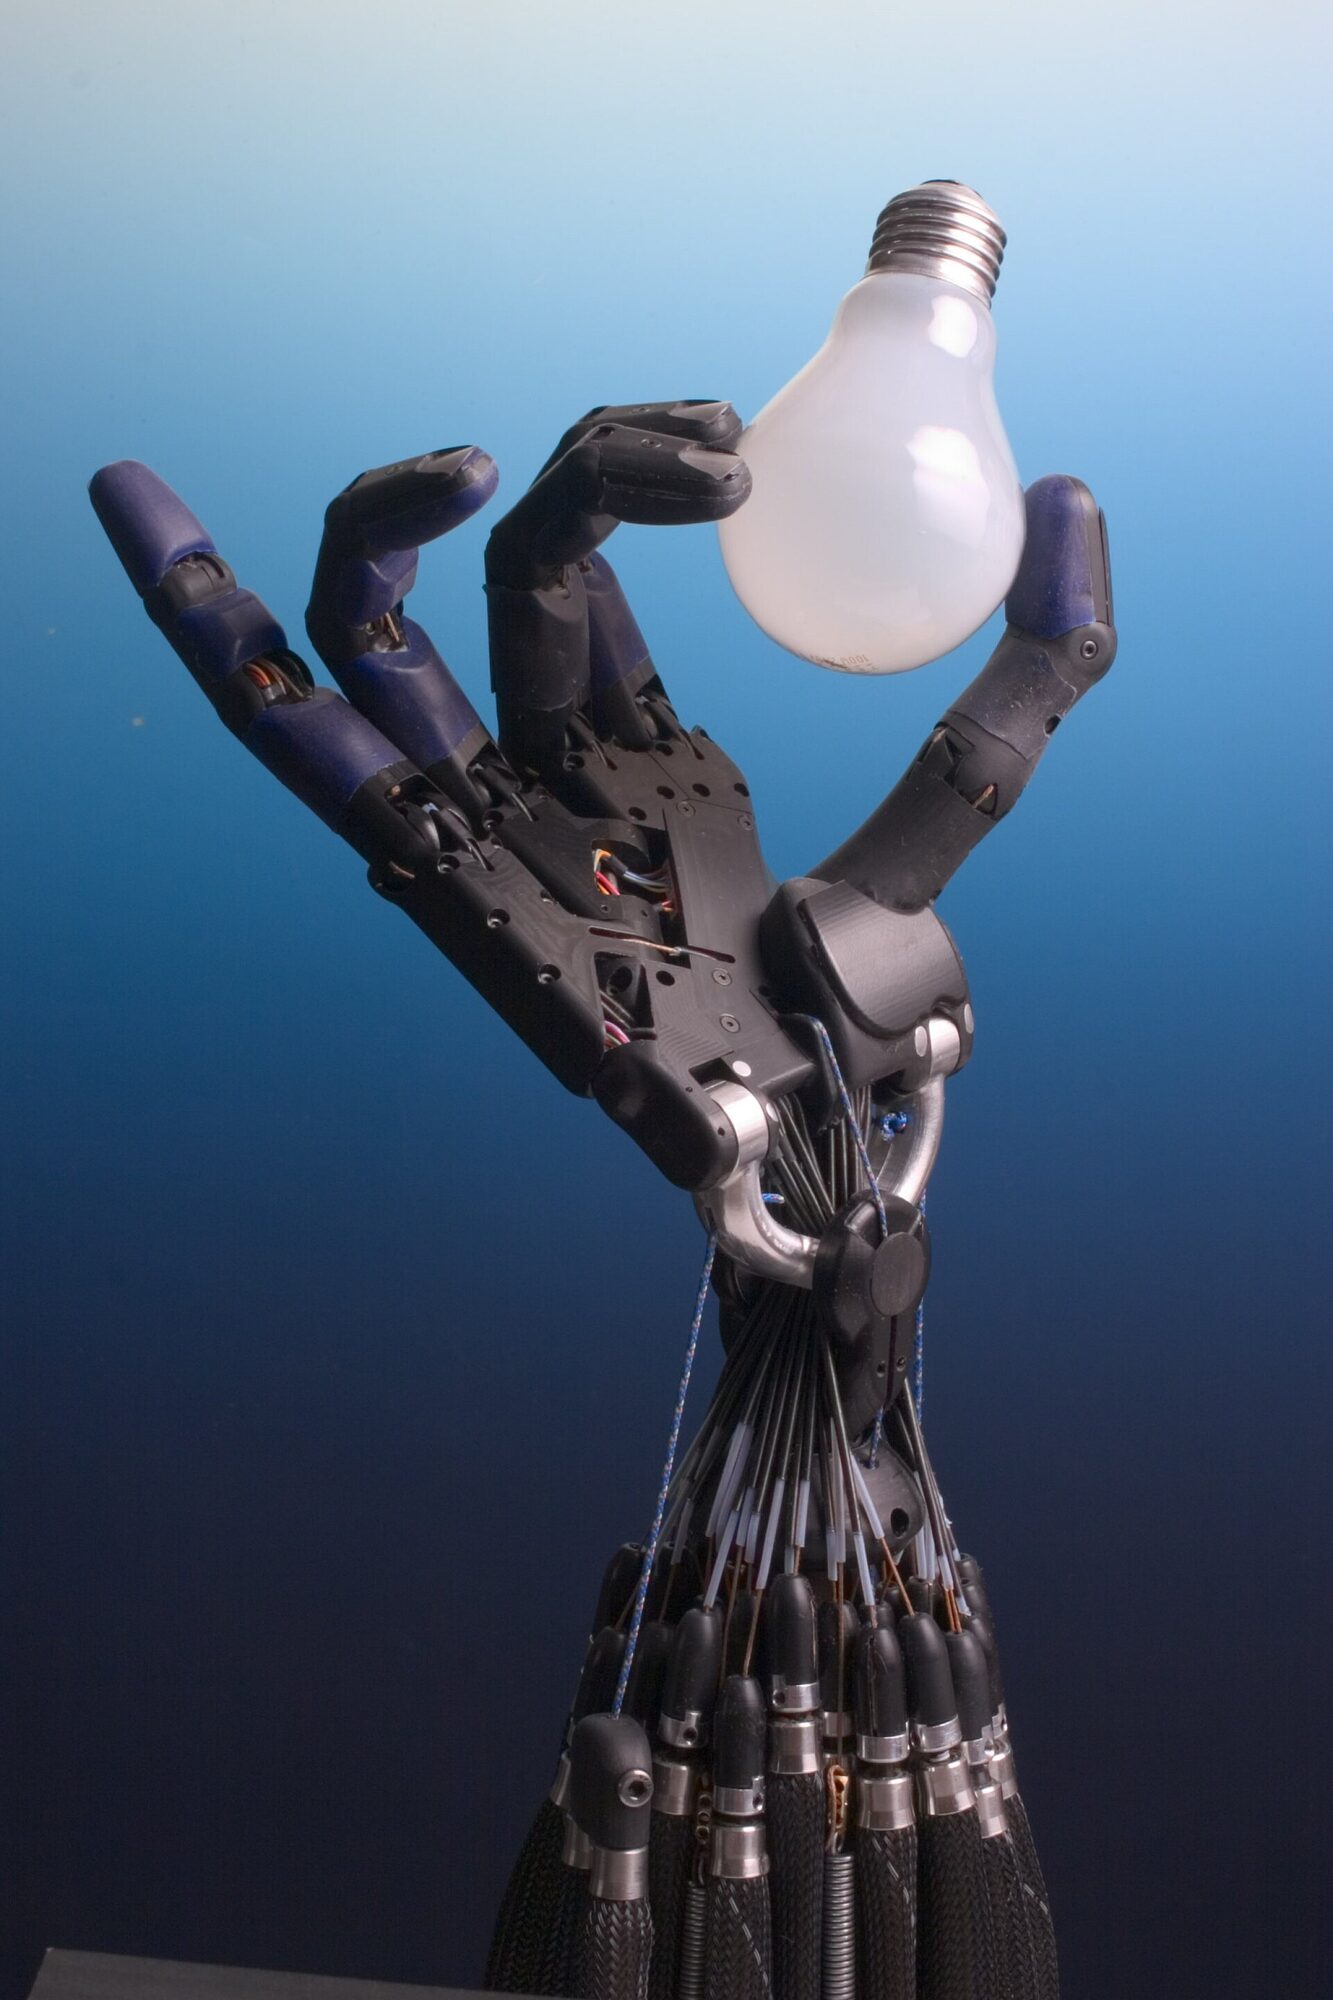
OpenAI's in-hand policy learned finger gaiting without human demonstrationsSource 21. Its Rubik's-cube successor, trained with automatic domain randomization, solved one fixed 43-subgoal scramble in two of ten trials with a sensor cube and zero of ten with vision for face angles, on customized hardware with tuned torque limits and a calibrated hand simulationSource 5. Visual Dexterity reorients novel shapes in a median of about seven seconds on hardware under $5,000Source 22, and DextrAH-RGB transfers an end-to-end RGB grasping policySource 23, distilled from a privileged teacher into a stereo-RGB student for a KUKA arm and Allegro handSource 3.
Sim-trained dexterity
The cube-solving hand finished at most 2 of 10 trials
The cube's face angles read by
How this was made
OpenAI trained the policy in simulation with automatic domain randomization, for a modified Shadow hand, and ran it on the real hand. With a sensor cube reporting its face angles it completed one fixed 43-subgoal scramble in two of ten trials; with vision for the face angles, in zero of ten. The system used customized hardware, tuned torque limits and a calibrated hand simulation.
Each square is one trial; filled squares are the trials that finished. The squares count, they do not order.
With a sensor cube reporting its face angles, the simulation-trained hand completed the fixed 43-subgoal scramble in 2 of 10 trials, against 0 of 10 with vision reading the face angles.
Trials that finished the scramble
| face angles read by | trials finished (of 10) |
|---|---|
| The cube's own sensors | 2 |
| Cameras | 0 |
In assembly, AutoMate's generalist solves 20 assemblies zero-shotSource 24, Play2Perfect reaches 60% on 0.5 mm-clearance insertionsSource 6, and InsertAnything, trained only on a simulated hexagonal insertion, succeeded on 95.0% of trials across eight unseen real insertion tasksSource 30. SPARR's real-world residual adds 38.4% success over zero-shot transferSource 25.
Such results often need per-task engineering: zero-shot force-controlled dexterous grasping needed tactile simulation, current-to-torque calibration and actuator modelsSource 26. SimToolReal instead trains one policy over procedural tools that transfers zero-shot across 24 real tasksSource 27, and Boston Dynamics says Atlas learned to lift a fridge with perception done implicitly from proprioceptionSource 16.
Imitation-trained baselines
Physical Intelligence reports π0.5 cleaning kitchens and bedrooms in entirely new homesSource 28, and TRI finds that multi-task pretraining raises success and cuts the data a new task needsSource 29. DeepMind's Gemini Robotics 2 reports 32% to 92% success on multi-finger tasksSource 7; humanoid whole-body control has the full results.
See also
- Dexterity
Contact-rich manipulation, touch sensing, in-hand reorientation and deformables.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
Linked from
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Massively Parallel Sim RL
GPU-parallel simulation with Isaac Lab, Newton, MJX and Brax.
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
References
Nikita Rudin, David Hoeller, Philipp Reist, Marco Hutter, CoRL 2021.
https://arxiv.org/abs/2109.11978
Elie Aljalbout, Jiaxu Xing, Angel Romero, Iretiayo Akinola, Caelan Reed Garrett, Eric Heiden, and 6 more, Annual Review of Control, Robotics, and Autonomous Systems 2026 (accepted), 2025.
https://arxiv.org/abs/2510.20808
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
Toru Lin, Kartik Sachdev, Linxi Fan, Jitendra Malik, Yuke Zhu, CoRL 2025.
https://arxiv.org/abs/2502.20396
OpenAI, Ilge Akkaya, Marcin Andrychowicz, Maciek Chociej, Mateusz Litwin, Bob McGrew, and 13 more, 2019.
https://arxiv.org/abs/1910.07113
Tyler Ga Wei Lum, Kushal Kedia, C. Karen Liu, Jeannette Bohg, CoRL 2026.
https://arxiv.org/abs/2606.26428
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Jemin Hwangbo, Joonho Lee, Alexey Dosovitskiy, Dario Bellicoso, Vassilios Tsounis, Vladlen Koltun, and 1 more, Science Robotics 4(26), 2019.
https://arxiv.org/abs/1901.08652
Joonho Lee, Jemin Hwangbo, Lorenz Wellhausen, Vladlen Koltun, Marco Hutter, Science Robotics 5(47), 2020.
https://arxiv.org/abs/2010.11251
Ashish Kumar, Zipeng Fu, Deepak Pathak, Jitendra Malik, RSS 2021.
https://arxiv.org/abs/2107.04034
Younggyo Seo, Carmelo Sferrazza, Juyue Chen, Guanya Shi, Rocky Duan, Pieter Abbeel, 2025.
https://arxiv.org/abs/2512.01996
Boston Dynamics, 2024.
https://bostondynamics.com/blog/starting-on-the-right-foot-with-reinforcement-learning/
Chen Tang, Ben Abbatematteo, Jiaheng Hu, Rohan Chandra, Roberto Martín-Martín, Peter Stone, Annual Review of Control, Robotics, and Autonomous Systems, 2025.
https://doi.org/10.1146/annurev-control-030323-022510
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Alberto Rodriguez, Shane Rozen-Levy, Vinay Kamidi, Boston Dynamics blog, 2026.
https://bostondynamics.com/blog/training-a-humanoid-robot-for-hard-work/
NVIDIA, NVIDIA Glossary, as of 2026-10-04.
https://www.nvidia.com/en-us/glossary/simready/
Brian Acosta, William Yang, Michael Posa, arXiv preprint (IEEE RA-L / IROS 2022), 2021.
https://arxiv.org/abs/2110.00541
Nima Fazeli, Samuel Zapolsky, Evan Drumwright, Alberto Rodriguez, 2017.
https://arxiv.org/abs/1710.04979
Yashraj Narang, Kier Storey, Iretiayo Akinola, Miles Macklin, Philipp Reist, Lukasz Wawrzyniak, and 6 more, Robotics: Science and Systems (RSS) 2022.
https://arxiv.org/abs/2205.03532
OpenAI, Marcin Andrychowicz, Bowen Baker, Maciek Chociej, Rafal Jozefowicz, Bob McGrew, and 11 more, 2018.
https://arxiv.org/abs/1808.00177
Tao Chen, Megha Tippur, Siyang Wu, Vikash Kumar, Edward Adelson, Pulkit Agrawal, arXiv preprint (Science Robotics 2023), 2022.
https://arxiv.org/abs/2211.11744
Ritvik Singh, Arthur Allshire, Ankur Handa, Nathan Ratliff, Karl Van Wyk, 2024.
https://arxiv.org/abs/2412.01791
Bingjie Tang, Iretiayo Akinola, Jie Xu, Bowen Wen, Ankur Handa, Karl Van Wyk, and 4 more, 2024.
https://arxiv.org/abs/2407.08028
Yijie Guo, Iretiayo Akinola, Lars Johannsmeier, Hugo Hadfield, Abhishek Gupta, Yashraj Narang, 2026.
https://arxiv.org/abs/2602.23253
Zhe Zhao, Haoyu Dong, Zhengmao He, Yang Li, Xinyu Yi, Zhibin Li, 2026.
https://arxiv.org/abs/2601.02778
Kushal Kedia, Tyler Ga Wei Lum, Jeannette Bohg, C. Karen Liu, 2026.
https://arxiv.org/abs/2602.16863
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Zhenghua Ma, Xinpan Meng, Zeyu Liu, Muyuan Ma, Hengdi Zhang, Houcheng Li, and 1 more, 2026.
https://arxiv.org/abs/2609.24511
Further reading
Ilija Radosavovic, Tete Xiao, Bike Zhang, Trevor Darrell, Jitendra Malik, Koushil Sreenath, arXiv preprint (Science Robotics 2024), 2023.
https://arxiv.org/abs/2303.03381
Haoru Xue, Tairan He, Zi Wang, Qingwei Ben, Wenli Xiao, Zhengyi Luo, and 6 more, arXiv preprint (CVPR 2026), 2025.
https://arxiv.org/abs/2512.01061
Kun Lei, Huanyu Li, Dongjie Yu, Zhenyu Wei, Lingxiao Guo, Zhennan Jiang, and 3 more, 2025.
https://arxiv.org/abs/2510.14830
Nicklas Hansen, Iretiayo Akinola, Yijie Guo, Jie Xu, Bingjie Tang, Hao Su, and 4 more, IROS 2026.
https://arxiv.org/abs/2609.28258
Spot a factual error or missing qualification? Report a content correction.