Massively Parallel Sim RL
GPU-parallel simulation with Isaac Lab, Newton, MJX and Brax.
Massively parallel simulation is training a robot policy across thousands of simulated copies of its environment at once, with the physics on a GPU. It produced Rudin and colleagues' four-minute ANYmal walking runSource 1, trained with the 2017 PPO algorithmSource 9.
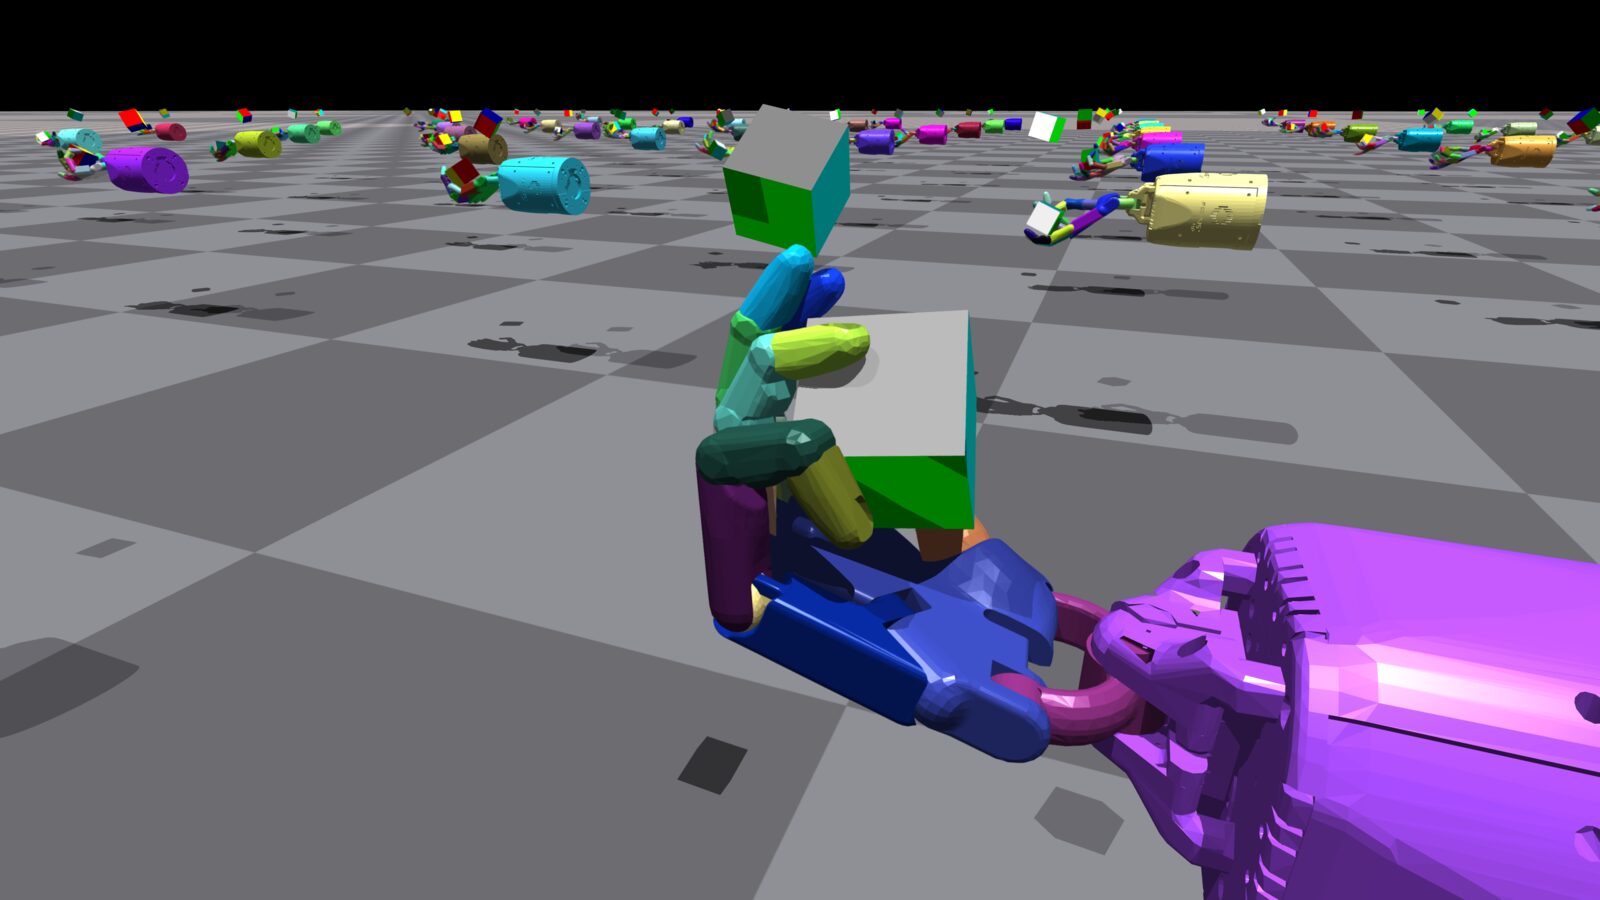
Parallel simulation
Running thousands of copies at once speeds training, with limits
Adjust more
training timewith computer overheadrobots shown
beat 4 / 4 16,384 robots at once: 1.5 minutes of training
An illustrative calculation, not a measured training curve
Robots need huge amounts of practice; a graphics chip running 16,384 virtual robots side by side finishes it in minutes.
How this was made
Both curves hold the amount of practice fixed: the same total number of simulated steps, a fixed-transition budget, however many robots share it. Each training round runs every robot for a short burst, then updates the network once, so more robots means fewer rounds. Each round also carries fixed costs: the learning update, moving data between the graphics chip and the main computer, and the Python loop. The dashed curve adds an assumed cost on the main computer for every robot, which grows with the robot count and flattens the curve.
These are illustrative calculations, not measured training curves: the robot counts, times and the main-computer cost are authored for this lab. The reported Rudin time bounds, their separate protocols and the CPU benchmark that motivates the dashed curve are in the article text. The time axis is logarithmic, from one minute to four hours.
The lab's times along the solid curve: 64 robots, 3.6 hours; 4,096 robots, 4.0 minutes; 16,384 robots, 1.5 minutes. Along the dashed curve: 3.6 hours, 7.3 minutes and 4.8 minutes.
- With 64 virtual robots practising at once, the same amount of practice takes hours.
- With 4,096 robots side by side on one graphics chip, the same practice finishes in minutes.
- Some work for each robot still runs on the main computer, so with that overhead the dashed line flattens.
- Robots need huge amounts of practice; a graphics chip running 16,384 virtual robots side by side finishes it in minutes.
Parallel rollouts change a fixed training budget. Beat 1: With 64 virtual robots practising at once, the same amount of practice takes hours. Beat 2: With 4,096 robots side by side on one graphics chip, the same practice finishes in minutes. Beat 3: Some work for each robot still runs on the main computer, so with that overhead the dashed line flattens. Beat 4: Robots need huge amounts of practice; a graphics chip running 16,384 virtual robots side by side finishes it in minutes.
< 4 min
Flat-terrain walk
Rudin abstract; single GPU, separate flat run
> 900k FPS
DextrAH teacher
initial headless training; 8 RTX PRO 6000 GPUs / 16,384 envs
> 1.6M FPS
Franka cabinet
initial headless training; same reported setup
252x / 475x
MJWarp vs MJX
NVIDIA report: locomotion / manipulation; limits below
The 2021 break: physics moved onto the GPU
Isaac Gym kept physics and policy training on one GPU, passing PhysX buffers straight to PyTorch tensors without CPU round trips. Its authors report 2 to 3 orders of magnitude improvement over a CPU simulator feeding a GPU networkSource 3.
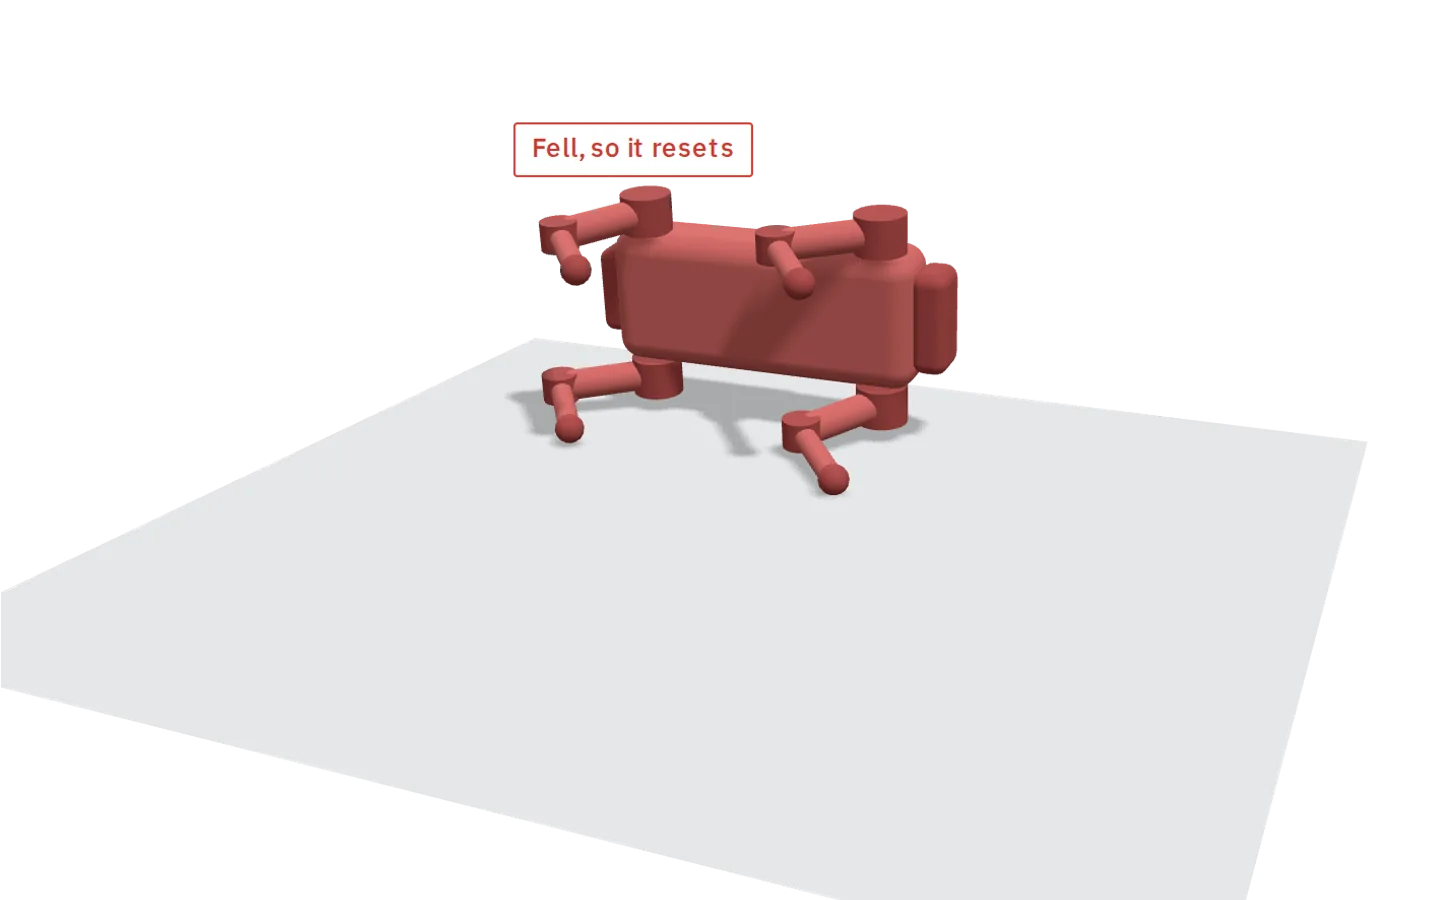
Rudin and colleagues scaled from 128 robots, typical of CPU implementations, to 16,384 on one workstation GPU. Flat terrain took under four minutes and uneven terrain twenty. Their deployment policy used 4,096 robots, 98,304-transition batches (24 steps per robot) and 1,500 updates in under 20 minutes on an i9-11900k CPU and RTX A6000 GPUSource 1. Zoom out in the figure below to see thousands of copies of one robot practise at once, then shuffle their worlds.
How do robots learn to walk without breaking?
Loading…
This robot exists only inside a computer. It tries to walk, falls, starts over and does a little better each time.
Practice in thousands of slightly different simulated worlds makes the real world just one more variation.
How this was made
The steps in words
- This robot exists only inside a computer. It tries to walk, falls, starts over and does a little better each time.
- Now run 4,096 copies at once on one computer. All their tries train one shared brain, so every fall teaches it.
- Make every world a little different: slippery or grippy ground, heavier bodies, random shoves. Shuffle to deal new worlds.
- One tile is the real world. Two robots step onto it: one practised in just one world, the other in all 4,096.
- After thousands of different worlds, the real world is just one more. This is massively parallel simulation with domain randomization.
Massively parallel simulation
One graphics chip trains thousands of robots at once
Robots practising at once
Each lit tile on the chip is 128 robots16,384 robots: 128 times the CPU-era count
Counts from the paper; one tile per 128 robots
How this was made
Isaac Gym kept the physics and the policy training on one GPU, passing simulation buffers straight to the learning code without round trips through the CPU; its authors report 2 to 3 orders of magnitude improvement over a CPU simulator feeding a GPU network. On it, Rudin and colleagues scaled from 128 robots, typical of CPU implementations, to 16,384 on one workstation GPU, and trained their deployment policy with 4,096 robots in under 20 minutes.
The drawing is a graphics card with its cooler set aside. Each of the 128 tiles on its chip stands for 128 robots, so the first tile, under the magnifier, is the CPU-era count and the whole chip is the paper's 16,384. The tiles are a way of counting; a real chip lays out its cores differently.
16,384 simulated robots practise at once, the most on one workstation GPU, which is 128 times the 128 typical of CPU simulators; each square in the grid stands for 128 robots.
Simulated robots at once
| robots at once | times the CPU-era 128 | in the paper |
|---|---|---|
| 128 | 1 | typical of CPU simulators |
| 4,096 | 32 | trained the deployed walking policy in under 20 minutes |
| 16,384 | 128 | the most on one workstation GPU |
Their game-inspired curriculum promotes robots that cross their tile, demotes those covering under half the commanded distance, and loops hardest-level solvers back to a random level, and in this massively parallel regime their PPO bootstraps the critic at time-outsSource 1. The paper's released legged_gym repository (October 2021) is the Isaac Gym environment used to train ANYmal on rough terrainSource 2.
The JAX line: Brax, MJX, MuJoCo Playground
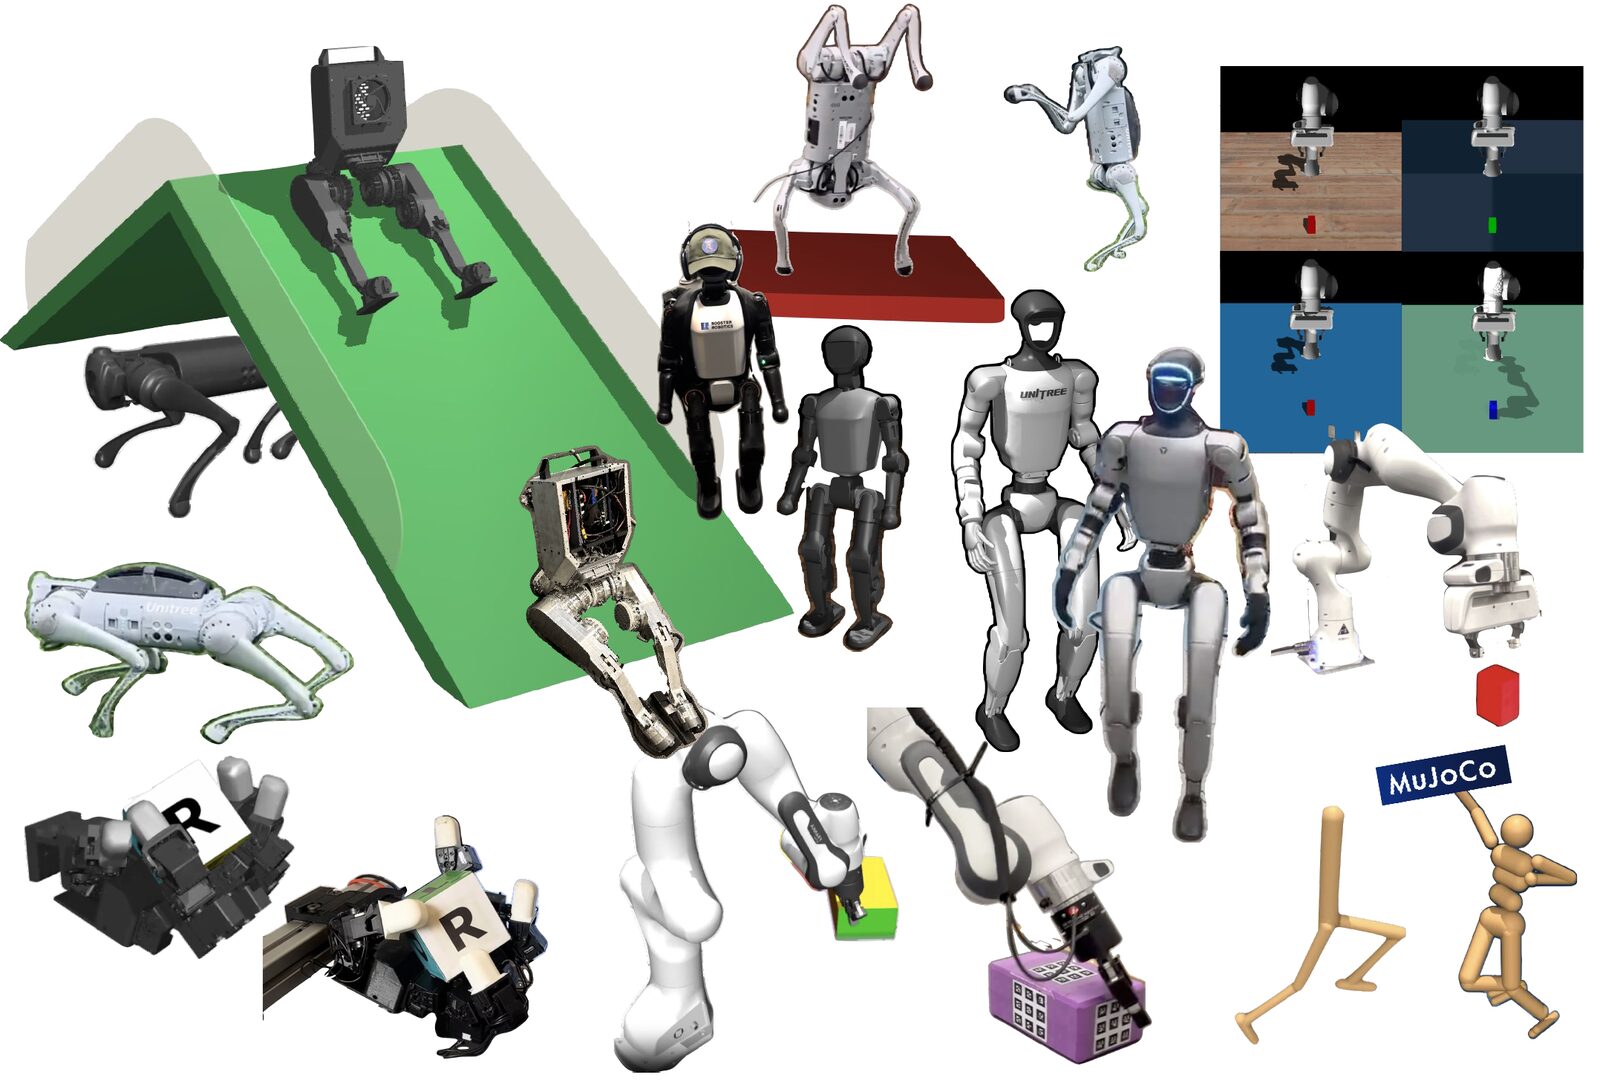
MuJoCo, a physics engine for model-based controlSource 10, has been open source under Google DeepMind since 2022Source 11. Brax (Google, 2021) compiled physics and learning algorithms in JAX on one accelerator, training performant policies on MuJoCo-like tasks in minutesSource 4. MuJoCo XLA (MJX) moved MuJoCo onto the GPU, and MuJoCo Playground (2025) built on it an open framework for quadrupeds, humanoids, hands and arms, aimed at sim-to-real transferSource 5. MJX-Warp, built for NVIDIA GPUs, fixes contact and constraint bottlenecks but lacks automatic differentiationSource 12.
What the environment count actually buys
The opening scene is an illustrative calculation: a fixed 220-million-transition budget, an assumed CPU-cost curve that raises per-iteration costs, and a calibrated near-four-minute time at 4,096 environments. Only Rudin's separate deployment run ties 4,096 robots to a reported boundSource 1.
The curve reflects a bottleneck the Isaac Lab paper reports: on a state-based Franka drawer task, an RTX 5090 workstation nearly matches a server with two RTX PRO 6000 GPUs and two 64-core EPYC 9554 CPUs, a task-dependent result the authors put down to CPU bottlenecks and the workstation's fast single coreSource 6.
Environment count also changes learning: at fixed batch size, more robots cut Rudin's training time but hurt the policy past a pointSource 1. SAPG reports PPO saturating beyond a certain countSource 13, while Beukman and colleagues avoid plateaus with over 1M environments, improving monotonically to one trillion transitionsSource 14.
Isaac Lab and the framework era
Isaac Lab grew out of OrbitSource 6, a 2023 framework on Isaac SimSource 15. Headless state-based training on RTX PRO 6000 GPUs scales "almost perfectly linearly". With eight GPUs and 16,384 environments, the DextrAHSource 16 teacher grasp-and-lift task exceeds 900,000 FPS and Franka cabinet 1.6 million, counting environment steps over simulation plus learning timeSource 6.
NVIDIA's 2026 overview says Isaac Lab 3.0 splits backend code from the core API, so users choose Isaac Sim's PhysX and RTX for sensor-rich work or headless Newton for throughputSource 8. Isaac Lab 3.0 entered early access on 16 September 2026Source 17.
Newton: physics as a multi-solver library
Newton, an open-source GPU physics engine co-developed by Disney Research, Google DeepMind and NVIDIA, joined the Linux Foundation on 29 September 2025Source 18. It generalizes the deprecated warp.sim module of NVIDIA WarpSource 19 and uses MuJoCo Warp as its primary backendSource 20. NVIDIA's 16 March 2026 post announced general availability of Newton 1.0 and called Isaac Sim 6.0 and Isaac Lab 3.0 early access releasesSource 7; Isaac Sim 6.1.0Source 21 and Newton v1.6.0Source 23 followed on 10 September 2026.
Behind one API, NVIDIA's overview lists MuJoCo and Featherstone solvers in generalized coordinates, and SemiImplicit, XPBD and Kamino in maximal coordinates, while VBD (vertex block descentSource 24) handles cloth and soft bodies and implicit MPM handles continuum materialsSource 8.
Multi-solver physics
One physics library, one solver per material
What is being simulated
Schematic; four of eight solvers
How this was made
Newton is an open-source GPU physics engine co-developed by Disney Research, Google DeepMind and NVIDIA, with MuJoCo Warp as its primary backend. NVIDIA's overview lists eight solvers behind one interface: MuJoCo and Featherstone in generalized coordinates; SemiImplicit, XPBD and Kamino in maximal coordinates; VBD for rigid bodies, particles, cloth and soft bodies; implicit MPM for particle-based continuum materials; and Style3D cloth. The release post credits Kamino with closed-chain mechanisms and couples a VBD cable solver two-way with MuJoCo Warp.
The drawing shows four of the eight, one per material. Sand is this figure's example of a particle-based continuum material; the overview does not name it.
Newton routes robot arms and legs to MuJoCo Warp, which handles jointed robots in generalized coordinates, as Newton's primary backend; the drawing shows 4 of the 8 solvers NVIDIA's overview lists behind one interface.
Which solver handles which material
| what is simulated | solver | what the sources say it handles |
|---|---|---|
| Robot arms and legs | MuJoCo Warp | jointed robots in generalized coordinates, as Newton's primary backend |
| Closed-chain linkages | Kamino | closed-chain mechanisms, credited to Disney Research |
| Cloth and cables | VBD | rigid bodies, particles, cloth and soft bodies; the cable solver coupled to MuJoCo Warp |
| Sand-like materials | implicit MPM | particle-based continuum materials |
The post describes SDF collision from CAD meshes and Drake-inspired hydroelastic contact over finite-area patches, and its assembly example sets a plus or minus 10 mm sparse-SDF bandSource 7. Isaac Sim 6.1 added hydroelastic contact, a pressure-field modelSource 25, to its experimental Newton integrationSource 22.
NVIDIA reports that Skild AI trains GPU-rack-assembly RL policies, including connector insertion, with Isaac Lab's Newton backend, SDF and hydroelastic contact, and that Samsung "will use Newton" for synthetic VLA training data; its refrigerator example couples MuJoCo Warp two-way with a VBD cable solver for RB-Y1 cable insertionSource 7. It also reports MuJoCo 3.5 (MJWarp) speedups over MJX of 252x for locomotion and 475x for manipulation on RTX PRO 6000 Blackwell GPUs, without stating task variants, environment counts, precision or timing definitionSource 7. MJWarp optimizes throughput, where MuJoCo optimizes single-step latencySource 26.
Limits
GPUSimBench finds GPU batching in Isaac Lab and Genesis adds significant run-to-run and inter-environment variability under identical initial conditionsSource 27. For domain randomization, Isaac Lab keeps simulation state on the GPU, but mass, friction, contact offsets and joint armature go through PhysX CPU APIs; mesh scale and collider type change only before simulation starts, most other parameters at runtimeSource 6.
Newton's README lists differentiabilitySource 20, and support differs between solversSource 8, but its primary backend says "Differentiability via Warp is not yet available"Source 28. SHAC cut training time over 17x against the best established RL algorithm on muscle-actuated locomotionSource 29, and Schwarke and colleagues report the first legged sim-to-real transfer learned entirely in differentiable simulationSource 30.
Isaac Sim 6.1 adds beta system identification tools for robot simulation parametersSource 22, and the overview's authors call Drake the "gold standard" when contact-implicit trajectory optimisation and rigorous numerics matter more than throughputSource 8.
See also
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Humanoid Whole-Body Control
How humanoids track retargeted human motion.
Linked from
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Sim-to-Real Transfer
Domain randomization, distillation, system identification and real-to-sim reconstruction.
- Legged Locomotion Lineage
How learned gaits became the default for legged robots.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
- Drones and Aerial Robotics
Autonomous flight, from state estimation to champion-level racing.
References
Nikita Rudin, David Hoeller, Philipp Reist, Marco Hutter, CoRL 2021.
https://arxiv.org/abs/2109.11978
Nikita Rudin, 2021.
https://github.com/leggedrobotics/legged_gym
Viktor Makoviychuk, Lukasz Wawrzyniak, Yunrong Guo, Michelle Lu, Kier Storey, Miles Macklin, and 5 more, 2021.
https://arxiv.org/abs/2108.10470
C. Daniel Freeman, Erik Frey, Anton Raichuk, Sertan Girgin, Igor Mordatch, Olivier Bachem, 2021.
https://arxiv.org/abs/2106.13281
Kevin Zakka, Baruch Tabanpour, Qiayuan Liao, Mustafa Haiderbhai, Samuel Holt, Jing Yuan Luo, and 7 more, 2025.
https://arxiv.org/abs/2502.08844
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
Philipp Reist, Miguel Zamora Mora, JC Chang, Rishabh Chadha, Mohammad Mohajerani, 2026.
https://developer.nvidia.com/blog/newton-adds-contact-rich-manipulation-and-locomotion-capabilities-for-industrial-robotics
Johnny Nuñez Cano, Mitesh Patel, Asier Arranz, lior ben horin, Raymond Lo, Rishabh Chadha, 2026.
https://huggingface.co/blog/nvidia/state-of-simulation-for-physical-ai
John Schulman, Filip Wolski, Prafulla Dhariwal, Alec Radford, Oleg Klimov, 2017.
https://arxiv.org/abs/1707.06347
Emanuel Todorov, Tom Erez, Yuval Tassa, IROS 2012.
https://doi.org/10.1109/IROS.2012.6386109
Google DeepMind, MuJoCo Documentation, as of 2026-10-04.
https://mujoco.readthedocs.io/en/stable/overview.html
Google DeepMind, MuJoCo Documentation, as of 2026-10-04.
https://mujoco.readthedocs.io/en/stable/mjx.html
Jayesh Singla, Ananye Agarwal, Deepak Pathak, ICML 2024.
https://arxiv.org/abs/2407.20230
Michael Beukman, Khimya Khetarpal, Zeyu Zheng, Will Dabney, Jakob Foerster, Michael Dennis, and 1 more, RLC 2026.
https://arxiv.org/abs/2603.06009
Mayank Mittal, Calvin Yu, Qinxi Yu, Jingzhou Liu, Nikita Rudin, David Hoeller, and 9 more, IEEE Robotics and Automation Letters 8(6), 2023.
https://arxiv.org/abs/2301.04195
Tyler Ga Wei Lum, Martin Matak, Viktor Makoviychuk, Ankur Handa, Arthur Allshire, Tucker Hermans, and 2 more, arXiv preprint, 2024.
https://arxiv.org/abs/2407.02274
NVIDIA, GitHub release v3.0.0-EA, isaac-sim/IsaacLab, 2026.
https://github.com/isaac-sim/IsaacLab/releases/tag/v3.0.0-EA
The Linux Foundation, Linux Foundation press release, 2025.
https://www.linuxfoundation.org/press/linux-foundation-announces-contribution-of-newton-by-disney-research-google-deepmind-and-nvidia-to-accelerate-open-robot-learning
NVIDIA, GitHub repository NVIDIA/warp, README as of 2026-10-04.
https://github.com/NVIDIA/warp
Newton project (Linux Foundation), GitHub repository newton-physics/newton, README as of 2026-10-04.
https://github.com/newton-physics/newton
NVIDIA, GitHub release v6.1.0, isaac-sim/IsaacSim, 2026.
https://github.com/isaac-sim/IsaacSim/releases/tag/v6.1.0
NVIDIA, Isaac Sim documentation, 2026.
https://docs.isaacsim.omniverse.nvidia.com/6.1.0/overview/release_notes.html
Newton project (Linux Foundation), GitHub release v1.6.0, newton-physics/newton, 2026.
https://github.com/newton-physics/newton/releases/tag/v1.6.0
Anka He Chen, Ziheng Liu, Yin Yang, Cem Yuksel, arXiv preprint, 2024.
https://arxiv.org/abs/2403.06321
Ryan Elandt, Evan Drumwright, Michael Sherman, Andy Ruina, IROS 2019.
https://arxiv.org/abs/1904.11433
Google DeepMind, NVIDIA, MuJoCo Documentation, as of 2026-10-04.
https://mujoco.readthedocs.io/en/latest/mjwarp/
Huzhenyu Zhang, Shenghai Yuan, Wenrui Yan, Li Ma, Hengjie Li, Jingcheng Pang, and 1 more, IROS 2026.
https://arxiv.org/abs/2607.13059
Google DeepMind, NVIDIA, GitHub repository google-deepmind/mujoco_warp, README as of 2026-10-04.
https://github.com/google-deepmind/mujoco_warp
Jie Xu, Viktor Makoviychuk, Yashraj Narang, Fabio Ramos, Wojciech Matusik, Animesh Garg, and 1 more, ICLR 2022.
https://arxiv.org/abs/2204.07137
Clemens Schwarke, Victor Klemm, Joshua Bagajo, Jean-Pierre Sleiman, Ignat Georgiev, Jesus Tordesillas, and 1 more, arXiv preprint (CoRL 2025), 2024.
https://arxiv.org/abs/2404.02887
Further reading
Kevin Zakka, Qiayuan Liao, Brent Yi, Louis Le Lay, Koushil Sreenath, Pieter Abbeel, arXiv preprint, 2026.
https://arxiv.org/abs/2601.22074
Zechu Li, Tao Chen, Zhang-Wei Hong, Anurag Ajay, Pulkit Agrawal, ICML 2023.
https://arxiv.org/abs/2307.12983
Younggyo Seo, Carmelo Sferrazza, Haoran Geng, Michal Nauman, Zhao-Heng Yin, Pieter Abbeel, arXiv preprint, 2025.
https://arxiv.org/abs/2505.22642
Spot a factual error or missing qualification? Report a content correction.