RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
Reinforcement learning (RL) for robotics trains robot policies from their own experience of acting, formalized as a Markov decision process of states, actions, transitions and rewardsSource 1. A simulated step is nearly free when thousands of GPU robots act at onceSource 2, while a real step costs machine time and a reset.
What a budget buys, and what it forbids
Sample efficiency
A simulator does in minutes what takes a robot months
Adjust more
Exact budget 158M steps; model wall clock 21.5 min at 123k steps/s, 1.0x slower than sim, toy on-policy band
modelled at a constant rate, not measuredpaper-reported durations and bounds
Illustrative calculation, not measured training times
How this was made
In this toy, 158M steps through massively parallel simulation at 123k steps/s takes 21.5 min. Illustration: PPO example; not an eligibility rule.
What is modelled rather than measured: the three lanes use constant illustrative rates. The simulation constant is 122,880 steps/s, computed at Rudin's 1,200-second boundary; the reported run implies a strictly greater end-to-end average, not an exact measured rate of 122,880. The single-robot constant is approximately 22.2 steps/s from Minitaur's whole training process, not its rollout control rate. Neither constant predicts arbitrary tasks or robots. Fleet scaling assumes perfect parallelism. QT-Opt's evaluation protocol allows up to 20 steps per grasp attempt; that cap is not a measured mean and does not establish a campaign step rate from grasp totals and robot-hours. No QT-Opt steps-per-robot-second value is presented here as measured. Robot-hours are not parallel wall time. The one-hour and 720-hour boundaries are editorial thresholds for this toy, not scientific algorithm-eligibility limits. The bands do not rule algorithms in or out.
The bands: a run under 1 hour sits in the toy on-policy band (PPO is an example), up to 720 hours in the toy off-policy band (SAC, TD3 and RLPD are examples), and longer in the toy offline band (CQL, IQL and TD3+BC are examples). The time axis is logarithmic: each tick is a much longer time than the last.
The real examples from papers, in time order:
- 1ANYmal flat terrain, under 4 min
- 2ANYmal uneven terrain, 20 min
- 3A1 walking, one reported run, 1 h
- 4Minitaur walking on hardware, about 2 h
- 5QT-Opt grasping, about 800 robot hours
- 6About 800k attempts, 6 to 14 robots, two months
Paper-reported durations, with different settings and units: Rudin reports ANYmal flat-terrain training in under four minutes and uneven terrain in twenty minutes on one workstation GPU. The separately described simulation/deployment policy used 4,096 environments, 98,304 samples per update and 1,500 updates in under twenty minutes on an i9-11900k CPU and RTX A6000 GPU Source 2; DayDreamer reports one A1 run learning to roll over, stand and walk in one hour without a simulator, with physical interventions at the training-area boundary that preserved joint configuration and orientation Source 6; Minitaur walking required 160,000 control steps over about two hours of whole-process training time Source 3; QT-Opt reports a 580,000-grasp off-policy dataset from seven robots over about 800 robot hours, separate from approximately 28,000 additional on-policy fine-tuning grasps Source 4; and section 5.2 of Levine's 2016 preprint reports about 800,000 grasp attempts over two months using 6-14 robots. Its abstract says “over 800,000” and its introduction says “several months”Source 5. Robot-hours are not parallel wall time. Bounds and approximate durations are plotted at their stated numeric anchors; two months is drawn as 60 days for placement, not as a measured elapsed-time conversion. These are not matched benchmarks. Keep the modelled budget fixed while switching sources or changing fleet size to inspect the toy assumptions.
In the constant-rate toy, 158M environment steps take 21.5 min of model wall clock in massively parallel simulation, 82.5 d on one robot and 11.8 d on a fleet of 7. The single-robot-to-simulation duration ratio is 5,530. Their toy bands are on-policy, offline and off-policy; these are editorial categories, not algorithm eligibility.
Modelled wall-clock cost of this budget under each source
| data source | model steps/s | model wall clock | toy band |
|---|---|---|---|
| massively parallel simulation | 123k steps/s | 21.5 min | toy on-policy band |
| a single real robot | 22 steps/s | 82.5 d | toy offline band |
| a fleet of 7 real robots | 156 steps/s | 11.8 d | toy off-policy band |
Lanes use constant illustrative rates; real examples keep each paper's own units and bounds.
A review of robotic deep RL case studies lists real-world challenges that research on games and simulated control seldom addressesSource 23, and a 2025 survey of real-world successes calls stable, sample-efficient real-world RL a prioritySource 24.
Two ways to spend a transition
An on-policy method can only update on data the current policy generated, so each batch is collected, consumed and discarded; PPO allows several minibatch epochs per batch, where plain policy gradient takes one stepSource 7. An off-policy method improves one policy from data another produced, so experience accumulates in a replay buffer. Underneath is Q-learning: fit the value of a state-action pair and bootstrap from the best next action, even one never takenSource 1.
On-policy and off-policy
Off-policy learners reuse experience; on-policy ones discard it
The learner
Illustrative batches
How this was made
An on-policy update is valid only for data the current policy produced, so each batch is collected, consumed and discarded; PPO makes several passes over each batch where plain policy gradient makes one. An off-policy method improves one policy from data another produced, so experience piles up in a replay buffer. Underneath is Q-learning, which fits the value of a state and action and can learn from any recorded step.
The batches are illustrative. With thousands of simulated robots, steps are nearly free and PPO's stability wins; on a real robot every step costs time, which is why reuse matters there.
After 6 rounds of collecting, an on-policy learner like PPO updates from only the newest batch, 1 of 6, and has discarded the other 5 after a few passes each; an off-policy learner would still hold all 6.
What the update may learn from after 6 rounds
| learner | batches usable after 6 rounds | older batches |
|---|---|---|
| On-policy, like PPO | 1 | thrown away |
| Off-policy, like SAC | 6 | kept in the replay buffer |
TD3 reduced DDPG's overestimation bias with clipped double critics, delayed policy updates and target policy smoothingSource 9. Soft actor-critic added a maximum-entropy objective aimed at sample complexity and brittle convergenceSource 8.
Why robotics defaulted to PPO anyway
With thousands of GPU environments, steps are nearly free and training stability is the scarce resource. SAC's authors credit on-policy training with stability at the price of "poor sample complexity", and call off-policy learning with neural function approximation "a major challenge for stability and convergence"Source 8.
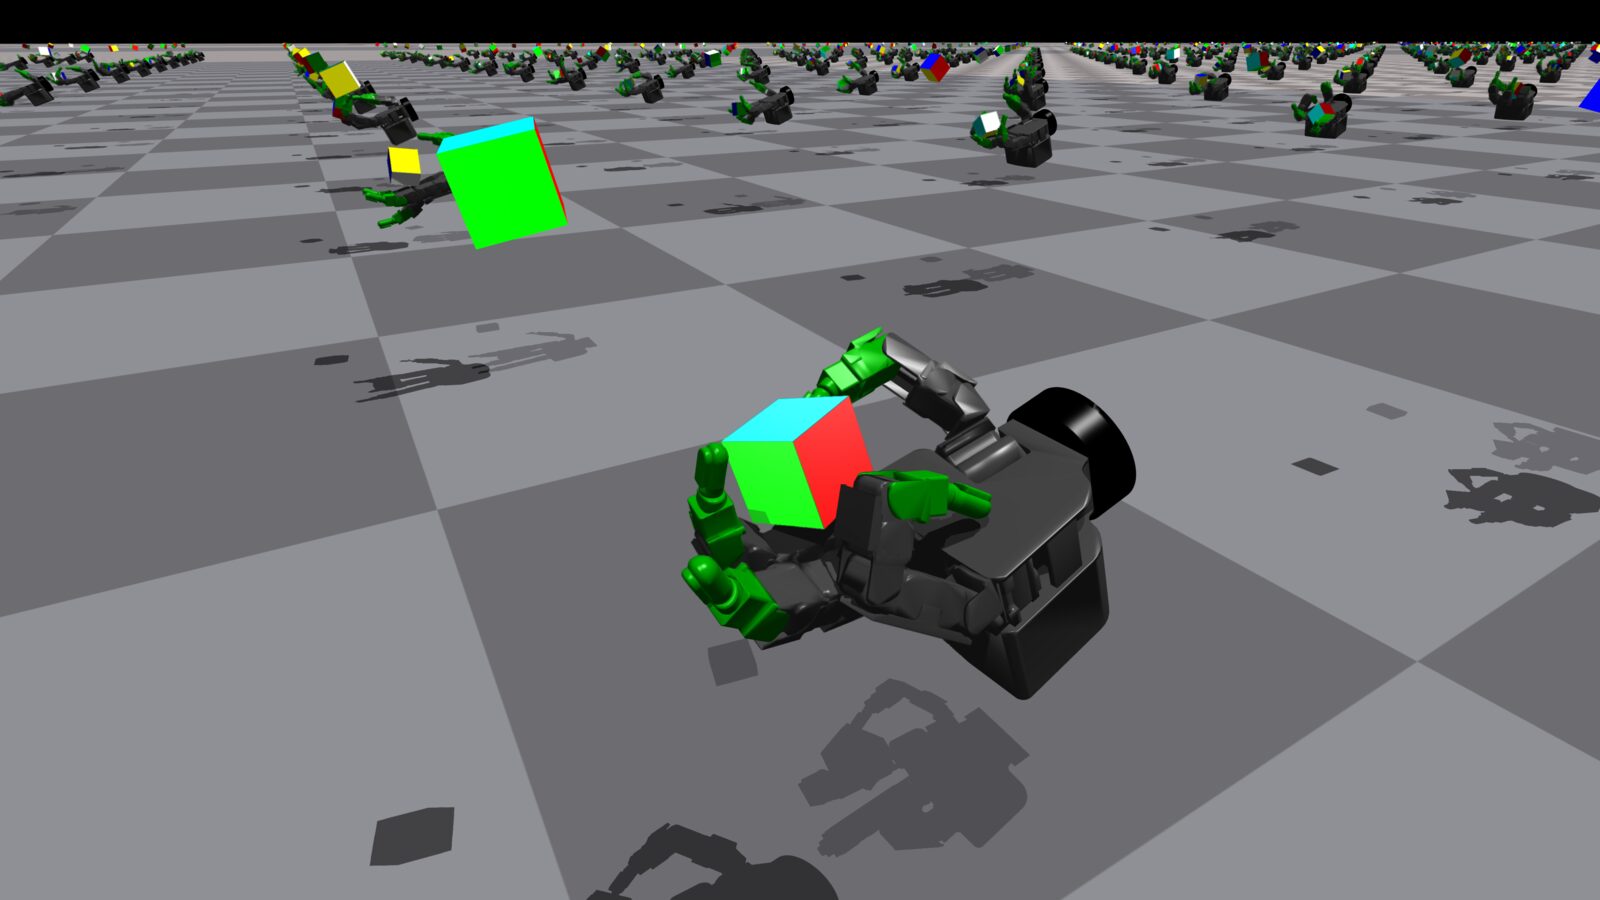
Rudin and colleagues trained ANYmal with 4,096 parallel robots, 98,304 steps per update and 1,500 updates in under twenty minutes on one workstation GPU, more than 122,880 environment steps per secondSource 2. Minitaur's 160,000 control steps over about two hours average about 22 per second, below its 50 Hz rollout rate because resets and overhead countSource 3. Parallel simulation covers the first regime.
Most GPU-simulation work used PPO for its simplicity and ease of scaling, while off-policy methods were more data-efficient but slower in wall-clock time; Parallel Q-Learning scales to tens of thousands of environments and beats PPO in wall-clock timeSource 25, and FastSAC and FastTD3 train sim-to-real humanoid locomotion in 15 minutes on one RTX 4090Source 26.
What sample efficiency looks like in step counts
160k steps
Minitaur walking
about two hours of real-world time, SAC
1 h
A1 walking
DayDreamer: one A1 run; no simulator; physical interventions
580k grasps
QT-Opt grasping
about 800 robot hours across 7 robots
about 800k attempts
hand-eye grasping
2016 preprint §5.2: two months, 6-14 robots
Sample efficiency is how much experience a method needs to learn. Haarnoja and colleagues learned Minitaur locomotion from 160,000 control steps in about two hours of real-world time that includes resets and the operatorSource 3. DayDreamer trained a Unitree A1 to roll over, stand and walk in one hour without a simulator, and ten more minutes of online learning taught it to withstand pushes; the authors intervened manually at the edge of the training areaSource 6.
QT-Opt collected over 580,000 grasp attempts across seven robots in about 800 robot hoursSource 4. The 2016 hand-eye preprint, which trained a supervised grasp-success predictor, reports about 800,000 grasp attempts over two months with 6 to 14 robots at a timeSource 5.
Offline reinforcement learning
Offline reinforcement learning learns a policy from a fixed dataset of transitions without further environment interaction during training, then deploys itSource 10. It can reuse corpora like those in the datasets module, but a learned policy can choose actions outside the behavior distribution, Bellman targets then use erroneously high Q-values for them, and later backups propagate the errors without fresh feedbackSource 10. BCQ showed that this extrapolation error leaves standard off-policy algorithms unable to learn from fixed batchesSource 27, and CQL answers it by learning a lower bound on policy value, penalizing Q-values on out-of-distribution actionsSource 11.
Does any of this beat behavior cloning on robot data?
Mandlekar and colleagues found batch RL weak on human demonstrations: neither BCQ nor CQL did well on human datasets, while history-dependent BC-RNN was a strong baselineSource 13. Kumar, Hong, Singh and Levine give sufficient conditions under which offline RL beats BC, assuming coverage of the optimal policy; with noisy data that improves coverage, conservative offline RL has a better bound than BC on equal expert data, while on expert data similar performance is a worst-case result. Their drawer-manipulation comparison, in simulation, pits BC on expert successes against CQL on noisy scripted data. Naive CQL can perform no better than BCSource 12.
For teleoperation data, a supervised behavior-cloning baseline is the simpler starting point, though newer real-robot results favor RL. Generalist policies fine-tuned on RL-generated data beat the same policies trained on human demonstrations by up to 40% in successSource 28, and Physical Intelligence's RECAP pretrains a VLA with offline RL and more than doubles task throughput on some of the hardest tasksSource 29.
Sparse reward, and learning from failure
A robot that has never completed a task has no successful trajectory, so a completion-only reward gives its value function nothing to fit. Shaping is one answer (reward design). Hindsight experience replay targets sparse binary rewards directly, storing transitions under their original goal and alternative goals and recomputing the reward for each, for example with goals achieved later in the same episodeSource 14.
Hindsight experience replay
Relabelled with where it ended, a miss still teaches
Judge the push against
Missed the goal: reward 0, nothing to learnJudged against the given goal · reward 0
Illustrative push; rule cited
How this was made
With a sparse reward, 1 for reaching the goal and 0 otherwise, a robot that has never reached the goal has nothing to learn from. Hindsight experience replay stores each step under its original goal and under goals the robot did reach, recomputing the reward for each. Its simplest version uses the spot reached at the end of the episode, as here; its future version samples spots reached later in the same episode.
Andrychowicz and colleagues trained a simulated seven-joint Fetch arm on pushing, sliding and pick-and-place; with the future version it learned all three, where the same learner without relabelling did not. Relabelling needs a reward that can be recomputed for any goal. The push drawn here is illustrative.
The drawing is a push test table. A robot arm at one end has pushed the puck across the felt, leaving a chalk trail from the start mark to where it stopped. The goal the robot was given is printed on the felt and marked by a pin. The goal the push is judged against is the lit hoop a gantry holds just above the felt; the flag on the gantry's carriage stands up when the puck lies inside the hoop, a reward of 1. Relabelling carries the hoop from the pin to the puck; the pin and its printed circle stay where the given goal was.
Judged against the goal it was given, the recorded push misses and earns a reward of 0; relabelled with the spot where the puck ended, the same push earns 1, so 1 missed push also yields 1 success to learn from.
The same push, judged against two goals
| judged against | reward (0 or 1) | what the robot learns |
|---|---|---|
| The given goal | 0 | nothing |
| Where the puck ended | 1 | how to push the puck to this spot |
Andrychowicz and colleagues trained DDPG with HER on a simulated seven-DoF Fetch arm for pushing, sliding and pick-and-place, where DDPG alone failed. Pushing added a contact-penetration penalty, and pick-and-place started half its training episodes with the box already grasped. A simulation-trained pick-and-place policy transferred to a physical Fetch without real-robot fine-tuning, and HER needs an achieved-goal mapping and a reward recomputable for any replacement goalSource 14.
The reset problem
A simulated episode restarts from a fresh state automatically, at only computational costSource 15; a physical one ends wherever the robot is, and a person or a learned behavior has to put it backSource 30.
Zhu and colleagues name learning from raw sensory inputs, assigning rewards without hand-designed instrumentation, and learning without human episode resets as the requirements for real-world RL; their D'Claw hand trained unattended, but evaluation included manual resets for bead manipulationSource 17. Leave No Trace learns a reset policy alongside the forward policy and aborts before non-reversible statesSource 30. Sharma and colleagues' EARL benchmark sums gaps to optimal deployment return over training and treats interventions as constrained costs, though its experiments still schedule resets during trainingSource 15.
Reset-free learning replaces manual resets with learned recovery behaviors. Gupta and colleagues' MTRF sequences task-specific policies with a designer-provided task graph, and a D'Hand on a Sawyer arm learned valve reorientation and pipe insertion without manual episode resets. The setup still used supplied rewards, motion capture for the in-hand object, scripted arm motion for pickup and a user who positioned the objects, pipe insertion used frozen fingers, and the method assumes that successful upstream tasks leave valid starting states for downstream onesSource 16. Without such a task graph a person handles the reset, a cost the human-in-the-loop line pays deliberatelySource 18.
Where this goes from here
Parallel simulation explains the sampler behind on-policy training, why RL won locomotion which problems simulation represents faithfully, and sim-to-real transfer deployment. RL fine-tuning covers RL on pretrained vision-language-action policies: pi_RL applies online PPO to flow-based pi0 and pi0.5 policies, replacing flow-matching regression with a policy-gradient updateSource 19, and PLD fine-tunes a generalist on hybrid recovery data from residual specialistsSource 20.
HIL-SERL reports 100% success in 100 evaluation trials per task, except IKEA whole assembly at 10 of 10. Nearly all tasks took one to two and a half hours of real-world training and timing-belt assembly six, counting scripted motion, rollouts and intended stopsSource 18. DROIDSource 21 and Open X-EmbodimentSource 22 supply large real-robot demonstration corpora, but both papers evaluate imitation policies, so offline RL on them needs reward labels the datasets do not define.
See also
- World Models vs Physics Simulators
Learned dynamics, physics engines and hybrids compared as robot simulators.
- The Reliability Gap
80% task success is a demo; 99.9% is a product.
- The Evaluation Crisis
What a success rate hides, from trial count to scorer.
Linked from
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
- Why RL Won Locomotion but Not Manipulation
Walking is cheap to simulate; contact-rich manipulation is not.
- Latent-Dynamics World Models
Dreamer 4, TD-MPC2 and Newt: compact learned dynamics for imagination-based control.
References
Richard S. Sutton, Andrew G. Barto, MIT Press, second edition, 2018.
https://web.archive.org/web/20260818231355/http://www.incompleteideas.net/book/the-book-2nd.html
Nikita Rudin, David Hoeller, Philipp Reist, Marco Hutter, CoRL 2021.
https://arxiv.org/abs/2109.11978
Tuomas Haarnoja, Sehoon Ha, Aurick Zhou, Jie Tan, George Tucker, Sergey Levine, RSS 2019.
https://arxiv.org/abs/1812.11103
Dmitry Kalashnikov, Alex Irpan, Peter Pastor, Julian Ibarz, CoRL 2018.
https://arxiv.org/abs/1806.10293
Sergey Levine, Peter Pastor, Alex Krizhevsky, Deirdre Quillen, arXiv preprint (v4), 2016.
https://arxiv.org/pdf/1603.02199v4
Philipp Wu, Alejandro Escontrela, Danijar Hafner, Ken Goldberg, Pieter Abbeel, CoRL 2022.
https://arxiv.org/abs/2206.14176
John Schulman, Filip Wolski, Prafulla Dhariwal, Alec Radford, Oleg Klimov, 2017.
https://arxiv.org/abs/1707.06347
Tuomas Haarnoja, Aurick Zhou, Pieter Abbeel, Sergey Levine, ICML 2018.
https://arxiv.org/abs/1801.01290
Scott Fujimoto, Herke van Hoof, David Meger, ICML 2018.
https://arxiv.org/abs/1802.09477
Sergey Levine, Aviral Kumar, George Tucker, Justin Fu, 2020.
https://arxiv.org/abs/2005.01643
Aviral Kumar, Aurick Zhou, George Tucker, Sergey Levine, NeurIPS 2020.
https://arxiv.org/abs/2006.04779
Aviral Kumar, Joey Hong, Anikait Singh, Sergey Levine, ICLR 2022.
https://arxiv.org/abs/2204.05618
Ajay Mandlekar, Danfei Xu, Josiah Wong, Soroush Nasiriany, CoRL 2021.
https://arxiv.org/abs/2108.03298
Marcin Andrychowicz, Filip Wolski, Alex Ray, Jonas Schneider, Rachel Fong, Peter Welinder, and 4 more, NeurIPS 2017.
https://arxiv.org/abs/1707.01495
Archit Sharma, Kelvin Xu, Nikhil Sardana, Abhishek Gupta, Karol Hausman, Sergey Levine, and 1 more, ICLR 2022.
https://arxiv.org/abs/2112.09605
Abhishek Gupta, Justin Yu, Tony Z. Zhao, Vikash Kumar, Aaron Rovinsky, Kelvin Xu, and 2 more, ICRA 2021.
https://arxiv.org/abs/2104.11203
Henry Zhu, Justin Yu, Abhishek Gupta, Dhruv Shah, Kristian Hartikainen, Avi Singh, and 2 more, ICLR 2020.
https://arxiv.org/abs/2004.12570
Jianlan Luo, Charles Xu, Jeffrey Wu, Sergey Levine, 2024.
https://arxiv.org/abs/2410.21845
Kang Chen, Zhihao Liu, Tonghe Zhang, Zhen Guo, Si Xu, Hao Lin, and 10 more, 2026.
https://arxiv.org/abs/2510.25889
Wenli Xiao, Haotian Lin, Andy Peng, Haoru Xue, Tairan He, Yuqi Xie, and 6 more, 2025.
https://arxiv.org/abs/2511.00091
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Julian Ibarz, Jie Tan, Chelsea Finn, Mrinal Kalakrishnan, Peter Pastor, Sergey Levine, International Journal of Robotics Research, 2021.
https://arxiv.org/abs/2102.02915
Chen Tang, Ben Abbatematteo, Jiaheng Hu, Rohan Chandra, Roberto Martín-Martín, Peter Stone, Annual Review of Control, Robotics, and Autonomous Systems, 2025.
https://doi.org/10.1146/annurev-control-030323-022510
Zechu Li, Tao Chen, Zhang-Wei Hong, Anurag Ajay, Pulkit Agrawal, ICML 2023.
https://arxiv.org/abs/2307.12983
Younggyo Seo, Carmelo Sferrazza, Juyue Chen, Guanya Shi, Rocky Duan, Pieter Abbeel, 2025.
https://arxiv.org/abs/2512.01996
Scott Fujimoto, David Meger, Doina Precup, arXiv preprint (ICML 2019), 2018.
https://arxiv.org/abs/1812.02900
Charles Xu, Qiyang Li, Jianlan Luo, Sergey Levine, 2024.
https://arxiv.org/abs/2412.09858
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/download/pistar06.pdf
Benjamin Eysenbach, Shixiang Gu, Julian Ibarz, Sergey Levine, 2017.
https://arxiv.org/abs/1711.06782
Further reading
Timothy P. Lillicrap, Jonathan J. Hunt, Alexander Pritzel, Nicolas Heess, Tom Erez, Yuval Tassa, and 2 more, ICLR 2016.
https://arxiv.org/abs/1509.02971
Ilya Kostrikov, Ashvin Nair, Sergey Levine, ICLR 2022.
https://arxiv.org/abs/2110.06169
Scott Fujimoto, Shixiang Shane Gu, NeurIPS 2021.
https://arxiv.org/abs/2106.06860
Yevgen Chebotar, Quan Vuong, Alex Irpan, Karol Hausman, Fei Xia, Yao Lu, and 19 more, CoRL 2023.
https://arxiv.org/abs/2309.10150
Philip J. Ball, Laura Smith, Ilya Kostrikov, Sergey Levine, ICML 2023.
https://arxiv.org/abs/2302.02948
Younggyo Seo, Carmelo Sferrazza, Haoran Geng, Michal Nauman, Zhao-Heng Yin, Pieter Abbeel, arXiv preprint, 2025.
https://arxiv.org/abs/2505.22642
Laura Smith, Ilya Kostrikov, Sergey Levine, 2022.
https://arxiv.org/abs/2208.07860
Aviral Kumar, Anikait Singh, Frederik Ebert, Mitsuhiko Nakamoto, Yanlai Yang, Chelsea Finn, and 1 more, 2022.
https://arxiv.org/abs/2210.05178
Kun Lei, Huanyu Li, Dongjie Yu, Zhenyu Wei, Lingxiao Guo, Zhennan Jiang, and 3 more, 2025.
https://arxiv.org/abs/2510.14830
Mitsuhiko Nakamoto, Yuexiang Zhai, Anikait Singh, Max Sobol Mark, Yi Ma, Chelsea Finn, and 2 more, arXiv preprint (NeurIPS 2023).
https://arxiv.org/abs/2303.05479
Archit Sharma, Abhishek Gupta, Sergey Levine, Karol Hausman, Chelsea Finn, 2021.
https://arxiv.org/abs/2107.12931
Jianlan Luo, Zheyuan Hu, Charles Xu, You Liang Tan, Jacob Berg, Archit Sharma, and 4 more, ICRA 2024.
https://arxiv.org/abs/2401.16013
Yuhui Chen, Shuai Tian, Shugao Liu, Yingting Zhou, Haoran Li, Dongbin Zhao, 2025.
https://arxiv.org/abs/2502.05450
Shaoyin Luo, Song Wang, Shibo Xia, Tianle Zhang, Zhaowei Liang, Guanghui Shen, and 2 more, 2026.
https://arxiv.org/abs/2609.37131
Claudio Canales, Fang Nan, Marco Hutter, Javier Ruiz-del-Solar, 2026.
https://arxiv.org/abs/2609.31025
Yi Wang, Xinchen Li, Pengwei Xie, Pu Yang, Buqing Nie, Yunuo Cai, and 10 more, 2026.
https://arxiv.org/abs/2605.00416
Lakshita Dodeja, Ondrej Biza, Shivam Vats, Stephen Hart, Stefanie Tellex, Robin Walters, and 2 more, RSS 2026.
https://arxiv.org/abs/2605.05172
Spot a factual error or missing qualification? Report a content correction.