Major Datasets
The major open robot datasets and what each collected.
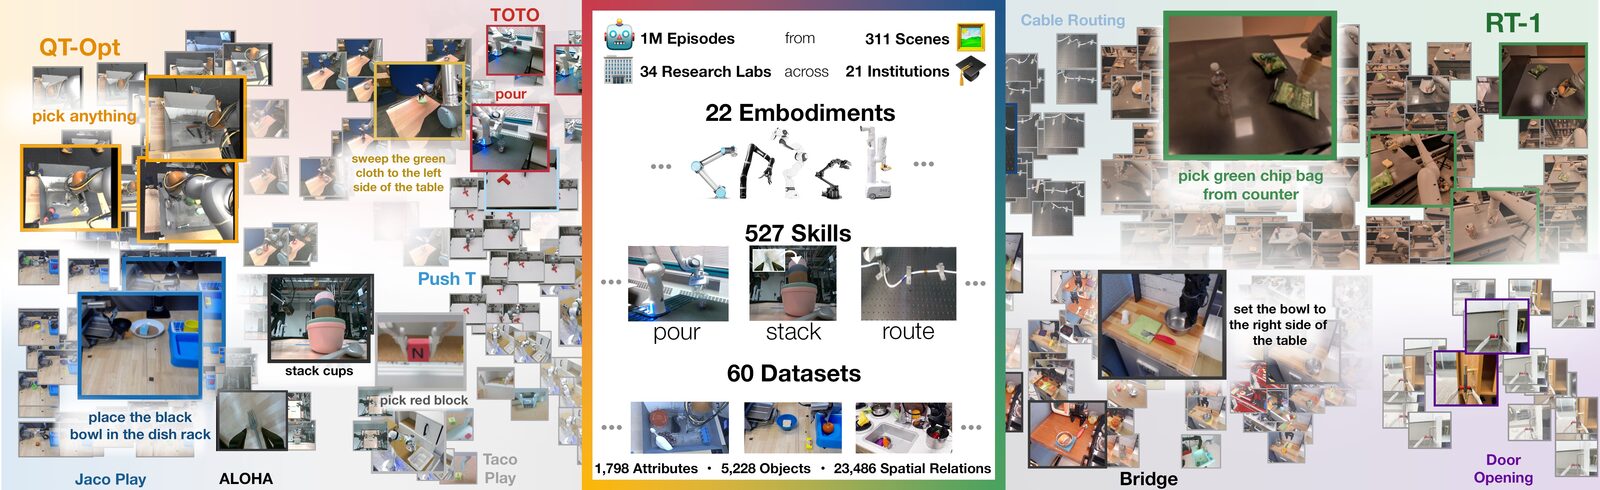
Major robot learning datasets are the open collections of recorded robot trajectories that generalist policies train on. Open X-Embodiment pools over a million trajectories from 22 embodimentsSource 1, AgiBot World holds 1,001,552 (2,976 hours) on one robot platformSource 5, and DROID holds 76,000 (350 hours) across 564 scenesSource 2.
1M+
largest pool
trajectories, Open X-Embodiment
350
one platform
hours, DROID's 12-month effort
24
environments
BridgeData V2 kitchens and tabletops
4
embodiments
RoboMIND, one collection protocol
The comparison table
Filter by size
Filter by embodiment
Filter by task count
6 of 6 datasets
| License | Source | |||||||
|---|---|---|---|---|---|---|---|---|
| AgiBot World | 2025 | 1,001,552Beta release; 1,003,672 after post-release additions | 2,976.4 | 2175 deployment scenarios | not disclosed | 1 platformAgiBot G1 | CC BY-NC-SA 4.0 | agibot-world.com |
| Open X-Embodiment (OXE) | 2023 | 1,000,000reported as 1M+; pooled from 60 datasets | not disclosed | 160,266527 skills | not disclosed | 22 platforms22 platforms pooled across 34 labs | mixed (per constituent dataset) | robotics-transformer-x.github.io |
| RoboMIND | 2024 | 107,000107k successful, real + simulated (paper v3); card versions 1.1/1.2; 5k additional real-world failures | 305.5Paper v3: real + simulated; real-only and failure-set durations not separately reported | 47996 object classes | not disclosed | 4 platformsFranka Emika Panda, UR5e, AgileX dual-arm, humanoid, dual dexterous hands | not disclosed | x-humanoid-robomind.github.io |
| DROID | 2024 | 76,000 | 350 | 86 | 564 | 1 platformFranka Panda | CC BY 4.0 | droid-dataset.github.io |
| BridgeData V2 | 2023 | 60,096incl. 9,731 scripted pick-and-place rollouts | not disclosed | 13skills | 24 | 1 platformWidowX 250 | CC BY 4.0 | rail-berkeley.github.io |
| AgiBot World 2026 | 2026 | not disclosed | not disclosed | not disclosed | not disclosed | 1 platformAgiBot G2 | CC BY-NC-SA 4.0 | huggingface.co |
Set the size filter to 1M+ episodes and one row remains; sort by Hours to compare published durations. Episodes and hours measure different things, because a trajectory can last eight seconds or eight minutes. RoboMIND reports 305.5 hours for its 107k-trajectory cohort, which mixes real and simulated dataSource 7. NVIDIA's open Physical AI dataset reports both, 15 terabytes and more than 320,000 trajectoriesSource 10.
Five robot datasets
Run counts and hours rank these datasets differently
How this was made
Each point is one dataset's own totals: the runs it recorded (the papers say trajectories or episodes) and the hours they add up to. Both rulers step by ten times. The run lengths are hours times 3,600 divided by runs; the dashed line is where an average run lasts one minute.
- FineART: 40,543 runs, 1,718 hours, about 2.5 minutes a run.
- DROID: 76k runs as printed, 350 hours, about 17 seconds a run.
- Galaxea: 100K runs as printed, 500 hours, about 18 seconds a run.
- RoboMIND: 107k runs as printed, 305.5 hours, about 10 seconds a run.
- AgiBot World: 1,001,552 runs, 2,976.4 hours, about 11 seconds a run.
RoboMIND's total mixes real and simulated runs, and AgiBot World is its Beta release. BridgeData V2 is left off: it reports 60,096 trajectories but no total hours, and its 5 Hz recording rate is stated for the teleoperated runs only, so any hours figure would be a guess.
Five robot datasets by runs and hours: FineART 40,543 runs and 1,718 hours, DROID 76,000 runs and 350 hours, Galaxea 100,000 runs and 500 hours, RoboMIND 107,000 runs and 305.5 hours, AgiBot World 1,001,552 runs and 2,976.4 hours. AgiBot World has about 25 times FineART's runs but 1.7 times its hours, because FineART's runs average 2.5 minutes and the other four average 10 to 18 seconds.
Runs, hours and average run length per dataset
| dataset | runs | hours | seconds per run |
|---|---|---|---|
| FineART | 40,543 | 1,718 | 153 |
| DROID | 76,000 | 350 | 17 |
| Galaxea | 100,000 | 500 | 18 |
| RoboMIND | 107,000 | 305.5 | 10 |
| AgiBot World | 1,001,552 | 2,976.4 | 11 |
Open X-Embodiment: breadth by federation
OXE pooled 60 existing datasets from 34 labs into one standardized RLDS format: over a million trajectories spanning 22 robot embodiments, 527 skills and 160,266 tasksSource 1. RLDS is a standard, lossless episode format for sharing and reusing datasetsSource 11.
RT-1-X trained on the pool beat each small-scale domain's original method by 50% on average, but underperformed RT-1 trained on a large-scale domain's own data, which the authors attribute to underfitting. The higher-capacity RT-2-X roughly tripled performance on out-of-distribution skills over the same model trained without the poolSource 1. Generalist policies train on it (VLA models): Octo used 800k OXE trajectoriesSource 12, and OpenVLA used 970k real-world demonstrationsSource 13.
Later cross-embodiment pools are larger or broader. ARIO reports about 3 million episodes across 321,064 tasksSource 14, and CrossFormer trained one policy on 900K trajectories from 20 embodiments, including wheeled robots, quadcopters and quadrupedsSource 15.
Federation costs consistency: constituents differ in action spaces, control rates, cameras and licenses. Moritz Reuss's review of VLA papers at ICLR 2026 calls OXE mostly low-quality data and notes that imitation learning still lacks good ways to quantify data qualitySource 8. Re-Mix's learned domain weights beat uniform weighting by 38% on average on the data used to train the RT-X modelsSource 16.
DROID: depth on one platform
DROID's distinction is scene and site diversity: 76,000 trajectories totaling 350 hours, across 564 scenes and 86 tasks, gathered by 50 operators at 13 institutions over 12 monthsSource 2. Every trajectory came from one rig, a Franka Panda with two ZED 2 cameras and a ZED Mini wrist camera, teleoperated through a Meta Quest 2. One platform gives one action space and one camera geometry, at the price of embodiment lock-in.
Single-platform collections can be larger. RT-1's fleet of 13 robots gathered about 130k episodes over 17 monthsSource 17, and Language-Table released nearly 600,000 language-labelled trajectoriesSource 18. The Galaxea Open-World Dataset holds 500 hours across 50 scenes, all from one consistent robot embodimentSource 19.
Diffusion policies trained on DROID beat policies trained on the next-best dataset by 22% in-distribution and 17% out-of-distributionSource 2. The project added language annotations for 75,000 episodes in December 2024 and improved camera calibrations for 36,000 in April 2025Source 20. The paper releases DROID under CC BY 4.0Source 2, whose deed allows commercial sharing and adaptation subject to attribution, a license link, change notices and the other license terms, and warns that other rights may limit a particular useSource 3.
BridgeData V2: the academic workhorse
BridgeData V2 holds 60,096 trajectories on a WidowX 250, a low-cost 6-DoF arm: 50,365 teleoperated demonstrations collected with a VR controller at 5 Hz and 9,731 scripted pick-and-place rollouts, across 24 environments and 13 skillsSource 4. Trajectories average 38 timestepsSource 21. Its 2021 predecessor had 7,200 demonstrations of 71 tasks in 10 environments, and joint training with 50 demonstrations of a new task in a new domain doubled success on averageSource 22.
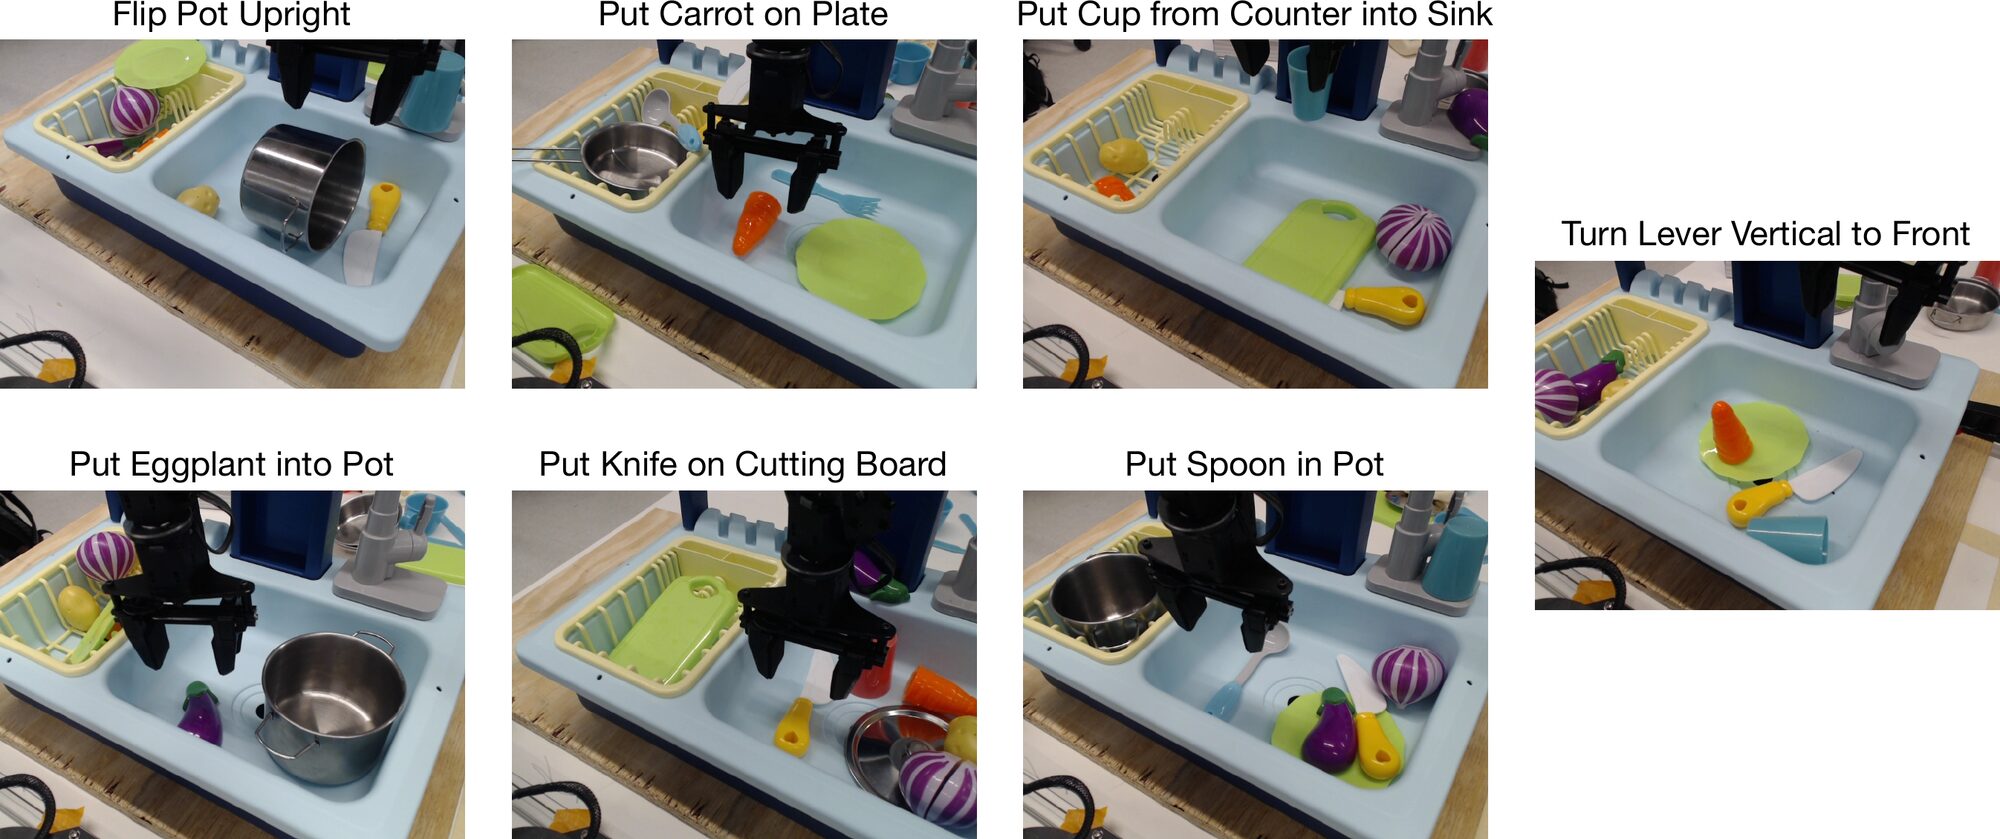
BridgeData V2's official project page states CC BY 4.0 for all dataSource 21. The paper shipped baselines from goal-conditioned behavior cloning to ACT and RT-1Source 4, and most of the data also ships inside OXESource 1.
AgiBot World: the corporate fleet
AgiBot World's Beta release holds 1,001,552 trajectories totaling 2,976 hours, all from the AgiBot G1 platform with a multi-camera rig. AgiBot reports 217 tasks in five deployment scenarios and a 30% average gain over OXE pretraining for policies pretrained on its data, a vendor figure with no independent replicationSource 5. Its repository now lists 1,003,672 trajectories and places all data and code under CC BY-NC-SA 4.0Source 23, whose NonCommercial term bars commercial useSource 24.
At about 11 seconds per trajectory, the million-trajectory headline covers less interaction than Ego4D's 3,670 hours of passive videoSource 25. AgiBot World 2026 was collected on the AgiBot G2 in real commercial and home spaces, as long-horizon restocking episodes with three annotation layers and a digital-twin simulation counterpart. Its card lists a 13.6 TB total file size but no episode or hour totalsSource 6.
RoboMIND: multi-embodiment under one protocol
RoboMIND's paper reports 107,000 successful trajectories totaling 305.5 interaction hours across 479 tasks and 96 object classes. The cohort mixes real-world and simulated demonstrations for four embodiments, a Franka Emika Panda, a UR5e, an AgileX dual-arm robot and a humanoid with dual dexterous hands, under one collection platform and standardized protocol. It also releases 5,000 real-world failure demonstrations with annotated causes and a digital twin of its tasks in Isaac SimSource 7.
RoboMIND 2.0 (December 2025) reports over 310K dual-arm trajectories from six embodiments and 739 tasks, including 12K tactile-enhanced episodes and 20K mobile manipulation trajectoriesSource 26. The public dataset card shows an Apache-2.0 tag but makes users accept access conditions before downloading, so check the terms before commercial useSource 27.
How to read dataset claims
Hours compare better than episodes. DROID averages about 17 seconds per trajectory and AgiBot World Beta about 11, so a large episode count can hide less interaction than a smaller set of long tasks (the data bottleneck). The 2025 BEHAVIOR Challenge supplies 10,000 teleoperated demonstrations totaling 1,200+ hoursSource 28, and the synthetic InternData-A1 holds over 630k trajectories and 7,433 hoursSource 29.
Modalities differ as much as size. RH20T records visual, force, audio and action data in over 110,000 contact-rich sequencesSource 30. Humanoid Everyday adds depth, LiDAR and tactile streams to 10.3k humanoid trajectories across 260 tasks, with a cloud evaluation platformSource 31. Scaling work finds task diversity worth more than per-task demonstration count, and multi-embodiment pretraining optional given high-quality single-embodiment dataSource 9.
Releases since 2025
RoboCOIN offers over 180,000 bimanual demonstrations from 15 platforms and 421 tasksSource 32. Scale AI and Hugging Face's FineART (September 2026) has 1,718 hours of bimanual teleoperation in 40,543 episodes, with 533,913 human-labelled subtasks across 151 tasksSource 38. SmolVLA trained on fewer than 30k episodes, all from community-contributed datasetsSource 33. The community-built AXIS holds 50K+ trajectories over 207 tasks, and continual pretraining on it raised π0.5's overall success rate by 5.8%Source 34.
In simulation, RoboCasa365 offers 365 tasks across 2,500 kitchens, with over 600 hours of human and over 1,600 hours of synthetic demonstrationsSource 35.
From dataset headline to training contract
A useful dataset is legal for the intended deployment, consistent in actions, units, frames and rates, complete for the claimed tasks, scenes and embodiments, and downloadable as versioned episodes traceable to a release. Datasheets for Datasets asks every dataset to document its motivation, composition, collection process and recommended usesSource 36. LeRobot's format moved to multi-episode files in 2025, after one file per episode hit file-system limits at millions of episodesSource 37.
Mixing datasets needs a canonical observation and action schema, one adapter per source and source labels kept through training, so positive transfer can be told apart from one corpus dominatingSource 1 Source 12 Source 16. The robot-learning stack supplies the versioned artifacts, and the robot-learning roadmap places dataset selection in a broader program.
See also
- Cross-Embodiment Transfer
How one policy learns from many robot bodies and from humans.
- Teleoperation Rigs
ALOHA, GELLO, UMI and VR rigs compared on cost and quality.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
Linked from
- Robot Learning Curriculum for ML Engineers
A dependency-ordered route from supervised learning to real robot policies.
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Offline Reinforcement Learning for Robotics
CQL and TD3+BC, and when behavior cloning is the stronger baseline.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
- Teleoperation Rigs
ALOHA, GELLO, UMI and VR rigs compared on cost and quality.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Robot Calibration
The measurements that make sensor coordinates agree with motion.
- Surgical Robotics
From da Vinci to Hugo and OTTAVA, authorized one indication at a time.
References
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
Homer Walke, Kevin Black, Abraham Lee, 2023.
https://arxiv.org/abs/2308.12952
AgiBot-World-Contributors, Qingwen Bu, Jisong Cai, Li Chen, Xiuqi Cui, Yan Ding, and 46 more, 2025.
https://arxiv.org/abs/2503.06669
AgiBot, 2026.
https://huggingface.co/datasets/agibot-world/AgiBotWorld2026
Kun Wu, Chengkai Hou, Jiaming Liu, RSS 2025, 2024.
https://arxiv.org/abs/2412.13877
Moritz Reuss, 2025.
https://mbreuss.github.io/blog_post_iclr_26_vla.html
Modi Shi, Li Chen, Jin Chen, Yuxiang Lu, Chiming Liu, Guanghui Ren, and 4 more, 2025.
https://arxiv.org/abs/2507.06219
Katie Washabaugh, NVIDIA Blog, 2025.
https://blogs.nvidia.com/blog/open-physical-ai-dataset/
Sabela Ramos, Sertan Girgin, Léonard Hussenot, Damien Vincent, Hanna Yakubovich, Daniel Toyama, and 6 more, 2021.
https://arxiv.org/abs/2111.02767
Octo Model Team, Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, and 14 more, 2024.
https://arxiv.org/html/2405.12213v2
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
- All Robots in One: A New Standard and Unified Dataset for Versatile, General-Purpose Embodied Agents
Zhiqiang Wang, Hao Zheng, Yunshuang Nie, Wenjun Xu, Qingwei Wang, Hua Ye, and 8 more, 2024.
https://arxiv.org/abs/2408.10899
Ria Doshi, Homer Walke, Oier Mees, Sudeep Dasari, Sergey Levine, 2024.
https://arxiv.org/abs/2408.11812
Joey Hejna, Chethan Bhateja, Yichen Jiang, Karl Pertsch, Dorsa Sadigh, 2024.
https://arxiv.org/abs/2408.14037
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Joseph Dabis, Chelsea Finn, and 45 more, 2022.
https://arxiv.org/html/2212.06817v2
Corey Lynch, Ayzaan Wahid, Jonathan Tompson, Tianli Ding, James Betker, Robert Baruch, and 2 more, 2022.
https://arxiv.org/abs/2210.06407
Tao Jiang, Tianyuan Yuan, Yicheng Liu, Chenhao Lu, Jianning Cui, Xiao Liu, and 4 more, 2025.
https://arxiv.org/abs/2509.00576
DROID Dataset Team, droid-dataset.github.io, n.d.; accessed 2026-10-13.
https://droid-dataset.github.io/
Homer Walke, Kevin Black, Frederik Ebert, Aviral Kumar, Anikait Singh, Yanlai Yang, and 18 more, rail-berkeley.github.io, n.d.; accessed 2026-10-13.
https://rail-berkeley.github.io/bridgedata/
Frederik Ebert, Yanlai Yang, Karl Schmeckpeper, Bernadette Bucher, Georgios Georgakis, Kostas Daniilidis, and 2 more, 2021.
https://arxiv.org/abs/2109.13396
OpenDriveLab, GitHub, n.d.; accessed 2026-10-04.
https://github.com/OpenDriveLab/AgiBot-World
Creative Commons, 2013.
https://creativecommons.org/licenses/by-nc-sa/4.0/
Kristen Grauman, Andrew Westbury, Eugene Byrne, CVPR 2022.
https://arxiv.org/abs/2110.07058
Chengkai Hou, Kun Wu, Jiaming Liu, Zhengping Che, Di Wu, Fei Liao, and 27 more, 2025.
https://arxiv.org/abs/2512.24653
x-humanoid-robomind, Hugging Face Datasets, n.d.; accessed 2026-10-13.
https://huggingface.co/datasets/x-humanoid-robomind/RoboMIND
Stanford Vision and Learning Lab, BEHAVIOR project site, 2025.
https://behavior.stanford.edu/challenge/archive/2025/index.html
Yang Tian, Yuyin Yang, Yiman Xie, Zetao Cai, Xu Shi, Ning Gao, and 10 more, 2025.
https://arxiv.org/abs/2511.16651
Hao-Shu Fang, Hongjie Fang, Zhenyu Tang, Jirong Liu, Chenxi Wang, Junbo Wang, and 2 more, 2023.
https://arxiv.org/abs/2307.00595
Zhenyu Zhao, Hongyi Jing, Xiawei Liu, Jiageng Mao, Abha Jha, Hanwen Yang, and 4 more, 2025.
https://arxiv.org/abs/2510.08807
Shihan Wu, Xuecheng Liu, Shaoxuan Xie, Pengwei Wang, Xinghang Li, Bowen Yang, and 78 more, 2025.
https://arxiv.org/abs/2511.17441
Mustafa Shukor, Dana Aubakirova, Francesco Capuano, Pepijn Kooijmans, Steven Palma, Adil Zouitine, and 8 more, 2025.
https://arxiv.org/abs/2506.01844
Mengfei Zhao, Dihong Huang, Yikai Tang, Peihao Li, Mingxuan Yan, Ruiqi Zhuang, and 9 more, 2026.
https://arxiv.org/abs/2607.21588
Soroush Nasiriany, Sepehr Nasiriany, Abhiram Maddukuri, Yuke Zhu, ICLR 2026.
https://robocasa.ai/assets/robocasa365_iclr26.pdf
Timnit Gebru, Jamie Morgenstern, Briana Vecchione, Jennifer Wortman Vaughan, Hanna Wallach, Hal Daumé III, and 1 more, 2018.
https://arxiv.org/abs/1803.09010
Francesco Capuano, Michel Aractingi, Quentin Lhoest, Caroline Pascal, Pepijn Kooijmans, Jade Choghari, and 5 more, Hugging Face blog, 2025.
https://huggingface.co/blog/lerobot-datasets-v3
Jade Choghari, Pepijn Kooijmans, Mansi Agarwal, Yusuf Umut Ciftci, Aseem Doriwala, Catherine Weaver, and 5 more, 2026.
https://arxiv.org/abs/2609.36416
Spot a factual error or missing qualification? Report a content correction.