Cross-Embodiment Transfer
How one policy learns from many robot bodies and from humans.
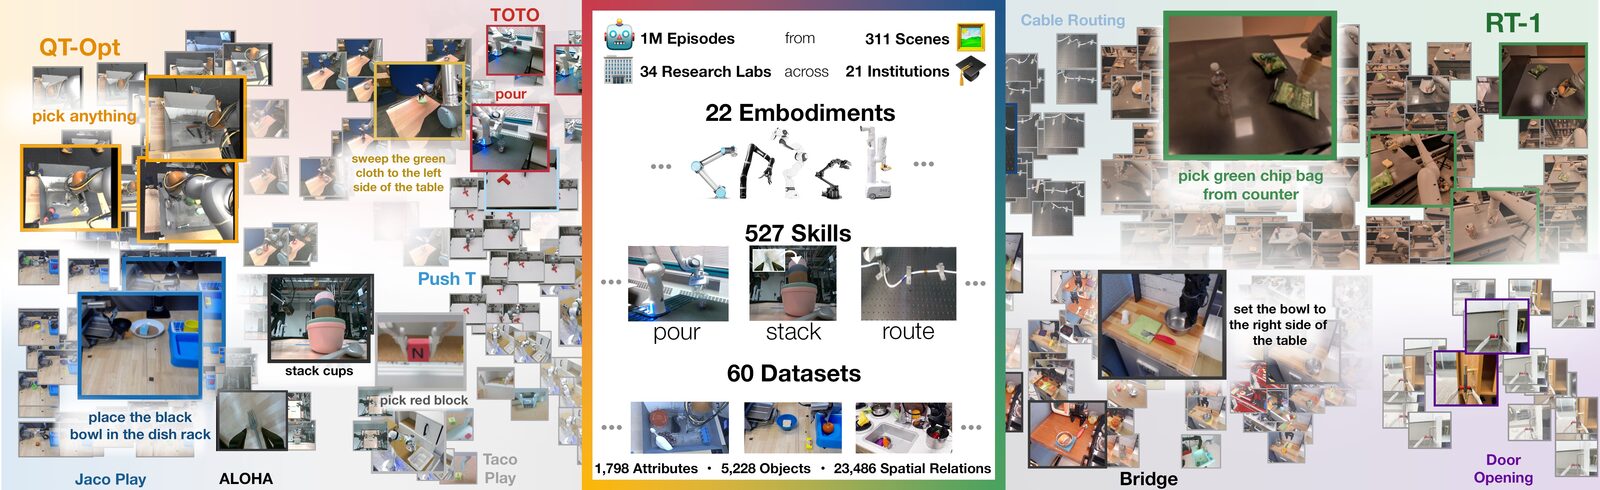
Cross-embodiment transfer is training one policy on data from bodies with different joint counts, action dimensions and sensors, or moving a policy to an unseen body. Open X-Embodiment pools data from 22 robot embodimentsSource 3, and human video adds a body whose actions are estimated from imagesSource 8.
Try “Translate between bodies”.
Cross-embodiment
Describe hand motion, not joints, and human videos become usable
Way to share one action list
Adjust more
All 32 slots for: Shared relative EEF space
7-DoF arm7 joint targets + gripper (illustrative)8 shared dims (toy); wrist and hand actions not separately modelled
bimanual setuptwo arms, two grippers (illustrative)8 shared dims (toy); wrist and hand actions not separately modelled
humanoid29 illustrative coordinates; not hardware DoF8 shared dims (toy); wrist and hand actions not separately modelled
human hand, egocentric video3D hand keypoints tracked from video8 shared dims (toy); wrist and hand actions not separately modelled
Shared relative EEF space: N1.7 README: 20K hours of EgoScale human video
Shared relative EEF spaceGR00T N1.7
NVIDIA describes N1.7 relative end-effector actions shared across human and robot data. EgoScale separately specifies wrist deltas and retargeted hand joint actions; this eight-slot strip does not implement those adapters.
The N1.7 README reports 20K hours of EgoScale human video alongside robot demonstrations. The separate EgoScale paper also uses aligned human-robot mid-training.
driven by this sourcezero-paddinghatched: illustrative link, not model dimensionsunused
How this was made
A model trained on many robots needs one action list that every body can write into. Each bar here is an illustrative 32-slot vector. The robot rows use toy widths: 8 coordinates for a 7-DoF arm (seven joint targets and a gripper; DoF counts the joints that move independently), 16 for two arms with two grippers, and 29 for a humanoid, which is not its hardware DoF count. A person on video has no joint targets at all, only 3D hand keypoints tracked from the footage.
Padding gives each robot its own leading slots and fills the rest with zeros; this toy models no adapter for human data. Motion transfer, in the Gemini Robotics 1.5 report, aligns embodiments during training; the 3 hatched slots are an illustrative link, not a disclosed latent. A shared relative end-effector (EEF) space describes where the hand or gripper moves relative to where it is, so a tracked human hand can fill the same 8 slots. NVIDIA's GR00T N1.7 README reports relative EEF actions shared across robot data and 20K hours of EgoScale human video; the EgoScale paper (Zheng 2026) separately uses wrist deltas, retargeted hand joint actions and aligned human-robot mid-training. The strips do not implement those adapters.
Shared relative end-effector space is illustrated with 8 shared slots. N1.7 reports 20K hours of EgoScale human video; EgoScale separately uses wrist deltas, hand joint targets and aligned mid-training. These operations are not implemented by the strips.
Current cross-embodiment mapping
- strategy
- Shared relative EEF space
- human video
- N1.7 README: 20K hours of EgoScale human video
- embodiments
- 4
- strip width
- 32 slots
Original slot illustrations; strip widths and the 8-, 16- and 29-coordinate robot rows are toy choices.
10K hours
pi0 own demonstrations
7 configurations, 68 tasks; additional public data is separate
22 embodiments
OXE v9 dataset
RT-X experiments used nine, not all 22
20K hours
N1.7 human pretraining
EgoScale human video, alongside robot demonstrations; README report
about 2×
PI generalization gain
human-robot co-fine-tuning; four human-only generalization scenarios
Counting robot and human data
π0's 10,000 hours are its own data from 7 robot configurations and 68 tasks; by timesteps, the open-source OXE, DROID and Bridge data are 9.1% of the mixtureSource 1. RT-X experiments used 9 of OXE's 22 embodimentsSource 3, and GR00T N1.7's rounded 20K pretraining hours are EgoScale human videoSource 7.
Moritz Reuss wrote in October 2025 that "OXE is mostly low-quality data" and that imitation learning lacks good ways to measure data qualitySource 4. Re-Mix's learned mixture weights beat uniform weights by 38% on averageSource 11, and Toyota Research Institute's controlled study of 89 policies found co-training with cross-embodiment robot data improves generalization to distribution shifts and unseen tasksSource 28.
Robot action interfaces
π0 zero-pads every action vector to the largest robot's 18 dimensionsSource 1. Octo curates 25 OXE datasets with delta end-effector control and aligns grippers to one convention, adding lightweight encoders or heads for new spacesSource 2, while CrossFormer trains one transformer on 900K trajectories from 20 embodiments without manually aligning observation or action spacesSource 12.
HPT maps each embodiment's proprioception and vision to a few tokens for a shared trunk, scaling to 52 datasetsSource 13. LAP writes low-level actions as natural language, and LAP-3B reports over 50% average zero-shot success on unseen robots, about twice the strongest prior VLAsSource 14.
Motion Transfer across robot embodiments
Gemini Robotics 1.5 trains on ALOHA, bi-arm Franka and Apptronik Apollo data plus Internet text, images and video, with Motion Transfer, an architecture and training recipe that aligns embodiments. On tasks demonstrated only on another robot it helps, less so for Apollo, in ablations run interleaved on one work cell; one checkpoint drives all three robots, though the long-horizon agent adds bi-arm Franka post-training, and the report specifies an orchestrator over the VLA but not the alignment representationSource 5. DeepMind says tasks shown only to ALOHA 2 "just work" on Apollo and bi-arm Franka, and vice versaSource 15.
DeepMind says On-Device 2, natively multi-embodiment with Motion Transfer, adapts to new bi-arm robots in a few hours, typically from fewer than 200 examplesSource 6.
Relative end-effector actions for robots and humans
GR00T N1 embedded state and action with embodiment-aware encodersSource 16; N1.6 moved most embodiments to state-relative action chunks, which NVIDIA found smoother and more accurate than absolute actionsSource 17. N1.7 shares relative end-effector deltas between human and robot embodiments and calls this a key factor in cross-embodiment performanceSource 7.
Shared actions
The hand's motion transfers between bodies; joint angles do not
The robot copies the person's
Faint: the person's check mark, placed at the robot's startJoint angles copied · strays 6.8 cm
Arm lengths, poses and the stroke are illustrative; the geometry is exact
How this was made
Robots and people have different joints and different link lengths, so one body's joint angles mean little to another. GR00T N1.7 writes actions as deltas from the hand's current pose, shared by robot and human embodiments, and NVIDIA calls this a key factor in its cross-embodiment performance: because the representation is the same for human and robot data, priors learned from human video carry over to robot control. EgoScale likewise uses relative wrist motion, and N1.6 moved most embodiments to state-relative action chunks.
The drawing is two easels on one bench. At the left a mannequin arm holds a pen to its squared sheet and draws a check mark. At the right a robot arm with shorter links holds its pen to the other sheet. The copy box between them carries the person's movement to the robot, and its lever picks what is sent. To the left, the shoulder and elbow angles go across as they are, and on the shorter arm they trace a smaller, skewed stroke. To the right, the hand's motion from the stroke's start goes across, the robot works out its own angles for it, and its ink lands on the faint check mark, which is the person's stroke placed at the robot's start.
The arms' lengths, the poses and the stroke are illustrative; the geometry is exact. Real arms have more joints, which makes copying angles across bodies harder still.
NVIDIA, Isaac GR00T repository (2026); NVIDIA GEAR, GR00T N1.6 (2025); Zheng and colleagues, EgoScale (2026).
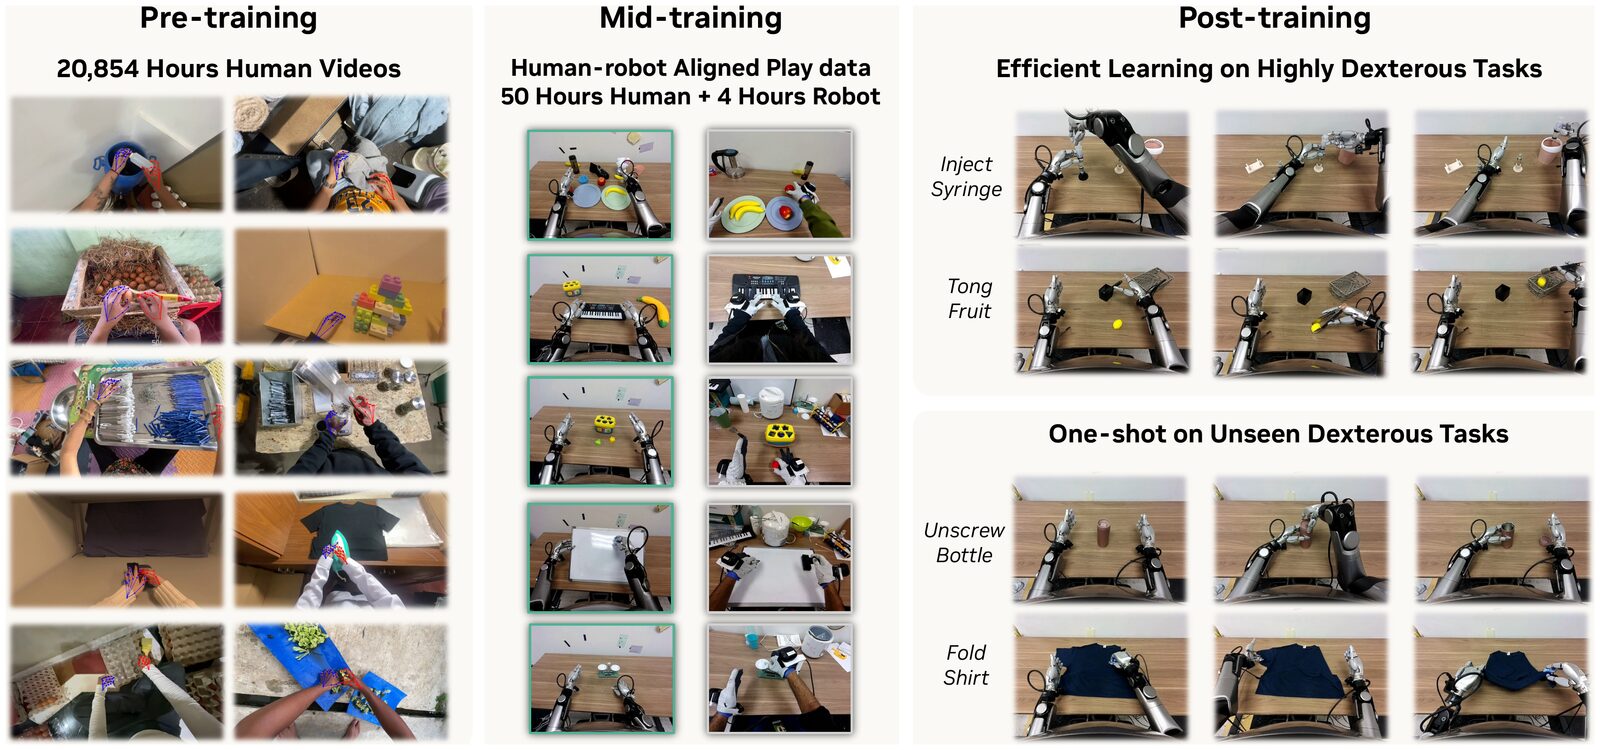
EgoScale uses relative wrist motion and retargets 21 human hand keypoints to the 22-DoF Sharpa hand, with embodiment-conditioned adapters for proprioception and hand actions around a shared backbone and action expertSource 8. Morphometric Imitation (September 2026) retargets reconstructed hand-object interactions across hand morphologies, then refines them with residual RL; on a Sharpa hand its policies reached 89.3% zero-shot success in 300 real trials on 30 objectsSource 10.
Closing the visual embodiment gap
Mirage masks out an unseen target robot and inpaints the source robot in real timeSource 18. RoVi-Aug synthesizes training images with other robots and viewpoints and deploys zero-shot on an unseen robot, and co-training with it raises success by up to 30%Source 19.
Latent actions as a shared interface
LAPA learns discrete latent actions between video frames, pretrains a VLA on them and fine-tunes on robot data; training only on human video still transfers positivelySource 20. LAC-WM (Stanford and Meta FAIR, October 2026) conditions a robot world model on a latent action space shared across embodiments; picking action chunks for a VLA on five unseen LIBERO tasks, it raised average success from 82.4% with an explicit-action world model to 92.0%Source 32.
Human-to-robot transfer recipes
Simar Kareer's EgoMimic treated human and robot data equally and found an extra hour of hand data worth more than one of robot dataSource 21. On December 16, 2025, Kareer and Physical Intelligence colleagues co-fine-tuned π0.5 on human data, with 3D hand positions as actions, and the most relevant robot data. PI reports about 2× performance on four scenarios present only in human data, without trial counts, and transfer that improves as robot pretraining diversifiesSource 9.
EgoScale's Ruijie Zheng and coauthors instead pretrain on human video, mid-train on aligned human-robot data and post-train on task robot data, and find adding aligned mid-training best overallSource 8. EgoBridge aligns human and robot policy latents with optimal transport and reports a 44% absolute success gain over human-augmented cross-embodiment baselinesSource 22. EgoLAP (Princeton, Toyota Research Institute and Physical Intelligence, October 2026) routes human and robot trajectories through a shared chain of language actions and reached 80.1% mean real-world task progress on bimanual YAM robots, 2.3 times the alternative action representationsSource 31.
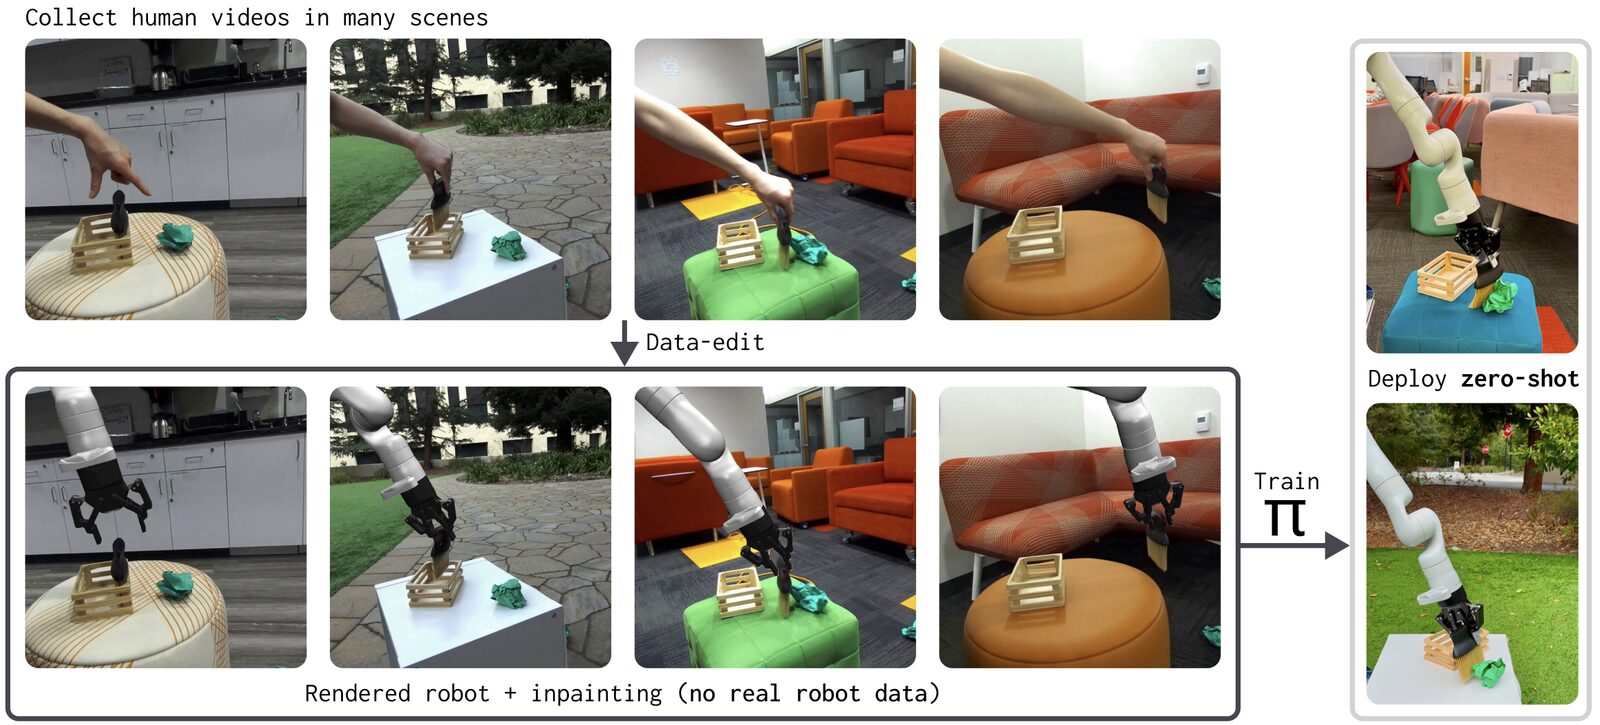
Phantom needs no robot data: it inpaints the human arm, overlays a rendered robot and deploys zero-shot, with success up to 92%Source 23. Masquerade robotizes in-the-wild human video and fine-tunes on 50 robot demonstrations per task, beating baselines by 5 to 6 timesSource 24. Figure reports that Index human-video pretraining, all else fixed, raised Helix 2.5's zero-shot success in 30 unseen homes from 9% to 56%Source 25, and Generalist's GEN-1 base model pretrains on over half a million hours from wearable devices on humans, with no robot dataSource 29.
Scaling the number of embodiments
Across about 1,000 procedurally generated locomotion bodies, adding embodiments generalizes more broadly than adding data on fixed onesSource 26. Skild reports training one model on 100,000 simulated robots and testing zero-shot on robots excluded from trainingSource 27. DreamZero adapted from AgiBot G1 to a YAM bimanual robot with 55 trajectories, about 30 minutes of play data, though its authors describe the result only qualitativelySource 30.
See also
- Teleoperation Rigs
ALOHA, GELLO, UMI and VR rigs compared on cost and quality.
- Dexterity
Contact-rich manipulation, touch sensing, in-hand reorientation and deformables.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
Linked from
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
- Other Generalist Policies
How to read the claims for Gemini Robotics, GR00T, Helix and GO-2.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
- Major Datasets
The major open robot datasets and what each collected.
- Kinematics
How joint angles place a robot's hand, and the reverse.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Dexterity
Contact-rich manipulation, touch sensing, in-hand reorientation and deformables.
- Generalization
From pi0.5's three unseen homes to Helix 2.5's 30.
References
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Octo Model Team, Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, and 14 more, 2024.
https://arxiv.org/html/2405.12213v2
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Moritz Reuss, 2025.
https://mbreuss.github.io/blog_post_iclr_26_vla.html
Gemini Robotics Team, Abbas Abdolmaleki, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, and 167 more, 2025.
https://arxiv.org/abs/2510.03342
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Ruijie Zheng, Dantong Niu, Yuqi Xie, Jing Wang, Mengda Xu, Yunfan Jiang, and 9 more, 2026.
https://arxiv.org/abs/2602.16710
Simar Kareer, Karl Pertsch, James Darpinian, Judy Hoffman, Danfei Xu, Sergey Levine, and 2 more, 2025.
https://www.pi.website/research/human_to_robot
Tara Sadjadpour, Siming He, C.K. Wolfe, Haozhi Qi, Lea Wilken, S. Shankar Sastry, and 2 more, 2026.
https://arxiv.org/abs/2609.28660
Joey Hejna, Chethan Bhateja, Yichen Jiang, Karl Pertsch, Dorsa Sadigh, 2024.
https://arxiv.org/abs/2408.14037
Ria Doshi, Homer Walke, Oier Mees, Sudeep Dasari, Sergey Levine, 2024.
https://arxiv.org/abs/2408.11812
Lirui Wang, Xinlei Chen, Jialiang Zhao, Kaiming He, NeurIPS 2024.
https://arxiv.org/abs/2409.20537
Lihan Zha, Asher J. Hancock, Mingtong Zhang, Tenny Yin, Yixuan Huang, Dhruv Shah, and 2 more, 2026.
https://arxiv.org/abs/2602.10556
Carolina Parada, Google DeepMind blog, 2025.
https://deepmind.google/blog/gemini-robotics-15-brings-ai-agents-into-the-physical-world/
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
GEAR Team, Allison Azzolini, Johan Bjorck, Valts Blukis, Fernando Castañeda, Rahul Chand, and 53 more, 2025.
https://research.nvidia.com/labs/gear/gr00t-n1_6/
Lawrence Yunliang Chen, Kush Hari, Karthik Dharmarajan, Chenfeng Xu, Quan Vuong, Ken Goldberg, RSS 2024.
https://arxiv.org/abs/2402.19249
Lawrence Yunliang Chen, Chenfeng Xu, Karthik Dharmarajan, Muhammad Zubair Irshad, Richard Cheng, Kurt Keutzer, and 3 more, CoRL 2024.
https://arxiv.org/abs/2409.03403
Seonghyeon Ye, Joel Jang, Byeongguk Jeon, Sejune Joo, Jianwei Yang, Baolin Peng, and 10 more, ICLR 2025.
https://arxiv.org/abs/2410.11758
Simar Kareer, Dhruv Patel, Ryan Punamiya, Pranay Mathur, Shuo Cheng, Chen Wang, and 2 more, 2024.
https://arxiv.org/abs/2410.24221
Ryan Punamiya, Dhruv Patel, Patcharapong Aphiwetsa, Pranav Kuppili, Lawrence Y. Zhu, Simar Kareer, and 2 more, NeurIPS 2025.
https://arxiv.org/abs/2509.19626
Marion Lepert, Jiaying Fang, Jeannette Bohg, CoRL 2025.
https://arxiv.org/abs/2503.00779
Marion Lepert, Jiaying Fang, Jeannette Bohg, ICRA 2026.
https://arxiv.org/abs/2508.09976
Figure AI, Figure news, 2026.
https://www.figure.ai/news/helix-2-5-zero-shot-30-home-generalization
Bo Ai, Liu Dai, Nico Bohlinger, Dichen Li, Tongzhou Mu, Zhanxin Wu, and 4 more, CoRL 2025.
https://arxiv.org/abs/2505.05753
Skild AI Team, Skild AI blog, 2025.
https://www.skild.ai/blogs/omni-bodied
Fanqi Lin, Kushal Arora, Jean Mercat, Haruki Nishimura, Paarth Shah, Chen Xu, and 6 more, 2026.
https://arxiv.org/abs/2602.01067
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
Lihan Zha, Shresth Grover, Tenny Yin, Samuel M. Bateman, Hengkai Pan, Mengchao Zhang, and 4 more, 2026.
https://arxiv.org/abs/2610.08726
Huang Huang, Sriram Yenamandra, Arjun Majumdar, Elie Aljalbout, Tushar Nagarajan, Tsung-Yen Yang, and 6 more, 2026.
https://arxiv.org/abs/2610.10846
Further reading
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Jinliang Zheng, Jianxiong Li, Zhihao Wang, Dongxiu Liu, Xirui Kang, Yuchun Feng, and 9 more, 2025.
https://arxiv.org/abs/2510.10274
Carolina Parada, Google DeepMind blog, 2025.
https://deepmind.google/blog/gemini-robotics-on-device-brings-ai-to-local-robotic-devices/
Marion Lepert, Ria Doshi, Jeannette Bohg, 2025.
https://arxiv.org/abs/2503.00774
Hongzhe Bi, Lingxuan Wu, Tianwei Lin, Hengkai Tan, Zhizhong Su, Hang Su, and 1 more, 2025.
https://arxiv.org/abs/2507.23523
Yulin Liu, Lai Wei, Yen-Jen Wang, Akash Sharma, Pieter Abbeel, Henrik I. Christensen, and 1 more, 2026.
https://arxiv.org/abs/2610.03861
Spot a factual error or missing qualification? Report a content correction.