Robot Learning Curriculum for ML Engineers
A dependency-ordered route from supervised learning to real robot policies.
The robot learning curriculum for ML engineers is a staged path through the robotics that policy experiments depend on: geometry, data, imitation, action representation, evaluation and deployment, each learned just before an experiment needs it. A 2025 open tutorial runs from behavior cloning and reinforcement learning to generalist policiesSource 9.
Try the check below.
Self-check
Read the reasoning
- Start with a behavior-cloning baseline and a manual evaluation protocolThis is the useful first experiment. It checks whether observations align with actions, whether the action space is learnable, and whether success can be measured before architecture becomes another variable.
- Fine-tune the largest available VLA immediatelyA larger pretrained model can add semantic priors, but it cannot tell you whether the demonstrations, action convention, reset procedure or evaluation labels are coherent. Starting here leaves every failure ambiguous.
- Run online reinforcement learning on the real armWithout a reward and a safe reset loop, online RL has neither a trustworthy objective nor a practical data-collection process. The missing evaluation system is the immediate blocker.
Earn complexity: first prove that the data, action convention and success measurement support a small closed-loop policy.
Stage 1: coordinates
Start with kinematics: which frame an object pose or end-effector delta uses, and where joint limits enter. Modern Robotics supplies the vocabularySource 1, and Tedrake warns that sloppy kinematic notation "will inevitably lead to confusion and bugs"Source 10. A drifting camera transform or timestamp mismatch can look like a stochastic policy, so calibration and state estimation come next; Kalibr estimates sensor time offsets to a fraction of the smallest measurement periodSource 11.
Expressed-in frame
Read in the wrong frame, the same move misses
Read the move in
60 degrees
Dark stroke: the demonstration. Blue ink: the replay60 degrees · table frame · 5 cm off
The move and the angles are illustrative; the geometry is exact
How this was made
An end-effector delta is a few numbers, and numbers alone do not say which way they point. Tedrake asks that every time a position is written as a vector of numbers, the frame it is expressed in be named; Lynch and Park write the same motion either in the fixed space frame or in the moving body frame. A dataset that stores deltas in the tool's frame and a controller that reads them in the table's frame disagree whenever the tool is turned, and the replay looks like a careless policy.
The drawing is a pen plotter. The rail along the back and the paper's squares are the table's frame. The tool hangs from a turret under the pen carriage, a gripper whose two fingers point along its own forward direction; the knob on the carriage reads how far it is turned. A demonstration moved 5 cm forward in the tool's frame and left the dark stroke along the fingers. The blue ink is a replay of the same two numbers: read in the tool's frame it runs down the stroke; read in the table's frame it runs along the rail and ends off the stroke. After each replay the pen lifts and the arm parks at the end of its rail, so both strokes stay in view. Square to the table, the two agree, so the mistake hides until the tool turns.
The move's length and the angles are illustrative. The miss is exact: the chord between the two moves, twice 5 cm times the sine of half the angle.
Tedrake, Robotic Manipulation (2026); Lynch and Park, Modern Robotics (2017).
Stage 2: data as a system
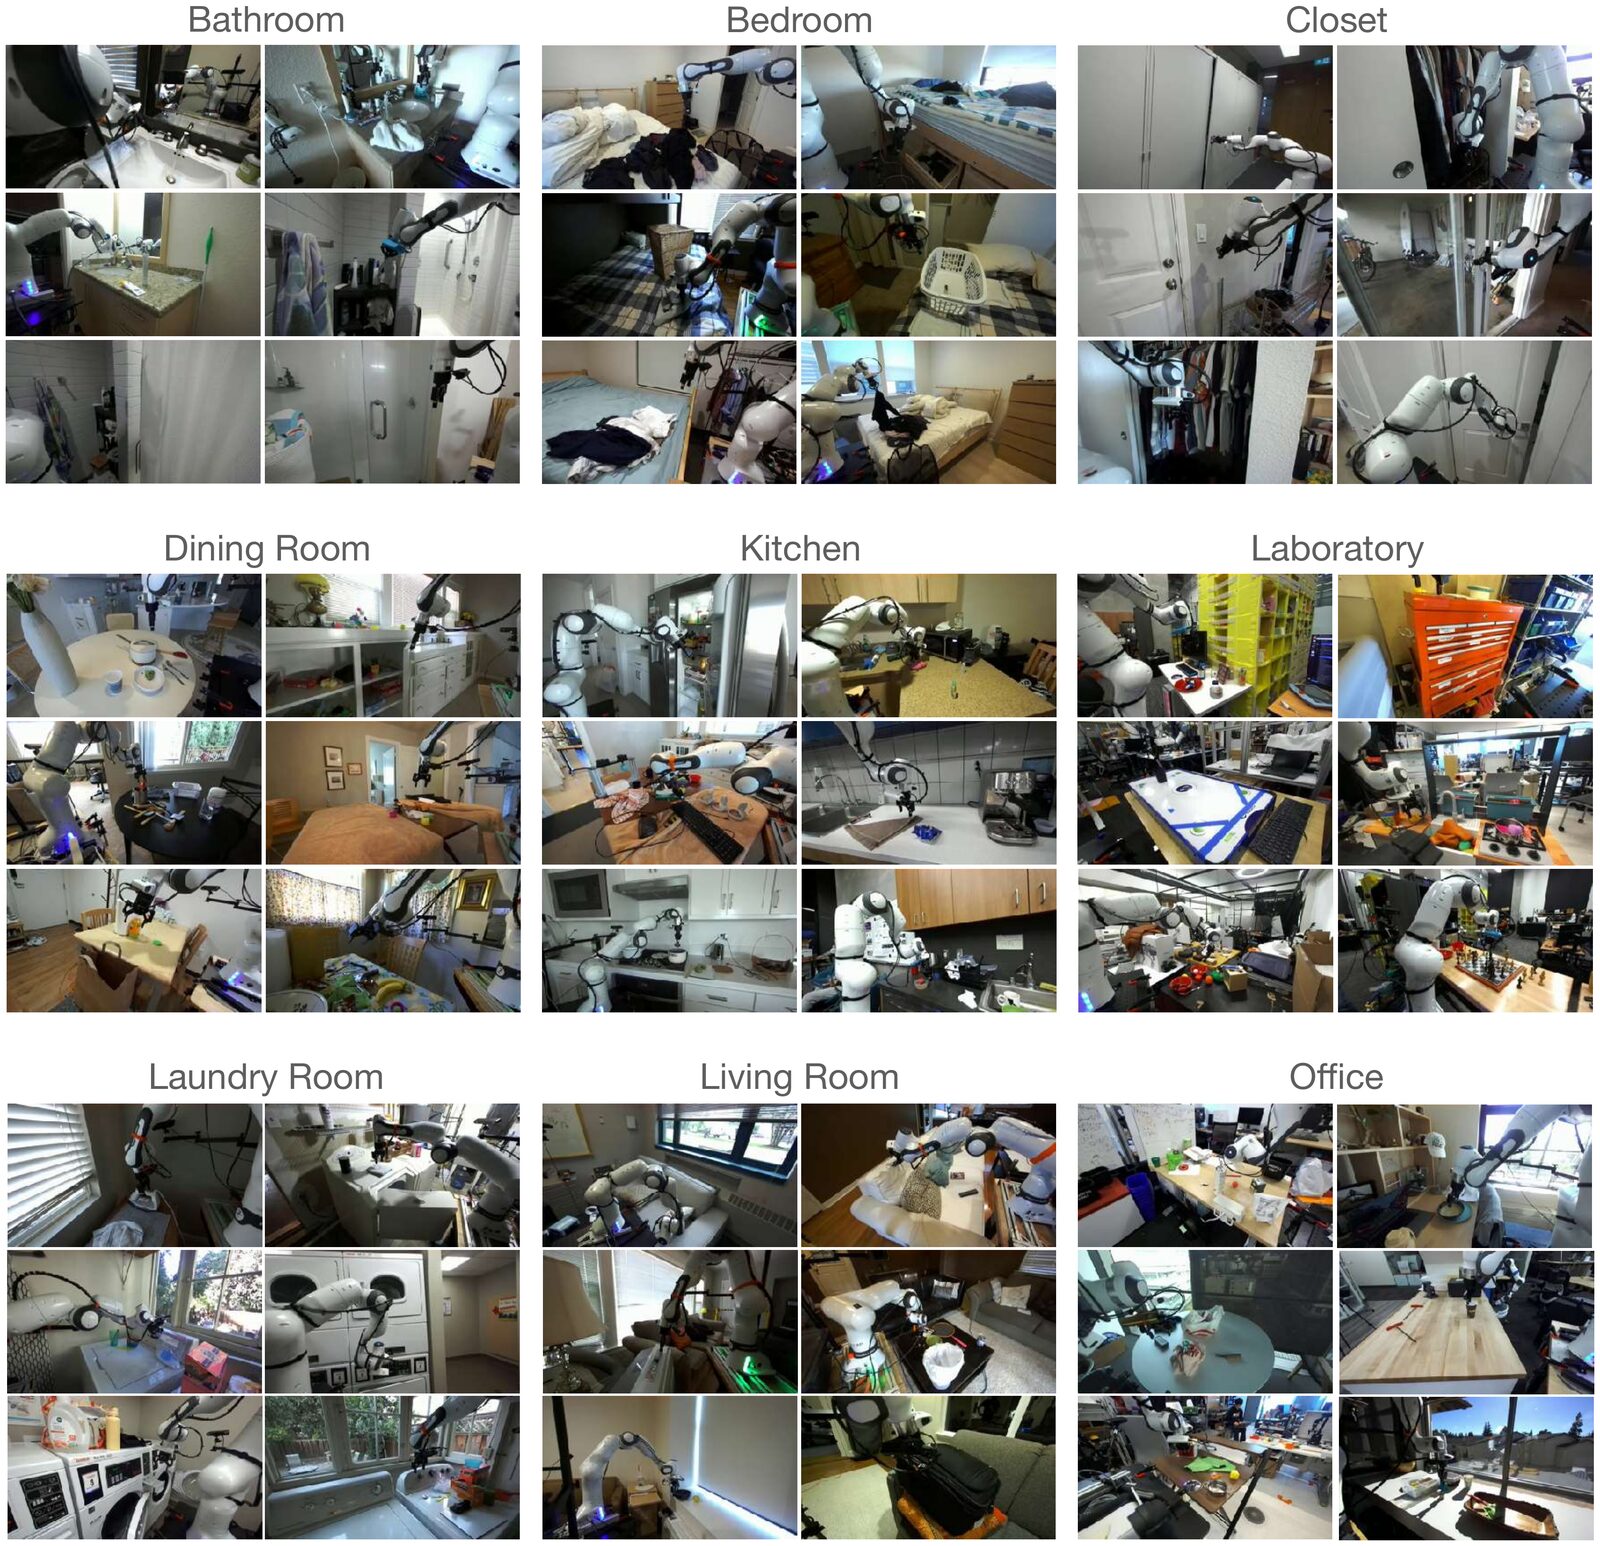
Each transition couples synchronized observations, commanded and realized actions, robot state, task identity, termination and provenance; RLDS stores such episodes losslesslySource 12. Among public datasets, Open X-Embodiment pools 22 robots from 21 institutionsSource 13, and DROID holds 76k trajectories from 13 institutionsSource 6.
Record and replay ten episodes before scaling, checking timestamps, units and rotation conventions. Past a threshold per environment or object, more demonstrations add little and diversity matters far moreSource 14. GELLO collects demonstrations more reliably than VR controllers or 3D spacemiceSource 15, and LeRobot spans the robot-learning stack from motor middleware to dataset streamingSource 16.
Stage 3: imitation baseline
Behavior cloning trains on expert states and then visits its own; DAgger formalized why errors compound and why corrective labels on learner-induced states change the problemSource 2. Start with the smallest closed-loop baseline, such as an image encoder and MLP on one camera, task and action convention, and debug alignment, normalization and reset diversity before adding scale. robomimic found results sensitive to design choices, demonstration quality and stopping criteriaSource 17.
Then add temporal structure: ACT predicts action chunksSource 3, and Diffusion Policy models a multimodal distribution over action sequencesSource 4.
Stage 4: action contract
Among action spaces, joint positions are mechanism-specific, while end-effector deltas share a task-space convention across compatible controllers. Per-dimension binning tokenizers handle high-frequency dexterous data poorlySource 18. The action representation is part of the dataset, fixing the labels, controller, error modes and which robots can share data, so change it separately from the model.
Stage 5: pretraining
A VLA helps when language, semantic generalization or multi-task transfer matters. OpenVLA made the recipe reproducibleSource 5, π0 pretrains on over 10,000 hours of robot dataSource 19, and SmolVLA trains on one GPU yet performs comparably to VLAs ten times largerSource 20. Pretraining can help recognize an unseen object category, but a wrong hand-eye transform still needs calibration; in TRI's blind, randomized trials, multitask pretraining taught new tasks with a fraction of the dataSource 21.
Stage 6: evaluation
Define success, failure, intervention, reset and timeout before the main run, and separate familiar configurations from changed objects, backgrounds, lighting and geometry. Papers often give little or no information on run counts, initial conditions, success criteria or statisticsSource 22. Report trial counts and uncertainty; STEP's sequential test needs up to 32% fewer trials than prior testsSource 23.
Open-loop loss is only a diagnostic; closed-loop success under controlled shifts is the measure. LIBERO-Plus shifts layout, viewpoint, initial state, language, lighting, background and sensor noiseSource 8, SIMPLER's simulated scores correlate with real performanceSource 24, and RoboArena's double-blind pairwise trials rank generalist policies better than centralized evaluationSource 25. For deployment, ROS 2 adds the production-grade features ROS 1 lackedSource 26.
Simulation and RL
Simulation tests controller stability and safe reward optimization. Domain randomization aims to make the real world look like one more simulated variationSource 27, and Isaac Lab targets large-scale robot learningSource 7, though its dynamics gap to the hardware needs measuring.
Offline RL learns from logged data without new collectionSource 28. Online RL needs safe exploration, automatic resets and cheap evaluation, which SERL bundles with an off-policy learnerSource 29; without them, start with imitation learning. In simulation, RL can stand in for scarce demonstrations: SimpleVLA-RL lifted OpenVLA-OFT trained on one demonstration per task from 48.9% to 96.9% average LIBERO successSource 30.
A practical sequence
Build replayable data and a deterministic evaluation harness, then behavior cloning; add chunks when the baseline needs them, a VLA for semantic transfer, and RL once reward, coverage and resets are real. The tutorial provides ready-to-use LeRobot examplesSource 9.
See also
- Kinematics
How joint angles place a robot's hand, and the reverse.
- ROS 2 for Machine Learning Engineers
ROS 2 as the production boundary around a learned policy.
- Behavior Cloning Foundations
Covariate shift makes naive imitation drift, and DAgger is the standard fix.
Linked from
- Major Datasets
The major open robot datasets and what each collected.
References
Kevin M. Lynch, Frank C. Park, Cambridge University Press, 2017.
https://hades.mech.northwestern.edu/index.php/Modern_Robotics
Stéphane Ross, Geoffrey J. Gordon, J. Andrew Bagnell, AISTATS 2011.
https://arxiv.org/abs/1011.0686
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
Alexander Khazatsky, Karl Pertsch, Suraj Nair, 2024.
https://arxiv.org/abs/2403.12945
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
Senyu Fei, Siyin Wang, Junhao Shi, Zihao Dai, Jikun Cai, Pengfang Qian, and 7 more, 2025.
https://arxiv.org/abs/2510.13626
Francesco Capuano, Caroline Pascal, Adil Zouitine, Thomas Wolf, Michel Aractingi, 2025.
https://arxiv.org/abs/2510.12403
Russ Tedrake, MIT course notes, 2026.
https://manipulation.csail.mit.edu/pick.html
Paul Furgale, Joern Rehder, Roland Siegwart, 2013 IEEE/RSJ International Conference on Intelligent Robots and Systems.
https://doi.org/10.1109/IROS.2013.6696514
Sabela Ramos, Sertan Girgin, Léonard Hussenot, Damien Vincent, Hanna Yakubovich, Daniel Toyama, and 6 more, 2021.
https://arxiv.org/abs/2111.02767
Open X-Embodiment Collaboration, Abby O'Neill, Abdul Rehman, Abhinav Gupta, Abhiram Maddukuri, Abhishek Gupta, and 288 more, 2023.
https://arxiv.org/abs/2310.08864
Fanqi Lin, Yingdong Hu, Pingyue Sheng, Chuan Wen, Jiacheng You, Yang Gao, ICLR 2025, 2024.
https://arxiv.org/abs/2410.18647
Philipp Wu, Yide Shentu, Zhongke Yi, Xingyu Lin, Pieter Abbeel, 2023.
https://arxiv.org/abs/2309.13037
Remi Cadene, Simon Aliberts, Francesco Capuano, Michel Aractingi, Adil Zouitine, Pepijn Kooijmans, and 11 more, 2026.
https://arxiv.org/abs/2602.22818
Ajay Mandlekar, Danfei Xu, Josiah Wong, Soroush Nasiriany, CoRL 2021.
https://arxiv.org/abs/2108.03298
Karl Pertsch, Kyle Stachowicz, Brian Ichter, Danny Driess, Suraj Nair, Quan Vuong, and 3 more, 2025.
https://arxiv.org/abs/2501.09747
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Mustafa Shukor, Dana Aubakirova, Francesco Capuano, Pepijn Kooijmans, Steven Palma, Adil Zouitine, and 8 more, 2025.
https://arxiv.org/abs/2506.01844
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Hadas Kress-Gazit, Kunimatsu Hashimoto, Naveen Kuppuswamy, Paarth Shah, Phoebe Horgan, Gordon Richardson, and 2 more, 2024.
https://arxiv.org/abs/2409.09491
David Snyder, Asher James Hancock, Apurva Badithela, Emma Dixon, Patrick Miller, Rares Andrei Ambrus, and 3 more, RSS 2025.
https://arxiv.org/abs/2503.10966
Xuanlin Li, Kyle Hsu, Jiayuan Gu, Karl Pertsch, Oier Mees, Homer Rich Walke, and 10 more, 2024.
https://arxiv.org/abs/2405.05941
Pranav Atreya, Karl Pertsch, Tony Lee, Moo Jin Kim, Arhan Jain, Artur Kuramshin, and 26 more, 2025.
https://arxiv.org/abs/2506.18123
Steven Macenski, Tully Foote, Brian Gerkey, Chris Lalancette, William Woodall, Science Robotics 7(66), 2022.
https://doi.org/10.1126/scirobotics.abm6074
Josh Tobin, Rachel Fong, Alex Ray, Jonas Schneider, Wojciech Zaremba, Pieter Abbeel, IROS 2017.
https://arxiv.org/abs/1703.06907
Sergey Levine, Aviral Kumar, George Tucker, Justin Fu, 2020.
https://arxiv.org/abs/2005.01643
Jianlan Luo, Zheyuan Hu, Charles Xu, You Liang Tan, Jacob Berg, Archit Sharma, and 4 more, ICRA 2024.
https://arxiv.org/abs/2401.16013
Haozhan Li, Yuxin Zuo, Jiale Yu, Yuhao Zhang, Zhaohui Yang, Kaiyan Zhang, and 15 more, 2025.
https://arxiv.org/abs/2509.09674
Further reading
Michael Kelly, Chelsea Sidrane, Katherine Driggs-Campbell, Mykel J. Kochenderfer, arXiv v2 (11 March 2019).
https://arxiv.org/abs/1810.02890
Roberto Martin-Martin, Michelle A. Lee, Rachel Gardner, Silvio Savarese, Jeannette Bohg, Animesh Garg, IEEE/RSJ Int. Conf. Intelligent Robots and Systems, 2019.
https://doi.org/10.1109/IROS40897.2019.8968201
Spot a factual error or missing qualification? Report a content correction.