Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
Reward design is writing the objective a reinforcement learning policy learns to maximize: in legged locomotion, a weighted sum of terms whose weights are tuned by handSource 1, and now also reward code written by language modelsSource 5. Model-predictive control instead plans actions online with an explicit dynamics modelSource 9.
Reward design
How you score a robot shapes how it walks
Scoring rule
Adjust more
Lit fader: the scoring rule in charge of the walkSteady trot
Illustrative teaching model. No policy is trained here.
How this was made
This is a local teaching model, not a trained robot. Its score adds up twelve illustrative reward terms: each term has a fixed size and a weight, rewards count up and penalties count down, and the sum is the weighted total per step. The terms, weights and sizes are teaching choices, not a source configuration or the paper reward.
Selected category: balanced gaitWeighted total: -5.52 / step
Preview phase: 0%Three rules pick a failure category, checked in this order. Chatter (the legs jitter) when the action-rate penalty is near zero. Freeze (the robot stands still) when the torque penalty reaches 2.5 and also 2 times the velocity-tracking weight. Prance (it bounces in place) when foot air time passes the same two bars. Otherwise the robot trots. These are chosen classification rules and drawn poses, not trained policies, measured control frequencies or actuator-damage predictions. The preview phase is how far the drawing is through one stride; Play loops it until Stop brings it back to where it started (with reduced motion, Play steps through one stride and stops there), and Step moves it on by 5 percent. At phase 0 the bounce is drawn at its top and the jitter at its widest, so a changed walk shows before Play.
The drawing is a mixing desk wired to a treadmill bay. Each of its twelve faders is one weight, in the order of the sliders, from 0 at the front of its slot to 4.0 at the back; a dot beside each slot marks the balanced score. The lit fader is the one in charge of the walk: velocity tracking while the trot holds, otherwise the weight that tipped it. The robot’s feet and body follow the same drawn poses, and the belt runs only while it walks.
The four scoring rules each change one weight of the balanced score: “Too strict on effort” sets the torque penalty to 4.0, “Loves high steps” sets foot air time to 4.0, and “Ignores jerky moves” sets the action-rate penalty to 0.0.
- Linear velocity tracking: default weight 1.0. Follow the commanded forward velocity. The task itself.
- Yaw rate tracking: default weight 0.5. Follow the commanded turn rate.
- Torque penalty: default weight 0.8. Discourage large joint torques; saves the actuators.
- Joint acceleration penalty: default weight 0.5. Smooths the motion by pricing jerky joints.
- Action-rate penalty: default weight 0.8. Penalizes step-to-step action changes; suppresses chatter.
- Joint limit penalty: default weight 1.0. Keeps joints off their mechanical stops.
- Collision penalty: default weight 1.0. Penalizes contact on bodies that should never touch.
- Base height: default weight 0.5. Holds the torso near a target height.
- Orientation penalty: default weight 0.8. Penalizes roll and pitch away from level.
- Foot air time: default weight 0.6. Illustrative air-time contribution; not the reference first-contact calculation.
- Foot stumble penalty: default weight 0.8. Penalizes feet catching vertical surfaces mid-stride.
- Termination penalty: default weight 1.5. Falling over ends the episode at a cost.
The 12 weighted reward terms give an illustrative total of -5.52 per step, and the preview is a balanced trot: neither torque 0.8 nor air time 0.6 clears the 2.5 attractor bar and 2x the 1.0 velocity-tracking weight together, so the chosen rule draws a trot instead of freezing, prancing, or chattering.
Current reward-weight attractor
- attractor
- balanced trot
- total
- -5.52 / step
- torque
- 0.8
- air time
- 0.6
- action-rate
- 0.8
9 terms
Rudin paper reward
including feet air time
83%
Eureka headline
29 simulated tasks; see protocol below
real-time
iLQR MPC
whole-body, on hardware
0
MPC task data
demonstrations required
The reward is the product
Rudin and colleagues define a weighted sum of nine reward terms, including feet air time, and prescribe no gait scheduleSource 1. The initial legged_gym commit (October 2021) declares fifteen entries in LeggedRobotCfg.rewards.scales. Nine are nonzero, from velocity tracking and joint torque to feet air time and action rate, and the joint-limit and contact-force functions among its nineteen reward functions are inactive in this configSource 2.
Rudin and colleagues report artifacts such as a dragging leg and unreasonably high or low base heights, and tuned the weights before hardware transferSource 1. Margolis and Agrawal note that a policy failing in a new environment needs "a slow and iterative cycle of reward and environment redesign"Source 16. Rudin's PPO adapts its learning rate from the KL divergence between new and old policies: with a target of 0.01, it lowers the rate when KL exceeds twice the target and raises it under halfSource 1.
Three answers to weight tuning
The first answer adds constraints. Yunho Kim and colleagues use three rewards (command tracking, joint torque, action smoothness) and 11 constraints, six probabilistic and five average, training separate controllers in simulation for Raibo, Mini-cheetah, Hound, ANYmal B, ANYmal C, Unitree Go1 and Atlas and deploying on Raibo and Mini-cheetah. Across robots they adjusted only the torque coefficient among the rewards, found by trial and error, though constraint limits and PD gains still changed, and the probabilistic and average limits are not per-step hard boundsSource 6.
Dohyeong Kim and colleagues split acrobatic tasks into manual stages with their own rewards and costs, five reward and five cost functions for a back-flip; stage-transition rules, cost thresholds, preferences and hyperparameters stay hand-set, and a real Go1 performs back-flips, side-rolls and two-hand walkingSource 8.
The second answer adapts weights during training. Srisuchinnawong and Manoonpong's ROGER shifts gains between the primary reward and penalties near selected constraint thresholds, with penalties subtracted from the primary reward; the revised paper reports an exploration-induced violation in simulation and limits its safety claims to assumptions of zero-penalty optimality and gentle system and learning dynamicsSource 7. The third answer removes per-skill tuning: BeyondMimic covers many agile humanoid skills with one tracking setup and shared hyperparametersSource 17, and language models can write the reward code itself.
Eureka: the reward as code under evolution
Eureka searches over reward code while PPO learns the policies. A language model receives a task description and environment observation code, with the existing reward excluded, and proposes Python reward functions; a separate task-fitness function selects candidates, and fitness and reward-component snapshots feed the next mutationSource 5.
The evaluation covers 29 simulated tasks, and the headline is 83% of tasks and 52% average normalized improvement over each benchmark's original shaped reward; Eureka matches or beats the human reward on all nine Isaac tasks and 15 of 20 Dexterity tasks. Search reports the best reward across restarts, and final rewards are scored by the mean of maximum task fitness over ten checkpoints. Human-normalized scores are bounded to [0, 3] for the headline, so 52% measures normalized reward improvementSource 5.
Teaching a robot to walk
An AI fixes a robot's scoring rules until it walks
- Rules
- Speed only
- In practice
- Sprints at 2.8 metres a second, then falls
- Task score
- 0.31 of 1
- Fix
- Reward staying up, and make a fall cost points
Illustrative example, not a recorded run
How this was made
Eureka loop, scripted replay
Scripted replay of the Eureka loop (propose reward code, train, select on fitness, reflect, mutate) with authored teaching data, not a recording of a real Eureka run. In Eureka a language model writes reward code for the task, a policy trains on each candidate, a task-fitness score picks the best, and the model reflects on per-term training statistics before writing the next generation. Task: quadruped forward walking at 1.0 m/s.
The drawing is that loop as a bench. Each round's rules are punched into a card, one notch on its top edge for each rule the reward code pays or charges for: raw speed, being near the target speed, staying up, a fall, jerky moves. The reader's pins drop into the notches, the robot runs, and the logger writes its speed on a ribbon that feeds back into the writer: a spike that ends in a fall within half a second, a flat line at almost zero for the full 20 seconds, then a line along the 1.0 metres a second target.
Generation 0 of 2Fitness: 0.31
Fitness is the task score after training with this reward, from 0 to 1; the scores here are authored.
Scripted reward statistics
- episode length
- 0.4 sfail
- base_vel_x (mean)
- 2.8 m/swatch
- episodes ending in a fall
- 100%fail
- time at target speed
- 3%fail
Scripted reflection on the statistics
Fitness is low. base_lin_vel_x spikes to 2.8 m/s, nearly three times the command, then every episode terminates in under half a second. The reward pays for speed and never for survival, so sprinting into a fall is the optimal policy. Next generation: add a survival bonus and make falls expensive.
Proposed reward code, generation 0
def reward(obs, act):
    # task: walk forward at 1.0 m/s
    return obs.base_lin_vel_x
Eureka needs a task-fitness function, which its authors say can diverge from human intent; they show an extension with human-written reward reflectionSource 5. Specification gaming satisfies the literal objective without achieving the intended outcome, and DeepMind researchers have collected around 60 examplesSource 18. DrEureka writes both reward functions and domain-randomization distributions, getting a quadruped to walk atop a yoga ballSource 19.
Curriculum: staying on the difficulty frontier
Reward shaping decides what to optimize; curriculum decides in what order difficulty appears. Ng and colleagues showed that a shaping reward expressible as a difference of potentials leaves the optimal policy unchanged, and that this form is necessary for invarianceSource 20.
A terrain curriculum promotes robots that succeed on a tile to harder terrain and demotes those that failSource 1. Manipulation lacks such cheap evaluation, since its MDP is not cheaply simulatable. Automatic Domain Randomization widens the randomization distribution as success crosses a threshold, an idea from OpenAI's dexterous hand work that Isaac Lab ships as a configurable curriculumSource 4 Source 3, and a velocity-command curriculum is one of the two main components of Margolis and colleagues' Mini Cheetah controllerSource 21.
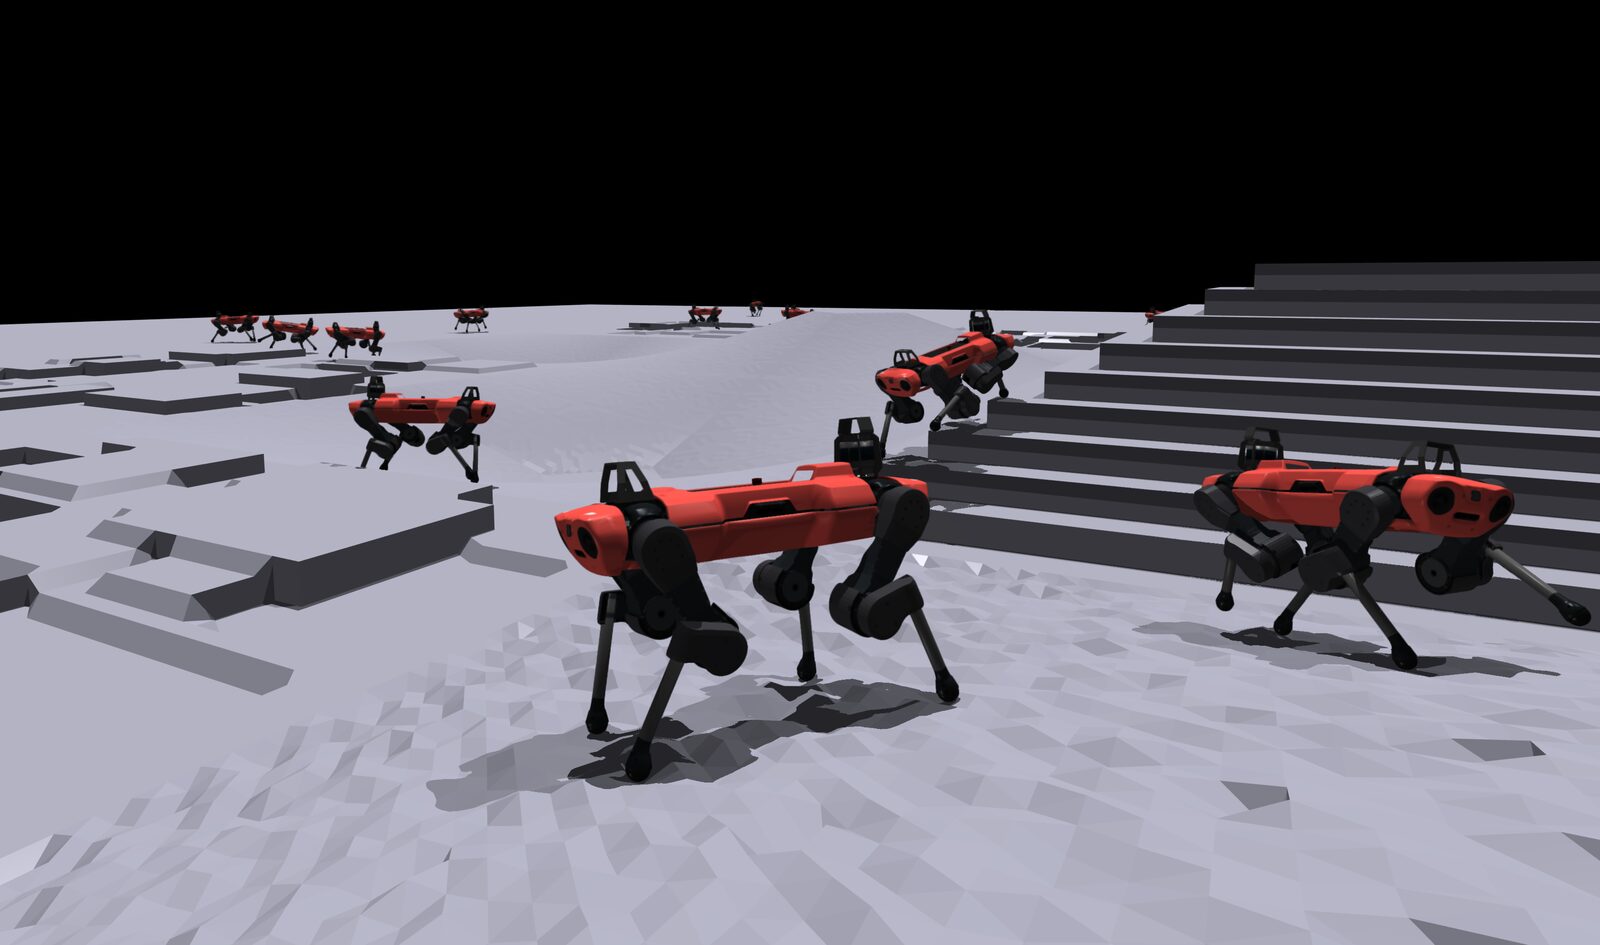
BVER, from Marco Hutter (ETH Zurich) and colleagues (October 2026), borrows from bidirectional RRT, growing start states outward from the goal and goals outward from the start; on quadruped box climbing it reached 95% success on a 0.4 m box in about 65% fewer iterations than the best reference-free curriculum it was compared withSource 32.
Success Guided Sampling (SGS), from Octi Zhang, Byron Boots and colleagues at the University of Washington and NVIDIA (CoRL 2026), applies the same idea to task configurations in general. It samples the configurations near the edge of what the policy can do, because uniform sampling spends a growing share of each batch on configurations already mastered or still out of reach. With up to about a million parallel environments, it solved multi-terrain quadruped locomotion and contact-rich assembly tasks that the prior methods it was compared with failed to solve, and the distilled RGB assembly policies transferred zero-shot to real hardwareSource 34.
The classical baseline got stronger
Classical legged control simplifies the model in its MPC layer. MIT Cheetah 3 cast its dynamics as a convex problem that still captures the full 3D system, planning ground reaction forces over horizons up to 0.5 s and solving in under 1 msSource 22. Zhang and colleagues call this tradition the "model hierarchies commonly seen in traditional model-based MPC", built on "reduced-order models and hierarchical control approaches"Source 9.
Whole-body MPC itself ran on legged hardware earlier: Sleiman and colleagues' 2021 framework plans locomotion and manipulation as one multi-contact optimal control problem, solved in real time onboard, and pushed and pulled a heavy resistive doorSource 33. DIAL-MPC optimizes full-order quadruped dynamics in real time without training and outperforms RL policies by 50% on climbing tasksSource 23.
Zhang and colleagues' MuJoCo-based iLQR controller, revised in 2026 to appear at ICRA 2026, runs on Unitree quadrupeds and an H1 humanoid with one warm-started iLQR update per solve. On a 20-core 13th-generation Intel i9, iLQR and TV-LQR feedback run at about 50 Hz and 300 Hz; the experiments fuse 100 Hz OptiTrack measurements with 500 Hz joint data, and onboard-only deployment is untested. Raising MuJoCo's impratio from 1 to 100 to reduce slipping doubled a quadruped iteration from 10 to 20 msSource 9.
MPC re-solves against the measured state at every step, so feedback corrects part of the model mismatch online, though not all of it: Zhang and colleagues call for better system identification "to overcome the significant sim-to-real gap"Source 9, and Boston Dynamics says MPC works well when "the controller's model behaves similarly to the physical system". Its 2024 Spot account keeps the model-based locomotion controller while a learned policy removes the need to run multiple MPC instances in parallelSource 11, and in its August 2025 Atlas report with TRI, language-conditioned policies drive the robot through the control interface of an MPC-based teleoperation systemSource 12.
The case for each side
| Axis | Model-based (MPC / whole-body QP) | Learned (sim-RL policy) |
|---|---|---|
| model error | Corrected online: every control step re-solves against the measured state, so model bias is rejected by feedback. | Must be anticipated at training time with domain randomization or system ID; the residual error is baked into the weights. |
| constraints | Explicit and enforced: friction cones and torque limits are hard constraints in the optimization. | Implicit: violations are discouraged by reward penalties, with no guarantee they hold. |
| deploy-time compute | High: a trajectory optimization problem is solved at every control step. | Low: a single network forward pass. |
| contact-mode discovery | Harder: contact schedules are combinatorial and often given, though sampling-based MPC now finds gaits and contact sequences without handcrafted patterns. | Emergent from exploration across thousands of parallel environments. |
| rich perception | Indirect: perceptive MPC plans against constraints extracted from elevation maps; there is no clean way to put an RGB image into a QP. | Natural: end-to-end from images or heightscans. |
| task data | Zero task data needed; the cost is a dynamics model instead. | No model needed; the cost is simulation samples and tuning. |
| development cost | Model derivation and gain tuning. | Reward tuning and randomization tuning. |
The case for learning: sim-trained controllers took two generations of ANYmal through natural environments "beyond the reach of prior published work in legged locomotion", in Lee and colleagues' words, at the cost of one forward pass at deploy timeSource 10. Miller and colleagues report an end-to-end RL policy on Spot at over 5.2 m/s, more than triple the default controller's maximum speedSource 24. In drone racing, RL beat optimal control because it "optimizes a better objective" and copes with model uncertainty through domain randomizationSource 25, and semantic, language-conditioned control comes from the learned side, as Gemini Robotics 2 shows on humanoid whole-body controlSource 13.
The case for model-based control: a deliberately simple whole-body iLQR baseline runs in real time on quadruped and humanoid hardware with no task dataSource 9. Grandia and colleagues optimize all of ANYmal's degrees of freedom in real time against foothold constraints from elevation mapsSource 26, and sampling MPC now discovers gaits and contact sequences without handcrafted patterns, in real time on a CPUSource 27. Convex MPC can enforce friction-cone limits as hard constraints, as MIT Cheetah 3's planner does, where a reward penalty only discourages violationsSource 22.
Newton's hydroelastic contact modeling is inspired by Drake's, Drake developer TRI partners with Newton on solvers and contact, and Newton is now a physics backend for Isaac LabSource 14 Source 15. Massively parallel sampling MPC on a real Franka still reports contact sensitivity as a main challengeSource 28.
Two ways to stay upright
Planning ahead fails on wrong guesses, practice on new surprises
Surprise for the robot
Adjust more
| Surprise | Plans ahead | Learned by practice |
|---|---|---|
| Sideways shove | stays up | stays up |
| Slippery patch | falls | stays up |
| Heavy backpack | stays up, body sags | stays up |
| Weaker motors | stays up, but slower | falls |
Illustrative, not measured
How this was made
Plans ahead: Model-based MPC (iLQR + MuJoCo). Compute per step: re-solves iLQR against the current state at every control step.
Learned by practice: Learned policy (sim RL). Compute per step: one network forward pass, weights fixed at training.
Each surprise in the literature's terms: Sideways shove, lateral push; Slippery patch, low-friction patch; Heavy backpack, +5 kg payload; Weaker motors, torque-limit cut. The traces are an illustrative model of the failure modes the literature reports, not measured hardware data: base-height deviation in centimetres over 40 control steps, with the surprise at step 4. The drawing shows how each response ends: standing for "stays up", on its back for a fall, and sagging or slower for a degraded response.
The model assumes a friction coefficient the patch does not provide. The plan is feasible for the wrong floor, the feet slip, and re-solving against a wrong model cannot recover.
Friction was randomized over a wide band at training time, so the patch is in-distribution. The policy absorbs it without ever knowing the coefficient.
The robot that plans ahead runs MPC and the robot that learned by practice runs an RL policy: after a low-friction patch at step 4 the MPC base-height deviation peaks at 24.00 cm and ends at 24.00 cm while the RL policy peaks at 5.50 cm and ends at 0.07 cm; MPC compute per step re-solves iLQR against the current state at every control step, the RL policy is one network forward pass, weights fixed at training, and both traces are an illustrative teaching model rather than measured hardware data.
Sampled base-height deviation for both controllers
| step | MPC (cm) | RL (cm) |
|---|---|---|
| 0 | 0.00 | 0.00 |
| 4 | 0.00 | 5.50 |
| 10 | 6.90 | -1.18 |
| 20 | 18.40 | 0.54 |
| 30 | 24.00 | -0.22 |
| 39 | 24.00 | 0.07 |
Where the debate landed
Hybrids now combine the two: MPC-guided policy search used MPC with full state to generate training data for a simulated quadrotor's network, which runs at a fraction of MPC's costSource 29. DTC trains an RL policy to track footholds from a model-based planner and reports more robustness than model-based counterparts on slippery or deformable groundSource 30, and a policy trained entirely in a differentiable simulator transferred zero-shot to a real quadrupedSource 31.
See also
- Sim-to-Real Transfer
Domain randomization, distillation, system identification and real-to-sim reconstruction.
- Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
Linked from
- RL for Robotics
Sample efficiency decides which RL algorithm a robot can use.
- Generative Simulation
Generated tasks, scenes and assets inside a physics engine.
- Model-Based Robot Learning
Learn dynamics, plan through them, and improve from imagined rollouts.
- Motion Planning
Configuration space, RRT and its variants, and trajectory optimization.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
References
Nikita Rudin, David Hoeller, Philipp Reist, Marco Hutter, CoRL 2021.
https://arxiv.org/abs/2109.11978
Nikita Rudin, 2021.
https://github.com/leggedrobotics/legged_gym
NVIDIA, Mayank Mittal, Yunrong Guo, Pascal Roth, David Hoeller, James Tigue, and 100 more, 2025.
https://arxiv.org/abs/2511.04831
OpenAI, Ilge Akkaya, Marcin Andrychowicz, Maciek Chociej, Mateusz Litwin, Bob McGrew, and 13 more, 2019.
https://arxiv.org/abs/1910.07113
Yecheng Jason Ma, William Liang, Guanzhi Wang, De-An Huang, Osbert Bastani, Dinesh Jayaraman, and 3 more, ICLR 2024.
https://arxiv.org/abs/2310.12931
Yunho Kim, Hyunsik Oh, Jeonghyun Lee, Jinhyeok Choi, Gwanghyeon Ji, Moonkyu Jung, and 2 more, IEEE Transactions on Robotics 2024.
https://arxiv.org/abs/2308.12517
Arthicha Srisuchinnawong, Poramate Manoonpong, RSS 2025.
https://arxiv.org/abs/2510.10759
Dohyeong Kim, Hyeokjin Kwon, Junseok Kim, Gunmin Lee, Songhwai Oh, 2024.
https://arxiv.org/abs/2409.15755
John Z. Zhang, Taylor A. Howell, Zeji Yi, Chaoyi Pan, Guanya Shi, Guannan Qu, and 3 more, ICRA 2026.
https://arxiv.org/abs/2503.04613
Joonho Lee, Jemin Hwangbo, Lorenz Wellhausen, Vladlen Koltun, Marco Hutter, Science Robotics 5(47), 2020.
https://arxiv.org/abs/2010.11251
Boston Dynamics, 2024.
https://bostondynamics.com/blog/starting-on-the-right-foot-with-reinforcement-learning/
Eric Cousineau, Scott Kuindersma, Lucas Manuelli, Pat Marion, 2025.
https://bostondynamics.com/blog/large-behavior-models-atlas-find-new-footing/
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Johnny Nuñez Cano, Mitesh Patel, Asier Arranz, lior ben horin, Raymond Lo, Rishabh Chadha, 2026.
https://huggingface.co/blog/nvidia/state-of-simulation-for-physical-ai
Philipp Reist, Miguel Zamora Mora, JC Chang, Rishabh Chadha, Mohammad Mohajerani, 2026.
https://developer.nvidia.com/blog/newton-adds-contact-rich-manipulation-and-locomotion-capabilities-for-industrial-robotics
Gabriel B. Margolis, Pulkit Agrawal, Conference on Robot Learning (CoRL) 2022.
https://arxiv.org/abs/2212.03238
Qiayuan Liao, Takara E. Truong, Xiaoyu Huang, Yuman Gao, Guy Tevet, Koushil Sreenath, and 1 more, 2025.
https://arxiv.org/abs/2508.08241
Victoria Krakovna, Jonathan Uesato, Vladimir Mikulik, Matthew Rahtz, Tom Everitt, Ramana Kumar, and 3 more, Google DeepMind blog, 2020.
https://deepmind.google/blog/specification-gaming-the-flip-side-of-ai-ingenuity/
Yecheng Jason Ma, William Liang, Hung-Ju Wang, Sam Wang, Yuke Zhu, Linxi Fan, and 2 more, RSS 2024.
https://arxiv.org/abs/2406.01967
Andrew Y. Ng, Daishi Harada, Stuart Russell, ICML 1999.
https://people.eecs.berkeley.edu/~russell/papers/icml99-shaping.pdf
Gabriel B. Margolis, Ge Yang, Kartik Paigwar, Tao Chen, Pulkit Agrawal, Robotics: Science and Systems (RSS) 2022.
https://arxiv.org/abs/2205.02824
Jared Di Carlo, Patrick M. Wensing, Benjamin Katz, Gerardo Bledt, Sangbae Kim, IEEE/RSJ IROS, 2018.
https://doi.org/10.1109/IROS.2018.8594448
Haoru Xue, Chaoyi Pan, Zeji Yi, Guannan Qu, Guanya Shi, arXiv preprint (ICRA 2025), 2024.
https://arxiv.org/abs/2409.15610
AJ Miller, Fangzhou Yu, Michael Brauckmann, Farbod Farshidian, arXiv preprint, 2025.
https://arxiv.org/abs/2504.17857
Yunlong Song, Angel Romero, Matthias Mueller, Vladlen Koltun, Davide Scaramuzza, Science Robotics 2023, adg1462.
https://arxiv.org/abs/2310.10943
Ruben Grandia, Fabian Jenelten, Shaohui Yang, Farbod Farshidian, Marco Hutter, 2022.
https://arxiv.org/abs/2208.08373
Fabian Schramm, Pierre Fabre, Nicolas Perrin-Gilbert, Justin Carpentier, arXiv preprint (ICRA 2026), 2025.
https://arxiv.org/abs/2511.19204
Magnus Dierking, Joao Carvalho, An Thai Le, Georgia Chalvatzaki, Jan Peters, ICRA 2026 Workshop on Frontiers of Optimization for Robotics.
https://arxiv.org/abs/2606.20712
Tianhao Zhang, Gregory Kahn, Sergey Levine, Pieter Abbeel, 2015.
https://arxiv.org/abs/1509.06791
Fabian Jenelten, Junzhe He, Farbod Farshidian, Marco Hutter, 2023.
https://arxiv.org/abs/2309.15462
Clemens Schwarke, Victor Klemm, Joshua Bagajo, Jean-Pierre Sleiman, Ignat Georgiev, Jesus Tordesillas, and 1 more, arXiv preprint (CoRL 2025), 2024.
https://arxiv.org/abs/2404.02887
Juri Pfammatter, Kaixian Qu, Clemens Schwarke, Victor Klemm, Marco Hutter, 2026.
https://arxiv.org/abs/2610.03395
Jean-Pierre Sleiman, Farbod Farshidian, Maria Vittoria Minniti, Marco Hutter, IEEE Robotics and Automation Letters, 2021.
https://arxiv.org/abs/2103.00946
Octi Zhang, Mateo Guaman Castro, Patrick Yin, Ignacio Dagnino, Abhishek Gupta, Rosario Scalise, and 1 more, CoRL 2026.
https://arxiv.org/abs/2610.12465
Further reading
Hojoon Lee, Ajay Subramanian, Ben Abbatematteo, Vijay Veerabadran, Pedro Matias, Karl Ridgeway, and 1 more, RLC 2026.
https://arxiv.org/abs/2606.01672
Takahiro Miki, Joonho Lee, Jemin Hwangbo, Lorenz Wellhausen, Vladlen Koltun, Marco Hutter, Science Robotics 7(62), 2022.
https://arxiv.org/abs/2201.08117
Nolan Fey, Gabriel B. Margolis, Martin Peticco, Pulkit Agrawal, 2025.
https://arxiv.org/abs/2502.10894
Xiyue Chen, Muhan Lin, Shuyang Shi, Joseph Campbell, 2026.
https://arxiv.org/abs/2606.25398
William Liang, Sam Wang, Hung-Ju Wang, Osbert Bastani, Dinesh Jayaraman, Yecheng Jason Ma, Conference on Robot Learning (CoRL) 2024.
https://arxiv.org/abs/2411.01775
Juan Alvarez-Padilla, John Z. Zhang, Sofia Kwok, John M. Dolan, Zachary Manchester, 2024.
https://arxiv.org/abs/2409.10469
Alberto Rodriguez, Shane Rozen-Levy, Vinay Kamidi, Boston Dynamics blog, 2026.
https://bostondynamics.com/blog/training-a-humanoid-robot-for-hard-work/
Robotics and AI Institute, RAI Institute blog, 2026.
https://rai-inst.com/resources/blog/iros-2026-publication-round-up/
Jean Pierre Sleiman, He Li, Alphonsus Adu-Bredu, Robin Deits, Arun Kumar, Kevin Bergamin, and 22 more, 2026.
https://arxiv.org/abs/2602.00401
Spot a factual error or missing qualification? Report a content correction.