Motion Planning
Configuration space, RRT and its variants, and trajectory optimization.
Motion planning computes a collision-free route from a robot's current configuration to a goalSource 9, a sequence of the joint angles that kinematics maps to poses. Sampling-based planners explore configurations and the connections between them; trajectory optimizers improve a complete candidate trajectory against an objectiveSource 7 Source 8.
Drag the slider to step through the search, or press "Grow the tree" to replay it.
Rapidly-exploring random tree (RRT)
Random branches feel their way around obstacles to the goal
Adjust more
iteration 288 / 288nodes 289goal reached at iteration 288path length 124.2 units
Thin lines: the treeLit: the first branch to reach the goal288 branches · path found
Illustrative: one run on a made-up map
How this was made
Authored fixed-seed scene. Each sampling attempt selects the goal with probability 1.5% and otherwise samples uniformly; steps are capped at 2 world units. Each accepted step grows from the tree node nearest a random sample, so the tree spreads into open space. Every iteration adds one node; with this seed a branch first reaches the goal at iteration 288, and the path it gives measures 124.2 units.
The RRT tree is at iteration 288 of 288 with 289 nodes and status goal reached at iteration 288; the highlighted start-to-goal path measures 124.2 units after a branch first reached the goal at iteration 288.
Current RRT tree state
- iteration
- 288 / 288
- nodes
- 289
- status
- goal reached at iteration 288
- path length
- 124.2 units
1998
RRT introduced
Iowa State TR 98-11; date in LaValle's bibliography
2009
CHOMP
covariant gradient refinement
2011
RRT* analysis
Karaman and Frazzoli; conditional theorem
2D
demo scene below
100 by 64 world, 5 obstacles
Configuration space
Lozano-Pérez's 1983 reformulation moves planning from the workspace into configuration space. A configuration is one complete posture, the vector of joint values. The set of all of them is 2D for a point robot in the plane and 7-dimensional for a 7-DoF armSource 1.
The configuration-space obstacle holds every configuration where the robot intersects an obstacle; the rest is free spaceSource 1:
Shrinking the robot to a point and growing each obstacle by its shape reduces collision checking to point membership. Planning becomes the search for a continuous curve in from to Source 1.
Explicit boundary or solid models of are difficult to build, though semi-algebraic models for chains and trees can be generated automatically. The basic semi-algebraic mover problem is PSPACE-hard when the number of degrees of freedom is unboundedSource 9. Hardness holds for a planar linkage with multiple links and for a multi-arm robot among 3D polyhedra; Canny's roadmap method is singly exponentialSource 11.
Sampling-based methods skip building by querying a collision checker and validating whole local paths, though closed-chain constraints make sampling difficultSource 9.
Sampling-based planning
The probabilistic roadmap (PRM) of Kavraki, Svestka, Latombe, and Overmars samples configurations uniformly, keeps the collision-free ones as nodes and adds extra nodes where a heuristic marks the space as difficult. A local planner links nearby nodes, and queries become graph searches, so one roadmap serves many start-goal pairsSource 2.
LaValle introduced the rapidly-exploring random tree in Iowa State Computer Science Technical Report 98-11, October 1998Source 3 Source 9. Each iteration samples a state, finds the nearest vertex under a chosen metric, picks a control input and integrates over a fixed time interval, keeping vertices and edge paths in free space. For dynamics , the Euler step isSource 3
with starting state and input ; the report recommends a higher-order integrator such as Runge-KuttaSource 3. LaValle's 2006 book drops the step size: each sample connects to the nearest point on the tree's swath, the union of its edge paths, splitting an edge when neededSource 9.
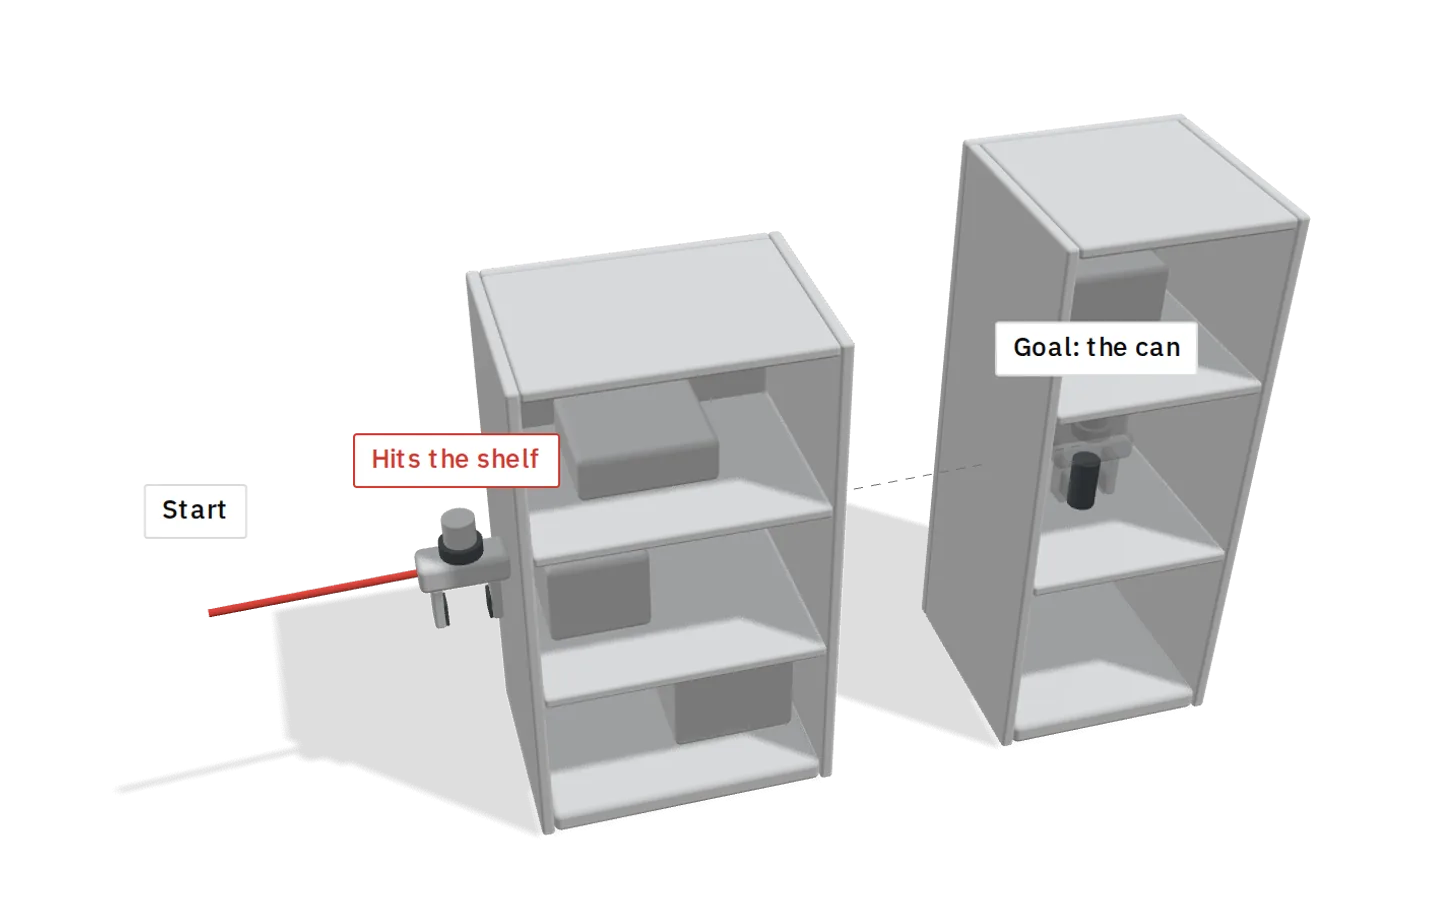
Nearest-neighbor selection gives RRT a Voronoi bias, because frontier vertices own larger Voronoi regions. The report leaves convergence rates openSource 3. LaValle and Kuffner's kinodynamic version steers with controls instead of straight linesSource 4. Drag the shelf in the figure below and the tree of random safe steps regrows around it to the goal.
How does a robot get around obstacles?
Loading…
A robot's gripper must reach the can on the far shelf. Going straight there, it hits the shelf in between.
A robot rarely knows the way around an obstacle in advance, but random safe steps grown into a tree find one.
How this was made
The steps in words
- A robot's gripper must reach the can on the far shelf. Going straight there, it hits the shelf in between.
- Pick a random point. Step a short way toward it from the closest spot already reached. Keep the step only if it hits nothing.
- Repeat thousands of times. The kept steps branch out into a tree that creeps into every open gap.
- When a branch reaches the goal, follow it back to the start. Then cut every corner where a straight shortcut is safe.
- Drag the shelf: the tree regrows. A fast version of this rapidly-exploring random tree plans a typical arm path in 40 millionths of a second.
Kuffner and LaValle's RRT-Connect grows two trees, rooted at the start and the goalSource 12. In the six manipulation problems of a 2023 comparison, it had the best overall success rateSource 13.
Probabilistic completeness means the chance of finding an existing solution approaches one as sampling continues, with no finite-budget guaranteeSource 9. Karaman and Frazzoli prove it for simplified PRM (sPRM) and geometric RRT on , , assuming a solution with clearance , uniform independent samples, a fixed sPRM radius, capped RRT steering and straight-line collision tests. A 1-nearest-neighbor sPRM is not probabilistically completeSource 5.
OMPL 2.0.0, released April 6, 2026, added VAMP as a SIMD backend for planning speeds up to 25 kHzSource 15; VAMP's authors report gains of more than 500x from fine-grained parallelism on 7 to 14 DoF robotsSource 14. The library implements PRM and RRT, includes benchmarking tools and plugs into external collision checkers and visualizersSource 10.
Optimality: RRT*
Karaman and Frazzoli's 2011 analysis separates feasibility from cost. In an obstacle-free Euclidean example with steering distance at least the domain diameter, RRT's best cost converges almost surely to a suboptimal value. Their PRM result concerns a forest-building version that rejects connections inside a connected component. Fixed-radius sPRM, which allows them, is asymptotically optimal at greater computational costSource 5.
RRT* adds least-cost parent selection and rewiring. A new vertex takes the cheapest collision-free parent among nearby vertices, and neighbors reattach to it only when that lowers their cost. With vertices, the connection radius isSource 5
where caps the steering distance and is the dimension. Of the paper's two sufficient bounds on , the conservative one is , with free-space volume and unit-ball volume Source 5.
The result assumes a bounded Euclidean domain, uniform independent samples and straight-line connections, which excludes differential constraints. Cost must be positive, monotone under concatenation and at most a constant times path length. The optimum must have weak clearance, deforming continuously into paths with positive clearance, with cost continuous near it in a bounded-variation normSource 5:
Here is the best cost after iterations, so a finite budget can return a suboptimal path. The non-optimality analysis assumes that optimal paths traverse a set of states of measure zero. Expected processing work is of order , within a constant factor of RRT, though RRT* makes collision checks per iteration to RRT's oneSource 5.
After a first solution, Informed RRT* skips routes irrelevant to the query by sampling only the domain's intersection withSource 6
This prolate hyperspheroid has the start and goal as foci and the best path length as transverse diameter. It contains every state on a strictly improving path, but its states need not be collision-free, so collision checks remain. Over 100 runs per variation with 60 seconds of refinement, it refined faster than RRT*, and it gains nothing once the set covers the domainSource 6.
Trajectory optimization
Trajectory optimization makes the trajectory the decision variable, with smoothness, clearance and task terms in the objective or constraints. Neither the objective nor an initial guess guarantees a collision-free result. CHOMP and TrajOpt both plan from infeasible guesses as well as refine existing trajectoriesSource 7 Source 8. Graphs of Convex Sets (GCS) poses planning as a mixed-integer program with a very tight convex relaxation, so in most cases a cheap rounding suffices for globally optimal trajectoriesSource 16.
CHOMP: covariant gradient descent
CHOMP combines an obstacle cost with an environment-independent prior on trajectory dynamics. In the discrete form, holds the interior waypoints, computes finite differences and accounts for the fixed endpointsSource 7:
The first-derivative term penalizes squared velocity; higher-order terms penalize other dynamics. The obstacle cost integrates a signed-distance penalty over the robot's body, weighted by arc length so that moving faster through a costly region cannot lower it. Covariant descent uses the inverse smoothness metric to spread each gradient step smoothly along the trajectorySource 7.
On the first six joints of a seven-DoF Barrett WAM, CHOMP solved 99 of 105 problems from 15 endpoint configurations. On LittleDog it ran inside a footstep controller with a separate footstep planner and a ZMP preview controller seeding the trunk. Trajectories were computed before execution because worst-case optimization took about 1.5 times as long as executionSource 7.
The paper also tests a Hamiltonian Monte Carlo variant and records finite-time local-minimum failuresSource 7; the 2013 journal CHOMP uses Hamiltonian Monte Carlo against high-cost local minima and for probabilistic completeness, and respects hard trajectory constraintsSource 17.
TrajOpt: penalties, trust regions, and collision limits
TrajOpt solves a sequence of convex subproblems, with a kinematic objective summing squared displacements between successive waypoints. Nonlinear constraints enter an penalty whose coefficients grow in an outer loop as needed; linear constraints are imposed directly. With signed distance positive for separated objects, the collision penalty isSource 8
It is nonzero inside the safety margin. Pairs out to enter the linearized subproblem, including some with zero current penalty. A box trust region bounds each step, expanding when actual improvement matches the local model and shrinking otherwiseSource 8.
Waypoint checks can miss collisions between waypoints, so TrajOpt penalizes a swept volume: the convex hull of endpoint shapes, inflated for rotation. The rotation bound adds to the safety margin, a correction omitted in experiments because it was well under 1 cm. The swept-volume gradient is not guaranteed accurate in 3D, and the implementation used Bullet with convex hulls of robot meshes and penalized self-collisions only at discrete timesSource 8.
What the TrajOpt benchmark measured
The 2013 benchmark used four simulated MoveIt scenes with fixed endpoints: 198 seven-DoF PR2 arm problems with 11 timesteps and 96 eighteen-DoF full-body problems with 41. OMPL ran with default parameters and MoveIt's default smoother, and path length was normalized by the shortest path any planner found. Both tables give historical 2013 timingsSource 8.
| Arm method | Success fraction | Average time (s) | Average normalized length |
|---|---|---|---|
| TrajOpt | 0.84 | 0.20 | 1.2 |
| TrajOpt, multiple initializations | 0.99 | 0.32 | 1.2 |
| OMPL RRTConnect | 0.97 | 1.2 | 1.6 |
| OMPL LBKPIECE | 0.96 | 3.1 | 1.7 |
| CHOMP | 0.66 | 3.1 | 2.4 |
| CHOMP, multiple initializations | 0.85 | 6.0 | 2.6 |
On the arm, single-initialization TrajOpt solved fewer problems than either OMPL planner and multi-initialization TrajOpt the most. The tested CHOMP implementation came from its authorsSource 8.
| Full-body method | Success fraction | Average time (s) | Average normalized length |
|---|---|---|---|
| TrajOpt | 0.63 | 2.1 | 1.08 |
| TrajOpt, multiple initializations | 0.84 | 7.6 | 1.09 |
| OMPL RRTConnect | 0.53 | 18.0 | 1.5 |
| OMPL LBKPIECE | 0.50 | 18.7 | 1.5 |
The full-body comparison omits CHOMP, for which the authors lacked documentation or data. The introduction gives every planner ten seconds, while the experiments specify three seconds per CHOMP initialization and thirty seconds for full-body OMPLSource 8.
cuRobo runs many parallel optimizer seeds on GPUs and solves difficult motion generation problems within 50 ms on average, 60x faster than state-of-the-art trajectory optimizationSource 18.
Initial guesses and the two-stage pattern
CHOMP and TrajOpt both need an initial trajectory and can stall in bad local minima. In CHOMP's tests, straight-line seeds often beat RRT seeds on the objective where collision removal succeeded; in TrajOpt's, multiple initializations changed success ratesSource 7 Source 8.
Ratliff and colleagues describe PRM and RRT as commonly deployed in two phases: find a feasible path, then remove redundant or jerky motionSource 7. Shortcutting, a cheap second stage, repeatedly picks two trajectory points and tries to replace the segment between them with a shorter collision-free oneSource 19.
Where this meets the learned stack
Motion Policy Networks trained on over 3 million motion planning problems in over 500,000 environmentsSource 23. A 2026 survey finds that neural motion planners often struggle to generalize to unseen, out-of-distribution planning settingsSource 30.
Deep Reactive Policy replaced AIT* with cuRobo as its expert planner because GPU acceleration let it scale to 10 million expert trajectories. Its authors report that AIT* achieved 0% success on all dynamic tasks, and cuRobo fell to 3.00% when the goal was temporarily obstructedSource 24.
Ariadne, from Carnegie Mellon's Silong Yong, Guanya Shi and colleagues (October 2026, accepted at NeurIPS 2026), trains only on valid states, with no trajectories, and builds a path by following the geometry of the learned state manifold. On DualKUKA, where two 7-DoF arms must avoid obstacles and each other, it averaged 53.3% success across three environments, against 44.7% for RRT, 31.7% for a trajectory-trained Diffuser and 53.2% for PBDMP, which also receives the scene layout. Ariadne learns one planner per sceneSource 31.
Receding-horizon model-predictive control keeps optimization inside the feedback loopSource 25; reward design and the MPC debate weighs it against learned policies. Diffusion Policy represents a visuomotor policy as a conditional denoising diffusion process run with receding-horizon controlSource 26. Control and state estimation track the resulting trajectories and locate the robot.
The runtime handoff contract
A deployable planner needs the robot model, current state, collision geometry, allowed contacts, attached objects, joint and timing limits and a controller that can execute the result, and a path checked against a stale scene is unsafe. Time-Optimal Trajectory Generation (TOTG) computes the time-optimal trajectory that exactly follows a differentiable joint-space path within velocity and acceleration boundsSource 27, and MoveIt 2 has recommended it for time parameterization since January 2023Source 20. Because TOTG sets no jerk limits, Ruckig, a real-time jerk-limited generatorSource 28, can smooth its outputSource 21.
The cuRoboV2 authors note that fast planners output physically unexecutable trajectories, and report 99.7% success under a 3 kg payload against 72 to 77% for baselinesSource 29.
The ROS 2 guide maps these artifacts onto the runtime graph. In hybrid systems a learned component proposes a goal, cost, waypoint or action chunk, and a planner or command gate checks what the model cannot certify. Validators fail too: MoveIt Pro 10.1.0 fixed a shortcut stage that let paths pass through obstacles between collision checks, and a ValidateTrajectory bug that checked the wrong robot configuration and risked passing a colliding trajectory as collision-freeSource 22.
See also
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
- Industrial Deployment
The jam-rate arithmetic that decides whether a 99 percent cell ships.
- Humanoid Whole-Body Control
How humanoids track retargeted human motion.
Linked from
- Hierarchical Approaches
From SayCan and Code as Policies to the hierarchies in Helix and pi0.5.
- Reward Design and the MPC Debate
Hand-tuned and language-model rewards, and the MPC debate.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
- State Estimation
Kalman filters, factor graphs, and pose estimation from noisy sensors.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
- Scene Representation and Mapping
From point clouds to Gaussian splats: what a robot remembers about space.
- Autonomous Vehicles
Driving as a robotics problem, down to the long tail.
References
Tomás Lozano-Pérez, IEEE Trans. Computers, 1983.
https://doi.org/10.1109/TC.1983.1676196
Lydia E. Kavraki, P. Švestka, J.-C. Latombe, M. H. Overmars, IEEE Trans. Robotics and Automation, 1996.
https://doi.org/10.1109/70.508439
Steven M. LaValle, Iowa State University TR 98-11, 1998.
https://lavalle.pl/papers/Lav98c.pdf
Steven M. LaValle, James J. Kuffner, Int. J. Robotics Research, 2001.
https://lavalle.pl/papers/LavKuf01b.pdf
Sertac Karaman, Emilio Frazzoli, arXiv preprint, 2011.
https://arxiv.org/abs/1105.1186
Jonathan D. Gammell, Siddhartha S. Srinivasa, Timothy D. Barfoot, IROS 2014.
https://arxiv.org/abs/1404.2334
Nathan Ratliff, Matthew Zucker, J. Andrew Bagnell, Siddhartha Srinivasa, ICRA 2009.
https://www.ri.cmu.edu/publications/chomp-gradient-optimization-techniques-for-efficient-motion-planning/
John Schulman, Jonathan Ho, Alex Lee, Ibrahim Awwal, Henry Bradlow, Pieter Abbeel, RSS 2013.
https://www.roboticsproceedings.org/rss09/p31.pdf
Ioan A. Șucan, Mark Moll, Lydia E. Kavraki, IEEE Robotics & Automation Magazine, 2012.
https://doi.org/10.1109/MRA.2012.2205651
Kiril Solovey, arXiv preprint (Encyclopedia of Robotics chapter), 2020.
https://arxiv.org/abs/2003.03632
J. J. Kuffner, S. M. LaValle, ICRA 2000.
https://doi.org/10.1109/ROBOT.2000.844730
Andreas Orthey, Constantinos Chamzas, Lydia E. Kavraki, Annual Review of Control, Robotics, and Autonomous Systems, 2023.
https://arxiv.org/abs/2309.13119
Wil Thomason, Zachary Kingston, Lydia E. Kavraki, arXiv preprint (ICRA 2024), 2023.
https://arxiv.org/abs/2309.14545
Kavraki Lab, OMPL documentation, 2026.
https://ompl.kavrakilab.org/releaseNotes.html
Tobia Marcucci, Mark Petersen, David von Wrangel, Russ Tedrake, arXiv preprint (Science Robotics 2023), 2022.
https://arxiv.org/abs/2205.04422
Matt Zucker, Nathan Ratliff, Anca D. Dragan, Mihail Pivtoraiko, Matthew Klingensmith, Christopher M. Dellin, and 2 more, Int. J. Robotics Research, 2013.
https://doi.org/10.1177/0278364913488805
Balakumar Sundaralingam, Siva Kumar Sastry Hari, Adam Fishman, Caelan Garrett, Karl Van Wyk, Valts Blukis, and 6 more, 2023.
https://arxiv.org/abs/2310.17274
Kris Hauser, Victor Ng-Thow-Hing, ICRA 2010.
https://doi.org/10.1109/ROBOT.2010.5509683
MoveIt Maintainers, MoveIt 2 Documentation, as of 2026-10-04.
https://moveit.picknik.ai/main/doc/concepts/trajectory_processing.html
MoveIt Maintainers, MoveIt 2 Documentation, as of 2026-10-04.
https://moveit.picknik.ai/main/doc/examples/time_parameterization/time_parameterization_tutorial.html
PickNik Robotics, MoveIt Pro documentation, 2026-09-18.
https://docs.picknik.ai/release-notes/2026/09/18/10.1.0
Adam Fishman, Adithyavairan Murali, Clemens Eppner, Bryan Peele, Byron Boots, Dieter Fox, CoRL 2022.
https://arxiv.org/abs/2210.12209
Jiahui Yang, Jason Jingzhou Liu, Yulong Li, Youssef Khaky, Kenneth Shaw, Deepak Pathak, arXiv preprint, 2025.
https://arxiv.org/abs/2509.06953
D. Q. Mayne, James B. Rawlings, Christopher V. Rao, P. O. M. Scokaert, Automatica, 2000.
https://doi.org/10.1016/S0005-1098(99)00214-9
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
Tobias Kunz, Mike Stilman, Robotics: Science and Systems VIII, 2012.
https://doi.org/10.15607/rss.2012.viii.027
Lars Berscheid, Torsten Kröger, RSS 2021.
https://arxiv.org/abs/2105.04830
Balakumar Sundaralingam, Adithyavairavan Murali, Stan Birchfield, arXiv preprint, 2026.
https://arxiv.org/abs/2603.05493
Davood Soleymanzadeh, Ivan Lopez-Sanchez, Hao Su, Yunzhu Li, Xiao Liang, Minghui Zheng, IEEE Transactions on Automation Science and Engineering, 2026.
https://arxiv.org/abs/2603.24318
Silong Yong, Anji Liu, Cunxi Dai, Carl Busart, Guanya Shi, Yilun Du, and 2 more, 2026.
https://arxiv.org/abs/2610.08863
Further reading
Shrutheesh R Iyer, I-Chia Chang, Andrew Z. Liu, Yan Gu, Zachary Kingston, arXiv preprint, 2026.
https://arxiv.org/abs/2604.13323
Thai Duong, Clayton W. Ramsey, Zachary Kingston, Wil Thomason, Lydia E. Kavraki, IEEE Trans. Robotics (accepted), 2026.
https://arxiv.org/abs/2603.16059
Chih H. Huang, Pranav Jadhav, Brian Plancher, Zachary Kingston, arXiv preprint, 2025.
https://arxiv.org/abs/2503.06757
Weihang Guo, Theodoros Tyrovouzis, Emiliano Flores, Clayton W. Ramsey, Zachary K. Kingston, Ioan A. Şucan, and 2 more, arXiv preprint, 2026.
https://arxiv.org/abs/2605.29301
Lucas Janson, Edward Schmerling, Ashley Clark, Marco Pavone, arXiv preprint, 2013.
https://arxiv.org/abs/1306.3532
Jonathan D. Gammell, Timothy D. Barfoot, Siddhartha S. Srinivasa, Int. J. Robotics Research, 2017.
https://arxiv.org/abs/1707.01888
Tyler Wilson, Wil Thomason, Zachary Kingston, Jonathan Gammell, IEEE Robotics and Automation Letters, 2025.
https://arxiv.org/abs/2505.10542
Mrinal Kalakrishnan, Sachin Chitta, Evangelos Theodorou, Peter Pastor, Stefan Schaal, ICRA 2011.
https://doi.org/10.1109/ICRA.2011.5980280
John Schulman, Yan Duan, Jonathan Ho, Alex Lee, Ibrahim Awwal, Henry Bradlow, and 4 more, Int. J. Robotics Research, 2014.
https://doi.org/10.1177/0278364914528132
Luai Abuelsamen, Harsh Rana, Ho-Wei Lu, Wenhan Tang, Swati Priyadarshini, Gabriel Gomes, arXiv preprint, 2025.
https://arxiv.org/abs/2508.04146
Chih H. Huang, Roy Xing, Brian Plancher, Zachary Kingston, arXiv preprint, 2026.
https://arxiv.org/abs/2609.30644
Murtaza Dalal, Jiahui Yang, Russell Mendonca, Youssef Khaky, Ruslan Salakhutdinov, Deepak Pathak, arXiv preprint, 2024.
https://arxiv.org/abs/2409.05864
Spot a factual error or missing qualification? Report a content correction.