Competing Theses
Six bets on how robot intelligence gets built.
The competing theses are the rival bets on how robot intelligence gets built: end-to-end VLA scaling, hierarchy, world models, RL fine-tuning, teleoperation as a bridge, and the humanoid form factor. The bets are expensive: Figure has committed $3.5B of compute to training HelixSource 23, and Physical Intelligence has staked its program, from π0 to π0.7, on scalingSource 10.
6
live theses
each with a kill condition
$3.5B
Figure compute
committed to training Helix
R²=0.9983
scaling fit
EgoScale law, validation loss
0
settled
of the six, as of Oct 2026
The theses can coexist, and π0.7 already combines several
Each card states one thesis, its bet and the result that would prove it wrong. Tap "Just make it bigger", then "Let the robot imagine first", to read the evidence on both sides. The theses can coexist: π0.7 is an end-to-end vision-language-action model that also reasons hierarchically, takes optional subgoal-image prompts from a separate world model initialized from BAGEL, which the paper describes as lightweight, and distills experience from RL-trained π*0.6 specialistsSource 10.
Competing theses
Six competing bets on how robots will get smart
Adjust more
Each bet names the result that would prove it wrong
6 bets. Tap one to read the evidence for and against.
How this was made
The grouping into six theses is Robot Wiki’s editorial reading of the field, not a published taxonomy. Each card’s plain name stands for the technical thesis in the table below; the evidence for and against, with its citations, opens when you tap a card. The table gives the original short “Falsified if” signal and the full falsification criterion.
| Thesis | Proponents | Falsified if | Full criterion |
|---|---|---|---|
| End-to-end VLA scalingJust make it biggerMore data and bigger models produce generalist robot intelligence, the way scaling produced generalist language models. | Physical Intelligence (π0 to π0.7); NVIDIA EgoScale team; Bessemer Venture Partners | 10x more data, no gain | A plateau in real-world success rate despite a 10x increase in training data, with no architectural change. |
| Hierarchical planner over skillsA planner directs simple skillsA vision-language model reasons about goals and decomposes them into subtasks; learned skills or a low-level policy execute the plan. | Google DeepMind (Gemini Robotics ER 2); Figure (Helix 02 S2/S1/S0); NVIDIA (GR00T dual-system) | flat model beats hierarchy | A flat end-to-end model with no high-level inference pass outperforming the best hierarchical system on long-horizon tasks. |
| World-model-based trainingLet the robot imagine firstLearn a model that predicts how the world evolves, then plan in it or train the policy inside it, instead of scaling real-robot data. | NVIDIA (Cosmos 3); Meta (V-JEPA 2) | no gain beyond VLA scaling | World-model training failing to improve real-world contact-rich task performance beyond what VLA scaling alone achieves. |
| RL fine-tuning on imitationCopy first, then practisePretrain on demonstrations, then close the reliability gap with reinforcement learning on the real robot. | Physical Intelligence (π*0.6 Recap); RL-100 team; ENPIRE team (NVIDIA, CMU, UC Berkeley) | specialists stay specialists | RL-finetuned specialists consistently failing to generalize to unseen tasks or environments without another round of per-task training. |
| Teleoperation as a bridgeHumans steer while robots learnDeploy teleoperated or human-supervised robots for real work now, harvest the data, and fade the human out as autonomy improves. | Nucleus (supervised operations); Physical Intelligence (Recap coaching); Bessemer (data flywheel) | >99% with zero teleop data | Autonomous policies reaching better than 99% success trained without any teleoperation data, which removes the bridge's reason to exist. |
| Humanoid versus task-specificHuman-shaped or built for the jobOne side bets a human body is the right interface to a world built for humans; the other bets purpose-built robots win on cost and reliability for any known task. | Humanoid side: Figure, Tesla, 1X, Apptronik, Unitree; Task-specific side: Rodney Brooks (Robust.AI); Between them: Agility Robotics, deploying its Digit humanoid in narrow logistics work | cost-per-task parity test | Task-specific robots consistently beating humanoids on cost per task and reliability in the same applications kills the humanoid side; a humanoid reaching cost-per-task parity with purpose-built systems across a broad task range kills the task-specific side. |
Scaling has early laws, such as EgoScale's log-linear fit to validation loss
The claim: keep the architecture general, scale data and parameters, and generalist robot intelligence follows, as it did for language. Rich Sutton's 2019 essay The Bitter Lesson frames it: general methods that leverage computation win in the long runSource 2. Brooks answered six days later, in a reply that paraphrases Sutton and describes itself, including its closing comment, as "seventy six words shorter than Sutton's post"Source 1. Bessemer's investor analysis argues that "scaling laws are emerging" and that capital is the moatSource 7 (VLA models).
EgoScale fit a log-linear scaling law (R² = 0.9983) from human-video pretraining hours to validation loss, which it reports correlates strongly with downstream robot performanceSource 8. Its full recipe lifts average success by 54% over a no-pretraining baseline on a 22-DoF handSource 8. Figure reports a human-to-humanoid transfer law on robot-action prediction, with Index pretraining lifting zero-shot success in 30 unseen homes from 9% to 56%Source 23. Lin et al. found single-task success following "a roughly power-law relationship with the number of environments and objects"Source 24. In entirely new homes, π0.5 cleaned kitchens and bedroomsSource 9.
Brooks and Goldberg cite engineered priors and a 100,000-year data gap
Brooks answered Sutton directly: image-labeling systems use a human-designed convolutional front end for translational invarianceSource 1. His 2025 essay extends the point to speech preprocessing rooted in telephone engineering, listing FFTs and Mel filter banks while noting that implementations use different selections. He also acknowledges that leaving as much as possible to learning was critical to the gains in speech and image tasks. Vision-only training, he adds, gives a robot no force channel (dexterity)Source 4.
On compute, Brooks notes that "self driving cars require about 2,500 Watts of power for computation", while "a human brain only requires 20 Watts"Source 1 (autonomous vehicles).
Ken Goldberg puts the data problem at a 100,000-year gap and argues good old-fashioned engineering can bootstrap robots into collecting the dataSource 5. Karcini and co-authors argue policy scaling misses the interfaces that turn physical data into supervisionSource 6. The kill condition is a plateau in real-world success despite 10x more data with no architectural change; the laws so far govern a proxy loss or a single task (generalization).
Hierarchical systems run long tasks, while single networks blur the line
The claim: a vision-language model decomposes goals into subtasks, and learned skills or a low-level policy execute them. SayCan (2022) had a separate LLM dispatch a fixed skill librarySource 18; today the hierarchy sits inside the network or in a paired fast system (hierarchical approaches). In Figure's Helix 02, S2 sequences behaviors from scenes and language, S1 converts perception into full-body joint targets at 200 Hz, and S0 executes at 1 kHz as the whole-body controllerSource 17. Google DeepMind's Gemini Robotics ER 2 plans multi-step tasks for a lower-level VLASource 15.
Hierarchical control
Helix 02's controller takes five steps for every joint target
7 milliseconds
Lit: the joint-target hand, which moves once every five control steps7 milliseconds · 7 control steps · 1 new joint target
Schematic: Figure's two rates on one clockwork, run 450 times slower
How this was made
Figure describes Helix 02 as three learned layers. S2 interprets the scene and the instruction and sequences behaviours; S1 turns what the robot senses into full-body joint targets at 200 Hz; S0, the whole-body controller, runs at 1 kHz. A joint target therefore lasts 5 milliseconds, and in that time the controller acts 5 times. Figure gives no rate for S2, so it is not drawn.
The drawing is a clock movement doing the same counting. The balance and the pallet fork let the escape wheel advance one tooth per control step, and its hand moves one division of the outer ring. Four pins on the escape wheel's arbor trip a lever once every fifth tooth, and the lever's pawl jumps the four-point star wheel by one point: its hand, the lit one, moves to the next of its four marks, a new joint target. The mainspring barrel and the third wheel power the train.
Schematic: only the two rates come from Figure. The clockwork, the 20 milliseconds shown and the alignment of the two clocks (each target landing on a control step) are illustrative, and the clock runs 450 times slower than real time so each tick can be seen. Figure does not say what S0 does with each target between updates; the figure shows only how often each layer acts.
Rates from Figure's Helix 02 announcement (January 2026).
The evidence for is long-horizon behavior: Figure reports that Helix 02 completed a continuous four-minute dishwasher unloading-and-reloading task without resets or human intervention, in 61 loco-manipulation actionsSource 17. Against it, π0.7's compositional generalization emerges from one networkSource 10, and Gemini Robotics 1.5 already "interleaves actions with a multi-level internal reasoning process" inside one VLASource 25. SayCan's authors found their system bounded by "the range and capabilities of the underlying skills"Source 18. The thesis dies if a flat model with no high-level inference pass outperforms the best hierarchical system on long-horizon tasks.
World models plan from under 62 hours of robot video but still miss contact
The claim is that a learned model of how the world evolves can replace most real-robot data: plan in it, or train the policy inside it. NVIDIA's Cosmos 3 and Meta's V-JEPA 2 are the largest such bets (what is a world model?). V-JEPA 2 plans zero-shot reaching, grasping and pick-and-place on Franka arms in unseen labs after post-training on less than 62 hours of unlabeled robot videoSource 19. DreamZero, a world action model that is itself the policy, reports over 2x better generalization to new tasks and environments than state-of-the-art VLAsSource 26 (generative video).
Cosmos 3 was pretrained on up to 31 trillion tokens, on clusters as large as 2,048 GB200 GPUsSource 20, and no world model yet predicts contact physics well enough for manipulation, where a one-millimeter error flips stick to slip. Karcini and co-authors argue world models alone cannot solve the supervision problemSource 6. It dies if world-model training fails to beat VLA scaling alone on real-world contact-rich tasks.
RL fine-tuning reaches 90% to 100% per task, but each result is a specialist
The claim: pretrain on demonstrations, then close the reliability gap with RL on the real robot. HIL-SERL reached near-perfect success in 1 to 2.5 hours of trainingSource 27, and π*0.6 with Recap more than doubled throughput and reached the 90%+ range on all tasks except diverse laundrySource 12. RL-100 reports 100% success across 1,000 evaluation episodes on eight tasksSource 13. ENPIRE hands the improvement loop to coding agents, reaching 99% on dexterous tasks such as pin-box organizingSource 14 (RL fine-tuning).
The evidence against concerns transfer: each result is per-task, and neither paper claims transfer to unseen tasksSource 12 Source 13. Physical Intelligence reports that one π0.7 model matches the RL-trained specialists on the evaluated laundry-folding, espresso-making, and box-building tasks, sometimes exceeding their throughput, after distilling Recap experience with strategy metadata. The paper measures throughput as successful episodes per hour; inference speed is a separate measureSource 10 Source 11. The recipe becomes a niche tool if RL specialists keep failing to generalize without per-task retraining.
Teleoperation feeds deployment data, but its share of vendor hours is unreported
The claim: deploy teleoperated or human-supervised robots for real work now, harvest the data, and fade the human out as autonomy improves. Nucleus deploys humanoids under human supervision on this logicSource 3, and 1X lets NEO owners schedule an expert for chores it does not know, "helping NEO learn"Source 28.
Recap, the π*0.6 method, learns from expert teleoperated interventionsSource 12, while Sergey Levine argues that surrogates for real robot data usually end up "a lousy spoon with holes or an ineffective blunt fork"Source 29. Bessemer quotes Voxel51's Brian Moore and Foxglove's Adrian Macneil on a data flywheel: "better decisions, better model improvements, and better deployments faster than everyone else." Bessemer lists both companies in its portfolioSource 7.
Agility reports 65,000 hours of Digit production experience on an undated homepageSource 21, and Figure reports 1,250+ runtime hours at BMW SpartanburgSource 22; neither quantifies teleoperation's share of those hours (teleoperation rigs). Bessemer quotes the Zeromatter CEO, Ian Glow: "you'll never get the scale or diversity you need from teleop alone." He recommends internet data or simulators with reinforcement learning, and Bessemer cautions that world models are expensive and sim-to-real manipulation remains an open research problemSource 7.
Egocentric human video is a cheaper source with a measured scaling lawSource 8. Generalist reports that its base models are "trained without any robot data" and reach 99% average success with "only 1 hour of robot data" per taskSource 30. The bridge dies if autonomous policies pass 99% success trained without any teleoperation data.
Cost per task decides between humanoid and task-specific robots
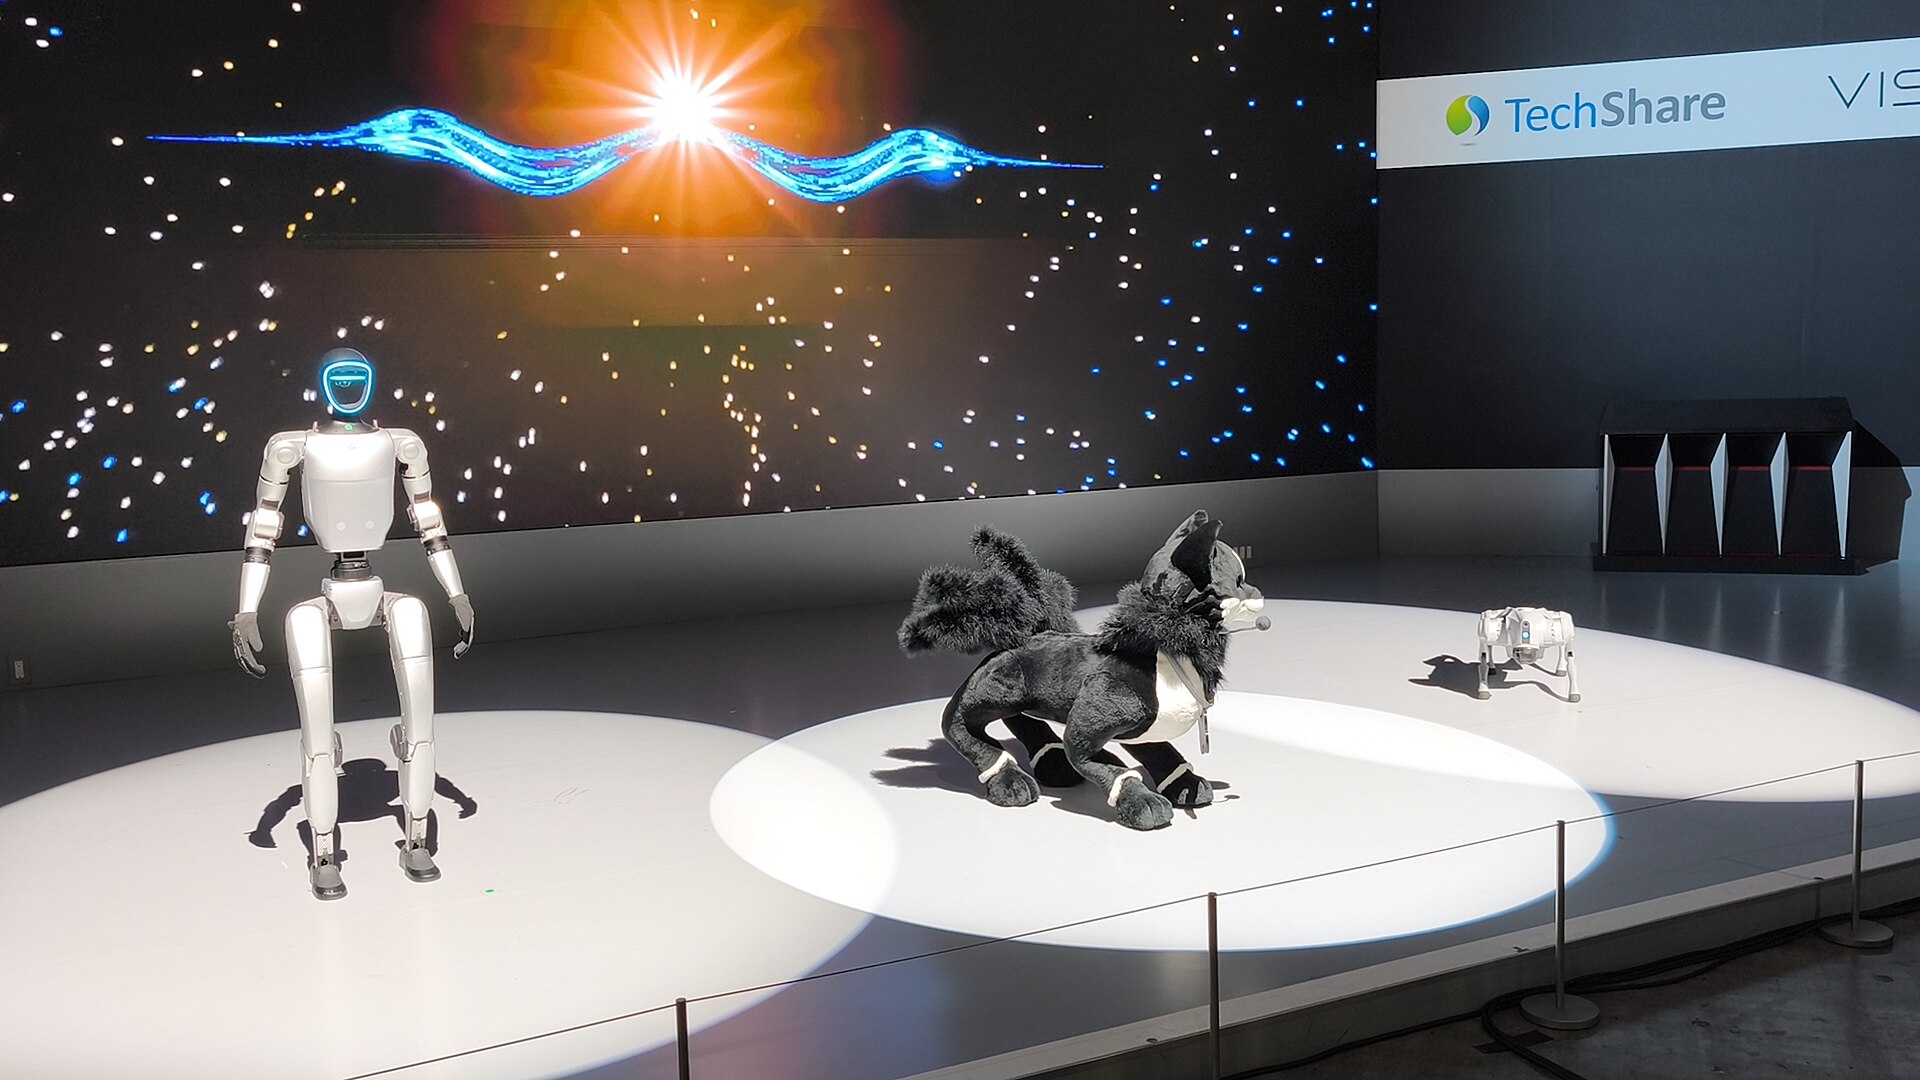
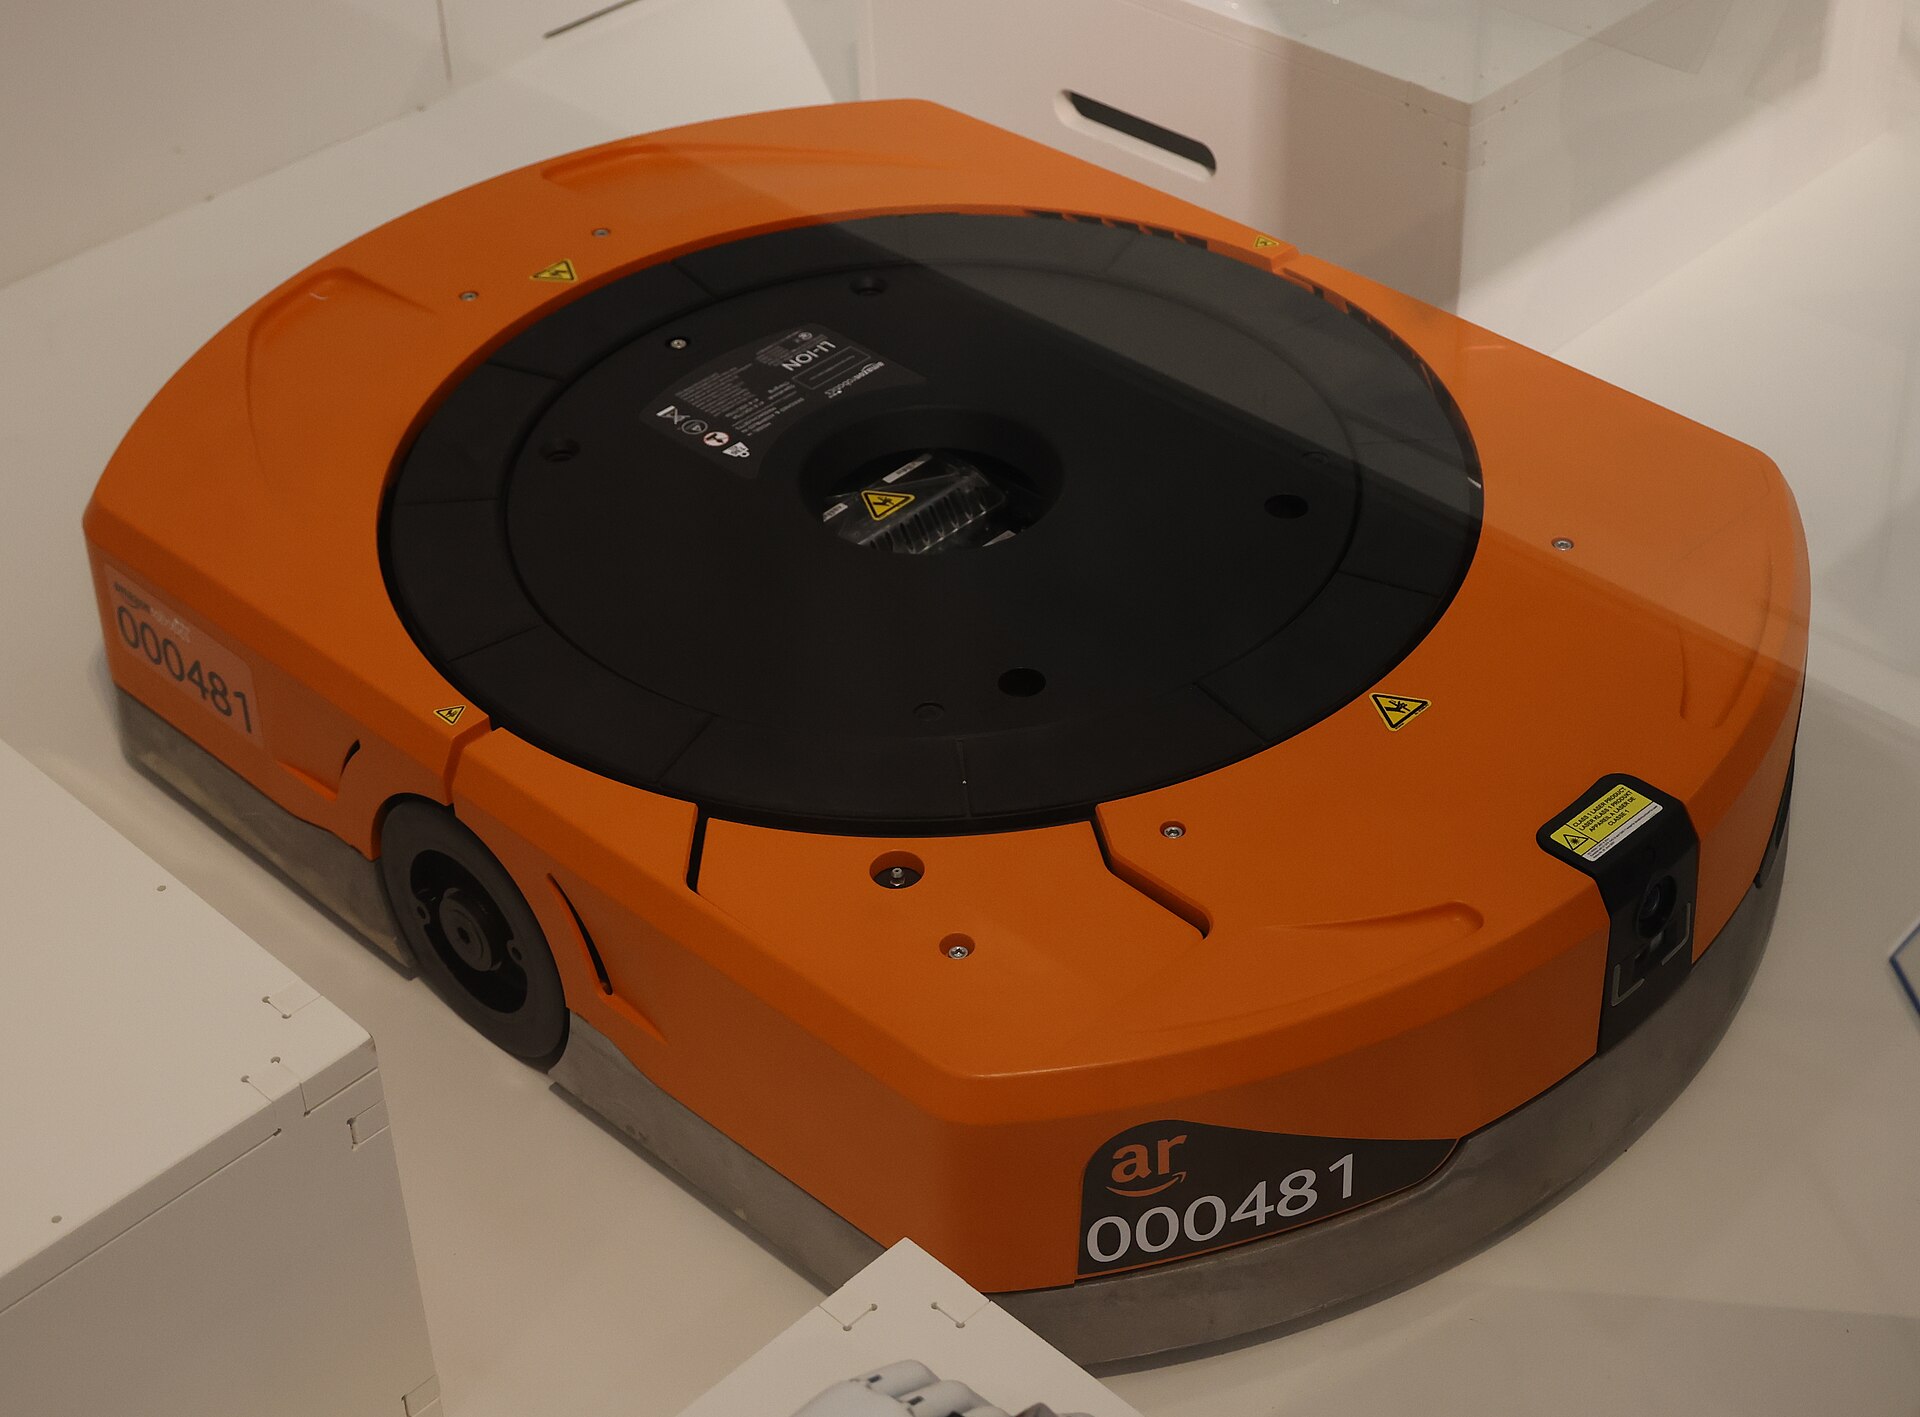
The humanoid side, backed by Figure, Tesla, 1X, Apptronik, and Unitree, bets that a human body is the right interface to a world built for humans. The task-specific side, argued by Rodney Brooks, who describes his company's warehouse robots and his work at Robust.AISource 4, bets that purpose-built systems win on cost and reliability for any task named in advance. Amazon has deployed its millionth robotSource 31, and Agility sits between the sides, deploying its Digit humanoid in narrow logistics workSource 21.
Helix 02 runs whole-body loco-manipulationSource 17, and Gemini Robotics 2 controls full humanoids from feet to fingertips with a single modelSource 16. Brooks calls plug-compatible humanoids replacing people in manual jobs at lower prices and just as well "pure fantasy thinking" within decades. He argues that articulated fingers lack the robustness, force and lifetime for industrial applications, and forecasts task-specialized robots still called humanoids over the next fifteen yearsSource 4.
Both kill conditions are one measurement, cost per task, since the humanoid plan is to do human manual work "at lower prices and just as well"Source 4. If task-specific robots keep winning it in the same applications, the humanoid thesis dies; if a humanoid reaches parity across many tasks, the task-specific thesis does.
Six observations would settle the theses, and GEN-1 nearly meets one
Each card's "wrong if" line is an observation to watch, from real-world success flat after a 10x data increase to humanoid cost-per-task parity. GEN-1 nearly meets the teleoperation test, but uses 1 hour of robot data per taskSource 30, and the bear case tracks each observation on its watchlist.
See also
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
- The Data Bottleneck
Robot data comes in hours; language data in trillions of tokens.
Linked from
- Hierarchical Approaches
From SayCan and Code as Policies to the hierarchies in Helix and pi0.5.
- The Bear Case
Why this could be another robotics winter.
References
Rich Sutton, 2019.
https://web.archive.org/web/20241231102234/http://www.incompleteideas.net/IncIdeas/BitterLesson.html
Rocking Robots, 2026.
https://www.rockingrobots.com/nucleus-robotics-emerges-from-stealth-with-humanoids-on-the-german-factory-floor/
Rodney Brooks, 2025.
https://rodneybrooks.com/why-todays-humanoids-wont-learn-dexterity/
Ken Goldberg, Science Robotics, 2025.
https://doi.org/10.1126/scirobotics.aea7390
Elis Karcini, Faisal Mehrban, Quang Nguyen, Mac Schwager, Arash Ajoudani, Cesar Cadena, and 3 more, 2026.
https://arxiv.org/abs/2606.06556
Jeremy Levine, Talia Goldberg, Janelle Teng Wade, Alexandra Sukin, Bhavik Nagda, Jason Scheller, and 1 more, 2026.
https://www.bvp.com/atlas/bessemer-predicts-robotics-and-physical-ai
Ruijie Zheng, Dantong Niu, Yuqi Xie, Jing Wang, Mengda Xu, Yunfan Jiang, and 9 more, 2026.
https://arxiv.org/abs/2602.16710
Physical Intelligence, Kevin Black, Noah Brown, James Darpinian, Karan Dhabalia, Danny Driess, and 30 more, 2025.
https://arxiv.org/html/2504.16054v1
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/blog/pi07
Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Kevin Black, Ken Conley, Grace Connors, and 49 more, 2025.
https://www.pi.website/download/pistar06.pdf
Kun Lei, Huanyu Li, Dongjie Yu, Zhenyu Wei, Lingxiao Guo, Zhennan Jiang, and 3 more, 2025.
https://arxiv.org/abs/2510.14830
Wenli Xiao, Jia Xie, Tonghe Zhang, Haotian Lin, Letian Fu, Haoru Xue, and 11 more, 2026.
https://arxiv.org/abs/2606.19980
Google DeepMind, 2026.
https://deepmind.google/models/gemini-robotics/embodied-reasoning/
Carolina Parada, 2026.
https://deepmind.google/blog/gemini-robotics-2-brings-whole-body-intelligence-to-robots/
Michael Ahn, Anthony Brohan, Noah Brown, Yevgen Chebotar, Omar Cortes, Byron David, and 39 more, 2022.
https://arxiv.org/abs/2204.01691
Mahmoud Assran, Adrien Bardes, David Fan, Quentin Garrido, Russell Howes, Mojtaba Komeili, and 23 more, 2025.
https://arxiv.org/abs/2506.09985
NVIDIA, Aditi, Niket Agarwal, Arslan Ali, Jon Allen, Martin Antolini, and 289 more, 2026.
https://research.nvidia.com/labs/cosmos-lab/cosmos3/technical-report.pdf
Agility Robotics, n.d.; accessed 2026-09-24.
https://www.agilityrobotics.com/
Figure AI, 2025.
https://www.figure.ai/news/production-at-bmw
Figure AI, Figure news, 2026.
https://www.figure.ai/news/helix-2-5-zero-shot-30-home-generalization
Fanqi Lin, Yingdong Hu, Pingyue Sheng, Chuan Wen, Jiacheng You, Yang Gao, ICLR 2025, 2024.
https://arxiv.org/abs/2410.18647
Gemini Robotics Team, Abbas Abdolmaleki, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, and 167 more, 2025.
https://arxiv.org/abs/2510.03342
Seonghyeon Ye, Yunhao Ge, Kaiyuan Zheng, Shenyuan Gao, Sihyun Yu, George Kurian, and 30 more, 2026.
https://arxiv.org/abs/2602.15922
Jianlan Luo, Charles Xu, Jeffrey Wu, Sergey Levine, 2024.
https://arxiv.org/abs/2410.21845
Sergey Levine, Learning and Control (Substack), 2025.
https://sergeylevine.substack.com/p/sporks-of-agi
Generalist Team, Generalist AI blog, 2026.
https://generalistai.com/blog/gen-1
Scott Dresser, About Amazon, 2025.
https://www.aboutamazon.com/news/operations/amazon-million-robots-ai-foundation-model
Further reading
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
Brett Adcock, X, 2026-05-14.
https://x.com/adcock_brett/status/2054973511572271172
Spot a factual error or missing qualification? Report a content correction.