Real-Time Execution
The latency budgets that decide whether the control loop closes.
Real-time execution means delivering a policy's actions on the controller's clock while the next inference runs. At 50 Hz the control period is 20 ms, shared by cameras, network, preprocessing and model, and the hand-off between action chunks changes what the robot doesSource 5.
Slide the model-size control and the missed-deadline count follows the new inference time.
Control-loop budget
The robot's brain thinks slower than the arm needs
Where the model runs
Adjust more
Synchronous toy: does not close at 50 Hz: 19 Hz reciprocal inference rate, not robot Hz; 2 deadlines missed
Cited latencies
pi0, H100 server6.15 mscloses at 50 HzVLA-Perf roofline: 1000/162.5 ms; BF16/FP16, 3 cameras, 10 steps, chunk 50, no network
pi0, Jetson Thor52.57 msover budgetVLA-Perf roofline: 19.0 inference Hz; BF16/FP16, 3 cameras, 10 steps, chunk 50, no network
pi0.6, H100 server63 msover budget5 denoising steps, 3 cameras, per chunk
RTC mean total, non-mobile robot108.76 msover budget±2.34 ms SD; 50 calls, RTX 4090/bfloat16, 5 steps, wired LAN
RTC mean total, mobile robot138.98 msover budget±6.71 ms SD; model 96.89, network 21.20, resize 11.22, other 9.67 ms
pi0.7 training-delay setting240 mspaper: maximum 12 simulated ticks at 50 Hz, not a measured guarantee
A filled beat gets a fresh command; a hollow grey beat passes with none.
How this was made
The arm in this figure runs a 50 Hz control loop, so a command is due every 20 ms. The bar is one synchronous inference call: the policy is asked once at time zero and the arm gets nothing new until it answers. Every beat that passes inside the call is a missed deadline. Real systems hide this wait with action chunks and asynchronous execution, described further down the article.
The two presets are VLA-Perf v1 roofline predictions for pi0, not measurements: 6.15 ms on an H100 server and 52.57 ms on a Jetson Thor, both at BF16/FP16 with three cameras, ten denoising steps, a chunk of 50 and no network. The other cited latencies in “Adjust more”: the pi0.6 model card reports 63 ms per chunk on an H100 with five denoising steps; the real-time chunking paper measured 108.76 ms (±2.34 ms) mean total on a non-mobile robot over a wired LAN with an RTX 4090 at bfloat16, and 138.98 ms (±6.71 ms) on a mobile robot (model 96.89, network 21.20, image resize 11.22, other 9.67 ms). The pi0.7 paper trains with up to 12 simulated ticks of delay at 50 Hz, a 240 ms training-delay setting rather than a measured latency.
Illustrative teaching model, not hardware profiling. VLA-Perf v1 models 2.7B pi0 at 52.57 ms and hypothetical 9.1B pi0-L at 3.9 Hz; this plot deliberately places the first reference at 3.0B.
The model-size slider follows a teaching curve on the robot's own computer: linear below the pi0 reference (modeled) at 3.0B, a power law up to the pi0-L hypothetical at 9.1B. Neither rule is a hardware measurement or a size limit. The inference rate in the readout, 19 answers a second at the current setting, is the reciprocal of one call's latency, not the rate at which the robot's controller runs.
In this toy, the 3.0B coordinate gives 52.6 ms of inference against the 20 ms budget of a 50 Hz loop, missing 2 deadlines and running at 19 Hz; inference stays under budget only below about 1.1B toy parameters. The 3.0B coordinate is deliberately chosen; VLA-Perf models pi0 at 2.7B and pi0-L as hypothetical. All displayed rates are reciprocal toy inference rates, not robot/controller frequencies.
Teaching-model inference by toy size, against the 20 ms budget
| model size | inference | effective rate | loop |
|---|---|---|---|
| 0.5B | 8.8 ms | 114 Hz | closes |
| 1.0B | 17.5 ms | 57 Hz | closes |
| 2.0B | 35.0 ms | 29 Hz | does not close |
| 3.0B | 52.6 ms | 19 Hz | does not close |
| 6.0B | 141.5 ms | 7 Hz | does not close |
| 9.1B | 256.4 ms | 4 Hz | does not close |
Latencies from VLA-Perf, the π0.6 model card, the real-time chunking paper and the π0.7 paper; teaching curve in between.
63 ms
pi0.6 per chunk
5 denoising steps, 3 cameras, one H100
19 Hz
pi0 Thor model
52.57 ms predicted; network excluded
138.98 ms
RTC mean total
mobile; 108.76 ms non-mobile, RTX 4090/LAN
0-12 ticks
pi0.7 training delay
paper: maximum 240 ms at 50 Hz
Where the milliseconds go
A 60 ms inference cannot fit in a 20 ms tick, so the current chunk supplies the 50 Hz commandsSource 5. Gemini Robotics pairs a cloud backbone with a local decoder: about 250 ms end to end, yet 50 Hz effective control through multi-action chunksSource 22.
The Real-Time Chunking (RTC) paper measures π0.5 on an RTX 4090 in bfloat16, with five denoising steps and a wired LAN. Over 50 inference calls in a real episode, the mobile setup spent 96.89 ms in the model, 21.20 ms on the network, 11.22 ms resizing images and 9.67 ms on other workSource 5.
The hardware wall
VLA-Perf (Jiang et al., 2026) is an analytical roofline model assuming optimistic software, adequate model accuracy and attainable peak compute and memory bandwidth. An optimized π0 Triton implementation on an RTX 4090 reaches 73.3 to 82.6% of its predicted throughput with one to three camerasSource 6.
Its baseline π0 has 2.7B parameters and models three 224×224 cameras, 32 language tokens, 14 action dimensions, chunk size 50, 10 denoising steps, batch size one, and BF16 or FP16. Excluding network, sensor and execution latency, it predicts 162.5 inferences per second on H100 and 19.0 on Jetson Thor. A hypothetical 9.1B π0-L reaches 3.9 on Thor, all three π0 components are memory-bound there, and on B100 raising denoising steps from 10 to 50 multiplies total latency by 2.15Source 6.
VLA-Perf calls 10 Hz inference "acceptable" and 100 Hz "high-performance" relative to common camera rates. Thor's predicted 19 Hz clears the first; the authors propose smaller models, fewer denoising steps or lower-precision quantization for the secondSource 6. NVIDIA's Jetson AI Lab measured a different setup, π0.5 with action horizon 10 on Jetson AGX Thor, at about 132 ms in PyTorch BF16 and 49 ms with FP8 plus NVFP4Source 24.
RT-2's 55B model ran at 1 to 3 HzSource 19, and the 7B OpenVLA runs at about 6 Hz on an RTX 4090 but 1.2 Hz on its evaluation A5000Source 20. OpenVLA-OFT's parallel decoding of chunked continuous actions raised throughput 26x and average success from 76.5% to 97.1%Source 21. Dexmal and StepFun ran π0 with two camera views in 27.3 ms on one RTX 4090Source 29, and Fast-in-Slow, which embeds a fast action module in its VLM, reaches 117.7 Hz control with eight-action chunksSource 28.
In VLA-Perf, server placement depends on the network: synchronous π0 on an RTX 4090 takes 38.7 ms over WiFi 6 against Thor's 52.6 ms, but 55.7 ms over 5G, and B100 over 4G with a slow cloud link takes 273.4 msSource 6.
Three ways to hand off a chunk
Chunking captures temporal dependencies in demonstrations at the cost of reactivity to unexpected statesSource 12. Let inference take milliseconds during the current chunk.
Synchronous execution runs part of a chunk, pauses for inference, then resumes, the default in many prior worksSource 5. π0 executes 16 of its 50 actions on its 20 Hz UR5e and Franka setups and 25 on the other 50 Hz robotsSource 2, and Physical Intelligence ran π0, π0-FAST and π0.5 synchronously before RTCSource 8. The RTC paper links stop-start motion to distribution shiftSource 5.
Naive switching jumps to the new chunk on arrival. That removes dead time but adds a discontinuity: the new chunk comes from an observation milliseconds old, and the command steps by the two chunks' disagreement in one tickSource 5.
Temporal ensembling, ACT's 2023 method, averages each timestep's predictions with weights that favour older onesSource 1, but averaging predictions from different modes need not give a valid action. In RTC's π0.5 real-robot comparison, both ensembling variants triggered the robot's protective stop at +100 and +200 ms of injected latencySource 5.
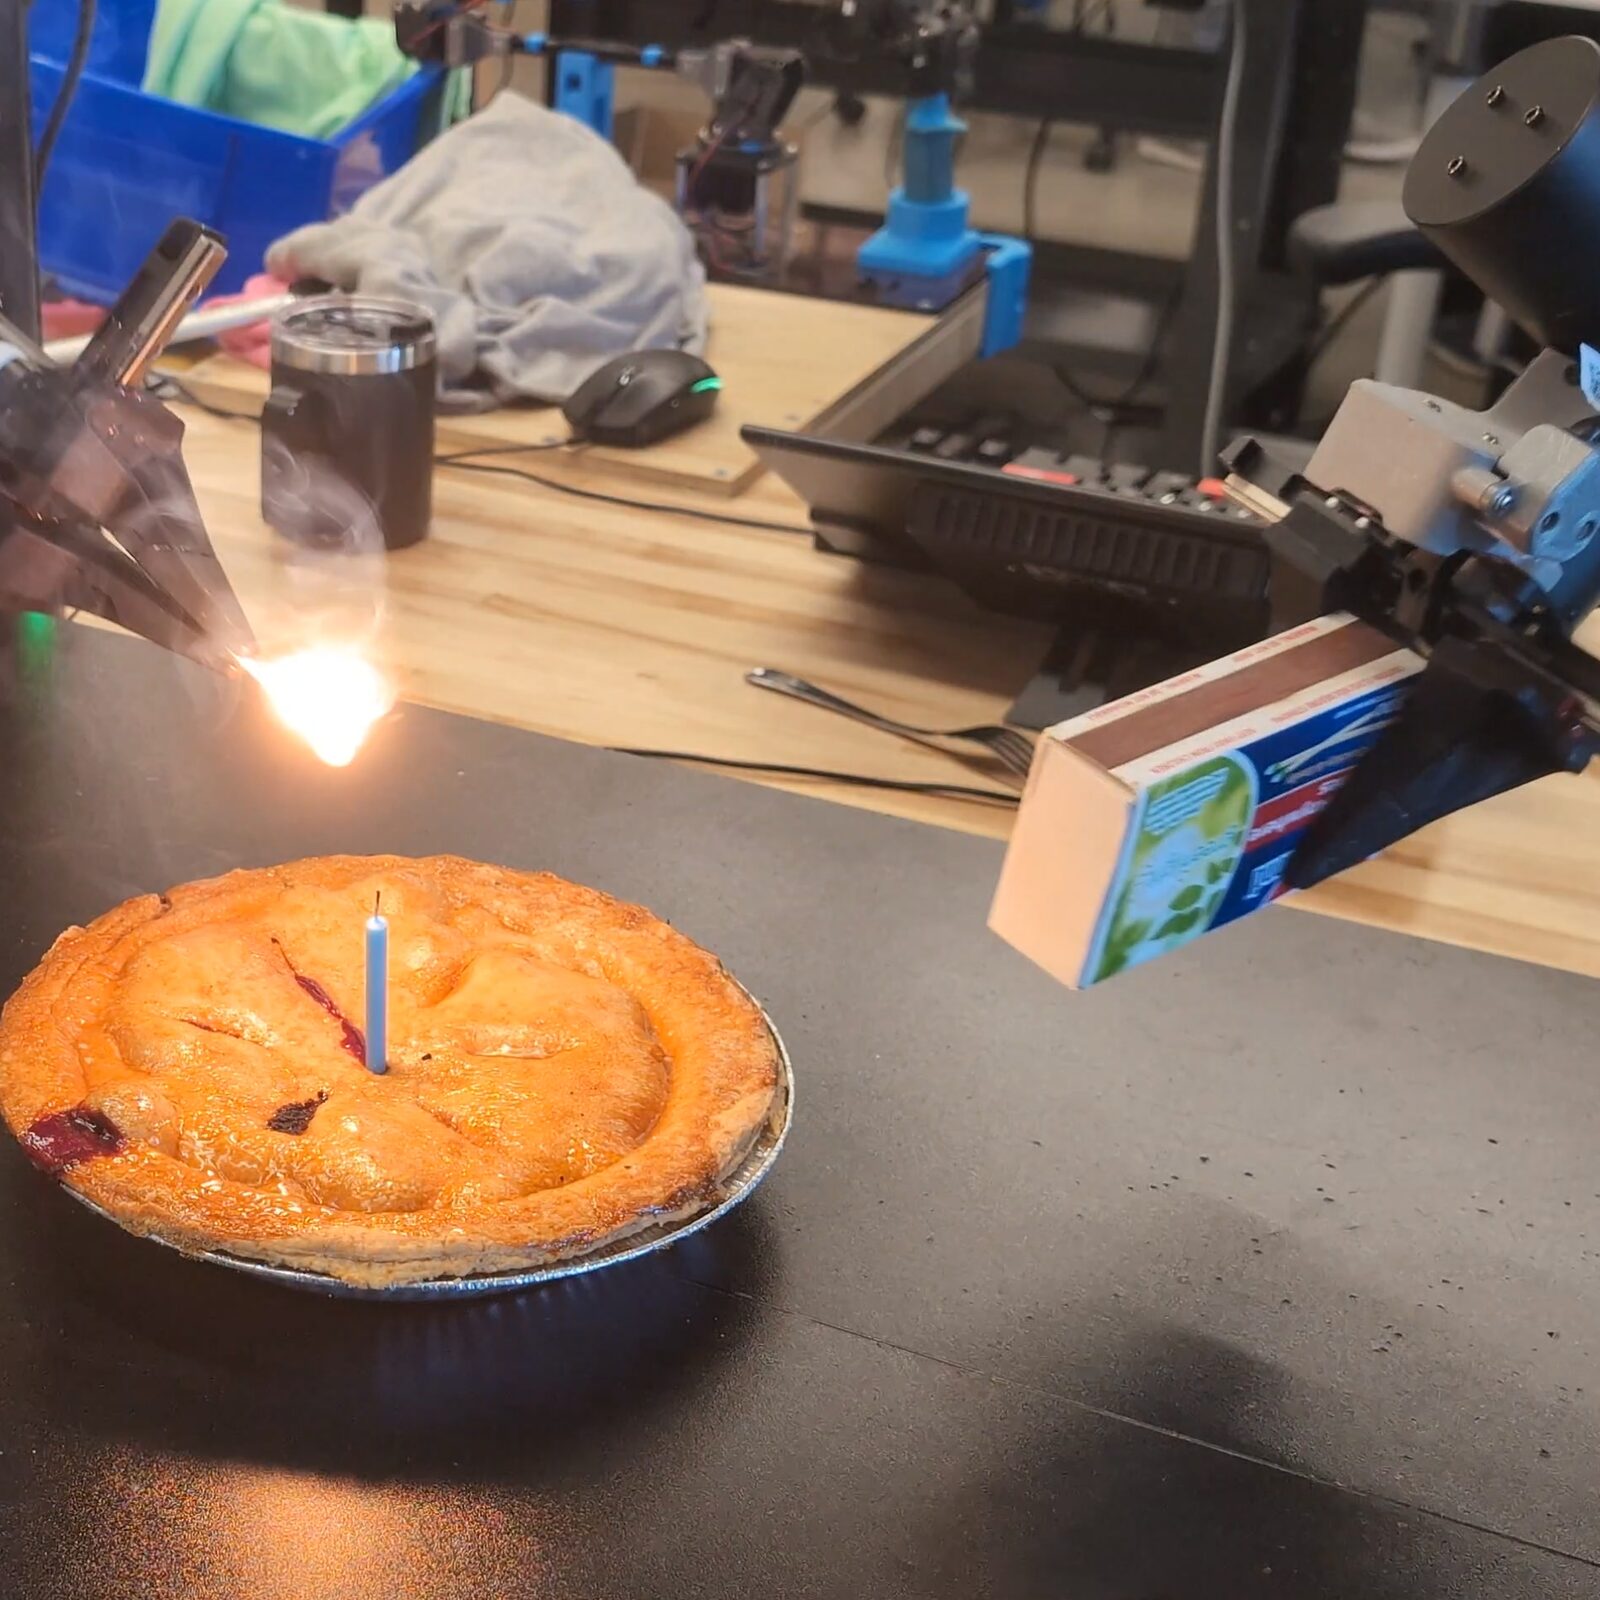
Real-Time Chunking inpaints the next chunk while the current one executes, fully weighting the first actions, which execute during inference, and works on diffusion and flow policies without retrainingSource 5 Source 8. On six π0.5 real-robot tasks, its aggregate throughput did not degrade at +0, +100 or +200 ms of injected delay, and it lit matches precisely at total delays above 300 msSource 5.
VLASH rolls the robot state forward with the previous chunk and cuts reaction latency up to 11.8x against synchronous inferenceSource 15, and A2C2's small per-step correction head gains 23 percentage points of success over RTCSource 16. Event-triggered inference sets the inference gap by scene change, averaging 95% real-world successSource 18. SmolVLA's asynchronous stack decouples prediction from executionSource 14, and on a local network its round trips stay under 100 ms while tasks finish about 2x fasterSource 13.
Chunk hand-off
Three ways to swap plans: pause, lurch, or blend
Thinking delay
Adjust more
d = 200 ms: the toy naive switch steps by 1.00 per tick; Δv proxy limit 0.30 per 20 ms tick
synchronouspeak |Δv| 0.17within 0.30 limitdead time 200 ms
naive switchpeak |Δv| 1.00exceeds 0.30 limit
real-time chunkingpeak |Δv| 0.18within 0.30 limit
Sudden jump: the arm lurcheswhen the new plan takes overpause 0.2 second · lurch 1.00 · blend 0.18 · limit 0.30
Lanes, back to front: pause, lurch, blend. Each gauge swings with the speed step of every tick.
How this was made
Each lane is the commanded velocity of one arm around a single chunk hand-off: the old chunk runs out at the dashed line and the new one, computed during the thinking delay, takes over. Pausing (synchronous execution) slows to rest, waits out the delay and starts again, so it costs dead time rather than a jump. Switching at once (a naive switch) applies the whole disagreement between the stale plan and the fresh one in one 20 ms tick. Real-time chunking keeps the moves already under way for the length of the delay, then eases into the new plan.
The velocity-step readouts in “Adjust more” read each lane against a 0.30 per-tick limit. With no delay all three lanes coincide: the new plan is ready the tick the old one ends, so the synchronous lane has nothing to wait for.
Illustrative hand-off traces, not an RTC solver or measured robot data, in arbitrary units. The 0.30 per-tick limit is a discontinuity proxy, not physical jerk. The sine-shaped plan, delay-dependent offset, four-tick ramps and five-tick linear blend are teaching assumptions, not the paper’s inpainting algorithm. RTC (arXiv:2506.07339) motivates overlapping inference and execution; these curves do not reproduce its experiments or guarantee safety.
At 200 ms of inference delay the synchronous velocity trace stops for 200 ms of dead time, while the naive switch reaches a peak velocity step of 1.00 per 20 ms tick and real-time chunking reaches 0.18, both read against the illustrative 0.30 discontinuity-proxy limit; these constructed traces use arbitrary velocity units, not physical jerk or measured robot data. The five-tick linear blend is not RTC inpainting, and each trolley's pendulum gauge keeps its largest step on a drag pointer.
Sampled commanded velocity across the hand-off
| tick | synchronous | naive | chunking |
|---|---|---|---|
| 0 | 0.60 | 0.60 | 0.60 |
| 6 | 0.83 | 0.83 | 0.83 |
| 12 | 0.00 | 1.77 | 0.77 |
| 18 | 0.00 | 1.49 | 0.69 |
| 24 | 0.51 | 1.35 | 1.35 |
| 29 | 0.45 | 1.48 | 1.48 |
Illustrative traces in arbitrary units; method from the real-time chunking paper.
Training the tolerance in
Black et al. (2025) simulate the delay in training, which avoids inference-time inpainting's added latency and works better at higher delaysSource 9. π0.7 trains with simulated delays of 0 to 12 timesteps, at most 240 ms on a 50 Hz robotSource 4, and Soft RTC's medium overlap window cuts high-delay action jerk by 9.6% against hard training-time RTCSource 10.
Chronos Policy, from Changhao Wang, Jaden Clark and Shuran Song at Stanford (October 2026), tells a diffusion transformer when each observation was captured and when each action will run, and randomizes both timings in training. On a simulated conveyor pick-and-place with inference delays up to 200 ms, it kept 76.4% success where Diffusion Policy fell to 1.8%, over 450 episodes per method and condition. On three real tasks with 10 or 20 trials per condition, it had the highest task score under every timing condition, against Diffusion Policy with and without RTCSource 31.
Real-Time EXPO-FT learns a lightweight edit policy that reacts to the latest observation while a slow VLA proposes chunks, raising average performance on four dynamic real tasks from 42% to 97%Source 30. NVIDIA uses test-time and train-time RTC for GR00T N1.6Source 11, and Figure's Helix offsets its two systems' training inputs to match their deployed latency gapSource 23.
ChunkTrust (September 2026) infers how many actions to execute before replanning from the policy's own outputs while it runs. Over all 50 RoboTwin2.0 tasks it raised π0.5's task-averaged success by 6.80 percentage points, and on four real household tasks the mean normalized process score from 50.4% to 57.5%Source 7.
Spending the step budget
π0 integrated its flow with 10 Euler steps per chunkSource 2, π0.6 cut that to 5Source 3, and π0.7's minimal variant takes 38 ms on one H100 with three camerasSource 4.
Distillation removes most steps: One-Step Diffusion Policy raises action prediction from 1.5 Hz to 62 HzSource 25, and Consistency Policy is an order of magnitude faster than the fastest alternative at competitive successSource 26. FASTER finds reaction time set by the time to first action and the execution horizon, and compresses the immediate reaction to a single denoising stepSource 17. For token-based VLAs, PD-VLA's parallel decoding recovers 2.52 times the execution frequencySource 27.
See also
- Hardware Taxonomy
A buyer's guide from SO-101 to Jetson Thor.
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
Linked from
- Action Chunking (ACT and ALOHA)
ACT predicts short action sequences and smooths them with temporal ensembling.
- Diffusion Policy
Visuomotor control as conditional denoising over action sequences, with receding-horizon execution.
- Comparison Matrix
Every major policy compared on eight architectural axes.
- RL Fine-Tuning of Policies
Improving a pretrained policy from its own online experience.
- Action Spaces for Robot Learning
What each action representation gives the learner and asks of the controller.
- Hardware Taxonomy
A buyer's guide from SO-101 to Jetson Thor.
- The Robot Learning Stack
From data capture to robot integration as one reproducible system.
- Motion Planning
Configuration space, RRT and its variants, and trajectory optimization.
- Control
PID, LQR, MPC and whole-body QP, the stack under every learned policy.
- ROS 2 for Machine Learning Engineers
ROS 2 as the production boundary around a learned policy.
- Drones and Aerial Robotics
Autonomous flight, from state estimation to champion-level racing.
References
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Physical Intelligence, 2025.
https://website.pi-asset.com/pi06star/PI06_model_card.pdf
Bo Ai, Ali Amin, Raichelle Aniceto, Ashwin Balakrishna, Greg Balke, Kevin Black, and 81 more, 2026.
https://www.pi.website/download/pi07.pdf
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://arxiv.org/abs/2506.07339
Wenqi Jiang, Jason Clemons, Karu Sankaralingam, Christos Kozyrakis, 2026.
https://arxiv.org/abs/2602.18397
Fanding Huang, Jingyan Jiang, Shifeng Bao, Mingkang Pu, Shiwei Li, Jing Xu, and 10 more, 2026.
https://arxiv.org/abs/2609.39754
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://www.pi.website/research/real_time_chunking
Kevin Black, Allen Z. Ren, Michael Equi, Sergey Levine, 2025.
https://arxiv.org/abs/2512.05964
Dongyang Liu, Zhaowen Zheng, Yu Sun, Longxu Zhang, Yixuan Liu, Hao Wan, 2026.
https://arxiv.org/abs/2605.25537
GEAR Team, Allison Azzolini, Johan Bjorck, Valts Blukis, Fernando Castañeda, Rahul Chand, and 53 more, 2025.
https://research.nvidia.com/labs/gear/gr00t-n1_6/
Yuejiang Liu, Jubayer Ibn Hamid, Annie Xie, Yoonho Lee, Maximilian Du, Chelsea Finn, 2024.
https://arxiv.org/abs/2408.17355
Francesco Capuano, Steven Palma, Michel Aractingi, Mustafa Shukor, Dana Aubakirova, Adil Zouitine, and 2 more, official post, 2025.
https://huggingface.co/blog/async-robot-inference
Mustafa Shukor, Dana Aubakirova, Francesco Capuano, Pepijn Kooijmans, Steven Palma, Adil Zouitine, and 8 more, 2025.
https://arxiv.org/abs/2506.01844
Jiaming Tang, Yufei Sun, Yilong Zhao, Shang Yang, Yujun Lin, Zhuoyang Zhang, and 4 more, 2025.
https://arxiv.org/abs/2512.01031
Kohei Sendai, Maxime Alvarez, Tatsuya Matsushima, Yutaka Matsuo, Yusuke Iwasawa, 2025.
https://arxiv.org/abs/2509.23224
Yuxiang Lu, Zhe Liu, Xianzhe Fan, Zhenya Yang, Jinghua Hou, Junyi Li, and 2 more, 2026.
https://arxiv.org/abs/2603.19199
Yansong Wu, Huaqing Li, Tianding Hou, Lingyun Chen, Alois Knoll, 2026.
https://arxiv.org/abs/2609.22587
Anthony Brohan, Noah Brown, Justice Carbajal, Yevgen Chebotar, Xi Chen, Krzysztof Choromanski, and 48 more, 2023.
https://arxiv.org/abs/2307.15818
Moo Jin Kim, Karl Pertsch, Siddharth Karamcheti, Ted Xiao, Ashwin Balakrishna, Suraj Nair, and 12 more, 2024.
https://arxiv.org/abs/2406.09246
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Gemini Robotics Team, Saminda Abeyruwan, Joshua Ainslie, Jean-Baptiste Alayrac, Montserrat Gonzalez Arenas, Travis Armstrong, and 112 more, 2025.
https://arxiv.org/abs/2503.20020
Figure AI, 2025.
https://www.figure.ai/news/helix
Aditya Sahu, Anqi Liu, official tutorial, n.d.; accessed 2026-10-04.
https://www.jetson-ai-lab.com/tutorials/openpi_on_thor/
Zhendong Wang, Zhaoshuo Li, Ajay Mandlekar, Zhenjia Xu, Jiaojiao Fan, Yashraj Narang, and 6 more, 2024.
https://arxiv.org/abs/2410.21257
Aaditya Prasad, Kevin Lin, Jimmy Wu, Linqi Zhou, Jeannette Bohg, 2024.
https://arxiv.org/abs/2405.07503
Wenxuan Song, Jiayi Chen, Pengxiang Ding, Han Zhao, Wei Zhao, Zhide Zhong, and 6 more, IROS 2025.
https://arxiv.org/abs/2503.02310
Hao Chen, Jiaming Liu, Chenyang Gu, Zhuoyang Liu, Renrui Zhang, Xiaoqi Li, and 5 more, 2025.
https://arxiv.org/abs/2506.01953
Yunchao Ma, Yizhuang Zhou, Yunhuan Yang, Tiancai Wang, Haoqiang Fan, 2025.
https://arxiv.org/abs/2510.26742
Perry Dong, Kuo-Han Hung, Dorsa Sadigh, Chelsea Finn, 2026.
https://arxiv.org/abs/2609.18207
Changhao Wang, Jaden Clark, Shuran Song, 2026.
https://arxiv.org/abs/2610.13929
Further reading
Hai Jiang, Yixian Zou, Binbin Liang, Boqian Liu, Fanman Meng, Shuaicheng Liu, 2026.
https://arxiv.org/abs/2607.24008
NVIDIA, Johan Bjorck, Fernando Castañeda, Nikita Cherniadev, Xingye Da, Runyu Ding, and 36 more, 2025.
https://arxiv.org/abs/2503.14734
NVIDIA, press release, 2025.
https://nvidianews.nvidia.com/news/nvidia-blackwell-powered-jetson-thor-now-available-accelerating-the-age-of-general-robotics
Spot a factual error or missing qualification? Report a content correction.