Diffusion Policy
Visuomotor control as conditional denoising over action sequences, with receding-horizon execution.
Diffusion Policy is a visuomotor robot policy that generates an action sequence by conditional denoising, from Chi et al. (2023). Its extended journal version evaluates 15 tasks and reports a 46.9% average relative improvement in simulation, using the best baseline and backbone per column, multi-human data excludedSource 1.
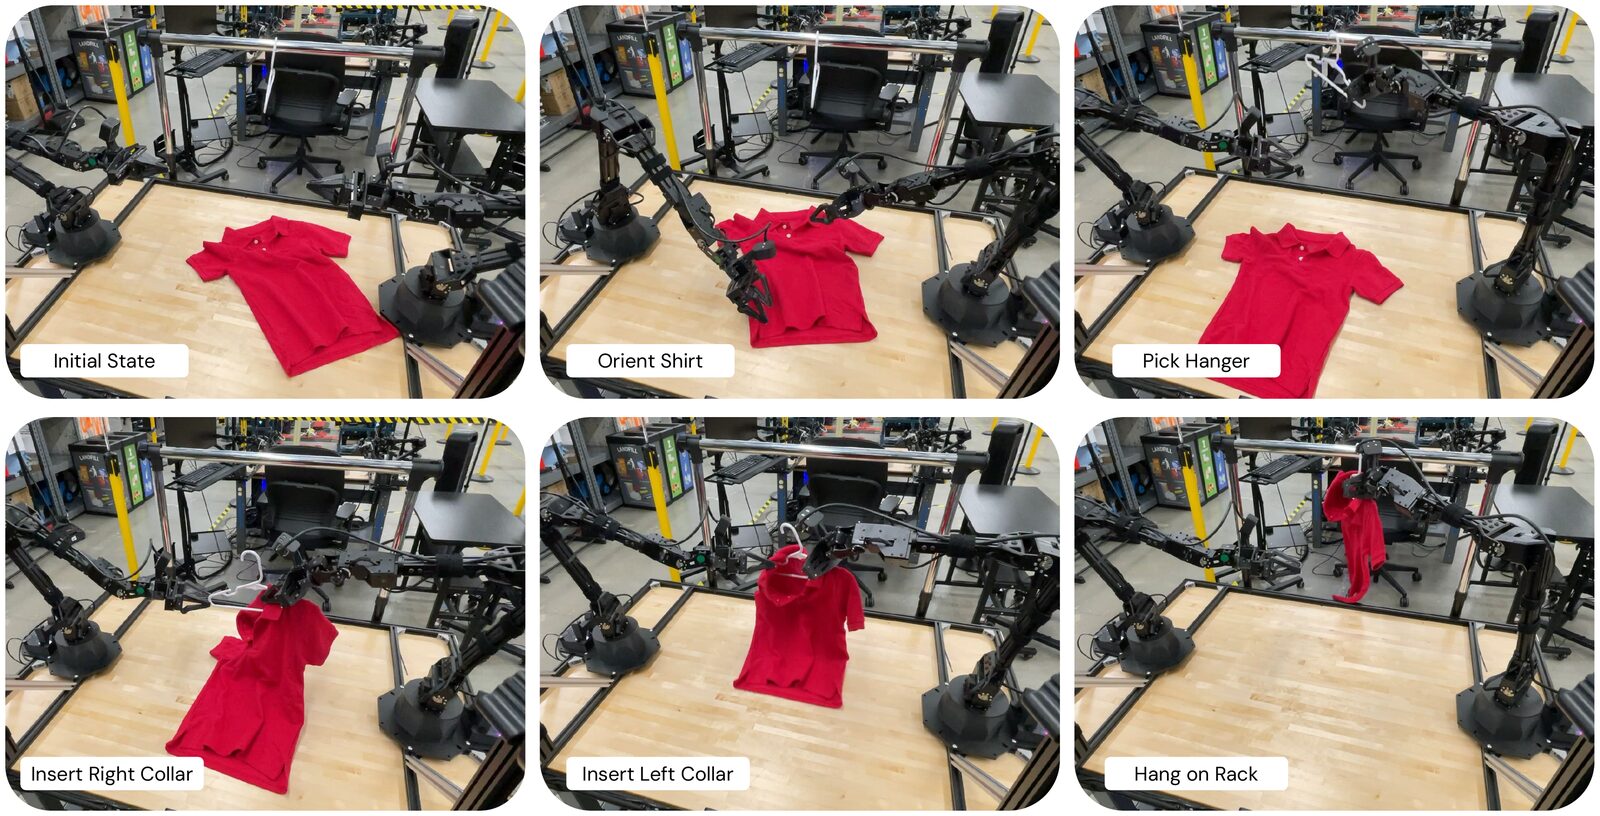
Receding-horizon control
Diffusion Policy executes actions of a -action prediction, then observes and replans. The CNN configuration executes 8 of 16 on many tasks, and the next inference can warm-start from the previous predictionSource 1.
acts like ACT's chunk size: large values give smooth motion that reacts slowly, and small values react fast but resample often, so each sample can switch modeSource 4. At the policy's 10 Hz command rate, commits the robot for 0.8 secondsSource 1. Try “Never rethink”: the dashed tails vanish.
Receding horizon
Plan 1.6 seconds ahead, act on half, then rethink
How often it rethinks
Adjust more
Run the reader to watch each plan cut shortplans 1.6 seconds ahead · acts on 0.8 seconds · rethinks 1.25 times a second
A schematic of the replanning cycle, not a recorded run.
How this was made
This is receding-horizon control. Each plan predicts T_p actions and the robot executes the first T_a before it plans again; the rest of each plan is replaced by the next plan and never executed. The presets use the Diffusion Policy setting, T_p = 16 and T_a = 8 at 10 Hz: 1.25 replans a second and 0.8 s committed per plan. “Never rethink” sets both to 32, so the robot runs each plan open-loop. Now T_p = 16, T_a = 8: 1.25 Hz replan rate, 0.8 s committed per plan.
The bench is a schematic, not a recorded run: one row of tape is one planned step, the hole across a row is where that step moves, and the path the holes follow is made up. Running, it moves three times slower than ten steps a second.
A receding-horizon plan with T_p 16 and T_a 8 issues 4 chunks across the 32-step window, replanning at 1.25 Hz and committing 0.8 s per plan; the inked rows are executed while the unread 8-step tails are thrown away into the bin.
Current receding-horizon plan
- T_p
- 16
- T_a
- 8
- chunks
- 4
- replan rate
- 1.25 Hz
- committed
- 0.8 s
Schematic of the replanning cycle; the preset uses the Diffusion Policy setting: plan 16 steps, act on 8, ten steps a second.
Multimodal demonstrations
When one operator passes an obstacle on the left and another on the right, mean-squared-error regression averages the demonstrations into a collision. Energy-based implicit policies often beat such explicit policiesSource 10, and diffusion models learn an expressive distribution over the joint action spaceSource 11. Pan et al. (2025) contest this motivation: generative policies owe their gains to supervised iterative computation, and a two-step regression policy essentially matches flow policiesSource 12. Fine-tuned OpenVLA-OFT, an L1-regression VLA, beat from-scratch Diffusion Policy and ACT by up to 15 points of average successSource 13.
Denoising in action space
Diffusion policy
From random noise to two good ways to move
Adjust more
pin set to a good movepin still randomthread through the pins: the move
beat 5 / 5 Two random guesses, two good moves · neither hits the bar
Illustrative: a drawn model of the idea, not a trained robot’s output.
Starting from random guesses and cleaning them up step by step lets the robot keep two different good moves instead of blurring them together.
How this was made
In symbols, the policy samples : an action a is drawn from a distribution of actions conditioned on what the robot observes, o. Over the 10 clean-up steps the two guesses’ average distance from the move each lands on falls from 0.87 → 0.00, measured in arch heights.
The guess the scene follows starts 0.82 from its move and ends 0.00 away.
The pin heights come from an illustrative model with fixed random seeds. Each move is 16 planned positions, the prediction horizon of the Diffusion Policy paper (Chi et al., 2023, arXiv 2303.04137); training mixes in noise on improved DDPM's square-cosine schedule, and acting runs the 10 deterministic DDIM steps the paper uses on real robots. The denoiser is the ideal one for a training set of just the two demonstrations, not a trained network’s output.
The drawing is a pin gauge, two of them side by side. Each pin’s height is one planned position, and the thread through the pins is the move. The bar is what the camera sees. A demonstration arches the thread over the bar or sags it under; a thread pulled straight, the average of the two, would run into it. The gauge, the bar and the camera are an illustration.
The five steps, in order:
- Demonstrations: people showed the robot two different good ways to make the same move.
- In training, random noise is added to every demonstrated move until they all blur into one random cloud.
- To act, the robot starts from random guesses and cleans them up in ten small steps, guided by what it sees; follow one guess.
- Every guess ends on a good move: in symbols, a move a is drawn to fit what the robot sees, o.
- Starting from random guesses and cleaning them up step by step lets the robot keep two different good moves instead of blurring them together.
Diffusion policy: denoising actions. A five-beat scene on two pin gauges, where each pin is one planned position of a move and a thread through the pins is the move, passing a bar the robot's camera sees. Beat 1: Demonstrations: people showed the robot two different good ways to make the same move. Beat 2: In training, random noise is added to every demonstrated move until they all blur into one random cloud. Beat 3: To act, the robot starts from random guesses and cleans them up in ten small steps, guided by what it sees; follow one guess. Beat 4: Every guess ends on a good move: in symbols, a move a is drawn to fit what the robot sees, o. Beat 5: Starting from random guesses and cleaning them up step by step lets the robot keep two different good moves instead of blurring them together. The relation a ~ p(a | o) means an action a is sampled from a distribution of actions conditioned on the observed state o. The guess the scene follows starts 0.82 from its move and ends 0.00 away; one guess ends under the bar and the other over the bar, and neither on the straight average that would hit the bar.
The policy is a denoising diffusion probabilistic model (DDPM)Source 15 conditioned on recent observations. Where a regression head computes , Diffusion Policy models over the next actions. Inference starts from Gaussian noise and repeatedly subtracts a fraction of the noise that the denoiser predicts,
until the sample is a valid action chunk. Training uses noise-prediction MSE with improved DDPM's square-cosine scheduleSource 1 Source 16. Real-world runs use DDIM, which keeps DDPM training but samples more efficientlySource 17, with 10 inference iterations and 0.1-second latency on an Nvidia 3080 in the main text and 16 in the appendixSource 1.
2
observations To
CNN Lift/Can/Square simulation rows
16
prediction Tp
predicted actions in those rows
8
execution Ta
executed actions in those rows
10 / 16
DDIM steps
real-world main text / appendix
CNN and transformer variants
The CNN backbone adapts Diffuser's one-dimensional temporal U-Net over state-action trajectoriesSource 3 to model only and predict only actionsSource 1, injecting observations through FiLM's feature-wise affine transformationSource 18:
Backbone variants
- CNN (default)
- 1D temporal U-Net over the action sequence
- CNN conditioning
- observations injected via FiLM
- transformer
- time-series diffusion transformer (minGPT-style)
- transformer conditioning
- observation embedding via cross-attention
- visual encoder
- ResNet-18 with GroupNorm, trained end-to-end
The CNN is the recommended default and works on most tasks without much tuning. The transformer gives most of the best state-based results, especially with fast action changes, but costs more tuning, and adding layers sometimes hurtsSource 1. ScaleDP confirms the layer problem and scales the transformer from 10 million to 1 billion parametersSource 19.
Variants and scale
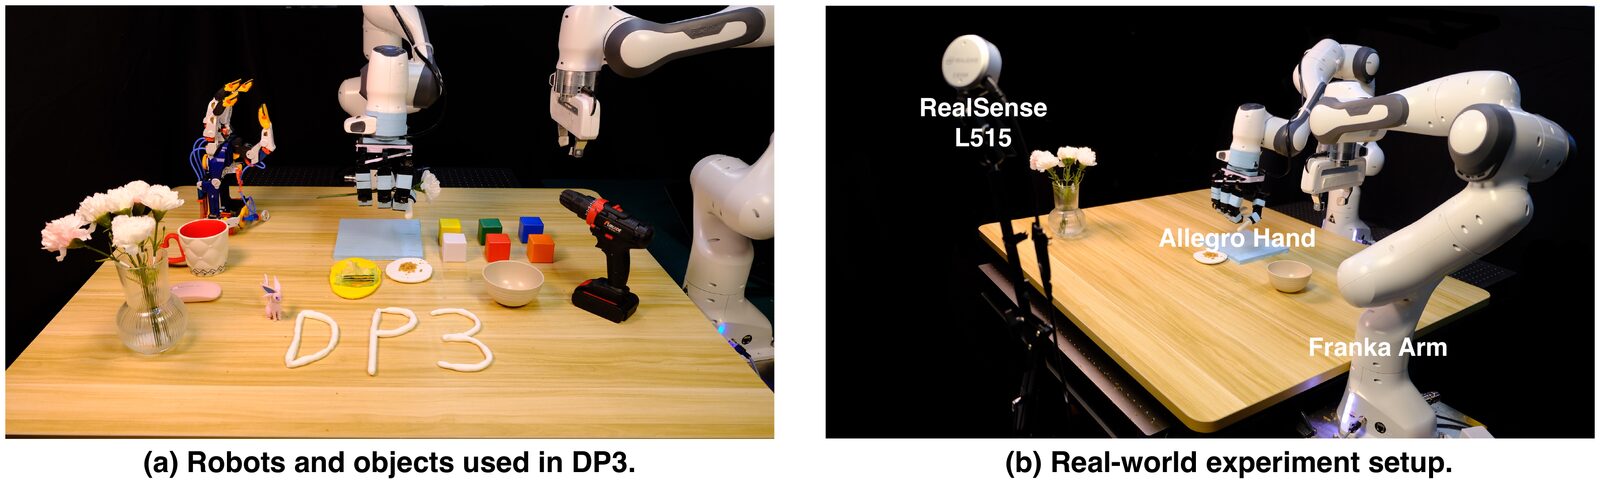
DP3 conditions on sparse point clouds and handles most of 72 simulation tasks with 10 demonstrationsSource 20, and Equivariant Diffusion Policy builds in SO(2) symmetry for 21.9% higher average successSource 21. ALOHA Unleashed pairs Diffusion Policies with large-scale ALOHA 2 data for deformable, contact-rich bimanual tasksSource 22, and TRI's Large Behavior Models scale the recipe to approximately 1,700 hours and match from-scratch policies with 3 to 5 times less dataSource 23.
Distillation
Iterative denoising is slow for mobile manipulators and quadrotors without high-end GPUs. Consistency models generate in one step by designSource 24, and Consistency Policy distills a Diffusion Policy teacher into one- or three-step generation; on Robomimic Square, three teachers at 0.84 to 0.92 success yielded students at 0.88 to 0.92Source 5.
One-Step Diffusion Policy lifts action prediction from 1.5 Hz to 62 Hz on real Franka tasksSource 6. Drifting Models (Kaiming He and colleagues, February 2026) train a one-step generator without distillation; swapped into Diffusion Policy, one step matched or beat the 100-step original on 10 of 14 simulated task settingsSource 30.
Flow matching
π0 replaced the DDPM with conditional flow matching, which regresses vector fields of fixed conditional probability pathsSource 26, on a straight path as in rectified flowSource 27. It samples noise and forms the interpolant
then trains the network to predict , drawing from a beta distribution weighted toward the noisy end. Sampling integrates from to with 10 forward Euler stepsSource 8.
Bilinear Flow Policy (Georgia Tech, University of Washington and Toyota Research Institute, October 5, 2026) targets goals outside the training distribution: across five simulated tasks it reached 2.63 times the out-of-distribution success of a goal-conditioned flow policy, and on two real tasks 50% against 18%Source 31.
Real-time chunking
Real-Time Chunking generates the next chunk while the current one executes, holding average throughput at +100 and +200 ms of injected delay on six real π0.5 tasksSource 9, and training-time RTC removes its inference overheadSource 28.
Limitations
The original paper conditions on observations alone, on single- and multi-task benchmarks and separate UR5 and Franka setupsSource 2; Octo adds language or goal-image conditioningSource 7, and π0 a pretrained vision-language backboneSource 8.
Reactivity is bounded by : events inside a committed segment wait for the next inferenceSource 14. Sampling cost remains, though one-step successors such as MP1 cut it to 6.8 msSource 25. With sparse data it acts like an action lookup table, returning training actions even for images of cats and dogsSource 29.
See also
- Teleoperation Rigs
ALOHA, GELLO, UMI and VR rigs compared on cost and quality.
- Real-Time Execution
The latency budgets that decide whether the control loop closes.
- Generative Video World Models
Cosmos, Genie and GR-2 use action-conditioned video prediction as a simulator.
Linked from
- Behavior Cloning Foundations
Covariate shift makes naive imitation drift, and DAgger is the standard fix.
- Action Chunking (ACT and ALOHA)
ACT predicts short action sequences and smooths them with temporal ensembling.
- Vision-Language-Action Models
RT-1, RT-2, Octo and OpenVLA, and what web-scale pretraining adds to robot control.
- The Pi Line
From pi0 to pi0.7, with flow-matching action experts and FAST tokenization.
- Grasp Planning
Contact mechanics, grasp quality metrics, and force closure.
References
Cheng Chi, Zhenjia Xu, Siyuan Feng, Eric Cousineau, Yilun Du, Benjamin Burchfiel, and 2 more, 2023.
https://arxiv.org/abs/2303.04137
Cheng Chi, Siyuan Feng, Yilun Du, Zhenjia Xu, Eric Cousineau, Benjamin Burchfiel, and 1 more, 2023.
https://arxiv.org/abs/2303.04137v1
Michael Janner, Yilun Du, Joshua B. Tenenbaum, Sergey Levine, ICML 2022.
https://arxiv.org/abs/2205.09991
Tony Z. Zhao, Vikash Kumar, Sergey Levine, Chelsea Finn, RSS 2023.
https://arxiv.org/abs/2304.13705
Aaditya Prasad, Kevin Lin, Jimmy Wu, Linqi Zhou, Jeannette Bohg, 2024.
https://arxiv.org/abs/2405.07503
Zhendong Wang, Zhaoshuo Li, Ajay Mandlekar, Zhenjia Xu, Jiaojiao Fan, Yashraj Narang, and 6 more, 2024.
https://arxiv.org/abs/2410.21257
Octo Model Team, Dibya Ghosh, Homer Walke, Karl Pertsch, Kevin Black, Oier Mees, and 14 more, 2024.
https://arxiv.org/html/2405.12213v2
Kevin Black, Noah Brown, Danny Driess, Adnan Esmail, Michael Equi, Chelsea Finn, and 18 more, RSS 2025, 2024.
https://arxiv.org/abs/2410.24164
Kevin Black, Manuel Y. Galliker, Sergey Levine, 2025.
https://arxiv.org/abs/2506.07339
Pete Florence, Corey Lynch, Andy Zeng, Oscar Ramirez, Ayzaan Wahid, Laura Downs, and 4 more, 2021.
https://arxiv.org/abs/2109.00137
Tim Pearce, Tabish Rashid, Anssi Kanervisto, Dave Bignell, Mingfei Sun, Raluca Georgescu, and 5 more, ICLR 2023.
https://arxiv.org/abs/2301.10677
Chaoyi Pan, Giri Anantharaman, Nai-Chieh Huang, Claire Jin, Daniel Pfrommer, Chenyang Yuan, and 5 more, 2025.
https://arxiv.org/abs/2512.01809
Moo Jin Kim, Chelsea Finn, Percy Liang, 2025.
https://arxiv.org/abs/2502.19645
Yuejiang Liu, Jubayer Ibn Hamid, Annie Xie, Yoonho Lee, Maximilian Du, Chelsea Finn, 2024.
https://arxiv.org/abs/2408.17355
Jonathan Ho, Ajay Jain, Pieter Abbeel, 2020.
https://arxiv.org/abs/2006.11239
Alex Nichol, Prafulla Dhariwal, 2021.
https://arxiv.org/abs/2102.09672
Jiaming Song, Chenlin Meng, Stefano Ermon, ICLR 2021.
https://arxiv.org/abs/2010.02502
Ethan Perez, Florian Strub, Harm de Vries, Vincent Dumoulin, Aaron Courville, AAAI 2018.
https://arxiv.org/abs/1709.07871
Minjie Zhu, Yichen Zhu, Jinming Li, Junjie Wen, Zhiyuan Xu, Ning Liu, and 5 more, 2024.
https://arxiv.org/abs/2409.14411
Yanjie Ze, Gu Zhang, Kangning Zhang, Chenyuan Hu, Muhan Wang, Huazhe Xu, RSS 2024.
https://arxiv.org/abs/2403.03954
Dian Wang, Stephen Hart, David Surovik, Tarik Kelestemur, Haojie Huang, Haibo Zhao, and 4 more, CoRL 2024.
https://arxiv.org/abs/2407.01812
Tony Z. Zhao, Jonathan Tompson, Danny Driess, Pete Florence, Kamyar Ghasemipour, Chelsea Finn, and 1 more, 2024.
https://arxiv.org/abs/2410.13126
TRI LBM Team, Jose Barreiros, Andrew Beaulieu, Aditya Bhat, Rick Cory, Eric Cousineau, and 76 more, 2025.
https://arxiv.org/abs/2507.05331
Yang Song, Prafulla Dhariwal, Mark Chen, Ilya Sutskever, ICML 2023.
https://arxiv.org/abs/2303.01469
Juyi Sheng, Ziyi Wang, Peiming Li, Mengyuan Liu, AAAI 2026.
https://arxiv.org/abs/2507.10543
Yaron Lipman, Ricky T. Q. Chen, Heli Ben-Hamu, Maximilian Nickel, Matt Le, 2022.
https://arxiv.org/abs/2210.02747
Xingchao Liu, Chengyue Gong, Qiang Liu, 2022.
https://arxiv.org/abs/2209.03003
Kevin Black, Allen Z. Ren, Michael Equi, Sergey Levine, 2025.
https://arxiv.org/abs/2512.05964
Chengyang He, Xu Liu, Gadiel Sznaier Camps, Guillaume Sartoretti, Mac Schwager, 2025.
https://arxiv.org/abs/2505.05787
Mingyang Deng, He Li, Tianhong Li, Yilun Du, Kaiming He, 2026.
https://arxiv.org/abs/2602.04770
Wonsuhk Jung, Sundhar Vinodh Sangeetha, Chen Xu, Abhishek Gupta, Masha Itkina, Shreyas Kousik, and 1 more, 2026.
https://arxiv.org/abs/2610.05765
Further reading
Shaolong Li, Lichao Sun, Yongchao Chen, 2026.
https://arxiv.org/abs/2603.12480
Xiaomi Robotics Team, Jun Guo, Piaopiao Jin, Jason Li, Peiyan Li, Yingyan Li, and 28 more, 2026.
https://arxiv.org/abs/2607.15330
Spot a factual error or missing qualification? Report a content correction.